How We Finally Solved Test Discovery
Yesterday I wrote about why test file discovery is still unsolved. Three approaches (stem matching, content grepping, hybrid), each failing differently. The hybrid worked best but had a broken ranking function – flat scoring that gave src/ the same weight as src/pages/checkout/. Today it’s solved.
The Problem With Flat Scoring
The March 30 post ended with this bug: +30 points for any shared parent directory. One shared path component got the same bonus as three. With 3 synthetic inputs, other factors dominated. With 29 real file paths, unrelated test files ranked above relevant ones.
The fix wasn’t tweaking the constant. It was replacing the scoring model entirely.
Five Tiers, Not Points
Instead of adding up weighted scores, we rank by structural relationship. Higher tiers always win over lower ones, regardless of path depth or name similarity.
Tier 1 – Colocated tests. Same directory, same stem with a test suffix. Button.tsx and Button.test.tsx side by side. This is the strongest signal possible.
Tier 2 – Same-directory content match. A test file in the same directory whose source code imports the implementation file.
Tier 3 – Path-based match. The test file’s path contains the implementation stem. tests/test_client.py for services/client.py. The classic mirror-tree convention.
Tier 4 – Content grep match. A test file anywhere in the repo references the implementation file in its source code.
Tier 5 – Parent directory content match. A test file in a parent directory that references the impl. Weakest signal, but still a real connection.
The key insight: tiers are ordinal, not additive. A Tier 1 match always outranks a Tier 3 match. No combination of bonus points can promote a distant test above a colocated one.
Content-Aware Matching
Path matching alone can’t handle barrel re-exports. When a test imports from '@/pages/checkout' and that resolves to index.tsx, the string “index” never appears in the import statement. Path matching sees nothing.
Content-aware matching reads the test file and greps for references to the implementation. If a test file contains import { CheckoutPage } from './index' or require('./checkout'), the content grep catches it. Tiers 2, 4, and 5 are the content tiers that fill gaps path-only matching leaves open.
Single-Source Patterns
Every language has its own test naming convention:
-
.test.ts, .test.tsx – JavaScript/TypeScript (Jest, Vitest)
-
.spec.ts, .spec.tsx – Angular, Cypress, Playwright
-
test_*.py – Python (pytest)
-
*_test.go – Go
-
*Test.java, *Test.kt – Java/Kotlin (JUnit)
-
*_spec.rb – Ruby (RSpec)
-
*.spec.js – JavaScript (Mocha, Jasmine)
All of these are defined once and imported everywhere. Before this change, three different functions each maintained their own pattern list – slightly different, each missing cases the others caught.
The Takeaway
Test file discovery looks like a string matching problem. It’s actually a ranking problem with structural priors. Flat scoring collapses structure into numbers and loses information. Tiered ranking preserves the structural relationship and makes the algorithm’s priorities explicit and debuggable. And the only way to validate ranking is against real data at real scale – not 3 curated inputs that any algorithm can pass.


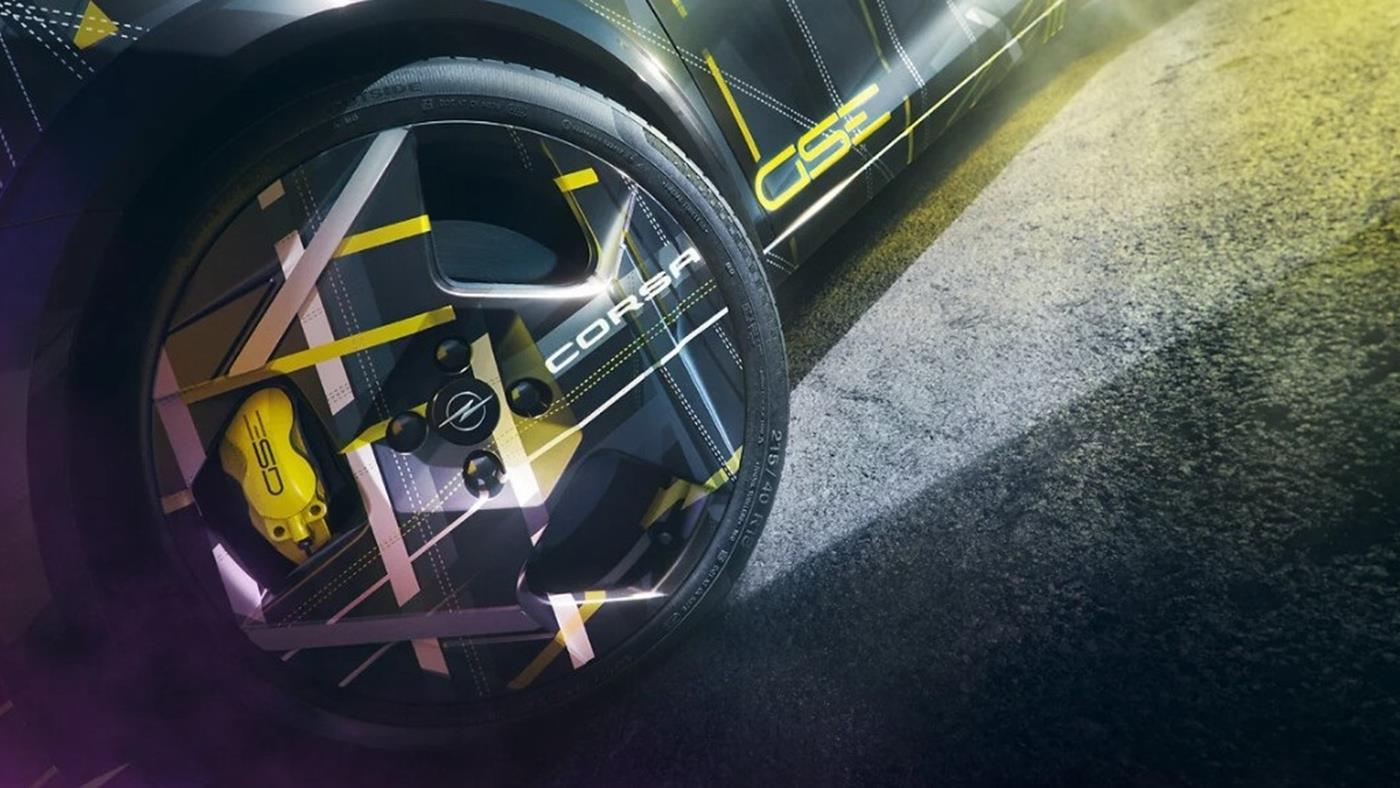
 Opel, Corsa GSE modelini Nürburgring’de test ediyor. 278 beygirlik elektrikli hot hatch, gelişmiş şasi ayarlarıyla ID. Polo GTI’ye güçlü bir rakip olmaya hazırlanıyor.
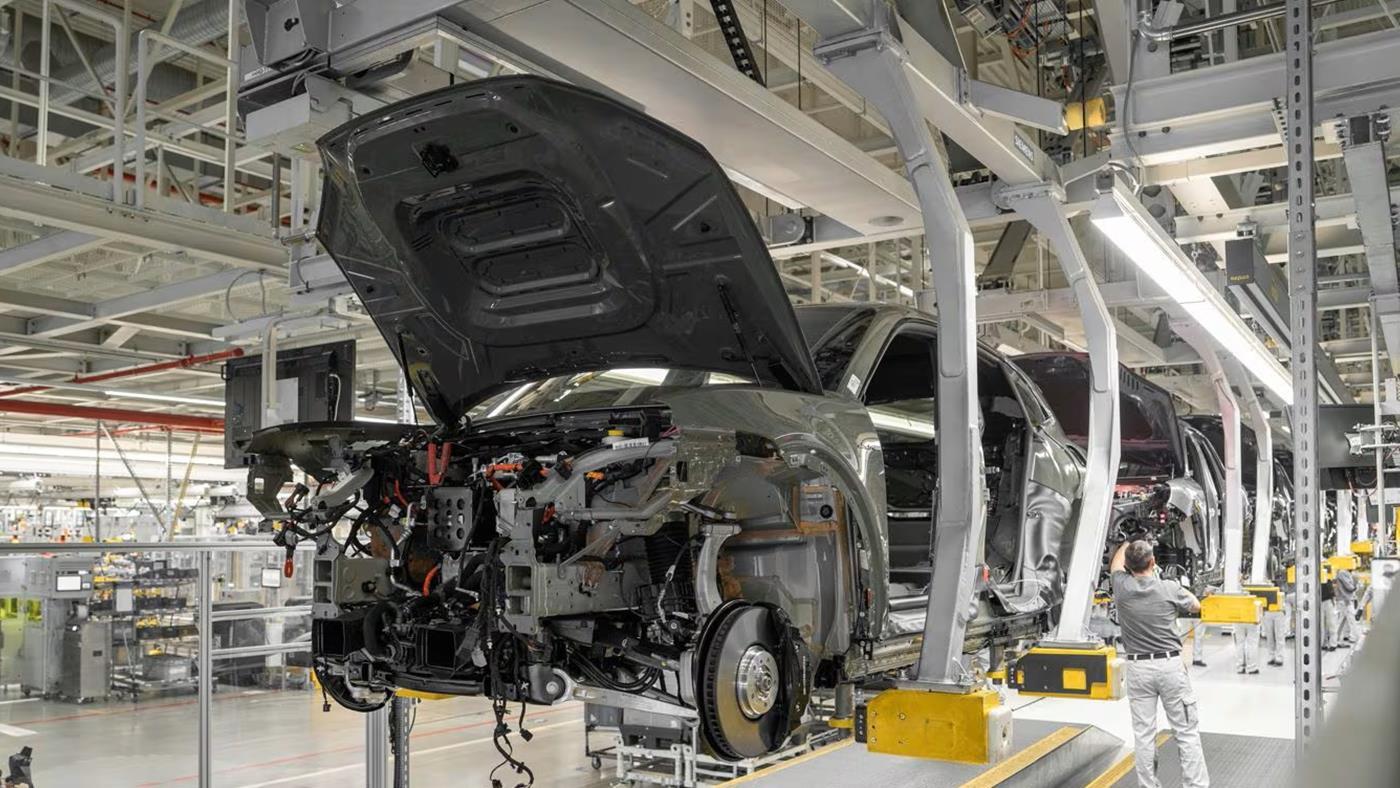
 İran savaşı ve Hürmüz Boğazı’ndaki kriz, petrol ve lojistik maliyetlerini artırarak otomotiv sektöründe üretim, tedarik ve fiyat dengelerini bozdu. Durum, küresel pazarda ciddi bir baskı oluşturuyor.
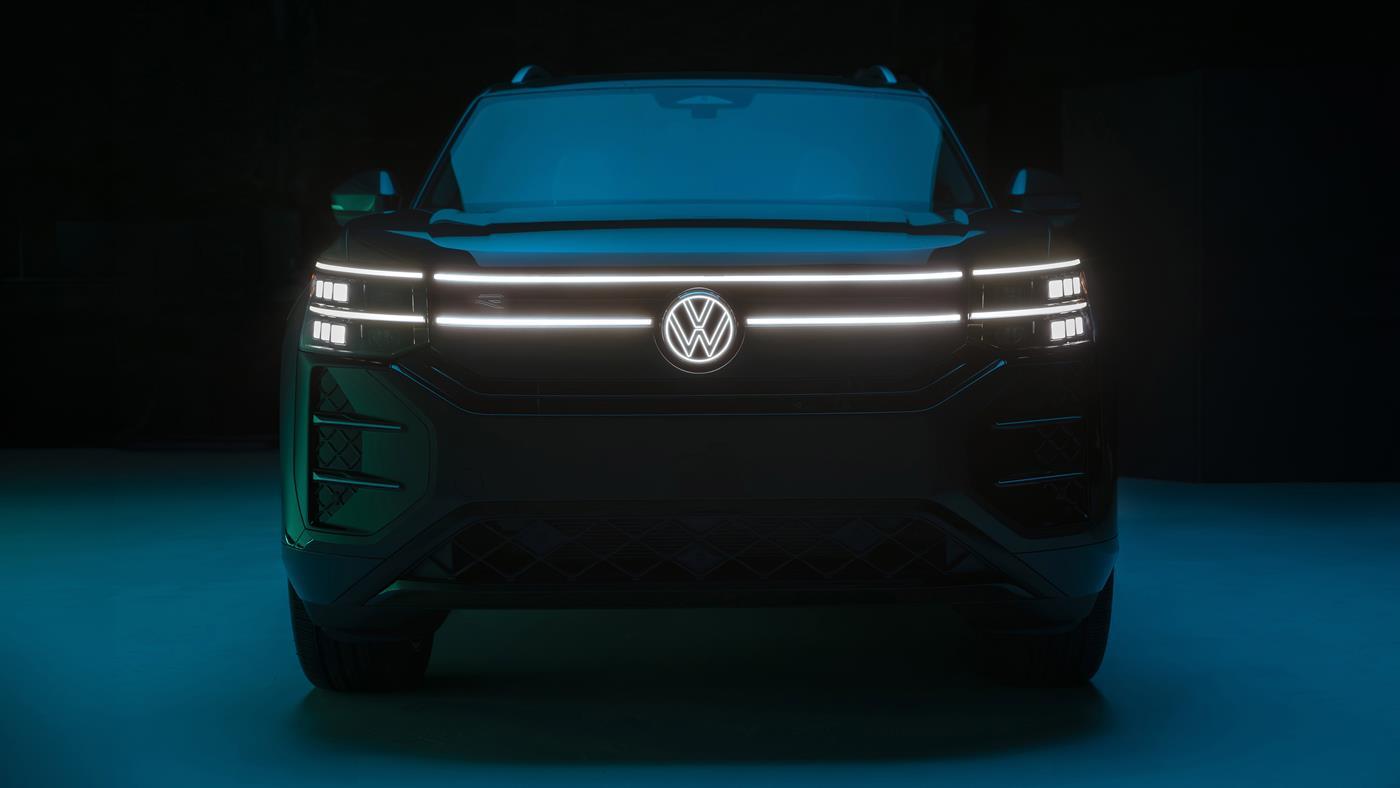
 Volkswagen Atlas, tamamen yenilenen iç mekânı, büyüyen ekranları ve güncellenen motoruyla sahneye çıktı. Benzinli motoru da güncellenen modelin hibrit versiyonu da yolda.