GitHub Account Suspended — Need Guidance & Help

Hey everyone!

I’m reaching out to the community because my GitHub account recently got suspended, and I’m honestly a bit confused about what exactly caused it and how to properly resolve it.

A while ago, my GitHub account was suspended. I didn’t receive a very detailed explanation, just a general notice about violating policies ( while i was logging in to it again).

Since then, I’ve been trying to understand:

  • What action might have triggered the suspension
  • Whether it was due to a specific repository, file type, or activity
  • What I should (or shouldn’t) do moving forward

My Concern

I’m planning to create new repositories that may include:

  • ZIP files (for distribution)
  • Setup/installation guides in the README
  • Possibly prebuilt assets (like UMD builds)

But now I’m unsure:

  • ❓ Is uploading ZIP-only repositories allowed?
  • ❓ Could that be a reason for suspension?
  • ❓ Are there best practices I should follow to avoid issues again?

What I’ve Tried

  • Looked into GitHub’s terms and policies, but they’re quite broad
  • Avoided anything that could be flagged (no spammy repos, no automation abuse, etc.)
  • Planning to keep things clean and transparent
  • already reported it to github support

🙏 What I Need Help With

If anyone here has experience with this or knows more about GitHub suspensions, I’d really appreciate your guidance:

  • Common reasons accounts get suspended
  • Safe practices for creating and sharing repositories
  • Whether distributing builds (ZIP/UMD) is okay
  • Steps to safely restart or continue development

I’m a student developer working on projects and trying to contribute and build in public. This situation has slowed me down a bit, and I want to make sure I don’t repeat any mistakes.

If you’ve faced something similar or have any advice, please share 🙌
Even small insights would really help.

Thanks a lot!

I built a Mac app after getting surprised by my Claude bill

A few months back I got my monthly API bill and felt sick.

I had been vibe-coding pretty hard with Claude, and I knew it wasn’t going to be zero. But the number was way higher than I expected. Like, embarrassingly higher. I had been running Claude Code sessions back to back, long context windows, lots of tool calls, and I had no idea how fast it was adding up.

The worst part? I couldn’t have known. There’s no live feedback. You just work, and then you find out later.

So I did what most developers do when something annoys them enough. I built a tool to fix it.

What I made

TokenBar is a macOS menu bar app that tracks your AI token usage in real time. It sits in your menu bar the whole time you’re working and shows you your spend as it happens, not after.

It works with Claude API, OpenAI, and a few others. You paste in your API key, and from that point on you can see tokens and cost right there in the menu bar while you code.

No dashboards to switch to. No end-of-month surprises. Just a number in the corner of your screen that tells you what’s actually happening.

Why menu bar

I tried building a dashboard version first. I never looked at it. I’d forget it was there and then check it once a day or not at all.

The menu bar is different because it’s persistent. You don’t have to remember to check it. You’re looking at your menu bar constantly anyway, so the information just becomes part of your workflow.

When I see the number creeping up I naturally adjust. Maybe I close a long context, maybe I switch models, maybe I just stop and think about whether the next prompt is actually necessary. Having visibility changes behavior.

The pricing thing

I charged $5 lifetime. I know it’s cheap. But the whole point is that this is a tool to help you spend less money on AI. It felt wrong to charge a lot for that.

Also I wanted it to be a no-brainer purchase. If you use Claude or GPT-4 even occasionally, you’ll make back $5 in avoided waste probably on the first week.

If you want to try it

It’s at tokenbar.site. Mac only for now.

Would love to hear if other people have had the same experience of getting surprised by their AI bills. It seems like it’s more common than people admit.

I Built a Social Post Engine to Escape the Canva-Export-Schedule Loop

As a solo founder running WahResume.com, I was spending way too much time on social media – not on creativity, but on process.
Same templates. Same brand assets. Same hashtags. Every post meant opening Canva, exporting, uploading, scheduling… and repeating it the next day.

So I built something to fix that.

Social Post Engine is a small tool that helps me stay consistent on social media without having to touch Canva or an endless queue of schedulers.

Here’s what it does:

✅ Seed & review topics in one command — it researches, outlines, and preps your next posts.
✅ Pre-generates branded images from templates (checklists, stat cards, charts, comparisons). It also writes captions in your brand’s voice using AI.
✅ Publishes automatically to LinkedIn and Instagram via a browser session.
✅ Runs on a timer, so your content goes live without you needing to think about it.

What started as a personal hack has grown into something that actually works — and saved me from the daily grind.

I’ve open-sourced it in case it helps other indie hackers, solo founders, or small teams trying to stay consistent without burning time.

You can drop in a simple config file with your brand details (like logo, fonts, hashtags, tone), and everything else runs on autopilot.

There’s still plenty to improve, but it’s already freeing up hours each week.

GitHub link in comments.
If it works for you, leave a ⭐ and share it with someone who might find it useful.

AI-Generated Go Serialization: Zero Boilerplate, Maximum Speed

I wanted to share a quick story about a weekend experiment.

There is a library called mok that lacks a code generator, so every time you want to mock an interface, it requires you to write all the boilerplate yourself. It’s simple but tedious work. I usually just offload it to an AI agent, and with a small example, it completes this task exceptionally well.

This got me thinking – could AI handle something more complex, like writing serialization code? If it could, we’d basically get the best of both worlds: the raw speed of generated code, with the same simplicity you get from reflection-based libraries.

But is it safe to trust AI with something as sensitive as serialization logic? With all its non-determinism and unpredictable behavior, the answer is more likely a hard “No”, unless we enforce two strict requirements:

  1. Provide a solid foundation — give the AI a robust library to work with.
  2. Test everything — all AI-generated code must be rigorously tested.

With those guidelines in place, I decided to give it a shot. After a few late nights, and honestly, way more fun than expected, I ended up building mus-skill: an AI skill for generating MUS serialization code.

At its core, the skill is just a set of rules for combining the serialization primitives provided by the mus and mus-stream libraries. In addition to the code itself, it also generates the accompanying tests so you can be sure everything works correctly.

Because the code looks exactly like the output of a traditional code generator you can expect from it the same high-performance.

|     NAME     |  NS/OP   | B/SIZE |  B/OP   | ALLOCS/OP |
|--------------|----------|--------|---------|-----------|
| mus          |   102.90 |  58.00 |   48.00 |         1 |
| protobuf     |   531.70 |  69.00 |  271.00 |         4 |
| json         |  2779.00 | 150.00 |  600.00 |         9 |

Full benchmarks https://github.com/ymz-ncnk/go-serialization-benchmarks

This approach even works flawlessly on deeply nested, complex types (where AI usually hallucinates), such as:

// mus:vl = ValidateLen
// mus:elemVl = ValidateComplexMapValue
type ComplexMap map[string]map[*[]int][][]float32

And supports user hints, so you can easily customize the generated code to fit your exact needs (like specifying custom validators).

Getting started is simple. Just clone this repository into your project’s agent directory (e.g., .agents/skills). Or, even easier, install it using the skills CLI tool:

npx skills add github.com/mus-format/mus-skill-go

Once installed, simply give your AI agent a prompt like this:

Generate MUS serializers for the types found in the <file_name>.go file.

The result? Two newly generated files: mus.ai.gen.go and mus.ai.gen_test.go. As always, just be sure to double-check that the generated tests actually cover all your edge cases.

Have you ever tried a similar approach? I’d love to hear how it went for you!

When Chrome Ate My RAM: Designing a Pressure-Aware Tab Orchestrator with Rust

Chrome wasn’t “crashing.”

It was just…slowly suffocating my system.

Over time, RAM usage would creep up. Background tabs accumulated state. Other applications started freezing. The fan would spin up. And yet, nothing looked obviously wrong. No single tab was the culprit.

The problem wasn’t too many tabs.
The problem was a lack of coordination between the browser and the system.
So I built something to experiment with that idea.

This article explains the architecture and reasoning behind a hybrid Chrome extension & Rust native host that manages tab lifecycle based on real system pressure and user context.

The Problem: Browser Entropy

Modern browsers are operating systems.

They manage:

  • Dozens of isolated processes
  • Background timers
  • Network activity
  • Memory-heavy applications (Jira, GitHub, Gmail, ChatGPT, Claude 😊 etc.)

Most tab suspension tools rely on a simple rule:

“If a tab hasn’t been used in X minutes, suspend it.”

That’s convenient, but blind.

They don’t know:

  • Whether the system is under memory pressure

  • Whether CPU is spiking

  • Whether you’re on battery

  • Whether the tab is part of your active workflow

They operate on time, not state.

What I wanted was:

A deterministic, pressure-aware, context-sensitive lifecycle engine.

Not AI. Not cloud analytics. Just a well-structured system.

Design Goals

Before writing any code, I defined constraints:

  • Deterministic behavior (no black-box magic)

  • No cloud, no telemetry

  • Respect user intent (never discard active or pinned tabs)

  • Pressure-aware decisions

  • Context-aware heuristics

  • Clean separation of responsibilities

This last one became the most important architectural decision.

Architecture Overview

The system consists of two components:

Chrome Extension (MV3)
  - Tab activity tracking
  - Focus clustering
  - TTL gating & guardrails
        ↓ Native Messaging
Rust Native Host
  - System metrics (RAM, CPU, Battery)
  - Pressure scoring engine
  - Deterministic classification

Why split it?

Chrome extensions cannot access low-level system metrics like real memory pressure in a reliable way.

So I separated concerns:

  • The extension manages browser lifecycle.

  • The Rust native host understands system state.

They communicate through Chrome’s Native Messaging API.

This keeps the system clean:

  • Browser logic stays in the browser.

  • System logic stays native.

The Pressure Engine (Rust)

Instead of checking raw RAM percentage, I built a weighted pressure scoring model.

The Rust host collects:

  • Total RAM
  • Used RAM
  • Free RAM
  • CPU usage
  • Battery state (if available)

From these, it computes:

  • pressure_score (0-100)
  • pressure_level (LOW / MEDIUM / HIGH)
  • pressure_reasons (RAM_HIGH, CPU_ELEVATED, ON_BATTERY, etc.)

RAM is the dominant signal.
CPU acts as a modifier.
Battery adds a small aggressiveness bias.

The goal is not to be perfect, it’s to be consistent and explainable.

Instead of saying:

“System busy.”

It says:

HIGH pressure because RAM_HIGH + ON_BATTERY.

That reason tagging matters for transparency.

Context Awareness – Focus Clustering

Not all inactive tabs are equal. A tab opened 30 minutes ago in your active workflow is very different from a forgotten tab in another window.

So I introduced Focus Mode.

Focus clustering is based on:

  • Same hostname as active tab
  • Recent activity window
  • Same window constraint
  • Cluster size cap

Tabs inside the active “cluster” use a longer TTL.Tabs outside the cluster expire faster under pressure. This makes the system:

  • Less disruptive
  • More aligned with user context
  • Less likely to discard something you’ll immediately need

It’s still deterministic, but just smarter.

Guardrails & Safety

Aggressive resource management can easily become destructive. So, strict guardrails were built in:

  • Never discard active tabs
  • Never discard pinned tabs
  • Never discard audible tabs
  • Respect protected domains
  • Enforce TTL minimums
  • Apply cooldown between prune cycles

This prevents oscillation and surprise behavior. The goal is not maximum efficiency. The goal is controlled stability.

Why Rust?

Rust was chosen for the native host because:

  • Memory safety
  • Explicit modeling
  • Strong type system
  • Clean modular architecture
  • Lightweight binary

The Rust side is structured into modules:

  • metrics, system state collection
  • battery, optional battery signal
  • pressure, scoring logic
  • protocol, native messaging transport
  • state, API contract

This makes the native host feel like a real subsystem, not a script.

What It Achieves

In practice, this system:

  • Reduces RAM pressure under load
  • Keeps active workflows intact
  • Makes browser behavior predictable
  • Avoids blind “time-based” suspension
  • Plays nicer with other system applications

It doesn’t eliminate memory usage. It orchestrates it.

What I Learned

A few things stood out during this project:

1. MV3 Service Workers Have Quirks

Extension background scripts are ephemeral. State management must be deliberate.

2. Determinism Beats “Smartness”

Clear, explainable rules feel safer than opaque heuristics.

3. Separation of Concerns Changes Everything

Keeping system logic in Rust and browser logic in the extension made experimentation much easier.

4. Observability Matters

Reason tagging and structured logging made debugging and tuning far easier.

Future Directions

This project is still evolving. Some experimental directions:

  • Event-driven pressure signals (instead of polling)
  • Chrome process memory integration
  • Predictive return probability modeling
  • Offline data analysis of tab lifecycle patterns
  • Adaptive TTL tuning

The architecture supports these without becoming tangled.

That was intentional.

Conclusion

Chrome didn’t have a bug. It was just operating without coordination. By introducing a pressure-aware, context-sensitive orchestration layer, the browser becomes less chaotic and more cooperative with the system.

This project started as frustration with RAM usage. It turned into an exploration of how browsers and operating systems can communicate more intelligently, without AI hype, and without cloud dependencies.

Just clean architecture and deterministic policy!

Checkout the project here:
Github: https://github.com/tase-nikol/tab-memory-orchestrator

Sometimes the problem isn’t that a system is broken
It’s that its parts aren’t talking to each other.

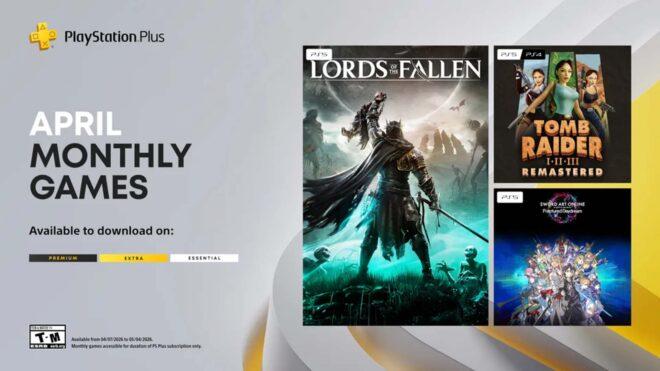
Yeni PlayStation Plus oyunları açıklandı [1 Nisan]

PlayStation Plus

PlayStation PlusSony bugün nisan ayının PlayStation Plus oyunlarını açıkladı. Aboneler için 7 Nisan’da aktif edilecek oyunlar; Lords of the Fallen, Tomb Raider I–III Remastered ve Sword Art Online: Fractured Daydream olarak duyuruldu. Şirket, mart ayında PGA Tour 2K25, Monster Hunter Rise, Slime Rancher 2 ve The Elder Scrolls Online Collection: Gold Road oyunlarını vermişti. Bu oyunların 6 Nisan tarihine kadar kütüphanelere eklenebileceği aktarıldı.

Yeni PlayStation Plus oyunları açıklandı [1 Nisan] yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Exception Handling Keywords in Java

What is an Exception?
An exception is an unwanted event that occurs during program execution.

Example:
Dividing a number by zero
Accessing null object
File not found

1. try Block
The try block contains code that may cause an exception.

Syntax:
      try {
// risky code
 }

Example:

try {
    int a = 10 / 0; // exception
}

Where we use:
–> Database operations
–> File handling
–> Network calls

2. catch Block
The catch block handles the exception thrown in the try.

  Syntax:
       catch(Exception e) {
// handling code
   }

Example:

try {
    int a = 10 / 0;
} catch (ArithmeticException e) {
    System.out.println("Cannot divide by zero");
}

Where we use:
–> To show user-friendly messages
–> To prevent program crash

3. finally Block
The finally block always executes whether an exception occurs or not.

Syntax:
    finally {
// cleanup code
   }

Example:

try {
    int a = 10 / 2;
} catch (Exception e) {
    System.out.println("Error");
} finally {
    System.out.println("Always executed");
}

Real-time use:
–> Closing database connection
–> Closing files
–> Releasing resources

4.throw Keyword
Used to manually throw an exception.

Syntax:
     throw new Exception("message");

Example:

public class Main {
    public static void main(String[] args) {
        int num = -5;

        if (num < 0) {
            throw new ArithmeticException("Negative number not allowed");
        }

        System.out.println("Valid number");
    }
}

Where we use:
–> Custom validations
–> Business rules (e.g., age restriction)

5. throws Keyword
Used to declare exceptions in method signature.

Syntax:
   void method() throws Exception {
// code
  }

Example:

import java.io.*;

class Test {
    void readFile() throws IOException {
        FileReader file = new FileReader("test.txt");
    }
}

Where we use:
–> File handling
–> Checked exceptions
–> Passing responsibility to caller

I Replaced 5 State Website Scrapers with One API Call

I Replaced 5 State Website Scrapers with One API Call

If you’ve ever had to verify a contractor or nurse license, you know the pain. Each state has its own website, its own search form, its own output format. California’s CSLB looks nothing like Texas’s TDLR, which looks nothing like Florida’s DBPR.

I was building a compliance tool for a staffing platform and kept writing throwaway scrapers for each state. After the third one broke because a state board redesigned their site, I just built an API that normalizes all of them.

Here’s the before/after.

The Manual Way (Per State)

For California contractors, you’d go to the CSLB site, fill out a form, parse the HTML response. For Texas, it’s TDLR with a completely different flow. Florida? DBPR, another UI.

Each state takes 5-10 minutes to look up manually. If you’re verifying 50 contractors for a construction company, that’s 4+ hours of tab-switching.

And if you’re doing it programmatically? You need a separate scraper for each state, each with its own selectors, error handling, and maintenance burden.

The API Way

One REST call, same JSON schema regardless of state:

curl "https://your-api/contractor-license/verify?state=CA&licenseNumber=1096738"
{
  "results": [
    {
      "state": "CA",
      "licenseNumber": "1096738",
      "businessName": "Pacific Construction Inc",
      "personName": "John Smith",
      "licenseStatus": "Active",
      "licenseType": "General Building Contractor",
      "expirationDate": "2026-12-31",
      "city": "Los Angeles"
    }
  ],
  "count": 1,
  "processingMs": 4523
}

Same call for Texas:

curl "https://your-api/contractor-license/verify?state=TX&name=Smith"

Same JSON schema. Same field names. No per-state logic in your app.

Nurse Licenses Too

The same API handles nurse credential verification:

curl "https://your-api/nurse-license/verify?state=FL&lastName=Johnson"
{
  "results": [
    {
      "state": "FL",
      "licenseNumber": "RN9876543",
      "personName": "Sarah Johnson",
      "licenseStatus": "Active - Clear",
      "licenseType": "Registered Nurse",
      "expirationDate": "2027-04-30"
    }
  ]
}

This matters for healthcare staffing platforms and credentialing departments that need to verify both trade licenses (contractors, electricians) and healthcare credentials (nurses, therapists) — normally two completely separate verification workflows.

Time Savings Breakdown

Task Manual API
Single license lookup 5-10 min 3-5 sec
50 contractor verifications 4+ hours 2 minutes (batch)
Adding a new state Build new scraper (days) Already supported
Handling site redesign Fix broken scraper API maintainer handles it

The real value isn’t the individual lookup speed — it’s the maintenance burden. State websites change their markup regularly. Someone has to keep those scrapers working.

Building a Compliance Workflow

Here’s a simple Node.js script that checks license status for a list of contractors:

const contractors = [
  { state: 'CA', licenseNumber: '1096738' },
  { state: 'TX', name: 'Smith Construction' },
  { state: 'FL', licenseNumber: 'CBC1234567' },
];

const results = await Promise.all(
  contractors.map(async (c) => {
    const params = new URLSearchParams(c);
    const res = await fetch(
      `https://your-api/contractor-license/verify?${params}`,
      { headers: { 'X-Api-Key': process.env.API_KEY } }
    );
    return res.json();
  })
);

const expired = results
  .flatMap(r => r.results)
  .filter(r => r.licenseStatus !== 'Active');

if (expired.length > 0) {
  console.log('⚠️ Expired/inactive licenses:', expired);
  // Send alert to compliance team
}

Runs on a daily cron, alerts your team when anything expires. Total code: ~20 lines.

What States Are Supported?

Currently: California (CSLB), Texas (TDLR), Florida (DBPR), and New York (NYC Open Data) for contractors. Florida (DOH) and New York (NYSED) for nurses.

More states are being added — the normalization layer means new states slot in without changing your integration code.

I built this because I needed it for my own projects. It’s on RapidAPI if you want to try it — free tier included.

Monitor Insider Trading Without Parsing SEC XML — Form 4 Data as Clean JSON

Monitor Insider Trading Without Parsing SEC XML — Form 4 Data as Clean JSON

SEC Form 4 filings are one of the most useful public datasets for tracking what company insiders (CEOs, directors, 10% owners) are doing with their stock. When a CEO buys 50,000 shares of their own company, that’s a signal.

The problem: getting this data from SEC EDGAR is genuinely painful.

The EDGAR Problem

EDGAR serves filings as nested XML/SGML documents. There’s no proper REST API for structured Form 4 data. Here’s what you’re dealing with:

  1. CIK-based lookups: You need to map ticker symbols to CIK numbers (EDGAR’s internal ID system)
  2. Full-text search returns everything: Searching for “AAPL” returns all 100+ filing types — 10-Ks, 8-Ks, proxies — not just insider trades
  3. XML parsing: Form 4 filings use XBRL/XML with nested schemas. The actual transaction data is buried inside <nonDerivativeTransaction> and <derivativeTransaction> elements
  4. No pagination or filtering: EDGAR’s XBRL feeds dump everything. You build the filtering logic

Most developers spend 2-3 days just getting the XML parsing right before they can extract a single transaction.

Skip the XML

I built an API that does all the EDGAR parsing and returns clean JSON. Here’s what a Form 4 query looks like:

curl "https://your-api/sec/insider-trades?ticker=AAPL&limit=5"
{
  "success": true,
  "total": 1542,
  "filings": [
    {
      "accession": "0000950123-26-001456",
      "filedDate": "2026-03-31",
      "periodOfReport": "2026-03-27",
      "insider": {
        "name": "Cook Timothy D",
        "cik": "0001234567"
      },
      "company": {
        "name": "APPLE INC",
        "cik": "0000320193"
      }
    }
  ]
}

Get full transaction details for any filing:

curl "https://your-api/sec/insider-trades/filing/0000950123-26-001456"
{
  "issuer": {
    "cik": "0000320193",
    "name": "APPLE INC",
    "ticker": "AAPL"
  },
  "owner": {
    "name": "Cook Timothy D",
    "isDirector": true,
    "isOfficer": true,
    "title": "Chief Executive Officer"
  },
  "transactions": [
    {
      "security": "Common Stock",
      "date": "2026-03-25",
      "code": "P",
      "codeLabel": "Purchase",
      "shares": 50000,
      "pricePerShare": 178.50,
      "sharesAfter": 3500000,
      "ownership": "direct"
    }
  ]
}

Ticker-based search (no CIK mapping needed), pre-filtered to Form 4 only, transactions parsed into flat JSON.

Building an Insider Trading Monitor

Here’s a Python script that checks for insider purchases above $100K:

import requests
from datetime import datetime, timedelta

API_URL = "https://your-api/sec/insider-trades"
API_KEY = "your-api-key"
WATCHLIST = ["AAPL", "MSFT", "GOOGL", "AMZN", "TSLA"]

headers = {"X-Api-Key": API_KEY}
yesterday = (datetime.now() - timedelta(days=1)).strftime("%Y-%m-%d")

for ticker in WATCHLIST:
    resp = requests.get(
        API_URL,
        params={"ticker": ticker, "startDate": yesterday},
        headers=headers,
    )
    data = resp.json()

    for filing in data.get("filings", []):
        # Get full transaction details
        detail = requests.get(
            f"{API_URL}/filing/{filing['accession']}",
            headers=headers,
        ).json()

        for tx in detail.get("transactions", []):
            if tx["code"] == "P":  # Purchase
                value = tx["shares"] * tx["pricePerShare"]
                if value > 100_000:
                    print(
                        f"🚨 {detail['owner']['name']} "
                        f"({detail['owner'].get('title', 'Insider')}) "
                        f"bought {tx['shares']:,} shares of {ticker} "
                        f"at ${tx['pricePerShare']:.2f} "
                        f"(${value:,.0f} total)"
                    )

Run this on a daily cron and you’ve got an insider trading alert system. The code is ~30 lines because all the hard work (XML parsing, CIK resolution, filing filtering) is handled by the API.

Transaction Codes Explained

Form 4 transactions use single-letter codes:

Code Meaning Signal
P Open market purchase Bullish — insider buying with own money
S Open market sale Could be planned (10b5-1) or discretionary
A Grant/award Compensation, not a market signal
M Option exercise Converting options to shares
F Tax withholding Automatic, not discretionary
G Gift Estate planning, not a trading signal

The most interesting transactions are P (purchases) and S (sales) — these represent discretionary decisions by insiders.

What You’d Build Without This

For context, here’s what the DIY version looks like:

  1. Build a CIK-to-ticker mapping table (SEC provides a bulk file, ~13,000 companies)
  2. Write an EDGAR full-text search query parser
  3. Build XML/SGML parsers for Form 4 documents (two different schemas depending on filing date)
  4. Handle XBRL footnotes, amendments (Form 4/A), and derivative transactions
  5. Implement rate limiting (SEC throttles to 10 req/sec with a required User-Agent header)
  6. Build storage and deduplication logic

That’s a week of work minimum, plus ongoing maintenance when EDGAR changes their schema.

I vibe coded this for my own trading research. It’s on RapidAPI — free tier if you want to poke around.

Web Scraping Is Dead. Web Agents Just Replaced It.

The market research experience — 40 tabs and a messy spreadsheet

Last month, I needed to pull together a competitive landscape report. Nothing exotic — pricing trends, feature comparisons, market positioning across about 30 to 40 industry sites and competitor pages.

Sounds manageable, right? Here’s what actually happened.

Half the sites loaded data dynamically — you scroll down, content appears, but view-source shows empty divs. A few required creating accounts just to see pricing. Others buried the good stuff behind three layers of filters and dropdown menus. And two sites hit me with CAPTCHAs the moment I tried to load them in an automated way.

I did what I always do: opened 40 Chrome tabs, spent two days copying and pasting into a spreadsheet, and ended up with a document that was already going stale by the time I finished formatting it.

That experience sent me down a rabbit hole. What I found changed how I think about web automation entirely.

The market research experience — 40 tabs and a messy spreadsheet

Why Traditional Scraping Doesn’t Cut It Anymore

Look, I’m not here to trash Beautiful Soup or Scrapy. If your target is a handful of static HTML pages that rarely change, those tools still work beautifully. No shame in using them. I still do for simple stuff.

But the web I was dealing with, the 2026 web, is a fundamentally different animal.

Most modern sites render content with JavaScript. Your scraper sends a request, gets back a skeleton of empty <div> tags, and has no idea that the actual data loads three seconds later through an API call triggered by a React component. Single-page apps mean the URL stays the same while the content changes entirely. Data hides behind interactive elements: filters, dropdowns, “load more” buttons, infinite scroll. And anti-bot systems have gotten genuinely sophisticated — they can tell the difference between a real browser with a real human behind it and a Python script pretending to be one.

Traditional scraping is like using a paper map in a city that redraws its streets every week. The map was accurate when you printed it. The city just didn’t care.

The problem isn’t that your code is bad. The problem is that the web wasn’t designed to be scraped. It was designed to be used — by humans, in browsers, with clicks and scrolls and waiting for things to load. And every year it gets better at enforcing that assumption.

So I started looking at what else is out there. The landscape has changed a lot more than I expected.

I Tried a Bunch of Tools. Here’s What Actually Happened.

Instead of just reading comparison articles, I spent a weekend actually testing different approaches against my real market research task. Here’s the honest breakdown.

Search APIs (Exa, Tavily)

I tried these first because they’re the fastest path to structured data. Give them a query, get back JSON with titles, snippets, and URLs. Some of them, like Exa, maintain their own semantic index that’s optimized for LLM consumption. Tavily focuses on research-grade search results. Both are impressive for what they do.

But I hit the wall pretty quickly. They surface what’s already been indexed and the data I needed wasn’t sitting on pages that Google had crawled. It was behind login walls, inside interactive dashboards, and loaded dynamically after user interaction.

My takeaway: search APIs are perfect for discovery — figuring out WHICH pages have the data you want. But they can’t go get it for you. It’s like asking a librarian which shelf a book is on. Helpful. But they can’t read it for you.

Content Extraction (Firecrawl)

Firecrawl was the logical next step. You give it a URL, it renders the JavaScript, and returns clean, structured content. It bridges the gap between “finding a page” and “reading a page.”

I liked it for known URLs where I just needed to pull the rendered content. But when I needed to interact with the page — click through filters, paginate through results, fill out a form to reveal pricing — it wasn’t built for that. It’s still reading, not doing.

Browser Agents (Browser Use, OpenAI Operator)

This is where things got genuinely interesting. These are AI systems that can actually navigate pages — clicking buttons, filling forms, interpreting what’s on screen and deciding what to do next.

Browser Use is open source and flexible. You can choose your own LLM, and their cloud offering means you’re not tying up your own machine. I was impressed by how well the AI reasoned about page layouts.

OpenAI Operator has a polished interface and feels smooth for single-task workflows. Good for “go to this site and do this thing.”

But here’s where I ran into friction: I needed to run the same basic task across 30+ sites. Not one site at a time. All of them, ideally in parallel. Orchestrating that myself — managing sessions, handling failures, collecting structured output — started feeling like I was building infrastructure rather than doing research.

Remote Web Agent Platforms (TinyFish, Browserbase)

This is the category I didn’t know existed until I went looking.

Browserbase is impressive cloud browser infrastructure. They spin up headless browsers at scale and handle the hard parts — proxies, anti-detection, session management. But it’s fundamentally an infrastructure layer. You connect your own automation code to their browsers. Powerful for teams that want full control, but you’re still writing the agent logic yourself.

Then I tried TinyFish. You give it a URL and a goal in plain English. It gives you structured JSON back. No selectors. No Playwright scripts. No browser management. I didn’t have to think about HOW to navigate each site — just WHAT I wanted from it.

That felt fundamentally different. Not a better scraper. Not a fancier browser automation. A different way of thinking about the problem.

The web automation spectrum — from search APIs to remote web agent platforms

Now, I want to be clear about something: every tool I tried has its sweet spot. Exa is fantastic for semantic search. Firecrawl is great for clean content extraction from known URLs. Browser Use gives you maximum flexibility with open-source transparency. Browserbase is the right call if your team wants to build custom agent infrastructure.

I’m not saying TinyFish is the only answer. I’m saying that the experience of “describe what you want, get it back” was the thing that made me rethink the whole approach. It was the moment I realized web automation might be going through the same kind of shift that happened when we went from writing assembly to writing in high-level languages. The abstraction layer matters.

The Real Shift: From “Automate Clicks” to “Describe Goals”

Here’s the idea that stuck with me after trying all of this.

The old way to automate the web was procedural. You’d write something like: “Navigate to this URL. Find the element with class price-card. Click the dropdown labeled ‘Enterprise’. Wait 2 seconds. Extract the text from the element with ID annual-price.”

Every single step is hard-coded. Change the class name? It breaks. Add a cookie banner that overlays the dropdown? It breaks. Redesign the page? Everything breaks.

The new approach is goal-oriented. You say: “Go to this company’s pricing page. Find the enterprise annual price. Return it as JSON.”

The agent figures out the how. You only specify the what.

Procedural automation vs goal-oriented: the fundamental shift

This might sound like a small difference. It isn’t. It’s the difference between giving a taxi driver turn-by-turn directions versus giving them an address. If the road is closed, turn-by-turn fails — the driver is stuck at the non-existent left turn. But if you gave them the destination, they just find another route. The goal hasn’t changed. Only the path.

And it changes who can automate web tasks. You don’t need to understand the DOM, write XPath expressions, or manage headless browser sessions. You need to be able to describe what you want. For someone like me — technical enough to understand what’s happening under the hood, but not wanting to maintain Playwright infrastructure for a market research project — this shift feels overdue.

Why I Kept Digging Into This

After my initial test, I got curious about TinyFish’s thinking. Not as a customer evaluating a purchase, more like a nerd who found something interesting and wanted to understand why it worked differently.

Their blog has this argument that I keep coming back to: search engines only index about 5% of online content. The other 90% or more sits behind logins, forms, dynamic interfaces, and interactive workflows. It’s not hidden in the sense that it’s secret. It’s hidden because you have to interact with a website to reveal it.

The iceberg of web data — search engines only see about 5%

That matched my experience exactly. The market data I needed wasn’t hard to find. I could see it in my browser just fine. It was hard to extract programmatically without writing a fragile script for every single site.

I’ve only scratched the surface of what their platform can do, but the way they frame the problem — that the web needs to be operated on, not just searched or scraped, resonates with what I experienced firsthand.

Where This Is All Going: WebMCP

One more thing worth mentioning, because it signals where this whole space is heading.

Google and Microsoft are jointly developing a new W3C standard called WebMCP (Web Model Context Protocol) that would let websites publish structured tools directly for AI agents. Instead of agents having to visually interpret a page — taking screenshots, parsing the DOM, guessing where to click — a site could expose a function like get_pricing({ plan: "enterprise" }) that agents call directly through a new browser API called navigator.modelContext.

(Quick note for the confused: WebMCP is not the same thing as Anthropic’s MCP. Anthropic’s MCP connects AI agents to backend services. WebMCP is a browser-native standard that connects agents to web page interfaces. Different protocols, complementary purposes. The naming is confusing — I know.)

Think of it this way: instead of making a delivery robot squint at a restaurant’s chalkboard menu from across the room, you hand it a structured list of dishes and prices. Same information. Completely different efficiency.

But this is still extremely early. Most sites won’t support it for years. And the sites that most need automation — legacy portals, government systems, enterprise SaaS with no API — are precisely the ones least likely to adopt it quickly. But it signals a future where the web isn’t just built for human eyes. It’s becoming readable by agents too.

What I’m Doing Next

The web automation landscape has genuinely shifted. “Scraping” as I knew it — writing brittle selector-based scripts — is being replaced by something more like “describing what you want and getting it back.”

You don’t have to throw out your working scripts overnight. Start with the workflows that break most often. The ones that cost you a day of copy-pasting every month. Those are your candidates for a different approach.

I’m planning to take this further: pick a real market research workflow I currently handle manually, run it through a proper hands-on test, and write up exactly what happens. The good, the bad, and the weird. Stay tuned for that.

If you’ve been fighting with web scrapers, I’d love to hear what’s worked for you — and what hasn’t. Drop a comment below.

Further reading if you want to go deeper: