iPhone 17e vs Galaxy S26: Ucuz iPhone mu, güçlü Android mi?
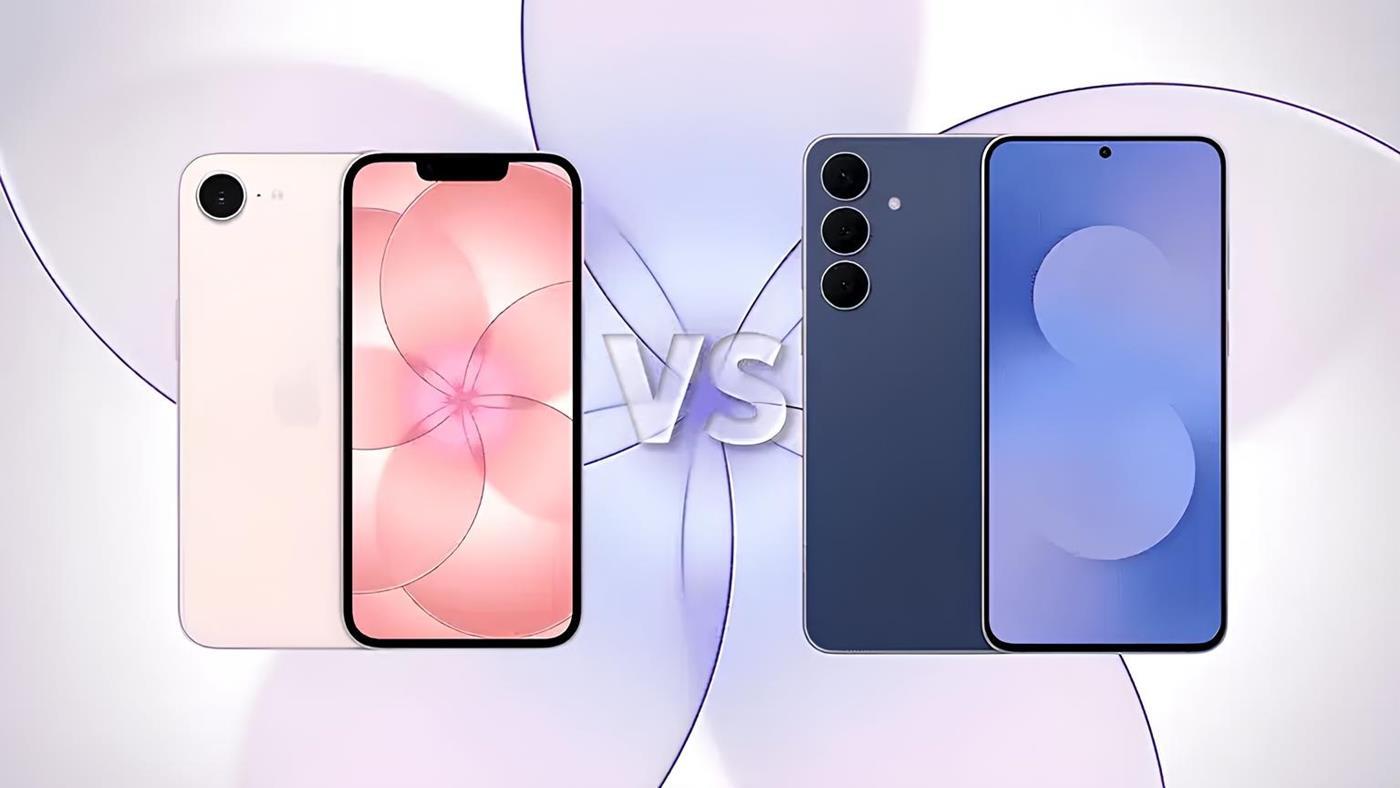
 Akıllı telefon pazarında rekabet artık sadece en güçlü modeli seçmekten ibaret değil. Peki Galaxy S26, iPhone 17e karşısında neler sunuyor? İşte Galaxy S26 vs iPhone 17e.

 Mert
Akıllı telefon pazarında rekabet artık sadece en güçlü modeli seçmekten ibaret değil. Peki Galaxy S26, iPhone 17e karşısında neler sunuyor? İşte Galaxy S26 vs iPhone 17e.
 Roblox yetkileri, Ulaştırma ve Altyapı Bakanlığı’nı ziyaret ederek çocukların platformdaki güvenliği hakkında kapsamlı değerlendirme toplantısı yaptı. Roblox yasağı yakında kalkabilir.
 Playstation kullanıcılarına sunulan abonelik servisi Playstation Plus’ın Nisan ayındaki ücretsiz oyunları belli oldu. İşte PS Plus abonelerine Nisan’da sunulacak ücretsiz oyunlar…

java
public class Main {
    public static void main(String[] args) {
        int num = 1234, sum = 0;

        while (num > 0) {
            sum += num % 10;
            num /= 10;
        }

        System.out.println("Sum = " + sum);
    }
}
output

2. Count of Digits
java
public class Main {
    public static void main(String[] args) {
        int num = 1234, count = 0;

        while (num > 0) {
            count++;
            num /= 10;
        }

        System.out.println("Count = " + count);
    }
}
output

3. Reverse a Number
 public class Main {
    public static void main(String[] args) {
        int num = 1234, rev = 0;

        while (num > 0) {
            int digit = num % 10;
            rev = rev * 10 + digit;
            num /= 10;
        }

        System.out.println("Reverse = " + rev);
    }
}
output

This is Day 6 of my 100 Days to Senior Android Engineer series. Each post: what I thought I knew → what I actually learned → interview implications.
🔍 The concept
Context is one of those Android classes you use dozens of times per day without thinking about it. You pass it to constructors, use it to inflate views, start activities, access resources.
But Context isn’t one thing — it’s a family of related objects with very different lifetimes. Pass the wrong one into a long-lived object, and you’ve just anchored that object to a screen that the user may have left minutes ago. The screen can’t be garbage collected. You’ve created a memory leak.
Not a theoretical one. A real one that affects every user who navigates back to that screen.
💡 What I thought I knew
My rule of thumb used to be: “Use applicationContext when in doubt.”
That’s not wrong exactly — applicationContext won’t leak. But it’s incomplete, and applying it blindly causes a different class of bugs: UI operations that crash, theme-aware resources that return wrong values, dialogs that fail to show.
The full picture is more nuanced, and more interesting.
😳 What I actually learned
What Context actually is
Context is an abstract class that provides access to application-level resources and operations:
Context (abstract)
  ├── ContextWrapper
  │     ├── Application        ← lives as long as the process
  │     ├── Activity           ← lives as long as the screen
  │     └── Service            ← lives as long as the service
  └── ContextImpl              ← the real implementation, hidden from you
Every Activity is a Context. Every Application is a Context. They wrap the same underlying ContextImpl but expose different capabilities and, critically, have different lifetimes.
The lifetime mismatch that causes leaks
The classic pattern that causes a leak:
// ❌ Singleton holding an Activity Context
object ImageLoader {
    private lateinit var context: Context

    fun init(context: Context) {
        // If caller passes an Activity, this singleton now holds
        // a reference to that Activity for the lifetime of the process
        this.context = context
    }
}

// In Activity:
override fun onCreate(savedInstanceState: Bundle?) {
    super.onCreate(savedInstanceState)
    ImageLoader.init(this)  // 💀 leaking 'this' into a singleton
}
The singleton lives forever. It holds the Activity. The Activity holds its entire view hierarchy — every View, every Bitmap, every Drawable. None of it can be garbage collected.
Rotate the screen twice and you have three leaked Activity instances, each holding their full view hierarchy in memory.
The fix is one word:
fun init(context: Context) {
    this.context = context.applicationContext  // ✅ survives rotation, no leak
}
applicationContext has the same lifetime as the process. No Activity is held. No leak.
But applicationContext isn’t always correct
Here’s where my old rule of thumb breaks down. applicationContext doesn’t have a theme. It doesn’t know which Activity it’s in. For operations that depend on the UI context, it either crashes or silently returns wrong results.
// ❌ Inflating a view with applicationContext — theme attributes broken
val view = LayoutInflater.from(applicationContext).inflate(R.layout.my_view, null)
// Colors from ?attr/colorPrimary, ?attr/textAppearanceBody1, etc. — all wrong

// ✅ Inflate with Activity context — theme attributes resolved correctly
val view = LayoutInflater.from(this).inflate(R.layout.my_view, null)
// ❌ Showing a Dialog with applicationContext — crashes on API 23+
AlertDialog.Builder(applicationContext)  // throws WindowManager$BadTokenException
    .setMessage("Are you sure?")
    .show()

// ✅ Show Dialog with Activity context
AlertDialog.Builder(this)
    .setMessage("Are you sure?")
    .show()
// ❌ Starting an Activity from applicationContext without NEW_TASK flag — crashes
applicationContext.startActivity(Intent(applicationContext, DetailActivity::class.java))
// throws AndroidRuntimeException: Calling startActivity() from outside of an Activity context

// ✅ With the required flag
applicationContext.startActivity(
    Intent(applicationContext, DetailActivity::class.java).apply {
        flags = Intent.FLAG_ACTIVITY_NEW_TASK
    }
)
The decision table
After going through the docs carefully, this is the table I now keep in my head:
| Operation | Application Context | Activity Context |
|---|---|---|
| Start an Activity | ⚠️ needs NEW_TASK flag |
✅ |
| Start a Service | ✅ | ✅ |
| Send a Broadcast | ✅ | ✅ |
| Load a resource (string, drawable) | ✅ | ✅ |
| Inflate a layout with theme | ❌ wrong theme | ✅ |
| Show a Dialog | ❌ crashes | ✅ |
| Create a ViewModel | ❌ | ✅ |
| Initialize a singleton / library | ✅ | ❌ leaks |
| Access SharedPreferences | ✅ | ✅ |
Get system services (e.g. ClipboardManager) |
✅ | ✅ |
The pattern: anything UI-related needs Activity context. Anything that lives longer than a screen needs Application context.
The this vs requireContext() vs requireActivity() confusion in Fragments
Fragments add another layer of confusion because they’re not a Context themselves — they have a context.
class MyFragment : Fragment() {

    override fun onViewCreated(view: View, savedInstanceState: Bundle?) {

        // 'this' — the Fragment, NOT a Context
        // Can't be passed where Context is expected

        // requireContext() — the Activity context (or throws if detached)
        val prefs = requireContext().getSharedPreferences("prefs", Context.MODE_PRIVATE)

        // requireActivity() — explicitly the Activity, useful when you need
        // Activity-specific APIs like ViewModelProvider, window insets, etc.
        val windowInsetsController = requireActivity().window.insetsController

        // context — nullable version of requireContext(), safe if you check
        context?.let { ctx ->
            Toast.makeText(ctx, "Hello", Toast.LENGTH_SHORT).show()
        }
    }
}
The practical rule in Fragments: use requireContext() for Context needs, requireActivity() only when you specifically need the Activity. The difference matters if you ever move the Fragment to a different host.
The WeakReference anti-pattern
You’ll sometimes see this pattern as an attempted fix for Context leaks:
class SomeManager(context: Context) {
    // "I'll use WeakReference so I don't leak"
    private val contextRef = WeakReference(context)

    fun doSomethingWithUI() {
        val ctx = contextRef.get() ?: return
        // use ctx
    }
}
This is better than holding a strong reference, but it’s still wrong for different reasons:
WeakReference that’s been collected gives you null at an unpredictable time — leading to silent no-ops or hard-to-reproduce bugs.applicationContext anyway.WeakReference<Context> is almost never the right answer. It papers over the real issue: the object’s lifetime is incompatible with the context’s lifetime. Fix the lifetime problem instead.
The ContextThemeWrapper you didn’t know you were using
When you write LayoutInflater.from(activity), you get a LayoutInflater that uses the Activity’s theme. But sometimes you need to inflate a view with a different theme than the current Activity — for example, inflating a dark-themed bottom sheet inside a light-themed Activity.
// Inflate with a custom theme, without changing the Activity's theme
val themedContext = ContextThemeWrapper(requireContext(), R.style.ThemeOverlay_App_BottomSheet)
val inflater = LayoutInflater.from(themedContext)
val view = inflater.inflate(R.layout.bottom_sheet_content, container, false)
ContextThemeWrapper wraps any Context and overlays a theme on top. Compose’s MaterialTheme uses this mechanism internally when you apply a LocalContentColor or a theme override. Knowing it exists saves you from the wrong solution — changing the Activity theme globally just to style one component.
🧪 The rule of thumb that actually works
Instead of “use applicationContext when in doubt”, the rule I use now:
Match the context’s lifetime to the consumer’s lifetime.
applicationContext
requireContext(), which gives you the host Activity’s context
// Checklist before passing context anywhere:
// 1. How long does the receiver live?
// 2. What operations will it perform with the context?
// 3. Does its lifetime match the context's lifetime?

// If receiver is longer-lived → applicationContext
// If receiver needs UI → Activity context, manage its lifecycle
❓ The interview questions
Question 1 — Mid-level:
“What’s the difference between
this,applicationContext, andbaseContextin an Activity?”
this — the Activity itself, which is a Context. Full UI capabilities, lifetime tied to the Activity.applicationContext — the Application object. No UI capabilities, lives as long as the process.baseContext — the wrapped ContextImpl inside the ContextWrapper. Rarely used directly; it’s the raw context before any wrapper applies its logic. Calling baseContext from an Activity skips the Activity’s own context wrapper logic — almost never what you want.Question 2 — Senior:
“You’re building an SDK that other apps will integrate. Your SDK has a singleton that needs to perform operations like loading resources and starting a background service. How do you handle Context?”
class MySdk private constructor(private val appContext: Context) {

    companion object {
        @Volatile private var instance: MySdk? = null

        fun init(context: Context): MySdk {
            return instance ?: synchronized(this) {
                instance ?: MySdk(
                    // Always store applicationContext — the caller's Activity
                    // will be destroyed; the SDK must outlive it
                    context.applicationContext
                ).also { instance = it }
            }
        }
    }

    fun loadResource(): String {
        // ✅ Resources work fine with applicationContext
        return appContext.getString(R.string.sdk_label)
    }

    fun startBackgroundWork() {
        // ✅ Starting a Service works with applicationContext
        appContext.startService(Intent(appContext, SdkSyncService::class.java))
    }

    fun showDialog(activity: Activity) {
        // ✅ For UI operations, require the caller to pass Activity explicitly
        // Don't store it — just use it for this operation
        AlertDialog.Builder(activity)
            .setMessage("SDK needs permission")
            .show()
    }
}
Key points: always store applicationContext in the singleton, never the caller’s Activity. For UI operations, make them instance methods that take an Activity parameter rather than storing it.
Question 3 — Senior:
“LeakCanary reports a Context leak in your app, originating from a custom View. How do you diagnose and fix it?”
First, understand what LeakCanary is telling you: the Context (likely an Activity) is retained after it should have been garbage collected, because something is holding a reference to it.
For a custom View, the most common causes:
// Cause 1: Static reference to a View (which holds its Context)
companion object {
    var lastClickedView: View? = null  // 💀 holds Activity via view.context
}

// Cause 2: Anonymous listener registered on a long-lived object
class MyView(context: Context) : View(context) {
    init {
        EventBus.register(object : EventListener {  // 💀 anonymous class holds outer View
            override fun onEvent(event: Event) { /* ... */ }
        })
        // EventBus holds the listener, listener holds the View, View holds Context
    }
}

// Fix: use weak reference or unregister in onDetachedFromWindow
override fun onDetachedFromWindow() {
    super.onDetachedFromWindow()
    EventBus.unregister(listener)
}

// Cause 3: Context stored in a non-View object without applicationContext
class ImageCache(val context: Context) {  // 💀 if passed Activity context
    // ...
}
// Fix: ImageCache(context.applicationContext)
Diagnosis approach: read the LeakCanary reference chain bottom-up. The chain shows exactly which object is holding the reference that prevents GC. The fix is usually at the top of that chain — nulling a reference, unregistering a listener, or swapping to applicationContext.
What surprised me revisiting this
applicationContext for LayoutInflater doesn’t just look wrong — it silently breaks theme-dependent attributes without throwing an exception. Views inflate but render incorrectly. The kind of bug that shows up in screenshots and is hard to reproduce in isolation.
WeakReference<Context> is a false sense of security. I’ve written this pattern before and thought I was being careful. Going back through the theory, it just moves the problem rather than fixing it.
ContextThemeWrapper being the mechanism behind Compose’s LocalContentColor — I’d used Compose theme overrides for months without ever connecting it to the View system’s ContextThemeWrapper. The mental model clicked when I saw them as the same concept.
Tomorrow
Day 7 → Week 1 Recap — six posts in, and I’m already finding more gaps than I expected. A summary of the most important insights from this week, plus the one question I couldn’t answer confidently until now.
What’s the most surprising Context-related bug you’ve encountered? Drop it in the comments.
← Day 5: Intent, Task & Back Stack — Why launchMode Is a Trap
Why .NET 10’s AI-First Architecture Changes How We Build Software
The Most Intelligent .NET Release Yet
For years, .NET releases focused on performance improvements and language features. .NET 10 signals a fundamental shift: AI isn’t an add-on anymore — it’s infrastructure.
What’s Actually New in .NET 10
1. Copilot Coding Agent Natively Supported
The .NET team published their 10-month study using GitHub Copilot Coding Agent (CCA) in dotnet/runtime. The findings are striking:
This isn’t marketing — it’s production data from the team building the runtime itself.
2. Microsoft.Extensions.AI — The AI Middleware
// Before .NET 10
var client = new OpenAIClient(apiKey);
var response = await client.CompleteAsync(prompt);

// .NET 10 with Microsoft.Extensions.AI
services.AddAIBuilder()
    .UseOpenAI(apiKey)
    .BuildChatClient();

var response = await chatClient.CompleteAsync("Explain this code");
The same dependency injection patterns you use for databases and HTTP clients now work for AI services.
3. RAG Patterns Built-In
Retrieval-Augmented Generation is now a first-class citizen:
// Semantic search with vector embeddings
var embeddings = await embeddingGenerator.GenerateAsync(codeSnippets);
var results = await vectorStore.SearchAsync(embeddings, topK: 5);
var response = await chatClient.CompleteAsync(
    context: results.Context,
    prompt: userQuestion
);
4. Agent Framework Patterns
Building AI agents in .NET 10:
public class CodeReviewAgent : IAgent
{
    public async Task<AgentResponse> ProcessAsync(UserQuery query)
    {
        var context = await RetrieveContextAsync(query);
        var plan = await planner.CreatePlanAsync(query, context);
        return await executor.ExecuteAsync(plan);
    }
}
.NET Skills — Teaching AI to Think in C
The new dotnet/skills repository provides:
If you’re building AI-powered developer tools, this is the foundation.
.NET MAUI + AI: 50-70% Faster Issue Resolution
The MAUI team built custom AI agents that:
The result: half the time from “issue filed” to “fix merged.”
DO’s and DON’Ts for .NET 10 AI Features
✅ DO
Microsoft.Extensions.AI for all new AI integrations.NET Skills for your domain-specific agents ❌ DON’T
The Competitive Landscape
| Feature | .NET 10 | Node.js | Python |
|---|---|---|---|
| Native AI DI | ✅ | ❌ | ⚠️ |
| Agent Framework | ✅ | ❌ | ⚠️ |
| RAG Patterns | ✅ | ❌ | ✅ |
| Skills Repository | ✅ | ❌ | ❌ |
Real-World Use Case: AI-Assisted Code Review
A mid-sized team (15 developers) implemented .NET 10 AI features:
Conclusion
.NET 10 isn’t just an incremental release. It’s the first .NET version designed with the assumption that AI will write significant portions of your code.
Key Takeaways:
Microsoft.Extensions.AI brings DI patterns to AI servicesNext Steps:
Resources
Questions about .NET 10 AI features? Drop them below!
TL;DR: PyTorch’s DataLoader can be 50-124x slower than direct tensor indexing for in-memory GPU workloads. We reproduced a real PyTorch issue on an RTX 4090 and traced every CUDA API call and Linux kernel event to find the root cause. The GPU wasn’t slow – it was starving. DataLoader workers generated 200,000 CPU context switches and 300,000 page allocations in 40 seconds, leaving the GPU waiting an average of 301ms per data transfer that should take microseconds.
The Problem
A PyTorch user reported that DataLoader was 7-22x slower than direct tensor indexing for a simple MLP inference workload. Even with num_workers=12, pin_memory=True, and prefetch_factor=12, the gap remained massive. GPU utilization sat at 10-20%.
We reproduced it. The gap was even worse on our hardware:
| Method | Time | vs Direct |
|---|---|---|
| Direct tensor indexing | 0.39s | 1x |
| DataLoader (shuffle=True) | 48.49s | 124x slower |
| DataLoader (optimized, 4 workers, pin_memory) | 43.29s | 111x slower |
The workload is trivial: 7M samples, 100 features, 2-layer MLP, batch size 1M. The model processes a batch in milliseconds. So where does the time go?
What nvidia-smi Shows
Nothing useful. GPU utilization flickers between 0% and 30%. Memory usage is stable. Temperature is fine. The GPU is clearly underutilized, but nvidia-smi can’t explain why.
What torch.profiler Shows
The reporter tried PyTorch’s built-in profiler and “obtained no meaningful trace data.” This is a common frustration – application-level profilers can show what CUDA kernels are running, but they cannot see the host-side scheduling, memory, and process lifecycle events that determine whether data arrives at the GPU on time.
What Kernel-Level Tracing Shows
We ran the benchmark while tracing both CUDA API calls (via eBPF uprobes on libcudart.so) and Linux kernel events (scheduler context switches, memory page allocations, process forks) simultaneously. The results tell the complete story.
4 HIGH-severity causal chains
The causal chain engine detected 4 high-severity patterns, all with the same root cause:
[HIGH] cudaStreamSync p99=42ms (1,638x p50=25us) - CPU 100% + 1,880 sched_switch events
Timeline:
  [SYSTEM] CPU 100%
  [HOST  ] 1,880 context switches (21s off-CPU)
  [CUDA  ] p99=42ms (1,638x p50=25us)
Root cause: DataLoader workers fighting for CPU, massive page allocation pressure

[HIGH] cudaLaunchKernel p99=24.67ms (349x p50=70us) - CPU 100%
Root: 34 sched_switch events

[HIGH] cuMemAlloc p99=627us (4.0x p50) - CPU 100%

[HIGH] cuLaunchKernel p99=106us (4.0x p50) - CPU 100%
The cudaStreamSync p99 is 1,638 times the p50. That’s not GPU slowness – that’s the GPU waiting for data that never arrives on time.
The Per-Process Breakdown
This is where it gets clear. The main process and its 4 DataLoader workers are visible as separate entities:
Main process:
cudaMemcpyAsync (host-to-device transfer): avg 301ms, max 2.9 secondscudaStreamSync: p99 = 42ms (normally 25us)DataLoader worker 1: 52,863 context switches, 89,338 page allocations, worst stall 5s
DataLoader worker 2: 50,638 context switches, 83,509 page allocations, worst stall 5s
DataLoader worker 3: 49,361 context switches, 70,035 page allocations, worst stall 5s
DataLoader worker 4: 38,862 context switches, 56,354 page allocations, worst stall 5s
Total across workers: ~191,000 context switches and ~299,000 page allocations in 40 seconds.
What This Means
The DataLoader workers are doing three expensive things that direct indexing avoids entirely:
Shuffling and indexing. DataLoader with shuffle=True generates a random permutation of indices, then each worker selects its chunk. This requires random memory access across the full 7M-sample tensor – terrible for cache locality and triggers page faults.
Collation and copying. Each worker gathers scattered samples into a contiguous batch tensor. This means allocating new memory (page allocations), copying data from random locations (cache misses), and serializing the result back to the main process via shared memory or a queue.
Competing for CPU. Four workers + the main process on a 4-vCPU machine means constant preemption. Each worker gets descheduled 50,000 times. The worst-case stall is 5 seconds – during which the GPU has nothing to process.
With direct indexing: X[i:i+batch_size] is a zero-copy view of a contiguous tensor already in memory. .to(device) triggers one DMA transfer from a single contiguous region. No workers, no shuffling, no collation, no cross-process copies, no context switches. The GPU gets data in microseconds, not hundreds of milliseconds.
The Fix
For in-memory GPU workloads where the entire dataset fits in RAM:
1. Don’t use DataLoader. Direct indexing with a pre-shuffled index array is simpler and 100x faster:
indices = torch.randperm(num_samples)
for i in range(0, num_samples, batch_size):
    batch = X[indices[i:i+batch_size]].to(device)
    output = model(batch)
2. When DataLoader is necessary, match num_workers to the actual CPU core count minus 1. On a 4-core machine, num_workers=2 reduces contention. Add persistent_workers=True to avoid fork overhead.
3. For larger-than-memory datasets where DataLoader is necessary, the real bottleneck shifts to disk I/O. Use prefetch_factor=2 (not higher – more prefetching means more memory pressure) and ensure the storage subsystem can keep up.
The Bigger Picture
This investigation illustrates a pattern we see constantly in GPU workloads: the GPU is fast, the host is the bottleneck, and GPU metrics can’t see it. nvidia-smi reported low utilization but couldn’t explain why. torch.profiler captured CUDA kernels but missed the 200,000 context switches happening in userspace.
The only way to see the full picture was to trace both sides simultaneously – CUDA API calls at the library level and Linux kernel scheduling events – and correlate them by time and process ID.
The causal chain CPU 100% -> 1,880 sched_switch -> cudaMemcpyAsync 301ms -> cudaStreamSync 42ms tells the complete story in one line. Without cross-stack tracing, this would have remained a mystery – as it was for the original reporter who spent weeks debugging it.
Try It Yourself
Reproduce the benchmark:
import torch, time
from torch.utils.data import DataLoader

X = torch.randn(7_000_000, 100)
model = torch.nn.Sequential(
    torch.nn.Linear(100, 512),
    torch.nn.ReLU(),
    torch.nn.Linear(512, 512),
    torch.nn.ReLU(),
    torch.nn.Linear(512, 10)
).cuda()

# Fast path
start = time.time()
with torch.no_grad():
    for i in range(0, len(X), 1_048_576):
        model(X[i:i+1_048_576].cuda())
    torch.cuda.synchronize()
print(f"Direct: {time.time()-start:.3f}s")

# Slow path
loader = DataLoader(X, batch_size=1_048_576, shuffle=True)
start = time.time()
with torch.no_grad():
    for batch in loader:
        model(batch.cuda())
    torch.cuda.synchronize()
print(f"DataLoader: {time.time()-start:.3f}s")
Trace with Ingero to see what’s happening under the hood:
git clone https://github.com/ingero-io/ingero.git
cd ingero && make build
sudo ./bin/ingero trace --duration 60s   # in one terminal
python3 benchmark.py                      # in another terminal
./bin/ingero explain --since 60s          # after benchmark completes
GitHub: github.com/ingero-io/ingero
Original issue: pytorch/pytorch#154318
Investigation performed on TensorDock RTX 4090 (24GB), Ubuntu 22.04, PyTorch 2.10.0+cu128.
Building Production RAG Systems in .NET 10: The Complete Guide to Embeddings
The Hallucination Problem
Your company spent $50K building an internal chatbot. It tells customers “yes, we ship internationally” when you only ship to the US. Your support team is drowning in corrections.
Sound familiar?
This happens because traditional LLMs generate responses from training data patterns, not your actual data. They hallucinate. They confidently state false information.
RAG (Retrieval-Augmented Generation) fixes this. Instead of hoping the LLM knows about your data, you explicitly feed it your documents first.
What Are Embeddings?
Think of embeddings as a way to convert text into mathematics.
The Simple Version
Text: "The quick brown fox"
↓
Embedding (float array, 1536 dimensions)
[0.234, -0.156, 0.892, ..., 0.421]
↓
This vector captures semantic meaning
Why Vectors Matter
Two sentences with different words can have similar embeddings if they mean the same thing:
Sentence A: "Our Q3 revenue exceeded $5 million"
Embedding A: [0.234, -0.156, 0.892, ...]

Sentence B: "Q3 generated more than $5M in sales"
Embedding B: [0.235, -0.154, 0.894, ...]

← Very similar! The model understands they mean the same thing.
But this completely different sentence:
Sentence C: "I like coffee"
Embedding C: [0.892, 0.234, -0.156, ...]

← Very different vector! Different meaning.
This is how RAG systems find relevant documents by meaning, not just keyword matches.
The RAG Pipeline in .NET 10
Step 1: Generate Embeddings from Your Documents
// In .NET 10 with Microsoft.Extensions.AI
public class DocumentEmbedder
{
    private readonly EmbeddingsClient _embeddingClient;
    private readonly VectorStore _vectorStore;

    public DocumentEmbedder(EmbeddingsClient client, VectorStore store)
    {
        _embeddingClient = client;
        _vectorStore = store;
    }

    // Embed your documents once
    public async Task IndexDocumentsAsync(List<string> documents)
    {
        var embeddings = await _embeddingClient.GenerateAsync(documents);

        var vectors = embeddings.Value.Select((e, i) => new VectorDocument
        {
            Id = Guid.NewGuid().ToString(),
            Content = documents[i],
            Vector = e.Vector.ToArray(),
            Metadata = new { Source = "DocumentLibrary" }
        }).ToList();

        await _vectorStore.UpsertAsync(vectors);
    }
}
Key point: You embed documents once and store them. Embeddings are deterministic—same document = same vector, every time.
Step 2: When User Asks, Search Semantically
public class RAGResponseGenerator
{
    private readonly VectorStore _vectorStore;
    private readonly EmbeddingsClient _embeddingClient;
    private readonly ChatClient _chatClient;

    public async Task<string> AnswerAsync(string userQuestion)
    {
        // 1. Embed the question
        var queryEmbedding = await _embeddingClient
            .GenerateAsync(new[] { userQuestion });

        // 2. Search vector database for similar documents
        var relevantDocs = await _vectorStore.SearchAsync(
            vector: queryEmbedding.Value[0].Vector.ToArray(),
            topK: 5,
            threshold: 0.7  // Similarity score
        );

        // 3. Build context from relevant documents
        var context = string.Join("nn", relevantDocs
            .Select(d => $"Source: {d.Metadata["Source"]}n{d.Content}"));

        // 4. Generate response grounded in real data
        var response = await _chatClient.CompleteAsync(
            new ChatMessage(ChatRole.System,
                "You are a helpful assistant. Answer using ONLY the provided context. " +
                "If the context doesn't contain the answer, say 'I don't have that information.'"),
            new ChatMessage(ChatRole.User, $"Context:n{context}nnQuestion: {userQuestion}")
        );

        return response.Content[0].Text;
    }
}
Real-World Use Cases
1. Enterprise Document Search
Problem: “Find all contracts where we agreed to 30-day payment terms”
Keyword search fails. It finds “30 days” but also matches “30-day warranty” in unrelated docs.
RAG solution:
// Semantic search understands intent
var searchResults = await _vectorStore.SearchAsync(
    query: "payment terms agreements",
    topK: 20
);

// Returns contracts actually discussing payment terms
// Not just keyword matches
2. Customer Support Automation
Problem: Support tickets are repetitive. Your FAQ is massive.
RAG solution:
public class SupportChatbot
{
    public async Task<string> AnswerSupportQuestionAsync(string question)
    {
        // Search FAQ, past tickets, knowledge base
        var relevantArticles = await _vectorStore.SearchAsync(
            query: question,
            filter: new { Type = "FaqOrTicket" }
        );

        // Generate response from actual support history
        var response = await _chatClient.CompleteAsync(
            context: relevantArticles,
            prompt: $"Customer asks: {question}"
        );

        return response;
    }
}
Result: Consistent answers based on real support history, not hallucinated solutions.
3. Technical Documentation Assistant
Problem: Your API docs are 500 pages. Developers give up.
RAG solution:
// "How do I paginate API results?"
// Search finds: Authentication docs, Pagination section, Examples
// Returns: Exactly what the developer needs

var docSearch = await _vectorStore.SearchAsync(
    query: "pagination API results",
    filter: new { DocumentType = "ApiDocs" },
    topK: 3
);
4. Code Analysis & Documentation
Problem: Onboarding takes weeks. New devs can’t find relevant code examples.
RAG solution:
public class CodebaseAssistant
{
    // Embed your entire codebase
    // "Show me examples of dependency injection usage"
    var examples = await _codeVectorStore.SearchAsync(
        query: "dependency injection usage examples",
        topK: 10
    );

    // Returns actual code from your repo
}
DO’s and DON’Ts for RAG in .NET
✅ DO
var chunks = ChunkDocument(doc, chunkSize: 512, overlap: 100);
  var vector = new VectorDocument
  {
      Content = text,
      Vector = embedding,
      Metadata = new { Source = "SalesReport", Date = DateTime.Now }
  };
  var results = await vectorStore.SearchAsync(query, topK: 5);
  var confident = results.Where(r => r.SimilarityScore > 0.75);
❌ DON’T
  // Bad
  var embedding = await client.GenerateAsync(pdfBytes);

  // Good
  var text = ExtractTextFromPdf(pdf);
  var embedding = await client.GenerateAsync(text);
  // Bad: Use anything over 0.5
  // Good: Use results > 0.7, fall back to "I don't know"
Use outdated embeddings for new documents. Inconsistent results.
Forget about cost. Embedding a million documents is expensive. Plan your chunk strategy.
Vector Databases for .NET
| Database | .NET Support | Best For | Cost |
|---|---|---|---|
| Azure Cosmos DB | ✅ Native | Enterprise, serverless | $$$ |
| Azure OpenAI | ✅ Built-in | Quick start, OpenAI models | $$$ |
| pgvector (PostgreSQL) | ✅ Npgsql | Self-hosted, low cost | $ |
| Milvus | ✅ Community | Open source, scalable | $ |
| Pinecone | ✅ REST API | Managed, serverless | $$ |
Minimal Example with Cosmos DB
services.AddAzureOpenAIClient(endpoint, credentials);
services.AddScoped<VectorStoreCosmosDb>();
services.AddScoped<EmbeddingsClient>();

// Dependency injection handles the rest
Measuring RAG Quality
Retrieval Metrics
Precision: Of top-5 results, how many are relevant?
var relevant = searchResults.Count(r => r.IsRelevant);
var precision = relevant / searchResults.Count;
// Target: > 0.8
Recall: Of all relevant documents, did we find them?
var foundRelevant = relevantDocuments
    .Count(d => searchResults.Contains(d));
var recall = foundRelevant / totalRelevantDocuments;
// Target: > 0.7
Conclusion
RAG eliminates hallucinations by grounding AI in your actual data.
Key Takeaways:
Next Steps:
Resources
What’s your biggest question about RAG? Drop it below!
Most founders assume WordPress is the safer SEO bet because it has been around longer. That assumption is costing them rankings.
Webflow’s architecture removes entire categories of technical debt that WordPress sites accumulate by default. This article breaks down exactly why Webflow outranks WordPress in organic search and when that advantage actually applies to your situation.
Key Takeaways
Does Webflow Actually Rank Faster Than WordPress?
Webflow sites load faster and require less technical SEO maintenance than most WordPress setups, which gives them a structural ranking advantage from day one.
The gap is not about content quality. It is about what each platform forces you to manage before your content can compete. WordPress is powerful, but it ships every site with technical SEO as an optional add-on. Webflow ships it as a default.
The result is that a competently built Webflow site starts with fewer technical SEO problems than a competently built WordPress site.
How Does Webflow Handle Core Web Vitals Compared to WordPress?
Webflow sites score better on Core Web Vitals out of the box because the platform controls the full rendering stack, unlike WordPress where theme and plugin choices determine performance.
Google’s Core Web Vitals measure Largest Contentful Paint, Cumulative Layout Shift, and Interaction to Next Paint. These scores directly affect where your site ranks on competitive queries in 2026. Webflow’s approach to each of these is fundamentally different from WordPress.
Closing the Core Web Vitals gap on WordPress requires a performance-focused hosting stack, a lightweight theme, image optimization plugins, and caching configuration. On Webflow, it is the starting point.
Why Does WordPress Accumulate Technical SEO Debt Over Time?
WordPress sites accumulate technical SEO debt because every update cycle introduces compatibility risk between themes, plugins, and core, and most teams prioritize functionality over performance.
A WordPress site that scores well on day one will degrade without active maintenance. Plugin updates break caching configurations. Theme changes introduce new render-blocking scripts. Hosting migrations disrupt redirect chains. None of these problems exist in the same form on Webflow because the platform manages the infrastructure.
The maintenance overhead compounds over time. Teams that start with a fast WordPress site often find themselves two years later managing a slow one because the cost of keeping it optimized was not built into their workflow.
What Does Webflow Do Better for On-Page SEO?
Webflow gives you direct, clean control over every on-page SEO element at the page and collection level, without the abstraction layers that WordPress plugins introduce.
On-page SEO control matters because it determines how quickly you can implement changes across a site without developer involvement. On WordPress, changing a meta template across 200 pages requires understanding how your SEO plugin handles dynamic fields. On Webflow, it is a single CMS field mapped to a page template.
If you are evaluating where Webflow fits inside a broader SEO strategy, understanding these native capabilities helps you scope what an agency actually needs to build versus what the platform provides by default.
When Does WordPress Still Win on SEO?
WordPress outperforms Webflow on SEO when your site requires complex programmatic content generation, deep CMS customization, or integrations that Webflow’s closed infrastructure cannot support.
Webflow’s SEO advantages are real, but they apply to a specific category of site. If your SEO strategy depends on capabilities outside that category, the platform choice changes.
The honest framing is this: Webflow wins on performance and technical SEO simplicity. WordPress wins on flexibility and scale. Your site architecture should match your actual content and growth requirements.
Conclusion
Webflow’s ranking advantage over WordPress is structural, not accidental. Clean code, built-in Core Web Vitals optimization, and native SEO controls give Webflow sites a faster starting point than most WordPress builds achieve after months of optimization. If your site fits within Webflow’s content model, the platform removes an entire layer of technical SEO work that WordPress requires you to manage manually.
Want to Build an SEO-Optimized Webflow Site?
Most Webflow sites underperform on SEO not because of the platform, but because the build did not account for SEO from the start.
At LowCode Agency, we are a strategic product team that designs, builds, and evolves Webflow sites with SEO built into the architecture, not bolted on afterward.
We have shipped 350+ products across 20+ industries. Clients include Medtronic, American Express, Coca-Cola, and Zapier.
If you are serious about building a Webflow site that ranks, let’s talk.

 I built PythPulse for the Pyth Hackathon 2026. It monitors 38 live price feeds using Pyth’s Hermes API and detects market anomalies in real-time. Live demo: https://pythpulse-2-wgig.vercel.app/