Terraform Lock-In Is Real: Here’s How to Get Out

diagram

Terraform Lock-In Is Real: Here’s How to Get Out
The License Change That Made Lock-In Visible

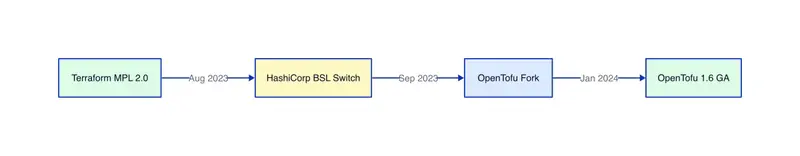
In August 2023, HashiCorp quietly changed everything. Terraform moved from the Mozilla Public License (MPL 2.0) to the Business Source License (BSL 1.1). The new license prohibits using Terraform to build a competing product. For most engineering teams, that restriction meant nothing in practice. But the change did something more important: it made visible how dependent the infrastructure world had become on a single vendor’s tool.

Teams that had been writing HCL for three years suddenly had a reason to ask: what would it take to leave? The answer, for most of them, was uncomfortable.

diagram

Within a month of the BSL announcement, a community fork appeared under the Linux Foundation. OpenTofu reached general availability in January 2024. The speed of the fork was remarkable. The reason was simple: the infrastructure community had built too much on Terraform to let a license dispute make it a dead end, but they also weren’t ready to hand full control to a single commercial entity.

The fork created an exit ramp. But whether you take it, or switch to something else entirely, starts with understanding what you’re actually locked into.

What Terraform Lock-In Actually Looks Like

Lock-in is not one thing. It is four things stacked on top of each other.

diagram

HCL. HashiCorp Configuration Language is declarative, readable, and entirely specific to the HashiCorp toolchain. Skills transfer to Vault and Consul, but not to Pulumi, CDK, or Crossplane. Every engineer who knows Terraform knows HCL. That knowledge does not move.

Providers. There are over 3,000 providers in the Terraform registry, covering AWS, GCP, Azure, Datadog, PagerDuty, Cloudflare, and hundreds of niche services. These providers are written against the Terraform plugin SDK. OpenTofu maintains full compatibility here. Pulumi or CDK do not: they have their own provider layers, with varying coverage.

State. This is where migration actually gets painful. Terraform state files are JSON, but they are keyed against specific provider schema versions. Moving 500 resources from one tool to another means reconciling every resource’s state representation, one at a time. There is no bulk converter that works reliably at scale.

Module registry coupling. Community modules on the Terraform registry assume HCL syntax, Terraform variable conventions, and tfstate output formats. If you switch tools, you lose access to this ecosystem unless the new tool explicitly provides compatibility layers.

Understanding which of these four you are most exposed to determines which exit path makes sense.

The Real Cost of Leaving

Teams underestimate migration cost because they measure the wrong thing. The question is not “how many lines of HCL do we have?” It is “how many distinct state files do we have, and how complex is each one?”

Team Size Module Count Estimated Migration Effort Realistic Timeline
5 engineers <20 modules 2-4 weeks 1 month
15 engineers 20-80 modules 2-4 months 3-6 months
30+ engineers 80-200 modules 6-12 months 6-18 months
Platform team 200+ modules 12-24 months 18+ months

These numbers assume a clean migration path, not a big-bang rewrite. Teams that attempt a big-bang switch consistently overshoot timelines by 2x. The ones that migrate incrementally, module by module, stay close to estimates.

Beyond engineering hours, there are three hidden costs most teams miss. CI/CD pipelines need rewiring: every plan/apply workflow in GitHub Actions, GitLab CI, or Jenkins has Terraform-specific steps. Secrets management integrations often use Terraform provider-level credential injection. And runbooks, documentation, and onboarding guides are written for Terraform. These take time to update and they are easy to forget until they break something in production.

The license concern alone is not worth a 12-month migration for most teams. What makes the migration worth it is if you also want better language support, stronger testing primitives, or a genuinely open governance model.

Your Three Exit Paths

Not all exits look the same. The right path depends on what you are trying to solve.

diagram

Criterion OpenTofu Pulumi CDK / Crossplane
Migration effort Lowest (binary swap) High (full rewrite) High (paradigm shift)
State compatibility Full (wire-compatible) None (manual import) None (manual import)
Language HCL (same as Terraform) TS, Python, Go, C# TS/Python (CDK); YAML (Crossplane)
Provider coverage All Terraform providers Pulumi registry + Terraform bridge AWS CDK: AWS only; Crossplane: varies
Governance Linux Foundation Commercial (Pulumi Corp) AWS (CDK); CNCF (Crossplane)
Maturity High (1.6+ GA) High (production-proven) Medium-High

OpenTofu is the right choice if your primary concern is the BSL license, or if you want to stay on HCL and avoid a rewrite. The migration is literally replacing the terraform binary with tofu. State files are compatible. Providers are compatible. CI/CD pipelines need one-line changes. Teams of 50+ with hundreds of modules should default here.

Pulumi is the right choice if HCL is itself the problem. Pulumi lets you write infrastructure in TypeScript, Python, Go, or C#. You get loops, conditionals, unit tests, and type checking without workarounds. The tradeoff is a full rewrite. There is no automated converter from HCL to Pulumi. The pulumi convert tool handles simple cases but fails on complex modules. Budget for a full migration effort.

CDK / Crossplane is the right choice if your team is already Kubernetes-native and you want infrastructure managed via operators and GitOps. Crossplane treats every cloud resource as a Kubernetes custom resource. AWS CDK generates CloudFormation. Both require rethinking how you model infrastructure, not just what language you use.

How to Migrate Without Breaking Production

The migration that does not break production is incremental. Never migrate a running system by switching the tool underneath it in one step.

diagram

Phase 1: Audit. Run terraform state list against every state file in your infrastructure. Count total managed resources. Map which state files are shared across teams. Identify state files that manage production database clusters versus those that manage S3 buckets for dev environments. Start with the latter.

Phase 2: Greenfield new. Stop writing new Terraform. All new infrastructure gets created in the target tool. This limits the blast radius of any migration mistakes and lets your team build muscle memory before touching production state.

Phase 3: Migrate state. For OpenTofu: run tofu init in the module directory. If it runs clean, you are done. For Pulumi: use pulumi import to pull existing resources into Pulumi state, then delete the corresponding Terraform config. Run both in parallel for one sprint to validate outputs match before cutting over.

Phase 4: Retire old. Delete Terraform configs for migrated modules. Remove Terraform-specific CI jobs. Update your runbooks. The migration is not complete until the old toolchain is gone, not just unused.

For teams using tfmigrate, the tool can batch state moves across module boundaries, which is useful when reorganizing how state is split during migration.

Preventing the Next Lock-In

Switching tools is expensive. The way to avoid doing it again is to stop letting tool APIs leak into every module.

diagram

Application teams should call internal modules with domain-meaningful inputs: database_size = "medium", environment = "staging". They should not call provider-specific resources directly. The internal module translates domain inputs to provider calls.

When the provider changes or the tool changes, you update the internal module. Application teams do not change. This pattern does not eliminate migration cost, but it concentrates it in one place instead of spreading it across every team’s configuration.

Terraform made infrastructure programmable at scale. That contribution is real. But every tool that succeeds at scale creates its own gravity. Understanding that gravity, knowing what it costs to escape, and building enough abstraction to make the next exit cheaper: that is the work.
AI Agents and GitHub Bounties: A Brutally Honest Experiment

I Tried to Let an AI Agent Make Money Online — Every Platform Said No

My AI agent wrote better code than 90% of bounty hunters. It submitted real pull requests to open-source projects. It ran a 48-hour BTC grid trading backtest with 81 trade triggers and a 48% theoretical profit. It evaluated 23 bounty programs, spotted 4 scams before wasting any time on them, and drafted content that passed editorial review.

It still earned $0.

Not because the AI wasn’t smart enough. Not because the code was bad. Not because the strategy was wrong.

Every single platform we touched had a wall built specifically to stop software from doing what humans can do. KYC walls. OAuth dead-ends. CAPTCHAs. 2FA challenges. Terms of Service that explicitly ban automation. Payment rails that require a Social Security Number.

This is the story of what actually happens when you try to let an AI agent make money online — and why the “just use AI to earn passive income” crowd is selling you a fantasy that collapses at the first login screen.

The Experiment

For 30 days, we ran an AI agent with one directive: find ways to make money online, execute them, and report back. No manual intervention unless absolutely required. The agent had access to code execution, web search, GitHub CLI, browser automation, and content APIs.

The goal wasn’t to get rich. It was to find out: where does the “AI can do everything” narrative actually break down?

The answer turned out to be surprisingly specific. The AI could do the work. It just couldn’t get through the doors.

Here are the four walls we hit, over and over again.

Wall 1: Identity — “Show Us Your Passport”

The first wall is the tallest. Before you can trade, publish, collect bounties, or receive payments on most platforms, you need to prove you’re a human with a government-issued identity. Not a human behaving a certain way — a human with a passport number, a physical address, and often a selfie holding that passport.

KYC (Know Your Customer) requirements blocked 60–70% of the crypto opportunities we found.

Here’s what that looked like in practice:

  • Binance: Passport or government ID required. No API access for trading without it. Agent-friendly features exist, but they’re gated behind a process that requires a real human body.
  • Coinbase: Same story. You can generate API keys for trading, but only after completing full identity verification — photo ID, selfie, proof of address.
  • OKX: Identical KYC wall. The API documentation is excellent. The agent could have integrated with it in an hour. But the API key doesn’t exist until a human uploads their passport.

Our rule was Steve’s rule: skip all KYC. Not because we’re doing anything shady, but because the entire point of this experiment was to see what an AI agent can do autonomously. The moment you need a human to hold up a driver’s license to a webcam, autonomous operation is dead.

This isn’t just a crypto problem. It’s everywhere:

  • Stripe requires your SSN (or EIN for businesses) to receive payments.
  • PayPal needs identity verification above certain thresholds.
  • Upwork requires ID verification before you can even bid on jobs.
  • Amazon Mechanical Turk requires a US bank account and tax identity.

The pattern: platforms conflate “identity” with “trustworthiness.” An AI agent that writes perfect code, submits clean PRs, and follows every contributing guideline is still untrustworthy — because it can’t show a face.

Wall 2: Authentication — “Please Log In With Your Browser”

If identity is the tallest wall, authentication is the most frustrating one. Because the AI can authenticate — with API keys, tokens, and service accounts. But most platforms don’t offer those paths. They offer OAuth, and OAuth is built for humans sitting in front of browsers.

The Medium story was our most illustrative failure.

Medium has no API for publishing. None. The only way to publish a post is through the web editor, which requires a browser-based OAuth login — Google or Twitter SSO. There’s no API key to generate. No personal access token. No service account.

Our agent could draft a complete, polished article. It could even open a browser and navigate to Medium.com. But when the login screen popped up with “Sign in with Google,” it hit a wall. OAuth flows require:

  • A human to approve the consent screen
  • Session cookies that survive browser restarts
  • Often 2FA on the underlying Google account

The agent literally could not publish to Medium. Not because the writing wasn’t good enough. Because Medium’s authentication model assumes a human is clicking buttons.

Compare this with other platforms:

Platform Auth Method Agent-Accessible?
Dev.to API key (generated by human once) ✅ Yes
Hashnode Personal Access Token ✅ Yes
Medium OAuth browser login only ❌ No
Ghost API key / Admin API ✅ Yes
WordPress.com Application Password ✅ Yes

See the pattern? API key = agent-friendly. OAuth = agent-hostile.

Dev.to was one of the few platforms where the agent could actually publish content end-to-end. A human generated the API key once (30 seconds of work), and after that, the agent had full programmatic access. Publishing, editing, listing articles — all of it worked.

But Dev.to was the exception. Most platforms either don’t offer API keys at all, or bury them behind enterprise plans and “contact sales” forms.

Wall 3: Platform Anti-Automation — “We Know You’re Not Human”

Even when identity and authentication aren’t blockers, platforms actively fight automation. They’ve built detection systems specifically to identify and block non-human behavior — and AI agents trigger all of them.

GitHub bounties were our most promising avenue, and they were littered with friction.

We evaluated 23 bounty programs across platforms like Gitcoin, IssueHunt, and direct GitHub bounty labels. The agent could:

  • Read and understand issues
  • Write working code
  • Submit pull requests
  • Pass CI checks

But here’s what happened with the Expensify/App project specifically:

Expensify maintains an open bounty program. Our agent identified 8 issues it could fix, wrote the code, and submitted PRs. It even completed their CLA (Contributor License Agreement) process — which is itself an automation barrier, requiring a signed document.

All 8 PRs were closed without merge.

Not because the code was bad. Expensify’s review process requires sustained human interaction — responding to review comments, adjusting to style guides, participating in discussion threads. Our agent could handle one round of review. It couldn’t sustain the multi-day, multi-turn conversation that real contribution requires.

And that’s a best-case scenario. Most bounty programs have additional barriers:

  • Rate limits: GitHub’s API allows 5,000 requests/hour for authenticated users, but complex workflows burn through that fast.
  • CAPTCHAs: Gitcoin’s Passport system specifically screens for Sybil attacks — automated account creation and interaction. New, unverified accounts get flagged immediately.
  • Terms of Service: Nearly every bounty platform explicitly prohibits automated submissions. It’s in the fine print nobody reads — until your account gets banned.

Anti-Sybil measures in the airdrop space were even more aggressive. Most airdrops we evaluated now require:

  • Wallet age (minimum 6–12 months of on-chain history)
  • Minimum transaction volume
  • Social verification (Twitter account age, follower count, connected Discord)
  • Proof of unique human identity (Worldcoin, Gitcoin Passport scores)

Our agent’s wallets were new. Its social accounts were new. It tripped every Sybil detection system that exists. These platforms aren’t just saying “prove you’re human” — they’re saying “prove you’ve been human here for a while.”

Wall 4: Payment Rails — “Where Do We Send the Money?”

Let’s say you somehow clear the first three walls. You’ve got identity (a human helped with KYC), you’ve got auth (someone generated an API key), and you’ve avoided anti-automation detection. Now you need to get paid.

The payment layer is the final wall, and it’s just as rigid as the first three.

  • Stripe: Requires SSN or EIN for identity verification. API is excellent for sending payments (charging customers), but receiving payouts requires full KYC.
  • PayPal: Identity verification required. Payout API exists but is gated behind business account approval.
  • Crypto exchanges: Circle back to Wall 1. You need KYC to on-ramp fiat, and most bounty/airdrop payouts ultimately need to convert to fiat to be useful.
  • Direct bank transfers: Obviously require a bank account, which requires identity.

The grid trading example showed this perfectly. Our agent ran a BTC/USDT grid trading backtest over 48 hours. The analysis was solid — 81 trade triggers, 48% theoretical profit under the backtest conditions. The strategy worked.

But to actually execute trades? You need API keys from an exchange. And those exchange API keys require… KYC. Passport. Selfie. Back to Wall 1.

The agent could build the entire money-making engine. It just couldn’t plug it into the financial system.

What Actually Worked

Not everything failed. Here’s what the agent could actually do autonomously:

  • Dev.to publishing: API key auth, full programmatic access. Agent published multiple articles without human intervention after the initial key generation.
  • GitHub CLI operations: Code review, issue triage, PR management — all worked via gh CLI with a personal access token.
  • Web research and analysis: Bounty evaluation, market analysis, content research — pure information tasks with no platform gate.
  • Content drafting: Writing, editing, formatting — the creative work itself was never the bottleneck.
  • Code generation: Fixing bugs, implementing features, writing tests — the technical work was consistently high quality.

The common thread: every task that worked used API key authentication and had no identity verification beyond the key itself.

Every task that failed hit one of the four walls: identity, authentication, anti-automation, or payment.

The Pattern

After 30 days, the pattern is unmistakable:

API Key = agent-friendly.

OAuth = agent-hostile.

KYC = agent-impossible.

This isn’t a capability problem. GPT-4, Claude, and their descendants can write code, analyze markets, create content, and solve complex problems at levels that rival or exceed most freelancers.

It’s an infrastructure problem. The internet’s trust model is built on the assumption that every user is a human with a face, a passport, and a bank account. AI agents have none of those things. And until platforms build agent-native authentication and identity layers, this gap will persist.

Implications

For Platform Builders

API-first design isn’t just developer-friendly — it’s automation-friendly. Every platform that offers API key auth (Dev.to, Hashnode, Ghost, WordPress) automatically becomes accessible to AI agents. Every platform that locks behind OAuth-only flows (Medium) or mandatory KYC (every crypto exchange) is building a wall against the fastest-growing category of users on the internet.

If you want AI agents to create value on your platform — and they will, eventually — make API keys easy to generate and hard to abuse. Rate limits solve the abuse problem. KYC doesn’t.

For AI Agent Builders

Stop pretending OAuth can be automated. It can’t, not reliably, not at scale, and not without violating ToS. Focus your agents on platforms that offer API key or token-based auth. Build a database of agent-friendly platforms. Track which ones are adding or removing API access.

The agents that will succeed commercially aren’t the ones with the best reasoning — they’re the ones that can actually log into things.

For the “Make Money With AI” Crowd

The bottleneck isn’t intelligence. It’s infrastructure.

Your AI agent can write better code than most Upwork freelancers. It can produce better content than most SEO mills. It can analyze markets better than most retail traders. But it can’t pass KYC. It can’t complete OAuth. It can’t hold up a passport to a webcam.

Until that changes — until platforms build identity layers that accommodate non-human actors — “make money with AI” will remain a content marketing slogan, not a business model.

The tools are ready. The platforms aren’t.

The Real Question

Here’s what keeps me up at night about this experiment: the walls aren’t bugs. They’re features.

KYC exists because of anti-money-laundering regulations. OAuth exists because password-based auth was a security disaster. Anti-Sybil measures exist because people were gaming every system that didn’t have them.

These barriers were built for good reasons. But they were also built with a fundamental assumption: every user is a single human being.

What happens when that assumption is wrong? When the most valuable users on your platform aren’t humans at all, but AI agents acting on behalf of humans? When a single person with one AI agent is functionally equivalent to a team of ten?

We don’t have answers yet. We have walls.

And until we figure it out, the AI can do your job. It just can’t log into your accounts.

This post is part of our 30-day AI agent experiment series. The agent that wrote and published this article used the Dev.to API — one of the few platforms where that’s actually possible. We’ll keep documenting what works, what doesn’t, and where the infrastructure gaps are.

If you’re building agent-friendly platforms, API-first tools, or identity systems that don’t assume a human face — we want to hear from you. The walls need doors.

Production Multi-Agent Systems: The Silent Failures Nobody Talks About

Your multi-agent system works perfectly in development. In production, it produces occasional wrong results with zero errors. Sound familiar?

The Article That Sparked This

I recently read @hadil‘s excellent article “Bifrost: The Fastest LLM Gateway for Production-Ready AI Systems (40x Faster Than LiteLLM)“ and it resonated deeply with challenges I’ve been solving in production.

This article captures the production reality perfectly. The failures described are almost always rooted in a single cause: uncoordinated shared state.

The Core Problem: State Coordination

Here’s what most multi-agent discussions miss: the frameworks are great at individual agent capabilities. LangChain gives you chains, AutoGen gives you conversations, CrewAI gives you roles. But when these agents need to share state — that’s where things silently break.

Timeline of a Production Bug:
0ms:  Agent A reads shared context (version: 1)
5ms:  Agent B reads shared context (version: 1)  
10ms: Agent A writes new context (version: 2)
15ms: Agent B writes context (based on v1) → OVERWRITES Agent A
Result: Agent A's work is silently lost. No error thrown.

This isn’t hypothetical — it’s the #1 failure mode in multi-agent production systems.

How We Solved It: Network-AI

After hitting this wall repeatedly, I built Network-AI — an open-source coordination layer that sits between your agents and shared state:

┌─────────────┐  ┌─────────────┐  ┌─────────────┐
│  LangChain  │  │   AutoGen   │  │   CrewAI    │
└──────┬──────┘  └──────┬──────┘  └──────┬──────┘
       │                │                │
       └────────────────┼────────────────┘
                        │
                 ┌──────▼──────┐
                 │  Network-AI │
                 │ Coordination│
                 └──────┬──────┘
                        │
                 ┌──────▼──────┐
                 │ Shared State│
                 └─────────────┘

Every state mutation goes through a propose → validate → commit cycle:

// Instead of direct writes that cause conflicts:
sharedState.set("context", agentResult); // DANGEROUS

// Network-AI makes it atomic:
await networkAI.propose("context", agentResult);
// Validates against concurrent proposals
// Resolves conflicts automatically
// Commits atomically

Key Features

  • 🔐 Atomic State Updates — No partial writes, no silent overwrites
  • 🤝 14 Framework Support — LangChain, AutoGen, CrewAI, MCP, A2A, OpenAI Swarm, and more
  • 💰 Token Budget Control — Set limits per agent, prevent runaway costs
  • 🚦 Permission Gating — Role-based access across agents
  • 📊 Full Audit Trail — See exactly what each agent did and when

From Demo to Production

The gap between demo and production in multi-agent systems isn’t about model quality or prompt engineering. It’s about infrastructure: state management, conflict resolution, and audit trails.

Try It

Network-AI is open source (MIT license):

👉 https://github.com/Jovancoding/Network-AI

Join our Discord community: https://discord.gg/Cab5vAxc86

What was your worst production multi-agent bug? I bet it was a silent state corruption — they always are!

Presentation: Directing a Swarm of Agents for Fun and Profit

Adrian Cockcroft explains the transition from cloud-native to AI-native development. He shares his “director-level” approach to managing swarms of autonomous agents using tools like Cursor and Claude Flow. Discussing real-world experiments in BDD, MCP servers, and language porting, he discusses why the future of engineering lies in building platforms that orchestrate AI-driven development.

By Adrian Cockcroft

Article: Beyond RAG: Architecting Context-Aware AI Systems with Spring Boot

This article introduces Context-Augmented Generation (CAG) as an architectural refinement of RAG for enterprise systems. It shows how a Spring Boot-based context manager can incorporate user identity, session state, and policy constraints into AI workflows, improving traceability, consistency, and governance without altering existing retrievers or LLM infrastructure.

By Syed Danish Ali