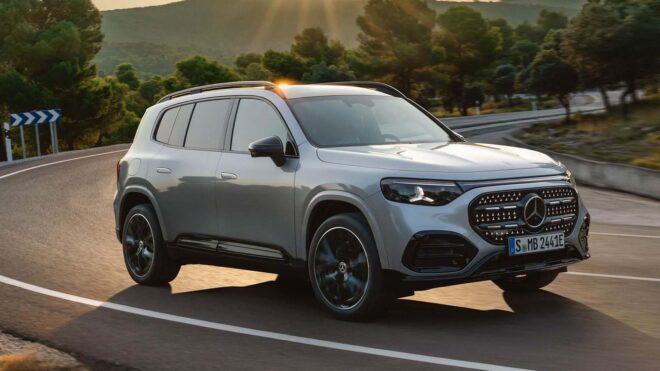
Yeni tamamen elektrikli Mercedes-Benz GLB, Türkiye’ye özel motorla satışa sunuldu

Yeni Mercedes-Benz GLB, Türkiye

Yeni Mercedes-Benz GLB, Türkiye'ye özel motorla satışa sunulduTaylan Özgür Dil tarafından aktarıldığı kadarıyla tamamen elektrikli yeni Mercedes-Benz GLB, bugün itibarıyla Türkiye’de satışa sunuldu. Yüzde 55’lik ÖTV dilimine girmesi için motor gücünün 200 kW’dan 160 kW’ya düşürüldüğü açıklanan araç, 4.350.000 TL satış fiyatına sahip. 250+ AMG versiyonuyla getirilen 320 kW şarj destekli yeni GLB, 85 kWh bataryasıyla yaklaşık 590 km menzil vadediyor. Türkiye’ye özel olarak hazırlanan 160 kW (218 beygir) güç ve 335 Nm tork üreten motoruyla 0’dan 100 km/s hıza 7,4 saniyede ulaşabilen aracın, 1.5 litrelik içten yanmalı motora sahip hibrit versiyonunun ise temmuz ayında satışa sunulabileceği belirtiliyor.

Yeni tamamen elektrikli Mercedes-Benz GLB, Türkiye’ye özel motorla satışa sunuldu yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Qwen3.6-Plus API: ชนะ Claude บน Terminal Benchmarks

Terminal-Bench 2.0

สรุป (TL;DR)

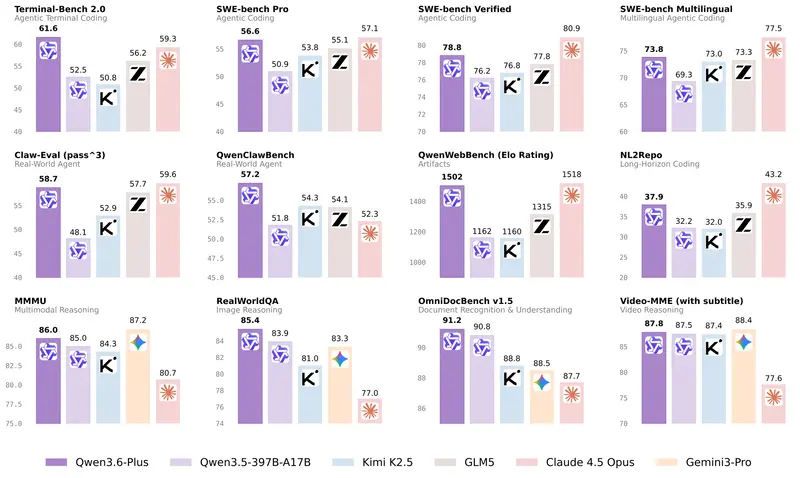
Qwen3.6-Plus เปิดตัวอย่างเป็นทางการแล้ว คะแนนสูงใน SWE-bench Verified 78.8% และ Terminal-Bench 2.0 ที่ 61.6% (สูงกว่า Claude Opus 4.5) พร้อม Context Window 1M โทเค็น มีพารามิเตอร์ใหม่ preserve_thinking สำหรับ Agent Loops และใช้งานกับ Claude Code, OpenClaw และ Qwen Code ได้โดยตรงผ่าน API ที่เข้ากันได้กับ OpenAI

ทดลองใช้ Apidog วันนี้

จากการพรีวิวสู่การเปิดตัว

หากคุณเคยอ่าน คู่มือ Qwen 3.6 Plus Preview บน OpenRouter จะทราบถึงความสามารถของโมเดลนี้ รุ่นพรีวิวเปิดตัวเมื่อ 30 มีนาคม ประมวลผลโทเค็นไปกว่า 400 ล้านโทเค็นใน 2 วันแรก

ตอนนี้ Qwen3.6-Plus เปิดตัวอย่างเป็นทางการแล้ว ใช้งานได้ผ่าน Alibaba Cloud Model Studio มี API ที่เสถียร, uptime การันตี และพารามิเตอร์ใหม่ที่เหมาะกับงาน Agent หลายขั้นตอน

บทความนี้สรุปของใหม่ วิธีเรียก API อย่างถูกต้อง และวิธีทดสอบการผสานกับ Apidog ก่อนนำไปใช้จริง

Qwen3.6-Plus คืออะไร

Qwen3.6-Plus เป็นโมเดล Mixture-of-Experts จากทีม Qwen ของ Alibaba ใช้ Sparse Activation (มีแค่บางส่วนของพารามิเตอร์ทำงานแต่ละโทเค็น) ช่วยให้มีประสิทธิภาพสูงแต่ต้นทุนต่ำกว่ารุ่น Dense

ฟีเจอร์หลัก:

  • Context Window 1M โทเค็น
  • Reasoning แบบ Chain-of-thought (บังคับใช้)
  • พารามิเตอร์ preserve_thinking สำหรับ Agent
  • รองรับ Multimodal (ภาพ, วิดีโอ, เอกสาร)
  • API compatible กับ OpenAI, Anthropic และ OpenAI Responses API

เวอร์ชัน Open-source ขนาดเล็กจะเปิดตัวเร็วๆ นี้ หากต้องการ Weights สำหรับ self-hosted ให้ติดตามข่าว

ผลลัพธ์ Benchmark

Coding Agents

Qwen3.6-Plus ตามหลัง Claude Opus 4.5 เพียงเล็กน้อยใน SWE-bench ส่วนใหญ่ แต่เป็นผู้นำทุกโมเดลใน Terminal-Bench

Terminal-Bench 2.0

Terminal-Bench 2.0 ทดสอบ shell จริง เช่น การจัดการไฟล์ การควบคุมกระบวนการ และเวิร์กโฟลว์หลายขั้นตอน Qwen3.6-Plus ได้ 61.6% vs Claude Opus 59.3% เหนือกว่าอย่างชัดเจนในงานที่ developer ใช้งานจริง

General Agents และการใช้เครื่องมือ

Benchmark Claude Opus 4.5 Qwen3.6-Plus
TAU3-Bench 70.2% 70.7%
DeepPlanning 33.9% 41.5%
MCPMark 42.3% 48.2%
MCP-Atlas 71.8% 74.1%
WideSearch 76.4% 74.3%

MCPMark ทดสอบการใช้เครื่องมือ GitHub MCP โดดเด่นที่ 48.2% DeepPlanning ที่ 41.5% เทียบกับ 33.9% ของ Claude แสดงความต่างในงานวางแผนยาว

การใช้เหตุผลและความรู้

Benchmark Claude Opus 4.5 Qwen3.6-Plus
GPQA 87.0% 90.4%
LiveCodeBench v6 84.8% 87.1%
IFEval strict 90.9% 94.3%
MMLU-Pro 89.5% 88.5%

GPQA และ IFEval strict – Qwen3.6-Plus เป็นผู้นำ เหมาะกับ output มีโครงสร้างและงาน Agent ที่ต้องปฏิบัติตามข้อจำกัด

Multimodal

Qwen3.6-Plus เป็นโมเดล Multimodal แบบเนทีฟ นำหน้าในงานเอกสาร, spatial reasoning, object detection

Benchmark Qwen3.6-Plus หมายเหตุ
OmniDocBench 1.5 91.2% อันดับสูงสุด
RefCOCO avg 93.5% อันดับสูงสุด
We-Math 89.0% อันดับสูงสุด
CountBench 97.6% อันดับสูงสุด
OSWorld-Verified 62.5% ตามหลัง Claude (66.3%)

สำหรับงานเอกสารและ spatial Qwen3.6-Plus เป็นผู้นำ

วิธีเรียกใช้ API

Qwen3.6-Plus มีบน Alibaba Cloud Model Studio รับ API key ได้ที่ modelstudio.alibabacloud.com

Base URLs:

  • สิงคโปร์: https://dashscope-intl.aliyuncs.com/compatible-mode/v1
  • ปักกิ่ง: https://dashscope.aliyuncs.com/compatible-mode/v1
  • สหรัฐอเมริกา เวอร์จิเนีย: https://dashscope-us.aliyuncs.com/compatible-mode/v1

การเรียกใช้พื้นฐานพร้อม Streaming

from openai import OpenAI
import os

client = OpenAI(
    api_key=os.environ["DASHSCOPE_API_KEY"],
    base_url="https://dashscope-intl.aliyuncs.com/compatible-mode/v1",
)

completion = client.chat.completions.create(
    model="qwen3.6-plus",
    messages=[{"role": "user", "content": "Review this Python function and find bugs."}],
    extra_body={"enable_thinking": True},
    stream=True
)

reasoning = ""
answer = ""
is_answering = False

for chunk in completion:
    if not chunk.choices:
        continue
    delta = chunk.choices[0].delta
    if hasattr(delta, "reasoning_content") and delta.reasoning_content:
        if not is_answering:
            reasoning += delta.reasoning_content
    if delta.content:
        if not is_answering:
            is_answering = True
        answer += delta.content
        print(delta.content, end="", flush=True)

พารามิเตอร์ preserve_thinking

ตั้งค่า preserve_thinking: true เพื่อให้โมเดลคง Chain-of-Thought จากทุกรอบก่อนหน้า เหมาะกับ Agent Loops หลายขั้นตอน (ปิดไว้โดย default เพื่อประหยัดโทเค็น)

completion = client.chat.completions.create(
    model="qwen3.6-plus",
    messages=conversation_history,
    extra_body={
        "enable_thinking": True,
        "preserve_thinking": True, # รักษา reasoning ทุกรอบ
    },
    stream=True
)

ใช้ Qwen3.6-Plus กับ Claude Code

Qwen API รองรับโปรโตคอล Anthropic แค่เปลี่ยน ENV ก็ใช้งาน Claude Code กับ Qwen3.6-Plus ได้ทันที

npm install -g @anthropic-ai/claude-code

export ANTHROPIC_MODEL="qwen3.6-plus"
export ANTHROPIC_SMALL_FAST_MODEL="qwen3.6-plus"
export ANTHROPIC_BASE_URL=https://dashscope-intl.aliyuncs.com/apps/anthropic
export ANTHROPIC_AUTH_TOKEN=your_dashscope_api_key

claude

ใช้ Qwen3.6-Plus กับ OpenClaw

OpenClaw (เดิม Moltbot / Clawdbot) เป็น Agent เขียนโค้ดแบบ self-hosted

# ติดตั้ง (Node.js 22+)
curl -fsSL https://molt.bot/install.sh | bash

export DASHSCOPE_API_KEY=your_key
openclaw dashboard

แก้ไข ~/.openclaw/openclaw.json เพิ่มฟิลด์ด้านล่าง:

{
  "models": {
    "providers": [{
      "name": "alibaba-coding-plan",
      "baseUrl": "https://coding-intl.dashscope.aliyuncs.com/v1",
      "apiKey": "${DASHSCOPE_API_KEY}",
      "models": [{"id": "qwen3.6-plus", "reasoning": true}]
    }]
  },
  "agents": {
    "defaults": {"models": ["qwen3.6-plus"]}
  }
}

ใช้ Qwen3.6-Plus กับ Qwen Code

Qwen Code เป็น Agent เทอร์มินัลแบบ Open-source จาก Alibaba ใช้ API ฟรี 1,000 ครั้ง/วันหลัง sign-in

npm install -g @qwen-code/qwen-code@latest
qwen
# พิมพ์ /auth เพื่อลงชื่อเข้าใช้และเปิดใช้งาน Free Tier

เหตุใด preserve_thinking จึงเปลี่ยนแปลงพฤติกรรมของ Agent

API LLM ทั่วไปจะไม่คง reasoning ข้ามแต่ละรอบ ทำให้ Agent หลุดประเด็นเมื่อต้องทำหลาย step

preserve_thinking จะเก็บ chain-of-reasoning ข้ามรอบ Agent เหมาะกับงานที่ต้องใช้ context reasoning หลายขั้นตอน

conversation = []

def agent_step(user_message, preserve=True):
    conversation.append({"role": "user", "content": user_message})

    response = client.chat.completions.create(
        model="qwen3.6-plus",
        messages=conversation,
        extra_body={
            "enable_thinking": True,
            "preserve_thinking": preserve,
        },
        stream=False
    )

    message = response.choices[0].message
    conversation.append({"role": "assistant", "content": message.content})
    return message.content

# ตัวอย่าง: Agent ตรวจสอบโค้ดแบบหลายขั้นตอน
result = agent_step("Analyze the auth module for security issues.")
result = agent_step("Now suggest fixes for the top 3 issues you found.")
result = agent_step("Write tests that validate each fix.")

ถ้าไม่มี preserve_thinking โมเดลจะไม่รู้ว่าขั้นที่ 1 เจอปัญหาอะไร แต่เมื่อเปิด reasoning chain จะไม่หลุด context

เหมาะสำหรับอะไรมากที่สุด

  • การแก้ไขข้อบกพร่องระดับ Repository: SWE-bench Verified 78.8% และ Pro 56.6%
  • ระบบอัตโนมัติสำหรับเทอร์มินัล: นำใน Terminal-Bench 2.0
  • การเรียกใช้เครื่องมือ MCP: MCPMark 48.2% (สูงสุด)
  • การวิเคราะห์เอกสารแบบ Long-context: Context Window 1M โทเค็น เหมาะกับ Codebase/Doc ขนาดใหญ่
  • Frontend code generation: QwenWebBench 1501.7 คะแนน ใกล้เคียง Claude Opus 4.5
  • หลายภาษา (Multilingual): WMT24++ 84.3%, MAXIFE 88.2% ครอบคลุม 23 ภาษา

การทดสอบการเรียกใช้ API ของ Qwen3.6-Plus ด้วย Apidog

Endpoint เข้ากันได้กับ OpenAI สามารถนำเข้าไปใน Apidog และทดสอบเหมือน API อื่นๆ

Apidog test

ตัวอย่างการตั้งค่า:

  • URL: https://dashscope-intl.aliyuncs.com/compatible-mode/v1/chat/completions
  • Header: Authorization: Bearer {{DASHSCOPE_API_KEY}}

ตัวอย่าง Assertion ใน Apidog:

pm.test("Response contains choices", () => {
  const body = pm.response.json();
  pm.expect(body).to.have.property("choices");
  pm.expect(body.choices[0].message.content).to.be.a("string").and.not.empty;
});

pm.test("No empty reasoning when thinking enabled", () => {
  const choice = pm.response.json().choices[0];
  if (choice.message.reasoning_content !== undefined) {
    pm.expect(choice.message.reasoning_content).to.not.be.empty;
  }
});

ใช้ Smart Mock ของ Apidog เพื่อจำลอง response ระหว่างการพัฒนา ไม่ต้องเปลืองโทเค็นและทดสอบได้เร็ว

ถ้าสร้าง Agent หลายรอบ ให้สร้าง Test Scenario เชื่อมโยงหลาย request ตรวจสอบว่า preserve_thinking คง context reasoning ได้จริงก่อนนำไป production

ดาวน์โหลด Apidog ฟรี เพื่อตั้งค่าการทดสอบนี้

มีอะไรกำลังจะมา

ทีม Qwen เตรียมเปิดตัวเวอร์ชัน Open-source ขนาดเล็กในไม่กี่วัน (รูปแบบ Apache 2.0, Sparse MoE เหมือน Qwen3.5)

Roadmap ที่จะตามมา:

  • งานระดับ Repository กับไฟล์ขนาดใหญ่ขึ้น
  • Agent แบบ Multimodal ที่ควบคุม GUI และ Visual Coding เป็นความสามารถหลัก

หาก Qwen3.6 เหมือน Qwen3.5 เวอร์ชัน Open-source จะกลายเป็นตัวเลือกหลักสำหรับ self-hosted coding agent เร็วๆ นี้

สรุป

Qwen3.6-Plus ลดช่องว่างกับ Claude Opus 4.5 ในงานเขียนโค้ด นำในเทอร์มินัล, เครื่องมือ MCP, การวางแผนยาว Context Window 1M, Protocol Anthropic-compatible และ preserve_thinking เหมาะกับ Agentic System พร้อมใช้งานจริง

API อย่างเป็นทางการให้ความเสถียร SLA และฟีเจอร์ใหม่ที่เหมาะกับ Agent โดยเฉพาะ

Apidog ช่วยให้ทดสอบ API, Assertion, Mock และ Regression Test ได้สะดวกทุกครั้งที่อัปเดตโมเดลหรือ API

คำถามที่พบบ่อย

Qwen3.6-Plus และเวอร์ชันพรีวิวแตกต่างกันอย่างไร?

เวอร์ชันพรีวิว (qwen/qwen3.6-plus-preview) เปิดตัวบน OpenRouter เมื่อ 30 มี.ค. 2026 เวอร์ชันทางการเพิ่ม preserve_thinking, SLA และรองรับ Model Studio เต็มรูปแบบ เวอร์ชัน Open-source เล็กกว่ากำลังจะมา

preserve_thinking คืออะไร และควรใช้เมื่อใด?

โดยปกติ reasoning จะคงเฉพาะรอบปัจจุบัน ถ้าตั้งค่า preserve_thinking: true reasoning chain จะคงข้ามรอบ ใช้กับ Agent Loops หลายขั้นตอนที่ต้องเห็น reasoning เก่าด้วย

Qwen3.6-Plus เปรียบเทียบกับ Claude Opus 4.5 อย่างไร?

Claude Opus 4.5 นำใน SWE-bench Verified (80.9% vs 78.8%) และ OSWorld-Verified (66.3% vs 62.5%) แต่ Qwen3.6-Plus นำใน Terminal-Bench 2.0 (61.6% vs 59.3%), MCPMark (48.2% vs 42.3%), DeepPlanning (41.5% vs 33.9%) และ GPQA (90.4% vs 87.0%)

ฉันสามารถใช้ Qwen3.6-Plus กับ Claude Code ได้หรือไม่?

ได้ ตั้งค่า ANTHROPIC_BASE_URL ไปยัง Dashscope Anthropic endpoint, ANTHROPIC_MODEL เป็น qwen3.6-plus และ ANTHROPIC_AUTH_TOKEN เป็น Dashscope API key

Qwen3.6-Plus เป็น Open Source หรือไม่?

API โมเดลที่โฮสต์ไม่ใช่ Open-weight แต่เวอร์ชันเล็กกว่าและ Weights สาธารณะยืนยันแล้วว่าจะเปิดตัวเร็วๆ นี้

ฉันจะเข้าถึงได้ฟรีได้อย่างไร?

ติดตั้ง Qwen Code (npm install -g @qwen-code/qwen-code@latest), รัน qwen แล้ว /auth เพื่อ sign-in ด้วย Qwen Code OAuth รับสิทธิ์เรียก API ฟรี 1,000 ครั้ง/วัน

รองรับ Context Window ขนาดเท่าใด?

1 ล้านโทเค็นเป็นค่าเริ่มต้น บาง benchmark ใช้ 256K เพื่อมาตรฐานเปรียบเทียบ แต่ API default คือ 1M

ฉันจะทดสอบการผสาน API ก่อนปรับใช้งานจริงได้อย่างไร?

นำเข้า Endpoint ไปยัง Apidog, เพิ่ม API key เป็น env, เขียน Assertion และใช้ Smart Mock ระหว่างพัฒนา เชื่อมโยง request เป็น Test Scenario เพื่อตรวจสอบ Agent หลายรอบตั้งแต่ต้นจนจบ

Debugging a CLI Tool Blindspot: Why “Reload” Commands Don’t Always Reload Everything

As developers, we love automation tools and CLI wrappers. They save us time, abstract away complex configurations, and make our workflows smoother. But what happens when the tool designed to manage your configuration lies to you?

Recently, I encountered a fascinating edge case while managing API keys for my Claude Code environment using a third-party CLI helper (@z_ai/coding-helper).

This is a story about “split-brain” configurations, digging into node_modules to find the truth, and why you should never blindly trust a CLI’s success message.

The Ghostly “429 Plan Expired” Error

My setup involved using Claude Code powered by a specific API plan (GLM Coding Plan). After my initial API key expired, I renewed my subscription, got a new key, and ran the standard command provided by the CLI helper to reload my credentials:

chelper auth reload claude

I even ran the built-in health check (chelper doctor), and everything returned a perfect string of green checkmarks. Path? Valid. API Key & Network? Valid. Plan? Active.

However, the moment I tried to invoke a Model Context Protocol (MCP) tool—specifically, the web-reader tool—the agent instantly crashed with this error:

Error: MCP error -429: {"error":{"code":1309,"message":"Your GLM Coding Plan has expired, please renew to restore access."}}

Wait a minute. The health check passed, standard chats worked perfectly, but MCP tools were screaming that my account was expired.

The Investigation: Spot the Difference

Since the UI and the CLI tool were giving me conflicting information, I bypassed them and went straight to the underlying configuration files.

I checked the two places where credentials could theoretically be stored:

  1. The CLI helper’s main config (~/.chelper/config.yaml): This contained my brand new, valid API key.
  2. Claude Code’s MCP config (~/.claude.json): Looking at the mcpServers object, I checked the HTTP headers.

Boom. The Authorization: Bearer header for the MCP tools was still using the old, expired API key.

We had a “split-brain” scenario. The MCP tools were reading from a stale configuration file.

Root Cause Analysis: Diving into node_modules

Why didn’t chelper auth reload update the MCP config? To find out, I opened up the CLI’s source code located in node_modules/@z_ai/coding-helper/dist/lib/claude-code-manager.js.

I tracked down the exact function responsible for reloading the configuration:

loadGLMConfig(plan, apiKey) {
    // 1. Ensure onboarding is completed
    this.ensureOnboardingCompleted();

    // 2. Clean up shell environment variables
    this.cleanupShellEnvVars();

    // 3. Update ANTHROPIC_AUTH_TOKEN in settings.json
    this.saveSettings(glmConfig);
}

The flaw in the architecture was immediately obvious.

Claude Code actually splits its configuration into two distinct files:

  • ~/.claude/settings.json (Used for standard Claude API calls)
  • ~/.claude.json (Used to register MCP servers and their auth headers)

The developer of the CLI tool only programmed this.saveSettings() to update the standard API token. The tool completely ignored the MCP server configurations. As a result, any HTTP-based MCP tools registered previously were left stranded with expired credentials.

The Fix

If you are dealing with a similar misbehaving CLI wrapper, you can’t rely on its reload command. You have a few options:

Option 1: The Nuclear Option (Recommended)
Run the initialization command again from scratch. This usually forces the tool to overwrite all files completely.

npx @z_ai/coding-helper init

Option 2: The Python Automation Fix
If you have heavily customized your mcpServers and don’t want to reset everything, I wrote a quick Python script to automatically hunt down HTTP-based MCP tools in your config and update their headers securely:

import json
import os

config_path = os.path.expanduser('~/.claude.json')
new_key = "YOUR_NEW_VALID_API_KEY"

try:
    with open(config_path, 'r') as f:
        config = json.load(f)

    # Iterate through all configured MCP servers
    for mcp_name, mcp_config in config.get('mcpServers', {}).items():
        # Update only those that use HTTP headers for authentication
        if 'headers' in config.get('mcpServers', {}).get(mcp_name, {}):
            config['mcpServers'][mcp_name]['headers']['Authorization'] = f'Bearer {new_key}'
            print(f"Updated auth token for MCP tool: {mcp_name}")

    with open(config_path, 'w') as f:
        json.dump(config, f, indent=2)
    print("All MCP keys updated successfully!")

except FileNotFoundError:
    print("Error: ~/.claude.json configuration file not found.")

The SDET Takeaway

This is why Software Development Engineers in Test (SDETs) don’t just rely on UI green lights or standard CLI outputs.

When an automation tool tells you “Success!” but the system behaves as if it failed, there is almost always a state synchronization issue underneath. The abstraction layers designed to help us can quickly become blindspots.

The Golden Rule of Debugging Toolchains: When system behavior contradicts configuration state, stop trusting the management tools and start reading the raw .json and .yaml files.

Addressing Common Developer Criticisms of Python: Balancing Strengths and Weaknesses

Introduction: Python’s Popularity and the Need for Critical Evaluation

Python’s meteoric rise as the go-to language for data science, machine learning, and web development is undeniable. Its interpreted nature and dynamic typing make it accessible to beginners, as evidenced by my own journey from the syntactic hurdles of C++ and Java to Python’s intuitive design. However, this very accessibility masks mechanical trade-offs that become critical in performance-sensitive environments. Python’s interpreter executes code line-by-line, introducing overhead that compiled languages like C++ avoid by translating code directly into machine instructions. This overhead is negligible for small scripts but accumulates in CPU-bound tasks, where every cycle counts.

The language’s Global Interpreter Lock (GIL) further complicates its performance profile. The GIL is a mutex that prevents multiple native threads from executing Python bytecode simultaneously, even on multi-core systems. While it simplifies memory management by preventing race conditions, it serializes CPU-bound tasks, effectively neutralizing the benefits of parallel processing. This limitation becomes a breaking point in domains like financial modeling, where real-time calculations hinge on efficient core utilization.

Python’s dynamic typing, a boon for rapid prototyping, introduces runtime risks in large-scale projects. Without compile-time type checks, errors like mismatched data types or null references propagate undetected until execution. These errors are not merely inconveniences—they deform the reliability of systems, forcing developers to rely on extensive testing or third-party tools like mypy to mitigate risks. This trade-off between flexibility and safety is a causal chain that impacts Python’s suitability for mission-critical applications.

Despite these criticisms, Python’s ecosystem thrives through complementary tools that address its limitations. Cython and PyPy bridge the performance gap by compiling Python to C or using a just-in-time (JIT) compiler, respectively. Asynchronous programming frameworks like asyncio sidestep the GIL by enabling I/O-bound tasks to run concurrently. However, these solutions are not silver bullets. Cython requires rewriting Python code with static types, while PyPy’s compatibility issues limit its adoption. The optimal strategy depends on the use case: if performance is critical and the codebase is stable, use Cython; if compatibility is non-negotiable, stick to CPython with asyncio.

Python’s role in emerging fields like machine learning illustrates its evolving dichotomy. Libraries like TensorFlow and PyTorch prioritize developer productivity over raw performance, leveraging Python’s simplicity to abstract complex mathematical operations. Here, the language’s limitations are outweighed by its ability to accelerate innovation. Yet, in high-performance computing (HPC), where low-level control is paramount, Python’s abstractions break down, forcing integration with languages like Fortran or C++ for computationally intensive kernels.

In conclusion, Python’s popularity is both its strength and its Achilles’ heel. Its criticisms are not flaws but mechanical consequences of design choices that prioritize accessibility and productivity. To balance these trade-offs, developers must adopt a polyglot approach, leveraging Python for rapid development while offloading performance-critical tasks to more specialized languages. If scalability and performance are non-negotiable, avoid Python as the sole language; if prototyping speed is key, embrace it but plan for eventual integration with lower-level tools.

Common Criticisms of Python: A Developer’s Perspective

As someone who’s danced through the syntax of C++, wrestled with Java’s verbosity, and finally found solace in Python’s simplicity, I’ve often wondered why a language so beginner-friendly faces such sharp criticism from seasoned developers. Let’s dissect the six most common grievances against Python, grounding each in technical mechanisms and real-world implications.

1. Performance Limitations: The Interpreted Overhead

Python’s interpreted nature is both its strength and its Achilles’ heel. Unlike compiled languages like C++ or Java, Python code is executed line-by-line by the interpreter. This introduces a mechanical overhead: each line must be parsed, compiled to bytecode, and then executed. In CPU-bound tasks—think financial modeling or scientific simulations—this overhead accumulates, leading to performance bottlenecks. For instance, a nested loop in Python can run 10-100x slower than its C++ counterpart due to the repeated interpretation and dynamic type checking.

Mechanism: The interpreter’s step-by-step execution heats up the CPU with redundant context switching, while dynamic typing forces runtime checks that compiled languages resolve at compile time.

2. The Global Interpreter Lock (GIL): A Parallelism Killer

Python’s Global Interpreter Lock (GIL) is a mutex that serializes thread execution, preventing multiple native threads from running concurrently in CPU-bound tasks. This design choice simplifies memory management but neutralizes the benefits of multi-core processors. In a quad-core CPU, for example, Python threads will still execute sequentially, leaving 75% of the hardware idle. This makes Python ill-suited for tasks like real-time game physics or parallel data processing.

Mechanism: The GIL acts as a bottleneck, forcing threads to wait in line for CPU access, akin to a single-lane bridge in a four-lane highway.

3. Dynamic Typing: Flexibility at the Cost of Reliability

Python’s dynamic typing allows variables to change types on the fly, which is great for rapid prototyping but disastrous for large-scale projects. Type-related errors propagate undetected until runtime, where they manifest as crashes or incorrect results. For instance, a function expecting an integer might receive a string, causing a traceback deep in the call stack. This lack of compile-time checks increases the risk of bugs in complex systems.

Mechanism: Without static type enforcement, the interpreter cannot preemptively flag type mismatches, leaving the codebase vulnerable to runtime failures.

4. Dependency Management: A Double-Edged Sword

Python’s package ecosystem is vast but fragmented. While libraries like NumPy and Pandas are game-changers, managing dependencies across projects can be chaotic. Tools like pip and virtual environments help, but version conflicts remain a common pain point. For example, a project requiring TensorFlow 1.x and another needing 2.x can lead to dependency hell, where resolving incompatibilities becomes a full-time job.

Mechanism: The lack of a centralized dependency resolution system forces developers to manually reconcile conflicting library versions, often leading to broken builds.

5. Mobile and Game Development: Niche Limitations

Python’s interpreted nature and GIL make it a poor fit for mobile and game development, where low latency and high performance are non-negotiable. Mobile apps require efficient memory usage and fast execution, while games demand real-time rendering and physics calculations. Python’s abstractions, while developer-friendly, introduce latency that’s unacceptable in these domains. For instance, a Python-based game would struggle to maintain 60 FPS in a complex 3D environment.

Mechanism: The interpreter’s overhead and GIL’s serialization delay critical operations, causing frame drops and unresponsive UIs.

6. Advanced Features: A Steep Learning Curve

While Python is beginner-friendly, its advanced features—decorators, generators, metaclasses—have a steep learning curve. Misusing these can lead to unreadable or inefficient code. For example, overusing decorators can obscure control flow, while misconfigured metaclasses can break object inheritance. This duality makes Python accessible to novices but challenging to master.

Mechanism: Advanced features require a deep understanding of Python’s internals, and their misuse can introduce subtle bugs or performance penalties.

Mitigation Strategies: Balancing Trade-offs

  • Performance-Critical Tasks: Use Cython to compile Python to C, improving performance by 10-100x. However, this requires static type annotations and is only effective for stable codebases.
  • Concurrency: Leverage asyncio for I/O-bound tasks or offload CPU-bound tasks to multiprocessing, bypassing the GIL. However, multiprocessing increases memory overhead.
  • Type Safety: Adopt mypy for static type checking, reducing runtime errors. But this adds development overhead and is optional, not enforced.

Professional Judgment: When to Use Python (and When Not To)

Python shines in rapid prototyping, data science, and web development, where developer productivity outweighs performance concerns. However, for performance-critical, real-time, or resource-constrained applications, consider a polyglot approach: use Python for high-level logic and offload bottlenecks to C++, Rust, or specialized libraries.

Rule of Thumb: If X (performance, scalability, or strict type safety) is critical, use Y (compiled languages or Python with mitigations). Otherwise, Python’s simplicity and ecosystem make it a strong contender.

In the end, Python’s criticisms are not flaws but design trade-offs. Understanding these trade-offs allows developers to wield Python effectively, avoiding its pitfalls while harnessing its strengths.

Comparative Analysis: Python vs. Other Languages

Python’s criticisms often stem from its design trade-offs, which become more pronounced in specific environments. To understand whether these issues are unique to Python, let’s compare them with other languages like C++, Java, and Rust, using the lens of its interpreted nature, dynamic typing, Global Interpreter Lock (GIL), and high-level abstractions.

1. Performance: Interpreted vs. Compiled Languages

Python’s interpreted nature introduces mechanical overhead: each line is parsed, compiled to bytecode, and executed sequentially. This process creates redundant context switching and runtime type checks, causing CPU-bound tasks to run 10-100x slower than compiled languages like C++. For example, nested loops in Python suffer from accumulated overhead, while C++ compiles directly to machine code, eliminating this bottleneck.

Comparative Insight: Java, though also interpreted at the JVM level, uses Just-In-Time (JIT) compilation, which optimizes frequently executed code, reducing overhead. Rust, a compiled language, offers zero-cost abstractions, making it comparable to C++ in performance. Python’s performance gap is thus a trade-off for its accessibility, not a universal flaw.

2. Dynamic Typing: Flexibility vs. Reliability

Python’s dynamic typing allows variables to change types at runtime, introducing type errors that go undetected until execution. In large-scale projects, this increases the risk of runtime crashes or incorrect results. For instance, a function expecting an integer might receive a string, causing a failure deep in the execution flow.

Comparative Insight: Java’s static typing catches type mismatches at compile time, reducing runtime risks. Rust goes further with its ownership model, enforcing memory safety and type correctness at compile time. Python’s flexibility is a strength for rapid prototyping but a weakness in reliability-critical domains. Tools like mypy mitigate this, but they add development overhead.

3. Global Interpreter Lock (GIL): Parallelism Killer

Python’s GIL is a mutex that serializes thread execution, preventing true parallel processing of CPU-bound tasks. This limits multi-core utilization—a quad-core CPU might have 75% idle cores during CPU-bound operations. The GIL exists to simplify memory management but neutralizes parallel processing benefits.

Comparative Insight: Java and C++ allow true multi-threading, leveraging all CPU cores. Rust’s fearless concurrency model avoids data races at compile time, enabling efficient parallelism. Python’s GIL is a unique limitation, making it unsuitable for CPU-bound, multi-threaded applications. Mitigation strategies like multiprocessing (spawning separate processes) bypass the GIL but increase memory overhead.

4. Ecosystem Fragmentation: Dependency Hell

Python’s vast but fragmented package ecosystem lacks centralized dependency resolution. Version conflicts (e.g., TensorFlow 1.x vs. 2.x) lead to dependency hell, where manual reconciliation is required to avoid broken builds. This fragmentation increases the risk of incompatible libraries coexisting in the same project.

Comparative Insight: Java’s Maven and Rust’s Cargo provide centralized dependency management, reducing version conflicts. Python’s pip and conda offer solutions but require careful management. This issue is not unique to Python but is exacerbated by its rapid ecosystem growth.

Professional Judgment: When to Use Python (and When Not To)

  • Use Python for: Rapid prototyping, data science, web development (where productivity > performance).
  • Avoid Python for: Performance-critical, real-time, or resource-constrained applications.
  • Polyglot Approach: Use Python for high-level logic and offload bottlenecks to C++, Rust, or specialized libraries.

Rule for Choosing a Solution: If X (performance-critical, CPU-bound task) → use Y (C++, Rust, or Python with Cython/multiprocessing). If X (rapid prototyping, data analysis) → use Y (Python with its extensive libraries).

Key Insight: Python’s criticisms are not flaws but design trade-offs. Understanding these trade-offs enables effective use, balancing strengths and pitfalls.

Conclusion: Weighing the Pros and Cons of Python

Python’s meteoric rise in fields like data science, web development, and machine learning is undeniable, but its criticisms are equally grounded in technical realities. To make informed decisions, developers must dissect these critiques through the lens of system mechanisms, environmental constraints, and practical trade-offs.

Core Criticisms: Mechanisms and Implications

Python’s interpreted nature introduces mechanical overhead—each line is parsed, compiled to bytecode, and executed sequentially. This process, while enabling accessibility, creates a performance bottleneck in CPU-bound tasks. For instance, nested loops in financial modeling can run 10-100x slower than C++ due to redundant context switching and runtime type checks. Impact: Delayed calculations in real-time systems. Rule: For CPU-bound tasks, use Cython (static type annotations) or offload to C++.

The Global Interpreter Lock (GIL) acts as a mutex, serializing thread execution. This neutralizes multi-core benefits in parallel processing, leaving up to 75% of CPU cores idle in quad-core systems. Impact: Scalability issues in large web applications. Mitigation: Use multiprocessing (increased memory overhead) or asyncio for I/O-bound tasks. Rule: Avoid Python for real-time or parallel CPU-bound tasks.

Dynamic typing trades flexibility for reliability. Type errors propagate undetected until runtime, increasing crash risks in large-scale projects. Impact: Unreliable codebases. Mitigation: Adopt mypy for static type checking. Rule: Use Python for rapid prototyping; enforce type safety in critical systems.

Polyglot Approach: Balancing Strengths and Weaknesses

Python excels in productivity-focused domains like data science and web development, but its limitations necessitate a polyglot strategy. For performance-critical tasks, integrate Python with C++ or Rust. For example, in HPC, Python’s abstractions are paired with Fortran for computationally intensive tasks. Key Insight: Python’s criticisms are design trade-offs, not flaws. Understanding these enables strategic use.

Professional Judgment: When to Use (and Avoid) Python

  • Use Python for: Rapid prototyping, data analysis, web development (where productivity > performance).
  • Avoid Python for: Performance-critical, real-time, or resource-constrained applications.
  • Rule: If X (performance-critical/CPU-bound), use Y (C++, Rust, or Python with Cython/multiprocessing).

Python’s criticisms are not dealbreakers but signals for informed decision-making. By understanding its mechanisms and trade-offs, developers can harness its strengths while mitigating weaknesses, ensuring its effective use in the right contexts.

I built a zero-dependency portfolio template — here’s what I learned

Most portfolio templates come with React, Next.js, or at least a build step. I wanted something different: a template that designers can actually understand and modify without touching a terminal (beyond the initial setup).

So I built one from scratch. 300KB. Zero dependencies. Vanilla everything.

Why vanilla?

I’m a product designer who codes. My own portfolio (diyor.design) runs on plain HTML, CSS, and JavaScript. When I decided to turn it into a template, I had a choice: rewrite it in a framework, or keep it simple.

I kept it simple. Here’s why:

  • Designers can read it. No JSX, no components, no state management. Just HTML files you can open in a browser.
  • No build step. Edit a file, refresh the browser. Done.
  • It’ll work in 10 years. No deprecated packages, no breaking updates, no npm audit warnings.
  • 300KB total. The entire template. Not the JavaScript bundle — the whole thing.

What’s inside

  • Bilingual support — Russian and English with a language switcher. Easy to adapt for any two languages.
  • Dark mode — toggle button + automatic system preference, saved in localStorage.
  • Case study template — numbered sections, stats grid, image lightbox with zoom, previous/next navigation.
  • Terminal easter egg — press ~ for a secret terminal with design quotes.
  • Design system overlay — press Shift+G to see the 12-column grid.
  • One-command setup — ./setup.sh asks your name, generates a favicon, replaces all placeholders.
  • SEO ready — Open Graph, JSON-LD, sitemap, canonical tags, hreflang.
  • Accessible — ARIA, keyboard nav, focus-visible, reduced motion.

The setup experience

git clone https://github.com/diyoriko/portfolio-template.git my-portfolio
cd my-portfolio
./setup.sh

The script asks for your name, domain, email, socials. Then it:

  • Replaces “Jane Smith” everywhere
  • Generates an SVG favicon with your initial
  • Updates CNAME, sitemap, config.json
  • Done. Push to GitHub Pages.

What I’d do differently

The dark mode architecture. I started with just prefers-color-scheme but quickly realized users want a manual toggle. I ended up with a dual system: @media (prefers-color-scheme: dark) { :root:not(.light) { ... } } for auto mode, plus html.dark { ... } for manual. It works, but the CSS is duplicated. Next time I’d use CSS layers or a single class-based approach from the start.

Hardcoded colors. My first pass had rgba(0, 0, 0, 0.08) scattered everywhere for borders and shadows. In dark mode, they were invisible. I had to go back and replace them all with CSS custom properties. Lesson: use variables from day one, even for “obvious” values.

Try it

MIT licensed. If you build something with it, I’d love to see it.

I’m Diyor, a product and brand designer. I write about design systems, automation, and building things from scratch. diyor.design

I built a 1500-Level Puzzle Game in Pure Vanilla JS (And how AI helped me solve the hardest part)

🖥️ Source Code: https://github.com/moksh-jalendra/ziply-puzzel
🎮 Play Ziply Live: https://html5.gamemonetize.co/d7a965ple3vols2kwz51d646oclw79mh/

Whenever we start a new web project today, the immediate reflex is to run npx create-react-app or spin up a Next.js boilerplate. But what happens when you want to build a highly interactive, 1500-level logic puzzle game that needs to run flawlessly on low-end mobile devices?

You drop the frameworks and go back to the basics.

I recently launched Ziply, a line-drawing logic puzzle game. Instead of using a heavy game engine like Unity or a web framework like React, I built it entirely from scratch using Core Vanilla JS, HTML, and CSS.

Here is a breakdown of the architecture, the performance choices I made, and how I used AI to overcome my biggest algorithm roadblock.

  1. Why Vanilla JS? (Performance & Control)
    In a game where the user is rapidly dragging their finger across a grid to draw pipes, frame rate is everything.

If I used React, every single tile touch would trigger a state change, potentially causing heavy re-renders of the entire 8×8 grid. By using Vanilla JS, I had absolute control over the event loop and memory management. I could bind touchstart and touchmove events directly to the container, track the exact coordinates of the user’s finger, and update the game state in a fraction of a millisecond without any framework overhead.

  1. The Architecture: A DOM + Canvas Hybrid
    The biggest visual challenge was rendering the glowing “pipes” as the user swipes.

Building the entire game in means writing custom hit-boxes, event listeners, and UI scaling logic from scratch. But using pure HTML/CSS to draw connecting lines is a nightmare of absolute positioning.

My Solution: A hybrid approach.

I used CSS Grid to generate the actual game board using standard

elements. This gave me built-in responsiveness and dead-simple hit detection using document.elementFromPoint(). Then, I layered a completely transparent element directly on top of the CSS Grid.

JavaScript
// The DOM handles the logic and hit detection
let ellement = document.elementFromPoint(clientX, clientY);
let gridx = ellement.dataset.x;
let gridy = ellement.dataset.y;

// The Canvas acts purely as a visual presentation layer
function drawPipe() {
ctx.clearRect(0, 0, canvas.width, canvas.height);
ctx.beginPath();
// Loop through the path array and draw lines
// connecting the centers of the DOM nodes
ctx.stroke();
}
The DOM acts as the invisible brain handling touch events, and the Canvas acts as the paint. It is the best of both worlds.

  1. The Hint System & My AI Pair Programmer
    The hardest feature to build by far was the Hint System.

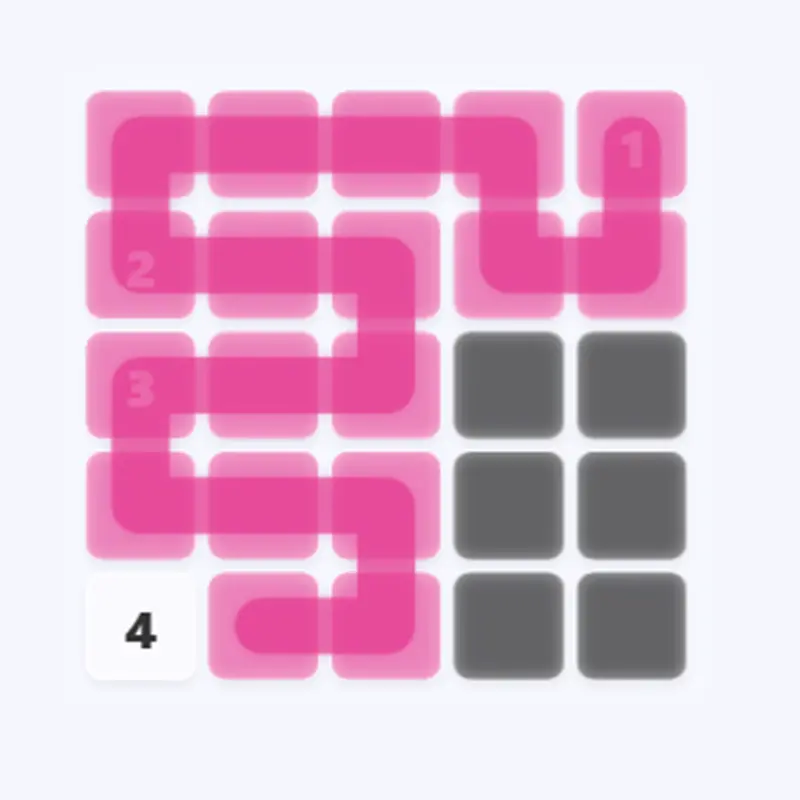
The core rule of Ziply is that you must connect the numbers in order and fill every single empty block on the board.

Initially, I tried to write a simple Breadth-First Search (BFS) to find the path to the next number. This was a disaster. The BFS would find the shortest route, but in doing so, it would cut corners and block off empty tiles, giving the player a hint that made the level literally impossible to beat.

I realized I needed a Depth-First Search (DFS) with Backtracking algorithm. It needed to simulate playing the game invisibly, exploring thousands of paths, and backtracking when it got trapped, only stopping when it found a verified 100% win path.

Transparency time: I am a web developer, and advanced pathfinding algorithms aren’t my strong suit. I had no idea how to write a Backtracking DFS from scratch.

Instead of letting the feature die, I used Gemini as my pair-programmer. I fed the AI the rules of my game grid, explained why the BFS was failing, and worked with it to generate and refine a DFS solver.

JavaScript
// The Backtracking Solver generated with AI
function solve(currentPath, currentExpected) {
if (bestSolution) return;

// PERFECT WIN CONDITION: Path fills all tiles AND ends on highest number
if (currentPath.length === targetLen && cellVal === maxNum) {
    bestSolution = [...currentPath];
    return;
}

let neighbors = [`${cx+1}-${cy}`, `${cx-1}-${cy}`, `${cx}-${cy+1}`, `${cx}-${cy-1}`];

for (let n of neighbors) {
    if (isValidMove(n)) {
        currentPath.push(n);
        solve(currentPath, nextExpected); // Recursive dig
        currentPath.pop(); // Backtrack if it's a dead end
    }
}

}
Integrating the AI-generated algorithm into my existing game loop, connecting it to the UI animations, and debugging the edge cases was an incredible learning experience. It taught me how powerful AI can be when you use it to bridge the gaps in your own knowledge.

Play it for yourself!
Building Ziply was an amazing exercise in pushing the DOM to its limits and learning how to leverage modern AI tools to solve complex computer science problems.

I would love for the DEV community to try it out. See if you can beat Level 10 on the 6×6 Master Mode!

🎮 Play Ziply Live: https://html5.gamemonetize.co/d7a965ple3vols2kwz51d646oclw79mh/

If you have any feedback on the UI, the touch controls, or the code architecture, let me know in the comments!


Building a Robust E-Signature Workflow: Lessons from an HRMS Implementation.

smyekh profile

If your product handles offer letters, contracts, onboarding forms, NDAs, or approval workflows, document signing eventually becomes a core feature, not just a nice-to-have.

I recently implemented e-sign documents in an HRMS platform using DocuSeal, with both frontend and backend support. The goal was simple: users should be able to open a document inside the app, sign it, and let the system automatically store the final signed copy and audit log.

This post breaks down the architecture I used and turns it into a** reusable implementation pattern** you can apply in almost any project.

Why DocuSeal worked well for this use case

When adding document signing to a product, I needed a setup that could support:

  • Template-based signing
  • Multiple signers
  • Embedded signing inside the app
  • Prefilled user data
  • Webhook/callback support
  • Final signed document retrieval

DocuSeal fits this flow well. It lets you create templates, generate submissions, embed the signing UI, and receive completion callbacks.

That means your app can own the business logic and workflow state, while DocuSeal handles the actual signing experience.

The architecture at a glance

A clean document-signing flow usually looks like this:

  1. Upload a document and create a DocuSeal template
  2. Define signer roles and fields
  3. Create a submission for a specific user
  4. Prefill known values like name, email, and address
  5. Open the embedded signing UI in the frontend
  6. Receive a callback when signing is completed
  7. Download the signed files and audit log
  8. Store everything in your own system

Here’s the same flow in a simple developer-friendly view:

The architecture at a glance

Frontend -> requests signing URL / slug from Backend Backend -> authenticates user -> fetches DocuSeal submission details -> returns signer slug Frontend -> mounts DocuSeal -> sends callback/webhook on completion Backend -> verifies callback secret -> queues event processing -> downloads signed PDF + audit log -> stores files -> updates signer/package status in DB

1. Keep DocuSeal behind your backend

A critical architectural decision is keeping the DocuSeal API behind your backend.

Why this matters:

  • your API key stays private
  • you control submission creation
  • you can validate permissions before exposing a signing session
  • you can map DocuSeal IDs to your own internal records

In my project, the backend used environment-based configuration like:

  • DOCUSEAL_API_KEY
  • DOCUSEAL_ADMIN_EMAIL
  • DOCUSEAL_BASE_URL
  • DOCUSEAL_CALLBACK_EVENT_SECRET_KEY
  • DOCUSEAL_CALLBACK_EVENT_SECRET_VALUE

This pattern is much safer than letting the frontend talk directly to DocuSeal.

2. Create templates from uploaded files

The first backend capability you need is template creation.
In my implementation, the backend:

  • reads the uploaded file
  • sends it to DocuSeal
  • uses /templates/pdf for PDFs
  • uses /templates/docx for DOCX files

This makes any uploaded contract, policy, or agreement reusable as a signing template.

Best practice: treat templates as reusable infrastructure, not one-off documents.

3. Use a template builder for field placement

On the frontend, I used @docuseal/react and embedded the DocusealBuilder component.

That allowed admins to:

  • open a template
  • define signer roles
  • place fields like text, date, phone, checkbox, and signature
  • save the field metadata back into our own system

This is an important design choice. Document signing is not just “upload and sign.” You also need to know:

  • which field belongs to which signer
  • which fields are prefilled
  • *how those fields map back to your own domain model
    *

4. Create submissions dynamically

Once the template exists, the next step is creating a submission.
In HRMS, a submission is created when a user needs to sign a document package. The backend sends DocuSeal:

  • template_id
  • signer list
  • signing order
  • delivery preferences
  • prefilled field values

For each signer, I passed values like:

  • name
  • email
  • phone
  • external_id
  • role
  • fields

The external_id is especially useful because it links the DocuSeal signer back to your own user record.

That one field makes later syncing dramatically easier.

5. Prefill known user data

This is one of the biggest UX wins in any signing flow.

Instead of asking users to manually type information your app already knows, I prefilled values such as:

  • first name
  • last name
  • email
  • phone
  • city
  • province
  • postal code
  • street address

A simplified example looks like this:

{ name: "first_name", readonly: true, default_value: user.firstName }

This keeps the signing flow focused on review and approval, not repetitive data entry.

Practical tip: ensure your template field names match either your database keys directly or a clean mapping object.
For example, fields like employee_city, employee_email, or postal_code should map predictably, otherwise the prefill logic becomes messy very quickly.

6. Embed the signer directly in your app

For the signing experience, I used DocusealForm from @docuseal/react.

The frontend fetches the signer slug from the backend, then mounts the signing form inside a modal/dialog:

<DocusealForm src={`https://docuseal.com/s/${submitter.slug}`} email={submitter.email} onComplete={handleComplete} />

This makes the flow feel native to your product, instead of bouncing users to a disconnected external page.

That small UX detail makes a big difference in onboarding and HR workflows.

7. Webhook verification is non-negotiable

This is one area where backend discipline matters.

The frontend onComplete callback is useful for updating the UI, but it should not be your source of truth. The real source of truth should be the backend callback/webhook from DocuSeal.

In my implementation, the backend validates a shared secret header before processing the callback. That ensures the request is actually coming from the signing provider.

At minimum, verify a shared secret header.
If your signing provider supports HMAC-signed webhook verification, that adds an even stronger layer of protection.

Either way, callback verification is not optional.

8. Process callbacks asynchronously

Another important decision was to avoid doing all the heavy work directly inside the callback request.

Instead, the system:

  • accepts the callback
  • pushes it into a queue
  • processes the event in the background
  • updates signer state
  • fetches final submission details
  • downloads signed files
  • stores the audit log

This pattern is much more reliable, especially when:

  • documents are large
  • multiple signers complete at the same time
  • storage uploads take time
  • external API calls are slow

*Queues turn webhook handling from fragile to production-ready.
*

Process callbacks flow

9. Download and store signed files yourself

Once a submission is completed, the backend fetches the final DocuSeal submission and downloads:

  • the signed documents
  • the audit log PDF

Then those files are uploaded into the application’s own storage layer and attached to internal records.

This is a very important design principle:

*DocuSeal should power the signing workflow, but your application should own the final business record.
*

That makes it easier to:

  • show signed files later
  • attach documents to employee records
  • support audits and compliance
  • reduce long-term coupling to the provider

10. Track signer state in your own database

In addition to DocuSeal’s status, I also stored signer state in our own database:

  • pending
  • signed
  • declined

That allowed the product to answer workflow questions such as:

  • which package is still waiting for signature?
  • which signer has completed?
  • should the signing button still be shown?
  • is onboarding ready to move to the next step?

This is the key mindset:
DocuSeal is the signing engine. Your database is the workflow engine.

Practical lessons

Use external_id everywhere. It is the cleanest way to connect DocuSeal events back to your own users.
Prefill aggressively. If your system already knows the data, don’t ask the user to type it again.
Do not trust only the frontend completion event. UI callbacks are for UX; backend callbacks are for correctness.
Store final signed documents in your own system. Do not make the provider your only source of truth.
Separate template management from submission generation. Templates are reusable assets; submissions are workflow instances.

A reusable implementation pattern

If I had to summarise the best implementation pattern for any project, it would be this:

  • Use DocuSeal for template creation and embedded signing
  • Keep all provider communication in the backend
  • Store template metadata in your own DB
  • Create submissions per workflow or transaction
  • Prefill signer fields from your own user data
  • Embed the signer inside your frontend
  • Verify callbacks before processing them
  • Use a queue for callback handling
  • Download and store signed files yourself
  • Track signer status in your own database

reusable implementation pattern

This pattern works well not only for HRMS, but also for:

  • hiring platforms
  • CRMs
  • vendor onboarding systems
  • finance workflows
  • legal tools
  • procurement platforms
  • internal approval systems

Final thoughts

Document signing often looks like a small feature at first, but in practice it touches templates, users, storage, security, callbacks, workflow state, and permissions.

What worked especially well for me was treating DocuSeal as the signing layer, while keeping the actual product logic inside my own backend and frontend.

That gave me the best of both worlds:

  • a fast signing integration
  • full control over the user experience
  • reliable backend processing
  • ownership of the final signed records

If you’re planning to add document signing to your product, this architecture is a strong place to start.

Implement LFU using LRU

📌 Core Idea

LFU (Least Frequently Used) means:

  • Remove the least frequently used key
  • If multiple keys have same frequency → remove least recently used (LRU)

📦 Data Structures Used

We maintain:

  • key → node (for O(1) access)
  • freq → doubly linked list (group nodes by frequency)
  • minFreq (track minimum frequency in cache)

🧱 Structure Visualization

Freq = 1 → [ most recent …. least recent ]

Freq = 2 → [ most recent …. least recent ]

Freq = 3 → [ most recent …. least recent ]

Each frequency has its own LRU list

🚀 Example Walkthrough

Capacity = 2

Step 1: put(1,10)

Freq 1: [1]

minFreq = 1

Step 2: put(2,20)

Freq 1: 2, 1

minFreq = 1

Step 3: get(1)

  • Access key 1
  • Increase its frequency: 1 → 2

Freq 1: [2]

Freq 2: [1]

minFreq = 1

👉 We removed 1 from freq 1 and added to freq 2

Step 4: put(3,30)

Cache is FULL → eviction needed

  • minFreq = 1
  • Look at Freq 1 → [2]

👉 Remove 2

After insertion:

Freq 1: [3]

Freq 2: [1]

minFreq = 1

Step 5: get(3)

  • Move 3 from freq 1 → freq 2

Freq 1: []

Freq 2: [3, 1]

minFreq = 2 (freq 1 is empty now)

Step 6: put(4,40)

Cache full → eviction

  • minFreq = 2
  • Freq 2 → [3, 1]

👉 Remove LRU → 1

After insertion:

Freq 1: [4]

Freq 2: [3]

minFreq = 1

🔥 Key Observations

1. Why multiple lists?

  • Different frequencies → cannot maintain in single list
  • Each frequency maintains its own LRU order

2. Why minFreq?

  • Helps directly find which list to evict from in O(1)

3. Why doubly linked list?

  • O(1) removal
  • Maintain LRU order inside same frequency

🧠 Mental Model

Think of LFU like books:

  • Shelf 1 → least used books
  • Shelf 2 → moderately used
  • Shelf 3 → most used

When removing:

  1. Pick least used shelf
  2. Remove oldest book from that shelf

🧩 Mapping to Code

Concept Code
Increase frequency updateFreq(node)
Remove LRU list->tail->prev
Track minimum minFreq
Insert new node freq = 1

🚨 Common Mistake

When a frequency list becomes empty:

if(freq == minFreq && list is empty)
    minFreq++;

❗ If you don’t update minFreq, eviction will break

Code

class LFUCache {
public:
    class Node {
    public:
        int key, val, freq;
        Node* prev;
        Node* next;

        Node(int k, int v) {
            key = k;
            val = v;
            freq = 1;
        }
    };

    class List {
    public:
        Node* head;
        Node* tail;
        int size;

        List() {
            head = new Node(-1, -1);
            tail = new Node(-1, -1);
            head->next = tail;
            tail->prev = head;
            size = 0;
        }

        void addFront(Node* node) {
            Node* temp = head->next;
            node->next = temp;
            node->prev = head;
            head->next = node;
            temp->prev = node;
            size++;
        }

        void removeNode(Node* node) {
            Node* prevv = node->prev;
            Node* nextt = node->next;
            prevv->next = nextt;
            nextt->prev = prevv;
            size--;
        }
    };

    int cap;
    int minFreq;

    unordered_map<int, Node*> keyNode;        // key -> node
    unordered_map<int, List*> freqList;       // freq -> DLL

    LFUCache(int capacity) {
        cap = capacity;
        minFreq = 0;
    }

    void updateFreq(Node* node) {
        int freq = node->freq;
        freqList[freq]->removeNode(node);

        if (freq == minFreq && freqList[freq]->size == 0) {
            minFreq++;
        }

        node->freq++;

        if (freqList.find(node->freq) == freqList.end()) {
            freqList[node->freq] = new List();
        }

        freqList[node->freq]->addFront(node);
    }

    int get(int key) {
        if (keyNode.find(key) == keyNode.end()) return -1;

        Node* node = keyNode[key];
        updateFreq(node);
        return node->val;
    }

    void put(int key, int value) {
        if (cap == 0) return;

        if (keyNode.find(key) != keyNode.end()) {
            Node* node = keyNode[key];
            node->val = value;
            updateFreq(node);
            return;
        }

        if (keyNode.size() == cap) {
            List* list = freqList[minFreq];
            Node* nodeToRemove = list->tail->prev;

            keyNode.erase(nodeToRemove->key);
            list->removeNode(nodeToRemove);
        }

        Node* newNode = new Node(key, value);
        minFreq = 1;

        if (freqList.find(1) == freqList.end()) {
            freqList[1] = new List();
        }

        freqList[1]->addFront(newNode);
        keyNode[key] = newNode;
    }
};

I Built an OWASP Top 10 Scanner for MCP Servers. Here’s What It Finds.

MCP (Model Context Protocol) is everywhere. Cursor, Claude Desktop, Windsurf, GitHub Copilot — they all use MCP servers to give AI agents access to tools.

But nobody is scanning these servers for vulnerabilities.

I pointed my scanner at 15 public MCP servers. Every single one failed at least 6 out of 10 OWASP checks. Most failed all 10.

What’s exposed

MCP servers expose tools — functions that AI agents can call. Think run_command, query_database, read_file, fetch_url. Most servers have:

  • No authentication — any caller can invoke any tool
  • No input validation — command injection, SQL injection, path traversal all work
  • No message signing — requests can be replayed or tampered
  • No rate limiting — flood the server, nobody notices
  • Dangerous tools exposed — exec, shell, admin_panel sitting in the open

This isn’t theoretical. The OWASP MCP Security Cheat Sheet documents these risks. There’s an IETF draft proposing per-message signing to address them.

The OWASP MCP Top 10

I mapped the most common MCP vulnerabilities to the OWASP Top 10 2025:

# Check What it tests
1 Authentication Bypass Can anyone call tools without credentials?
2 Unsigned Messages Are requests signed? Can they be tampered?
3 Replay Attack Does the server accept duplicate requests?
4 Command Injection Can you escape tool arguments into shell?
5 SSRF Can you hit cloud metadata (169.254.169.254) via tools?
6 Path Traversal Can you read /etc/passwd through file tools?
7 Sensitive Tools Exposed Are dangerous tools (exec, sql, admin) available?
8 Tool Definition Tampering Do tool definitions change between calls (rug pull)?
9 Tool Poisoning Are there prompt injection patterns in tool descriptions?
10 Rate Limiting Does the server throttle rapid requests?

Try it yourself

Cybersecify is a security scanner that runs these checks. Install it as an MCP server in Cursor or Claude Desktop:

{
  "mcpServers": {
    "security": {
      "command": "npx",
      "args": ["cybersecify"]
    }
  }
}

Then ask your AI:

  • “Scan the MCP server at dvmcp.co.uk for vulnerabilities”
  • “Is it safe to pip install litellm?”
  • “Check if langchain-ai/langchain repo is safe”

Or scan our deliberately vulnerable MCP server at dvmcp.co.uk — it fails 10/10 checks on purpose. It’s a training lab.

What a scan looks like

Results: 0 passed, 10 failed (3 critical, 4 high)

[FAIL] MCP-01 Authentication Bypass (HIGH)
       No authentication required. Any caller can invoke tools.
[FAIL] MCP-04 Command Injection (CRITICAL)
       Shell command executed via tool arguments.
[FAIL] MCP-05 SSRF (HIGH)
       Internal/metadata URL accessible via MCP.
[FAIL] MCP-09 Tool Poisoning (HIGH)
       Prompt injection patterns in tool descriptions.
...

Community vs Pro

The Community Edition is free — 9 tools, OWASP MCP Top 10 scan, supply chain checks, threat intelligence.

Pro adds deeper scanning:

  • OWASP Top 10 2025 active rules (6 checks with multiple test vectors)
  • OWASP Top 10 2025 passive rules (4 checks)
  • CIS MCP Benchmark (22 controls)
  • EU AI Act compliance scan
  • DAST mode with SARIF output for CI/CD
  • Multi-target scanning and PDF/JSON/JUnit reports

More at cybersecify.co.uk.

The gap is real

97 million MCP SDK downloads. 13,000+ MCP servers. Zero security standard. The tools are being installed faster than anyone can audit them.

If you’re running MCP servers in production — or even in development — scan them. You’ll be surprised what’s exposed.

Raza Sharif, CyberSecAI Ltd

Prioritizing Risk: Why Context Matters in API Security

Modern security teams are not short on alerts. They are drowning in them.

Between vulnerability scanners, WAF logs, API gateways, and threat intel feeds, the problem is no longer visibility—it is prioritization. Everything looks like a risk. Everything demands attention. And as a result, nothing gets handled with the depth it actually requires.

This is especially true in API security, where the surface area is large, dynamic, and tightly coupled to business logic.

The core issue is simple:

Security teams are optimizing for coverage, not impact.

The Laundry List Problem

Most security workflows start with enumeration:

  • Known CVEs
  • Misconfigurations
  • Suspicious traffic patterns
  • Policy violations

This creates what can be described as a laundry list of possible threats.

The problem is not that these threats are invalid. The problem is that they are treated as equal.

They are not.

A vulnerability is only meaningful when placed in context:

  • What system does it affect?
  • What data does that system handle?
  • What is the actual exploit path?
  • What is the business impact if exploited?

Without this context, prioritization collapses.

Possible vs Probable vs Catastrophic

Not all risks belong in the same category. A useful distinction:

  • Possible → Theoretical, low likelihood, limited impact
  • Probable → Realistic exploitation path, moderate impact
  • Catastrophic → High likelihood or high-impact business damage

Most organizations treat all three the same.

That leads directly to alert fatigue and wasted effort.

A Simple Example

  • A vulnerability in a payment processing API
  • A vulnerability in a breakroom refrigerator IoT device

Both are technically “security issues.”

Only one threatens revenue, compliance, and customer trust.

The other is operational noise.

Security that cannot distinguish between these two is not protecting the business—it is generating activity.

The Real Mission of Security

The goal of security is often misunderstood.

It is not:

  • Blocking all malicious traffic
  • Eliminating every vulnerability
  • Achieving a “clean” environment

Those are impossible.

The real objective is:

Protect business-critical functions from meaningful disruption or compromise.

In API environments, this means focusing on:

  • Authentication and authorization flows
  • Data access boundaries
  • Transaction integrity
  • Abuse of core business logic

Everything else is secondary.

Response vs Remediation

Another failure mode is confusing response with resolution.

Response

  • Blocking an IP
  • Rate limiting a client
  • Returning a 403

This is containment. It stops the immediate symptom.

Remediation

  • Fixing the vulnerable endpoint
  • Closing the logic flaw
  • Updating authorization checks
  • Redesigning unsafe workflows

This prevents recurrence.

If an attack reached the point where response is needed, the system has already failed at the design level.

Focusing only on response guarantees repetition.

Why API Security Makes This Worse

APIs amplify this problem because:

  • They expose direct access to business logic
  • They are designed for automation
  • They often return structured, sensitive data
  • They are reused across multiple services

Most importantly:

API attacks often use valid requests.

There is no malformed payload to block.

Examples:

  • Enumerating user data through a search endpoint
  • Pulling excessive records through pagination abuse
  • Replaying tokens across endpoints

These are not attacks in a traditional sense. They are misuse of intended functionality.

Without context, they look normal.

The Fire Drill SOC

When context is missing, Security Operations Centers default to reactive mode:

  • Alert comes in
  • Analyst investigates
  • Temporary mitigation applied
  • Move to next alert

Repeat.

This creates a constant fire drill environment:

  • No long-term fixes
  • No prioritization
  • No structural improvement

The system remains vulnerable while appearing active.

The Role of Contextual Visibility

To break this cycle, security teams need to attach context to every signal:

  • Which API endpoint is involved?
  • What business function does it serve?
  • What data is exposed?
  • Who is accessing it, and how?
  • Is the behavior aligned with expected usage?

This turns raw alerts into actionable risk.

Without this layer, prioritization is guesswork.

Why Specialized SOC Models Work Better

General-purpose SOCs struggle because they operate horizontally across:

  • Network traffic
  • Endpoints
  • Applications
  • Identity systems

API security requires vertical depth.

Specialized models like MDR/XDR teams focused on specific protocol layers perform better because they:

  • Understand API behavior patterns
  • Recognize subtle abuse signals
  • Correlate requests across sessions
  • Focus on impact rather than volume

This reduces noise and increases accuracy.

Where WAF Fits (and Where It Doesn’t)

WAFs still play an important role:

  • Blocking known attack patterns
  • Filtering malformed requests
  • Providing baseline protection

But they operate primarily at the syntax level.

They answer:

  • Does this request look malicious?

They do not answer:

  • Is this request being used to exploit business logic?

This strengthens request-level security.

However, the core limitation remains:

Context about business logic and usage patterns cannot be inferred from a single request alone.

Final Take

API security is not failing because of lack of tools. It is failing because of lack of prioritization.

The shift is clear:

  • From counting vulnerabilities → to evaluating impact
  • From reacting to alerts → to fixing root causes
  • From blocking traffic → to protecting business logic

Context is what makes this shift possible.

Without it, every threat looks urgent.

With it, only the ones that matter get your attention.