Mert
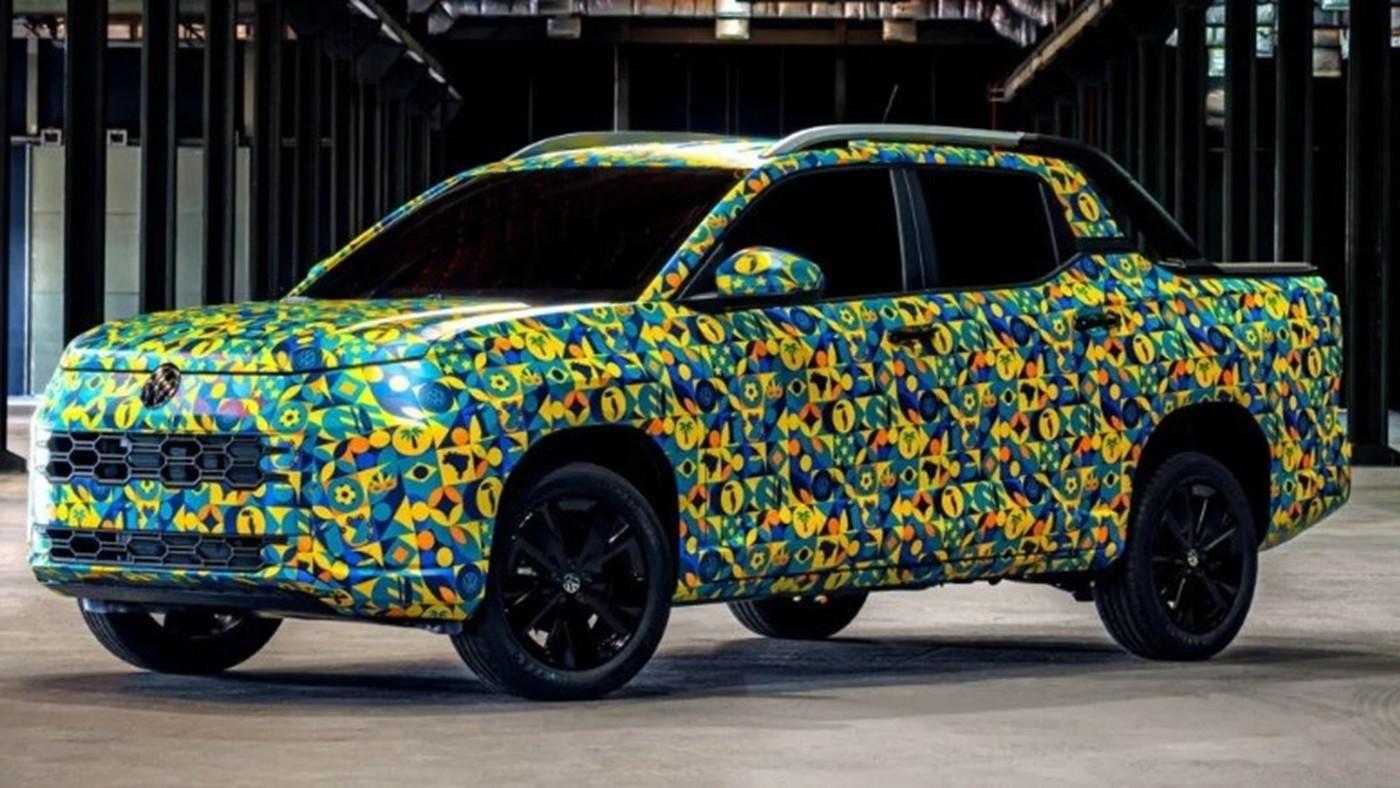
Volkswagen’in yeni pickup modeli ortaya çıktı: İşte Tukan
Volkswagen, Brezilya pazarı için geliştirdiği yeni kompakt pickup modeli Tukan’ı kamuflajlı şekilde görücüye çıkardı. Monokok şasiye sahip araç, benzinli ve hafif hibrit motorlarla satılacak.Yapay zekâ ile e-ticarette yeni dönem: Universal Commerce Protocol (UCP)
Küresel e-ticaret ekosistemi, yapay zekâ ajanlarının ve dijital asistanların alışveriş süreçlerini otonom bir şekilde yönetmesini sağlayacak devrim niteliğinde bir standartla tanıştı.PS Plus Extra ve Premium’dan çıkacak oyunlar: Haziran 2026
Playstation kullanıcılarına sunulan abonelik servisi Playstation Plus kütüphanesi sürekli olarak güncellenmeye devam ediyor. Son olarak Haziran ayında platformdan ayrılacak oyunlar belli oldu.The Unit That Crossed a Boundary: Mars Climate Orbiter, 1999
Tales from the Bare Metal — Episode 04
23 September 1999. The Mars Climate Orbiter fires its main engine to enter orbit around Mars, passes behind the planet as planned, and is never heard from again. The spacecraft cost 193 million dollars to build, part of a 327.6 million dollar mission. It travelled 670 million kilometres across nine months of deep space, and it was lost to a number with no unit written on it.
This is the cleanest example in the engineering record of why a quantity is not the same thing as a number.
The Incident
The Mars Climate Orbiter launched on 11 December 1998. Its job was to enter a stable orbit around Mars and study the planet’s atmosphere, also serving as a communications relay for the Mars Polar Lander that would follow.
The mission proceeded normally for nine months. On 23 September 1999, the orbiter executed its Mars Orbit Insertion burn: a planned firing of the main engine to slow the craft enough for Mars’ gravity to capture it. The burn was designed to place the orbiter at a closest approach of 226 km above the Martian surface, comfortably above the atmosphere.
The craft passed behind Mars, as expected, and signal was lost, as expected. It was never reacquired. Post-failure reconstruction showed that the trajectory had brought the orbiter to approximately 57 km above the surface, deep within the atmosphere. A spacecraft built for the vacuum of orbit does not survive atmospheric entry at orbital speed. It either burned up or was torn apart; either way, it was gone.
The Mars Climate Orbiter Mishap Investigation Board released its Phase I report on 10 November 1999. The root cause was stated plainly, and it was not a hardware fault, not a navigation error in the usual sense, not a launch problem. It was a unit mismatch at a software interface.
The Diagnosis
The trajectory of a spacecraft is adjusted over its journey by small thruster firings, called Angular Momentum Desaturation manoeuvres among others. Each firing produces an impulse, and the magnitude of that impulse must be fed into the navigation software so the predicted trajectory stays accurate.
Two organisations wrote the two halves of this loop. Lockheed Martin, in Colorado, built the spacecraft and the ground software that calculated the impulse from each thruster firing. NASA’s Jet Propulsion Laboratory, in California, ran the navigation software that consumed those impulse figures and computed the resulting trajectory.
Lockheed Martin’s software produced the impulse in pound-force seconds. This is an imperial unit: a pound-force is the force exerted by gravity on a one-pound mass, and a pound-force second is that force applied for one second.
JPL’s navigation software expected the impulse in newton-seconds. This is the metric (SI) unit: a newton is the force that accelerates one kilogram at one metre per second squared, and a newton-second is that force applied for one second.
One pound-force second equals 4.45 newton-seconds. The two numbers describe the same physical impulse, but the number representing it differs by a factor of 4.45 depending on which unit you mean.
The interface specification between the two systems required metric units. Lockheed Martin’s software, for the specific file in question, produced imperial. JPL’s software read the imperial numbers as though they were metric, and so every impulse was interpreted as 4.45 times smaller than it actually was. The trajectory corrections were therefore systematically wrong, in the same direction, for nine months. The error accumulated until the predicted 226 km insertion altitude was, in reality, 57 km.
The single most important sentence in the whole account is this: the number was correct. The software did not miscalculate. The bits that crossed the interface were the right bits. What was missing was the label that said what those bits meant, and each side filled in the missing label with its own assumption.
The Context
A unit mismatch sounds like the kind of thing that should be caught in an afternoon. The interesting question is not how the mistake was made, but how it survived nine months and 670 million kilometres without being caught. Three conditions allowed it.
First, the interface specification existed and was clear: it required metric. The imperial output was a deviation from spec. But nothing enforced the specification at runtime. The specification was a document, not a check. A document does not stop a wrong number; it only assigns blame after the wrong number has done its work.
Second, the discrepancy was visible before the loss. Navigators at JPL noticed during the cruise that the trajectory was not behaving quite as the models predicted; small corrections were needed more often than expected. The signal was there in the data, months before arrival. It was discussed informally but never escalated into a formal anomaly investigation, partly because each individual correction was within tolerance and the cumulative drift looked like ordinary navigation noise until it was too late.
Third, there was no end-to-end test. No test ran the Lockheed Martin impulse calculation and the JPL trajectory calculation against the same manoeuvre and compared the result to an independent reference. Each system was tested in isolation and behaved correctly in isolation. The fault lived only in the handoff between them, which is precisely the region that isolated unit tests do not cover.
These three conditions recur in almost every interface failure. The spec is a document not a check; the warning signal is visible but below the escalation threshold; the test coverage stops at the boundary rather than crossing it.
The Principle
Science settled the question of units a century ago. The Système International (SI) is the one coherent measurement system the entire scientific and engineering world shares, precisely so that a number computed by one team means the same thing to another. The Mars Climate Orbiter was lost because one half of the programme had not honoured that settlement: it still computed in pound-force seconds, an imperial unit with no place in serious engineering work.
The lesson is direct. In scientific and engineering contexts, measure in metric. There is no defence for imperial units in work where a factor of 4.45 decides whether a spacecraft enters orbit or enters the ground. Every serious laboratory, the United States included, standardised on SI for exactly this reason, and the orbiter is the canonical demonstration of what the alternative costs. Imperial units are a regional convention for everyday life; they are not a tool for computing trajectories, and the moment a programme treats them as one, it has built a 4.45 into its maths and dared the universe to find it.
There is a second guard worth stating, because metric alone is not sufficient. Two systems both using metric can still fail if one means seconds and the other milliseconds, if one means metres and the other kilometres, if one means bytes and the other kibibytes. So the unit must also travel with the number, enforced where the two systems meet:
-
Types the compiler checks. Rust newtypes let you define a
NewtonSeconds(f64)distinct from aPoundForceSeconds(f64); the compiler refuses to pass one where the other is expected. F# has units of measure built into the type system: a value typedfloat<N*s>cannot be assigned to afloat<lbf*s>without an explicit conversion. The mistake becomes a compile error, which is the cheapest place a mistake can possibly be caught. - Fields the parser demands. A data interchange format that requires the unit as a mandatory field (not an optional comment) makes the bare number unrepresentable. You cannot serialise the quantity without stating what it is.
-
Names the variable carries. The oldest discipline, available in any language: never write
timeout = 30; writetimeout_ms = 30ortimeout = Duration::from_secs(30). The unit lives in the name where the next reader cannot miss it.
The first rule needs no tooling: in science, measure in metric. The second rule catches what the first cannot: name the unit at every boundary regardless. The orbiter needed both, and had neither.
On FreeBSD this discipline is visible in the small, ordinary places. dd bs=1M states the block size with its unit; the bare number would be ambiguous. sysctl values are documented with their units, and the tunables in loader.conf name their dimensions. The convention across the base system is that a number with a physical meaning is rarely written naked. This is not glamorous and it has prevented an enormous number of quiet disasters.
The boundary is where the unit must be loudest, because the boundary is exactly where two assumptions meet and discover they disagree.
Where It Travels
The Mars Climate Orbiter is a spacecraft, which makes the failure feel exotic. It is not exotic. The same failure ships in ordinary software every day:
- Every API that passes a duration as a bare integer. Is
30seconds or milliseconds? The function namesetTimeout(30)does not say, and the two readings differ by a factor of a thousand. - Every configuration value that takes a size without a suffix. Is
cache_size = 1000bytes, kilobytes, or entries? - Every function signature with a parameter named
distance,interval,rateorsizeand no unit anywhere in the type or the name. - Every CSV handed from one team’s export to another team’s import, where column 7 is “amount” and nobody agreed whether it is gross or net, dollars or cents.
- Every number that means one thing on the left of an interface and another thing on the right, because the interface carried the number faithfully and the meaning not at all.
The Same Mistake, Smaller: Gigabyte and Gibibyte
The unit mismatch does not even need two systems as different as imperial and metric. It hides inside a single system, in the gap between decimal and binary.
A gigabyte, by the SI definition, is 1,000,000,000 bytes; “giga” is the standard decimal prefix for a billion, the same prefix as in gigahertz or gigawatt. A gibibyte, defined by the IEC in 1998, is 1,073,741,824 bytes: two to the power of thirty, the nearest binary round number. The two differ by about 7.4%, and the gap widens with every step up the ladder: terabyte versus tebibyte is about 10%, petabyte versus pebibyte about 12.6%.
The disk industry sells in decimal. A “1 TB” drive holds 1,000,000,000,000 bytes, exactly as labelled. Many operating systems, Windows most stubbornly, then display that capacity in binary while still calling the result “GB”. The drive shows up as roughly 931 “GB”, the customer concludes they have been short-changed by seven per cent, and a support ticket is born. Nobody has lied; two definitions of the same word have simply met at a boundary without introducing themselves.
It is the Mars Climate Orbiter with the stakes turned down from a spacecraft to a slightly disappointing disk. The IEC defined a complete binary ladder in 1998, parallel to the decimal one at every rung: kibibyte (KiB) beside kilobyte (kB), mebibyte (MiB) beside megabyte (MB), gibibyte (GiB) beside gigabyte (GB), and on through tebibyte (TiB), pebibyte (PiB) and beyond.
The recommendation applies to the entire scale, and it is the same discipline as everywhere else in this story. If you mean the binary value, write GiB, MiB, TiB. If you mean the decimal value, write GB, MB, TB. Never write one while meaning the other. The standard is correct, unambiguous, and has been available for over a quarter of a century. Use it: prefer the explicit binary prefixes (KiB, MiB, GiB, TiB) wherever you actually mean powers of two, which on a computer is most of the time. The only thing still keeping GB where GiB belongs is habit, and habit is precisely what put pound-force seconds where newton-seconds were expected.
A 193-million-dollar spacecraft was lost because one team did its sums in imperial units. The number was right. The unit was from the wrong century.
The lesson costs nothing to apply. In science and engineering, measure in metric; the rest of the world, and most of science within the imperial holdouts themselves, settled this long ago for exactly the reason the orbiter demonstrates. And where two systems must still meet, name the unit of every number that crosses between them, so that the compiler or the variable name holds what no shared assumption ever safely will.
Read the full article on vivianvoss.net →
By Vivian Voss, System Architect and Software Developer. Follow me on LinkedIn for daily technical writing.

How I Decompose Any Image Into Recomposable Layers on Melius
When you iterate on an AI-generated image by re-prompting, you destroy it.
You ask the model to “move the figure left and remove the truck,” and the entire scene shifts: different lighting, different building geometry, different snow texture. Anything that wasn’t pinned by the original seed gets re-rolled. You lose the bake you liked.
Photographers don’t work this way. Concept artists don’t work this way. They hold the layers and move them.
I wanted that. So I built it.
The pipeline in one paragraph
One Melius canvas. An analyzer LLM reads any input image and outputs a JSON blueprint of seven candidate layers: background, middle ground, foreground, and up to four subjects. Seven parallel extractor LLMs pull each layer’s isolation prompt out of the JSON. Seven NanoBanana Pro nodes regenerate each layer on chroma green, preserving original position, scale, and lighting. Background-removal nodes strip the green. A final NanoBanana Pro pass takes all seven transparent layers and renders a unified, lighting-coherent composition. You can move, scale, drop, or swap any layer before the final pass.
Why this matters
Single-pass generation treats an image as one indivisible thing. Inpainting and reference conditioning are partial fixes, but the model still guesses at occluded regions. Move the truck and the snow underneath has to be invented from nothing.
The fix is to never bake the image to begin with. Treat the original as a brief, decompose it into stacked elements, and only recompose at the end, after the elements are arranged the way you want them.
That requires a real pipeline. A node graph is the right shape for a real pipeline. Melius gave me the canvas that can hold one.
What’s in the full breakdown
I wrote the full workflow on Scopeful Pro: every node, both system prompts (the analyzer and the universal extractor template), the mistakes I made first, and the things I’d change in v2.
If you want the prompts, the node-by-node walkthrough, and the canvas itself, here is the full version:
How I Decompose Any Image Into Recomposable Layers on Melius
The video demo (14 seconds, the layer explode shot) is on my X feed (@igorgridel).
I Built 100+ Free Developer Tools That Run Entirely in Your Browser — Here’s Why
I was debugging an authentication issue at 11pm when I caught myself pasting a production JWT token into a random online decoder.
The token contained user IDs, roles, and expiry claims. The site had no privacy policy. I had no idea where that token was going.
I closed the tab, fixed the bug using console.log, and spent the next few weeks building DevBench — a toolbox where nothing you paste ever leaves your browser.
What DevBench is
DevBench is a collection of 135 free developer utilities, all running client-side in the browser using JavaScript and the Web Crypto API. No account. No upload queue. No server receives your data.
Here’s what’s available today:
JSON tools (12)
Format, validate, minify, diff, tree view, JSON↔YAML, JSON↔CSV, JSON↔TypeScript, JSON Schema validation, AES-256-GCM encryption, NDJSON parser, and more.
Dev utilities (36)
JWT decoder + encoder (HS256/384/512 via Web Crypto), regex tester, SQL formatter, cURL-to-fetch converter, UUID/ULID/NanoID generator, hash generator (SHA-1/256/384/512), color converter, QR code generator, CSS box-shadow builder, Linux command reference, HTTP status codes reference, and more.
Encoding (13)
Base64 encode/decode, URL encode/decode, HTML entities, Hex, Binary, ROT13, Morse code — all client-side.
PDF tools (14)
Compress, merge, split, rotate, watermark, convert PDF to Word/Excel/images — processed locally using PDF.js and pdf-lib.
Text tools (18)
Diff checker, markdown preview, case converter, string inspector, Lorem ipsum generator, Unicode checker, word counter, and more.
Image tools (6)
Background remover (WASM ML model), resizer, compressor, format converter, EXIF viewer — no pixels leave your device.
Plus conversion tools, finance calculators, health calculators, math tools, and date/time utilities.
Why “runs in your browser” actually matters
Most of us paste sensitive data into online tools without thinking about it:
- JWT tokens containing user roles and session claims
- API responses with PII or internal service data
- Hashed passwords (even hashes can be revealing)
- Private SSH keys into format converters
- Confidential PDFs into compression tools
Every tool that sends your data to a server is a potential data exposure. It doesn’t require malice — even accidental logging, misconfigured S3 buckets, or a breach of the tool’s database can expose data you thought was “just being formatted.”
DevBench uses the Web Crypto API for all cryptographic operations (JWT verification, AES encryption, hashing) so the computation happens in your browser’s secure context. For PDF processing, we use pdf-lib compiled to WebAssembly. For the AI background remover, the ML model runs via WASM entirely on your device.
The tradeoff is that we can’t support files over ~50MB on some operations (browser memory limits), and very complex operations can be slower than server-side equivalents. For most developer use cases — debugging a JWT, formatting a JSON response, compressing a PDF — the browser is fast enough.
The tech stack
- Framework: Next.js 16 (App Router) with Turbopack
- UI: React 19, Tailwind CSS v4
- Cryptography: Web Crypto API (native browser API, no third-party crypto library)
- PDF processing: pdf-lib + PDF.js
- AI background removal: WASM ML model (runs locally)
- Hosting: Vercel
- Repo: github.com/SaiBhargavRallapalli/all-in-one (MIT License)
The repo is fully open source with Playwright e2e tests, Vitest unit tests, GitHub Actions CI, and Lighthouse CI enforcing performance budgets.
What I learned building 135 tools in one codebase
Single tool registry was the right call. Every tool is defined in a central tools-registry.ts with metadata (name, slug, description, category, keywords). New tools are one registry entry + one component. The /tools/[slug] dynamic route handles metadata, schema markup, and layout automatically.
Client-side PDF is harder than it looks. The Web APIs are powerful but quirky. PDF rendering fidelity varies by browser. Font embedding is a consistent pain point. Plan for 2–3x more time than you’d expect on any PDF feature.
Topical authority matters more than I expected. Writing blog content around each tool category (not just building the tools) is what gets the pages indexed and ranked. Tools without supporting content are invisible to search engines.
Web Crypto API is genuinely excellent. The crypto.subtle API covers HMAC signing, AES-GCM encryption, RSA operations, and secure random generation natively in every modern browser. No crypto-js, no forge, no external dependencies. Smaller bundle, better security.
What’s next
- VS Code extension to open DevBench tools from the command palette
- Pro tier (ad-free, file upload history, API access)
- More language/framework-specific tools (TypeScript playground, SQL query builder, regex with named groups UI)
If you have a tool you reach for constantly that isn’t here — open an issue. The contributing guide is at CONTRIBUTING.md and the first-contribution list has approachable tasks.
And if the privacy-first, client-side approach resonates with you — share it with your team. The JWT debugger specifically is worth bookmarking as an alternative to jwt.io for anything involving real tokens.
The Free Note Frequency Chart: A Practical Guide to Understanding Pitch and Tuning
Explore how a free note frequency chart bridges music theory and physics. This article explains note names, Hertz values, equal temperament, and practical uses for musicians, producers, and audio engineers.
Music exists in two parallel worlds: the creative world of melody, harmony, and rhythm, and the scientific world of vibrations, waves, and cycles per second. The bridge between these two realms is often a simple yet powerful tool—the free note frequency chart. While many musicians learn to read notes on a staff or play by ear, few instinctively know that the A above middle C vibrates exactly at 440 Hz (or sometimes 432 Hz, depending on tuning preference). Understanding this relationship unlocks deeper control over synthesis, recording, instrument repair, and even orchestration.
This article provides a comprehensive walkthrough of the free note frequency chart, explains how frequencies are calculated, why the chart matters, and how you can use it in real-world scenarios. No jargon traps, no keyword stuffing—just useful knowledge you can apply today.
What Is a Note Frequency Chart?
At its core, a note frequency chart maps every musical note (C, C#, D, etc.) across octaves to its corresponding frequency in Hertz (Hz). Hertz measures cycles per second—how many times a sound wave oscillates in one second. Higher pitch equals higher frequency.
For example:
Middle C (C4) = 261.63 Hz
A4 (standard tuning pitch) = 440 Hz
The lowest note on a standard piano (A0) = 27.5 Hz
The highest note on a standard piano (C8) = 4186.01 Hz
A free note frequency chart typically covers the entire human hearing range (roughly 20 Hz to 20,000 Hz), though most instruments stay within 30 Hz to 5,000 Hz. These charts are available online as PDFs, images, or interactive tables. The word “free” matters because many proprietary software tools lock frequency data behind paywalls, but the physics of sound belongs to everyone.
The Math Behind the Chart
Western music uses twelve-tone equal temperament (12-TET), where an octave is divided into twelve equal semitones. The frequency ratio between two adjacent semitones is the 12th root of 2, approximately 1.059463. To find the frequency of any note, you use this formula:
Frequency = 440 Hz × 2^((n – 49) / 12)
Here, n = MIDI note number. A4 is MIDI note 49. C4 (middle C) is MIDI note 40. Plug in n=40, you get 440 × 2^((40-49)/12) = 440 × 2^(-9/12) = 261.63 Hz.
This mathematical foundation ensures that every octave doubles the frequency. The free note frequency chart simply displays these precomputed values, saving you the algebra. But understanding the formula helps when you need non-standard notes or microtonal tuning.
Why Musicians and Engineers Need a Free Note Frequency Chart
-
Tuning instruments without a tuner
If your electronic tuner dies before a gig, you can use a reference frequency from memory—A=440 Hz. Then tune relative intervals by ear. But a printed free note frequency chart gives you every pitch. Bassists often use it to set intonation on each string; guitarists reference 12th fret harmonics against open string frequencies. -
Synthesizer programming
Many synthesizers (especially modular and vintage gear) display frequency in Hz, not note names. To dial in a bassline in E1 (41.20 Hz), you need the chart. Without it, you are twisting knobs blindly. Sound designers also use frequency values to set filter cutoff points relative to musical fundamentals—for instance, setting a low-pass filter just above C3 (130.81 Hz) to preserve harmonic content while removing rumble. -
Audio repair and restoration
When removing hum, clicks, or resonance, engineers identify offending frequencies by ear, then match them to note names. A 120 Hz hum could be B2 (123.47 Hz) slightly off pitch. A free note frequency chart helps you label and target specific problem frequencies with surgical EQ. -
Arranging for dense mixes
Masking occurs when two instruments compete at similar frequencies. For example, a kick drum peaking at 60 Hz might clash with a bass guitar playing B1 (61.74 Hz). The chart reveals these conflicts numerically, allowing you to transpose a part or EQ with precision.
Anatomy of a Standard Chart
Let me describe what a typical free note frequency chart includes. Octaves are labeled from 0 to 8 (sometimes -1 for subsonic). Each row lists:
Note name (e.g., C, C#/Db, D)
MIDI note number (0–127)
Frequency in Hz (rounded to two decimals)
Some advanced charts add:
Wavelength in centimeters or inches
Adjacent harmonic frequencies (2nd, 3rd, 4th partials)
Equal temperament vs. just intonation comparison
For quick reference, here are a few anchor points (values you can memorize):
Note Octave Frequency (Hz)
C 0 16.35
C 1 32.70
C 2 65.41
C 3 130.81
C 4 261.63
C 5 523.25
A 4 440.00
B 4 493.88
These anchor points allow you to derive nearby notes quickly. For instance, G4 is roughly 392 Hz. No chart? Multiply or divide by 1.059463 repeatedly.
Equal Temperament vs. Pure Tuning
A free note frequency chart based on equal temperament is a compromise. Pure intervals (just intonation) sound more consonant but limit key changes. For example, a perfect fifth should have a 3:2 frequency ratio. In 12-TET, the fifth is slightly narrow (700 cents instead of 702). The chart reveals these discrepancies: compare E4 (329.63 Hz) in equal temperament versus the pure third from C4 (261.63 × 5/4 = 327.04 Hz). The difference is 2.59 Hz, easily audible.
Some free charts include a second column for just intonation or Pythagorean tuning. If you play baroque music, bagpipes, or vocal ensembles, seek out those variant charts. Otherwise, standard 12-TET works for 99% of Western productions.
Creating Your Own Free Note Frequency Chart
You do not need to download anything. Generate your own in three minutes using a spreadsheet:
Open Excel, Google Sheets, or LibreOffice Calc.
In column A, list note names (C0, C#0, D0 … B8).
In column B, input MIDI numbers (12 for C0, 13 for C#0 … 127 for G9).
Apply formula: =440 * 2^((MIDI_number – 69)/12) for A4=440 Hz.
Copy down all rows.
Adjust the formula if you prefer A=432 Hz: replace 440 with 432. Then format to two decimals. Now you have your own free note frequency chart without begging for permission. Print it, laminate it, stick it on your studio wall.
Practical Exercise: Apply the Chart Today
Try this five-minute exercise. Load a sine wave oscillator (free plugins like Signal Gen by Aegean Music or any DAW test tone). Using your chart, dial in:
55 Hz – This is A1, the low A on a bass guitar. Listen.
82.41 Hz – E2, low string on a standard guitar. Listen to the difference.
164.81 Hz – E3, same note one octave up. Notice the perceived doubling.
Now sweep from 55 Hz to 110 Hz (A1 to A2). Hear how it smoothly rises. That is the logarithmic nature of pitch—doubling frequency equals octave, yet our ears hear linear steps.
Finally, play a 440 Hz tone. Sing or hum an A. Then play 443 Hz (roughly 12 cents sharp). Most people hear the beating interference when both tones sound together. This is the foundation of tuning: matching frequencies eliminates beats.
Where to Find and Store a Free Note Frequency Chart
Search for “free note frequency chart PDF” on any engine. Look for results from university music departments, open-source synth forums, or audio blogs. Avoid pages that ask for email signups—those are not truly free. Good sources include:
The University of New South Wales’ Music Acoustics page
Independent GitHub repositories with markdown tables
Manufacturer support pages (e.g., Moog, Korg sometimes publish reference sheets)
Save the chart as an image on your phone or print a copy for your hardware synth rack. Better yet, memorize the first octave (C0–B0) and learn to double/halve frequencies mentally. Then you never need the chart again—except for odd notes like F#5 (739.99 Hz) that rarely stick in memory.
Common Misconceptions
Myth 1: Frequency equals volume.
No. Frequency is pitch; amplitude is loudness. A free note frequency chart tells you nothing about how loud a note sounds. The ear’s frequency response changes with level (Fletcher-Munson curves).
Myth 2: Sub-20 Hz is useless.
Organ pipes and electronic music often use 16 Hz (C0). You do not hear it as pitch, but you feel physical vibration. Some charts extend to 8 Hz for completeness, though that is infrasound.
Myth 3: All charts use A=440 Hz.
Not true. Orchestras sometimes tune to 442 Hz or 444 Hz for a brighter sound. Baroque ensembles may use 415 Hz. Always check the reference frequency printed on your chart. Adjust formulas accordingly.
Final Thoughts
A free note frequency chart is deceptively simple. It is just a list of numbers. Yet it connects mathematical ratios to emotional music. Whether you are a producer fixing a muddy mix, a guitarist setting intonation, or a student learning acoustics, this chart saves time and trains your ear to think in frequencies rather than arbitrary note names.
Do not hoard it. Share it with a bandmate. Tape it to a practice room wall. The best tools in music cost nothing and serve forever. The physics of sound does not ask for a subscription—and neither should your reference chart.
I Spent $50 on LLM API Calls. Then Optimized to $0.
The real cost of AI features isn’t the subscription — it’s the prompts you haven’t optimized yet.
The $50 Month
Two months ago, my OpenAI API bill hit $50. For a side project used by maybe 100 people.
The features I was using weren’t complex:
- User name extraction
- Email subject generation
- Simple categorization
I was calling GPT-4o mini for everything because it was “cheap enough.” But it added up.
What I Changed
1. Better Prompt Engineering
Same model, better prompts. A well-structured prompt with examples often matches a more expensive model.
Before:
Categorize this email: "{subject}"
After:
Categorize this email into one of: [urgent, follow-up, spam, newsletter]
Example: "RE: Meeting at 3pm" → follow-up
Example: "Free iPhone!" → spam
Now categorize: "{subject}"
Result: Same model, 40% fewer tokens needed.
2. Switched to Local Models for Simple Tasks
For categorization and extraction, I switched to:
- Ollama + Llama 3.2 for self-hosted inference
- Groq API (free tier) for production
Both handle simple structured extraction tasks at near-zero cost.
3. Caching Everything
Repeated questions get cached. If 50 users ask the same question, one API call serves all.
# Simple semantic cache
cache_key = hash(prompt + first_50_chars_of_context)
if cache.exists(cache_key):
return cache.get(cache_key)
4. Model Selection by Task
Not everything needs GPT-4o:
| Task | Model | Cost |
|---|---|---|
| Simple categorization | Groq (free tier) | $0 |
| Structured extraction | Ollama (local) | $0 |
| Long-form generation | GPT-4o mini | $0.002/1K |
| Complex reasoning | Claude 3.5 Sonnet | $0.003/1K |
The Results
After optimization:
- API bill dropped from $50/month to $8/month
- Response times actually improved (local models are faster for simple tasks)
- Caching covered 60% of requests
What I’d Tell Myself
Start with the cheapest model that works. Optimize prompts before switching models. Add caching before adding more expensive calls.
The $50/month problem is usually a $5/month problem you haven’t solved yet.
What’s your biggest AI API expense? Any optimization wins you’ve found?
Codex in the ChatGPT Mobile App: What a Pocket Coding Agent Actually Changes
Cloud coding agents have always had a scheduling problem. You describe a task, the agent works for several minutes in a sandbox somewhere, and then it stops and waits for you — to read the diff, approve it, or send it back with corrections. If you sat at your desk for that entire stretch, the cloud part bought you almost nothing. You may as well have run the work locally and watched it finish.
OpenAI putting Codex inside the ChatGPT iOS and Android apps is aimed straight at that gap. The agent keeps running in the cloud; you check on it from a coffee line, a meeting, or the couch. The desk stops being the place the loop has to close.
What moved into the ChatGPT app
Codex here means OpenAI’s software-engineering agent — the cloud product, not the 2021 model that shared the name. It connects to a repository, runs each task in an isolated sandbox preloaded with your code, edits files, runs the commands a task needs, and returns a diff for you to review. Until this rollout, that loop lived in the ChatGPT web sidebar and the Codex CLI.
The mobile version carries over the parts that do not need a keyboard. From the ChatGPT app you can:
- Start a task by describing it in plain language
- See active runs and which ones have finished
- Open the diff a run produced and read the proposed changes
- Send a run back with follow-up instructions, or approve it
What you are not doing on a phone is hand-editing code. The mobile surface is built around delegation and review, not typing — and that is the right scope. Describing a task and judging a result both work on a touchscreen; writing and steering code line by line does not. By shipping the agent inside an app developers already keep open, OpenAI also skipped the install step every standalone coding tool has to fight through.
Treat the mobile app as a triage surface, not a development environment. The highest-value mobile actions are starting a run before you leave your desk and clearing a review queue while you are away — not trying to drive a full feature from your phone.
Why a phone changes the workflow more than it looks
The headline is not “code from a beach.” It is that an asynchronous agent only pays off when triggering and reviewing are both cheap. A cloud agent you can reach from one machine is just a slower local agent. Make the two cheap actions — kick off, check back — available everywhere, and the economics change.
Think about how a normal day fragments. You have a ten-minute gap before a call, a commute, a stretch of waiting at an appointment. None of that is long enough to load a feature into your head and write it. All of it is long enough to describe a contained task — “add input validation to the signup form and a test for the empty-email case” — and let the agent run while you do something else. You come back to a diff, not a blank editor.
It also changes how you batch work. Because each Codex task runs in its own sandbox, you can have several in flight at once. The bottleneck stops being how fast the agent writes code and becomes how fast you review what it produced. A review queue you can chip away at in two-minute increments is a queue that does not pile up until Friday afternoon.
Mobile also gives the agent a way to interrupt you. A run that finishes, fails a test, or needs a decision can surface as a notification instead of sitting silent in a browser tab you already closed. That turns the agent from something you have to remember to check into something that tells you when it needs you — roughly the difference between three review cycles in a day and thirty.
The honest limitation: this only helps for work that decomposes into self-contained, well-specified tasks. Vague instructions produce diffs you cannot judge from a phone, and ambitious refactors still need a real editor and a test run in front of you. The mobile app rewards developers who already write tight task descriptions and offers little to hand-waving.
A small screen makes it tempting to approve a diff you only skimmed. A coding agent will confidently produce changes that pass a glance and fail in CI. Before you tap approve on mobile, confirm the run included a test step and that you have actually read the parts of the diff that touch logic — not just the line count.
Where this leaves Cursor and Claude Code
Each major coding agent has staked out a different home surface. Cursor is editor-first: the agent lives inside an IDE where your edits and the agent’s edits share one window, which suits tight, interactive work and does nothing for you away from the machine. Claude Code is terminal-first: it runs where your shell and scripts already are, which fits developers who live on the command line. Codex is now ChatGPT-app-first, and that app is already on the device in your pocket.
That is a real distribution advantage. The ChatGPT app sits on hundreds of millions of phones, so OpenAI did not have to sell developers a new tool — it added a capability to one they open for other reasons. The trade-off is depth: a chat app wrapped around an agent will not match a dedicated IDE for the moment-to-moment work of writing and steering code.
The realistic outcome is not a single winner. It is that your desk tool and your away-from-desk tool stop being the same product. You might steer a hard refactor in an editor at your desk, then use a mobile agent to keep small, well-defined tasks moving for the rest of the day.
If your day is mostly deep work at one machine, an editor-resident agent will still carry most of the load. If it is fragmented across meetings and travel, a coding agent inside the ChatGPT app turns dead time into a working review queue. Most developers will end up using both — for different hours of the same day.
Originally published at pickuma.com. Subscribe to the RSS or follow @pickuma.bsky.social for new reviews.