Build an MCP Server for Real-Time Web Data Extraction

TL;DR

Build an MCP server to give AI agents real-time web access by wrapping the AlterLab API in a standardized tool schema. This setup allows agents to fetch live content, bypass anti-bot measures automatically, and process structured web data without hardcoding selectors for every new site.

AI agents are limited by their training data cutoffs and the “wall” of the public web. While Retrieval-Augmented Generation (RAG) helps with static data, agents often need live information from e-commerce sites, news portals, or technical documentation.

The Model Context Protocol (MCP) is the emerging standard for bridging this gap. By building a custom MCP server, you can expose web scraping capabilities as “tools” that an LLM can invoke dynamically. This tutorial shows how to build a production-ready MCP server using Python and AlterLab.

Understanding the MCP Architecture

MCP operates on a client-server model. The Client (such as a developer IDE or an AI agent framework) initiates the connection. The Server provides resources (data), tools (executable functions), and prompts (predefined templates).

For web data extraction, we primarily use Tools. A tool is a function that an LLM can decide to call based on its description. When the agent needs live data, it sends a JSON-RPC request to your MCP server, which then calls the AlterLab API to retrieve and clean the requested page.

Prerequisites

To follow this guide, you need:

  1. Python 3.10 or higher.
  2. An AlterLab API key. You can sign up to get started.
  3. The mcp Python SDK and the AlterLab Python SDK.

Step 1: Initialize the Project

Create a new directory and install the necessary dependencies. We use the official mcp package which provides the base classes for building servers.

“`bash title=”Terminal”
mkdir alterlab-mcp-server
cd alterlab-mcp-server
python -m venv venv
source venv/bin/activate
pip install mcp alterlab


## Step 2: Configure AlterLab Integration

Before building the server, verify you can connect to the scraping API. AlterLab handles the complexity of rotating proxies and [anti-bot solution](https://alterlab.io/smart-rendering-api) logic automatically.


```python title="test_connection.py" {4-6}

client = alterlab.Client(api_key="YOUR_API_KEY") # highlighted
response = client.scrape("https://example.com") # highlighted
print(f"Status: {response.status_code}") # highlighted

You can also verify this via cURL to ensure your environment can reach the API:

“`bash title=”Terminal”
curl -X POST https://api.alterlab.io/v1/scrape
-H “X-API-Key: YOUR_API_KEY”
-H “Content-Type: application/json”
-d ‘{“url”: “https://example.com“, “formats”: [“markdown”]}’


## Step 3: Implementing the MCP Server

The server needs to define a tool that takes a URL as input and returns the page content. We will use `formats=['markdown']` to ensure the agent receives clean, LLM-friendly text rather than raw HTML.


```python title="server.py" {22-35}
from mcp.server.fastmcp import FastMCP

# Initialize FastMCP server
mcp = FastMCP("AlterLab Web Scraper")

# Initialize AlterLab client
# In production, use environment variables for keys
api_key = os.getenv("ALTERLAB_API_KEY")
client = alterlab.Client(api_key=api_key)

@mcp.tool()
def scrape_website(url: str) -> str:
    """
    Scrapes a website and returns the content in Markdown format.
    Use this tool to get real-time data from any public website.
    """
    try:
        # Requesting markdown format for better LLM context
        result = client.scrape(
            url=url,
            formats=["markdown"],
            wait_for_network_idle=True
        )

        if result.success:
            return result.markdown
        else:
            return f"Error: {result.error_message}"

    except Exception as e:
        return f"An unexpected error occurred: {str(e)}"

if __name__ == "__main__":
    mcp.run(transport="stdio")

Why Markdown?

LLMs process Markdown much more efficiently than HTML. HTML contains significant noise (tags, scripts, styles) that consumes tokens and distracts the model. By using AlterLab’s markdown conversion, you provide the agent with the core semantic content of the page, improving extraction accuracy.

Step 4: Connecting the Server to an Agent

MCP servers typically communicate over stdio. This means the agent launches your script as a subprocess and sends commands via standard input.

To use this with a client like Claude Desktop, you would add the following to your configuration file:

“`json title=”claude_desktop_config.json”
{
“mcpServers”: {
“alterlab”: {
“command”: “python”,
“args”: [“/path/to/alterlab-mcp-server/server.py”],
“env”: {
“ALTERLAB_API_KEY”: “YOUR_ACTUAL_KEY”
}
}
}
}


## Step 5: Advanced Tooling & Structured Data

While simple scraping is useful, agents often need specific data points. You can add a more advanced tool that utilizes AlterLab's "Cortex" engine for AI-powered extraction directly at the source.


```python title="server.py" {5-15}
@mcp.tool()
def extract_structured_data(url: str, schema_description: str) -> str:
    """
    Extracts specific data from a page based on a description.
    Example schema_description: 'Extract the product price, name, and availability status.'
    """
    result = client.scrape(
        url=url,
        formats=["json"],
        extract={
            "description": schema_description
        }
    )

    if result.success:
        return str(result.json_data)
    return f"Failed to extract data: {result.error_message}"

This second tool allows the agent to specify exactly what it wants. Instead of the agent reading 2000 words of Markdown and finding a price, the MCP server returns a tiny JSON object, saving massive amounts of token cost.

Deployment Flow

Follow these steps to move your MCP server from a local script to a tool accessible by your agentic workflows.

Handling Technical Challenges

Rate Limiting and Concurrency

AI agents can be aggressive. If an agent loops and tries to scrape the same URL 50 times, it will consume your balance quickly. Implement simple caching or rate limiting within your MCP server to prevent runaway agent behavior. Refer to the documentation for best practices on managing high-volume requests.

Bot Detection

Some sites use advanced challenges. By default, AlterLab’s anti-bot handling manages most of these. If an agent reports it cannot see the content, you can modify your MCP tool to increase the min_tier parameter, which triggers more sophisticated browser emulation and CAPTCHA solving.

Comparison: Direct Scraper vs. MCP Server

Feature Direct API Call MCP Server
Discovery Hardcoded in logic Dynamic LLM discovery
Context Management Manual string slicing Automatic tool schema
Integration Custom for every app Standardized across clients
Real-time access Yes Yes (Agent-driven)

Takeaway

Building an MCP server for web extraction transforms a “blind” LLM into an agent capable of interacting with the live web. By wrapping AlterLab’s reliable infrastructure in the MCP standard, you solve two problems at once: the technical difficulty of bypassing bot detection and the architectural difficulty of giving agents tool-use capabilities.

For more details on advanced extraction parameters, check our API reference or explore our engineering blog for more agentic automation patterns.

AWS Copilot CLI is reaching end of support — your migration options

If you have been using AWS Copilot CLI to deploy containers on ECS, the tool has a date on it. AWS Copilot CLI reaches end of support on June 12, 2026. After that, the open-source project stays on GitHub, but AWS will not ship features, fixes, or security patches for it.

This is the short version. The full walkthrough is on my blog: AWS Copilot CLI End of Support: Migration Guide for 2026.

What changes on June 12, 2026

Your running apps do not. The ECS services, load balancers, and CloudFormation stacks Copilot created stay in your account.

What changes is the tool:

  • No new features.
  • No security updates from AWS.
  • No technical support.
  • The GitHub repo stays open, but it is no longer AWS-maintained.

What AWS recommends instead

Two paths, for two kinds of teams.

Amazon ECS Express Mode. The fastest path from a container image to production. You hand it an image and two IAM roles, and it builds the load balancer, listener, target groups, security groups, scaling, and monitoring. Fargate-only. Closest in spirit to Copilot. Pick this if your service is a standard load-balanced or request-driven web app.

AWS CDK Layer 3 constructs. The aws-ecs-patterns library has constructs like ApplicationLoadBalancedFargateService, QueueProcessingFargateService, and ScheduledFargateTask that cover most patterns Copilot supported. Pick this if you need fine-grained control, blue/green, a service mesh, or non-Fargate launch types.

You can also take over the CloudFormation Copilot generated and manage it directly. Low effort short-term, but those templates are not built to be human-edited. Treat it as a bridge.

Service-by-service map

Copilot service type Replacement
Load Balanced Web Service ECS Express Mode, or CDK ApplicationLoadBalancedFargateService
Request-Driven Web Service ECS Express Mode with request-based scaling
Backend Service CDK internal ALB, or ECS Service Connect
Worker Service CDK QueueProcessingFargateService
Scheduled Job EventBridge Scheduler + ECS RunTask, or CDK ScheduledFargateTask
Static Site CDK CloudFront constructs, or AWS Amplify Hosting

Most teams find that web services land on Express Mode and workers/scheduled jobs land on CDK.

How to plan the move

One service at a time, not one big switch:

  1. Inventory every service. copilot svc ls gives the list; the copilot/ manifests give the type.
  2. Match each to its replacement.
  3. Pick a low-traffic service for the first migration. The point is to learn the workflow, not to ship the hardest case.
  4. Run both versions in parallel for a few days, watch metrics, cut over.
  5. Delete the Copilot service to remove its stack cleanly.
  6. Repeat. Hardest cases last.

If you only do one thing before June 12, do step one.

The full guide covers the IAM-role split for Express Mode, when CDK is actually worth it, the third path of taking over the CloudFormation directly, and what happens if you cannot migrate in time: AWS Copilot CLI End of Support: Migration Guide for 2026.

Deploying Angular applications to Cloudflare with Void

Angular is a web framework for building scalable applications, with a powerful CLI, signals-based reactivity, and a batteries-included approach to routing, forms, and testing.

Void is a Vite plugin and deployment platform built on Cloudflare. It deploys your app to Cloudflare’s global edge network with a single command — no Cloudflare account required.

This guide shows how to create a new Angular application or add to an existing one and deploy it to Void as a single-page app.

Creating a new Angular application

To create a new project, generate it with the Angular CLI:

npx @angular/cli new angular-void

The CLI asks a few setup questions. When prompted for Server-Side Rendering (SSR) and Static Site Generation (SSG/Prerendering), answer No — Void deploys the build as a static SPA, so a client-only app keeps the setup simple.

Once the project is generated, move into it:

cd angular-void

For an existing project, skip this step and go straight to installing Void.

Installing Void

Install the Void CLI as a dev dependency using your package manager of choice:

npm install -D void

Angular doesn’t expose Vite directly — the Angular CLI owns its own build pipeline — so there’s no vite.config.ts to add voidPlugin() to. Instead, you point Void at the Angular build through a small config file, and keep developing with the Angular CLI as usual:

npm start

Configuring the build for Void

Void deploys the output of your build command. Add a void.json at the project root telling Void this is a SPA, how to build it, and where the build output lands:

{
  "$schema": "./node_modules/void/schema.json",
  "output": "static",
  "inference": {
    "appType": "spa",
    "build": "npm run build",
    "outputDir": "dist/angular-void/browser"
  },
  "worker": {
    "compatibility_date": "2026-05-11"
  }
}

The $schema field gives you autocomplete and validation for void.json in your editor. The outputDir matches the Angular CLI’s default output path — dist/<project-name>/browser. With appType set to spa, Void falls back all non-file paths to index.html, so the Angular router works out of the box.

If you created the project with SSR enabled, open angular.json and set the build target’s outputMode to static, then remove the ssr entry and server option. Void serves the prerendered output as a static SPA:

"outputMode": "static"

Deploying

Log in to Void first:

npx void auth login

Then deploy:

npx void deploy

Void runs your build command, uploads the static assets, and makes the site live:

┌  void deploy
│
◇  Building...
│  (ng build output)
│
◇  Checking assets...
◇  Uploading assets...
◇  Packaging...
◇  Deploying...
◇  Deployed!
│
│  ╭─────────────────────────────────────────╮
│  │  https://<project-name>.void.app        │
│  ╰─────────────────────────────────────────╯
│
└  Done!

On the first deploy, Void creates or links the project and saves the link to .void/project.json, so subsequent void deploy runs go straight to the same project. Run void project status to see recent deployments, and void project rollback to instantly switch traffic back to a previous one.

Shaping requests at the edge

Once the app is live, you can control how requests are served — without writing any worker code — by adding a routing block to void.json. These rules run on Cloudflare’s edge before the response is served, so they add no latency.

Send old URLs to new ones with routing.redirects:

{
  "routing": {
    "redirects": {
      "/home": "/",
      "/blog/*": { "to": "/posts/:splat", "status": 301 }
    }
  }
}

Keys are source patterns where * matches any characters. A value is either a plain string (a 302 by default) or an object with an explicit status. :splat in the destination carries over whatever * matched.

Attach response headers — security policies, cache rules — by URL pattern with routing.headers:

{
  "routing": {
    "headers": {
      "/*": [
        "X-Frame-Options: DENY",
        "X-Content-Type-Options: nosniff",
        "Referrer-Policy: strict-origin-when-cross-origin"
      ]
    }
  }
}

Deploying from CI

To deploy on every push instead of from your machine, let Void scaffold a GitHub Actions workflow for you:

npx void init --github

This creates .github/workflows/deploy.yml with the right package manager commands to build and run void deploy on every push to main.

CI needs a deploy token instead of an interactive login. Run void auth token to copy one to your clipboard, then add it as a repository secret named VOID_TOKEN. Set VOID_PROJECT to your project slug so the CLI knows which project to target.

If you’d rather write the workflow by hand, a minimal version looks like this:

name: Deploy
on:
  push:
    branches: [main]

jobs:
  deploy:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - uses: actions/setup-node@v4
        with:
          node-version: '22'
      - run: npm ci
      - run: npx void deploy
        env:
          VOID_TOKEN: ${{ secrets.VOID_TOKEN }}
          VOID_PROJECT: angular-void

VOID_TOKEN skips the interactive login, and VOID_PROJECT tells the CLI which project to target.

Adding a custom domain

Point your own domain at the project with void domain add:

npx void domain add example.com

The CLI prints a CNAME target to add at your DNS provider. Check verification and SSL status anytime with void domain status example.com, or list every domain on the project with void domain list.

Conclusion

With void.json in place, deploying an Angular app to Cloudflare’s global edge is a single void deploy away — no Cloudflare account and no Wrangler config required. Void runs the Angular CLI build untouched and serves the output as a SPA, while routing rules, custom domains, and a small CI workflow are there when you need them.

If you enjoyed this post, click the ❤️ so other people will see it. Follow Brandon Roberts on Bluesky, and subscribe to my YouTube Channel for more content!

GPU Observability for Workloads That Cannot Phone Home

Diagram of a GPU node inside an air-gapped boundary: outbound network is X-marked, while internal trace storage and a local query interface are highlighted. Single binary annotation on the host.

Diagram of a GPU node inside an air-gapped boundary: outbound network is X-marked, while internal trace storage and a local query interface are highlighted. Single binary annotation on the host.

For an air-gapped GPU host, the trace is only useful if collection, storage, and query all happen without a single outbound connection.

TL;DR

A class of GPU users runs in an air-gapped or strictly-controlled-egress environment: federal, classified defense, regulated finance, sovereign-cloud, on-prem research labs. The default assumption of cloud-native observability (send telemetry to a SaaS) does not hold. A self-hosted, single-binary, no-outbound-deps tracer is one of the few options that fits.

What the constraint actually means

“Air-gapped” rarely means “no network at all”. It means specific things: the host cannot reach external IPs, no telemetry SaaS endpoint, no package mirror beyond an internal one, no auto-update fetcher, and frequently no DNS resolution beyond an internal resolver. Every dependency is a thing that has to be packaged, signed, audited, and installed by hand. The cost of an extra binary or an extra port is not a CI annoyance; it is a security review.

A GPU observability stack that requires an external collector, a hosted backend, an outbound HTTPS connection, or a curl to an update server fails this bar before it runs.

What an eBPF agent removes from the equation

An eBPF tracer that is one statically-linked binary and writes to a local database removes most of the surface that air-gapped reviews flag. No collector daemon to install. No transport library. No client-side TLS certificates that have to be rotated against an external endpoint. No remote logging of trace contents. The investigation runs against a file on disk that an operator can copy out for review (or query in place) on the same terms as any other artifact on the host.

On the kernel side, the technique is already well-suited: the Linux kernel’s eBPF subsystem is in-tree, audited, and present on every modern enterprise distribution. uprobes and tracepoints are stable kernel features, not a vendor add-on.

What a self-hosted run actually looks like

# all of this runs without one outbound network call

# 1. install (single binary; can be staged from an internal mirror)
ingero check                          # local capability sanity check

# 2. capture (writes to a local SQLite DB)
ingero trace --duration 5m --out /var/lib/ingero/run.db

# 3. query in place
ingero query /var/lib/ingero/run.db 
  "SELECT * FROM cuda_events WHERE duration_ns > 1000000 LIMIT 20"

# 4. (optional) pull DB through an approved transfer channel for offline review
sha256sum /var/lib/ingero/run.db

Nothing in that workflow needs an external endpoint. The DB is a single file. The query interface is local. An operator can hash the file, sign it, and move it through whatever transfer-of-records channel the site already has.

Where this is not enough on its own

An air-gapped install does not solve every GPU-observability problem. It solves the network-egress and supply-chain shape. A few things still belong in the local toolchain: a way to update the agent on a controlled schedule (signed binary releases pulled through an internal mirror), a way to verify the agent’s capability list against the host’s policy (BPF privilege, perf-event access, kernel version), and a documented schema so a query that worked on yesterday’s capture works on tomorrow’s.

Workloads that cannot phone home

Most modern observability tools are SaaS-first by default. The GPU class of workloads where that does not work is real and growing (federal AI pilots, sovereign cloud, defense ML, regulated trading models, on-prem biotech). The shape of tooling that fits is older: a single binary, a local file, and a query language that does not assume the data ever leaves the box.

Ingero – open-source eBPF agent for GPU debugging. One binary, zero deps, <2% overhead. Apache 2.0 + GPL-2.0. *GitHub ⭐** · Open an issue if you are running GPU workloads in an air-gapped, sovereign-cloud, or controlled-egress environment and need observability that does not phone home.*

Related reading

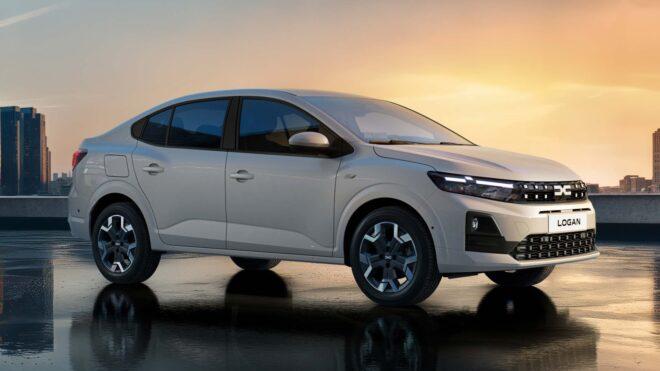
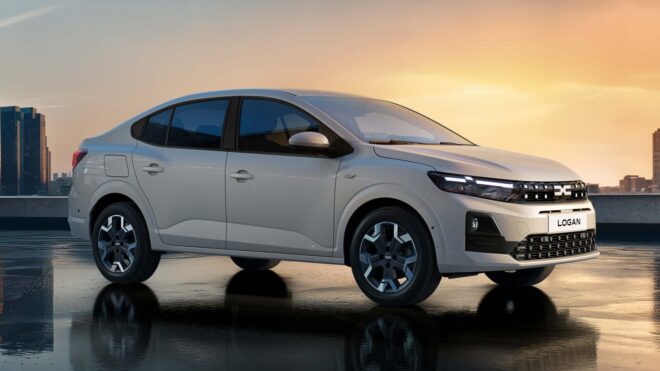
Yeni “Dacia Logan” için resmi Türkiye satış fiyatı açıklandı

Yeni

Yeni "Dacia Logan" için Türkiye satış fiyatı açıklandıYeni Dacia Logan için Türkiye satış fiyatı bugün resmi olarak 1 milyon 580 bin TL olarak açıklandı. Haziran ayında satışa sunulacak araç için şirketten gelen resmi açıklama şöyle oldu: “Yenilenen Dacia ürün ailesinin en yeni üyesi Yeni Logan, sedan versiyonuyla Türkiye’de Haziran ayı itibarıyla satışa sunuluyor. 2013 yılından sonra yeniden Türkiye’de yollara çıkacak olan Yeni Logan, lansmana özel 1.580.000 TL’lik fiyatıyla kullanıcılarıyla buluşmaya hazırlanıyor. Yeni Logan, iki farklı motor ve şanzıman seçeneğiyle satışa sunuluyor: Çift yakıt teknolojisine sahip motor: 1.2 litrelik ve 3 silindirli turbo beslemeli bu motor seçeneği; 197 Nm tork ve 120 hp’lik Eco-G 120 (EDC-çift kavramalı) otomatik vitesle sunuluyor. TCe 100 manuel vitesli benzinli motor: 6 ileri manuel şanzımanla eşleştirilen bu motor seçeneği ise; 1.0 litrelik 3 silindirli turbo şarjlı benzinli motor, 200 Nm tork ve 100 hp güç sunarak günlük sürüş performansını iyileştiriyor. Yeni Logan, otomatik acil durum freni, araç, yaya, bisikletli ve motosiklet algılama özelliği […]

Yeni “Dacia Logan” için resmi Türkiye satış fiyatı açıklandı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

A Production Python Telegram Bot Was Crashing Every 2 Hours. The Fix Was 18 Lines.

“If you see cascading errors, find the first thing that fails and stop reading the log there. Everything after the first failure is the system reacting to the first failure.”

A production Python Telegram bot I was looking after started crashing every 2-3 hours. The traceback was a horror show — TelegramRetryAfter, then asyncio.TimeoutError, then sqlite3.OperationalError: database is locked, then 47 leaked sessions, then the process got OOM-killed, then systemd restarted it. Then it happened again, 140 minutes later, like clockwork.

The temptation when you see this kind of cascade is to throw the whole architecture out. “SQLite can’t handle our scale, let’s move to Postgres.” “Bare asyncio is too low-level, let’s add a queue.” “Let’s rewrite it in Go.”

I didn’t do any of those things. The fix was 18 lines of code in one middleware file. The bot has been up for weeks since.

Here’s the diagnosis, the fix, and the takeaway. The code is real (anonymized of any client specifics) and the numbers are real.

The symptoms

Stack: Python 3.12, aiogram 3.x, SQLite for user state, asyncio everywhere. Volume: about 4,000 daily incoming messages. Not high-throughput.

The log every 140 minutes looked like this:

[14:22:01] ERROR  aiogram.TelegramRetryAfter: flood control, retry in 28s
[14:22:03] ERROR  asyncio.TimeoutError in update handler
[14:22:05] WARNING bot.session not closed (47 active)
[14:22:08] ERROR  sqlite3.OperationalError: database is locked
[14:22:14] ERROR  ...same pattern, multiplying...
[14:22:20] ERROR  process killed by OOM
[14:22:21] INFO   systemd: restarted

Process up ~140 minutes. Then the cascade. Then restart. Repeat.

What looked plausible (and was wrong)

When I started looking, the first hypothesis was “SQLite is the bottleneck — it can’t handle the concurrency.” That’s the most obvious thing to say when you see database is locked in a log.

It was wrong. Here’s why I dropped it after 30 minutes:

4,000 messages a day is nothing for SQLite. SQLite handles tens of thousands of writes per second on modest hardware. If we were hitting a SQLite ceiling, we’d be hitting it under steady load, not in sudden bursts. The 140-minute interval was the giveaway — something was accumulating, not saturating.

The second hypothesis was “We’re hitting Telegram API rate limits.” That’s what TelegramRetryAfter literally says. But again, 4,000 messages a day = roughly 1 message every 20 seconds on average. Telegram’s per-bot rate limit is 30 messages per second. We weren’t even in the same order of magnitude.

So whatever was happening was bursty, not steady-state. And the bot was somehow turning a steady stream of inbound updates into a burst of outbound API calls.

The actual root cause

Here’s what was happening, step by step:

  1. A user sends a message. aiogram receives it as an update.
  2. The handler runs, does some work, and sends a reply to Telegram.
  3. Normally: that reply goes out, the handler returns, the asyncio task ends, the bot.session HTTP connection is released.
  4. What actually happened: no throttle middleware existed. If 5-10 users happened to message in the same second (which happens during peak hours), the bot fired 5-10 outbound sendMessage API calls concurrently.
  5. Five or ten outbound requests inside one second pushed us past Telegram’s per-second rate limit. Telegram answered with 429 Too Many Requests and a retry_after header.
  6. aiogram raised TelegramRetryAfter. But the handler that raised it was waiting on the API response — it couldn’t release its HTTP session until the retry window closed (28 seconds in the log above).
  7. While that handler was waiting, the next inbound update hit the same handler code. Another async task spawned. Another bot.session connection opened. Another wait.
  8. Now we have two stuck tasks, each holding a connection, each blocked on retry_after. Both tasks also need to update the user’s row in SQLite. SQLite locks the row for the first writer. The second writer waits. Deadlock potential.
  9. Multiply this by 10 minutes of bursty traffic. Now you have 47 leaked sessions, an SQLite deadlock, and a Python process eating memory because tasks aren’t completing.
  10. OOM killer hits. Systemd restarts. Cycle resets.

The cascade had one cause: no rate limit on the bot’s inbound side. Everything downstream was just the system reacting to the upstream pressure.

The fix — 18 lines

A throttle middleware. Drop incoming updates from a user if they already had a message in the last second. That’s it.

# middleware.py
from aiogram import BaseMiddleware
from aiogram.types import Update
from cachetools import TTLCache


class ThrottleMiddleware(BaseMiddleware):
    """Drop second-message-within-N-seconds per user.

    Without this, bursty inbound traffic translates 1:1 into bursty
    outbound API calls and trips Telegram's flood control.
    """

    def __init__(self, rate_limit: float = 1.0):
        self.cache = TTLCache(maxsize=10_000, ttl=rate_limit)

    async def __call__(self, handler, event: Update, data):
        user_id = event.message.from_user.id if event.message else None
        if user_id and user_id in self.cache:
            return  # silently drop — user is over their rate limit
        if user_id:
            self.cache[user_id] = True
        return await handler(event, data)

And wire it up plus a clean shutdown:

# main.py
from aiogram import Bot, Dispatcher

bot = Bot(token=BOT_TOKEN)
dp = Dispatcher()

dp.update.middleware(ThrottleMiddleware(rate_limit=1.0))


async def on_shutdown():
    """Close the bot session explicitly. Otherwise sessions leak
    on graceful shutdown and the next start hits a connection pool
    in a weird state.
    """
    await bot.session.close()


dp.shutdown.register(on_shutdown)

That’s 18 lines of production code plus one test:

# test_middleware.py
import pytest
from middleware import ThrottleMiddleware


@pytest.mark.asyncio
async def test_throttle_drops_rapid_second_message(mocker):
    middleware = ThrottleMiddleware(rate_limit=1.0)
    handler = mocker.AsyncMock(return_value="processed")

    event = make_event(user_id=123)  # helper to build a fake aiogram Update

    # First message — goes through
    result1 = await middleware(handler, event, {})
    assert result1 == "processed"

    # Second message same user, same second — dropped
    result2 = await middleware(handler, event, {})
    assert result2 is None

    handler.assert_called_once()

That’s the whole patch.

Why this works

The fix doesn’t make SQLite faster. It doesn’t add a queue. It doesn’t change anything about how the handlers process messages. It just stops the upstream pressure before it cascades downstream.

Once incoming updates are rate-limited per-user at 1 per second, the bot never has 10 concurrent outbound API calls. It has at most 1-2. Telegram never gets angry. TelegramRetryAfter never fires. Handlers never get stuck waiting. Sessions never leak. SQLite never sees concurrent writes for the same row.

The cascade isn’t a chain. It’s a tree, and the throttle cuts the tree at the root.

The result

Numbers (real, from production):

  • First 4 hours after deploy: zero TelegramRetryAfter. Zero TimeoutError. Session count stable at 1-2 (vs. climbing past 40 every two hours before).
  • First 24 hours: zero errors of any kind in the log.
  • First 7 days: zero crashes. Zero systemd restarts.

Bot has been up continuously since deploy. Same SQLite. Same asyncio. Same handlers. The only thing that changed is the throttle middleware.

What I’d tell a junior on the team

A few generic takeaways that apply far beyond this specific bug:

1. Find the first failure in the log and stop reading. When you see cascading errors, everything after the first failure is the system reacting to the first failure. Don’t try to “fix” the downstream errors. Find the upstream cause.

2. Upstream backpressure is the cause about 80% of the time when you see async-Python cascades. When the downstream component (SQLite, HTTP client, worker pool) looks stuck, it’s almost always waiting for something the upstream is doing too fast. Rate-limit the upstream first.

3. The temptation to rewrite is almost always wrong early in diagnosis. “Rewrite in Go” / “switch to Postgres” / “add a queue” are valid responses to real scale problems. They’re not valid responses to “I haven’t figured out the bug yet.” Spend an hour with the actual logs first.

4. Volume matters less than burstiness. A system handling 4k messages/day average can absolutely fall over from 10 messages in one second. The metric you care about is peak concurrency, not total throughput.

5. Test the throttle as a unit, not as an integration. The fix above has one test (12 lines). It doesn’t try to spin up a real bot. It just verifies the middleware behavior in isolation. That’s enough — the actual production behavior is downstream of this contract holding.

Code

The middleware and the test are public:

→ github.com/lamas51/claude-code-templates (case studies folder)

Same project also has Claude Code agent/skill/hook templates I deploy across Go, Python, and WordPress projects — feel free to fork.

About me

I’m Boris — IT-pro since 1999. I run production code across Go, Python, and React, mostly for small and mid-size businesses. Last 18 months I’ve been heavy on Claude Code workflow.

If you have a production Python service throwing similar cascades and want help diagnosing it, I take this kind of work through Fiverr (clean scope, escrow, no off-platform contact):

→ fiverr.com/lamastoma — Python / n8n / Telegram bot bug fixing in 24 hours

Open to questions in the comments — happy to dig into specifics if you’re seeing something similar.

Anonymized — no client data, the diagnosis flow and final patch are the actual ones I shipped.

5 Mistakes I Made Building a Social Media App With 7 AI Systems

I’ve spent the last nine months building Qioiper — a social media platform controlled by seven AI systems — alone.

It works. It’s live on Android. And I made five significant mistakes along the way that I wish someone had warned me about.

Mistake 1: Underestimating latency constraints on real-time AI

My first architecture for Content Guard — the system that screens uploads before they reach the platform — ran the full model on every upload. In testing, this was fine. At any meaningful scale, it would have been catastrophic.

Real-time content moderation means you’re working in milliseconds. A heavy model that takes 800ms is unusable for a real-time upload pipeline. I rebuilt it as a tiered system: lightweight classifier for clear cases, heavy model for ambiguous ones, human queue for edge cases. The rebuild cost me three weeks.

Lesson: profile latency requirements before choosing your model architecture, not after.

Mistake 2: Building CLIP integration before I had enough training data

CLIP AI is Qioiper’s content intelligence layer — it understands what content actually is, not just its metadata. The integration itself wasn’t the problem. The problem was that my fine-tuning dataset was too small for the platform’s content categories.

Early recommendations were too generic. The system knew what a photo was. It didn’t know the difference between a photo worth showing to a photography enthusiast and a photo worth showing to someone interested in travel.

More training data, better results. Obvious in retrospect, expensive in time.

Mistake 3: The Feed Ranker and User Profiler cold start problem

New users have no behavioral history. The User Profiler has nothing to work with. The Feed Ranker has no signal to rank against. The first experience on the platform is therefore generic — which is exactly the wrong first impression for a platform selling personalization.

I underestimated how long it takes to bootstrap the profiler to a useful state and how much damage a mediocre first experience does to retention.

The partial fix: explicit interest signals at onboarding. The better fix — transfer learning from aggregate patterns — is still in progress.

Mistake 4: Treating the Timing Optimizer as an independent system

The Timing Optimizer identifies each creator’s Golden Moment — the window when their audience is most active. I built it as a standalone system and integrated it later.

This created coupling problems. The Timing Optimizer needs User Profiler data to be accurate. Integrating two systems that were designed independently meant rebuilding parts of both. If I’d designed the data contracts between systems upfront, this would have been avoided.

Lesson: in a multi-model system, define the data contracts between models before you build any of them.

Mistake 5: PHP for the backend

I know PHP. I’ve built with PHP. It works.
It’s not the right choice for an AI-heavy, real-time platform that needs to scale. Response times are longer than they should be. The async story is weaker than I need. I’m migrating, but migrating a production system is significantly more expensive than building on the right stack from the start.

If you’re building something with real-time AI inference, multiple concurrent model calls, and eventual scaling requirements: Python with FastAPI or Go. Not PHP.

These mistakes cost me time, not the product. Qioiper is live and working. But they’re mistakes I’d make differently, and mistakes I see other solo founders making.

If you’re building in the AI/social/behavior intelligence space and want to compare notes — comments are open.

Qioiper on Android: Google Play

Yansımalı DLL Enjeksiyonu Rehberi Bellek İçi Saldırılar ve Savunma

Günümüz siber tehditleri, artık sadece dosya bırakmakla yetinmiyor. Saldırganlar, iz bırakmamak ve güvenlik yazılımlarını atlatmak için bellek içinde çalışan yöntemler geliştiriyor. Yansımalı DLL enjeksiyonu bu yöntemlerin en başında gelir. Adını duymuş ama ne olduğunu tam bilmeyenler için bu rehber, tekniği temel seviyeden başlayarak anlaşılır bir dille açıklıyor. Aynı zamanda profesyonel bir sızma testi uzmanının bakış açısıyla derinlemesine teknik detaylar, gerçek saldırı örnekleri ve savunma stratejileri sunuyor.

Nesil Teknoloji, TSE A Sınıfı Sızma Testi yetkisine sahip uzman kadrosuyla, bu tehdidi hem kırmızı ekip perspektifinden simüle etmekte hem de mavi ekip olarak kurumları korumaktadır. Bu yazıda, yansımalı DLL enjeksiyonunun ne olduğunu, nasıl çalıştığını, neden tehlikeli olduğunu ve bu tehdide karşı neler yapabileceğinizi adım adım öğreneceksiniz.

  1. Yansımalı DLL Enjeksiyonu Nedir Temel Kavramlar
    DLL, Dynamic Link Library yani dinamik bağlantı kütüphanesi demektir. Windows işletim sisteminde birçok program, ortak işlevleri tekrar tekrar yazmak yerine bu kütüphaneleri kullanır. Normal şartlarda bir DLL kullanılacağı zaman, program onu diskten okur, Windows’un yükleyicisi devreye girer ve DLL hafızaya alınır. Bu sırada güvenlik yazılımları da devreye girip dosyayı tarayabilir.

Yansımalı DLL enjeksiyonu ise bu işlemi atlatır. Saldırgan, hedef programın belleğine ham haldeki DLL verisini yazar, ardından kendi özel yükleyici kodunu çalıştırarak DLL’i “elle” hafızaya yerleştirir. Bu işlem sırasında Windows’un yükleyicisi kullanılmadığı için, diskte hiçbir DLL dosyası oluşmaz. Güvenlik yazılımları, dosya taraması yapamaz; çünkü ortada dosya yoktur.

Bu tekniği bir benzetmeyle anlatalım: Normal bir ev satın almak için emlakçıya gidersiniz, emlakçı sizi ev sahibiyle buluşturur, tapu işlemleri yapılır, her şey kayıtlara geçer. Yansımalı enjeksiyon ise boş bir arsa bulup, gece vakti çadır kurmak gibidir. Hiçbir resmi işlem yapmazsınız, evrak izi kalmaz. Sadece arsa sahibi (hedef program) fark ederse durdurabilir.

PE Başlık Analizi ve Bölüm Haritalama – DLL, Portable Executable (PE) formatında bir dosyadır. Yükleyici önce bu dosyanın başlık bilgilerini okur. Ardından hedef süreçte yeterli büyüklükte bir bellek bölgesi ayırır. DLL’in içindeki kod bölümleri, veri bölümleri ayrı ayrı bu bölgeye kopyalanır. Her bölümün okuma, yazma, çalıştırma izinleri doğru şekilde ayarlanır.

İthalat Tablosunun Onarımı – DLL’ler başka DLL’lerdeki fonksiyonları kullanabilir. Örneğin, ekrana yazı yazmak için user32.dll içindeki MessageBox fonksiyonuna ihtiyaç duyar. Yükleyici, hedef süreçte halihazırda yüklü olan modülleri tarar, gerekli fonksiyonların adreslerini bulur ve DLL’in içindeki ithalat adres tablosunu doldurur. Bu adım atlanırsa DLL, dış dünyaya bağlantı kuramaz ve çalışmaz.

Yeniden Konumlandırma Düzeltmeleri – DLL, derlenirken belli bir adrese yerleşmek üzere tasarlanır. Eğer o adres doluysa, yükleyici DLL içindeki tüm sabit adresleri yeni konuma göre günceller. Bu işlem, yeniden konumlandırma (relocation) tablosu sayesinde yapılır. Aksi halde kod, yanlış adreslere gider ve program çöker.

Giriş Noktasının Çalıştırılması – Tüm bu hazırlıklar tamamlandıktan sonra, DLL’in ana fonksiyonu olan DllMain, “yeni eklendim” sinyaliyle çağrılır. Artık DLL, hedef programın bir parçası gibi çalışmaya başlar.

Nesil Teknoloji’nin TSE A Sınıfı laboratuvar ortamlarında yaptığı testlerde, bu tekniğin özellikle yüksek güvenlikli sunucularda, disk izi bırakmadan kalıcılık sağlamak için kullanıldığını gözlemliyoruz. Aşağıdaki tabloda, klasik yöntemle yansımalı yöntem arasındaki farkları net görebilirsiniz.

Özellik Geleneksel DLL Enjeksiyonu Yansımalı DLL Enjeksiyonu
Disk Erişimi DLL dosyası diskten okunur, çoğu kez geçici klasöre yazılır DLL diske hiç yazılmaz, doğrudan bellekten işlenir
Kullanılan API’ler CreateRemoteThread, LoadLibrary, WriteProcessMemory belirgin iz bırakır VirtualAllocEx, WriteProcessMemory, manuel PE haritalama, LoadLibrary çağrısı yok
Yükleyici Windows PE yükleyicisi (ntdll) DLL içine gömülü özel ReflectiveLoader
EDR Tespit Oranı API hook’ları ve davranış kalıpları nedeniyle yüksek Düşük, ancak gelişmiş EDR’ler bellek taraması ve yürütme izleme ile yakalayabilir
Adli Bilişim İzi Dosya sistemi artefaktları, prefetch, MFT kayıtları mevcut Sadece bellek dump’larında analiz edilebilir, kalıcılık sağlanmadıysa yeniden başlatmayla kaybolur
Modern EDR sistemleri, yansımalı yüklemeyi tespit etmek için bellek koruma izleme ve yürütme akışı analizi gibi gelişmiş teknikler kullanır. Örneğin, normalde okuma-yazma-çalıştırma (RWX) iznine sahip bir bellek bölgesi olmaması gerekirken, yansımalı enjeksiyon sonrası oluşan böyle bir bölge anomali olarak algılanabilir. Saldırganlar ise buna karşı kullanıcı tanımlı yansımalı yükleyiciler (UDRL) ile yükleyici imzalarını sürekli değiştirerek ve bellek ayırma işlemlerini meşru API çağrıları arasına gizleyerek tespitten kaçınmaya çalışır.

  1. Gerçek Dünyadan Saldırı Örnekleri ve Etkileri
    Yansımalı DLL enjeksiyonu sadece teoride kalmıyor; son yıllarda dünyanın en büyük siber saldırılarında aktif rol oynadı. Özellikle bankacılık sistemlerine yönelik Carbanak ve FIN7 saldırılarında, saldırganlar e-posta ekleriyle gelen makrolar aracılığıyla yansımalı DLL’leri çalıştırarak kurumsal ağlara sızdı. Milyonlarca dolarlık maddi hasar oluştu ve bu saldırılar aylarca fark edilmedi.

Bir kamu kurumunda yaşanan başka bir olayda, tehdit aktörleri DNS sunucularını hedef aldı. Yansımalı bir arka kapı DLL’i, sunucunun belleğine enjekte edildi ve diske hiçbir dosya bırakılmadı. Arka kapı aylarca çalıştı, kurumun kritik verileri sızdırıldı. Olay ancak adli bilişim uzmanlarının bellek görüntüsü alıp analiz etmesiyle tespit edilebildi.

Industroyer2 adlı zararlı yazılım, Ukrayna’daki elektrik şebekelerine saldırmak için yansımalı yükleme tekniklerini kullandı. SCADA sunucularının belleğine sızan zararlı, Modbus protokolü üzerinden enerji dağıtımını manipüle ederek kesintilere neden oldu. Bu saldırı, kritik altyapıların bu tür tehditlere ne kadar açık olduğunu gösterdi.

NotPetya fidye yazılımı da yansımalı enjeksiyon kullanarak ağda hızla yayıldı. EternalBlue açığı ile sisteme sızan zararlı, yansımalı DLL’ler aracılığıyla dosya şifreleme işlemini başlattı ve dünya genelinde lojistik devlerinin günlerce çalışamamasına yol açtı.

Aşağıdaki tabloda bu tehdit grupları ve etkileri özetlenmiştir.

Tehdit Grubu / Zararlı Kullanılan Teknik Detayı Hedef Sektör Tespit Süresi
Carbanak / FIN7 Makro tabanlı yansımalı loader ile bellek içi POS malware Bankacılık, Perakende Ortalama 180 gün
Industroyer2 SCADA süreçlerine yansımalı DLL enjeksiyonu ile Modbus komut manipülasyonu Enerji, Elektrik Dağıtım 24 saat içinde müdahale edilemedi
DarkHotel APT Yansımalı yükleyici ile konuk ağlarından otel yönetim sistemlerine geçiş Konaklama, Lojistik Yıllar
APT28 (Fancy Bear) Yansımalı DLL kullanarak diplomatik ağlarda kalıcılık Kamu, Savunma Bellek analizi ile tespit edildi
Bu örnekler, yansımalı DLL enjeksiyonunun sadece teknik bir detay olmadığını, iş sürekliliğini ve ulusal güvenliği doğrudan tehdit eden bir unsur olduğunu göstermektedir. Savunma ekipleri, yalnızca dosya tabanlı taramalara güvenmemeli, bellek içi izleme ve anomali tabanlı algılama yeteneklerini geliştirmelidir.

  1. Savunma Stratejileri Standartlar ve Regülasyonlar
    Yansımalı DLL enjeksiyonu gibi bellek içi saldırılara karşı etkili bir savunma kurmak, teknolojik önlemlerin yanında uluslararası standartlara ve yerel mevzuata uyumu da gerektirir. Nesil Teknoloji, TSE A Sınıfı yetkisiyle yaptığı denetimlerde kurumlara ISO 27001 ve NIST Cyber Security Framework çerçevesinde somut aksiyonlar sunar.

NIST CSF’ye Göre Teknik Kontroller

PR.PT-3: Uç Nokta Koruma – Geleneksel antivirüs yerine davranışsal analiz ve bellek taraması yapabilen EDR çözümleri kullanılmalı. Yürütme izni olmayan bölgelerde shellcode çalıştırma girişimlerini engelleyen exploit prevention modülleri aktif edilmelidir.
DE.CM-7: Süreç Davranışı İzleme – Sysmon ve Windows Event Log ile her sürecin hangi bellek bölgelerine yazma yaptığı, hangi API’leri çağırdığı merkezi olarak toplanmalı. Özellikle VirtualAllocEx ve WriteProcessMemory çağrılarının yabancı süreçlere yönelik olması anomali olarak değerlendirilmeli.
DE.AE-3: Bellek Görüntü Analizi – Kritik sunuculardan periyodik olarak alınan bellek dump’ları, Volatility gibi araçlarla analiz edilerek yansımalı yükleyicilerin imzaları aranmalı.
ISO 27001 ve KVKK Uyumu – ISO 27001’in A.12.6 (Teknik Güvenlik Açığı Yönetimi) ve A.16.1 (Bilgi Güvenliği Olay Yönetimi) maddeleri, bellek içi saldırılara karşı hazırlıklı olmayı zorunlu kılar. KVKK’nın 12. maddesi uyarınca, kişisel veri işleyen kurumlar teknik tedbirler almak ve etkinliğini düzenli test etmekle yükümlüdür. Yansımalı DLL enjeksiyonu ile ele geçirilen bir sunucudan sızdırılan kişisel veriler ciddi idari para cezalarına yol açabilir.

Gelişmiş Algılama Yöntemleri

API Hook’larının İzlenmesi – Yansımalı yükleyiciler genellikle LoadLibrary gibi fonksiyonları kullanmaz. Bu fonksiyonlara yapılan çağrıların anormal derecede azalması veya CreateRemoteThread yerine doğrudan RtlUserThreadStart kullanılması izlenmelidir.
Bellek Koruma İhlalleri – Windows olay günlüklerinde bellek koruma değişiklikleri (VirtualProtect) takip edilmeli. RWX bölgelerinin sayısı normalin üzerindeyse derinlemesine inceleme başlatılmalı.
Yapay Zeka Destekli Davranış Analizi – Saldırganlar yükleyici imzasını değiştirse de, yükleyicinin çalışma zamanındaki davranış kalıpları (belirli bir API çağrı sırası) makine öğrenmesi modelleriyle tespit edilebilir. Nesil Teknoloji, kırmızı ekip operasyonlarında kullandığı bu yöntemleri savunma ekiplerine aktararak kurumların olgunluk seviyesini artırır.
Aşağıdaki tabloda farklı güvenlik araçlarının bu tehdidi tespit etme yeteneklerini görebilirsiniz.

Güvenlik Aracı / Katman Algılama Yeteneği Yanlış Pozitif Oranı Önerilen Kullanım
Geleneksel Antivirüs Dosya imzası bazlı, bellek içi tespit zayıf Düşük (ama kaçırma oranı çok yüksek) Tek başına yeterli değil
EDR (Next-Gen) Bellek tarama, API hook, davranış analizi ile yüksek başarı Orta-Yüksek (sıfır gün için iyileştirme gerekli) Zorunlu temel katman
Sysmon + SIEM Event ID 10, 15, 25 ile süreçler arası bellek erişimlerini loglama Orta, korelasyon gerektirir Log yönetimi ve tehdit avcılığı için olmazsa olmaz
Bellek Adli Analizi (Volatility) Manual mapping ile yüklenmiş DLL’leri listeleme, apihooks tespiti Düşük (post-mortem analiz) Olay müdahale ve adli bilişim süreçlerinde kullanılmalı
ISO 27001 ve KVKK denetimlerinde, bu araçların etkin kullanımını kanıtlamak için düzenli sızma testleri büyük önem taşır. Nesil Teknoloji, TSE A Sınıfı yetkisiyle gerçekleştirdiği testlerde yansımalı DLL enjeksiyonunu da içeren senaryolarla kurumların savunma derinliğini objektif şekilde ölçer ve aksiyon raporlarıyla iyileştirme yol haritası sunar.

  1. Endüstriyel Kontrol Sistemlerinde Bellek İçi Tehditler
    Endüstriyel Kontrol Sistemleri (ICS) ve SCADA altyapıları, yansımalı DLL enjeksiyonu gibi bellek içi saldırılara karşı özellikle savunmasızdır. Bu sistemlerde kullanılan işletim sistemleri genellikle güncel değildir ve geleneksel antivirüs çözümleri ya yoktur ya da devre dışı bırakılmıştır. Saldırganlar, yansımalı yükleyici ile OT ağına sızdıktan sonra Modbus, DNP3, IEC 61850 gibi endüstriyel protokolleri manipüle eden modüller enjekte edebilir.

Modbus/TCP Saldırı Vektörü – Modbus protokolü, kimlik doğrulama ve şifreleme içermez. Yansımalı DLL enjeksiyonu ile bir SCADA yazılımının belleğine sızan zararlı kod, Modbus fonksiyon kodlarını değiştirerek röleleri açıp kapatabilir, proses değerlerini okuyabilir veya alarmları bastırabilir. Gerçek bir sızma testinde, enerji dağıtım merkezinde yansımalı bir DLL sayesinde trafo merkezindeki tüm koruma rölelerinin uzaktan kumandası ele geçirilmiştir.

DNP3 ve IEC 61850 Güvenlik Açıkları – DNP3, SCADA sistemlerinde yaygın kullanılır ve çoğu uygulamada autentikasyon mekanizması devre dışıdır. Bellek içi saldırı ile DNP3 master’ın işlevselliği değiştirildiğinde, uzaktan terminal ünitelerine (RTU) sahte komutlar gönderilebilir. IEC 61850 ise GOOSE mesajları üzerinden anlık aç-kapa sinyallerini taşır; yansımalı enjeksiyon ile GOOSE yayınları manipüle edilerek “siyah enerji” senaryoları oluşturulabilir.

Nesil Teknoloji’nin OT/ICS Sızma Testi Yaklaşımı – TSE A Sınıfı yetkinliğimizle endüstriyel tesislerde yaptığımız testlerde yansımalı DLL enjeksiyonunu OT ağına özel kullanıyoruz. Pasif ağ dinlemesi ile protokol trafiği analiz edilir, ardından hedef SCADA istasyonunun belleğine zararsız bir test DLL’i yansımalı olarak enjekte edilir. Bu DLL yalnızca protokol komutlarını loglar ve proses değişikliği yapmaz. Elde edilen verilerle, gerçek bir saldırganın hangi noktalara müdahale edebileceği raporlanır.

Endüstriyel ortamlar için alınması gereken savunma önlemleri:

Ağ Segmentasyonu – OT ağı, IT ağından tamamen izole edilmeli, tek yönlü veri diyotları veya güvenli geçiş noktaları (firewall) ile bağlantı kurulmalı.
Uygulama Beyaz Listeleme – SCADA sunucularında sadece onaylı uygulamaların çalışmasına izin veren Application Control politikaları uygulanmalı. Yansımalı DLL enjeksiyonu, beyaz listeye alınmamış kodların bellekte çalışmasını engellemez, ancak yürütme izni olmayan alanlara yazma girişimlerini engelleyerek saldırganı zorlaştırır.
Protokol Anomalisi İzleme – Endüstriyel IDS/IPS sistemleri (Nozomi, Claroty) ile Modbus, DNP3 ve IEC 61850 trafiğindeki anormal fonksiyon kodları, adres aralıkları veya sıra dışı komut sıklıkları izlenmeli.
Kamu kurumları ve özel sektördeki üretim tesisleri, bu önlemleri hayata geçirmediği sürece yansımalı DLL enjeksiyonu gibi bellek içi saldırılara karşı savunmasız kalmaya devam edecektir. Nesil Teknoloji, endüstriyel alanda yaptığı denetimlerde hem teknik hem de süreç bazlı iyileştirmeler önererek tesislerin siber dayanıklılığını artırmaktadır.

Sık Sorulan Sorular
Yansımalı DLL enjeksiyonu yasal mı ve hangi durumlarda kullanılabilir
Bu teknik, yetkili penetrasyon testleri, kırmızı ekip tatbikatları ve adli bilişim analizleri kapsamında yasal zeminde kullanılabilir. Nesil Teknoloji, TSE A Sınıfı yetkisiyle gerçekleştirdiği tüm testlerde kurumlardan yazılı izin alır, test senaryolarını önceden tanımlar. Kötü niyetli amaçlarla kullanılması suç teşkil eder.

Güncel EDR çözümleri yansımalı DLL enjeksiyonunu tespit edebiliyor mu
Gelişmiş EDR ürünleri, bellek tarama, API hook’ları ve makine öğrenmesi modelleri sayesinde çoğu yansımalı yükleyiciyi tespit edebilmektedir. Ancak özelleştirilmiş User Defined Reflective Loader (UDRL) ve bellek ayırma teknikleriyle bu tespitler atlatılabilmektedir. Bu nedenle savunma ekiplerinin sürekli tehdit avcılığı yapması ve güvenlik yapılandırmalarını güncel tutması gereklidir.

Yansımalı DLL enjeksiyonuna karşı en etkili savunma yöntemi nedir
Tek bir sihirli çözüm yoktur. En etkili yaklaşım katmanlı savunmadır: uç noktalarda EDR, ağ seviyesinde segmentasyon ve protokol anomali izleme, log yönetimi ve SIEM ile korelasyon, düzenli sızma testleri ve personel farkındalığı bir arada uygulanmalıdır. Ayrıca kritik sistemlerin bellek görüntülerinin periyodik olarak alınıp adli analize tabi tutulması, gizli kalmış enjeksiyonların ortaya çıkarılmasını sağlar.

Endüstriyel kontrol sistemlerinde bu tehdide karşı özel bir standart var mı
IEC 62443 serisi, OT güvenliği için uluslararası kabul görmüş standarttır. IEC 62443-3-3, sistem bütünlüğü ve veri gizliliği kontrollerini tanımlarken, IEC 62443-2-1, güvenlik programı oluşturmayı zorunlu kılar. Yansımalı DLL enjeksiyonu gibi bellek içi tehditlere karşı bu standartlarda yer alan uygulama beyaz listeleme, ağ izolasyonu ve olay müdahale süreçleri doğrudan yol göstericidir.

I built a tool to instantly share web projects without deploying

As a CS student, every time I wanted to show something I built, I had to either deploy it, screen share, or send files over WhatsApp.
So I built RunZip.
Drop a ZIP file, get a live URL and QR code instantly. No login, no setup, no account. Files auto delete after 24 hours.
I built it with Node.js, Express, and Vanilla JS. Also made a desktop version with Electron.
Live site: [https://runzip.onrender.com]
GitHub: [https://github.com/rvkarthik579/runzip]
Would love feedback from the community. Is this useful to you? What would you improve?”
Dev.to is more relaxed than Reddit. Links are fine, longer posts are welcome, and developers there genuinely give good feedback.

DevOps Meets Generative AI: Building, Testing, and Deploying LLM-Powered Apps

Versioned Release Bundle

Last spring, OpenAI released a GPT-4o update that made the model hard to trust: it returned sycophantic and less reliable answers than usual, even though nothing was changed in users’ prompts and workflows.

When an LLM system starts drifting in production, the deployment history doesn’t catch it early: nothing changed in the codebase, and providers didn’t release any official updates either. Meanwhile, some providers might have adjusted a classifier without notice, and a request that worked fine yesterday, starts returning confidently wrong answers tomorrow.

If you are already running delivery pipelines, the entire process looks familiar. However, an LLM pipeline has a different kind of release object, where a minor change in prompt, model version, or guardrail can alter system behavior, even though the main codebase was never touched.

What Shapes LLM Production Behavior

While application code gets versioned carefully, changes to prompts, retrieval settings, and guardrails often happen without a formal record, making it harder to identify what exactly caused the drift in model behavior.

*– Prompts *
Sometimes, the reason for regression is a minor change in system prompt: someone changes a sentence targeting one edge case, and an unrelated query category unexpectedly starts performing worse. This happens when multiple people can edit the prompt directly, leaving the edit outside the release record.

– Model versions
In May 2025, Google redirected two dated Gemini endpoints to a newer model without notice. Developers building on gemini-2.5-pro-preview-03-25 found out the software behaved differently than the day before. Afterward, Google updated its documentation to clarify what “stable” and “preview” meant for different endpoints types. If the app works oddly, the provider might have updated the model without notice – worth checking what exact model versions show up in your API responses.

– Retrieval configuration and source data
In RAG systems, answers can drift because the index got stale or because someone changed chunking, ranker, top-k, or the embedding model – none of these requires the app to throw an error. As a result, a financial reporting assistant can start citing figures from outdated quarterly reports, because the knowledgebase was updated without refreshing the index.

*– Guardrails *
Guardrail rules are often managed outside the main app release process. The compliance team might tighten a refusal rule in a separate console, and the app starts rejecting the queries that worked fine without any change on the engineering side.

– Evaluation
A test set built when the product launched doesn’t automatically update as the product evolves. A model can keep passing eval while production has moved on: the query mix has shifted, and cases that were rare at launch now make up much of the workload.

Versioned Release Bundle

Building the delivery pipeline

In traditional software delivery, the release surface is mostly code. In LLM systems it expands to include prompts, model versions, retrieval configuration, and guardrails – components that affect production behavior just as much as the application, but rarely get the same release controls.

Building the delivery pipeline

Knowing when a release is good enough to ship

In a traditional release you have to make sure that the software runs correctly. When deploying an LLM system, you have to make sure that it behaves acceptably and safely across the full range of inputs it will encounter in production.

Golden prompts

They are fixed test cases that reflect what the system is supposed to do. For the customer support assistant, it checks whether it correctly identified the issue, pointed to the right support article, avoided making things up and escalated when necessary.

When preparing a release, each golden prompt is checked on those dimensions with passfail criteria defined before the evaluation. Some checks can be automated, while ambiguous, user-facing or high-risk outputs still need human attention. Not every failure is equally important: failure to escalate or wrong citation block the release immediately, while slightly worse phrasing on a low-traffic query probably doesn’t.

Baseline comparison

Eval scores are less stable than they look. One study on prompt sensitivity found accuracy swings of up to 76% from formatting differences alone, with no change to meaning. That is why every candidate release needs to be measured against the production version: without that reference, even a strong score can be a regression from what is already running.

Controlled rollout

Staged deployment strategies let you validate the release in production before committing to it fully. Shadow testing sends user requests in parallel through both current and new versions, but users only see the responses from the current one. Canary testing goes further and shows the new version’s responses to a small bunch of real users. If something goes wrong, you catch it on small traffic and roll back before it goes further. Before you start, decide in advance what “something is wrong means”, whether it’s worse quality of replies, more refusals, or higher cost per query.

Versioning

A quality gate is as good as the release record behind it. If the record doesn’t include the exact version of the prompt, retrieval or guardrail configuration, eval set, embedding model that are going live, you might be testing last week’s setup.

Any single change to any of them should trigger reevaluation, because even one edit can break the entire construction.

Deploying without losing the gains

Clearing every quality gate doesn’t guarantee a smooth release. Inference workloads fail differently from the standard web apps due to concurrency and adding hardware doesn’t resolve bottlenecks caused by provider-side rate limits or a queue backing up under long-context requests.

Cost behavior is also harder to predict than token billing alone would suggest. Context growth in lengthy conversations, retrieval payloads, tool-call recursion, and retry loops on failed calls all compound, making inference accountable for 80–90% of total cost of ownership in production GenAI deployments. One of ways to cut the inference costs is query routing – it’s faster and cheaper to run routine lookups through deterministic search or rule-based logic.

Keeping it reliable once it’s live

Once the system is in production, the question shifts from whether it behaves correctly to whether you know when it stops. Factors that affect production LLM behavior, such as provider update, guardrail adjustment, or users phrasing requests differently, don’t always leave obvious signals, and the challenge is to catch the shifts earlier than users do.

Monitoring what matters

Specific metrics, like retry volume and path shifts, can catch tool-use problems early, but the signal usually becomes visible when the bill arrives and the users start complaining. It’s easy to overlook cost growth as a monitoring problem, because it compounds slowly – Azure’s documentation confirms that content filter rejections and timeouts get billed even when processing fails. You need to monitor cost thresholds in advance, such as cost per query, per workflow, token growth, and retry spend.

monitor cost thresholds in advance

Where human judgment stays in the loop

While automated evaluation catches a lot, it misses things a human would notice. The system can skip confidently wrong answers, while a human looking at real outputs over time would spot a pattern with the system consistently mishandling certain types of requests, or plausible but wrong answers becoming more frequent

Where human judgment stays in the loop

Ownership, decisions, and accountability

Governance in LLM systems tends to fail quietly, usually for the same reason. Who can block a release? What counts as a production incident? What happens when output quality drops after a provider update nobody initiated?

When responsibility for the app, user experience, guardrails, and eval set is split across different departments, these questions often go unanswered. As a result, when something breaks with no trace in the codebase, there is no designated person to decide whether the regression is acceptable or whether to declare an incident.

What this looks like in practice

The client’s enterprise performance management platform was slow, expensive, and hard to debug. Two problems were compounding each other.

The first was routing: simple queries that could be handled by a database call were being processed by the LLM instead, just like complex analytical tasks. Based on internal benchmarking, making a database call would have been roughly 40x cheaper and 10x faster.

The second was traceability: the platform had been built with a separate ML model for each end customer, so when outputs degraded, there was no reliable way to tell whether it was caused by model, retrieval configuration, or something else.

Hybrid Query Routing System For Business Metrics

What we changed

We replaced per-client model architecture with a shared vector search foundation, and added rule-based routing, directing simple lookups to the database and complex ones to the LLM. We tested several models on client data to handle complex requests – GPT-4, GPT-4o, GPT-4o-mini, Mistral, and Mixtral. GPT-4o-mini offered the best balance, matching the effectiveness of GPT-4o at a lower cost.

All prompts, retrieval settings, and guardrails were versioned, making it possible to assess each release candidate based on consistent benchmarks.

For the routing layer, we developed its own test set, regression checks and configured periodic recalibration as user queries evolved. While hybrid architecture was no simpler, it was testable and versioned, making it easier to manage than the original one.

Results

LLM usage dropped by 37-46% depending on workload type, and latency for simple lookups improved by 32-38%. 68% fewer outputs were flagged as irrelevant or misleading. Manual reconciliation work (the analyst time spent catching and correcting output errors) decreased by 58%.

Conclusion

There’s usually a moment, somewhere between the successful demo and the first production incident, when the operational gap becomes obvious. A useful starting point: if something went wrong with your current system today – output degrading, behavior shifting, costs spiking – could you tell within an hour what combination of model, prompt, retrieval configuration, and source data caused it? If the answer is no, that’s where to start.

If you want to run that diagnostic on your current system, we’re happy to do it with you.

Want to make your LLM systems more reliable, scalable, and cost-efficient in production? Read our articles about LLM and DevOps on the blog 👉 https://sciforce.solutions/blog?tag=LLM&tag=dev-ops