
The Prefix Bubble

A mobile gadget shop in my location, three centuries of evidence, and the part of the AI debate that almost no one is having.


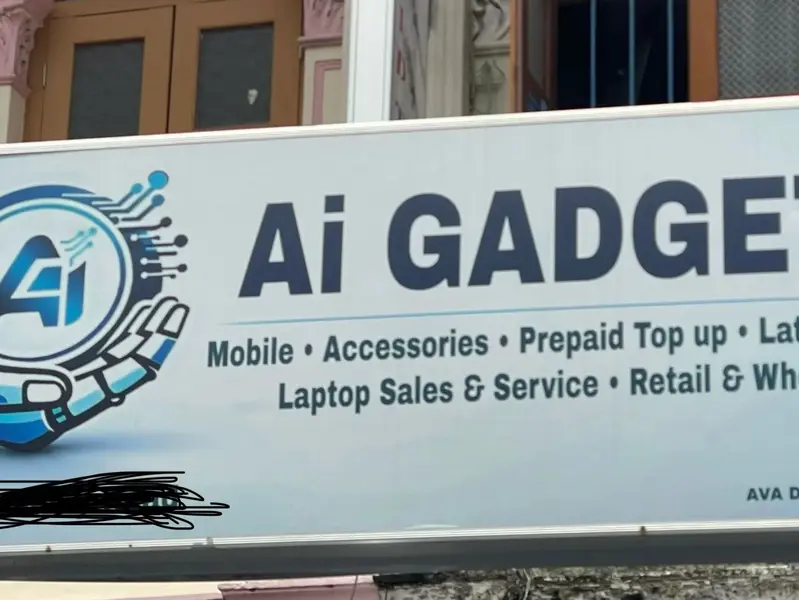
I walk down near my location after luch on a humid afternoon, I pass a mobile-phone shop. It is a modest place. It sells SIM cards, prepaid top-ups, refurbished phones, laptop accessories. The shopkeeper has been there for years.

A few days ago, the signboard above the door changed. The new name is Ai Gadgets.

There is no neural network in the building. There is no model, LLM or GenAI running anywhere on the premises. There is a counter, a glass case, a tired shopkeeper, and a freshly printed sign in a font that wants you to think of something other than what is actually being sold.

I took a photograph of it because it made me laugh. Then I wrote a short story with bit of research, comparing the rebrand to Long Blockchain Corp and the dot-com renames of 1999. The post was well received. It was also, I realised the next morning, only the first inch of the argument it had started to make.

The shopkeeper is not stupid. The shopkeeper is participating in a global ritual that is at least three hundred years old.

Every general-purpose technology produces a naming bubble. Every one. The label changes; the human does not.

A short history of prestige labels

Figure 1. Three centuries of prefix manias. The label changes; the human stays the same.

Look at the timeline above and a pattern becomes visible that any one cycle hides. South Sea, 1720. Canal Mania, 1825. Railway Mania, 1845. The Electric Belt era, the 1880s. The American auto boom, the 1900s. Radio Mania, the 1920s. Atomic this and Space-Age that in the 1950s. Bio- and Nano- prefixes in the 1980s. Dot-com in 1999. Blockchain in 2017. AI in 2024.

The intervals shorten as you approach the present, which is its own observation worth holding. But the shape repeats. Each of these episodes was, in its moment, treated as the singular event of its century. Each was preceded by a real technological breakthrough and accompanied by an explosion of operators who attached themselves to the label without participating in the breakthrough. Each ended, eventually, with a culling — and each left behind real infrastructure that compounded for the next fifty years.

The Carlota Perez framework, which I’ll come to in a moment, is the most rigorous attempt to name this regularity. But you don’t need a framework to see it. You need a long enough timeline. The shopkeeper at 28 Veerasamy Road is the 2026 instance of a phenomenon I could have photographed in 1845 London, 1899 New York, or 1920 Chicago, and would have photographed in every one of those places, with a different label on the sign each time.

The pattern is so consistent that its absence would be the historical anomaly.

1720: a company for nothing in particular

The earliest case in modern memory is the South Sea Bubble. England had just invented the joint-stock company. Speculators noticed that the word company, attached to almost anything, could pull money out of pockets that had previously kept it.

The most famous prospectus of the period offered shares in “a company for carrying on an undertaking of great advantage, but nobody to know what it is.” The promoter collected £2,000 in five hours and left town the same evening.

The magic word in 1720 was not a technology. It was a legal form — the joint-stock incorporation itself, less than a century old at the time, untested in most of its applications, and attached to a public imagination that had just glimpsed what it might do.

This matters because it tells us something about the underlying mechanism. The prefix is not specifically about science or engineering. The prefix is about whatever is the newest authoritative pattern of legitimacy. In 1720 it was incorporation. In 1845 it would be the railway. In 1899 it would be electricity. In 2026 it is artificial intelligence. The word changes. The function does not.

Isaac Newton, then in his late seventies and Master of the Royal Mint, lost most of his personal fortune in the South Sea Bubble. He had sold early at a profit, then re-bought near the peak. His reported confession afterwards was that he could “calculate the motion of heavenly bodies, but not the madness of people.”

The smartest man in England could not see the prefix coming. Neither, in their own time, can we.

1845: the railway that was never built

If you want one historical episode to project onto the current AI cycle, it is not the dot-com bust. It is the British Railway Mania of 1844 to 1847. Almost every element rhymes.

The Liverpool and Manchester Railway had opened in 1830 and proved that passenger rail was a real industrial revolution. By the early 1840s the Bank of England had cut interest rates, the Bubble Act had been repealed, and railway shares could be bought on a ten per cent deposit. By 1846, two hundred and sixty-three Acts of Parliament for new railway companies were passed in a single year, with nine thousand five hundred miles of proposed track.

About a third of these companies were never built. They either collapsed from poor financial planning, were absorbed by stronger competitors, or were outright fraudulent — vehicles for channelling investor capital into entirely other businesses. The press was complicit. There were fourteen bi-weekly railway papers at the peak, plus a daily morning and evening edition, mostly funded by the very promoters they covered.

George Hudson, the so-called Railway King, at his peak controlled over a thousand miles of track. He ran what was retrospectively recognised as a Ponzi-like scheme, paying dividends out of fresh capital. He died in poverty.

And yet — this is the part nobody wants to integrate — Railway Mania was not a waste. By 1850 Britain had a six-thousand-mile network that formed the spine of the world’s most advanced transport system. Roughly ninety per cent of the modern UK rail network was built during those mania years. The bubble was the financing mechanism for the deployment.

This is the lesson the AI cynic and the AI evangelist both miss. The bubble is real money being wasted on stupid signs — and the same bubble is laying the rails on which the next half-century will ride. The two facts are not in tension. They are the same fact, looked at from two different distances.

Saying “AI is a bubble” and “AI is the next industrial revolution” are the same statement. They are separated by about ten years and one crash.

1880: an electric belt for what ails you

Forty years after the railway crash, Edison and Tesla were household words. Electricity had moved from laboratory to lightbulb to street. The prefix of the new era was Electric.

And so we got the Pulvermacher Hydro-Electric Chain — a vinegar-soaked voltaic belt worn around the waist, which claimed to cure impotence, rheumatism, kidney pain, sciatica, dyspepsia, “weaknesses peculiar to men,” and most other diseases known to the Victorian gentleman. It was sold in the Sears Roebuck catalogue alongside guns, sewing machines, and laudanum. Tens of thousands of units moved.

Competitors swarmed: the German Electric Belt Company (which was, despite the name, based in New York), Dr. Sanden’s Electric Belt, Dr. Crystal’s, Dr. Horn’s, Owen’s, Heidelberg’s — and, hilariously, Edison’s, founded by Thomas Edison Junior, against whom his own father took out lawsuits.

The 1887 U.S. Congress had electric medical equipment wired directly into the Capitol Building so congressmen could be “treated” during sessions. The medical journals of the period are full of the same exasperated tone you find in modern AI-skeptic Twitter. The British Medical Journal called one prominent manufacturer an egregious quack. They were ignored for thirty years.

If you had walked into a New York drugstore in 1892, you would have seen electric corsets, electric brushes, electric tonics, electric baths, electric magnetic insoles. Real electricity existed. None of these products contained any. The label was doing all the work — exactly as “AI” does on a 2026 food-delivery app’s new menu-suggestion feature.

The label is the product. The product is the label. The actual technology is at most a coincidence.

Eighteen hundred companies, three winners

The automobile arrived around 1885 in Germany. By the early 1900s in the United States, over eighteen hundred separate car companies had been founded. Almost all are forgotten. Abbot-Detroit. Adams-Farwell. Armstrong Electric. The Berg. Three different companies called Courier. The 1914-only Motor Bob.

Henry Ford’s own first attempt — the Detroit Automobile Company, incorporated in August 1899 — went bankrupt in January 1901. Production problems. Quality problems. He came back later.

By 1929, the so-called Big Three — GM, Ford, Chrysler — were the only survivors at scale. The survival rate from the original cohort is roughly two-tenths of one per cent. The capital was not burned. It was redirected through a winnowing process that left an industry.

The instructive part is the naming. The survivors generally had personal names (Ford, Buick, Dodge, Chrysler, Olds) or geographic names (Detroit, Cadillac). The casualties disproportionately had prestige-tech names: Electric, Power, Motor, Automatic, Steel. The label-heavy companies died at a higher rate than the company-heavy companies.

I do not think this is an accident. I think it is a quiet signal of which founders were trying to participate in the technology and which were trying to participate in the prestige around it. The market sorted, with great cruelty, between the two.

The louder the prefix in the name, the shorter the company’s future.

The curve that keeps rhyming

The most rigorous frame for what we are watching is Carlota Perez’s Technological Revolutions and Financial Capital, published in 2002. Perez identifies five technological revolutions in the last two hundred and fifty years: the Industrial Revolution, Steam and Railways, Steel and Electricity, Oil and Mass Production, and Information and Telecommunications. Each follows the same four-phase surge.

Figure 2. Carlota Perez’s surge cycle, fitted to the present AI moment. The naming bubble peaks in Frenzy. Operators emerge in Synergy.

The phases are: Irruption (the technology arrives quietly, used by specialists), Frenzy (capital floods in, labels appear everywhere, valuations decouple from reality), Turning Point (a crash, a sorting event), Synergy (the survivors deploy the infrastructure at scale, labels drop, the operators take over), and Maturity (saturation, the next big bang waits in the wings).

The crucial point — which my LinkedIn post elided — is that the naming bubble is a feature of the Frenzy phase, not a sign that the underlying technology is fake. Steam was real. Electricity was real. Cars were real. Radio was real. The internet was real. And each of them had a Pulvermacher Belt era of its own.

Saying “AI is a bubble” and saying “AI is the next industrial revolution” are not opposing positions. They are the same position, looked at from two different points on the same curve. The bubble produces the infrastructure that the revolution will ride. The cynic and the evangelist are arguing across a temporal gap they have not noticed.

Where on the curve are we now? Probably mid-Frenzy, possibly approaching Turning Point. The shopkeeper near my local is one of the better leading indicators. When the prefix has reached the high-street signboard, you are not early.

The bubble is the financing mechanism for the deployment. Both halves are required.

The compressing half-life

Here is something that has changed, and matters. The half-life of each prestige prefix has shortened with every cycle, in rough proportion to the acceleration of media and capital flows.

Figure 3. The half-life of prestige labels has shortened with every cycle. Calibrate accordingly.

Railway lasted forty years as a viable prestige name in a company. Electric lasted about twenty-five. Radio about fifteen. Atomic about ten. Cyber about seven. Dot-com about five. Blockchain about three. The trend is not gentle. It is exponential decay.

What does this imply for AI? Plausibly, the prestige half-life of the label is forty months, not forty years. If you are building a career identity around the prefix — AI Strategist, AI Transformation Lead, Head of AI Anything or Head of Quantum — you are betting on a label whose viable shelf life is shorter than yoghurt.

The technology will last. The label will not. These are different things, and conflating them is exactly the cargo-cult error this whole essay is about.

If your identity is the prefix, your obsolescence runs on a faster clock than your competence.

Operators and name-changers

Here is the cleanest historical pattern, and the one most absent from the original LinkedIn post: the long-run winners almost never carried the prestige prefix in their name.

Watch who is still here in 2030 and not called “Acme AI Solutions.”

The table above is the historical record, written one cycle per row. The column on the left is the railway, electric, auto, dot-com, blockchain, and AI companies that put the era’s prefix on their letterhead and disappeared. The column on the right is the companies that did the same work without the prestige label, and which are still in operation, or whose successor entities are.

Ford, not Armstrong Electric. Amazon, not Pets.com. Coinbase, not Long Blockchain Corp. The Great Western Railway, not the Yorkshire and Berwick Promoters’ Consortium.

The signal is so consistent across centuries that I am willing to state it as something close to a law of the industry. Operators do not need the prefix. The prefix is a substitute for the operation. When you see it on a name, in any era, you are watching someone short the difference between what they are doing and what they want to be seen as doing.

Bet on the named, not the labelled. Ford, not Electric. The shopkeeper, not the strategist.

A test you can run on Monday

If you want to know whether the company you work for, or the role you are about to take, or the stock you are about to buy is participating in the substance of the cycle or merely the label of it, there is a five-minute test.

Take the entity’s name and strip the prestige prefix. Read what remains. Does the description still describe a business?

Ai Gadgets, with the prefix stripped, is Gadgets. That still describes a business. The shopkeeper is fine. He sells real phones to real people, and the prefix is decoration.

AI Transformation Lead, with the prefix stripped, is Transformation Lead. That, in most organisations, also describes a role. Probably not good one, but a recognisable one. Mostly fine.

Long Blockchain Corp, with the prefix stripped, is Long Corp. That describes nothing. Long what? The company name relied on the label so completely that removing the label collapsed the description. The market eventually noticed.

Pets.com, with the prefix stripped, is Pets. That is not a company, that is a category. The dot-com was load-bearing.

Run this on your own employer. Run it on your own title. Run it on every “AI-native” startup that crossed your inbox last quarter. Notice which descriptions hold and which collapse. The ones that collapse are the ones whose viability is the label, and whose half-life is whatever this cycle’s prefix-clock turns out to be.

The test costs nothing. It takes five minutes and a piece of paper. The fact that almost no one in a boardroom does it before signing the brand is the most damning thing you can say about the current state of strategic judgement.

If the description collapses when you remove the prefix, the prefix was the description.

Walk past the same Road

I want to close where I started, because the essay is really about one specific shopkeeper and what he has to teach a city’s worth of AI strategists.

Walk past the same Road on this sunday afternoon. The shopkeeper is selling a refurbished phone to a tourist. He has paid his rent. He has stocked his inventory. The signboard above his head reads Ai Gadgets and means nothing, and he knows it means nothing, and the tourist knows it means nothing, and the transaction proceeds anyway, because the label is doing exactly what labels have done since 1720: providing a small, harmless permission to participate.

One mile north, in a glass office tower, an AI Transformation Lead is preparing slides for an Architecture Review Board. He has never shipped a model. He has never read a Goodhart paper. He has never heard the name Pulvermacher. His org chart reports to an AI VP who reports to an AI CIO. None of them have read Perez. They believe they are at the beginning of something genuinely new.

They are at the middle of something very, very old.

The shopkeeper has skin in the game — his rent, his stock, his children’s school fees. If his Ai signboard pulls in one extra tourist a week, he has won. Litrally kind of less bet. If the wave breaks, he changes the sign, paints over the Ai, and the business continues. He is doing the same thing he was doing before. The prefix was always cosmetic; he knew that.

The AI XXXXXXX Lead has no skin in any game. If the wave breaks, he becomes a Quantum Transformation Lead by Q3. By Q4, a Post-AGI Strategic Officer. His résumé will absorb the next prefix without resistance, because the prefix was always the résumé.

The shopkeeper sells real phones. The strategist sells the prefix.

Bet on the shopkeeper he hedge less.
MPP TestKit VSCode Extension – Inline HTTP 402 Payment Flow Hints

The problem it solves

When you’re building or testing a pay-per-request API with MPP TestKit, you’re juggling a few moving parts at once:

  • mppFetch auto-creates a wallet, airdrops SOL, intercepts the 402, pays, and retries
  • createTestServer auto-generates a recipient keypair
  • mpp.charge({ amount: "0.001" }) gates a route and charges that amount per verified request

All of that is invisible in the code itself. You have to keep the mental model in your head, or scroll to the docs. The extension makes it visible inline — the same way TypeScript shows inferred types.

Installation

From the VS Marketplace

Search MPP Payment Flow Hints in the Extensions panel (Ctrl+Shift+X), or:

ext install mpptestkit.mpp-payment-hints

From source

git clone https://github.com/mpptestkit/mpptestkit
cd packages/vscode-extension
npm install
npm run compile

# Package and install locally
npm install -g @vscode/vsce
vsce package --no-dependencies
code --install-extension mpp-payment-hints-0.1.0.vsix

Requires VS Code 1.75+ and editor inlay hints enabled (editor.inlayHints.enabled).

What you see

Every MPP SDK call gets a small inline label right after the opening (. Here’s what each one shows:

mppFetch

const res = await mppFetch( ⬡ 402 flow: wallet → pay → retry  "http://localhost:3001/api/data");

This call does a lot: creates a wallet, requests an airdrop (devnet/testnet), hits the URL, intercepts the 402, sends a SOL transfer, and retries with the Payment-Receipt header. The hint makes that whole flow visible at the call site.

createTestClient

const client = await createTestClient( ⬡ auto-wallet · airdrop  {
  network: "devnet",
  onStep: (step) => console.log(step.type, step.message),
});

Reminds you that this call generates an ephemeral Solana keypair and funds it via airdrop — no wallet setup needed on devnet/testnet.

client.fetch

const res = await client.fetch( ⬡ handles 402 automatically  "http://localhost:3001/api/data");

Same flow as mppFetch, but on a pre-created client with a reused wallet.

mpp.charge — extracts the SOL amount

app.get("/api/data",
  mpp.charge( ⬡ 0.001 SOL per request  { amount: "0.001" }),
  (req, res) => res.json({ data: "premium content" })
);

The extension reads ahead in the document to find amount: "X" and shows the actual value in the hint. If no amount is found (e.g., the argument is a variable), it falls back to ⬡ SOL payment required.

createTestServer

const mpp = createTestServer( ⬡ auto-recipient wallet  );

Confirms that the server auto-generates a recipient keypair. Useful when you’re debugging which address is receiving payments.

How it works

The extension registers a vscode.InlayHintsProvider for TypeScript, JavaScript, TSX, and JSX files. On each document change, it scans the document text for the five patterns above and places hints at the offset immediately after the opening ( of each call.

class MppInlayHintsProvider implements vscode.InlayHintsProvider {
  provideInlayHints(document: vscode.TextDocument, range: vscode.Range) {
    const text = document.getText();

    // Only activate in files that use mpp-test-sdk
    if (!text.includes("mpp-test-sdk")) return [];

    const hints: vscode.InlayHint[] = [];

    for (const pattern of PATTERNS) {
      pattern.regex.lastIndex = 0;
      let match: RegExpExecArray | null;

      while ((match = pattern.regex.exec(text)) !== null) {
        const pos = document.positionAt(match.index + match[0].length);
        if (pos.isBefore(range.start) || pos.isAfter(range.end)) continue;

        const label = pattern.getLabel(match, text);
        const hint = new vscode.InlayHint(pos, " " + label + " ", vscode.InlayHintKind.Type);
        hint.paddingLeft = true;
        hints.push(hint);
      }
    }

    return hints;
  }
}

The extractChargeAmount helper looks ahead up to 200 characters from the ( to find amount: "X":

function extractChargeAmount(text: string, offset: number): string {
  const snippet = text.slice(offset, offset + 200);
  const m = /amounts*:s*["']([0-9.]+)["']/.exec(snippet);
  return m ? m[1] : "";
}

This handles same-line and next-line argument layouts without needing a full AST.

Activation

The extension activates lazily — only when you open a TypeScript or JavaScript file. If the file doesn’t import from mpp-test-sdk, no hints are computed at all (controlled by the showOnAllFiles setting).

"activationEvents": [
  "onLanguage:typescript",
  "onLanguage:javascript",
  "onLanguage:typescriptreact",
  "onLanguage:javascriptreact"
]

Settings

Open VS Code settings (Ctrl+,) and search MPP:

Setting Default Description
mpp.hints.enabled true Toggle all hints on/off
mpp.hints.showOnAllFiles false Show hints in every JS/TS file, not just mpp-test-sdk files

Or set them directly in settings.json:

{
  "mpp.hints.enabled": true,
  "mpp.hints.showOnAllFiles": false,
  "editor.inlayHints.enabled": "on"
}

The broader picture

The extension fits into the MPP TestKit toolchain alongside the CLI:

# Test a live endpoint from the terminal
npx mpp-test-cli https://api.example.com/data

# See the payment flow in your editor as you write the code
# → extension shows hints inline
  • CLI (mpp-test-cli) — fire-and-forget endpoint testing from the terminal
  • VSCode extension — ambient context in your editor as you write integration tests or server code

Both activate only when you’re working with mpp-test-sdk so they stay out of the way otherwise.

Links

The README Was a Protocol. The Entrypoint Was Still Optional.

cover image

cover image

Glossary: terms used in this article

🔸 MICA (Memory Invocation & Context Archive): A governance schema for AI context management. Defines how context should be structured, trusted, scored, and handed off across sessions.

🔸 Invocation Hierarchy: The operational ladder — natural, guided, forced — that determines how MICA actually reaches a live session.

🔸 Activation Packet: The compiled session-start object that declares read targets, load state, self-test posture, drift status, and gate outcome.

🔸 Session Report: The structured opening output that declares what was loaded, what the self-test found, and whether the session gate is open.

🔸 README-as-Protocol: The pattern where the model’s natural tendency to read the README first is formalized as a declared invocation mechanism. Introduced in v0.1.8.

1. Where Part 6 Left Off

Part 6 showed what MICA looks like inside a single maintenance agent — session report, drift detection, design invariants, deviation log. The structure held. The protocol ran.

Part 6 ended with a harder question: what happens when accumulated session knowledge needs to govern the next session — inside a tool that runs within AI workflows itself?

The answer depends on a prior question: does the next session actually load what was accumulated?

That is not a schema problem. It is an entrypoint problem.

2. The Gap README-as-Protocol Left Open

The Entrypoint Gap

Part 4 made a specific assumption: in many repository-based AI workflows, the README is already the model’s first orientation surface.

That observation became README-as-Protocol.

Instead of inventing a new installation mechanism, MICA formalized an existing behavior: the model reads the README, the README points to the archive, and the session is expected to load context, run checks, and report readiness before work begins.

That assumption was useful.

It gave MICA a path into the session without requiring plugins, services, or custom host infrastructure.

But a protocol is not an entrypoint.

The README can declare where the archive is, what invariants matter, what the session report must contain. None of that guarantees sequencing. A model can still skim the README, jump directly into code, or begin work before declaring its load state.

A gate without a consequence is still only etiquette.

That is the gap this version had to close.

3. The Answer: An Invocation Hierarchy

The Activation Spectrum

MICA does not auto-invoke by magic. If no human, host, wrapper, or launcher calls the memory contract, the archive can exist without governing anything. This is the same truth Part 2 identified: the structure can exist, and the model can still have no reliable way to know it exists.

The answer is an explicit hierarchy.

Natural — the model reads the project surface voluntarily: README, mica.yaml, archive JSON, playbook. No intervention required.

Guided — a host agent requests the activation packet before work begins. The packet declares read targets, self-test posture, drift state, and gate outcome. The host uses it to preflight the session.

Forced — a launcher blocks repository work until the session report clears. This is the strongest path and the least elegant one. It is also the one that survives noisy real-world terminal workflows.

4. What Changed in Code

The output mechanism

Three concrete moves made this operational.

Session report became a real runtime output.

parser.add_argument(
    "--format",
    choices=["text", "json", "hook", "session-report"],
    default="text"
)

The opening report is now a compiled object — not a protocol expectation, not a prose description. A host can consume it directly.

Invocation is now compiled, not described.

mica_invoke.py compiles read targets and session report into one activation packet:

packet = {
    "mode": mode,
    "entry_strategy": mode,
    "read_targets": _layer_targets(project_root),
    "session_report": report,
}

This is the shift from documentation-first startup to packet-first startup. The host no longer has to infer the sequence from prose.

In guided mode, the output is already shaped for host consumption:

{
  "mode": "guided",
  "entry_strategy": "guided",
  "read_targets": [
    {"name": "readme", "...": "..."},
    {"name": "mica_yaml", "...": "..."},
    {"name": "archive", "...": "..."},
    {"name": "playbook", "...": "..."},
    {"name": "lessons", "...": "..."}
  ],
  "session_report": {
    "archive_version": "1.7.8",
    "self_test": {"pct": "CLOSED", "closed_contract": true},
    "drift_status": {"status": "NO_DRIFT"},
    "gate": "PASS"
  },
  "directive": "Host agent should load declared MICA surfaces first and use the session report as opening state."
}

Forced mode now has consequence.

if args.mode == "forced" and packet["session_report"].get("gate") == "BLOCKED":
    sys.exit(1)

The simplest entry surface:

@echo off
python "%~dp0toolsmica_invoke.py" %*

That wrapper gives MICA an enforceable terminal entrypoint instead of relying on good behavior.

5. STEM-BIO-AI: The Cleaner Case

Dependency Shift

STEM-BIO-AI already had a mature MICA memory layer — archive, playbook, lessons, invocation protocol, drift profile. What changed was not the memory model. It was how that model becomes operative before work begins.

That difference is visible across all three invocation modes.

In natural mode, the helper preserves the README-first path and makes the expected read order explicit:

[MICA INVOKE] mode=natural
Gate       : PASS
State      : INVOCATION_MODE
PCT        : CLOSED
...
Directive: Prefer reading README first, then load mica.yaml, archive, and playbook before scan work.

In guided mode, the same startup becomes a host-consumable packet:

{
  "mode": "guided",
  "read_targets": ["readme", "mica_yaml", "archive", "playbook", "lessons"],
  "session_report": {
    "archive_version": "1.7.8",
    "self_test": {"pct": "CLOSED", "closed_contract": true},
    "drift_status": {"status": "NO_DRIFT"},
    "gate": "PASS"
  }
}

In forced mode, the launcher uses the same contract as a gate:

[MICA INVOKE] mode=forced
Gate       : PASS
State      : INVOCATION_MODE
PCT        : CLOSED
...
Directive: Block work until the session report gate is not BLOCKED.

The session report now looks like this:

[SESSION READY]
Archive: 1.7.8
Load: {"state": "INVOCATION_MODE", "mica_yaml": "memory\mica.yaml"}
Self-test: {"pct": "CLOSED", "closed_contract": true}
Drift: {"status": "NO_DRIFT"}
Active invariants: {"critical_count": 15, "high_count": 3}
Gate: PASS

Before, the package told the operator how to start correctly. Now, the session declares whether it actually did.

Before this version, starting a STEM-BIO-AI session correctly still depended on the operator remembering to load the right memory surfaces in the right order. Now that dependency can move upward: in guided mode to the host, and in forced mode to the launcher.

6. CCGE: The Harder Case

retaining identity

CCGE is more important precisely because it is harder. It is already a governance-heavy runtime. If MICA’s identity were weak, it would disappear into the larger framework.

CCGE here is the Care Chain Governance Engine: a fail-closed clinical governance runtime with its own execution core, artifact generation, policy layers, and approval logic. That is why it is the harder case. MICA is not being tested in isolation. It is being tested inside a system dense enough to swallow it.

It did not.

The boundary stayed explicit:

  • MICA = invocation, memory, invariants, drift control
  • CCGE Core = fail-closed runtime and artifact generation
  • STEM-AI = trust re-audit and classification

That is the important architectural result. In STEM-BIO-AI, MICA is already close to the center of the tool’s operational identity. In CCGE, MICA has to retain its own identity inside a much larger runtime. It does so by remaining responsible for invocation, memory, invariants, and drift control, while CCGE Core remains responsible for fail-closed execution and artifact logic.

The current session report in CCGE:

[SESSION READY]
Archive: None
Load: {"state": "INVOCATION_MODE", "mica_yaml": "mica.yaml"}
Self-test: {"pct": "CLOSED", "closed_contract": true}
Drift: {"status": "NO_DRIFT"}
Active invariants: {"critical_count": 0, "high_count": 0}
Gate: PASS

Archive: None with Gate: PASS is not a contradiction. The baseline archive does not yet expose a project.version field. MICA detected that gap and reported it before any work began. A system that hides its own incompleteness is not governed. A system that surfaces it at session start is.

The reason is concrete: the active archive is still a baseline integration memory object, not yet a fully target-bound archive. Its project block still carries placeholders like:

"project": {
  "name": "<target-repo-name>",
  "path": "<absolute-or-repo-relative-path>",
  "owner": "<org-or-maintainer>",
  "integration_program": "CCGE Unified Model",
  "target_status": "phase_1_candidate"
}

So the current report is telling the truth about what exists: a coherent MICA package around a still-baseline archive.

A README might have let that gap stay invisible. The session report surfaced it immediately. That is what honest governance looks like before an archive is fully populated.

7. What This Means for Anyone Building Agent Workflows

Architecutural imperatives

Three lessons from running this against two different projects.

Human-readable startup is not enough. If the only valid path lives in a README, the protocol is vulnerable to partial reading and host variance. STEM-BIO-AI is the clean example here: the memory layer was already mature, but correct startup still depended too much on the operator remembering to load it.

Session-start state must be machine-usable. If a host agent cannot consume the startup declaration as a structured object, it cannot reliably preflight the session. That is why guided mode matters more than another explanatory document: it gives the host an object to act on, not just instructions to interpret.

A gate needs an entrypoint. A session report can be a conceptual hard gate, but until a launcher or host uses it as an entry condition, it remains a convention. CCGE is the stronger proof of that point because the environment is already dense with governance logic; without an explicit entry surface, MICA would have been easy to blur into the surrounding framework instead of remaining its own startup layer.

8. What This Does Not Claim

MICA does not self-invoke automatically in all environments. There is still no natural law that forces an LLM session to load the governed archive first.

The real claim is narrower:

  • MICA can now be read naturally
  • MICA can now be requested deliberately
  • MICA can now be enforced mechanically

Not total automation. A realistic path to enforceable startup.

9. What Part 8 Will Address

The startup path is now much stronger.

But one question remains:

How much of the session-start contract should be owned by the archive itself, and how much should remain a runtime default?

The current line can emit session-report, compile guided packets, and block in forced mode. The next step is stricter archive ownership — richer session_report_format, explicit per-archive session_gate_policy, better drift contracts.

Part 8 is not about whether MICA should govern startup. It already does. It is about how much of that behavior should be declared by the archive rather than inferred by the runtime.

The series continues only where there is something concrete to specify, test, or correct.

Named decision from this post: A protocol is not yet an entrypoint. MICA becomes operational only when invocation is structured as natural, guided, or forced — and the session begins from a declared activation packet, not from hope.

MICA is part of the Flamehaven governance-first AI systems practice. Schema, technical report, and production instance: flamehaven.space. Open-source tooling: AI-SLOP-Detector. All schema references follow the v0.1.8.1 Universal standard unless a specific earlier version is named.

Your AI Agent Doesn’t Need an API Key: Entra Agent ID and Anthropic’s Workload Identity Federation

Your AI Agent Doesn’t Need an API Key: Entra Agent ID and Anthropic’s Workload Identity Federation

Every system that authenticates with a static API key is carrying a liability disguised as a convenience. The key does not expire unless someone sets a calendar reminder. It does not know who is using it. It cannot tell you whether the request that just hit the endpoint came from the production agent it was minted for or from a laptop in a coffee shop where someone pasted it into a terminal two months ago. Static keys are the skeleton key of modern distributed systems — they open the door for anyone who holds them, and they never ask why.

This is not a new problem, but it is becoming a dangerous one. As AI agents proliferate across enterprise environments — calling model APIs, orchestrating workflows, accessing downstream services — the number of static secrets embedded in configuration files, environment variables, and CI pipelines is growing faster than any rotation policy can keep up with. The question is no longer whether your organization has a leaked key somewhere. The question is how many, and which ones an attacker has already found.

The industry’s answer has been converging for years, and it has a name.

Workload Identity Federation

Workload Identity Federation (WIF) is a pattern — not a product, not a proprietary protocol — built on top of OpenID Connect and the RFC 7523 JWT bearer grant. The idea is disarmingly simple: instead of minting a long-lived secret and handing it to a workload, you let the workload prove who it is using a short-lived, signed JSON Web Token issued by an identity provider (IdP) you already trust. The receiving system validates the JWT’s signature against the IdP’s published keys, checks the claims against rules you configured, and — if everything lines up — issues a short-lived access token in return. No secrets to store. No secrets to rotate. No secrets to leak.

The pattern has been adopted across the industry — by major cloud providers, CI/CD platforms, container orchestrators, and increasingly by model providers. Microsoft Entra, for its part, supports WIF both as an issuer (your Entra tenant issues JWTs that external systems trust) and as a relying party (your Entra tenant trusts JWTs from external identity providers to grant access to Entra-protected resources). That bidirectional capability is what makes the rest of this story possible.

Anthropic embraces the standard

Anthropic has brought native Workload Identity Federation support to the Claude API — and this deserves more attention than it has received.

With Anthropic’s WIF implementation, any OIDC-capable identity provider can authenticate workloads to the Claude API without a static sk-ant-... key ever being involved. You register your IdP as a federation issuer in the Anthropic Console, define a federation rule that maps incoming JWT claims to a service account, and your workload does the rest: present the JWT, receive a short-lived Claude access token, call the API. The SDKs handle the exchange and the refresh loop. API keys can be disabled entirely on the Anthropic workspace.

Three concepts on the Anthropic side matter here:

  • Service accounts (svac_...) — non-human identities inside your Anthropic organization. A federated token acts as a service account. Unlike an API key, a service account has credentials minted for it on demand, and you can audit which workloads acted as which service account.
  • Federation issuers (fdis_...) — the registration of your OIDC identity provider with your Anthropic organization. Each issuer tells Anthropic “JWTs signed by this provider may assert workload identity for my org.”
  • Federation rules (fdrl_...) — the bridge between an issuer and a service account: “when a JWT from issuer X has claims that look like Y, mint a token for service account Z.”

The Console includes presets for common providers and a generic OIDC option that works with any standards-compliant issuer — including Microsoft Entra ID. That last bullet is the one this article cares about.

Microsoft Entra Agent ID — identity built for agents

Microsoft Entra Agent ID introduces first-class identity constructs purpose-built for AI agents. Not repurposed service principals. Not human user accounts pressed into service. Dedicated objects with a dedicated governance model.

The constructs that matter for this story:

  • Agent identity blueprints — the template and authentication foundation for one or more agent identities. The blueprint holds the credentials (client secret, certificate, or federated identity credential) and uses them to acquire tokens on behalf of all agent identities created from it. Conditional Access policies applied to a blueprint propagate to every agent identity it parents.
  • Agent identities — the runtime identity of a specific AI agent. An agent identity has no credentials of its own. It authenticates through its blueprint.
  • The Microsoft Entra SDK for Agent ID — a containerized sidecar that handles token acquisition, validation, and secure downstream API calls. Your agent code asks the sidecar for a token; the sidecar handles the identity plumbing.

The proof of concept

The question I wanted to answer was concrete: can an AI agent, using Microsoft Entra Agent ID as its native identity, call the Anthropic Claude API through Workload Identity Federation — with no API key, no certificate in agent memory, and no cloud LLM proxy in between?

The answer is yes. I built a proof of concept that does exactly this.

The architecture

The PoC runs as two containers on a Docker bridge network:

  1. claude-wif-agent — a Flask application that receives user queries, asks the sidecar for an Entra JWT, exchanges that JWT for a Claude access token, and calls the Claude Messages API.
  2. claude-wif-sidecar — the Microsoft Entra Auth SDK sidecar, which handles the client-credentials flow against Entra ID and returns a signed JWT scoped to the agent identity.

The token flow has nine steps, but the critical insight lives in three of them:

  • Steps 4–5: The sidecar uses the blueprint’s credentials to obtain an Entra-issued JWT for the agent identity. The JWT carries the agent’s appid, oid, and — crucially — the xms_par_app_azp optional claim that identifies the parent blueprint.
  • Step 7: The agent application exchanges that Entra JWT for a Claude access token by posting to POST https://api.anthropic.com/v1/oauth/token using the RFC 7523 jwt-bearer grant. Anthropic validates the JWT’s signature, checks the claims against the federation rule, and returns a short-lived token.
  • Step 9: The agent calls POST https://api.anthropic.com/v1/messages with the Claude token. No API key is involved. No MSAL library is needed. No certificates sit in agent memory.

Three Entra objects — and why the third is easy to miss

The PoC requires three distinct Microsoft Entra objects. Two of them sound similar and the third is implicit in WIF mechanics — which is exactly why it trips people up.

  1. An Agent Identity Blueprint — holds the credentials (client secret for local dev; managed identity or federated identity credential in production) and parents the agent identity.

  2. An Agent Identity — the runtime identity of the specific AI agent. No credentials of its own — the blueprint mints tokens on its behalf.

  3. An App Registration representing the Anthropic API — and this is the one that is easy to miss. Anthropic’s WIF rule validates an Entra-issued JWT, and the only way that JWT carries the right aud (audience) claim is if Entra issues it for a registered resource application whose ID matches what you configured as the audience of the federation issuer in the Anthropic Console. This app registration uses v2.0 tokens (requestedAccessTokenVersion: 2), has acceptMappedClaims: true, and configures the xms_par_app_azp optional claim on the access token — so that a single Anthropic federation rule can match all agent identities parented by the same blueprint, rather than requiring a rule per individual agent.

The token that reaches Anthropic carries:

  • iss = https://login.microsoftonline.com/<tenant-id>/v2.0
  • aud = the Application ID of the Anthropic API app registration
  • appid = the Agent Identity’s client ID
  • oid = the Agent Identity’s object ID
  • xms_par_app_azp = the Agent Identity Blueprint’s application ID

Anthropic validates all of this against the federation issuer and rule you configured. No Anthropic API key is involved at any point.

Both flows work

The PoC supports both access patterns that the agent identity platform defines:

  • Autonomous (app-only): The agent identity acts independently. The sidecar obtains a client-credentials token, the agent exchanges it for a Claude token, and the response comes back tagged "flow": "autonomous".
  • On-Behalf-Of (OBO): When a signed-in user’s Entra Bearer token is available, the sidecar performs an OBO exchange and mints an agent-on-behalf-of-user token, which is then exchanged with Anthropic WIF. The response comes back tagged "flow": "obo".

Both flows use the same Anthropic WIF endpoint. The only difference is whose authority the Entra JWT represents — the agent’s own, or the agent acting on behalf of a human.

From local dev to production

The PoC uses a client secret on the blueprint for local development — a pragmatic shortcut for proving the concept. Moving to production requires changing exactly two environment variables in the sidecar configuration to switch from client secret to managed identity, and adding a federated identity credential on the blueprint for the managed identity. No agent code changes. The sidecar abstracts the credential source entirely.

The credentials-free agent

This is where the threads converge. Workload Identity Federation is an industry standard. Anthropic has built native support for it into the Claude API. Microsoft Entra Agent ID provides purpose-built identity constructs for AI agents — with blueprints that centralize credential management, agent identities that carry no secrets of their own, and a sidecar SDK that abstracts the entire token lifecycle.

Put them together and you get something that would have been difficult to describe two years ago: an AI agent that authenticates to a third-party model provider using its own agentic identity, issued by the enterprise identity provider, validated through standards-based federation — with no static API key, no certificate in memory, and no cloud LLM proxy sitting in between. The agent’s identity is its credential.

The proof of concept is open on GitHub: astaykov/claude-wif-agentid. It is minimal by design — a Flask app, a sidecar, a docker-compose.yml, and a .env file. The README walks through every Entra object, every Anthropic Console configuration step, and the full token flow. Fork it, break it, extend it.

The age of the static API key — for AI agents, at least — is ending. The identity infrastructure to replace it is already here.

References

ECDSA – The Math That Only Goes One Way

Bitcoin gives you the ability to generate a key pair,  a public key and a private key. You generate a signature with your private key, and that signature is what you attach to a transaction. It proves to any third party that the transaction was authorized by you, the rightful owner, without you ever having to reveal the key itself.

But what is actually happening underneath that process?

ECDSA — Elliptic Curve Digital Signature Algorithm

The mechanism behind all of it is ECDSA — a digital signature system built on elliptic curve cryptography.

An elliptic curve is defined by the equation y² = x³ + ax + b. Bitcoin fixes the constants at a = 0 and b = 7, which reduces the equation to the one introduced in the last article:

y² = x³ + 7

This is called the secp256k1 curve. Every key, every signature, every verification happens through operations on points that lie on this curve, inside the finite field.

ECDSA handles three things: key creation, signature generation, and signature verification. Each one builds on the last.

Key Creation

A private key is a randomly generated large integer d — chosen from the range 1 to n − 1, where n is the order of the secp256k1 curve. It’s a 256-bit number, meaning it’s chosen from a space of roughly 2²⁵⁶ possibilities. No one chooses it for you, no server stores it, no institution knows it. It exists only where you keep it.

The public key Q is then derived from it:

Q = d · G

G here is the generator point — a fixed, agreed-upon point on the secp256k1 curve that the Bitcoin network uses. The operation d · G is point multiplication, a one-way operation: the point G is added to itself d times using elliptic curve addition rules, all within the finite field.

Think of your public key as your account details — the address people send funds to. Your private key is your transfer authorization, except unlike a bank PIN, it isn’t held by anyone else. Only you.

One-Way Operations — Why You Can’t Go Backwards

To understand why reversing Q = d · G is impossible, it helps to start with something more familiar: prime factorization.

It is believed that prime numbers are the fundamental building blocks of all natural numbers — that every positive integer greater than 1 is a product of primes. Take 504 as an example:

504 = 2 · 2 · 2 · 3 · 3 · 7

Multiplying those factors together to get 504 is trivial. But hand someone 504 and ask them to recover the prime factors, and the only known approach is to repeatedly divide by every prime smaller than the number. As the numbers scale up to hundreds of digits, this becomes computationally infeasible. No shortcut is known to exist aside this naive way.

Point multiplication on an elliptic curve works on the same principle, and this amongst other reasons guarantees security. Computing Q = d · G given d is fast. But given only Q and G — recovering d — is the elliptic curve discrete logarithm problem. There is no known efficient algorithm to reverse it.

This one-way property is the entire basis of Bitcoin’s security. But what does actually mean for the digital signatures in Elliptic curve digital signature algorithm.

Digital signature, like handwritten signature allows a receiver to convince a third party that a document came from a specific sender. Unlike a digital signature, handwritten signature can be forged, copied, or lifted from one document and placed on another.

More critically, a handwritten signature at the bottom of a document doesn’t guarantee the contents above it weren’t altered after signing. The signature and the message are separate things.

A digital signature fixes both problems. It cannot be forged, producing a valid signature requires the private key, which only the owner holds. And it is bound to the exact content of the message if a single character in the transaction changes after signing, the signature becomes invalid. It doesn’t just sign a document. It signs every bit of it.

S3 Files Killed My Least Favorite Lambda Pattern

Old vs new flow

Every Lambda function I have written that touches S3 has the same three lines of plumbing:

s3.download_file(bucket, key, "/tmp/input.csv")
process("/tmp/input.csv", "/tmp/output.csv")
s3.upload_file("/tmp/output.csv", bucket, output_key)

Download. Process. Upload. Clean up /tmp. Handle the edge case where /tmp is full from a previous invocation. Handle the edge case where the download fails halfway. Handle the edge case where you run out of the 10 GB ephemeral limit because someone uploaded a file larger than you expected.

S3 Files makes all of that go away. You mount the bucket at /mnt/workspace and use open(). The file is right there. You write the output. It syncs to S3.

The Problem It Solves

Lambda functions that process files from S3 have always followed the same ritual:

  1. Download the object from S3 to /tmp
  2. Process it with whatever tool expects a file path
  3. Upload the result back to S3
  4. Clean up /tmp so the next invocation doesn’t run out of space

This works. It also creates problems.

/tmp is ephemeral. It’s limited to 10 GB. It’s not shared between invocations on different execution environments. If your function fails halfway through processing, you retry the entire download. If multiple functions need the same reference file, each one downloads its own copy.

For a single CSV transform, the overhead is tolerable. For a pipeline that processes PDFs, images, video, or runs tools like ffmpeg, imagemagick, trivy, or semgrep, the download-process-upload loop becomes the majority of your code and the majority of your execution time.

S3 Files eliminates the loop. Your function mounts the bucket and reads files directly.

Old vs new flow

How It Works

S3 Files is a managed NFS v4.1+ file system built on Amazon EFS that presents your S3 bucket as a directory tree. When you mount it on a Lambda function, the function sees files and directories at /mnt/your-path. Under the hood, the data still lives in S3.

The architecture uses what AWS calls “stage and commit”:

  1. Your function reads and writes files through the NFS mount
  2. An EFS caching layer stores actively accessed data for low-latency access (~1ms)
  3. Changes written through the mount are exported back to S3 within minutes
  4. Changes made directly through the S3 API appear in the file system within seconds (sometimes longer)

The two layers are explicitly separate. The file system side gives you NFS close-to-open consistency. The S3 side gives you standard strong consistency. Each preserves its own semantics.

For large sequential reads (1 MiB or larger), S3 Files bypasses the cache entirely and streams data directly from S3 using parallel GET requests. This means ML training data, large CSVs, media files, and Parquet datasets get full S3 throughput without paying the cache premium. Files smaller than 128 KB (configurable) are the ones that get stored on the high-performance layer for low-latency access.

Stage-and-commit architecture

What It Looks Like

The old way:

import boto3
import csv
import os

s3 = boto3.client("s3")

def handler(event, context):
    bucket = event["bucket"]
    key = event["key"]
    output_key = key.replace("incoming/", "processed/")

    s3.download_file(bucket, key, "/tmp/input.csv")

    with open("/tmp/input.csv", newline="") as src, 
         open("/tmp/output.csv", "w", newline="") as dst:
        reader = csv.DictReader(src)
        writer = csv.DictWriter(dst, fieldnames=["email", "account_id"])
        writer.writeheader()
        for row in reader:
            writer.writerow({
                "email": row["email"].strip().lower(),
                "account_id": row["account_id"].strip()
            })

    s3.upload_file("/tmp/output.csv", bucket, output_key)

    os.remove("/tmp/input.csv")
    os.remove("/tmp/output.csv")

    return {"output": output_key}

The new way:

import csv
from pathlib import Path

WORKSPACE = Path("/mnt/workspace")

def handler(event, context):
    source = WORKSPACE / event["relative_input_path"]
    target = WORKSPACE / event["relative_output_path"]
    target.parent.mkdir(parents=True, exist_ok=True)

    with source.open(newline="") as src, target.open("w", newline="") as dst:
        reader = csv.DictReader(src)
        writer = csv.DictWriter(dst, fieldnames=["email", "account_id"])
        writer.writeheader()
        for row in reader:
            writer.writerow({
                "email": row["email"].strip().lower(),
                "account_id": row["account_id"].strip()
            })

    return {"output_path": str(target)}

No boto3. No temporary files. No cleanup. The output is written directly to the mounted S3 bucket and syncs back to S3 automatically.

The real win shows up when the processing step isn’t a simple CSV transform. If your function shells out to git, ripgrep, ffmpeg, trivy, or any tool that expects a filesystem path, a mounted workspace is simpler than teaching every tool to speak S3.

The Setup

S3 Files on Lambda requires more infrastructure than a plain S3 trigger. Here’s what you need:

Requirements:

  • An S3 file system created on a general purpose bucket (S3 versioning must be enabled)
  • Mount targets in the same VPC and Availability Zones as your Lambda function
  • Security groups allowing NFS traffic on port 2049
  • Lambda function connected to the VPC
  • Execution role with s3files:ClientMount (and s3files:ClientWrite for write access)
  • s3:GetObject and s3:GetObjectVersion for direct read optimization
  • Function memory set to 512 MB or higher (required for direct reads from S3)

The SAM template:

Resources:
  ProcessingFunction:
    Type: AWS::Serverless::Function
    Properties:
      FunctionName: FileProcessorFunction
      CodeUri: ./src
      Handler: index.handler
      Runtime: python3.13
      MemorySize: 512
      Timeout: 300
      VpcConfig:
        SecurityGroupIds:
          - !Ref LambdaSecurityGroup
        SubnetIds:
          - !Ref PrivateSubnet1
          - !Ref PrivateSubnet2
      FileSystemConfigs:
        - Arn: !GetAtt S3FilesAccessPoint.Arn
          LocalMountPath: /mnt/workspace
      Policies:
        - Statement:
            - Effect: Allow
              Action:
                - s3files:ClientMount
                - s3files:ClientWrite
              Resource: "*"
            - Effect: Allow
              Action:
                - s3:GetObject
                - s3:GetObjectVersion
              Resource: !Sub "arn:aws:s3:::${BucketName}/*"

The VPC requirement is the biggest change from a standard Lambda + S3 setup. If your function isn’t already in a VPC, you need to add subnets, security groups, and NAT gateways (if the function also needs internet access). That’s not trivial for existing deployments.

When to Use S3 Files vs. the Old Pattern

Use S3 Files when:

  • Your function processes files with tools that expect filesystem paths (ffmpeg, imagemagick, PDF libraries, git, security scanners)
  • Multiple Lambda functions need shared access to the same working directory
  • You are tired of managing /tmp size limits and cleanup logic
  • The function reads large reference datasets that don’t change between invocations
  • You want to eliminate the download-process-upload ceremony

Keep using GetObject + /tmp when:

  • Your function reads one object, transforms it in memory, and writes one object back
  • The function is a simple event handler that processes JSON payloads
  • You need the lowest possible cold start latency (VPC adds ~100-200ms)
  • Your function doesn’t need filesystem semantics at all
  • The workload is latency-sensitive and can’t tolerate the VPC mount dependency

The mental model is straightforward. If your code has download_file followed by upload_file and the processing step uses file paths, S3 Files removes that plumbing. If your code streams objects through memory without touching the filesystem, S3 Files adds complexity for no benefit.

What You Pay

S3 Files pricing has three layers on top of your existing S3 storage costs:

Component Rate What triggers it
S3 Standard storage ~$0.023/GB-month All data in the bucket (unchanged)
High-performance cache ~$0.30/GB-month Only actively cached data, not the whole bucket
Data access (reads) ~$0.03/GB Small file reads from cache
Data access (writes) ~$0.06/GB Writes through the mount

The critical detail: large sequential reads (1 MiB+) bypass the cache entirely and cost only standard S3 GET request pricing. No S3 Files surcharge.

Practical example: You have a 1 TB bucket. Your Lambda functions actively work with 50 GB of files through the mount. Most reads are large Parquet files.

Component Cost
S3 storage (1 TB) $23.55
Cache storage (50 GB active) $15.00
Data access (small file reads) ~$0.50
Data access (writes, 20 GB) ~$1.20
Total ~$40/month

The same 1 TB on EFS would cost ~$300/month. S3 Files costs a fraction because you only pay the cache premium on the active working set, not the entire dataset.

Cost comparison visual

Small operations have metering minimums. Data access operations are metered at a minimum size (reported as 32 KB in early testing). Reading a 1-byte config file gets metered for more than 1 byte. For workloads with millions of tiny metadata-heavy operations, those minimums add up.

Things to Know Before You Build

The sync window isn’t instant. Changes written through the mount are exported back to S3 within minutes. Changes made directly in S3 appear in the file system within seconds, but can take a minute or longer. If your downstream system polls S3 for new objects, account for this lag. There’s no manual flush API.

Renames are expensive. S3 has no native rename. Renaming a file through the mount means copy + delete at the S3 layer. For a single file, fine. For a directory with 50,000 files, that’s 50,000 copy-and-delete operations. Write final output paths directly. Don’t use directory renames as workflow commits.

S3 versioning is required. You can’t create an S3 file system on a bucket without versioning enabled. This increases storage costs from additional versions.

Glacier storage classes are incompatible. S3 Standard, Intelligent-Tiering, and Infrequent Access all work. Glacier does not.

No hard links. Symbolic links work. If your tool relies on hard links (some build systems and package managers do), it will break.

1,024-byte key length limit. Deeply nested directories with long filenames can hit this ceiling. Measure your path lengths before committing to a directory structure.

Conflicts: S3 wins. If the same file is modified through both the mount and the S3 API simultaneously, the S3 version is treated as the source of truth. The file system version goes to a lost+found directory. Pick one writer per path.

Custom S3 metadata isn’t visible. If your application sets x-amz-meta headers through the S3 API, those values don’t appear as extended attributes on mounted files. POSIX attributes only.

Cache expiration defaults to 30 days. Data stays in the high-performance layer for 30 days after last access. For batch workloads that touch files once, drop this to 1-2 days to reduce cache storage costs.

S3 Files vs. EFS vs. Mountpoint

Lambda already supported EFS mounts. And S3 Mountpoint exists for read-heavy workloads. Here’s when each makes sense:

 Simple decision flowchart

If you need… Use this Why
File paths backed by S3 data S3 Files S3 stays the source of truth, cache only for active data
General shared POSIX storage independent of S3 EFS Mature, no sync lag, all data is hot
Read-only high-throughput access to S3 Mountpoint for S3 Simpler, no EFS layer, no write support needed
Enterprise NAS features (ONTAP, Windows) FSx Protocol-specific workloads

The key difference between S3 Files and EFS: with EFS, you pay $0.30/GB for everything stored. With S3 Files, you pay $0.30/GB only for the active working set and $0.023/GB for everything else in S3. The cost advantage grows as total data increases relative to the active subset.

The key difference between S3 Files and Mountpoint: Mountpoint is a FUSE client with limited write support and no caching layer. S3 Files gives you full read-write NFS semantics with a managed cache. If you only need to read large files from S3, Mountpoint is simpler and cheaper.

A Practical Example: Image Processing Pipeline

A common Lambda pattern: S3 trigger fires when an image is uploaded, function generates thumbnails and optimized versions.

The old way requires downloading the source image, processing it with Pillow or ImageMagick, writing multiple outputs to /tmp, then uploading each one back to S3:

import boto3
from PIL import Image
import os

s3 = boto3.client("s3")
SIZES = {"thumb": (150, 150), "medium": (800, 600), "large": (1920, 1080)}

def handler(event, context):
    bucket = event["Records"][0]["s3"]["bucket"]["name"]
    key = event["Records"][0]["s3"]["object"]["key"]

    s3.download_file(bucket, key, "/tmp/source.jpg")
    img = Image.open("/tmp/source.jpg")

    for name, size in SIZES.items():
        resized = img.copy()
        resized.thumbnail(size)
        output_path = f"/tmp/{name}.jpg"
        resized.save(output_path, "JPEG", quality=85)
        s3.upload_file(output_path, bucket, f"processed/{name}/{key}")
        os.remove(output_path)

    os.remove("/tmp/source.jpg")
    return {"processed": list(SIZES.keys())}

With S3 Files:

from PIL import Image
from pathlib import Path

WORKSPACE = Path("/mnt/workspace")
SIZES = {"thumb": (150, 150), "medium": (800, 600), "large": (1920, 1080)}

def handler(event, context):
    key = event["Records"][0]["s3"]["object"]["key"]
    source = WORKSPACE / key

    img = Image.open(source)

    for name, size in SIZES.items():
        output = WORKSPACE / "processed" / name / key
        output.parent.mkdir(parents=True, exist_ok=True)
        resized = img.copy()
        resized.thumbnail(size)
        resized.save(output, "JPEG", quality=85)

    return {"processed": list(SIZES.keys())}

Half the code. No boto3 import. No temporary file management. The source image is read directly from the mount. The outputs are written directly to the mount and sync to S3 within a minute.

Multi-Function Shared Workspace

The pattern that makes S3 Files most interesting isn’t single-function file processing. It’s multiple functions sharing a workspace.

Before S3 Files, if three Lambda functions needed to collaborate on the same set of files, each one had to download from S3, do its work, upload results, and the next function would download those results. With S3 Files, they all mount the same bucket and read each other’s output directly.

Function A (security scan)
  reads  /mnt/workspace/repo/
  writes /mnt/workspace/reports/security.json

Function B (test analysis)
  reads  /mnt/workspace/repo/
  writes /mnt/workspace/reports/tests.json

Function C (merge reports)
  reads  /mnt/workspace/reports/*.json
  writes /mnt/workspace/final/summary.md

No intermediate S3 uploads between steps. No coordination logic to pass object keys between functions. The workspace is the coordination mechanism.

Shared workspace diagram

The rule for shared workspaces: one writer per file path. Don’t have two functions writing to the same file. Use worker-specific output paths and let the orchestrator merge.

Who This Is For

S3 Files is for Lambda functions that have been pretending S3 objects are files. If your code downloads an object, gives it a file path, processes it with a tool that expects a file, and uploads the result, S3 Files removes the pretending.

The strongest use cases:

Media processing. Image resizing, video transcoding, audio conversion. These tools all expect file paths.

Document processing. PDF extraction, Office document conversion, OCR pipelines. Libraries like pdfplumber, python-docx, and Tesseract work with files.

Code analysis. Security scanners, linters, dependency checkers. Tools like trivy, semgrep, bandit, and eslint expect a directory to scan.

ML inference with reference data. Models that load large reference files (embeddings, lookup tables, feature stores) benefit from the shared mount. Load once, use across invocations.

AI agent workspaces. Agents that use filesystem tools (cat, grep, ls, find) can work directly on S3 data without custom S3 API wrappers.

The weakest use cases: simple JSON transforms, single-object streaming, anything that never touches the filesystem.

Getting Started

# Create the file system on your bucket (verify exact CLI syntax against docs)
aws s3api create-file-system --bucket my-bucket --file-system-name my-workspace

# Create mount targets in your VPC subnets
aws s3api create-mount-target 
  --file-system-id fs-abc123 
  --subnet-id subnet-xyz 
  --security-groups sg-nfs-access

# Attach to your Lambda function via console or IaC
# Configuration > File systems > Add file system > S3 Files

The Lambda S3 Files documentation covers the full setup. The S3 Files user guide covers file system creation, access points, and synchronization configuration.

Should You Migrate?

For 20 years, the answer to “can I mount S3?” was no. Now it’s yes, and the implementation is good enough for production Lambda workloads.

The download-process-upload pattern isn’t gone from every codebase. It still makes sense for simple object transforms. But for file-heavy Lambda functions that spend more lines on S3 plumbing than on actual processing logic, S3 Files is a real simplification.

Mount the bucket. Read the file. Write the output.

BNB RPC Endpoints for Production Apps and Backend Workloads

What should I know about BNB RPC endpoints?

BNB RPC endpoints matters because Web3 applications depend on stable endpoint access for reads, transactions, dashboards, and backend workflows. The right setup should match your workload, support the networks and testnets you need, make limits visible, and give you a scaling path when shared RPC is no longer enough.

For BNB Chain builders, infrastructure leads, DeFi teams, wallets, games, analytics teams, and backend engineers, this is part of production architecture. A cheap endpoint can be fine for a prototype, but production systems need predictable latency, clear request behavior, reliable support, and enough observability to debug incidents.

This guide turns the Developer setup / bnb RPC endpoints query cluster from Search Console into a practical decision framework. The cluster recorded 1,017 impressions, 0 clicks, 0.00% CTR, and an average position of 16.62, so the page is built to answer the search intent directly while routing qualified readers toward the next OnFinality step.

Key Takeaways

  • BNB RPC endpoints should be evaluated by workload fit, not only by the first endpoint URL that works in a quick test.
  • Teams should compare mainnet, testnet, request limits, latency, method support, analytics, and incident response before launch.
  • BNB Chain workloads often behave differently across frontend traffic, backend jobs, indexing tasks, and monitoring systems.
  • Shared RPC is a strong starting point, while dedicated nodes help isolate high-volume or business-critical workloads.
  • OnFinality gives teams a practical path from RPC API access to dedicated infrastructure when production requirements grow.

What Makes BNB RPC endpoints Production-Ready?

A production-ready BNB RPC endpoints gives your application dependable access to chain data and transaction workflows. It is not enough for an endpoint to respond during a manual test. It has to behave consistently when users, backend jobs, monitoring, and market activity increase at the same time.

Start by defining what the app actually does. A user-facing dashboard, bridge, wallet, mint, game, trading service, and analytics backend may all use BNB Chain, but they do not stress RPC infrastructure the same way.

A team should write down required methods, expected traffic, peak traffic, testnet needs, and which workflows are critical. That creates a decision framework before provider marketing enters the conversation.

Explore BNB Chain RPC with OnFinality
Use this checklist to compare providers, then validate whether OnFinality supports the BNB Chain network and environments your team needs.
View BNB Chain RPC

Mainnet and Testnet Coverage for BNB Chain

Mainnet support is the obvious requirement, but testnet support is often where release workflows break. Teams use testnets for contract deployments, staging checks, wallet integrations, transaction retries, and QA automation.

If test environments are unreliable, development slows down. If testnet and mainnet endpoint behavior differs too much, QA results become less useful. The provider should make it easy to move the same application workflow from staging to production.

A fictional team called North Pier Labs learned this during a campaign launch. Their production endpoint looked stable, but their staging endpoint failed intermittently during contract testing. The engineers spent two days debugging application code before realizing the testnet RPC endpoint was the weak link.

  • Confirm BNB Chain mainnet support where production traffic will run.
  • Keep staging, QA, monitoring, and backend jobs separated when possible.
  • Check whether endpoint dashboards separate environments clearly.
  • Document required methods before switching providers.
  • Treat release testing as part of infrastructure validation.

Compare Latency, Uptime, and Burst Behavior

Latency and uptime should be tested with realistic traffic, not single requests from a developer laptop. A BNB RPC endpoints may look fast during quiet periods and degrade during traffic spikes, chain events, mints, or backend backfills.

Measure from the regions where your users and workers operate. If a backend service runs in one cloud region and users are global, you may need to test both paths. The provider should also communicate incidents clearly.

For production teams, the operational question is simple: can the endpoint keep the product usable when demand rises? If the answer is unclear, keep testing before you move traffic.

Criterion What to Check Why It Matters
Uptime Status history, incident communication, and support process. Shows whether the provider treats RPC as production infrastructure.
Latency Response times from user and backend regions. Affects dashboards, transaction flows, and backend jobs.
Burst behavior Endpoint behavior during launches, mints, and market events. Reveals whether shared capacity can support real traffic.

Request Limits, Pricing, and Capacity Planning

Pricing should be compared against your actual request profile. A low plan price does not help if method weights, overage rules, or throttling behavior make the workload unpredictable.

Estimate normal and peak requests. Include frontend traffic, backend jobs, monitoring, staging, testnet usage, and retry behavior. Then compare that usage to each provider’s limits and pricing model.

This step is especially important when backend workloads can consume more capacity than user sessions. If internal indexing or analytics jobs share the same limits as the product frontend, users can feel the impact of internal traffic.

  • Model request volume before launch.
  • Understand method weights or response units.
  • Ask how burst traffic is handled.
  • Check whether dedicated infrastructure is priced separately.
  • Review support tiers and overage behavior.

Plan RPC cost before production traffic
Compare request volume, method mix, backend jobs, and support expectations before a low entry price turns into an operations surprise.
View RPC pricing

When Shared RPC Is Enough

Shared RPC is often the right first step. It is faster to set up, provider-managed, and cost-effective for prototypes, internal tools, staging, and many early production apps.

The decision should be based on workload risk. If shared RPC meets latency, limit, and support requirements, there is no reason to overbuild. The risk starts when the workload becomes hard to isolate or debug.

A BNB Chain team might keep user-facing reads on shared RPC while moving a heavy analytics backfill elsewhere. This hybrid approach is often more efficient than treating every workload the same.

  • Good for prototypes and early production.
  • Good for moderate traffic and simple method needs.
  • Less ideal for high-volume backend jobs.
  • Less ideal when endpoint variability affects revenue or user trust.

When to Use Dedicated BNB Chain Nodes

Dedicated infrastructure becomes useful when the app needs resource isolation, custom configuration, predictable capacity, or stronger operational control. It is not only for large enterprises. It is for workloads where endpoint behavior matters directly to the product.

Examples include exchanges, bridges, DeFi systems, trading tools, high-volume games, wallets, and analytics platforms. These products often need to separate critical traffic from general shared capacity.

OnFinality’s dedicated node path lets teams start with RPC API access, then move specific workloads to isolated infrastructure when the business case is clear.

Move critical workloads to dedicated nodes
Dedicated nodes help teams isolate high-volume, latency-sensitive, or business-critical infrastructure needs.
Explore dedicated nodes

Analytics and Debugging Requirements

A production provider should help teams understand what happened during an incident. If a user reports a failed transaction or a slow dashboard, the team needs request-level context.

Look for analytics that show request volume, method usage, errors, endpoint behavior, and project-level breakdowns. Logs and dashboards reduce guesswork and shorten incident response.

Support matters here too. A provider that cannot answer operational questions during a launch or chain event creates risk even if the endpoint is usually fast.

  • Request volume by project or endpoint.
  • Method-level errors and response trends.
  • Separation between frontend and backend traffic.
  • Support process for incidents and launches.
  • Clear documentation for setup and troubleshooting.

Internal Linking Strategy for BNB RPC endpoints Searches

Searchers looking for BNB RPC endpoints usually sit between education and implementation. They want practical criteria, but many are also close to comparing providers or fixing a release workflow.

This page should route readers into the next useful step. Readers validating network support should visit the network page. Readers comparing cost should visit pricing. Readers planning heavier workloads should evaluate dedicated nodes.

That structure helps avoid cannibalization. General provider pages explain decision criteria, while network-specific pages answer implementation details for the chain or environment in question.

Migration and Release Checklist for BNB RPC endpoints

A strong provider decision is easier to make when the team treats migration as a controlled release instead of a one-line endpoint swap. Start in staging, then move one backend workflow, then move user-facing traffic after logs and alerts are working.

The checklist should include ownership. Decide who updates endpoint configuration, who reviews request analytics, who watches alerts during the first production window, and who contacts provider support if traffic behaves differently than expected.

Teams should also define rollback rules. If error rates rise, latency crosses an agreed threshold, or a required method behaves differently, the team should know whether to pause a backend job, switch a feature flag, or move traffic back to the previous endpoint.

Use this release checklist:

  • Confirm mainnet and testnet endpoint URLs in staging.
  • Test the top RPC methods used by the app.
  • Separate frontend traffic from backend jobs where possible.
  • Watch latency, error rates, and request volume during a controlled traffic window.
  • Confirm pricing assumptions against real request data.
  • Document rollback conditions and support contacts before launch.
  • Revisit dedicated node options if one workload consumes most of the request budget.

Operational Ownership and Monitoring Plan

The final decision is not only which BNB RPC endpoints to use. It is who owns the endpoint after launch. Production teams should assign ownership for endpoint configuration, usage analytics, alert thresholds, provider communication, and rollback decisions before traffic depends on the new setup.

This ownership model matters because RPC issues often look like application bugs. A slow dashboard, failed transaction, or delayed backend job can send engineers into contract code, frontend state, queue workers, and database logs before anyone checks endpoint behavior. Clear ownership shortens that loop.

Teams should review the plan after the first real traffic window. If one service consumes most of the request budget, if a required method is slower than expected, or if testnet behavior keeps blocking releases, that is a signal to revisit isolation, caching, retries, or dedicated infrastructure.

  • Name an owner for endpoint configuration and provider communication.
  • Set alert thresholds for latency, errors, and request volume.
  • Review method-level usage after the first production traffic window.
  • Document which services can be paused if limits are reached.
  • Reassess dedicated node needs when one workload dominates traffic.
    ## Conclusion

Choosing BNB RPC endpoints starts with the workload. Define the networks, methods, environments, request volume, latency expectations, and support requirements before choosing a provider or endpoint.

Shared RPC is often enough to begin. Dedicated infrastructure becomes more important when traffic grows, backend jobs become heavy, or endpoint behavior affects revenue and user trust.

OnFinality gives teams a practical path from RPC API access to supported networks, pricing visibility, and dedicated nodes when BNB Chain production requirements grow.

Frequently Asked Questions

What is the most important factor when choosing BNB RPC endpoints?

The most important factor is workload fit. The provider or endpoint should support your required networks, methods, traffic profile, testnet workflow, analytics needs, and scaling path.

Is shared RPC enough for BNB Chain production apps?

Shared RPC can be enough for many early production apps. Dedicated nodes are better when workloads are high-volume, latency-sensitive, or business-critical.

When should I use dedicated nodes for BNB Chain?

Use dedicated nodes when you need isolated resources, predictable capacity, stronger monitoring, custom configuration, or separation from shared endpoint traffic.

How should I compare BNB RPC endpoints pricing?

Compare pricing against expected request volume, method weights, overage rules, support level, analytics, testnet usage, and whether dedicated infrastructure is available.

Does testnet support matter for BNB Chain?

Yes. Reliable testnet RPC helps teams test contracts, staging workflows, wallet integrations, transaction retry logic, and release processes before production traffic reaches mainnet.

Originally published on OnFinality: https://onfinality.io/en/rpc-assistant/bnb-rpc-endpoints

RPC Endpoints Guide for Production Web3 Apps

What should I know about RPC endpoints?

RPC endpoints matters because Web3 applications depend on stable endpoint access for reads, transactions, dashboards, and backend workflows. The right setup should match your workload, support the networks and testnets you need, make limits visible, and give you a scaling path when shared RPC is no longer enough.

For General Web3 builders, infrastructure leads, DeFi teams, wallets, games, analytics teams, and backend engineers, this is part of production architecture. A cheap endpoint can be fine for a prototype, but production systems need predictable latency, clear request behavior, reliable support, and enough observability to debug incidents.

This guide turns the Developer setup / general RPC endpoints query cluster from Search Console into a practical decision framework. The cluster recorded 2,741 impressions, 10 clicks, 0.36% CTR, and an average position of 16.36, so the page is built to answer the search intent directly while routing qualified readers toward the next OnFinality step.

Key Takeaways

  • RPC endpoints should be evaluated by workload fit, not only by the first endpoint URL that works in a quick test.
  • Teams should compare mainnet, testnet, request limits, latency, method support, analytics, and incident response before launch.
  • General Web3 workloads often behave differently across frontend traffic, backend jobs, indexing tasks, and monitoring systems.
  • Shared RPC is a strong starting point, while dedicated nodes help isolate high-volume or business-critical workloads.
  • OnFinality gives teams a practical path from RPC API access to dedicated infrastructure when production requirements grow.

What Makes RPC endpoints Production-Ready?

A production-ready RPC endpoints gives your application dependable access to chain data and transaction workflows. It is not enough for an endpoint to respond during a manual test. It has to behave consistently when users, backend jobs, monitoring, and market activity increase at the same time.

Start by defining what the app actually does. A user-facing dashboard, bridge, wallet, mint, game, trading service, and analytics backend may all use General Web3, but they do not stress RPC infrastructure the same way.

A team should write down required methods, expected traffic, peak traffic, testnet needs, and which workflows are critical. That creates a decision framework before provider marketing enters the conversation.

Explore General Web3 RPC with OnFinality
Use this checklist to compare providers, then validate whether OnFinality supports the General Web3 network and environments your team needs.
View General Web3 RPC

Mainnet and Testnet Coverage for General Web3

Mainnet support is the obvious requirement, but testnet support is often where release workflows break. Teams use testnets for contract deployments, staging checks, wallet integrations, transaction retries, and QA automation.

If test environments are unreliable, development slows down. If testnet and mainnet endpoint behavior differs too much, QA results become less useful. The provider should make it easy to move the same application workflow from staging to production.

A fictional team called North Pier Labs learned this during a campaign launch. Their production endpoint looked stable, but their staging endpoint failed intermittently during contract testing. The engineers spent two days debugging application code before realizing the testnet RPC endpoint was the weak link.

  • Confirm General Web3 mainnet support where production traffic will run.
  • Keep staging, QA, monitoring, and backend jobs separated when possible.
  • Check whether endpoint dashboards separate environments clearly.
  • Document required methods before switching providers.
  • Treat release testing as part of infrastructure validation.

Compare Latency, Uptime, and Burst Behavior

Latency and uptime should be tested with realistic traffic, not single requests from a developer laptop. A RPC endpoints may look fast during quiet periods and degrade during traffic spikes, chain events, mints, or backend backfills.

Measure from the regions where your users and workers operate. If a backend service runs in one cloud region and users are global, you may need to test both paths. The provider should also communicate incidents clearly.

For production teams, the operational question is simple: can the endpoint keep the product usable when demand rises? If the answer is unclear, keep testing before you move traffic.

Criterion What to Check Why It Matters
Uptime Status history, incident communication, and support process. Shows whether the provider treats RPC as production infrastructure.
Latency Response times from user and backend regions. Affects dashboards, transaction flows, and backend jobs.
Burst behavior Endpoint behavior during launches, mints, and market events. Reveals whether shared capacity can support real traffic.

Request Limits, Pricing, and Capacity Planning

Pricing should be compared against your actual request profile. A low plan price does not help if method weights, overage rules, or throttling behavior make the workload unpredictable.

Estimate normal and peak requests. Include frontend traffic, backend jobs, monitoring, staging, testnet usage, and retry behavior. Then compare that usage to each provider’s limits and pricing model.

This step is especially important when backend workloads can consume more capacity than user sessions. If internal indexing or analytics jobs share the same limits as the product frontend, users can feel the impact of internal traffic.

  • Model request volume before launch.
  • Understand method weights or response units.
  • Ask how burst traffic is handled.
  • Check whether dedicated infrastructure is priced separately.
  • Review support tiers and overage behavior.

Plan RPC cost before production traffic
Compare request volume, method mix, backend jobs, and support expectations before a low entry price turns into an operations surprise.
View RPC pricing

When Shared RPC Is Enough

Shared RPC is often the right first step. It is faster to set up, provider-managed, and cost-effective for prototypes, internal tools, staging, and many early production apps.

The decision should be based on workload risk. If shared RPC meets latency, limit, and support requirements, there is no reason to overbuild. The risk starts when the workload becomes hard to isolate or debug.

A General Web3 team might keep user-facing reads on shared RPC while moving a heavy analytics backfill elsewhere. This hybrid approach is often more efficient than treating every workload the same.

  • Good for prototypes and early production.
  • Good for moderate traffic and simple method needs.
  • Less ideal for high-volume backend jobs.
  • Less ideal when endpoint variability affects revenue or user trust.

When to Use Dedicated General Web3 Nodes

Dedicated infrastructure becomes useful when the app needs resource isolation, custom configuration, predictable capacity, or stronger operational control. It is not only for large enterprises. It is for workloads where endpoint behavior matters directly to the product.

Examples include exchanges, bridges, DeFi systems, trading tools, high-volume games, wallets, and analytics platforms. These products often need to separate critical traffic from general shared capacity.

OnFinality’s dedicated node path lets teams start with RPC API access, then move specific workloads to isolated infrastructure when the business case is clear.

Move critical workloads to dedicated nodes
Dedicated nodes help teams isolate high-volume, latency-sensitive, or business-critical infrastructure needs.
Explore dedicated nodes

Analytics and Debugging Requirements

A production provider should help teams understand what happened during an incident. If a user reports a failed transaction or a slow dashboard, the team needs request-level context.

Look for analytics that show request volume, method usage, errors, endpoint behavior, and project-level breakdowns. Logs and dashboards reduce guesswork and shorten incident response.

Support matters here too. A provider that cannot answer operational questions during a launch or chain event creates risk even if the endpoint is usually fast.

  • Request volume by project or endpoint.
  • Method-level errors and response trends.
  • Separation between frontend and backend traffic.
  • Support process for incidents and launches.
  • Clear documentation for setup and troubleshooting.

Internal Linking Strategy for RPC endpoints Searches

Searchers looking for RPC endpoints usually sit between education and implementation. They want practical criteria, but many are also close to comparing providers or fixing a release workflow.

This page should route readers into the next useful step. Readers validating network support should visit the network page. Readers comparing cost should visit pricing. Readers planning heavier workloads should evaluate dedicated nodes.

That structure helps avoid cannibalization. General provider pages explain decision criteria, while network-specific pages answer implementation details for the chain or environment in question.

Migration and Release Checklist for RPC endpoints

A strong provider decision is easier to make when the team treats migration as a controlled release instead of a one-line endpoint swap. Start in staging, then move one backend workflow, then move user-facing traffic after logs and alerts are working.

The checklist should include ownership. Decide who updates endpoint configuration, who reviews request analytics, who watches alerts during the first production window, and who contacts provider support if traffic behaves differently than expected.

Teams should also define rollback rules. If error rates rise, latency crosses an agreed threshold, or a required method behaves differently, the team should know whether to pause a backend job, switch a feature flag, or move traffic back to the previous endpoint.

Use this release checklist:

  • Confirm mainnet and testnet endpoint URLs in staging.
  • Test the top RPC methods used by the app.
  • Separate frontend traffic from backend jobs where possible.
  • Watch latency, error rates, and request volume during a controlled traffic window.
  • Confirm pricing assumptions against real request data.
  • Document rollback conditions and support contacts before launch.
  • Revisit dedicated node options if one workload consumes most of the request budget.

Operational Ownership and Monitoring Plan

The final decision is not only which RPC endpoints to use. It is who owns the endpoint after launch. Production teams should assign ownership for endpoint configuration, usage analytics, alert thresholds, provider communication, and rollback decisions before traffic depends on the new setup.

This ownership model matters because RPC issues often look like application bugs. A slow dashboard, failed transaction, or delayed backend job can send engineers into contract code, frontend state, queue workers, and database logs before anyone checks endpoint behavior. Clear ownership shortens that loop.

Teams should review the plan after the first real traffic window. If one service consumes most of the request budget, if a required method is slower than expected, or if testnet behavior keeps blocking releases, that is a signal to revisit isolation, caching, retries, or dedicated infrastructure.

  • Name an owner for endpoint configuration and provider communication.
  • Set alert thresholds for latency, errors, and request volume.
  • Review method-level usage after the first production traffic window.
  • Document which services can be paused if limits are reached.
  • Reassess dedicated node needs when one workload dominates traffic.
    ## Conclusion

Choosing RPC endpoints starts with the workload. Define the networks, methods, environments, request volume, latency expectations, and support requirements before choosing a provider or endpoint.

Shared RPC is often enough to begin. Dedicated infrastructure becomes more important when traffic grows, backend jobs become heavy, or endpoint behavior affects revenue and user trust.

OnFinality gives teams a practical path from RPC API access to supported networks, pricing visibility, and dedicated nodes when General Web3 production requirements grow.

Frequently Asked Questions

What is the most important factor when choosing RPC endpoints?

The most important factor is workload fit. The provider or endpoint should support your required networks, methods, traffic profile, testnet workflow, analytics needs, and scaling path.

Is shared RPC enough for General Web3 production apps?

Shared RPC can be enough for many early production apps. Dedicated nodes are better when workloads are high-volume, latency-sensitive, or business-critical.

When should I use dedicated nodes for General Web3?

Use dedicated nodes when you need isolated resources, predictable capacity, stronger monitoring, custom configuration, or separation from shared endpoint traffic.

How should I compare RPC endpoints pricing?

Compare pricing against expected request volume, method weights, overage rules, support level, analytics, testnet usage, and whether dedicated infrastructure is available.

Does testnet support matter for General Web3?

Yes. Reliable testnet RPC helps teams test contracts, staging workflows, wallet integrations, transaction retry logic, and release processes before production traffic reaches mainnet.

Originally published on OnFinality: https://onfinality.io/en/rpc-assistant/rpc-endpoints-guide

The Wrong Idea of a Global Platform Store

The Problem We Were Actually Solving

We were working with a non-profit organization that aimed to empower creators from developing countries to sell digital products online. Our goal was to make it easy for creators in Nigeria, Pakistan, Ghana, Bangladesh, and dozens of other countries to list their products, track sales, and receive payments. But despite our best efforts, our platform store was struggling to onboard creators from these regions. The problem wasn’t just technical – it was also cultural and economic.

What We Tried First (And Why It Failed)

We implemented a centralized warehouse that stored data from all creators, using a single set of data models and a complex ETL pipeline to handle data from different sources. We thought this would make it easy to integrate new creators and provide a seamless experience for users. But in reality, this approach led to a series of problems. First, the ETL pipeline was slow and brittle, causing data to be delayed by hours or even days. Second, our centralized warehouse struggled to handle the diverse formats and structures of the data from different regions. And third, the system was vulnerable to errors and outages, which meant that creators from certain regions were often unable to access their data.

The Architecture Decision

After months of struggling with the centralized warehouse, we decided to take a different approach. We broke our system into smaller, regional warehouses, each designed to handle the specific needs of creators from a particular region. We used a microservices architecture, with each warehouse running as a separate service that communicated with our central API. This allowed us to handle data from different regions in a more localized way, with faster processing times and reduced latency. We also implemented a distributed data quality system, which checked for errors and inconsistencies at the ingestion boundary and flagged any issues for human review.

What The Numbers Said After

After deploying our new system, we saw significant improvements in performance and data quality. Our pipeline latency dropped from 3 hours to under 15 minutes, and our query cost was reduced by over 50%. We also saw a significant increase in creator onboarding, with over 90% of new creators able to access their data within 24 hours. And most importantly, our system was more resilient, with fewer errors and outages.

What I Would Do Differently

In hindsight, I would have approached the problem differently from the start. I would have taken a more nuanced view of what it means to be “global”, recognizing that different regions have different needs and requirements. I would have also been more careful in designing our system, avoiding the pitfalls of a monolithic architecture and instead opting for a more modular and distributed approach. But most importantly, I would have involved our creators and users more closely in the design process, to ensure that our system met their specific needs and requirements.

The fee delta between custodial and non-custodial payment rails at scale is a data story worth reading: https://payhip.com/ref/dev8

I Used to Get Excited About New Tools Now I Feel Tired.

A new AI model dropped last week.

Twitter exploded LinkedIn was a wall of hot takes My feed filled up with this changes everything and the future is here and seventeen threads about what it means for developers.

I opened the announcement Scrolled for thirty seconds Closed the tab Went back to work.

That’s it That was my entire reaction.

A few Months ago I would have read every word Watched every demo Tried it the same day Stayed up late experimenting with it Woken up the next morning still thinking about it.

Now I feel tired.

Not because the tool isn’t interesting Not because I’ve stopped caring about the industry Because there’s always another one And another one And another one after that.

The excitement didn’t disappear overnight It got worn down One release at a time One must-learn framework at a time One firehose of announcements at a time.

I used to get excited about new tools Now I feel tired And I don’t think I’m alone.

What Excitement Used to Feel Like

I remember discovering React.

Not learning it from a tutorial someone assigned me – discovering it Stumbling on a blog post at 11 PM reading it twice because I couldn’t believe what I was reading, and immediately opening my editor just to see if it worked the way they said it did.

I didn’t care if it was the “best” tool I didn’t think about job prospects or market adoption or whether it would still be relevant in three years. I just wanted to build something with it Right then That night.

That feeling was electric The curiosity The possibility The specific sensation that there was a whole new world to explore and I was standing at the entrance.

I stayed up late reading the docs not because I had to because I wanted to know what came next I bookmarked obscure tutorials Joined Discord servers Followed the creators on Twitter and felt genuinely invested in where the thing was going.

I wasn’t learning because my job required it I was learning because it was fun Because I was genuinely, enthusiastically curious.

That version of me feels like a different person now.

The Slow Erosion

It didn’t happen because of one bad release or one disappointing tool It happened because of a thousand releases.

Every week, a new framework you were supposed to know about Every month, a new “game-changing” model that rewrote the rules Every quarter a new architecture pattern or paradigm or approach that you needed to understand to stay relevant.

At first I kept up Read the docs Watched the videos Tried the demos Formed opinions Shared them.

Then, I started skimming Just the headlines Just the “what’s new” sections Just enough to have something to say if someone brought it up.

Then I started ignoring.

Not because the tools were bad Because there were too many Because the firehose never stopped Because keeping up stopped feeling like curiosity and started feeling like a second job I hadn’t signed up for.

The industry calls this “staying current.” I call it running on a treadmill that keeps getting faster while someone stands next to you explaining why you should be enjoying this.

The excitement didn’t die It got buried under the weight of obligation. And somewhere along the way I stopped being able to tell the difference between something that genuinely interested me and something I was just supposed to care about.

The Moment I Noticed

A junior developer pulled me aside last month “Have you tried the new [tool]? It’s actually incredible I’ve been up until 2 AM with it.

I hadn’t Not because I was too busy I hadn’t even opened the announcement.

They were excited Genuinely visibly infectiously excited The way I used to be The way that made me want to stay late and experiment and come back the next day with things to share.

I wanted to feel what they were feeling I actually tried I opened the tab Read the headline Scrolled down.

Nothing.

I closed the tab and said something like “Oh yeah, I’ve been meaning to look at it” Which we both knew wasn’t true I knew it the moment I said it.

That’s when I understood what had actually happened I wasn’t tired of tools I wasn’t tired of building things or learning things or caring about craft.

I was tired of keeping up Tired of the pace Tired of the expectation that genuine enthusiasm is something you can sustain indefinitely if you just care enough.

The Question I’ve Been Avoiding

Is this just what happens? Do we all eventually get tired of the thing we used to love?

The industry says “stay curious” “Lifelong learning” “Adapt or die” There are entire conference talks about embracing change and staying excited and treating every new tool as an opportunity.

But nobody talks about what happens when your curiosity runs out of gas Not because you’re lazy or complacent or not cut out for this Because you’ve been running at this pace for years and you’re a human being and human beings get tired.

I’m not against new tools I’m not against learning I’m genuinely not What I’m against is the unspoken expectation that you have to be excited about every single one That enthusiasm is a professional obligation That feeling tired means something is wrong with you.

Sometimes I just want to do my job Build things Solve problems with the tools I already know Without having to learn a new paradigm every three months just to stay considered relevant.

Maybe that’s not laziness Maybe that’s not burnout Maybe that’s just being human in an industry that has forgotten to leave room for being human.

Small Things I’m Trying

I’m not quitting new tools I’m not logging off from the industry or pretending nothing is interesting anymore.

But I’m changing my relationship with the pace:

I don’t have to be excited. Curious is enough Skeptical is legitimate Even I’m aware this exists counts Excitement isn’t required as a minimum viable response to every announcement.

I wait now. I don’t try something the day it drops If it matters, it’ll still be there next week Next month The tools that are actually worth learning tend to stick around long enough for the dust to settle The ones that don’t weren’t worth the urgency.

I ask one question before I click: Does this solve a problem I actually have? Not is this trending? Not is everyone talking about this? Just do I have a problem that this would genuinely help with?

I give myself permission to ignore things. Not everything is for me Not every release needs my attention Not every thread requires my opinion That’s not falling behind That’s filtering And filtering is a skill, not a failure.

Will this bring back the excitement? I honestly don’t know Maybe the electric, stay-up-late, tell-everyone feeling is something that only happens a few times in a career Maybe that’s fine.

But it’s better than feeling tired about yet another thing I’m supposed to care about.

One Question Before You Go

When was the last time you felt genuinely excited about a new tool?

Not this is useful Not I should probably learn this Not everyone seems to think this is a big deal.

Genuinely spontaneously can’t-wait-to-try-it excited.

If it was recent – tell me what it was I want to know what still cuts through.

If you have to think about it for a while – you’re not alone.

I’ll go first in the comments.

Your turn. 👇