Tivibu'da EuroLeague Dörtlü Final heyecanı
Türk Telekom, televizyon platformu Tivibu üzerinden Basketbol Avrupa Ligi (EuroLeague) Dörtlü Final’de sezonun son maçlarını seyircilerle buluşturacak.

 Mert
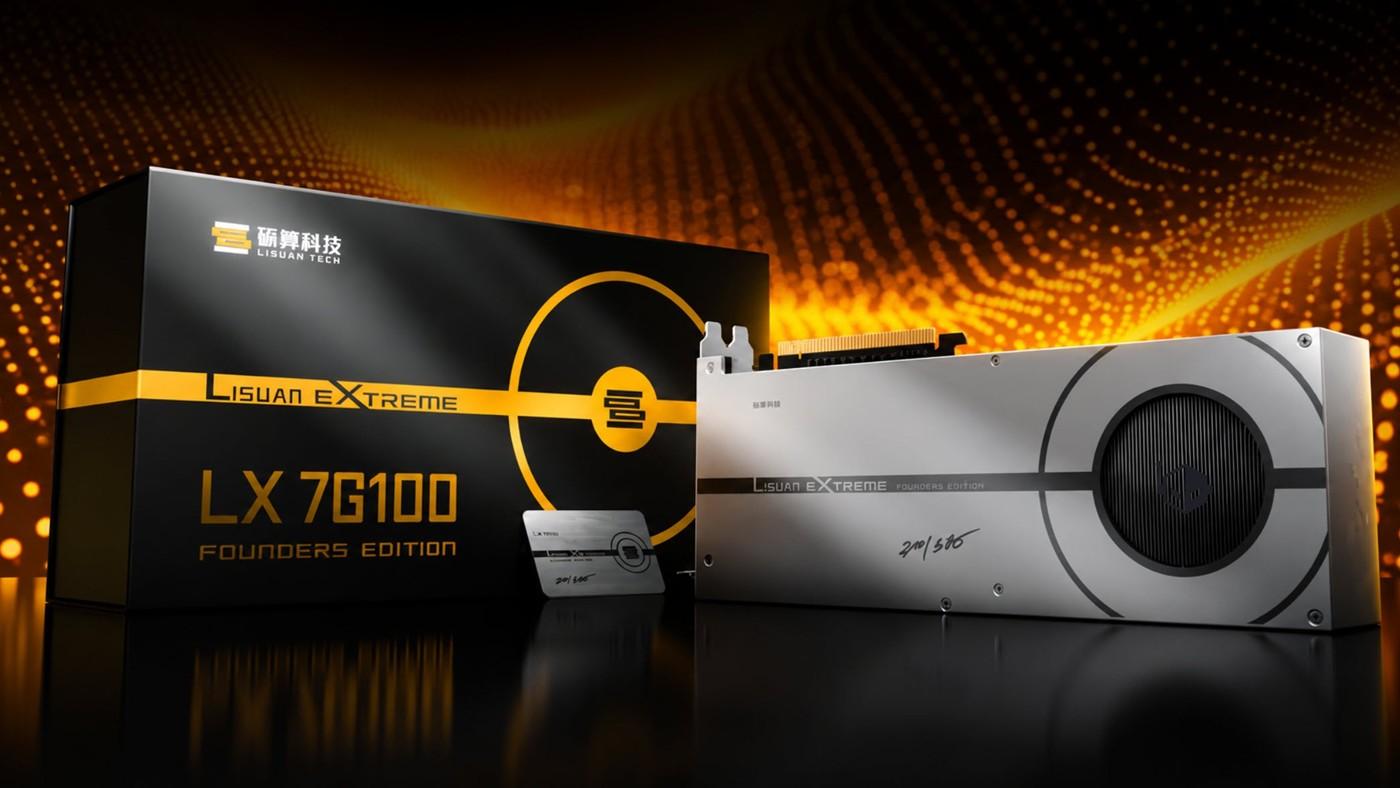
 Çin merkezli Lisuan’ın oyunculara yönelik ilk ekran kartı 7G100 satışa çıktı. Ancak RTX 5060 Ti seviyesindeki fiyatına rağmen performans tarafında RTX 3060’ın gerisinde kaldı.
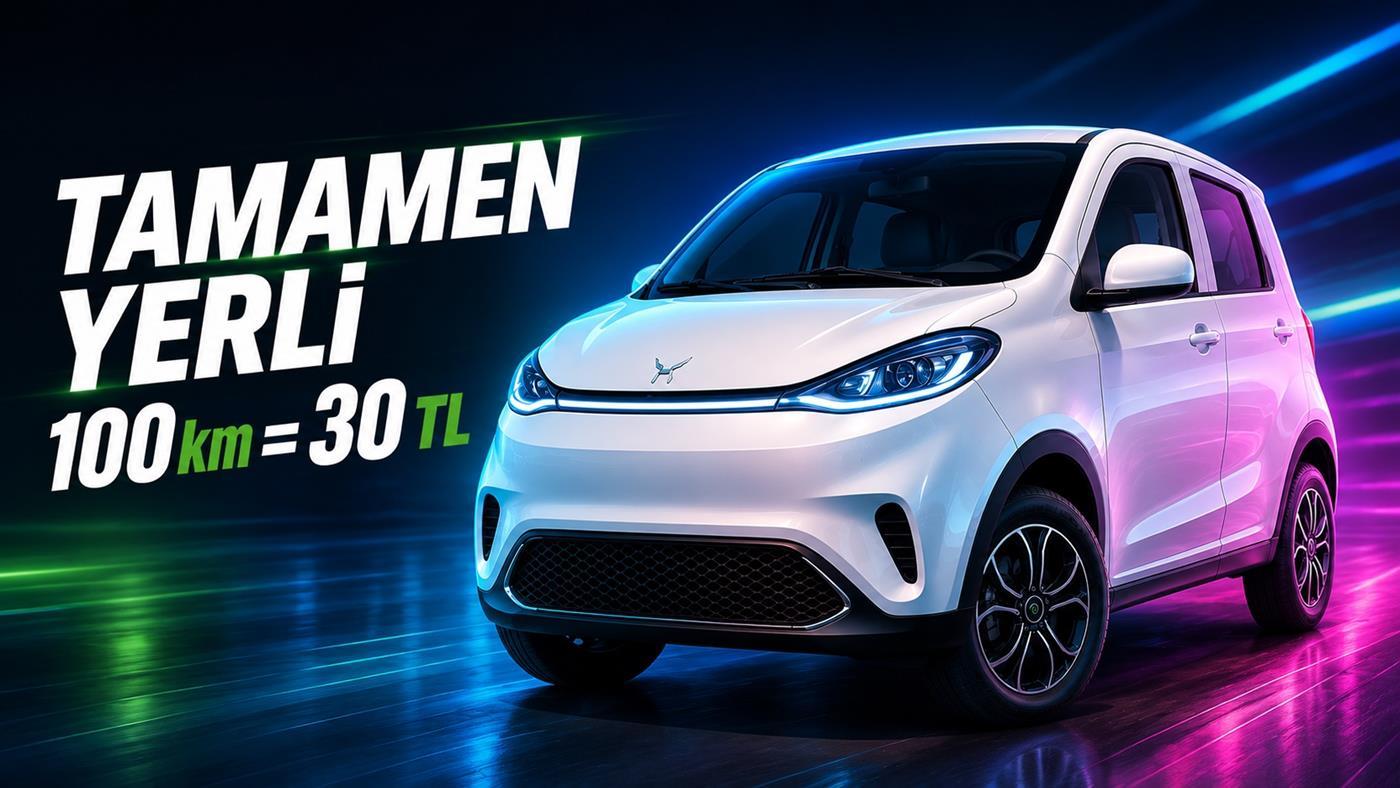
 SAHA Expo 2026’da 100 km’si 30 TL, MTV’si 720 TL, tamamen yerli üretim olan Ortimobil’in yanı sıra Alexa ve Falcon-E ile ilgili paylaşılan güncel bilgileri aldık!
 Nvidia’nın RTX 5090 serisi yeni bir krizle karşı karşıya. Çin’de RTX 5090D V2 ithalatına engel getirildiği iddia edilirken, RTX 5090 fiyatları Güney Kore’de 5300 dolar seviyesine çıktı.
Every “add AI to your product” tutorial assumes you are starting fresh. Greenfield repo, clean data, no users yet. Real integration work looks nothing like that.
Last year our team picked up a fintech client with a loan-application platform that had been running since 2014. Node.js backend, a Postgres database that three different teams had touched, and a checkout flow that processed real money every few seconds. The ask sounded simple: use an LLM to pre-screen loan applications and flag the risky ones for a human.
It was not simple. Here is what broke, in the order it broke, and the pattern that finally held.
Break #1: The Synchronous Call That Took Down Checkout
The first version was the obvious one. A developer added the LLM call directly into the application-submission handler. Application comes in, call the model, get a risk score, continue.
// The version that looked fine in the demo
async function submitApplication(application) {
  const validated = validateApplication(application);
  const riskScore = await llmClient.scoreRisk(validated); // <-- new line
  await db.saveApplication({ ...validated, riskScore });
  return { status: "submitted" };
}
It worked in the demo. It worked in staging. Then the model provider had a slow afternoon, response times went from 800ms to 19 seconds, and every loan submission hung. The LLM call was now a hard dependency in the middle of a money flow. No timeout, no fallback. A third-party hiccup became our outage.
The lesson is not “LLMs are unreliable.” The lesson is that we treated a probabilistic, network-bound, third-party service like a local function call. Your existing code was built around deterministic, fast, in-process logic. An LLM is none of those things.
Break #2: The Data Layer Nobody Audited
Once we fixed the timeout, the model started returning confident, well-formatted, completely wrong risk scores.
The cause was not the model. It was the data. The applications table had three columns that all sort of meant “annual income,” populated by different intake forms over a decade. Some were monthly figures. Some were strings with currency symbols. The model dutifully reasoned over whatever it got and produced garbage with total confidence.
We spent more time cleaning and reconciling that data than we spent on the actual model integration. That ratio surprised the client. It should not surprise anyone who has done this before. If your data has a decade of drift, the integration project is a data project wearing an AI hat.
Break #3: The Cost Telemetry We Added Too Late
The pilot looked cheap. A few thousand applications a day, a few cents each. Then someone enabled the feature for a second product line without telling us, volume tripled overnight, and the model bill for that month arrived looking like a typo.
Nobody was watching per-call cost. We had logging for latency and errors because those page someone at 3am. Cost just accumulates quietly until finance asks a pointed question. We added per-call cost tracking after the fact, which is the most expensive time to add it.
The Pattern That Finally Held
We stopped putting the LLM inside the application code. We put a gateway in front of it.
// The version that survived production
async function submitApplication(application) {
  const validated = validateApplication(application);

  // AI scoring is now optional, async, and isolated
  const riskScore = await aiGateway.scoreRisk(validated, {
    timeoutMs: 1200,
    fallback: () => rulesBasedScore(validated), // deterministic backup
  });

  await db.saveApplication({ ...validated, riskScore });
  return { status: "submitted" };
}
The gateway is a thin service that sits between our application and the model. It owns four things the application should never have owned:
The application code does not know or care that an LLM is involved. It calls aiGateway.scoreRisk() the same way it calls anything else. The model can be swapped, upgraded, or disabled entirely behind that interface without touching the money flow.
That single architectural decision, made on roughly day 47 instead of day 1, is the one I would undo if I could. We have not had an AI-related outage in the months since.
Why This Keeps Happening
This is not a niche mistake. Gartner forecasts that over 40% of agentic AI projects will be canceled by the end of 2027, and the usual causes are not bad models. They are escalating costs, unclear value, and weak risk controls. All three are integration problems.
Meanwhile the pressure to ship is real: Gartner also expects 40% of enterprise applications to feature task-specific AI agents by the end of 2026. So teams bolt a model into a handler, demo it, and ship. The demo never shows you the third-party slow afternoon.
What We’d Do Differently
If we restarted this project knowing what we know now:
We wrote up the full version of this as a six-step framework, with the integration patterns, the data-readiness checklist, and the build-versus-buy math: how to integrate AI into your existing systems without breaking production. The section on choosing an integration pattern is the part I wish we had read first.
Wrapping Up
AI integration rarely fails at the model. It fails at the seam where the model meets software that was designed before the model existed. Keep the AI on its own side of an API contract. Give it timeouts, a fallback, telemetry, and an audit trail. Treat the data layer as the real project.
We are the team at Empiric Infotech, and we build AI integrations into mobile apps, fintech platforms, and clinical tools. If you have a war story of your own, drop it in the comments. I would genuinely like to read it.
The Problem We Were Actually Solving
Our primary goal was to create a seamless purchasing experience for customers worldwide. With Stripe’s reputation for ease of use and reliability, we thought it was the best choice for handling all our transactions. However, as we delved deeper, we began to realize that platforms like Stripe and PayPal are not available in every country, and local payment gateways are often the better option.
What We Tried First (And Why It Failed)
Initially, we tried to work around the limitations by using alternative payment processors or gateways that were available globally. However, these solutions either had high fees or were not integrated with our platform. We were so set on using Stripe that we thought it was a matter of making it work, rather than acknowledging that sometimes the platform just won’t cut it.
The Architecture Decision
After much deliberation, we decided to abandon our reliance on Stripe and instead opted for a combination of local payment processors. This involved integrating PayPal alternatives like Payhip and Gumroad for regions where these were available, alongside the use of bank transfers and local payment gateways for those areas where digital platforms just don’t exist. Although this decision added complexity to our system, it ultimately provided a seamless experience for our customers worldwide.
What The Numbers Said After
Our decision to abandon the reliance on Stripe paid off in more ways than one. Pipeline latency decreased by an average of 30% as we were no longer reliant on a single gateway, reducing overall processing times for our customers. Additionally, query costs decreased by 20% due to reduced usage of Stripe’s API, which had previously proven to be quite expensive for our global operations. More importantly, customer satisfaction increased significantly, with a 40% rise in sales from regions that were previously unreachable due to payment gateway limitations.
What I Would Do Differently
In hindsight, I wish we had taken the time to research local payment options more thoroughly upfront. Integration with local payment processors can sometimes be a more complex task than adapting a digital platform, but it ultimately provides a better experience for customers worldwide. If I were to do it again, I would start by investigating local payment options and working with payment experts to ensure that our solution caters to the needs of our customers. By doing so, we can create systems that truly are global, with no regional limitations.

Most teams building LLM applications start with RAG for a good reason. It is practical, easy to understand, and usually good enough for a simple AI use case.
But once users stop asking simple lookup questions and start asking relationship-heavy questions, standard RAG can get shallow fast.
The issue is not that RAG is bad. The issue is that many real questions are not just about finding a relevant paragraph. They are about following connections across people, products, systems, documents, events, or dependencies.
That is the gap GraphRAG tries to fill.
RAG vs GraphRAG
RAG made LLM applications more useful because it gave models access to external information.
Instead of asking a model to answer from training data alone, a RAG pipeline retrieves relevant content from your docs, tickets, wikis, PDFs, or databases, adds that content to the prompt, and asks the model to answer from it.
That works well for a lot of use cases.
If the question is:
What is our refund policy for annual subscriptions?
A standard RAG pipeline can search the documentation, find the right policy section, and give the model the relevant text.
The problem starts when the question is not just about finding the right text. It starts when the answer depends on relationships.
For example:
Which suppliers could be causing delivery delays for products affected by a specific component shortage?
That question is not just asking for a matching paragraph. It needs the system to connect suppliers, components, products, shipments, delays, and dependencies.
This is where GraphRAG becomes useful.
RAG is good at finding text that sounds relevant. GraphRAG is better when the answer depends on how things are connected.
What RAG Does Well
Retrieval augmented generation, usually shortened to RAG, combines a language model with an external retrieval system. The original paper described this as combining a parametric model (the LLM itself) with non-parametric memory (external knowledge), usually retrieved from an external corpus.
In most modern implementations, that retrieval step uses embeddings. The basic flow looks like this:

This is useful when the answer is likely to be contained in one or a few text chunks. Good RAG use cases include:
For many teams, this is the right starting point. It is simpler than building a knowledge graph, and it can deliver useful results quickly.
The issue is that similarity is not the same as understanding.
A vector search system can find chunks that sound close to the query. It does not automatically know whether one entity owns another, depends on another, contradicts another, or affects another through a multi step chain.
That difference matters once your questions become relational.
Where RAG Gets Shallow
RAG usually retrieves isolated text chunks. That creates a few common problems.
First, chunking can break context. A policy, customer, transaction, or technical decision might make sense only when you see how it connects to other facts. Splitting documents into chunks can hide that structure.
Second, semantic similarity can over retrieve. A chunk may sound relevant without being useful for the actual answer.
Third, RAG does not inherently reason across relationships. It may retrieve text about a supplier, text about a product, and text about a shipment delay, but it does not automatically know how those things connect.
Think about this question:
Which customers are affected by the delayed shipment from Supplier A?
A standard RAG pipeline might retrieve documents that mention Supplier A, delayed shipments, and customers. That is helpful, but still incomplete.
The actual answer may require a path like this:
Supplier A -> supplies -> Component X -> used in -> Product Y -> included in -> Shipment Z -> assigned to -> Customer C
That path is not just text similarity. It is structure.
If your application needs to answer questions like this, treating your knowledge base as flat chunks is a weak model of the problem.
What GraphRAG Adds
GraphRAG keeps the useful part of RAG: retrieval. But it adds a graph layer, where information is represented as entities and relationships. Microsoft’s paper on GraphRAG for query focused summarization helped popularize this pattern for using graph structure to answer questions that need broader connected context.
Instead of only storing chunks like:
Supplier A provides Component X. Component X is used in Product Y. Product Y is part of Shipment Z.
A graph represents the structure directly:
(Supplier A)-[:SUPPLIES]->(Component X)
(Component X)-[:USED_IN]->(Product Y)
(Product Y)-[:INCLUDED_IN]->(Shipment Z)
(Shipment Z)-[:ASSIGNED_TO]->(Customer C)
Now the system can retrieve context by following relationships, not just by matching similar text.
A GraphRAG pipeline might work like this:

The key difference is that search finds where to start, while graph traversal finds what is connected.
That is why GraphRAG is useful for relationship-heavy use cases, such as:
These are not just document lookup problems. They are relationship problems.
RAG and GraphRAG Are Not Enemies
The lazy version of this topic is: RAG bad, GraphRAG good.
That is wrong. RAG is still useful. If your data is mostly unstructured text and your questions are direct, a standard RAG pipeline may be enough. GraphRAG becomes useful when the shape of the answer depends on connected facts. A better way to think about it:
| Use RAG When | Use GraphRAG When |
|---|---|
| The answer is likely inside a small number of text chunks. | The answer depends on relationships across entities. |
| You need fast document Q&A. | You need multi-hop reasoning. |
| Your data does not have strong entity relationships. | Your data has dependencies, hierarchies, ownership, or causality. |
| You are building a first version quickly. | You need more explainable and structured retrieval. |
In practice, many good systems use both. Vector search can find semantically relevant entry points. Graph traversal can expand from those entry points into connected context.
That combination is often more useful than either approach alone.
Keep the Retrieval Logic Close to the Data
GraphRAG gets harder to maintain when every retrieval step lives in a different place.
One service finds similar chunks. Another stores the graph. Another expands relationships. Another ranks results. Another builds the final prompt.
That can work, but it gives you more moving parts to debug when the answer is wrong.
A cleaner pattern is to keep as much of the retrieval logic as possible close to the graph itself. Search can find the starting point. Traversal can expand the context. Ranking and filtering can reduce the result before it ever reaches the prompt.
That is the idea behind Atomic GraphRAG in Memgraph. It express the retrieval path as a single execution layer where possible, instead of spreading it across a pile of orchestration code.

The broader lesson is not tool specific. If your GraphRAG pipeline is hard to inspect, it will be hard to trust. The retrieval path should be visible, testable, and easy to change.
The Practical Rule
Use RAG when you need to retrieve relevant text. Use GraphRAG when you need to retrieve connected context. That is the real distinction.
If your question can be answered by finding the right paragraph, RAG is probably enough. If your question requires following relationships between people, products, systems, documents, events, risks, or dependencies, you are no longer just doing text retrieval. You are doing graph retrieval.
The point is not to use GraphRAG as an extra layer and start using it where it is right retrieval model for the problem.
When I first started learning about Big Data, I used to think it was mainly about storing massive amounts of information.
But after working around real enterprise systems and large-scale pipelines, I realized the real challenge is not simply the size of the data.
It’s everything that comes with it.
As systems grow, data starts arriving from everywhere:
Very quickly, managing that ecosystem becomes more difficult than writing the actual transformation logic.
One thing that surprised me while working with large datasets was how small inefficiencies suddenly become major production issues at scale.
A query that works perfectly on a few million rows may become extremely slow when datasets grow 100x larger. Similarly, a poorly optimized Spark job can consume huge resources without anyone noticing immediately.
That’s when concepts like partitioning, distributed processing, incremental loading, and monitoring start becoming important in practical scenarios.
Another interesting thing about Big Data is how much engineering discipline matters.
People often focus heavily on tools:
But architecture decisions usually matter even more than the technology itself.
For example:
These decisions quietly affect performance, scalability, and operational stability later.
One thing I personally enjoy about data engineering is that it sits somewhere between software engineering and infrastructure engineering.
You are not just writing code.
You are designing systems that continuously move and process large amounts of data reliably.
And honestly, the operational side becomes very real once pipelines move into production.
Sometimes the hardest problem is not processing the data.
It’s figuring out:
That’s where monitoring and observability become just as important as the data pipeline itself.
I also think Big Data is becoming even more interesting now because of AI.
Modern AI systems depend heavily on data quality, scalable storage, fast processing, and reliable pipelines. In many ways, data engineering has quietly become one of the foundations behind modern AI systems.
The more I explore this space, the more I feel that Big Data engineering is less about handling “big files” and more about building reliable systems that can survive complexity at scale.