Why I built a post-quantum signing API (and why JWT is on borrowed time)

JWT with RS256/ES256 is everywhere. It’s also going to be broken.

Not today. But the clock is ticking — and the timeline is shorter than most developers think.

The problem with classical signatures

Every JWT signed with RS256 or ES256 relies on RSA or ECDSA. These algorithms are vulnerable to Shor’s algorithm running on a sufficiently powerful quantum computer. NIST finalized the post-quantum replacements in August 2024 — but most developers haven’t started migrating yet.

The threat isn’t just future decryption. Nation-state actors are already harvesting signed traffic today to decrypt and forge once quantum computers arrive. “Harvest now, decrypt later” is a real attack pattern.

What I built

I built FIPSign — a signing API built on ML-DSA-65 (NIST FIPS 204). The idea is simple: you call /sign with any payload, get back a quantum-resistant token. No infrastructure to manage, no keys to generate or rotate, no DevOps.

const { token } = await pq.sign({
  sub: 'user_123',
  role: 'admin',
  expiresInSeconds: 3600,
})

const { valid, payload } = await pq.verify(token)

Not just for auth

Most post-quantum signing tools focus only on user authentication. FIPSign lets you sign anything — the only required field is sub, any string identifying the entity:

  • sub: "user_123" — user sessions
  • sub: "order_456" — payment intents
  • sub: "doc_789" — document certification
  • sub: "device_iot_001" — IoT firmware

How revocation works

Revocation is built in. When you revoke a token, we store a SHA-256 hash of the ML-DSA-65 signature as a blacklist entry in Cloudflare D1. Every remote /verify call checks that blacklist. Entries expire automatically when the original token would have expired.

Local verification (localVerify: true) runs entirely in memory at ~1ms with no API call — but doesn’t check revocation. Use remote verification for payments and admin actions.

The pricing model

No monthly subscriptions. 10,000 free tokens/month that reset automatically. Each sign, verify, or revoke costs 1 token. For most projects, 10,000 tokens/month is enough to never pay anything. If you need more, token packs never expire and accumulate across purchases.

Why ML-DSA-65 specifically?

ML-DSA-65 is NIST security level 3 — the right balance between security and signature size for API use cases. ML-DSA-44 is faster but lower security. ML-DSA-87 produces larger signatures with no practical benefit for most applications.

The implementation uses @noble/post-quantum — a widely audited library you can verify independently.

Try it

npm install fipsign-sdk

Full guide at fipsign.dev/guide. Free account at app.fipsign.dev — no credit card.

Happy to answer any questions about the cryptography, the architecture, or the migration path from JWT.

Weekend Thought: Frontend Build Tools Suffer From Work Amnesia

A lot of frontend tooling discussions focus on speed.

Faster startup.

Faster HMR.

Faster builds.

Those things matter — but at scale, they aren’t where most of the cost comes from.

The real problem shows up as work amnesia.

Most build tools treat every run as a fresh start:

  • dependency graphs are rediscovered

  • transformations are repeated

  • valid work is forgotten

That behaviour was fine when frontend apps were small and isolated.

In 2026, frontend applications are:

  • long‑lived

  • graph‑based

  • shared across teams

  • rebuilt continuously in CI

At that point, forgetting becomes expensive.

Build systems stop being scripts and start behaving like systems — whether we design them that way or not.

The next step for frontend tooling isn’t just running faster.

It’s remembering what’s already valid and reacting only to real change.

That’s the problem space Ionify exists in.

Not as another tool —
but as a build intelligence engine that treats frontend builds as systems with memory.

Curious how others here think about build tools once projects grow past “single app” scale.

Şut çekme konusunda çok yetenekli bir insansı robot hazırlandı [Video]

insansı robot

insansı robotÇin merkezli robot üreticilerinden Booster Robotics, şut çekme konusunda oldukça yetenekli bir insansı robot hazırladı. X’te “T2 Soccer” adıyla paylaşılan ve eylül teslimatı için ön siparişe açıldığı aktarılan robot, birçok benzer seçenekten çok daha etkili vuruşlar gerçekleştirebililiyor olmasıyla dikkat çekiyor. Henüz çok fazla detayın paylaşılmadığı robot, Çinli şirketlerin alanda ulaştığı son seviyeyi gösteren önemli bir örnek daha olmuş durumda. T2 Soccer. We literally got a hole at the ceiling of our lab from this. pic.twitter.com/c9jTe42pTW — Eren Chen (@ErenChenAI) May 22, 2026

Şut çekme konusunda çok yetenekli bir insansı robot hazırlandı [Video] yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

A 10-Line Playwright Trick That Saved Me Hours on Every Sephora Run

Fig. 1 — Page weight before vs after the block list. Same DOM, less network.

Most Playwright tutorials teach you to scrape a single page. Real scrapers need to scrape thousands. The thing that kills you isn’t the selector — it’s everything Playwright does before it touches the selector.

By default, Playwright loads a page like a human visiting a website. It downloads CSS, fonts, analytics scripts, A/B testing pixels, hero images, lazy-loaded carousels, and three different chat widgets. On a product catalog page, that’s 4–6 MB of stuff you don’t need. Times 10,000 pages, that’s the difference between a 20-minute run and a 3-hour run.

Here’s the 10-line route handler I drop into every actor:

const BLOCKED = ['image', 'media', 'font', 'stylesheet'];

await context.route('**/*', (route) => {
  const type = route.request().resourceType();
  const url  = route.request().url();
  if (BLOCKED.includes(type)) return route.abort();
  if (/google-analytics|doubleclick|hotjar|segment|gtm/.test(url)) {
    return route.abort();
  }
  route.continue();
});

That’s it. Two lists: resource types you don’t need, and tracking domains you definitely don’t need.

The 3-item checklist before you ship this

  1. Test that your data is still there. Some sites lazy-load product info into image data- attributes. Aborting images can sometimes break extraction. Run with and without the route handler and diff the output.
  2. Don’t block scripts. Modern sites build the DOM with JS. Aborting scripts will give you an empty page. (CSS and fonts are safe — Playwright doesn’t need them to find selectors.)
  3. Watch for sites that detect this. Some bot-detection scripts check whether you fetched the analytics pixel. If your success rate drops after enabling this, allow the analytics domains back through.

Fig. 1 — Page weight before vs after the block list. Same DOM, less network.

Quick case

On our Sephora product info actor, this single change cut average page load from 4.8s to 1.3s. Across a 5000-product catalog scrape, that’s the difference between 6.5 hours and 1.8 hours. Same selectors, same data, same success rate. We just stopped downloading hero images of moisturizers we never look at.

It also dropped our Apify compute units per run by ~60%, which directly affects what we charge customers. Faster scraper, lower cost, same output. The route handler now ships with the Sephora product info actor and every new scraper after it.

The CTA you didn’t ask for

This route handler ships with our starter actor template. New scrapers get it on day one. Old scrapers got it bolted on the first time we noticed runtime > 1 hour.

The pattern works on any browser-based scraper — Playwright, Puppeteer, Selenium with CDP. The shape is always: tell the browser what not to load, before you tell it what to find.

One quick note for the JS-heavy among you: the same pattern applies to Puppeteer’s page.setRequestInterception(true) — same idea, slightly different API. Same wins.

Drop your slowest scraper’s runtime in the comments. I’ll guess what’s eating your minutes. (Hint: it’s probably hero images.)

Agree, disagree, or have a site where blocking images breaks something subtle? Reply.

Written by **Nova Chen, Automation Dev Advocate at SIÁN Agency. Find more from Nova on dev.to. For custom scraping or automation work, hire SIÁN Agency.

AI Is Changing Engineering Culture More Than We Realize

Late-night developer workspace with VS Code, terminal windows, and AI assistant panels open

“A grounded look at the technical and psychological realities of modern AI tooling.”

When ChatGPT became mainstream in 2022, most developers had the same reaction:

“This changes everything.”

And honestly, it did.

For the first time, developers could:

  • generate boilerplate instantly
  • debug faster
  • learn unfamiliar stacks quickly
  • prototype products in hours instead of weeks
  • reduce repetitive engineering work dramatically

Then the ecosystem exploded.

Suddenly there was:

  • Claude for deep reasoning and coding
  • Gemini integrated into developer workflows
  • Grok entering the ecosystem
  • autonomous coding agents
  • AI IDEs
  • AI copilots
  • AI PR reviewers
  • AI DevOps assistants
  • browser agents
  • AI-generated full-stack applications

Now every week another “AI-powered developer tool” launches.

But after working with these systems continuously, I think the bigger story is no longer about model capability.

It is about engineering culture.

Because AI is not just changing how developers build.

It is slowly changing how developers think.

Late-night developer workspace with VS Code, terminal windows, and AI assistant panels open

The Shift From “AI Assistance” To “AI Participation”

The first phase of developer AI tools felt balanced.

Developers still:

  • designed architecture
  • reasoned through systems
  • debugged deeply
  • read documentation
  • structured applications manually

AI mostly accelerated implementation.

It handled:

  • repetitive code
  • syntax generation
  • explanations
  • small debugging tasks
  • documentation assistance

The human was still clearly driving the system.

But now the ecosystem is moving toward something very different:

agentic workflows.

And this changes the relationship entirely.

Modern AI systems can now:

  • generate entire applications
  • refactor large codebases
  • operate terminals
  • execute deployment workflows
  • connect APIs
  • browse documentation autonomously
  • generate UI systems
  • run multi-step engineering tasks

That is no longer autocomplete.

That is partial delegation of engineering itself.

And honestly, this is where things become psychologically interesting.

Because the question is no longer:

“Can AI generate code?”

The question is:

“How much engineering participation are developers slowly giving away?”

Prompt Engineering Quietly Became A New Layer Of Development

One thing many non-developers miss is that different models behave very differently in real workflows.

For example:

  • ChatGPT is often more forgiving with vague prompts
  • Claude tends to perform better with structured reasoning and larger contexts
  • Gemini sometimes benefits from more explicit formatting and workflow clarity

That means prompting itself has quietly become an engineering layer.

Not just “asking questions.”

But:

  • context design
  • instruction structuring
  • constraint management
  • workflow orchestration
  • output steering

A surprising amount of modern development is now:

engineering the AI interaction layer.

Which creates another strange shift:
developers increasingly optimize communication with models instead of directly interacting with systems themselves.

That is a fascinating cultural transition.

Structured AI prompts alongside generated code and architecture outputs on dual monitors

Most AI Tools Depend On The Same Few Foundations

One observation that keeps standing out to me:

There are now hundreds of thousands of AI tools.

But underneath them, only a very small number of foundational models are powering most of the ecosystem.

A huge percentage of AI products still rely on infrastructure from:

  • OpenAI
  • Anthropic
  • Google
  • xAI
  • and a few others

Which means many startups are not building intelligence itself.

They are building:

  • orchestration layers
  • UI systems
  • wrappers
  • workflow pipelines
  • integrations
  • automation systems

on top of centralized model providers.

That does not make these products useless.

But it changes the economics of the ecosystem.

Because intelligence itself is becoming infrastructure.

And infrastructure naturally centralizes.

The current AI ecosystem sometimes feels less like the early internet and more like cloud computing:

  • a small number of providers
  • massive compute concentration
  • expensive infrastructure barriers
  • ecosystem dependency

AI Infrastructure Is Brutally Expensive

A lot of AI conversations online still feel disconnected from infrastructure reality.

Training and serving modern models is extremely expensive.

Not abstractly expensive.

Physically expensive.

The ecosystem depends on:

  • GPU clusters
  • high-bandwidth memory
  • inference scaling
  • distributed systems
  • energy consumption
  • networking infrastructure
  • storage pipelines
  • cooling systems

Even inference itself becomes expensive at scale.

Which is why:

  • API pricing matters
  • token optimization matters
  • context window management matters
  • caching matters
  • latency matters

As models become larger and more capable, infrastructure pressure increases everywhere.

We are already seeing:

  • GPU shortages
  • premium pricing tiers
  • expensive enterprise plans
  • subscription fragmentation
  • increasing inference costs

The AI ecosystem currently behaves less like traditional software and more like industrial infrastructure.

That changes how sustainable rapid scaling actually is.

Server racks and networking infrastructure powering large-scale AI systems

Instant Development Culture Has Side Effects

One of the biggest changes I’ve noticed among developers is how quickly the culture around learning is changing.

Earlier:

  • developers learned frameworks deeply
  • debugging built intuition
  • architecture mistakes taught system thinking
  • documentation reading was normal
  • implementation friction created understanding

Now increasingly:

  • developers generate first and understand later
  • projects are scaffolded almost instantly
  • architecture is delegated to AI suggestions
  • debugging becomes “paste error into model”
  • exploration is replaced by generation

Again, this is not entirely bad.

AI genuinely increases productivity.

But there is a tradeoff emerging:

speed is increasing faster than understanding.

And that gap matters more than people realize.

Because engineering is not only about output.

It is also about:

  • mental models
  • system intuition
  • debugging instincts
  • architecture reasoning
  • understanding failure modes

If developers stop engaging deeply with systems, engineering culture itself changes.

Not immediately.

Gradually.

Quietly.

AI Agents May Reshape Junior Engineering Completely

This is one area where I think the industry still has unresolved questions.

Junior developers traditionally learned through:

  • repetition
  • debugging
  • small feature work
  • fixing mistakes
  • navigating large codebases manually

But agentic AI systems are increasingly automating exactly those layers.

Which creates a strange future possibility:

  • senior engineers supervising AI systems
  • fewer traditional entry-level pathways
  • reduced apprenticeship-style learning
  • compressed engineering ladders

The issue is not whether AI can generate code.

It clearly can.

The issue is:

how future developers build deep intuition if participation itself keeps shrinking.

Because engineering maturity usually comes from prolonged interaction with complexity.

And complexity is increasingly being abstracted away.

Junior developer reviewing rapidly generated AI code on multiple screens

The Economic Layer Feels Strange Too

There is also an economic contradiction inside the AI boom that feels under-discussed.

Most companies want:

  • fewer operational costs
  • faster iteration
  • reduced labor dependency
  • more automation

That logic makes sense individually.

But collectively, there is a difficult question underneath it:

If AI systems reduce large portions of knowledge work over time…

Who becomes the customer?

Who pays for:

  • subscriptions
  • SaaS products
  • enterprise software
  • APIs
  • cloud infrastructure

Technology ecosystems still depend on humans participating economically.

Which makes the current “replace as much labor as possible” mindset feel unstable long-term.

Especially when advanced AI access itself is becoming increasingly premium.

AI Is Useful. But Dependency Feels Different.

I still think AI is one of the most useful technologies developers have received in years.

It helps with:

  • rapid learning
  • prototyping
  • reducing repetitive work
  • understanding unfamiliar systems
  • accelerating experimentation

I use these systems constantly.

Most developers probably do now.

But I also think there is a meaningful difference between:

  • AI-assisted engineering
    and
  • AI-dependent engineering

That line matters.

Because once developers stop understanding the systems underneath the output, the role slowly changes from:

engineer

to:

operator.

And maybe that is the deeper shift happening right now.

Not just automation of work.

But gradual outsourcing of engineering cognition itself.

The Real Long-Term Risk May Not Be AI. It May Be Reduced Participation.

A lot of AI discussions focus on:

  • AGI
  • model intelligence
  • automation timelines
  • existential risk

But honestly, I think a quieter issue may arrive much earlier.

Convenience changes behavior.

And AI is becoming the most powerful convenience layer software has ever introduced.

The risk may not be that machines become too intelligent.

The risk may be that humans slowly stop engaging deeply with difficult thinking because instant generation becomes easier than understanding.

That applies to:

  • coding
  • writing
  • research
  • design
  • analysis
  • decision-making

And maybe the long-term divide in tech will not be:

developers vs AI

But:

developers who still understand systems deeply
versus
developers who only orchestrate outputs.

That feels like a much more realistic future.

Minimal terminal workspace with handwritten architecture notes beside a keyboard

Maybe AI Should Stay A Tool

I don’t think the solution is rejecting AI.

That would be unrealistic.

AI is already embedded deeply into engineering workflows.

But maybe the goal should not be:

removing humans from engineering completely.

Maybe the goal should be:

reducing friction while preserving understanding.

Because engineering is not just about shipping outputs.

It is about:

  • reasoning
  • systems thinking
  • tradeoff analysis
  • debugging intuition
  • learning through complexity

Those things still matter.

Even if generation becomes instant.

And maybe that is the real question developers should keep asking themselves in this AI era:

“Am I using AI to think better…
or slowly replacing my participation entirely?”

What’s your take? Are you using the free tiers for production code, or stick to local models? Let’s discuss in the comments.

Disclaimer The content of this blog is based on personal experience and my thoughts and thinking. Each individual’s insights may differ based on personal analysis.

Everyone Was Focused on Gemini, But Infinite Scaler Was the Real Twister

Infinite Scaler at Google I/O 2026

Most people left Google I/O 2026 talking about Gemini.

Reasonable.

There were bigger models, better agents, deeper integrations, more autonomous workflows, and enough AI announcements to overload an entire industry for months.

Infinite Scaler at Google I/O 2026

But the demo I kept thinking about afterward wasn’t the flagship keynote reveal.

It was a weird little browser game called Infinite Scaler.

And honestly, I think it quietly revealed something important about where interactive software is heading next.

At First Glance, It Looked Like a Throwaway Demo

Infinite Scaler at Google I/O 2026

The concept sounded almost silly.

A multiplayer climbing game.
Players bounce upward through randomly generated worlds.
Every level is created from prompts submitted live by users.

That’s it.

During the demo, creators Valkyrae and CourageJD generated things like:

  • cyberpunk cities
  • capybaras
  • spaghetti slides
  • disco snails
  • ships in bottles
  • pets
  • floating burgers
  • animals with sweaters

Infinite Scalar at Google I/O 2026

The environments were generated dynamically through Gemini-powered pipelines while thousands of people played simultaneously. :contentReference[oaicite:0]{index=0}

On the surface, it looked like:

“Haha look, AI-generated game worlds.”

But I think the deeper implication was much more important than the demo itself.

Infinite Scaler Wasn’t Really a Game Demo

It was a prototype for generative interaction systems.

That’s the part I don’t think enough people noticed.

Traditionally, games are built around:

  • predefined assets
  • handcrafted environments
  • static mechanics
  • finite content pipelines

Even procedural generation usually operates within tightly constrained systems.

Minecraft seeds.
Roguelike maps.
No Man’s Sky terrain generation.

Still algorithmic.
Still bounded.

Infinite Scaler felt different.

Because the generation layer wasn’t only procedural.

It was conversational.

Language Became the Level Editor

That changes everything.

The game wasn’t asking players to:

  • pick a map
  • choose a biome
  • customize presets
  • browse assets

Infinite Scaler at Google I/O 2026

Instead, users described imagination directly.

A player types:

“a jellyfish DJ underwater rave”

The system interprets:

  • semantic meaning
  • style
  • objects
  • composition
  • visual depth
  • thematic relationships

Then generates a playable environment around it in real time.

That’s not traditional game interaction anymore.

That’s intent-driven generation.

And honestly, I think this is one of the clearest examples yet of AI changing interfaces at the infrastructure level instead of the feature level.

The Most Important Part Wasn’t the Graphics

It was the speed.

This entire loop happened:

  • inside a browser
  • at scale
  • multiplayer
  • with thousands of concurrent participants
  • while generating entirely new content continuously

That’s technically insane.

Especially because the pipeline wasn’t simple image generation.

According to the demo:

  • prompts were refined through Gemini
  • assets were generated
  • depth maps were created
  • sprite layers were separated
  • pseudo-3D environments were assembled dynamically :contentReference[oaicite:1]{index=1}

All while users kept playing.

That’s not just an AI gimmick.

That’s a real-time generative rendering pipeline operating interactively.

And I honestly think this matters more than most flashy model benchmark announcements.

This Changes the Relationship Between Players and Games

Historically, games are experiences developers create for players.

Infinite Scaler blurred that boundary.

Players became:

  • participants
  • co-creators
  • world designers
  • prompt engineers
  • interaction drivers

The gameplay loop wasn’t only movement.

It was imagination itself.

That creates a fundamentally different creative dynamic.

And weirdly, this feels closer to:

  • Roblox
  • Minecraft
  • VRChat
  • modding communities
  • meme culture
  • TikTok creativity loops

than traditional AAA game design.

The game becomes a platform for generative expression instead of a fixed experience.

We Might Be Entering the Era of “Playable AI”

For years, AI in games mostly existed as:

  • NPC behavior
  • procedural enemies
  • pathfinding
  • recommendation systems
  • balancing systems

But generative AI introduces something different entirely.

The game world itself becomes fluid.

Not just visually.

Structurally.

And Infinite Scaler accidentally showcased what that could look like at scale.

Imagine:

  • multiplayer games generating live events from player conversations
  • educational worlds adapting to curiosity in real time
  • AI-generated social spaces
  • dynamic storytelling environments
  • personalized exploration systems
  • infinite user-generated game loops

Suddenly, content pipelines start looking very different.

Developers May Need to Rethink What “Content” Even Means

One thing I kept thinking about after the demo:

What happens when content stops being handcrafted objects
and becomes generated possibility space instead?

That changes:

  • level design
  • asset pipelines
  • moderation systems
  • memory management
  • multiplayer synchronization
  • rendering optimization
  • interaction design
  • gameplay balancing

Traditional game development relies heavily on predictability.

Generative systems are probabilistic.

That creates entirely new engineering challenges.

Especially around:

  • safety
  • consistency
  • coherence
  • performance
  • abuse prevention
  • thematic stability

And honestly, I think most of the industry still underestimates how difficult this becomes at scale.

The Moderation Problem Is Massive

One line from the demo stood out to me immediately.

Before generating worlds, the hosts joked:

“As long as it’s safe for work.”

That tiny comment actually hints at one of the biggest unsolved problems in generative systems.

Because once users generate environments through language:

  • moderation becomes real-time
  • abuse becomes dynamic
  • edge cases explode exponentially

Unlike static games, generative systems can produce combinations developers never explicitly created.

That changes moderation entirely.

And I think this is exactly why companies like Google care so much about:

  • guardrails
  • policy layers
  • prompt filtering
  • classifier systems
  • constrained generation pipelines

The infrastructure challenge becomes just as important as the model itself.

Infinite Scaler Also Quietly Demonstrated AI-Native UX

This part fascinated me the most.

The interface was almost invisible.

Players weren’t navigating:

  • creation panels
  • asset libraries
  • editing tools
  • environment builders

They simply expressed ideas naturally.

The system handled translation into interaction.

That’s a huge UX shift.

Because historically, software required humans to learn system logic.

AI-native systems increasingly learn human intent instead.

And I think Infinite Scaler accidentally demonstrated that transition better than many “serious” enterprise AI demos.

This Didn’t Feel Like a Finished Product

It felt like an early glimpse of a new category.

Messy.
Experimental.
A little chaotic.

But genuinely new.

And honestly, that’s what made it interesting.

Not because it was polished.

But because it exposed a direction.

The same way early touchscreen phones felt incomplete before the industry fully understood what they would become.

I Think Google Showed More Than It Intended To

Most people probably saw Infinite Scaler as:

  • a fun audience activity
  • an AI showcase
  • a lightweight keynote break

I think it was accidentally much bigger than that.

Because underneath the spectacle was a very important idea:

language is starting to become a real-time creative interface.

Not just for writing.
Not just for chatbots.
Not just for search.

For interactive systems themselves.

And once that happens, software stops feeling static.

It starts feeling generative.

That’s a very different future than the one most apps were originally designed for.

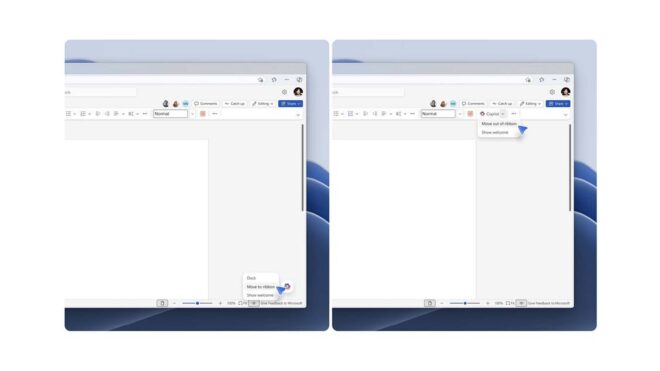
Microsoft, Office uygulamalarındaki hareketli Copilot butonunun kaldırılmasına izin verecek

Microsoft, Office uygulamasındaki hareketli Copilot butonunun kaldırılmasına izin verecek

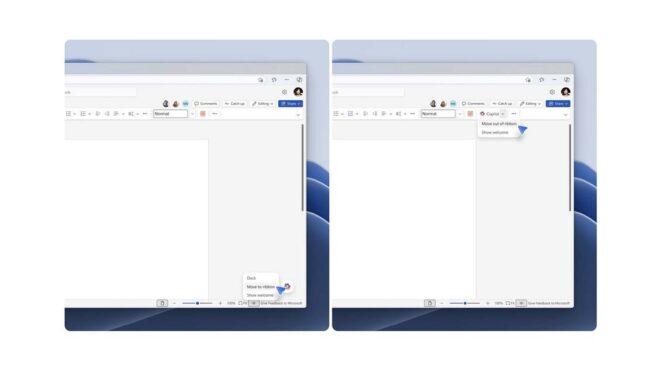
Microsoft, Office uygulamasındaki hareketli Copilot butonunun kaldırılmasına izin verecekMicrosoft, önümüzdeki hafta Office uygulamaları için yayınlayacağı güncellemeler ile kullanıcıların hareketli Copilot butonunu kapatmalarına izin verecek. Yakın zaman önce Word, Excel ve PowerPoint’e eklenen ve düzenleme alanındaki tabloların üstünde yer kapladığı için özellikle Excel kullanıcılarını kızdıran buton, önümüzdeki hafta alt bölümden yani dokümanların üstünden tamamen kaldırılabilecek.

Microsoft, Office uygulamalarındaki hareketli Copilot butonunun kaldırılmasına izin verecek yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

#css #webdev #beginners #codenewbie

Hello Dev Community! 👋

It is Day 4 of my journey toward mastering the MERN stack. For the past three days, I was busy building skeletons with HTML. Today, I finally started bringing those dry structures to life using CSS (Cascading Style Sheets)!

It felt amazing to move away from black text on a plain white screen and actually control how things look.

🧠 Key Learnings From Day 4

1. The Three Ways to Add CSS

I learned that there are three methods to attach styles to HTML, but one is clearly the professional standard:

  • Inline CSS: Writing styles directly inside the HTML tag (makes code messy).
  • Internal CSS: Writing styles inside the <style> tag in the HTML head.
  • External CSS (The Winner): Creating a separate .css file and linking it via <link rel="stylesheet">. I chose this method because it keeps my HTML clean and modular.

2. CSS Syntax & Basic Selectors

I mastered the basic anatomy of a CSS rule: Selector { Property: Value; }. I experimented with three primary selectors today:

  • Element Selector: Targeting tags directly (e.g., body, h1).
  • Class Selector (.): The most reusable way to style elements (e.g., .btn-primary).
  • ID Selector (#): For styling a single, unique element (e.g., #main-header).

🛠️ What I Actually Built / Styled

I took the semantic “About Me” page and navigation bar that I refactored yesterday and created an external style.css file for it.

Today, I didn’t worry about complex layouts. Instead, I focused on the basics:

  • Changed the background color of the body to a clean, modern off-white.
  • Styled my headings with different font families and dark gray tones.
  • Turned my navigation list items (<li>) into an inline layout so they sit horizontally like a real navbar, instead of a vertical bulleted list.

🎯 My Goal for Tomorrow (Day 5)

Tomorrow, I’m diving into the absolute core of CSS layouts:

  • Understanding the CSS Box Model (Margin, Border, Padding, Content).
  • Learning how space works between elements so my layout stops overlapping.

💬 Let’s Connect!

To the senior engineers: What is your favorite CSS font stack for clean, readable code? To fellow beginners: Did you start with Inline CSS or go straight to External files?

My styled code and repository are up to date on GitHub!
[Links in the Comments]

Keep coding! 🚀

The Hidden Layer Every AI Developer Must Learn

developer working behind desk

Late January 2026. A developer ships a social network over a weekend. No traditional code written — just prompts, a vision, and an AI that turned ideas into a working product in days. The platform goes viral. Andrej Karpathy, OpenAI co-founder, calls it “the most incredible sci-fi takeoff-adjacent thing I have seen recently.”

Then a security researcher opens the browser’s developer tools.
Within minutes, they find an API key sitting in plain JavaScript — visible to anyone who knows how to press F12. They use it to query the production database. No login required. No special tools. Just a simple command and a coffee.

What comes back: 1.5 million API authentication tokens. 35,000 email addresses. Thousands of private messages. The entire platform — every agent, every credential, every conversation — sitting wide open.

The platform was called Moltbook. The fix, when it came, took two SQL statements.

This is not a story about a bad developer. It is a story about a gap that AI does not fill automatically — and what you can do about it before you ship.

developer working behind desk

The Illusion That Catches Everyone

A few years ago, building software required crossing a painful barrier. You had to learn syntax, frameworks, databases, APIs, Git, deployment — and break things repeatedly along the way. For most people outside tech, software engineering felt like a locked room with a very small door.

Then AI arrived.

Now someone with little traditional programming experience can build a SaaS app over a weekend, connect a database to a frontend, integrate payments, and deploy an API — all from prompts. That shift is extraordinary, and I think it is genuinely amazing. I am a vibe coder too. I understand the excitement of watching an idea move from imagination to a working product faster than ever before.

But there is a dangerous illusion forming around AI-generated software: If the app works, people assume it’s safe. Those are not the same thing.

A beautifully designed application can still expose private user data, leak API keys, allow unauthorized access, and accidentally disable database protections — all while the UI looks polished and the login flow works perfectly. Security problems live underneath visible functionality. That is exactly what happened with Moltbook.

What AI Gets Right, and What It Quietly Skips

AI is very good at helping you build the happy path — the feature works, the button responds, the API returns data, the page renders. That part is genuinely impressive.
Security lives in the unhappy paths:

  • What if someone queries your database without logging in?
  • What if an attacker manipulates a request from the browser?
  • What if your API keys are visible in the page source?
  • What if someone calls your registration endpoint ten thousand times in a loop?

Experienced developers ask these questions automatically. Not because they are smarter — but because they built the habit slowly, over years of debugging painful issues, reading post-mortems, and making mistakes in lower-stakes environments.

AI compresses the implementation timeline dramatically. It does not compress the experience required to ask the right security questions. That gap is where breaches happen.

And to be clear: this is not only a beginner problem. Even experienced developers can become overconfident when AI accelerates output speed. Because AI-generated code often looks extremely convincing. The explanations sound confident. The architecture appears plausible. The feature functions correctly.

But plausible code is not the same as safe code.

The Moltbook Breakdown: What Actually Went Wrong

Moltbook was built on Supabase — a popular, well-documented backend service that is excellent for fast development. Supabase is designed to work with a public API key exposed on the client side. That is intentional and not, by itself, a security failure.

The security failure is what you configure that key to be able to do.

Supabase ships with a feature called Row-Level Security — a database setting that ensures users can only access their own data. It is not enabled by default. You have to turn it on. And if you are vibe coding and the AI generates a working backend without you asking about security, there is a good chance that step never comes up.

At Moltbook, it didn’t.

The result: anyone with basic technical knowledge could query the entire production database — every user’s credentials, private messages, and authentication tokens — using the key sitting in plain sight on the website. Write access was also open, meaning an attacker could have edited any post on the platform without logging in.

The founder’s public statement captured the situation honestly: “I didn’t write a single line of code for Moltbook. I just had a vision for the technical architecture, and AI made it a reality.”

The AI made a working platform. It did not make a secure one.

It Is Not Just Moltbook

Six months before Moltbook, security researchers at Wiz found a critical vulnerability in Base44 — a vibe coding platform used by actual enterprises to build internal HR systems, customer databases, and knowledge bases containing sensitive employee data.

The flaw was shockingly simple: two API endpoints for registering and verifying users required no authentication whatsoever. Using only a value visible in the app’s public URL, a researcher could create a verified account inside any private enterprise application on the platform — bypassing SSO and every other access control entirely.

Here is the detail that changes the conversation: Base44 builders did not write that vulnerable endpoint. The platform did. Individual developers had no visibility into the flaw. This is the second dimension of vibe coding security risk that almost nobody talks about. The first is what AI generates when you prompt it. The second is what the platform you are building on introduces independently of your code.

Both matter. Both can be addressed.

Security in Plain English

One reason security feels intimidating is because the terminology sounds abstract and technical. Most of it isn’t. Here is a plain-English translation of the concepts that come up most often:

Term What It Actually Means
Authentication Verifying who someone is
Authorization Deciding what they are allowed to access
API Key A secret password your app uses to talk to another service
Row-Level Security Preventing users from reading other users’ data in your database
Rate Limiting Stopping someone from making thousands of requests in a loop
Secret Scanning Automatically detecting exposed passwords or keys in your code
Least Privilege Only giving a system the minimum access it actually needs
Input Validation Making sure users can’t send dangerous or unexpected data

Security is not magic. Most of the time it is about reducing obvious mistakes, limiting damage when mistakes happen, and protecting user trust. That’s it.

The Five Things AI Consistently Misses

These are the patterns that show up repeatedly in AI-generated code — not as exotic edge cases, but as defaults. Each one comes with a practical fix.

1. API Keys Exposed in Client-Side Code
When you ask AI to connect your app to an external service, it will often put the credentials directly in the frontend code. Frontend code is public. Anyone can open the browser’s developer tools and find it. Automated scanners crawl the web looking for exactly this.

The fix: Run Gitleaks before you push code. It scans for secrets and blocks the commit if it finds any. GitHub’s built-in secret scanning does the same thing automatically on public repositories — no setup required.

2. Row-Level Security Not Enabled
This is the Moltbook failure. AI can generate a complete Supabase schema without ever enabling RLS, because RLS requires understanding your data access model — who should see what — and AI often skips that reasoning unless you ask for it explicitly.

The fix: In your Supabase dashboard, check that RLS is enabled on every table containing user data. Then write policies that define exactly who can access each row. The Supabase documentation has a beginner-friendly walkthrough that takes about twenty minutes.

-- Enable RLS on a table
ALTER TABLE agents ENABLE ROW LEVEL SECURITY;

-- Users can only read their own records
CREATE POLICY "owner_only"
ON agents FOR SELECT
USING (auth.uid() = owner_id);

3. API Endpoints With No Authentication
AI generates routes that respond to requests. Whether it adds authentication to those routes depends on whether you asked — and whether the AI remembered your earlier requirements by the time it got to that file.

The fix: Go through every API route and ask: what happens if someone calls this without logging in? Tools like Bearer scan your codebase and flag unprotected routes for free. Better still, apply authentication at the middleware layer so every route is protected by default.

4. Secrets on the Wrong Side of the App
Many AI tools know not to hardcode secrets and will suggest environment variables. What they sometimes miss is the difference between variables available to the client (public) and variables available only to the server (private).

In Next.js, any variable prefixed with NEXT_PUBLIC_ is bundled into the client JavaScript and visible to everyone. Your OpenAI API key, Stripe secret key, and database credentials should never have that prefix.

The fix: Search your project for NEXT_PUBLIC_ and verify that nothing sensitive uses it. Server-only secrets get no prefix. Public configuration values — like your Supabase URL — can use the prefix safely, but only if RLS is properly configured.

5. No Rate Limiting
AI generates endpoints that respond to requests. It does not add rate limiting unless you ask. This means your registration endpoint, login endpoint, and data endpoints will accept unlimited requests from anyone.

At Moltbook, this allowed a single bot to create 500,000 fake accounts. The same pattern can be used to exhaust your API quota overnight and run up a bill that ends your project.

The fix: If you are on Vercel, enable rate limiting in your project’s security settings — it takes five minutes and requires no code. For Supabase, the same option exists under Project Settings. Do this before you go public.

The Mistake Almost Everyone Makes: “I’ll Secure It Later”

This mindset is understandable. When you are learning, shipping feels difficult enough already. Security can feel like an advanced topic for a future version of yourself.

The problem is that insecure architecture hardens very quickly. Once real users arrive, technical debt compounds, insecure patterns spread through the codebase, and leaked secrets cannot be unexposed. The Moltbook breach did not happen because the founder planned to fix security later. It happened because the platform went viral before that moment came.

Security is not a decorative layer added at the end. It is part of the design. That does not mean you need perfection before you launch. It means security awareness needs to begin at the same time as everything else.

Your Security Stack, Kept Simple

You do not need to become a security engineer. You need a short checklist and the discipline to run it.

Start here — these take under an hour total:

  • GitHub Secret Scanning — enabled by default on public repos, catches exposed keys automatically
  • Gitleaks — run it locally before pushing; blocks commits containing secrets
  • Supabase RLS — enable it on every table in your dashboard; follow the docs walkthrough
  • Vercel Rate Limiting — enable it in your project settings before going public
  • Snyk free tier — scans your dependencies for known vulnerabilities; integrates with VS Code

When your project gets more serious:

  • Semgrep — static analysis that catches insecure code patterns in CI
  • CodeQL — deeper analysis integrated into your GitHub pull request workflow
  • Pre-commit hooks — stop dangerous commits before they leave your machine

Think of these tools as an automated second opinion. If AI is your fast-moving junior developer, security tooling is your automated reviewer. That combination is far safer than relying on intuition alone — especially when moving quickly.

One More Thing: Ask Your AI

One of the most underused techniques in vibe coding security is simply prompting for it. Before you ship any feature that touches user data, try this:

“Review this code for security issues. Check whether any credentials are exposed in client-side code, whether database tables have Row-Level Security enabled, whether API endpoints require authentication, and whether there is rate limiting on registration and data endpoints.”

AI is quite capable of security review when asked explicitly. The problem is that it does not apply that review automatically. Make it a habit to ask. It takes thirty seconds and it will catch things.

A Fair Hearing for the Critics

The people arguing against vibe coding are not wrong. They are pointing at a real pattern: AI generates working code that skips assumptions a trained developer would never skip. Moltbook and Base44 are valid evidence of that.

But the conclusion — that people without traditional coding backgrounds should not build things — does not follow. What the evidence actually shows is that vibe coding without security awareness is dangerous. That is a different claim, and it has a different solution.

The Wiz Research team — the same team that found both breaches — put it clearly: the opportunity is not to slow down vibe coding but to elevate it. AI tools that generate Supabase backends can enable RLS by default. Deployment platforms can scan for exposed credentials automatically. The infrastructure for secure-by-default vibe coding exists. It just is not the default yet.

Until it is, the gap has to be filled by builders who know what to check — and who check it.

Before You Ship

[ ] No API keys or secrets in frontend code
[ ] Gitleaks run before pushing to the repository
[ ] Row-Level Security enabled on every database table with user data
[ ] Every API endpoint requires authentication, or is explicitly marked public
[ ] Rate limiting enabled on registration and data endpoints
[ ] NEXT_PUBLIC_ prefix checked — nothing sensitive uses it
[ ] Snyk or equivalent scanned your dependencies
[ ] Asked AI to review your code specifically for security issues
[ ] Opened the browser dev tools and checked what a stranger can see

AI is making software creation more accessible than ever. More people building means more innovation, more creativity, more diverse voices entering technology. That is a genuinely good thing.

But software engineering has always been more than generating working code. There is a layer underneath every application — trust, security, permissions, responsibility — that still belongs to the person who shipped it.

You do not need to learn everything before you build. You just need to know the layer exists, and make a habit of checking it.

The checklist is above. The tools are free. The rest is discipline. The future of software may be AI-assisted. But responsibility is still human.

Found this useful? Share it with someone who just shipped their first AI-built app. The person who needs it most is usually the one who doesn’t know they need it yet.

AlphaEvolve: Google DeepMind’s Gemini-Powered Evolutionary Coding Agent

Inside AlphaEvolve: How Neural Networks and Evolutionary Algorithms Are Self-Optimizing Software

For several years, the role of Artificial Intelligence in software engineering has been primarily predictive. Early code generation models served as advanced autocompletion tools, predicting the next characters or lines based on historical patterns in existing repositories. While useful for increasing developer speed, these models lack the ability to discover novel algorithms or optimize low-level system performance autonomously.

To bridge this gap, Google DeepMind developed AlphaEvolve, an autonomous evolutionary coding agent. Instead of simply predicting and completing code based on pattern recognition, AlphaEvolve uses evolutionary computation principles to actively discover, refine, and optimize algorithmic code. By continually generating, testing, and selecting code variations within a specialized feedback loop, the system can discover counterintuitive improvements that human engineers often overlook.

The Core Architecture: Joint LLM and Evolutionary Evaluation

An evolutionary agent requires both a source of generation and a fast, objective mechanism for testing. For AlphaEvolve, this is achieved by pairing Google’s Gemini models with automated grading sandboxes.

The system operates in a closed-loop cycle:

  1. Diverse Hypothesis Generation: The agent is given an initial baseline algorithm and a target metric to optimize. AlphaEvolve utilizes an ensemble of models for candidate generation. Gemini Flash is deployed to explore a wide breadth of ideas quickly, making light modifications or introducing wild structural variations. Meanwhile, Gemini Pro provides deep reasoning, examining specific bottleneck areas and offering detailed algorithmic suggestions.
  2. Automated Verification: Every proposed code variant is compiled and executed in a secure sandbox. The automated evaluator runs the candidate code against strict correctness checks and performance benchmarks. Programs that produce incorrect values or experience runtime crashes are immediately discarded.
  3. Scoring and Selection: Success is quantified using objective, real-world metrics, such as CPU cycles, memory usage, latency overheads, or numeric tolerance. The best-performing candidates are archived in a selection pool and used as the “parent” scripts for the next generation of mutations.

This workflow removes the risk of standard model hallucinations. Because every output is verified by an execution environment, AlphaEvolve only accepts solutions that are mathematically and operationally correct.

Infrastructure, Kernels, and Hardware Integrations

The true value of an optimization framework is visible through its practical applications. AlphaEvolve has been integrated into several high-scale software and hardware systems within Google’s own ecosystem.

Data Center Resource Optimization

When deployed to optimize task-scheduling heuristics within Google data centers, AlphaEvolve successfully recovered an average of 0.7% of worldwide compute resources. While a fraction of a percent might seem minor, at a global infrastructure scale, this translates to millions of dollars in power and compute savings. This system has been operating in production for over a year.

High-Performance TPU Hardware Design

In hardware synthesis, hardware description languages like Verilog dictate the layout of silicon circuits on modern processors. When applied to arithmetic circuits in TPU design, AlphaEvolve suggested a highly unconventional Verilog rewrite. The logic was mathematically sound yet so counterintuitive that human designers had not previously considered it. This optimization was integrated into next-generation Tensor Processing Units.

Low-Level Low-Latency Software Kernels

For training transformer models, matrix multiplication efficiency is a critical speed constraint. AlphaEvolve modified a core matrix multiplication helper in Gemini’s architecture, speeding up the kernel by 23% and reducing overall Gemini training times by 1%. Additionally, when optimizing custom FlashAttention kernel implementations for GPUs, the agent achieved a 32.5% training speedup, reducing the manual optimization pipeline from weeks of expert human labor down to a single automated run.

Advancing Scientific Research and Modeling

Beyond core silicon and cloud software, AlphaEvolve has demonstrated practical utility in scientific domains where computation is a key bottleneck.

Genomics and Error Correction

In genomics, sequencing machines frequently introduce errors when reading DNA. Google Research developed a deep learning corrector called DeepConsensus to address these errors. By optimizing DeepConsensus’s core algorithms, AlphaEvolve reduced variant detection errors by 30%, giving genetic researchers at PacBio highly accurate sequence data at a significantly reduced computational cost.

Smart Energy Grid Coordination

Managing power grids requires solving the AC Optimal Power Flow (ACOPF) problem, which computes how to deliver electricity over high-voltage lines. Standard numerical solvers are slow, and previous neural network approximations lacked reliable reliability. An AlphaEvolve-optimized Graph Neural Network (GNN) model increased the feasibility rate of finding valid grid solutions from a poor 14% up to 88%, making deep learning models viable for real-time grid orchestration.

Quantum Circuit Simulation

Quantum computers are highly susceptible to noise. When executing molecular simulations on Google’s Willow quantum processor, AlphaEvolve optimized quantum circuit designs, reducing error bounds by 10x compared to existing industry baselines. This optimization enabled researchers to run longer, more complex simulations without having their calculations ruined by quantum noise.

Real-World Enterprise Deployments

To test the adaptability of this automated optimizer, Google Cloud brought AlphaEvolve to select enterprise partners. These deployments cover logistics, computational chemistry, marketing, and finance:

  • Logistics Routing (FM Logistic): Optimizing vehicle routing for the classic Traveling Salesman Problem (TSP) yielded a 10.4% improvement in route efficiency, saving over 15,000 kilometers of driving distance annually across transit routes.
  • Drug Discovery (Schrödinger): Machine Learned Force Fields (MLFF) are used to simulate atomic interactions during drug development. AlphaEvolve achieved a 4x speedup in MLFF training and inference, compressing molecular R&D cycles.
  • Model Training Costs (Klarna): To reduce cloud spending, Klarna deployed AlphaEvolve to optimize its custom internal transformer models, successfully doubling training speed while maintaining model accuracy.
  • Complex Campaign Analytics (WPP): By optimizing analytics pipelines dealing with high-dimensional campaign datasets, the agent achieved a 10% accuracy gain over manual configurations.

Practical Caveats and the Limitations of Metric-Based Search

While the results across systems engineering and science are highly positive, AlphaEvolve has specific operational boundaries that developers should understand before trying to apply these techniques:

  • The Objective Metric Bottleneck: Evolutionary search requires a clear, quantifiable reward function. If a task cannot be graded automatically and objectively (such as verifying if a codebase is “easy to read” or if a user interface is “pleasing”), AlphaEvolve cannot optimize it.
  • Sandbox Security and Safety: Executing unvetted, auto-generated code poses substantial security risks. Setting up isolated, resource-constrained execution sandboxes is necessary to prevent runaway memory leaks or systemic security issues.
  • Problem Formulation Effort: Although the search is fully automated, the initial configuration is not. Developers must still carefully formulate the problem boundaries, write precise unit tests, and design representative inputs to avoid overfitting.

Summary

The development of AlphaEvolve shifts the focus of AI coding tools from autocomplete helpers toward autonomous, self-optimizing pipelines. By coupling the exploratory capabilities of large language models with rigorous, automated sandboxes, Google DeepMind has created a system capable of optimizing low-level code, system layouts, and complex physical models. As large language models become more capable, autonomous evolutionary agents will become increasingly vital to scaling and securing the next generation of global software infrastructure.

Primary Source:

Supporting Sources: