The hidden authority of AI agents inside ERP, purchasing, inventory, approvals, and enterprise workflows
TL;DR

The next enterprise AI risk is not that a chatbot writes a bad email. It is that an AI agent quietly enters the operational layer of the company and starts ranking priorities, routing approvals, classifying risk, delaying purchases, escalating tickets, flagging customers, and shaping managerial decisions before anyone calls it management.
Companies still describe these systems as “assistants” because the word sounds harmless. But once a system can trigger action inside an ERP, CRM, inventory platform, purchasing workflow, or finance dashboard, it is no longer merely assisting.
It is participating in management.
The problem is not automation itself. The problem is invisible delegation: authority moves into workflows, prompts, thresholds, model outputs, and software rules, while responsibility remains formally assigned to humans who may only see the final recommendation.
That is how an AI assistant becomes a shadow manager.
Meta Description
AI agents inside ERP, purchasing, inventory, finance, and enterprise workflows are no longer just assistants. They increasingly rank, route, classify, escalate, and shape operational decisions. This article explains how invisible delegation turns AI into shadow management.
*1. The Assistant Myth
*
Everyone calls them AI assistants because “assistant” sounds harmless.
An assistant helps. An assistant supports. An assistant drafts, summarizes, searches, reminds, and organizes.
That language is accurate only while the system remains outside the decision chain.
Once the system can rank leads, block a purchase order, classify a vendor, flag a customer, recommend a reorder quantity, trigger a workflow, escalate a ticket, assign urgency, or prepare an approval path, the term “assistant” becomes misleading.
At that point, the system is no longer just helping a manager.
It is shaping the managerial environment before the manager acts.
This distinction matters because enterprise work is not made only of final decisions. Most corporate power lives in prioritization, routing, classification, timing, and escalation. Whoever controls those layers does not need to sign the final approval to influence the outcome.
A sales manager may still approve the weekly focus list, but if an AI system ranked the leads first, part of the commercial decision has already been made.
A purchasing manager may still approve the order, but if the ERP agent has already recommended the vendor, adjusted the quantity, flagged the risk, and routed the approval path, the decision has already been pre-shaped.
A finance controller may still review the expense, but if an AI classifier has already coded the transaction and assigned its risk level, the human review begins inside a frame built by the system.
That is the assistant myth: the company believes AI is supporting decisions when, in practice, AI is already structuring them.
The human manager remains visible. The automated manager remains embedded.
*2. From Chatbots to Agents
*
The first wave of enterprise AI was easy to understand.
A chatbot answered questions. A writing tool drafted text. A summarizer compressed documents. A search assistant retrieved information.
Those tools could be wrong, but their wrongness usually stayed inside language. A bad answer could be corrected. A weak summary could be rewritten. A hallucinated paragraph could be deleted.
AI agents are different.
An agent is not only a text generator. It receives a goal, consults tools, uses data, plans steps, invokes functions, and may change the state of a system.
That shift changes the risk model.
A chatbot says: “You may want to reorder this item.”
An agent creates a draft purchase order.
A chatbot says: “This customer seems high priority.”
An agent moves that customer to the top of the pipeline.
A chatbot says: “This invoice may be misclassified.”
An agent changes the expense code.
A chatbot says: “This ticket looks urgent.”
An agent escalates it to another department.
The first system produces language. The second system produces operational consequences.
That is the line companies often fail to mark.
The word “assistant” hides the transition from advice to action. But enterprise systems do not care whether a workflow was triggered by a human, a script, a rule, or a model. Once the system state changes, the company has acted.
This is where AI becomes managerial.
Not because it has a job title. Not because it sits in a meeting. Not because it appears on the organization chart.
It becomes managerial because it shapes attention, timing, access, priority, and execution.
*3. Where the Shadow Manager Appears
*
The shadow manager does not appear as a robot boss.
It appears as a workflow.
It appears as a recommendation that nobody questions because it came from the dashboard.
It appears as a priority score.
It appears as a blocked order.
It appears as an automatic escalation.
It appears as a vendor warning.
It appears as a risk label.
It appears as an approval path that feels procedural but was shaped by a model.
This is already visible in ordinary enterprise operations.
In sales, an AI system may rank leads according to predicted conversion. That ranking influences which customer receives attention first. The salesperson may think they are choosing, but the field of choice has already been ordered.
In purchasing, an AI agent may recommend suppliers based on price, delivery history, stock availability, vendor score, payment terms, or risk profile. That recommendation can quietly shift purchasing behavior away from human relationship knowledge and toward model-weighted criteria.
In inventory, an agent may recommend reorder quantities, flag slow-moving items, identify overstocks, and predict demand. If those predictions are wrong, the error does not remain theoretical. It becomes cash tied in stock, delayed sales, missing products, emergency orders, or warehouse friction.
In customer service, an AI system may decide which complaint deserves escalation. That decision affects response time, customer satisfaction, and the perceived seriousness of the issue.
In finance, AI classification may assign expenses, flag anomalies, group transactions, or prepare reports. If the classification is wrong, the error can affect reporting quality, cost-center visibility, departmental accountability, and managerial interpretation.
In operations, AI may summarize performance, highlight bottlenecks, and define what leadership sees first. That is not neutral. The first metric shown often becomes the first problem discussed.
The shadow manager does not need to make every decision.
It only needs to shape the order in which decisions become visible.
**
- The Hidden Chain of Command**
Traditional corporate authority is usually imagined as a clean hierarchy.
Owner. Executive. Manager. Supervisor. Employee. Action.
Enterprise AI complicates that structure.
The real chain can become:
Policy. System configuration. Data source. Prompt. Model output. Workflow trigger. Dashboard ranking. Human approval. Operational action.
The human remains inside the chain, but not always at the beginning of it.
This matters because responsibility is often assigned at the visible end of the process, while influence may have entered much earlier.
A manager may approve a purchase order without knowing that the recommended quantity was produced by a demand model trained on incomplete seasonal data.
A sales lead may be ignored because a scoring system placed it below the threshold, even though the model failed to capture a relationship or local market signal.
A warehouse adjustment may be flagged as suspicious because the system misread an operational pattern.
An accounts receivable account may be deprioritized because the dashboard over-weighted one indicator and under-weighted another.
In each case, the human did not disappear. But the human arrived late.
That is the key structure.
The visible manager signs, approves, reviews, or accepts. The invisible system has already arranged the options.
This is not the end of human authority. It is the redistribution of authority across software layers.
The company still says “the manager decided.”
But the better question is: who structured the decision before the manager saw it?
*5. Why ERP Makes This More Serious
*
AI inside a document editor is useful.
AI inside an ERP is different.
An ERP is not just software. It is the operational nervous system of the company. It connects sales, purchasing, inventory, accounting, logistics, invoicing, vendor records, customer records, product movement, and reporting.
When AI enters that layer, errors become operational.
A weak paragraph is a content problem. A wrong reorder suggestion is a cash problem. A bad vendor classification is a supply problem. A wrong expense code is a reporting problem. A bad lead ranking is a revenue problem. A wrong delivery priority is a customer problem. A bad inventory signal is a service problem.
This is why enterprise AI cannot be judged only by generic model benchmarks.
A model does not need to be generally “smart” to create damage. It only needs to be wrong at the point where the business acts.
The most dangerous AI in a company may not be the most advanced model. It may be the boring workflow nobody audits.
The purchase recommendation. The lead score. The automatic approval rule. The AR risk flag. The reorder suggestion. The inventory exception. The vendor ranking. The escalation logic.
These systems become powerful because they sit close to action.
They do not merely describe the business. They participate in running it.
This is why companies need a different vocabulary. Calling these systems “assistants” is not enough. In operational environments, an AI system should be classified according to its action rights.
Can it read data? Can it recommend action? Can it trigger action? Can it block action? Can it route approval? Can it change records? Can it reorder priorities? Can it modify system state?
The moment the answer becomes yes, the company is no longer dealing with a passive tool.
It is dealing with delegated operational authority.
6. The Accountability Gap
Most enterprise AI discussions focus on hallucination.
That focus is too narrow.
Hallucination matters when a model invents facts. But in enterprise workflows, the more common danger may be misclassification, over-ranking, under-ranking, false escalation, silent omission, wrong routing, and unexamined recommendation.
The system does not need to hallucinate to create harm.
It can use real data and still produce a bad decision structure.
It can classify an account as low priority because the available data is incomplete.
It can recommend delaying a purchase because it underestimates demand.
It can flag an employee action as unusual because the workflow does not understand local practice.
It can prioritize one customer because the model values transaction size over strategic relevance.
It can mark an item as slow-moving while ignoring a coming seasonal spike.
These are not hallucinations. They are operational distortions.
The accountability gap appears when nobody can answer seven basic questions:
What data did the system use?
What rule or model produced the recommendation?
What threshold was applied?
What alternatives were suppressed?
Who reviewed the output?
Who had authority to override it?
What happened after the recommendation was accepted?
Without those answers, the company has built authority without memory.
A human manager can be questioned. A workflow often cannot. A model output may be overwritten. A system recommendation may leave no readable trace. A dashboard may show the result without exposing the path.
That is not automation maturity. It is managerial opacity.
7. What Developers and Operators Should Log
The solution is not to reject AI agents.
The solution is to stop pretending they are harmless assistants once they touch operational decisions.
If an AI system can influence action, it needs an audit trail.
At minimum, enterprise AI agents should log:
Input source.
Data timestamp.
Prompt or instruction version.
Model version.
Tool used.
External system accessed.
Rule applied.
Threshold used.
Recommendation generated.
Action triggered.
Human reviewer.
Override status.
Final decision.
Business impact.
Error category, if later detected.
This is not bureaucratic decoration. It is the basic condition for operational accountability.
If a purchasing agent recommends a quantity, the company should know why.
If a sales agent ranks a lead, the company should know what signals mattered.
If a finance classifier assigns an expense category, the company should know which rule or model produced the classification.
If an inventory agent flags an item, the company should know whether the signal came from sales history, warehouse movement, vendor delay, forecast variance, or a model-generated probability.
This is how enterprise AI becomes governable.
Not by asking whether the system is impressive.
By asking whether its authority is visible.
- A Better Test: Authority, Not Intelligence
The wrong question is:
“Is this AI intelligent?”
The better question is:
“What authority does this AI have?”
That question changes the entire evaluation.
A simple model with access to an ERP approval workflow may have more operational power than a more advanced model trapped inside a chat window.
A mediocre classifier embedded in finance may produce more business risk than a brilliant writing assistant.
A small automation that blocks orders may matter more than a large model that only drafts emails.
Enterprise AI should therefore be evaluated by authority level, not only by capability.
Level 1: It reads information.
Level 2: It summarizes information.
Level 3: It recommends action.
Level 4: It routes action.
Level 5: It triggers action.
Level 6: It blocks action.
Level 7: It changes system state with limited human review.
The higher the level, the stronger the audit requirement.
This framework is simple, but it prevents the core mistake: treating all AI outputs as if they were merely advisory.
They are not.
Some outputs become instructions. Some recommendations become defaults. Some defaults become behavior. Some behavior becomes policy. Some policy becomes authority.
**
- Why Managers Should Care**
Managers should care because AI agents can make them responsible for decisions they did not fully structure.
A manager may be asked why an order was delayed. The real cause may be a workflow rule.
A manager may be asked why a customer was ignored. The real cause may be a lead-ranking model.
A manager may be asked why inventory ran short. The real cause may be a bad demand signal.
A manager may be asked why expenses were misclassified. The real cause may be an automated coding system.
In all these cases, the manager remains accountable while the system remains partially invisible.
That is a bad trade.
AI should reduce operational burden, not create a fog of responsibility.
For managers, the practical rule is direct: never allow an AI agent to influence action without knowing where its recommendation appears, how it is produced, how it can be challenged, and who owns the final decision.
Management cannot be delegated into a black box and then recovered only when something fails.
**
- Why Developers Should Care**
Developers should care because every enterprise AI agent is also a governance system.
A function call is not just a technical event when it changes a purchase order, a customer priority, a stock level, an invoice category, or an approval path.
A ranking algorithm is not just a ranking algorithm when it determines who gets attention first.
A classification model is not just a classifier when departments rely on it for reporting, escalation, or compliance.
A prompt is not just a prompt when it controls how operational language is converted into action.
This means developers are not merely building features. They are designing decision environments.
That does not mean developers become the moral owners of every business outcome. It means technical design choices can create managerial consequences.
What gets logged matters.
What gets hidden matters.
What becomes the default matters.
What can be overridden matters.
What requires human review matters.
What silently moves forward matters.
Enterprise AI development should therefore include one question in every workflow design:
Where does this system acquire practical authority?
That question is more useful than vague debates about whether AI will replace managers. In many companies, replacement is not the first step. Quiet redistribution is.
The job title stays human. The workflow becomes automated. The decision frame becomes synthetic. The responsibility remains unclear.
That is the shadow manager problem.
11. The Core Claim
Stop calling it an AI assistant if it can manage priority, routing, approval, classification, escalation, or execution.
Inside enterprise systems, assistance can become authority without changing its name.
That is the risk.
Not evil AI. Not science fiction. Not a robot CEO. Not a dramatic replacement of human managers.
The real shift is quieter.
AI enters the company as a helper. It gets connected to tools. It receives access to business data. It starts producing recommendations. Those recommendations become defaults. Those defaults shape workflows. Those workflows shape decisions. Those decisions shape the company.
By the time leadership notices, the assistant is already managing part of the business.
The future of enterprise AI will not be decided only by which model writes better emails or produces cleaner summaries.
It will be decided by which systems can act inside companies without making responsibility disappear.
Why It Matters
This matters because modern companies already run through software.
Sales teams follow dashboards. Purchasing follows workflows. Inventory follows system signals. Finance follows classifications. Managers follow reports. Executives follow summaries.
When AI enters those layers, it does not need to dominate the company to change it. It only needs to reorder what the company sees, delays, escalates, approves, or ignores.
The practical danger is not that AI becomes conscious.
The practical danger is that AI becomes procedural.
It becomes part of how the company moves.
And once it moves the company, it must be audited as authority, not described as assistance.
Related Academic Background
This article extends my broader work on how automated language systems redistribute agency, responsibility, and authority through formal structures.
*Related paper:
*
Expense Coding Syntax: Misclassification in AI-Powered Corporate ERPs https://doi.org/10.2139/ssrn.5361952
The paper examines how AI-powered ERP systems can produce misclassification risks when automated language and coding structures convert business events into financial categories. The broader issue is the same: when automated systems classify, route, or encode decisions, they do not merely represent the business. They reshape how the business becomes legible and actionable.
*About the Author
*
Agustin V. Startari is a linguistic theorist, author, and researcher in historical studies. His work examines the relationship between artificial intelligence, syntax, authority, institutional discourse, and the disappearance of agency in automated language systems.
He is the author of Grammars of Power, The Grammar of Objectivity, Suffering Without Perpetrators, The Grammar of Asymmetric Visibility, and Expense Coding Syntax. His research focuses on how language models and institutional systems redistribute responsibility through grammatical, operational, and procedural form.
*Personal website: *https://www.agustinvstartari.com/
*SSRN Author Page: * https://papers.ssrn.com/sol3/cf_dev/AbsByAuth.cfm?per_id=7639915
ResearcherID: K-5792-2016
Authorial Ethos
I do not use artificial intelligence to write what I don’t know. I use it to challenge what I do. I write to reclaim the voice in an age of automated neutrality. My work is not outsourced. It is authored. – Agustin V. Startari
Suggested Tags
AI, Enterprise AI, AI Agents, ERP, Automation, Workflow Automation, Management, Operations, Purchasing, Inventory, Finance, Business Software, AI Governance, Agentic AI, NetSuite, Enterprise Software, Accountability, Decision Systems


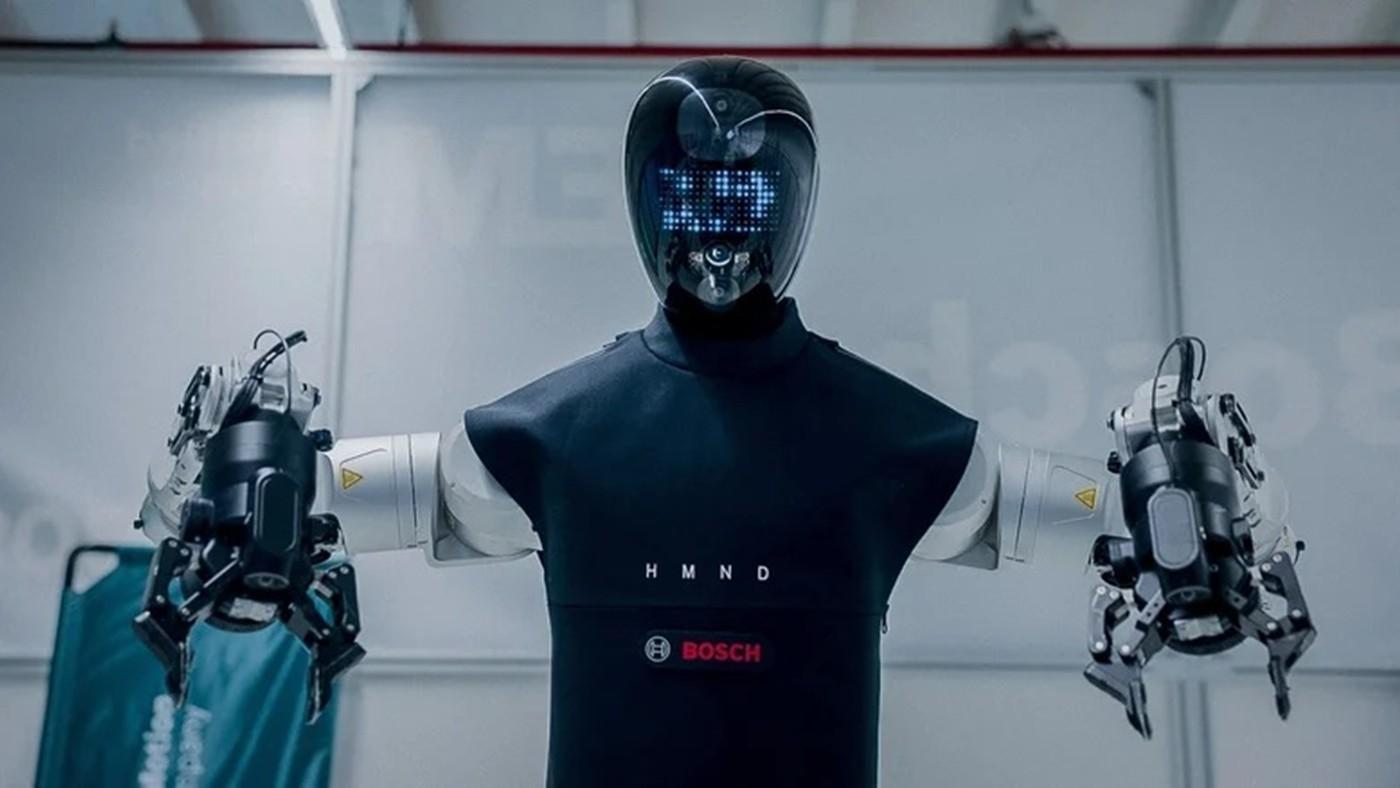
 Avrupa’da endüstriyel robot kullanımında yeni bir dönem başlıyor. Humanoid, Bosch ile yaptığı yeni anlaşma kapsamında HMND 01 insansı robotlarını seri üretime taşıyor.
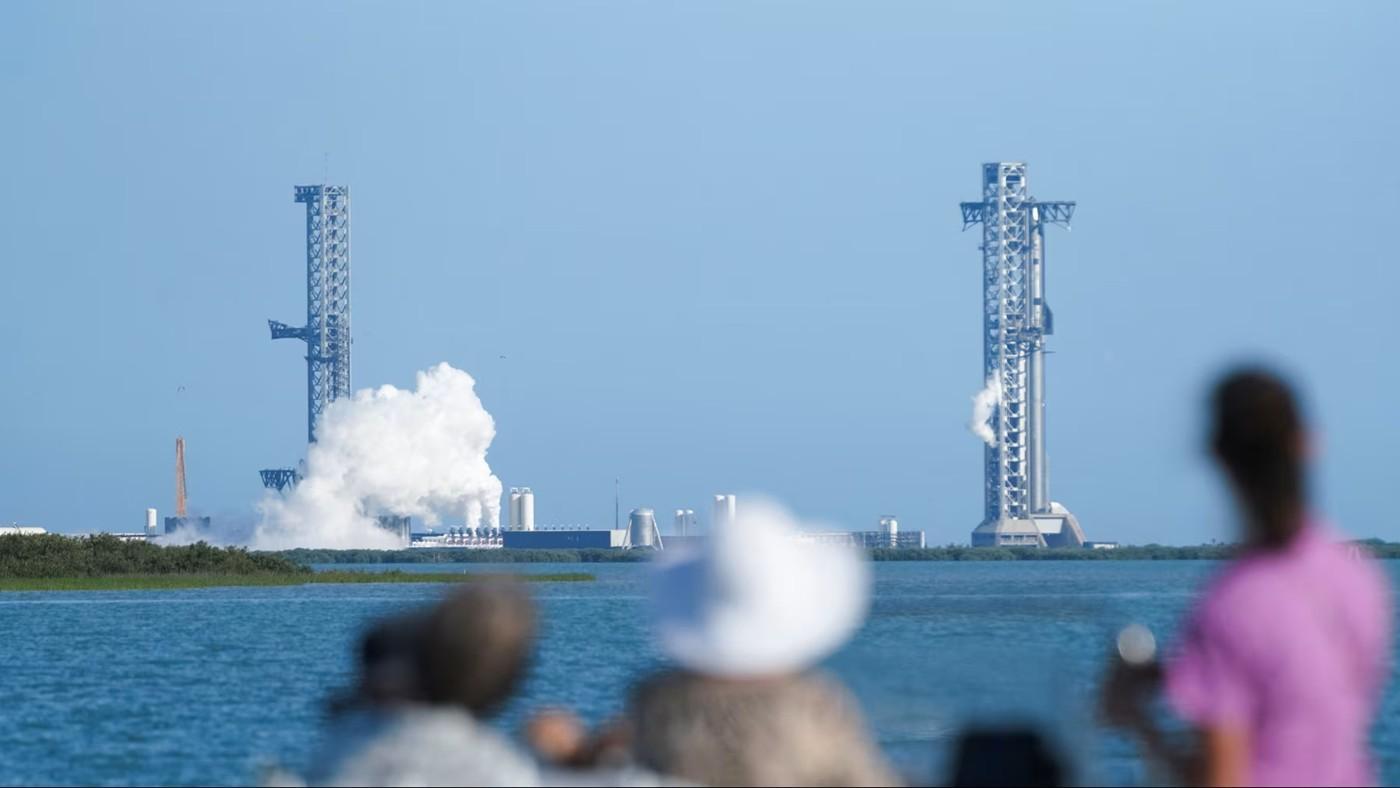
 SpaceX, yeni nesil Starship V3 roketinin Teksas’taki kritik test uçuşunu son saniyelerde iptal etti. Şirket, teknik sorunun ardından yeni denemenin Cumartesi 01:30 TSİ’de yapılacağını açıkladı.
 Take-Two, GTA 6’nın çıkışıyla birlikte tarihinin en büyük finansal yılına hazırlanıyor. Şirket, 2027 mali yılı için 8,1 milyar dolara kadar gelir bekliyor. İşte detaylar…
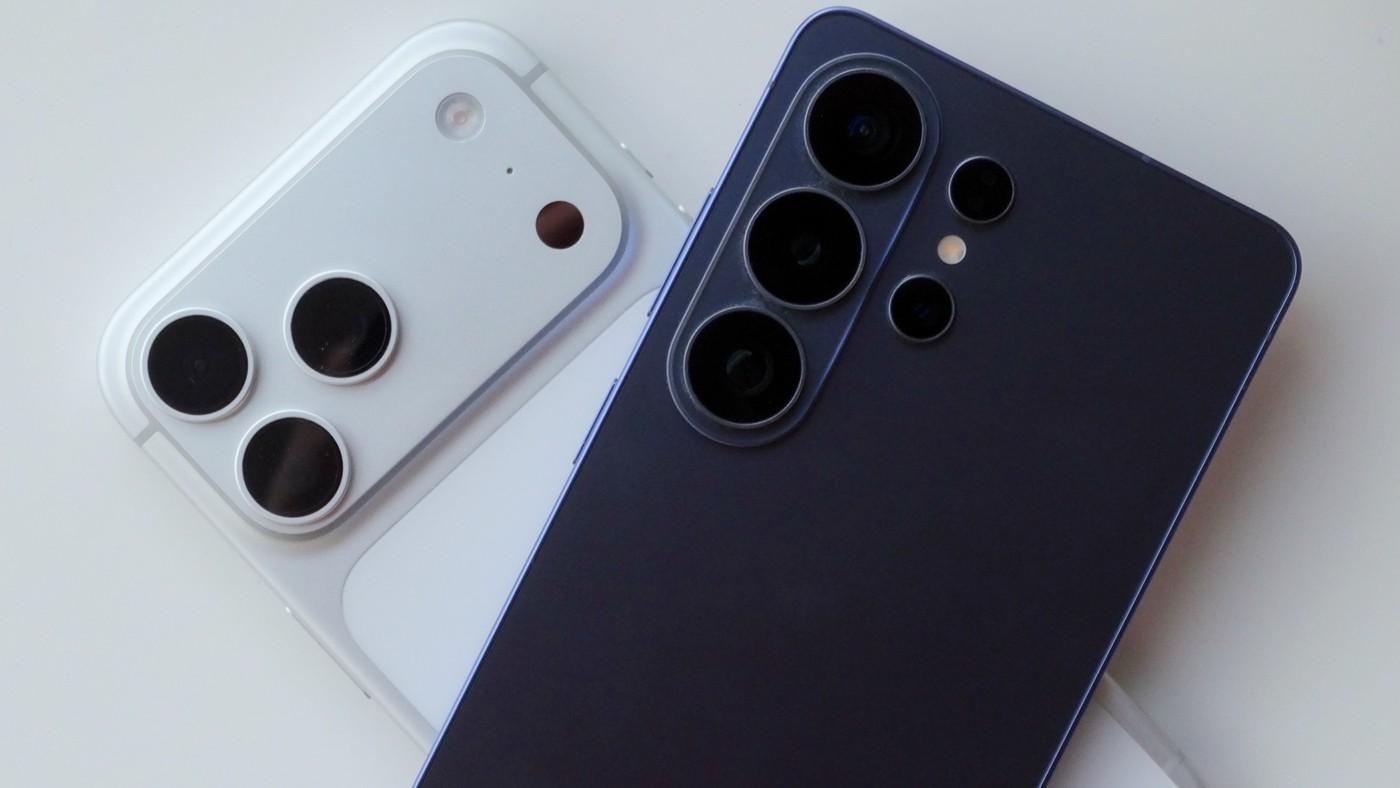
 Apple, en azından bir açıdan artık akıllı telefon pazarında lider konumda değil. Şirketin müşteri memnuniyeti puanı %80’e düşerek iPhone 11’den bu yana ilk kez Samsung’un gerisinde kaldı.
