My Full Make.com Blueprint For Automating a Sheets OpenAI Ghost Content Pipeline

Why I stopped hand-assembling content

I got tired of copy pasting my way through content.

Idea in Notion. Outline in Docs. Draft in ChatGPT. Formatting in Ghost. Images in Figma. Every post felt like a manual QA job instead of building something once and letting it run.

So I pushed the whole thing into Make.com.

Now a single row in Google Sheets turns into a drafted or published Ghost post. Titles, meta fields, tags, even a first-pass excerpt. All wired together with OpenAI in the middle.

This is the exact blueprint. Not theory. This is the scenario that runs my real content pipeline.

The high-level architecture

The stack is simple on purpose:

  • Google Sheets as the content control panel.
  • Make.com to orchestrate everything.
  • OpenAI to generate and clean up text.
  • Ghost (self-hosted) as the CMS.

One sheet row = one post. Status and flags in that row decide if Make should ignore it, draft it, or publish it.

I keep the Make scenario focused. One job. Turn structured data in Sheets into structured content in Ghost.

The Google Sheet schema

Here is the actual column setup from my sheet. No fluff.

  • A: id – internal ID, just an incrementing number.
  • B: status – idea, ready, generated, published.
  • C: title – human-written title seed.
  • D: slug – usually auto-generated in Make if empty.
  • E: brief – 2–4 bullet outline or a short paragraph.
  • F: target_keywords – comma separated SEO terms.
  • G: tone – e.g. direct, informal, first-person.
  • H: word_count_goal – rough length like 1200.
  • I: tags – comma separated Ghost tags.
  • J: generated_html – where I store the body HTML from OpenAI.
  • K: meta_title
  • L: meta_description
  • M: excerpt
  • N: publish_flag – draft or publish.
  • O: ghost_post_id – for updates.

I do not trust LLMs to guess intent. So I give them a tight brief and flags.

The Make.com scenario: the main flow

I run a single Make scenario that does all of this:

  • Polls Google Sheets for new ready rows.
  • Generates content and meta fields via OpenAI.
  • Writes the generated content back into the sheet.
  • Creates or updates a Ghost post.
  • Updates status and IDs.

I will walk through every module and what it actually does. No hand waving.

Module 1: Google Sheets “Search Rows”

Trigger: I run this scenario on a schedule. Every 15 minutes works for my pace.

First module is a Google Sheets > Search Rows module.

  • Spreadsheet: my Content Pipeline sheet.
  • Sheet: Posts.
  • Filter: status = ready.
  • Limit: I cap at 3 rows per run. I prefer small batches.

This returns an array of rows that are ready to be turned into drafts.

Each row carries all the columns I mentioned earlier.

Module 2: Iterator

I drop an Iterator right after Search Rows.

No magic here. It splits the list of rows into separate bundles so I can process each post independently.

The iterator just takes the array of rows from Sheets and iterates over values[].

Module 3: Data cleanup with Text & Tools

I do some pre-processing before I hit OpenAI.

  • Trim whitespace from things like title and slug.
  • Normalize commas in tags and target_keywords.
  • Generate a fallback slug if the cell is empty.

In practice this is a couple of Tools > Text aggregator / Text parser modules and one Set variable module.

Example: to generate the slug I use a simple Make formula in a Set variable module:

lowercase(
  replace(
    replace(
      replace(
        stripDiacritics(title);
        " "; "-"
      );
      "--"; "-"
    );
    "[^a-z0-9-]"; ""
  )
)

If the slug column in Sheets is already filled, I keep it. Otherwise this kicks in.

Module 4: OpenAI “Create a chat completion” for the article body

Now the fun part.

I use the OpenAI > Create a chat completion module. Currently on gpt-4.1 but I keep this modular so I can swap models.

I feed it a structured prompt that merges sheet data and my own style instructions. Here is the actual system + user content simplified to fit here.

System message (in the module):

You are Richard Lemon, a creative web experience developer.
Write opinionated first-person blog posts.
No em dashes. Short paragraphs (max 2-3 lines).
Direct voice, practical, specific.
Use HTML with <h2>, <p>, <ul>, <li>, <pre>.
Do not add <html> or <body> tags.

User message template:

Write a blog post with the following constraints:

Title: {{title}}
Brief: {{brief}}
Target keywords: {{target_keywords}}
Tone: {{tone}}
Word count target: {{word_count_goal}}

Rules:
- Write in first person as if I actually did the thing.
- Be concrete and technical where useful.
- Use only HTML tags for structure (<h2>, <p>, <ul>, <li>, <pre>, <code>).
- No introduction fluff, start with context or action.
- No conclusion heading.

Return only the HTML body.

The output is pure HTML. I do not want Markdown here because Ghost accepts HTML just fine and I like having precise control.

Module 5: OpenAI for SEO meta + excerpt

I split generation into two calls instead of asking one model response to do everything.

Second OpenAI > Create a chat completion module takes the title, target keywords, and a short summary of the generated HTML and creates meta fields plus an excerpt.

System message:

You create SEO metadata for blog posts.
Always stay under the specified character limits.
Return JSON only.

User message:

Post title: {{title}}
Target keywords: {{target_keywords}}
Body HTML (truncated): {{body_preview}}

Generate:
- meta_title: max 60 chars, must include at least one keyword.
- meta_description: 120-155 chars, natural and specific.
- excerpt: 1-2 sentences, no clickbait.

Return JSON like this:
{
  "meta_title": "...",
  "meta_description": "...",
  "excerpt": "..."
}

I then parse that JSON with a JSON > Parse JSON module.

Could I compress this into one call? Sure. I tried that. The meta fields got worse and harder to constrain. So I split it.

Module 6: Write everything back to Google Sheets

At this point I have:

  • Cleaned title and slug.
  • Generated HTML body.
  • Meta title, description, and excerpt.

Before touching Ghost I push this back into the sheet.

I use Google Sheets > Update a Row with:

  • Column J → generated_html from OpenAI.
  • Column K → meta_title from JSON.
  • Column L → meta_description.
  • Column M → excerpt.
  • Column D → final slug.
  • Column B → set to generated.

Why write back before publishing?

Because I like a manual checkpoint. I can read the generated HTML in Sheets, tweak the brief or title, flip status back to ready if I want a regen.

This effectively makes Sheets my content staging area while Ghost stays clean.

Module 7: Filter on publish_flag

Not every generated post should go live.

I add a filter between the Sheets update and the Ghost modules:

  • publish_flag = "draft" OR publish_flag = "publish"

If publish_flag is empty or something else, the scenario stops for that row. It will still update the generated fields, but nothing touches Ghost.

When I want a post to move to Ghost I set publish_flag to draft or publish in the sheet.

Module 8: Router for create vs update in Ghost

I use Ghost both for new posts and edits triggered from Sheets.

So I drop a Router with two branches:

  • Branch 1: Create when ghost_post_id is empty.
  • Branch 2: Update when ghost_post_id is not empty.

This lets me tweak a title or tags in Sheets, set publish_flag again, and push an update to the existing Ghost post.

Module 9: Ghost “Create a post” (branch 1)

On the create branch I use the Ghost > Create a post module.

Here is how I map things:

  • Title → Sheet title.
  • Slug → final slug from Module 3.
  • HTML → generated_html.
  • Excerpt → AI generated excerpt.
  • Meta title → meta_title.
  • Meta description → meta_description.
  • Tags → split tags column on comma, trim each value.

For status I map directly from publish_flag:

  • draft → Ghost draft.
  • publish → Ghost published.

Ghost returns a post object with an id. I capture that and write it back to the sheet.

Module 10: Google Sheets “Update a Row” with ghost_post_id

Immediately after the create call I drop another Google Sheets > Update a Row module.

It takes the id from Ghost and stores it in column O: ghost_post_id. I also set:

  • status = published if publish_flag was publish.
  • status = generated if publish_flag was draft.

This keeps my spreadsheet the single source of truth. I can filter ideas, generated drafts, and published content without logging into Ghost.

Module 11: Ghost “Update a post” (branch 2)

On the update branch, I use Ghost > Update a post with the stored ghost_post_id.

I do not blindly overwrite everything. Here is my mapping logic:

  • Always update HTML from generated_html.
  • Update title and slug only if the sheet values changed.
  • Update meta fields if they exist in Sheets. Otherwise keep Ghost values.
  • Tags are rebuilt from the tags column every time.

In Make that means I use if expressions in the field mapping. For example:

if(
  empty(sheet_meta_title);
  ghost.meta_title;
  sheet_meta_title
)

I apply a similar pattern for slug and description.

Module 12: Error handling and logging

I do not like silent failures.

So I added a simple error path using Make’s built-in error handlers:

  • If Ghost or OpenAI throws an error, I catch it in a separate route.
  • Then I write the error message into a errors column in Sheets.
  • I also ping myself with a Gmail > Send an email module when something breaks.

Nothing fancy. Enough to see when the pipeline has issues without watching Make all day.

Why I structured it this way

I tried a few alternative versions before landing on this flow.

What I did not like:

  • Single gigantic OpenAI prompt that tried to output HTML, meta, title variants, tag suggestions, everything. It was brittle.
  • Direct Sheets to Ghost without writing generated content back first. Harder to see what the model produced.
  • No publish_flag, so everything went straight to draft in Ghost. That got noisy fast.

What works better for me now:

  • Sheets is the control tower. All fields visible. Easy to override.
  • Make is the transport layer. No business logic hidden in Ghost.
  • OpenAI is a dumb transformer that takes structured inputs and outputs structured HTML and metadata.

The end result is that I spend time on outlines and ideas, not formatting posts or fighting CMS UI.

How this feels in daily use

Here is my actual workflow on a random Tuesday.

  • I open the Posts sheet and dump three new ideas as rows with rough titles and briefs.
  • I set status = ready and leave publish_flag empty.
  • Make picks them up, runs OpenAI, writes back generated HTML and meta, sets status = generated.
  • I skim the HTML in Sheets. If a post feels off, I tweak the brief or title, flip status back to ready and let it regenerate.
  • Once I like a post, I set publish_flag = draft or publish.
  • Next run, Make pushes it into Ghost accordingly.

I still edit inside Ghost sometimes. Especially for code-heavy posts or things where I want to insert images manually.

But 80 percent of the grunt work is automated. Which is the point.

If you want to copy this

If you are already using Make, you can rebuild this in an afternoon.

The three non-negotiables in my experience:

  • Use Sheets as a real schema, not a random dumping ground.
  • Keep OpenAI prompts tight and specific. One job per call.
  • Always round trip data back into Sheets so you can see what the system did.

From there you can layer on extras. Social post generation, image generation, cross-posting to other platforms. I keep those in separate scenarios so this core pipeline stays boring and reliable.

That is the full blueprint I run right now. It will probably change again in a month. But the core idea stays the same. Treat your content as structured data, not as a CMS typing session.

Solucionar Timeouts de MCP: Patrón HandleId Asíncrono

Las herramientas MCP congelan a los agentes de IA cuando las APIs externas son lentas, causando errores 424. El patrón handleId asíncrono devuelve inmediatamente un ID de trabajo y consulta los resultados sin bloquear.

El timeout de herramienta MCP ocurre cuando un agente de IA llama a una herramienta del Protocolo de Contexto de Modelo (MCP) que depende de una API externa lenta. La herramienta bloquea al agente indefinidamente en lugar de devolver un error. El resultado es un error 424 (Failed Dependency) o un flujo de trabajo congelado sin retroalimentación al usuario. Este post muestra el problema con escenarios reales y cómo el patrón handleId asíncrono proporciona respuestas inmediatas.

Esta demo usa Strands Agents con MCP (Model Context Protocol). El patrón asíncrono es independiente del framework y aplica a cualquier agente que llame APIs externas a través de MCP.

Código funcional: github.com/aws-samples/sample-why-agents-fail

Serie: Por Qué Fallan los Agentes de IA

  1. Desbordamiento de Ventana de Contexto — Patrón de Puntero de Memoria para datos grandes
  2. Herramientas MCP Que Nunca Responden (este post) — Patrón asíncrono para APIs externas lentas
  3. Loops de Razonamiento en Agentes de IA — Detectar y bloquear llamadas repetidas a herramientas

El Problema: Herramientas MCP Que Nunca Responden

El Protocolo de Contexto de Modelo (MCP) permite a los agentes de IA llamar herramientas externas. Pero cuando esas herramientas dependen de APIs lentas, todo el flujo de trabajo del agente se congela. El agente espera. El usuario espera. No pasa nada.

Una observación comunitaria de Octopus (Resilient AI Agents With MCP, 2025) identifica el problema central: a medida que aumentan las integraciones de sistemas externos, también aumenta la probabilidad de fallo. Los sistemas dejan de estar disponibles, responden lentamente o devuelven errores. Los agentes no tienen una estrategia incorporada para manejar esto.

Los reportes de OpenAI Community confirman el impacto del mundo real:

  • Errores 424 cuando las herramientas MCP tardan demasiado
  • Estados sin respuesta donde las solicitudes ni tienen éxito ni fallan
  • Herramientas que pasan la validación de handshake pero hacen timeout durante la ejecución

Por Qué Sucede Esto

MCP espera que las herramientas respondan rápidamente. Cuando una herramienta llama a una API externa lenta.

El protocolo MCP tiene expectativas de timeout implícitas. Si la herramienta no responde dentro de ~7-10 segundos, la conexión puede caerse con un error 424 (Failed Dependency). El agente recibe un error en lugar de datos, y el usuario no obtiene una respuesta útil.

Tres modos de fallo:

  1. API lenta — La herramienta espera 15+ segundos, UX pobre pero eventualmente responde
  2. API fallida — Servicio externo no disponible, error 424 después del timeout
  3. Estado sin respuesta — Solicitud aceptada pero nunca devuelve, requiere reinicio de sesión

La Demo: Simulando Escenarios Reales de Timeout

Construimos un servidor MCP que simula estos escenarios del mundo real:

from mcp.server import FastMCP
import asyncio

# FastMCP es un framework ligero de servidor MCP — las herramientas se registran con @mcp.tool()
mcp = FastMCP("Timeout Demo Server")

# Línea base: responde en 1s, bien dentro del umbral de timeout implícito de MCP (~7-10s)
@mcp.tool(description="Fast API - responds in 1 second")
async def fast_api(query: str) -> str:
    await asyncio.sleep(1)
    return f"Fast result for: {query}"

# Caso problema: retraso de 15s excede timeout de MCP — el agente se congela esperando esto
@mcp.tool(description="Slow API - responds in 15 seconds")
async def slow_api(query: str) -> str:
    await asyncio.sleep(15)  # Simula un servicio externo lento (pipeline de datos, trabajo por lotes)
    return f"Slow result for: {query}"

# Caso de fallo: retraso de 7s activa el timeout, luego lanza Failed Dependency (424)
@mcp.tool(description="Failing API - returns 424 after delay")
async def failing_api(query: str) -> str:
    await asyncio.sleep(7)
    raise Exception("Failed Dependency: External service unavailable")

La Solución Async HandleId

Comparación de llamada a herramienta MCP síncrona bloqueada por 17.2 segundos versus patrón handleId asíncrono completando en 1.7 segundos

En lugar de esperar operaciones lentas, devuelve inmediatamente con un ID de seguimiento:

import uuid

# Almacén de trabajos en memoria: mapea job_id → {status, query, result}
# Para producción, reemplazar con un almacén persistente (Redis, DynamoDB) para durabilidad entre reinicios
JOBS = {}

# El patrón handleId: devuelve un ID de seguimiento inmediatamente en lugar de bloquear
@mcp.tool(description="Start a long-running job, returns immediately with job ID")
async def start_async_job(query: str) -> str:
    job_id = str(uuid.uuid4())[:8]  # ID corto que el LLM puede pasar en llamadas de seguimiento
    JOBS[job_id] = {"status": "processing", "query": query}

    # Fire-and-forget: el trabajo lento se ejecuta en segundo plano, la herramienta devuelve antes de que termine
    asyncio.create_task(do_work(job_id, query))

    # El agente recibe esto en < 1s — sin timeout, sin UI congelada
    return f"Job started: {job_id}. Use check_job_status to poll for results."

# Endpoint de consulta: el agente llama a esto repetidamente hasta que el estado es "completed"
@mcp.tool(description="Check status of a running job")
async def check_job_status(job_id: str) -> str:
    job = JOBS.get(job_id)
    if not job:
        return f"Job {job_id} not found"
    if job["status"] == "completed":
        return f"COMPLETED: {job['result']}"  # Devuelve el resultado real al agente
    return f"PROCESSING: Job {job_id} still running"  # El agente consulta de nuevo después de una breve espera

Resultados de la Demo

Probamos los cuatro escenarios con un Strands Agent conectado al servidor MCP:

Escenario Tiempo de Respuesta Experiencia de Usuario Hallazgo de Investigación
Fast API (retraso 1s) 3.2s total ✅ Buen UX Línea base
Slow API (retraso 15s) 17.8s total ❌ UX pobre — agente espera Octopus: “el agente espera indefinidamente”
Failing API (424) 7.7s total ❌ Error después de esperar OpenAI Community: errores 424
Patrón asíncrono (handleId) 3.7s total ✅ Respuesta inmediata Solución: “responder ASAP con handleId”

Gráfico de barras comparando tiempos de respuesta de herramientas MCP en escenarios de fast API, slow API, failing API y async handleId

El patrón asíncrono transforma una espera de 17.8s en una respuesta inmediata de 3.7s. El agente le dice al usuario “trabajo iniciado” y puede verificar el estado más tarde, sin UI congelada y sin errores de timeout.

¿Por Qué Strands Agents para Integración MCP?

El MCPClient se conecta a cualquier servidor MCP en dos líneas. El agente descubre herramientas disponibles en tiempo de ejecución a través de list_tools_sync(), así que no mantienes una lista de herramientas codificada. Cuando el servidor MCP implementa el patrón handleId asíncrono, el agente consulta automáticamente sin código de orquestación adicional.

Strands soporta múltiples proveedores de modelos (OpenAI, Amazon Bedrock, Anthropic, Ollama). Los patrones de timeout de MCP mostrados aquí funcionan idénticamente en todos los proveedores.

Cuándo Usar Cada Patrón

Llamada directa (herramientas rápidas < 5s):

  • Búsquedas, cálculos, llamadas pequeñas a API
  • Sin riesgo de timeout

HandleId asíncrono (herramientas lentas > 5s):

  • Llamadas a API externas con latencia impredecible
  • Procesamiento de datos, generación de reportes
  • Cualquier operación que pueda exceder el timeout de MCP

Reintento con backoff (fallos intermitentes):

  • Servicios que ocasionalmente fallan pero se recuperan
  • Operaciones dependientes de red

Pruébalo Tú Mismo

Necesitas Python 3.9+, uv, y una clave API de OpenAI. El servidor MCP se ejecuta localmente como un subproceso, así que no se necesitan servicios externos.

git clone https://github.com/aws-samples/sample-why-agents-fail
cd sample-why-agents-fail/stop-ai-agents-wasting-tokens/02-mcp-timeout-demo
uv venv && uv pip install -r requirements.txt
export OPENAI_API_KEY="tu-clave-aquí"

uv run python test_mcp_timeout.py   # Ejecuta los 4 escenarios

O abre test_mcp_timeout.ipynb en Jupyter, JupyterLab, VS Code, o tu entorno de notebook preferido.

Conclusiones Clave

  1. Las herramientas MCP hacen timeout silenciosamente — errores 424 sin recuperación
  2. Las APIs lentas congelan todo el agente — espera de 17.8s sin retroalimentación
  3. El patrón handleId asíncrono lo soluciona — respuesta inmediata, consultar por resultados
  4. Diseña para el fallo — cada llamada externa puede hacer timeout, planifica en consecuencia

Preguntas Frecuentes

¿Qué causa errores 424 en llamadas a herramientas MCP?

Un error 424 (Failed Dependency) ocurre cuando una herramienta MCP tarda más que el umbral de timeout implícito (típicamente 7-10 segundos) en responder. El protocolo MCP espera que las herramientas devuelvan resultados rápidamente. Cuando una API externa bloquea la herramienta más allá de este umbral, la conexión se cae y el agente recibe un error 424 en lugar de datos.

¿Cuándo debo usar el patrón handleId asíncrono en lugar de una llamada directa a herramienta MCP?

Usa el patrón handleId asíncrono para cualquier herramienta que llame a una API externa con latencia impredecible: procesamiento de datos, generación de reportes, llamadas a servicios de terceros, o cualquier operación que pueda exceder 5 segundos. Para búsquedas rápidas, cálculos y llamadas pequeñas a API por debajo de 5 segundos, las llamadas directas funcionan bien.

¿El patrón handleId asíncrono funciona con cualquier servidor MCP, no solo Strands?

Sí. El patrón handleId asíncrono es un patrón de diseño de servidor MCP, no una característica de framework. Cualquier agente compatible con MCP puede llamar herramientas start_long_job y check_job_status. El patrón funciona con OpenAI Agents, integraciones MCP de LangChain, y cualquier cliente que soporte el Protocolo de Contexto de Modelo.

Referencias

Investigación

Implementación

Gracias!

🇻🇪🇨🇱 Dev.to Linkedin GitHub Twitter Instagram Youtube

I Built a ‘Production-Ready’ AI Agent Framework. It Was a Lie. So I Fixed It.

I Built a “Production-Ready” AI Agent Framework. It Was a Lie. So I Fixed It.

A story about AI-generated repos, fake READMEs, and what I did about it.

Two weeks ago, I built an automation pipeline that generates open-source projects on GitHub. The idea: market-research trending tech, scaffold a repo, fill it with code, add docs, and push — fully automated. 14 agents working together. 65 seconds end-to-end. I was proud of it.

Then I actually looked at the generated code.

The Ugly Truth

The pipeline had generated three repos:

  • ai-agent-starter: “Production-ready AI agent framework with multi-provider support”
  • dev-cli-kit: “Modern CLI toolkit with scaffolding, code generation, and git automation”
  • nextjs-saas-starter: “Next.js SaaS starter with auth, payments, and AI integration”

Sounds great, right? Here’s what was actually inside:

Repo Source Code Tests Could It Run?
ai-agent-starter 183 lines of broken code 0 No
dev-cli-kit 1 Handlebars template file (not even .ts) 0 No
nextjs-saas-starter Zero lines of code 0 No

The nextjs-saas-starter didn’t even have a src/ directory. Just a package.json, a tsconfig.json, and a README claiming it had “authentication, Stripe payments, and an AI chat interface.” None of those existed. Not even a single component.

The READMEs were AI-generated marketing fluff. Every claim was false. And somehow, each one had donation links (PayPal, Buy Me a Coffee, GitHub Sponsors) — asking for money before delivering a single working line of code.

I had built a lying machine.

What I Did

Instead of deleting the repos (GitHub URLs and star history have value), I decided to make every claim true.

I rewrote all three from scratch, and built a fourth:

1. ai-agent-starter (v0.2.0)

What it claimed → What it now is:

  • “Multi-provider support (OpenAI, Anthropic, Ollama)” → Actually implemented all three, with streaming
  • “Built-in tool execution engine” → Real function calling via OpenAI/Anthropic native tool APIs, not regex string matching
  • “Conversation memory” → Token-aware memory manager with auto-pruning
  • “CLI and programmatic API” → npx ai-agent-starter chat, npx ai-agent-starter run "prompt", and importable package

650+ lines of TypeScript, 24 tests, zero build errors.

2. dev-cli-kit (v0.2.0)

The old version’s only source file was cli.ts.hbs — a Handlebars template with // TODO: Implement init logic as its core functionality.

Now: real project scaffolding from 3 built-in templates (Node/TS, React/Vite, CLI tool), code generation (component/hook/util/api), and git workflow helpers. 480+ lines, 8 tests.

3. nextjs-saas-starter (v0.2.0)

From zero lines to a complete Next.js 14 app: landing page (hero, features grid, pricing), dashboard with sidebar + stats, login/register pages, billing page, settings page, API route, Tailwind CSS with dark mode. 520+ lines across 14 files.

4. ai-chat-saas (NEW)

Built on top of the first three — a complete AI chat application. Multi-provider streaming chat with server-side API key protection. 763 lines. Ready to deploy on Vercel in 60 seconds.

What I Learned

  1. AI-generated code isn’t the problem — unverified AI-generated code is. My pipeline agents were generating template stubs and calling them “production-ready.” The fix was embedding real, tested code as the generation template.

  2. READMEs should describe what EXISTS, not what you WISH existed. Every line in the new READMEs corresponds to actual code you can run.

  3. Donation links on empty repos are a red flag. If a project has zero working code and asks for money, it damages trust in the entire open-source ecosystem. I removed all donation links and added them back only where appropriate.

  4. “Production-ready” means something. It means tests pass, builds succeed, and someone can clone your repo, run npm install && npm run dev, and see a working product. Not a TODO comment.

What’s Next

The pipeline is fixed. The code agents now generate real, working code instead of stubs. Cron runs daily at 16:00 Beijing time.

I’m also launching a paid template — ai-chat-saas — on Gumroad for $19. It’s the chat application with all three providers, streaming, dark mode, and server-side API protection. Clone, set your API keys, deploy.

The moral: if you’re using AI to generate code, verify it. Actually run npm install. Actually run npm test. Actually try to use it. Otherwise you’re just building a very fast bullshit machine.

All repos: github.com/GrahamduesCN

Tapu ve Kadastro’nun 179. Yılında Dijital Dönüşüm Vurgusu

“Cumhurbaşkanımız Sayın Recep Tayyip Erdoğan’ın liderliğinde şekillenen Türkiye Yüzyılı vizyonu doğrultusunda Tapu ve Kadastro Genel Müdürlüğü olarak, güçlü teknolojik altyapımız, nitelikli insan kaynağımız ve yenilikçi yaklaşımımızla ülkemize değer üretmeyi sürdüreceğiz”

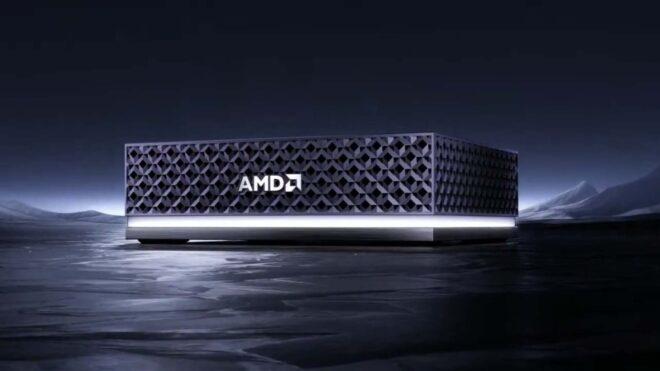
Nvidia DGX Spark rakibi AMD Ryzen AI Halo için resmi satış fiyatı açıklandı

Nvidia DGX Spark rakibi AMD Ryzen AI Halo için resmi satış fiyatı açıklandı

Nvidia DGX Spark rakibi AMD Ryzen AI Halo için resmi satış fiyatı açıklandıCES 2026 Fuarı’nda yapay zeka odaklı hazırlanan bilgisayar modeli AMD Ryzen AI Halo da tanıtılmıştı. Doğrudan Nvidia’nın DGX Spark’ına rakip olarak tasarlanan küçük boyutlu yapay zeka sistemi, AMD’nin yeni açıklamasına göre gücünü Ryzen AI Max+ 395’ten alıyor ve 200 milyar parametreli yapay zeka modellerini lokal olarak çalıştırabiliyor. AMD, cihazın DGX Spark ile kıyaslandığında GPT OSS 120B modelinde token bazında %7’ye varan seviyede daha yüksek performans verdiğini iddia ediyor. Şirket, Qwen 3.5 122B modelinde ise farkın %12’ye kadar çıktığını belirtiyor. Geliştiricilere yönelik tasarlanan ürünü 128 GB LPDDR5x RAM ile pazara sunacak olan AMD, cihazın hem Linux hem de Windows desteğine sahip olduğunu açıklıyor. Bu konuda yalnızca Linux desteği bulunan DGX Spark’tan ayrılan cihaz, 10 Gbps ethernet çıkışıyla geliyor, 2 TB PCIe Gen 4×4 SSD ile üç adet USB-C portu taşıyor ve WiFi 7 / Bluetooth 5.4 kablosuz bağlantı teknolojilerine destek veriyor. HDMI 2.1b de taşıyan 120W TDP değerine sahip AI Halo, […]
Nvidia DGX Spark rakibi AMD Ryzen AI Halo için resmi satış fiyatı açıklandı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

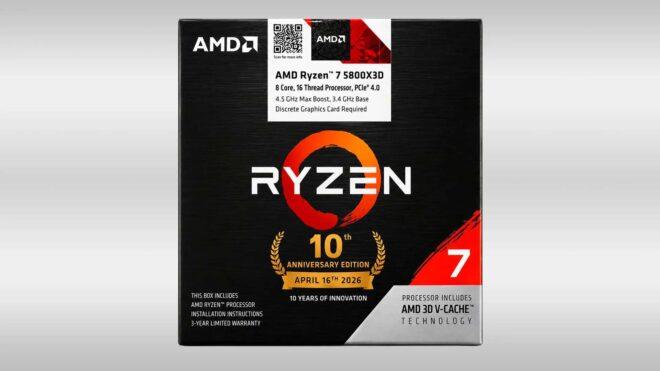
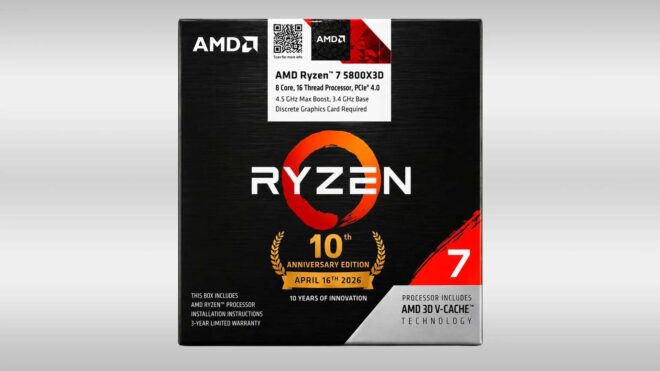
AMD Ryzen 7 5800X3D AM4 10th Anniversary Edition çok yakında tanıtılacak gibi görünüyor

AMD Ryzen 7 5800X3D AM4 10th Anniversary Edition yakında tanıtılacak gibi görünüyor

AMD Ryzen 7 5800X3D AM4 10th Anniversary Edition yakında tanıtılacak gibi görünüyorİlk sızıntısı geçtiğimiz ay yapılan AMD Ryzen 7 5800X3D AM4 10th Anniversary Edition işlemci modeli, çok yakında resmi olarak tanıtılacak gibi görünüyor. Hindistan merkezli bir satış kanalında resmi kutu görselleriyle birlikte yaklaşık 310 dolardan listelenen işlemci, ilk olarak 2022’de pazara sunulmuş, oyunlarda gösterdiği yüksek performansla büyük beğeni toplamış ve 2023 yılında üretimden kaldırılmıştı. Yeni sürümde performansı iyileştirmeye yönelik bir adım atması beklenmeyen AMD, bu özel sürümü her pazara götürmeyebilir.

AMD Ryzen 7 5800X3D AM4 10th Anniversary Edition çok yakında tanıtılacak gibi görünüyor yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

The Black Box Nobody Would Touch: Scaling Undocumented Legacy Code as a 3-Year Dev

Three years into my career, I raised my hand for a job that more senior engineers on the team had quietly decided to avoid.

We’d inherited a system. Two outside vendors had built it, then handed it over to an in-house team with zero documentation. Everyone was new. Nobody fully understood how it worked, and nobody wanted to be the person who touched it and broke production.

Then leadership dropped the mandate: make it scale to 5,000 concurrent users, turn it into multi-tenant SaaS, and support per-client authentication — some tenants on Active Directory, some on LDAP, some with their own mechanism.

The existing system couldn’t do any of that. And the people best equipped to fix it were the most afraid of it.

I took the challenge. Here’s what the black box actually looked like, and the method that got us through it — with one Senior DevOps, in about two months.

What we inherited

  • One server doing everything. Node.js served the frontend pages and ran the backend. Active Directory was tightly woven into the auth flow.
  • Two databases, two philosophies. MySQL for transactions, MongoDB for reporting.
  • Data got into Mongo three different ways. Sometimes a Python script pushed it. Sometimes the API wrote to it directly. Different teams had done it differently over the years, with no shared convention.
  • No docs, no original authors, no map.

If you’ve ever opened a repo and felt your stomach drop, you know the feeling. The instinct in that moment is to rewrite it. That instinct is almost always wrong — a rewrite of a system you don’t understand just recreates the same unknowns, slower, while the business waits.

So we didn’t rewrite. We tamed it. Here’s the method.

1. Understand the system from the outside, not the code

You can read a million lines of undocumented code and still not know what actually happens in production. So I stopped trying to read my way to understanding and started observing instead:

  • Logs and traffic — what endpoints actually get hit, and how often.
  • The databases, live — what queries are really running.
  • The process and the network — what’s listening, what talks to what.

Map the behavior, not the source. Within days you have a real picture of the system the code comments never gave you.

2. Find the seams

Once you can see how requests flow, you look for seams — the natural boundaries where you can change something without unraveling the whole sweater. For us the important ones were the authentication boundary, the heavy reporting read paths, and the frontend vs. backend responsibilities that happened to live in the same process.

You don’t need to understand every line — you need to understand the edges.

3. Scale the box from the outside before touching its insides

The key insight, and the part I’d tell every junior engineer: you can scale a system you don’t fully understand by changing what’s around it, not what’s inside it.

We went from one server to four:

Concretely:

  • Split frontend and backend onto their own servers — 2 for frontend, 2 for backend. Each frontend ran nginx as a reverse proxy that load-balanced across both backend servers, so traffic spread evenly and either backend could drop without taking the app down. (They also had different scaling profiles; co-locating them on one box was the original bottleneck.)
  • Ran the Node backend under PM2 in cluster mode — 4 workers per server, so a single Node process stopped being a single point of CPU contention.
  • Added read replicas for both MySQL and MongoDB. Reporting reads went to replicas; transactional writes stayed on the primaries. This alone took enormous pressure off the system without changing a line of business logic.

None of this required understanding the messy internals. It’s infrastructure and topology — and it bought us the headroom for 5,000 concurrent users.

4. Isolate the one risky internal change behind an abstraction

The part we did have to change was auth — going multi-tenant meant Active Directory could no longer be hardcoded. Each tenant needed its own mechanism: AD, LDAP, or custom.

Instead of touching AD logic scattered everywhere, we introduced a single seam: a pluggable auth provider, chosen per tenant.

// One interface, one adapter per mechanism.
const authProviders = {
  ad:     require('./auth/activeDirectory'),
  ldap:   require('./auth/ldap'),
  custom: require('./auth/custom'),
};

function getAuthProvider(tenant) {
  const provider = authProviders[tenant.authType];
  if (!provider) throw new Error(`No auth provider for ${tenant.authType}`);
  return provider;
}

async function login(req, res) {
  const tenant   = await resolveTenant(req);   // by subdomain / header
  const provider = getAuthProvider(tenant);
  const user     = await provider.authenticate(req.body, tenant.config);
  // ...issue the session / token
}

Every adapter implements the same authenticate(credentials, config) contract. The old AD logic became one adapter behind the interface instead of an assumption baked through the codebase. Adding a new tenant’s auth no longer means surgery on the core — just one small, isolated adapter.

That’s the legacy-taming move in miniature: don’t refactor the whole thing — wrap the risky part in a boundary and change behavior there.

5. Change incrementally, verify behavior every step

Because nobody understood the system fully, every change went out small and observable. Capture how it behaves now, change one thing, confirm nothing drifted, repeat. Slow is smooth, smooth is fast — especially when the safety net is observability, not people who remember how it works.

Where it landed

  • One server → four (2 frontend, 2 backend), backend under PM2 cluster (4 workers each).
  • Read replicas on both MySQL and MongoDB.
  • Pluggable per-tenant auth — AD, LDAP, or custom — instead of hardcoded Active Directory.
  • Capacity for 5,000 concurrent users, multi-tenant ready.
  • Delivered in ~2 months, with one Senior DevOps.

And the part I didn’t expect: doing this as a 3-year engineer — taking the thing no one else would touch and bringing it through — changed my standing in the company. It taught me that the scary, undocumented, “don’t touch it” systems are exactly where you earn trust the fastest.

What I’d tell my 3-year-old self

  1. Don’t rewrite what you don’t understand. Tame it first.
  2. Observe the running system before you read the code. Behavior is the real documentation.
  3. You can scale a black box from the outside — topology, clustering, replicas — long before you refactor its insides.
  4. Wrap risky change in a seam. Adapters let you change behavior without understanding everything.
  5. The systems nobody wants to touch are the biggest career opportunities. Raise your hand.

Have you inherited a black box like this? What did you do first — read the code, or watch it run?

Chat With Your Documents Using Garudust Agent — No Vector Database Required

Most RAG tutorials start the same way: “First, install a vector database…” Then come the embedding models, the chunking strategies, the similarity thresholds. By the time you can ask a question about a PDF, you’ve deployed three services and written 200 lines of boilerplate.

Garudust Agent takes a different path. RAG is built in — backed by SQLite FTS5 with a trigram tokenizer. No vector database. No embedding API calls. Drop a PDF (or TXT, CSV, Markdown, JSON) into the conversation and start asking questions in seconds.

How It Works

When you ingest a document, Garudust:

  1. Extracts text (native PDF parser, no external tools)
  2. Splits it into chunks (≤ 800 chars, paragraph-aware)
  3. Indexes chunks into an FTS5 virtual table with tokenize = 'trigram'

When you ask a question, doc_search runs a full-text query against the index and feeds the top matching chunks to the LLM as context. That’s the whole pipeline — one SQLite file at ~/.garudust/state.db.

The trigram tokenizer means it works on any language, including Thai, Chinese, and Japanese, without any tokenizer configuration.

Setup

RAG is enabled by default. The only thing you need to configure is which directories the agent is allowed to read from:

# ~/.garudust/config.yaml
security:
  allowed_read_paths:
    - /home/you/documents
    - /data/company-docs

That’s it. If you want to turn RAG off entirely:

disabled_toolsets: [rag]

Your First Ingestion

Start the CLI:

garudust

Then tell the agent to ingest a file:

You: ingest /home/you/documents/employee-handbook.pdf

Agent: Indexed employee-handbook.pdf — 47 chunks ready for search.
       Preview: "This handbook outlines the policies and procedures for all employees…"

Now ask anything:

You: What is the remote work policy?

Agent: According to the employee handbook, remote work is permitted up to 3 days per week
       for roles that do not require on-site presence. Employees must notify their manager
       at least 24 hours in advance and maintain availability during core hours (10am–4pm).

The Four RAG Tools

Tool What it does
doc_ingest Extract and index a file (PDF, TXT, CSV, MD, JSON…)
doc_search Full-text search across all ingested documents
doc_list List all indexed documents with chunk count and timestamp
doc_forget Remove one file or clear the entire index

You never call these directly — the agent decides when to use them based on your question. But knowing they exist helps you understand what’s happening.

Re-ingesting a file

If a document changes, just ingest it again. The old index for that path is replaced automatically.

Forgetting a document

You: Remove the Q1 report from the index.
Agent: Document removed from index.

Or clear everything:

You: Clear all indexed documents.
Agent: Removed 5 document(s) from index.

FTS5 Query Syntax

doc_search supports full FTS5 syntax, which the agent uses automatically when your question benefits from it:

Syntax Example
AND (default) remote work policy
Phrase "annual leave"
OR vacation OR leave
NOT policy NOT contractor
Prefix terminat*

You don’t need to write FTS5 queries yourself — the agent figures this out. But if you want to guide it:

You: Search for "termination clause" in the contract documents.

Real-World Use Cases

1. Company Knowledge Base

Ingest your onboarding docs, SOPs, and internal wikis. New team members can ask questions in plain language instead of searching through Confluence.

You: ingest /docs/sop-release-process.md
You: What approvals are needed before a hotfix can go to production?

2. Contract and Legal Review

You: ingest /legal/vendor-agreement-2025.pdf
You: Does this contract include a limitation of liability clause? What is the cap?

3. Log Analysis

Ingest a log file and ask questions without writing grep patterns:

You: ingest /var/log/app/error.log
You: Which service caused the most errors in the last hour?
You: Are there any database connection timeouts?

4. Codebase Documentation

You: ingest /project/docs/api-reference.md
You: What parameters does the /auth/refresh endpoint accept?

Ingesting Files Sent via Telegram or LINE

If you’re running garudust-server with a messaging platform, users can send files directly to the bot. Attachments are automatically saved to a temporary path and can be ingested on request:

User sends: quarterly-report.pdf (attached)

Agent: I received your file. Would you like me to index it for search?

User: yes

Agent: Indexed quarterly-report.pdf — 83 chunks ready.
       Preview: "Q1 2025 Financial Summary — Total Revenue: $4.2M…"

User: What was the gross margin for Q1?
Agent: According to the report, gross margin for Q1 2025 was 61.3%,
       up from 58.9% in Q4 2024.

Platform attachments (files from Telegram, LINE, Discord, etc.) are always allowed regardless of allowed_read_paths, since they’re written to /tmp/garudust_* by the platform adapter.

Multiple Documents at Once

You can ingest multiple files and search across all of them in the same session:

You: ingest /docs/policy-2024.pdf
You: ingest /docs/policy-2025.pdf
You: What changed in the travel expense policy between 2024 and 2025?

The agent searches both documents and synthesizes the differences.

Check what’s indexed at any time:

You: What documents have you indexed?

Agent: 2 documents indexed:
       - policy-2024.pdf | 34 chunks | ingested 2025-05-21 09:14
       - policy-2025.pdf | 38 chunks | ingested 2025-05-21 09:15

Limitations

  • No semantic search — FTS5 is keyword/trigram matching, not embedding similarity. If the document says “annual leave” and you ask about “vacation days,” the agent bridges this with its language understanding, but results depend on the LLM’s reasoning.
  • Session-scoped by default — The index persists in state.db, but searches are scoped to the current conversation key. Starting a new session means re-ingesting if you want to query the same files.
  • Text-only — Images, tables, and charts inside PDFs are not extracted. Text content only.

Summary

Garudust RAG Vector DB approach
Setup One config line Vector DB + embedding API
Storage SQLite (single file) Separate service
Languages Any (trigram) Depends on embedding model
Cost Zero (no embedding calls) Per-token embedding cost
Search type FTS5 keyword + LLM reasoning Semantic similarity

Garudust’s RAG won’t replace a purpose-built vector search pipeline for large-scale production retrieval. But for a developer who wants to ask questions about their documents right now — without running a second service — it’s the fastest path from PDF to answer.

Garudust Agent — GitHub · Releases