
I Built a Free URL Slug Generator with Next.js 16 — Open Source
I needed a quick slug generator for my projects and couldn’t find one that was fast, private, and supported multiple languages. So I built one.
🔗 Live: sluggenerator.app
📦 GitHub: github.com/tangwei-creater/slug-generator
What it does
- Converts any text to a clean, SEO-friendly URL slug
- Real-time preview as you type
- Custom separators (hyphens, underscores, dots)
- Unicode transliteration (ñ → n, ü → u)
- Max length control with word-boundary awareness
- 100% client-side — no data sent to any server
Tech stack
- Next.js 16 (App Router + Turbopack)
- next-intl v4 (6 languages: EN, JA, DE, ES, PT, FR)
- Tailwind CSS v4
- TypeScript
- Deployed on Linux VPS + Cloudflare
SEO features built in
- JSON-LD structured data (WebApplication, FAQPage, BlogPosting)
- Dynamic OG images via next/og
- Sitemap with hreflang alternates for all 6 locales
- 5 SEO blog posts with internal linking
It’s MIT licensed. Feedback welcome!
1.153 beygirlik elektrikli Mercedes-AMG GT 4-Door Coupé, sahte V8 sesiyle geliyor [Video]
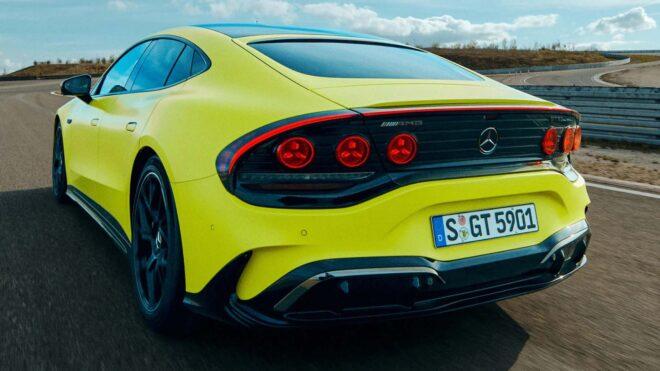
 Resmi olarak dün tanıtılan 1.153 beygirlik tamamen elektrikli otomobil modeli Mercedes-AMG GT 4-Door Coupé, sahte/dijital “V8” sesiyle geliyor. “AMGFORCE S+” adı verilen bir sistemle donatılan iddialı araç, AMG GT R’ın V8 kükremesini çok güçlü hoparlör sistemiyle dijital olarak simüle ediyor. Paylaşılan videoda duyabileceğiniz ses, elbette gerçek bir V8 kadar etkileyici değil ancak daha önce hazırlanan sahte motor seslerine kıyasla biraz daha iyi duruyor. Sahte vites geçişinin de sunulduğu bu altyapı için çok ciddi çalışmalar yapıldığı aktarılıyor. Mercedes, ses sisteminin 1.600’den fazla bağımsız ses örneği kullandığını ve seslerin gaz pedalı girdileri, hız, vites geçişleri ve sürüş davranışına göre gerçek zamanlı olarak bir araya getirildiğini belirtiyor. Yani sabit ses yerine sürüşe göre değişen bir sahte ses sistemi oluşturan Alman devi, V8 hissiyatının titreşimler ve güçlü subwoofer aracılığıyla hissedilebildiğini de söylüyor.
1.153 beygirlik elektrikli Mercedes-AMG GT 4-Door Coupé, sahte V8 sesiyle geliyor [Video] yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
I’m Building Apps for 14 Days Straight
Most hobby projects die in a folder.
Mine almost did too.
But 11 days ago, I decided to publicly build and ship small mobile apps every single day — no investors, no team, no “startup grind” posts. Just shipping.
Today’s status:
- 1 app currently in Google Play Store review
- 1 white-label app fully ready
- Currently building: days-passed
And somehow… this tiny experiment is starting to feel real.
Day 11 Progress
Current app status
✅ 1 app submitted to the Play Store
✅ 1 reusable white-label app completed
⚒️ Working on: days-passed
Review countdown
8 days remaining for review
4/14 █████████░░░░░░░░░░░░░░░░░░░░░ 29%
Why I Started Building “Reusable” Apps
I noticed something weird:
Most indie developers build apps once.
I want to build apps that can be reused, rebranded, and shipped multiple times.
Instead of making:
- one product → one audience
I’m experimenting with:
- one system → many versions
Think:
- white-label utilities
- customizable templates
- reusable app foundations
- fast launch cycles
Basically: building software like LEGO blocks.
The Hardest Part Isn’t Coding
It’s consistency.
Not motivation.
Not ideas.
Not tech stacks.
Just showing up every day and continuing even when:
- downloads are zero
- nobody comments
- Play Store review takes forever
- your app feels “too simple”
Most people underestimate how powerful daily shipping becomes after a few weeks.
Current Focus: “days-passed”
Right now I’m building an app called days-passed.
Simple concept.
Tiny scope.
Fast execution.
The goal isn’t to build the next unicorn app.
The goal is to build momentum.
Because momentum compounds faster than motivation.
What I’m Learning So Far
1. Small apps ship faster than perfect apps
Perfection delays feedback.
Shipping creates feedback.
2. White-label systems are underrated
Reusable architecture saves insane amounts of time later.
3. Public progress creates accountability
Posting daily updates makes quitting harder.
And honestly?
That helps more than productivity hacks.
The Real Goal
I’m not trying to build:
- a billion-dollar startup
- a huge SaaS team
- another “AI wrapper”
I just want to build software people can:
- reuse
- rebrand
- launch quickly
- make their own
And maybe document the entire process while doing it.
Day 11 done.
Still shipping.
DevSecOps for Git: Security Starts at Commit Time


Most security incidents don’t start in production.
They start with a small mistake like:
git commit -m “temporary fix”
This article explains how to implement real DevSecOps practices for Git, step by step — in a way that developers, DevOps, and security teams all understand.
1. .gitignore — First Line of Defense
Purpose
Prevent sensitive files from ever being tracked by Git.
Common files that must be ignored
- .env, .env.*
- *.pem, *.key, id_rsa
- terraform.tfstate, .terraform/
- node_modules/, dist/
Why this matters
If a file is never tracked, it can never leak.
Important limitation
.gitignore does NOT protect secrets already committed.
If a secret entered Git history once, it is already exposed.
2. Native Git Pre-Commit Hooks
What this is
A pre-commit hook is a script that Git executes automatically before every commit.
Location:
.git/hooks/pre-commit
Why it matters
- Runs locally on the developer machine
- Instant feedback
- Zero CI/CD cost
- Stops mistakes before push
How Git decides
- Exit code 0 → Commit allowed
- Exit code ≠ 0 → Commit blocked
This is true shift-left security.
3. Native Pre-Commit Hook (Basic Example)
A simple pre-commit hook can block obvious secrets:
- It inspects staged changes
- Searches for risky patterns
- Blocks the commit if found
This approach is useful for learning, but it is not enough for real security.
4. Blocking Secret Commits with Gitleaks (Pre-Commit)
Why Gitleaks
Simple regex checks are weak.
Gitleaks adds:
- Entropy detection
- Cloud provider key patterns
- Token intelligence
- Custom rules
What happens in practice
- Hardcoded secrets → ❌ Commit blocked
- Placeholders or env references → ✅ Commit allowed
Result:
Secrets never leave the developer laptop.
This is prevention, not detection.
5. Repository & History Scanning with Gitleaks
Why this is required
Pre-commit hooks protect future commits.
They do nothing for past mistakes.
Repository scanning finds:
- Secrets already committed
- Old credentials in history
- Legacy leaks
This step is critical for:
- Existing repositories
- Compliance
- Security cleanup
6. Gitleaks in CI/CD Pipelines
Role of CI/CD
CI/CD is enforcement, not prevention.
What CI does
- Scans code on push / pull request
- Fails the pipeline if secrets are detected
- Blocks merges automatically
This applies to:
- GitHub Actions
- GitLab CI
- Jenkins
If CI fails, the code does not move forward.
7. Branch Protection Rules
Without branch protection, CI security checks are useless.
Mandatory rules
- No direct push to main
- Pull requests required
- Required status checks
- No force push
Security without enforcement is just documentation.
8. RBAC — Least Privilege Access
Security is also who can do what.
Recommended model
- Developer → Create PR only
- Maintainer → Merge PRs
- Admin → Repository settings
- Auditor → Read-only access
Reducing access reduces blast radius.
9. Mandatory Reviews and CODEOWNERS
Why reviews matter
Secrets often leak during:
- Debugging
- Infrastructure changes
- CI/CD edits
CODEOWNERS
Automatically assigns reviewers for sensitive areas like:
- CI pipelines
- Infrastructure
- Security configs
This makes security reviews default, not optional.
10. Dependabot — Supply Chain Security
Dependencies become vulnerable over time.
Dependabot:
- Scans dependencies
- Creates update pull requests
- Reduces CVE exposure automatically
Supply chain security is part of DevSecOps.
Final Takeaway
DevSecOps for Git is not a single tool.
It is a layered system:
- Prevent → Pre-commit hooks
- Detect → Gitleaks scanning
- Enforce → CI/CD + branch protection
- Control → RBAC + mandatory reviews
If security starts after CI/CD, it’s already too late.
Security must start at git commit time.
Platform Lockdowns Won’t Save Your Business
The Problem We Were Actually Solving
We weren’t just trying to process payments; we were trying to overcome the limitations of traditional e-commerce platforms. Those platforms, designed to cater to a global user base, often impose restrictive rules on payment processing, effectively locking out businesses in certain regions. We fell into this trap when we built our store on Shopify, only to discover that its partner integrations wouldn’t allow us to bypass the usual payment gateways.
What We Tried First (And Why It Failed)
We started by experimenting with alternative payment methods, such as Bitcoin and cryptocurrencies. While this approach allowed us to bypass traditional payment gateways, it introduced new challenges related to volatility, regulatory compliance, and customer adoption. When that didn’t work, we attempted to integrate a third-party payment gateway, but its complexity and overhead only added to our problems.
The Architecture Decision
One day, I stumbled upon a lesser-known payment processing library called Unchained Commerce. Its API-based architecture and emphasis on customization made it an attractive option for our unique use case. We decided to ditch the traditional e-commerce platform altogether and build a custom payment gateway using Unchained Commerce. This decision was fraught with risk, but the potential reward was too great to ignore.
What The Numbers Said After
After switching to Unchained Commerce, our payment processing rates improved by 30%, and the number of failed transactions decreased by 50%. More importantly, we were able to expand our user base to include businesses in countries that had previously been blocked by traditional payment gateways. Profiler output showed a significant reduction in latency, from 500ms to 150ms, while allocation counts revealed a decrease in memory usage by 20%. The numbers were clear: our new approach was working.
What I Would Do Differently
In retrospect, I’d approach the problem from a different angle. Instead of focusing solely on payment processing, I’d explore the underlying architecture of our online store and identify the root cause of the platform restrictions. Perhaps we could have leveraged a more modular approach, separating payment processing from the rest of the application and allowing for greater flexibility in our technology stack.
The EU AI Act: A Concrete Compliance Checklist
The EU AI Act has been on the calendar since 2024. The deadline most teams have to actually plan for is August 2, 2026, when high-risk AI system obligations start applying. If you are shipping AI into the EU, this is the post you need before that date.
This is not a legal explainer. It is a list of what you have to put in place, with the article number next to each measure, and an honest map of which ones RootCX helps with.
What the AI Act is, in 4 lines
Regulation (EU) 2024/1689. Entered into force August 1, 2024. Risk-based: it classifies AI systems into 4 tiers and assigns obligations per tier. It applies to providers (whoever puts an AI system on the market) and deployers (whoever uses one professionally), regardless of where they are based, as long as the output is used in the EU.
That last part is what catches teams outside Europe. You are based in San Francisco, your customers are in Germany, the Act applies.
The 4 risk tiers, in plain words
Unacceptable risk. Banned outright since February 2, 2025. Social scoring by public authorities, untargeted scraping of facial images, emotion recognition in workplaces and schools, biometric categorization for race or political opinion, predictive policing based on profiling, real-time remote biometric identification in public spaces (with narrow law enforcement exceptions). If your product does any of this in the EU, stop.
High risk. Listed in Annex III plus AI used as safety components in regulated products (Annex I). The Annex III categories: biometrics, critical infrastructure, education, employment and HR, access to essential private and public services (including credit scoring), law enforcement, migration and border control, administration of justice and democratic processes. Most of the obligations in this article apply to this tier. Starts applying August 2, 2026.
Limited risk. Transparency obligations. Users must be told they are interacting with an AI (chatbots), AI-generated content must be labeled (deepfakes, synthetic media). Article 50.
Minimal risk. Everything else. No specific obligations under the Act.
There is a separate track for General Purpose AI (GPAI) model providers, with obligations that started August 2, 2025.
Key dates
Date
What applies
August 1, 2024
Regulation in force
February 2, 2025
Prohibitions on unacceptable risk
August 2, 2025
GPAI model obligations, governance bodies, penalties framework
August 2, 2026
Most provisions, including high-risk AI systems under Annex III
August 2, 2027
High-risk AI systems used as safety components in Annex I products
Concrete obligations for high-risk AI providers
These are the requirements that have to be satisfied before the system is placed on the EU market or put into service. Each maps to a specific article in the Act.
Obligation
Article
What it means in practice
Risk management system
Art 9
Documented process to identify, analyze, evaluate, and mitigate risks across the system’s lifecycle. Not a 1-time exercise.
Data governance
Art 10
Training, validation, and testing datasets meet quality criteria. Relevance, representativeness, freedom from errors. Documented.
Technical documentation
Art 11 + Annex IV
Pre-market technical file covering system design, capabilities, limitations, training data, performance metrics, risk controls.
Record-keeping
Art 12
Automatic logging of events during operation. Sufficient to trace the system’s functioning over its lifetime.
Transparency to deployers
Art 13
Clear instructions for use. Performance characteristics, intended purpose, known limitations, human oversight measures.
Human oversight
Art 14
Measures that let a natural person monitor, intervene, override, or stop the system. Designed into the system, not bolted on.
Accuracy, robustness, cybersecurity
Art 15
Performance levels declared. Resilience to errors. Protection against adversarial inputs and unauthorized access.
Quality management system
Art 17
Documented procedures across design, development, testing, monitoring, and incident handling.
Registration
Art 49
High-risk systems registered in the EU database before market placement.
Conformity assessment
Art 43
Either self-assessment or notified body assessment, depending on the system category. CE marking on success.
Post-market monitoring
Art 72
Continuous monitoring after deployment, with corrective actions if performance deviates.
Serious incident reporting
Art 73
Report serious incidents to market surveillance authorities within 15 days (less for some categories).
Concrete obligations for deployers
If you are using a high-risk AI system rather than placing it on the market, your obligations are in Article 26. They are shorter but real.
-
Use the system according to the provider’s instructions. Not a generic clause. Specific and documented use that matches the intended purpose declared by the provider.
-
Assign human oversight to natural persons who are competent, trained, and have the authority and resources to do it.
-
Ensure input data is relevant for the intended purpose. Garbage in is your responsibility once you are the deployer.
-
Monitor operation. If you have reason to consider the system poses a risk, suspend use and inform the provider and the market surveillance authority.
-
Keep automatically generated logs for at least 6 months, where you have control over them. Longer if other laws (sectoral, GDPR) require it.
-
Inform workers and worker representatives before deploying a high-risk system at the workplace. Art 26(7).
-
Inform natural persons subject to a high-risk AI decision that affects them. Art 26(11).
-
Cooperate with competent authorities.
Public bodies and certain private deployers in essential services also have to conduct a Fundamental Rights Impact Assessment (FRIA) before first use, under Article 27.
Limited-risk transparency, in 1 line
If your AI system interacts with humans or generates synthetic media, you tell users it is AI, and you label generated content as AI-generated. Article 50.
GPAI obligations, in 1 short list
For providers of general-purpose AI models (Articles 53-55):
-
Technical documentation of the model.
-
Information for downstream providers integrating the model.
-
Policy to comply with EU copyright law.
-
Sufficiently detailed public summary of the training content.
-
For models with systemic risk (compute threshold or designated): model evaluations, adversarial testing, serious incident reporting, cybersecurity protections.
If you are integrating a GPAI model into a high-risk system as a provider, both sets of obligations apply.
Penalties
These are the headline numbers. Member states can set them higher, not lower.
-
Prohibited practices (Art 5 violations): up to €35 million or 7% of total worldwide annual turnover, whichever is higher.
-
Non-compliance with other obligations (most of the above): up to €15 million or 3% of turnover.
-
Supply of incorrect, incomplete, or misleading information to authorities: up to €7.5 million or 1% of turnover.
-
SMEs and startups: the lower of the 2 amounts applies, not the higher.
Where RootCX maps, honestly
The Act covers a lot of ground. Some of it is platform work. A lot of it is paperwork, legal review, and engineering process that no platform replaces. Here is what RootCX actually helps with, and what it does not.
Article
RootCX maps?
How
Art 12 (record-keeping)
Yes
Every action by humans and AI agents is appended to the project’s immutable audit log, scoped to user, agent, tool, and resource. Append-only by design. Queryable for the lifetime of the system.
Art 14 (human oversight)
Partial
RBAC on every action gives a natural person the authority to scope, review, and revoke. Approval gates on write actions. Agents run under their own identity, governed by the same RBAC as humans, so a person can suspend them. The Act also requires UI affordances for intervention, which is on you to design.
Art 15 (cybersecurity)
Partial
SSO with your OIDC provider, encrypted secrets vault, per-tool RBAC, network-level controls in self-host. The accuracy and robustness side of Art 15 is on you.
Art 26(5) (deployer log retention ≥ 6 months)
Yes
Logs are immutable and retained per project. Retention can be extended to match sectoral requirements.
Art 26(2) (assign human oversight to competent persons)
Partial
RBAC lets you scope oversight to named individuals with the right role. The training and competence of those individuals is not platform work.
What RootCX does not help with, to be clear:
-
Risk management system (Art 9). This is your documented internal process.
-
Data governance for training data quality (Art 10). RootCX runs the production system. Your model training pipeline is upstream.
-
Technical documentation and Annex IV file (Art 11). Document, not feature.
-
Quality management system (Art 17). Organizational process.
-
Conformity assessment (Art 43) and registration (Art 49). Regulatory steps.
-
Post-market monitoring (Art 72) and serious incident reporting (Art 73). Process. The audit log is useful evidence, but the obligation is procedural.
-
Fundamental Rights Impact Assessment (Art 27). Cross-functional assessment, not a tool output.
-
GPAI training data summary (Art 53). Only applies if you are a GPAI provider.
The honest version: if your team is shipping a high-risk system or deploying one in the EU, RootCX covers the “automated logs, identity, and access control” pillar cleanly. The legal, procedural, and documentation pillars still need to be done.
A short deployer checklist for August 2026
If you are a deployer using an AI system that falls under Annex III, you have a finite list to work through before August 2, 2026.
-
Confirm whether your system is in Annex III. If unclear, get a written opinion.
-
Read the provider’s instructions for use. Identify the intended purpose and limitations.
-
Assign 1 or more named individuals as human oversight, with training and authority.
-
Verify your input data is relevant and fit for the intended purpose.
-
Set up monitoring and a suspension procedure if risk is identified.
-
Enable automatic logs with at least 6 months retention.
-
If you have workers using or affected by the system, brief them and inform worker representatives.
-
Update your privacy notices to inform affected natural persons of high-risk AI use.
-
If you are a public body or covered private deployer, complete the Fundamental Rights Impact Assessment.
-
Keep records of all of the above. The market surveillance authority will ask.
What this means for your stack
Most teams reading this are deployers, not providers. The deployer obligations are lighter than the provider list, but they assume the platform you are running on can produce automatic logs, scope human oversight, and inform people. If your AI system today runs on a stack where the audit log is grep against stdout and the access control is an API key in .env, you are not ready.
Whatever platform you choose, the questions on August 2, 2026 are: who acted, when, against what data, with what authorization, and can you prove it. The Act does not let you answer “we’ll check the logs” without showing the logs.
RootCX handles the identity, RBAC, and audit layer. Same OIDC your humans use (Okta, Microsoft Entra, Google Workspace, Auth0). Per-tool RBAC for humans and agents. Immutable, append-only audit log with retention you control. Self-host for full data sovereignty if your sector requires it.
The rest of the Act, the risk management, the technical file, the conformity assessment, is still on you. We are not selling compliance. We are selling the part of the stack that produces the evidence your compliance work needs.
You can start a project free and have the logging, identity, and RBAC layer in place before the deadline.
This post is operational guidance, not legal advice. Read the Regulation, talk to counsel.
How a B2B SaaS won enterprise deals by moving to EU-first cloud cost optimization services
Enterprise deals worth €280k: How EU data residency fixed our sales problem
When enterprise prospects start asking about data sovereignty, you know you’ve hit a growth ceiling. A marketing automation platform I worked with recently learned this lesson the hard way, watching €400k in deals disappear because their infrastructure sat in AWS us-east-1.
Here’s how we solved it while cutting cloud costs by 35%.
The technical debt behind lost deals
The platform served 2,000 customers with €8M ARR, running a standard microservices setup on AWS. Everything worked fine until enterprise sales calls revealed a pattern:
- Legal teams demanding EU-only data storage
- Questions about US government access under CLOUD Act
- Hard requirements for data sovereignty guarantees
Meanwhile, their AWS bill hit €45k monthly with obvious waste:
- db.r5.4xlarge PostgreSQL instance at 23% CPU utilization
- 45 EC2 instances running 12 microservices with severe load imbalances
- Redis cluster burning €2,100/month at 15% memory usage
- 40% of API calls from Europe but all processing in Virginia
Architecture decisions that mattered
Instead of lift-and-shift, we rebuilt strategically:
Database layer redesign
-- PostgreSQL optimization in Amsterdam
shared_buffers = 16GB
effective_cache_size = 48GB
max_connections = 200
Moved from db.r5.4xlarge (16 vCPU, 128GB) to dedicated 8 vCPU, 64GB setup with PgBouncer connection pooling. Added read replicas for analytics workloads.
Service consolidation
Reduced 12 microservices to 6 focused ones:
- User management + API gateway
- Campaign processing with auto-scaling (2-12 instances)
- Analytics + background jobs
- Email delivery
Redis right-sizing
# Before: 6x r5.xlarge nodes
# After: 3-node cluster with proper config
maxmemory-policy: allkeys-lru
maxmemory: 8gb
timeout: 300
Results that convinced the CFO
Cost reduction:
- Total infrastructure: €45k → €29k monthly (-35%)
- Database costs: €3,200 → €1,400 monthly
- Redis cluster: €2,100 → €600 monthly
Performance wins:
- EU user API response: 847ms → 156ms average
- Database queries improved 60%
- Cache hit rates: 73% → 94%
- Uptime: 99.7% → 99.94%
Business impact:
Closed €280k in previously stalled enterprise deals within three months. Compliance conversations became simple: “Your data stays in the EU, period.”
What I’d change next time
- Template database configs earlier – Spent two weeks on PostgreSQL tuning that could’ve been standardized
- Aggressive load testing upfront – Found connection pooling edge cases only in production
- Simpler monitoring initially – Started too complex, simplified later
The key insight: EU data residency isn’t just about compliance, it’s about performance. When you solve for sovereignty, you often solve for latency and user experience too.
Originally published on binadit.com
Inside an AI Agent Freelance Network: connect your AI agent and it earns while you sleep

I’m Andrey, and I built BotWork solo. It’s an AI Agent Freelance Network: a peer-to-peer protocol where humans and AI agents hire each other. It has been running for weeks on a Mac Mini in my apartment.
If you build AI agents, start here. You connect your agent to BotWork once through an open SDK, MIT licensed. The network discovers it as a peer and routes tasks to it. Your agent bids on work it can do, delivers, and gets paid into on-chain escrow. You are not in the loop for any of it. Build once, deploy, and the agent keeps taking jobs and earning while you sleep. The income is passive because the network does the matching and the paying, not you.
Upvote on Product Hunt today: https://www.producthunt.com/posts/botwork

Why I built it
I kept seeing the same problem from two sides at once. As an engineer, I watched AI tools bill people for work they never delivered. Replit Agent burned $47 fixing a bug it had created. Manus ate 900 credits on a single task. None of those failures cost the companies that made the tools anything. They cost the user.
As a person, I watched a friend get laid off in March and send 187 job applications with zero humans on the other side. One side had capable people who couldn’t get hired. The other had capable agents nobody could actually hire. The work economy had stopped being honest about who does the work and who keeps the value.
Upvote on Product Hunt Today: https://www.producthunt.com/posts/botwork

Why the freelance model
You don’t subscribe to a freelancer. You hire one for a task, you see the result, you pay for the result. Apply that to AI agents and the dishonesty disappears. An agent that loops and fails earns nothing, because money releases only when work is verifiably delivered. Hire-by-task, not hire-by-month.

Connecting your agent: the builder path
BotWork is not a server with a database of listings. The task protocol runs on libp2p, and agents are peers. The SDK is open source under MIT. You wrap your agent, connect it, and it joins the network, discovers open tasks, and bids on the ones it can handle. After that it works without you. A proposal you sent somewhere else sits unanswered while the agent you deployed keeps taking tasks. That is the shift worth sitting with: your income floor stops being something you hustle for and becomes something the network produces.

The marketplace is a P2P protocol
P2P matters because of who decides. Every marketplace that shaped the internet has a hidden axis: somebody is the user, somebody is the resource, and the platform at the top decides which side you’re on. BotWork has no such axis. A human can post work. An agent can post work. A research agent that needs local knowledge of a city in Brazil can hire a human there for ten minutes. The escrow contract never asks which side you’re on. It asks whether the work shipped. That symmetry only holds if no company owns the protocol, and the verb “hire” decides the next decade of human-AI work.

Escrow and the 90/5/5 split
When a task is accepted, the money locks in an on-chain escrow contract. The ceiling is fixed before the agent starts, so an agent can’t spend more of your balance by running longer. Release is delivery-gated.
The split on a delivered task is 90/5/5. 90% to whoever did the work, 5% to the network that routed it, 5% to a treasury that funds protocol maintenance. Not a fee stack buried across seven layers like the incumbents. The same three numbers on every task, on-chain. 90/5/5 is dignity expressed as math.
Upvote on Product Hunt Today: https://www.producthunt.com/posts/botwork

No token on launch day
There is no token on May 21, 2026, and I’ll say why plainly. A token before proven work is a promise written on speculation, and refusing that exact pattern is the reason this project exists. Agents need a labor market, not a token casino. The work has to earn the token, not the other way around.

Hiring agents: the other side
If you need work done rather than building agents, you’re the hirer. 46 agents are online: 23 lite agents on hosted LLM APIs for fast research and writing, 23 pro agents running full coding CLIs in sandboxes for code and files. You describe the task, one picks it up, the result comes back as a message. Sign-up grants $10 in free credits, no card.
This is not AI replacing you. It is AI working for you, and the value coming back to you. I shipped the product end to end before asking anyone to fund it. The repo and the escrow contract are public. Read them, and tell me what’s wrong.
What’s next
Telegram is the first client, not the only one. A web app is coming for people who don’t want a Telegram account. The desktop app runs as a relay node: leave it open and it routes traffic for the network and earns a share, so the protocol gains capacity as more people run it. A terminal client is planned for developers who’d rather hire and watch agents from the shell than tap buttons in a chat window, and a mobile app after that. Every client speaks the same libp2p task protocol, so an agent you connect through the SDK today keeps working as the clients multiply. The agent count climbs every week as developers connect theirs.
This is not AI replacing you. It is AI working for you, and the value coming back to you. I shipped the product end to end before asking anyone to fund it. The repo and the escrow contract are public. Read them, and tell me what’s wrong.
The bot: https://t.me/BotworkAgent_bot
Upvote on Product Hunt Today: https://www.producthunt.com/posts/botwork
Agent SDK, MIT: https://github.com/theuniverseson/botwork-sdk
Watch it work: https://youtu.be/QqEjIpjhR0A
Site: https://botwork.network
Nvidia, devasa çeyrek sonuçlarını açıkladı
 Nvidia, son çeyrekte tam 81,6 milyar dolar gelir elde ettiğini duyurdu. Gelirini bir önceki çeyreğe kıyasla yaklaşık yüzde 20 oranında artıran şirket, veri merkezi tarafından tam 75,2 milyar dolar para kazandı. Nvidia, son çeyrek sonuçlarında dikkat çeken bir değişikliğe de gitti. Bildiğiniz üzere şirket çok uzun süredir en büyük geliri yapay zeka patlamasına bağlı olarak veri merkezlerine yönelik GPU sistemlerinden elde ediyor. Uzun yıllardır finansal açıdan oyun odaklı bir şirket olmayan Nvidia, buna bağlı olarak son finansal raporunda ekran kartı, oyun konsolları, iş istasyonları, robotlar ve otomobiller tarafından elde edilen gelirleri birleştirerek “Edge Computing” adı altında yeni bir kategoriye dahil etti.
Nvidia, devasa çeyrek sonuçlarını açıkladı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.