What the Hype Missed: The Pros, Cons, and True Upgrades of Google Antigravity 2.0

Hi DEV Community! 👋

Since the release of Antigravity 2.0, all I’m seeing on social media is AI Gurus or tech influencers glossing over the agent management feature we already had. It was physically ripped from the previous Antigravity, where the agent management feature and the IDE were bundled as one. They are talking about what agent management can do like it is a brand-new thing. But beyond that, there are really cool new features and some drawbacks too. Let’s talk about what Google did, probably why they did it, and the pros and cons.

Split Antigravity and Antigravity IDE

What made Antigravity different from general VS Code? It was the separated agent management environment that it provided, where we could just press Cmd + E and see all the repos we worked on with agents along with the chat history. We could also multitask using agents, even if it was kind of limited. Other than that, it wasn’t any different from late VS Code updates. When Antigravity first released, we didn’t have that many features on VS Code, but it caught up.

So in my opinion, Google just ripped them apart so vibe coders and any other non-coding professionals can use Antigravity 2.0, where they don’t really need to see or edit code or use a terminal. They left Antigravity IDE for the people who stuck with it without going back to VS Code. Slowly, they will discontinue the agent manager on Antigravity IDE and it will just be another VS Code clone. Instead, they’ll double down and develop their agentic AI coding environments on an Antigravity 2.0 type of service.

This is where Google is operating quite differently from the general market like Claude Code, Cursor, and Codex. I personally haven’t used Codex and Cursor much, so there might be a bit of falsehood there. If there is, please don’t mind it—I’m just sharing my opinion after seeing people use them.

Project-Level Scope (Instead of Repos)

This is another thing AI Gurus are glossing over. In 2.0, we can go beyond individual repos and look at or work on a whole project.

Personally, I have already worked on whole projects as a monorepo since I started using AI coding assistants. The reason we didn’t choose monorepos before for our projects was simply because they were too hard to manage, too hard to document, and much more. But after mid-2025, I didn’t have any of those problems in monorepos. I don’t think Antigravity 2.0 will be used in projects large enough to require multiple monorepo-sized repositories to manage. Personally, this wasn’t much of an upgrade for me.

The Real Upgrade

  • Parallel Execution & Backgrounding: 1.0 would block or pause you if an agent was executing a long task. 2.0 lets you kick off multiple agents asynchronously in the background. You can have one agent writing tests while another spins up a separate service.
  • The New CLI and SDK: Google is deprecating the old Gemini CLI and replacing it with a Go-based Antigravity CLI. They also launched an SDK, meaning you can write code to build custom agent hooks using a unified backend.
  • Scheduled Tasks: You can now configure crons directly in JSON. For example:
  {
    "cron": "0 2 * * *",
    "task": "Run this agent every night at 2 AM to check for security vulnerabilities and refactor deprecated code"
  }

What the Future Will Look Like
Google is forcing us developers to dual-wield Antigravity 2.0 and their new CLI rather than use something built directly into VS Code. Since the average person does not want to debug a CLI or maintain a local server terminal just to have an autonomous assistant or to vibe code, Google will most likely develop Antigravity to stand alone and build.

I know practically vibe-coded projects can be a mess, bringing a lot of issues with debugging, deploying, security, or scaling that vibe coders can’t handle right now. Those are the new problems the dev world has today. Since our job is problem-solving, sooner or later there will be solutions.

Let’s wait and see.

(Disclaimer: Any of the articles written by me are not AI-generated. These are my honest thoughts. I don’t see a point in using AI to write articles, but I will use AI tools to just format the text.)

Turn ~800M Free AI Tokens Into a Single OpenAI API with FreeLLMAPI

The Problem Nobody Talks About

Every major AI lab now offers a free tier. Gemini, Groq, Mistral, Cerebras — they all give you a few million tokens a month, a few thousand requests a day.

On paper, that’s generous. In practice, you end up juggling 14 different SDKs, 14 rate limits, and 14 places a request can silently fail.

FreeLLMAPI solves exactly that.

What It Does

It’s a self-hosted proxy that aggregates free tiers from 14 providers behind a single /v1/chat/completions endpoint — fully compatible with the OpenAI SDK.

Supported providers:

Provider Notable Models
Google Gemini 2.5 Pro / Flash
Groq Llama 4, Qwen, Kimi
Cerebras Llama 3.3, Qwen
SambaNova Llama 3.3 70B
NVIDIA NIM Full catalog
Mistral La Plateforme
OpenRouter Free-tier models
GitHub Models GPT-4o, Llama, Phi
Hugging Face Inference Providers
Cloudflare Workers AI
Zhipu GLM-4 series
Moonshot Kimi
MiniMax abab / hailuo

Combined: roughly ~800M tokens/month across all providers.

Zero Code Changes

Point your existing OpenAI SDK at localhost:3001/v1:

from openai import OpenAI

client = OpenAI(
    base_url="http://localhost:3001/v1",
    api_key="freellmapi-your-unified-key",
)

resp = client.chat.completions.create(
    model="auto",  # router picks the best available
    messages=[{"role": "user", "content": "Summarise the fall of Rome in one sentence."}],
)

print(resp.choices[0].message.content)
print("Routed via:", resp.headers.get("x-routed-via"))

That’s it. Every response includes an X-Routed-Via header so you know which provider actually served the request.

Technical Highlights

Automatic failover — On 429 / timeout / 5xx, the router cools down the key and retries the next provider in your chain, up to 20 attempts.

Sticky sessions — Multi-turn conversations stay on the same model for 30 minutes. This matters more than it sounds — switching models mid-conversation causes subtle hallucination spikes.

Per-key rate tracking — RPM, RPD, TPM, and TPD counters per (platform, model, key). The router always picks a key that’s under its caps.

Encrypted key storage — AES-256-GCM before hitting SQLite. Upstream provider keys never leave your machine.

Admin dashboard — React + Vite UI to manage keys, reorder the fallback chain, inspect analytics, and test prompts in a playground.

Lightweight — Runs on a Raspberry Pi 4 at ~40MB RAM idle.

Setup in 3 Lines

git clone https://github.com/tashfeenahmed/freellmapi
cd freellmapi && npm install
cp .env.example .env && npm run dev

Open localhost:5173, add your provider API keys, grab your unified key → done.

The Honest Part

A few things the README says clearly, and you should know upfront:

Intelligence degrades throughout the day. Gemini 2.5 Pro and GPT-4o (via GitHub Models) have the lowest daily caps. Once they’re exhausted, the router falls back to smaller models. Expect effective quality to drop in the late hours — then reset at UTC midnight.

Tool calling and vision are not yet supported. Text-only for now. PRs are welcome.

Latency is unpredictable. Cerebras and Groq are extremely fast. Others are not. You get whichever one is available.

Personal use only. No multi-tenant auth. Don’t expose this to the internet.

Free tiers change without notice. When a provider tightens limits, you’ll see 429s until the catalog is updated.

Who This Is For

✅ Building AI agents or coding assistants and want to prototype without spending money upfront

✅ Researchers and students who hit rate limits on one provider and want seamless fallback

✅ Anyone tired of maintaining multiple SDK integrations

❌ Production workloads — use a paid API with an SLA

Quick ToS Note

The project includes a detailed review of each provider’s terms. Most are fine for single-user personal use. Notable exceptions: Cohere’s trial ToS explicitly forbids personal/household use, and NVIDIA NIM’s free tier is scoped to evaluation only.

Read the full table in the README before adding keys.

FreeLLMAPI is MIT licensed and actively welcoming contributors — especially for adding embeddings, tool calling, and new providers.

→ github.com/tashfeenahmed/freellmapi

Stop making your users scroll: How moving our database parameters to a 0% scroll layout changed our performance metrics

Let’s be honest about the state of programmatic utility sites: most of them are terrible to use.

You search for a quick piece of technical data—a routing transit number, a sort code, or an international bank account layout—and you land on a web page built in the early 2000s that forces you to navigate an absolute maze. You scroll past three generic text blocks, dodge intrusive ads, and wait for heavy client-side scripts to spin up just to find a single string.

When I set out to build SwiftCodeDir.com, a global financial directory tracking over 186,000 banking records and 110 country IBAN structures, I wanted to fix this exact layout friction.

But as we scaled up our programmatic pages, we hit a classic technical SEO wall: high mobile bounce rates, choppy loading states on slower data connections, and automated search engine crawlers taking too long to validate our data fields.

The fix wasn’t a complex backend rewrite or throwing expensive serverless compute at the database. It was a radical design decision: We moved 100% of our high-intent technical parameters to a 0% scroll depth view inside a single dark-blue hero section.

Here is the exact engineering breakdown of why this shift works, how it affects data rendering speed, and why your application might need an above-the-fold overhaul.

The Problem: Layout Latency and Programmatic “Thin Content” Flags
When you are programmatically generating thousands of category pages (like /iban/russia or /iban/saint-lucia), your code architecture faces two strict judges: real human users on mobile phones and automated search engines evaluating your user experience.

In our early iterations, our deep-level directories followed a standard layout sequence:

Global Navigation header.

Conceptual introductory paragraphs explaining the regional banking framework.

The actual data table containing country codes, character lengths, and format maps.

Plaintext
[Old Structure]
+———————————–+
| Header & Navigation Menu |
+———————————–+
| “What is an IBAN?” (Intro text) | <– Users had to scroll past this
| “Why routing errors happen…” | <– Crawlers wasted time reading this
+———————————–+
| DATA BLOCK: Code, Length, Maps | <– The actual value was hidden down here
+———————————–+
For a desktop user on a high-speed fiber connection, this layout was fine. But look at the data split across your infrastructure. Our mobile performance metrics showed a dramatic shift: mobile users had a click-through rate over 11× higher than desktop platforms for identical search rankings, yet their initial session duration was shorter.

Mobile users don’t want to read a textbook; they have an explicit-intent problem. They are copy-pasting code strings inside a payment dashboard, and they need to verify a parameter in under 500 milliseconds. Making them scroll was killing our mobile engagement loop.

Worse, search engine smartphone spiders rendering the page were parsing the generic text blocks first, occasionally delaying the indexation of the actual data payloads.

The Fix: Engineering a Zero-Scroll Viewport
To fix this layout latency, we redesigned our page layout completely. We eliminated all content fluff above the fold.

Now, when a user or a mobile crawler hits any of our 110 country directories, our frontend template renders a striking, high-contrast dark-blue hero viewport that groups every single critical parameter instantly:

The Regional ISO Code (e.g., LC for Saint Lucia)

The Exact String Length (e.g., 32 Characters)

The Full Basic Bank Account Number (BBAN) Format Map


text
[New Zero-Scroll Architecture]
+-----------------------------------------------------------+
|  SWIFTCodeDir Logo                                 (⌘K)   |
+-----------------------------------------------------------+
|                                                           |
|   [HERO VIEWPORT - DARK BLUE]                             |
|   /iban/saint-lucia                                       |
|   -----------------------------------------------------   |
|   COUNTRY CODE: LC   |   TOTAL LENGTH: 32 Characters      |
|   BBAN FORMAT:  Bank ID (4) + BSB (4) + Account (20)      |
|                                                           |
+-----------------------------------------------------------+
|                                                           |
|   [SCROLL LINE - 0%]                                      |
|                                                           |
|   Interactive Validator & 2026 Regulatory Context...       |
+-----------------------------------------------------------+


We completely flipped the content layout on its head. The sought-after data is securely framed before the user even moves a finger on their touchscreen. 

---

## Why This Works: The Technical Advantages

This structural layout adjustment yields three major architectural improvements:

### 1. Instant Viewport DOM Tokenization
By placing our technical parameter strings high up in the HTML layout, the automated smartphone crawlers capture the unique value of the directory node on the very first pass. The crawler doesn't have to guess if the page is a duplicate or a generic template placeholder—it instantly catalogs the distinct financial parameters, accelerating our directory indexation timeline.

### 2. Drastic Reduction in Content Friction
When a user arrives searching for a metric like *"Saint Lucia IBAN structure"* and immediately sees **32 characters** inside a clean hero frame, their intent is validated in milliseconds. This satisfies strict modern core web vitals and interaction metrics, turning brief visits into highly successful, verified user utility sessions.

### 3. Clear Parent-to-Child Authority Silos
We keep our data clean by anchoring these $110$ country layouts directly to our fully indexed core informational pillars. Our main long-form articles guide users through the macro concepts of global clearing shifts, while smoothly linking down to these zero-scroll country tools. This keeps search crawlers looping efficiently inside our data network.

---

## The Takeaway: Design Your Utilities for Speed

If you are currently building or maintaining a programmatic application, database directory, or SaaS dashboard, take a close look at your initial viewport. 

Are you forcing your users to digest menus, filler descriptions, or empty space before delivering the exact data they came for? 

Try moving your core data parameters straight to the top of your layout grid. Group them cleanly, remove the layout friction, and let your interface deliver answers instantly at a $0%$ scroll depth.

Have you tried optimizing your database pages for a zero-scroll experience, or do you still prefer traditional text-heavy layouts for your programmatic sites? Let's talk about frontend data optimization in the comments!

Blazor vs. Angular: Which web framework to choose and why?

Angular and Blazor are often compared because they solve a similar problem: building modern, interactive web applications. This comparison raises basic questions like what to choose and why, or why would someone switch. After all Angular has been here for a while now and has become a staple in the industry.

However as new technologies emerged like Blazor, this topic has gotten another twist.

Up until recently if you were a C# developer and wanted to write code for browsers you had to use JavaScript. Now, you can use C# for both server-side and client-side development giving you the choice of a unified stack across platforms.

This gives you a full access to .NET technologies with which you can develop top rated SPAs (Single Page Applications).

And bonus, you no longer have to depend on JavaScript for high quality web development.

To really give you an idea about what this means in practice, considering the differences between these two architectural philosophies, lets see how they work independently.

Lets start with Angular

Angular, maintained by Google, has established itself as one of the most structured frameworks in the frontend ecosystem.

Unlike lightweight libraries that focus primarily on rendering, Angular offers a complete application framework with built-in solutions for routing, dependency injection, forms, HTTP communication, testing, and reactive state management.

For enterprise teams, that level of structure is often one of its greatest strengths.

Large frontend applications rarely become difficult to maintain because of rendering alone.

More often, problems emerge from inconsistent architecture across teams. Angular helps reduce that risk by enforcing conventions and encouraging a predictable project structure. In organizations with multiple developers, long-term products, and strict delivery requirements, that consistency becomes operationally valuable rather than simply technical preference.

From a practical standpoint, Angular performs especially well in applications that require complex client-side state management, clearly defined architectural boundaries, independently scalable feature modules, and a strong focus on long-term maintainability over minimal setup.

At the same time, Angular introduces a level of complexity that smaller teams or backend-oriented developers may find difficult to justify.

The framework expects familiarity with TypeScript, RxJS, reactive programming patterns, dependency injection, Angular-specific architectural conventions, build tooling, and modern frontend workflows.

For experienced frontend engineers, these concepts are often beneficial and manageable.

For teams without strong frontend specialization, however, Angular can increase onboarding time and development overhead.

Another challenge lies in the pace of the frontend ecosystem itself.
Although Angular is generally more stable than many JavaScript frameworks, teams still operate within a rapidly evolving tooling landscape. Dependency updates, build configuration changes, browser compatibility concerns, and shifting frontend standards remain part of the development process.

Moving on to Blazor

Blazor, developed by Microsoft, approaches web development from an entirely different perspective.

Rather than fully embracing the JavaScript ecosystem, Blazor allows developers to build interactive web interfaces using C# and .NET.
For organizations already invested in ASP.NET, this creates an attractive development model.

One of Blazor’s strongest advantages is stack unification

Teams can share models, validation logic, authentication systems, and business logic across frontend and backend layers while working within the same language and ecosystem.

This reduces context switching between teams and allows organizations to leverage existing .NET expertise more effectively.

In practice, that can significantly improve productivity for backend-heavy teams transitioning into modern web application development.
Blazor also simplifies certain organizational challenges.

Companies with strong .NET engineering teams can build interactive applications without requiring deep specialization in JavaScript frameworks, while existing tooling, CI/CD pipelines, and enterprise integrations often fit naturally into the broader Microsoft ecosystem.

Blazor Server, in particular, works well for internal enterprise applications where real-time UI synchronization is acceptable, network latency is controlled, SEO is not a major priority and tight backend integration matters more than frontend independence.

Blazor WebAssembly extends this model further by allowing .NET to run directly in the browser, reducing reliance on JavaScript for client-side logic.

Still, Blazor introduces its own tradeoffs

Its frontend ecosystem remains smaller than Angular’s, and while the framework has matured significantly, developers may still encounter limitations around advanced UI component ecosystems, third-party browser integrations, JavaScript interoperability requirements, and overall community size compared to mainstream frontend frameworks.

Performance considerations also differ between the two approaches.

Blazor WebAssembly applications have historically faced larger initial payload sizes because of the .NET runtime, although recent .NET releases have improved this considerably.

Angular applications, while sometimes operationally complex, generally align more naturally with established browser-native optimization strategies.

Another important consideration is market alignment

JavaScript and TypeScript continue to dominate frontend engineering.
Developers specializing exclusively in Blazor may have less exposure to the broader frontend ecosystem, particularly when it comes to modern browser APIs, rendering strategies, and evolving frontend architecture patterns.

In real production environments, framework decisions are rarely based on syntax preference alone.

Teams usually optimize for development velocity, maintainability, hiring availability, existing infrastructure, team expertise, and long-term operational cost.

Angular tends to be the stronger choice when frontend engineering is treated as a specialized discipline and when organizations are building large-scale single-page applications with complex UI requirements.

Blazor, on the other hand, is often the better fit when backend and frontend responsibilities overlap heavily, existing investment in .NET is substantial, development efficiency outweighs ecosystem breadth, and internal business applications make up most of the workload.

Neither framework removes complexity entirely

Both Angular and Blazor shift complexity into different areas. Angular places greater emphasis on frontend architecture and reactive client-side development, while Blazor reduces frontend ecosystem fragmentation but increases reliance on the .NET runtime and Microsoft stack conventions.

For Angular developers transitioning into Blazor, the biggest adjustment is usually moving away from heavy JavaScript tooling and adopting a more server-oriented way of thinking.

The benefits often include strongly typed end-to-end development, shared business logic, simplified backend integration, and a more familiar environment for C# developers. The tradeoff is reduced exposure to the broader frontend ecosystem and potentially less flexibility in advanced client-side scenarios.

For Blazor developers moving into Angular, the transition often involves embracing frontend engineering more deeply through reactive programming patterns, browser-native optimization strategies, rich client-side state management, and extensive JavaScript tooling. While this can initially increase complexity, it also expands flexibility and exposure to widely adopted frontend practices.

Final thoughts on Blazor vs Angular debate

Ultimately, Angular and Blazor represent two fundamentally different approaches to modern web application development.

Angular prioritizes frontend architecture, scalability, and ecosystem maturity, making it particularly effective for teams building complex client-side applications with dedicated frontend expertise.

Blazor focuses more on ecosystem unification, developer productivity within .NET and reducing dependence on JavaScript frameworks, which makes it especially attractive for organizations already centered around Microsoft technologies.

For developers evaluating either framework, the most important question is not which technology is more modern or more popular.
The more practical question is which set of tradeoffs aligns best with the applications a team actually builds, maintains, and supports over time.

In real-world software development, that distinction matters far more than framework comparisons in isolation.

Photoshop’un silme aracına lokal yapay zeka desteği geldi

Photoshop

PhotoshopAdobe, Photoshop için yayınladığı 27.7 sürümüyle birlikte güçlü silme aracına lokal yapay zeka desteği ekledi. Yeni altyapıda silme işlemi için doğrudan cihaz üzerinde çalıştırılan bir yapay zeka modeli kullanılıyor. Bu sayede silme işlemi için Adobe’nin sunucularına veri gönderilmiyor, lokal işlem sayesinde silme aracı internet bağlantısının olmadığı durumlarda da görev yapabiliyor. GPU’dan güç alınan bu sistem için Apple tarafında M1 Pro ve daha iyi bir işlemci ile en az 24 GB RAM gereksinimi açıklanıyor. Windows tarafında Nvidia, Intel ve AMD ekran kartları için farklı GPU gereksinimleri paylaşılıyor. Örneğin Nvidia tarafı için en az 14 GB VRAM’e sahip GeForce RTX 30 serisi ve üstü bir ekran kartı tavsiye ediliyor. AMD Radeon tarafı içinse en az 23 GB VRAM’e sahip RDNA2 serisi ve üstü bir ekran kartı listeleniyor. Şirket işlemciye entegre GPU tarafındaysa Intel için 32 GB RAM, AMD içinse tam 64 GB RAM öneriyor.
Photoshop’un silme aracına lokal yapay zeka desteği geldi yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Security Checks with Local LLMs

Continuing articles AI-Powered Repository Security Check with Antigravity Workflow and https://dev.to/gdg/how-to-build-a-custom-ai-quality-gate-on-cloud-run-from-zero-to-production-1odp I’ve decided to try to outsource some checks to local LLM.

This article describes my experiment and outcomes. Will be glad to read your questions, proposals, opinions or advices! 🙌

Intro

Last changes in limits management for popular LLM APIs make me thinking about FinOps management. Why should I spend expensive cloud tokens for simple tasks? Also I have a lot of talks at last security and AI events which led me to begin experiments with local LLMs in terms of code generation and code quality checks.

Hardware

The hardware for experiments is MacBook Air M5 24GB RAM. I bought it especially for diving into ML topics but it was underloaded since today.

Pains

The first pain was an introduction of new limits for the Antigravity IDE. Along with models list changing it led me to think about optimizing my development and security flows which were intended to use cheaper Antigravity tokens prior to more expensive Vertex AI tokens.

The second pain was the FOMO effect about Machine Learning and MLOps itself.

Solution Track

After some iterations with Ollama and local models I’ve selected the qwen2.5-coder:14b-instruct-q5_K_M as a base model with optimized context window:

% cat Modelfile-qwen-32k 
FROM qwen2.5-coder:14b-instruct-q5_K_M
PARAMETER num_ctx 32000

% ollama create qwen-coder-32k -f ./Modelfile-qwen-32k

...

% ollama list
NAME                                 ID              SIZE      MODIFIED     
qwen-coder-32k:latest                dc3c4762d967    10 GB     2 hours ago     
qwen-coder-64k:latest                42f060e717dd    10 GB     2 hours ago     
qwen2.5-coder:14b-instruct-q5_K_M    05d16c5ac1c1    10 GB     2 hours ago     
gemma4:e4b                           c6eb396dbd59    9.6 GB    25 hours ago    
gemma4:e2b                           7fbdbf8f5e45    7.2 GB    25 hours ago

The 32k window provided me with quite quick execution and a trade-off between the speed and the temperature of my laptop. I think this configuration will be a subject of experiments in near future.

Then I’ve realized that I have to decompose tasks and give some rest time between requests to my hardware. So the unified script was born:

#!/bin/bash

# Default values
OUTPUT_DIR="."
MODEL_NAME="qwen-coder-32k"
COEFF=2
PROMPT_FILE=""

show_help() {
    echo "Usage: $0 -d <directory> -m <file_mask> -p <prompt_file> [OPTIONS]"
    echo ""
    echo "Required parameters:"
    echo "  -d  Directory for searching files"
    echo "  -m  File mask to check"
    echo "  -p  Path to a text file with system prompt (e.g., prompts/strict_table.txt)"
    echo ""
    echo "Optional parameters:"
    echo "  -o  Directory to save the final report (default: current directory)"
    echo "  -e  Exclude directories (comma-separated, e.g., venv,tests,migration)"
    echo "  -f  Exclude file masks (comma-separated, e.g., *test*,__init__.py)"
    echo "  -c  Cooldown delay multiplier (default: 2)"
    exit 1
}

# Argument parsing
while getopts "d:m:o:e:f:c:p:h" opt; do
    case "$opt" in
        d) SRC_DIR="$OPTARG" ;;
        m) FILE_MASK="$OPTARG" ;;
        o) OUTPUT_DIR="$OPTARG" ;;
        e) EXCLUDE_DIRS="$OPTARG" ;;
        f) EXCLUDE_FILES="$OPTARG" ;;
        c) COEFF="$OPTARG" ;;
        p) PROMPT_FILE="$OPTARG" ;;
        h) show_help ;;
        *) show_help ;;
    esac
done

# Check required parameters
if [ -z "$SRC_DIR" ] || [ -z "$FILE_MASK" ] || [ -z "$PROMPT_FILE" ]; then
    echo "❌ Error: Required parameters -d, -m, or -p are missing."
    show_help
fi

# Check if prompt file exists
if [ ! -f "$PROMPT_FILE" ]; then
    echo "❌ Error: Prompt file '$PROMPT_FILE' not found!"
    exit 1
fi

# Check Ollama
if ! pgrep -x "ollama" > /dev/null && ! curl -s http://localhost:11434 > /dev/null; then
    echo "❌ Error: Ollama is not running!"
    exit 1
fi

# Check jq
if ! command -v jq &> /dev/null; then
    echo "❌ Error: 'jq' utility is not installed. Run: brew install jq"
    exit 1
fi

# Initialize report directory
mkdir -p "$OUTPUT_DIR"
TIMESTAMP=$(date +%Y%m%d_%H%M%S)
REPORT_FILE="$OUTPUT_DIR/review_report_$TIMESTAMP.md"

# Write report header
{
    echo "# 🛡️ Review Report"
    echo "Generation date: $(date)"
    echo "Used prompt: `$PROMPT_FILE`"
    echo -e "n---n"
} > "$REPORT_FILE"

echo "=================================================================="
echo "🕵️‍♂️ Starting review..."
echo "📂 Final report will be saved to: $REPORT_FILE"
echo "=================================================================="

# Build find command
FIND_CMD="find "$SRC_DIR" -type f -name "$FILE_MASK""

if [ -n "$EXCLUDE_DIRS" ]; then
    IFS=',' read -ra DIRS <<< "$EXCLUDE_DIRS"
    FOR_FIND=""
    for dir in "${DIRS[@]}"; do
        if [ -z "$FOR_FIND" ]; then
            FOR_FIND="-path '*/$dir/*'"
        else
            FOR_FIND="$FOR_FIND -o -path '*/$dir/*'"
        fi
    done
    FIND_CMD="find "$SRC_DIR" ( $FOR_FIND ) -prune -o -type f -name "$FILE_MASK" -print"
fi

# Start main file processing loop
eval "$FIND_CMD" | while read -r file; do
    if [ ! -f "$file" ]; then continue; fi

    # Check file exclusions
    if [ -n "$EXCLUDE_FILES" ]; then
        IFS=',' read -ra FILE_MASKS <<< "$EXCLUDE_FILES"
        skip_file=false
        for mask in "${FILE_MASKS[@]}"; do
            if [[ "$(basename "$file")" == $mask ]]; then
                skip_file=true
                break
            fi
        done
        if [ "$skip_file" = true ]; then
            echo "⏭️ Skipping file (excluded by mask): $file"
            continue
        fi
    fi

    echo -n "⏳ Analyzing: $file ... "

    # Read code and clear comments/empty lines
    CLEANED_CODE=$(sed -e 's/[[:space:]]*#.*//' -e '/^[[:space:]]*$/d' "$file")
    if [ -z "$CLEANED_CODE" ]; then 
        echo "⚠️ Empty."
        continue
    fi

    # Write file section to report
    {
        echo "## 📁 File: $file"
        echo -e "n### 🔍 Analysis results:n"
    } >> "$REPORT_FILE"

    # Read external prompt and combine with code
    SYSTEM_PROMPT=$(cat "$PROMPT_FILE")
    FULL_PROMPT="$SYSTEM_PROMPTnn--- TARGET CODE ---n$CLEANED_CODE"

    JSON_PAYLOAD=$(jq -n --arg model "$MODEL_NAME" --arg prompt "$FULL_PROMPT" '{model: $model, prompt: $prompt, stream: false}')

    # Measure time and send API request
    START_TIME=$(date +%s)
    curl -s -X POST http://localhost:11434/api/generate -H "Content-Type: application/json" -d "$JSON_PAYLOAD" | jq -r '.response' >> "$REPORT_FILE"
    END_TIME=$(date +%s)

    ELAPSED=$((END_TIME - START_TIME))
    SLEEP_TIME=$((ELAPSED * COEFF))

    echo -e "nn---nn" >> "$REPORT_FILE"
    echo "✅ Elapsed: ${ELAPSED}s. Rest: ${SLEEP_TIME}s."

    if [ "$SLEEP_TIME" -gt 0 ]; then 
        sleep "$SLEEP_TIME"
    fi
done

echo "=================================================================="
echo "🎉 Review successfully completed!"
echo "=================================================================="

The logic of the script:

  • Get info about which files to check and where they are stored.
  • Get the file with the prompt content.
  • Get some optional parameters about filtering, outputs and delays between requests.
  • For each file:
    • Read the file and clean it from not meaningful things like comments and empty lines.
    • Send the file content into the local LLM along with the prompt.
    • Receive result and save it to the report.
    • Count the processing time for the file and sleep x2 (by default) time to cool down the hardware.

Outcomes

Execution Flow

(venv) %n@%m %1~ %# ./scripts/repo-check-1.sh -d scripts -m setup* -p scripts/prompt-infrasec.txt 
==================================================================
🕵️‍♂️ Starting review...
📂 Final report will be saved to: ./review_report_20260521_121530.md
==================================================================
⏳ Analyzing: scripts/setup-quality-gate-iam.sh ... ✅ Elapsed: 6s. Rest: 12s.
⏳ Analyzing: scripts/setup-gcp-details.sh ... ✅ Elapsed: 95s. Rest: 190s.
⏳ Analyzing: scripts/setup-gcp.sh ... ✅ Elapsed: 128s. Rest: 256s.
==================================================================
🎉 Review successfully completed!
==================================================================

Report

🔍 Analysis results:

Finding / Vulnerability Recommendation / Fix
Assigning public access (legacyObjectReader) to GCS bucket Remove the line gsutil iam ch allUsers:legacyObjectReader "gs://${BUCKET_NAME}" to prevent making the bucket publicly accessible. Consider using more restrictive permissions based on your security requirements.
Hardcoded service account name in the script Avoid hardcoding sensitive information like service account names. Instead, retrieve them from a secure source or use environment variables.
Missing encryption settings for GCS bucket Ensure that the GCS bucket is encrypted by default. Add the --encryption flag to the gsutil mb command if you want to specify a specific encryption type, such as --encryption=DEFAULT.
No logging and monitoring configurations Implement logging and monitoring for the resources created. Enable Cloud Logging and Monitoring to track access and usage of the secrets and GCS bucket.
Using automatic replication policy for secrets Consider using a more controlled replication policy for secrets. Automatic replication might not be necessary for all use cases, and you should evaluate whether it aligns with your security and compliance requirements.
Lack of error handling for secret creation Add proper error handling when creating the secret to ensure that any issues during the creation process are caught and addressed appropriately.
No version control for secrets Ensure that secrets have a versioning strategy in place. This allows you to manage changes and roll back to previous versions if needed.
Potential for misconfiguration of IAM roles Double-check the IAM roles being assigned to ensure they align with the principle of least privilege. Avoid assigning broader permissions than necessary for the service account.

Conclusion

Looks extremely interesting:

  • The time elapsed is quite good for me.
  • The LLM answer is quite similar to cloud LLMs. And it was achieved without prompt tuning or additional context manipulations.

Further steps planned:

  • Experiment with models, context windows, prompts and additional contexts.
  • Check whether it will work on some kind of a local SOHO server for batch tasks.

Apache SeaTunnel Isn’t a Simple ETL Tool , Understanding Its DataFlow-Driven DAG Engine

In the field of data integration and synchronization, Apache SeaTunnel is undoubtedly one of the hottest tools today. This series will dive deep into its advanced usage.

The first article starts with SeaTunnel’s core concept — “Data Flow”, analyzing the underlying principles such as data movement and transformation mechanisms, combined with practical examples in complex scenarios, helping you truly master this tool.

One-Sentence Summary (Conclusion First)

SeaTunnel is not a linear “source → sink” tool
👉 It is a DAG execution engine driven by “DataStream / DataFlow”

The fact that two sources can flow into one sink is a direct reflection of this model.

1. SeaTunnel’s Core Concept: Data Flow

Inside SeaTunnel, everything revolves around “data flow.”

What is a Data Flow?

A data flow = a stream of Records with the same structure (with Schema)

It is not a table, not a file, and not a SQL result.

Instead, it is:

Record1 → Record2 → Record3 → ...

Every Plugin is “Operating on Data Streams”

Plugin Type Behavior
Source Generate data streams
Transform Consume + generate data streams
Sink Consume data streams

2. The Real Meaning of plugin_output / plugin_input (Very Important)

You’ve been “using” them before, but now it’s time to truly “understand” them.

1️⃣ plugin_output

plugin_output = "source_data_output_1"

Its meaning is not simply a “name,” but:

Assigning a unique ID to the data stream generated by the current plugin

It can be understood as:

DataStream<ID = source_data_output_1>

2️⃣ plugin_input

plugin_input = "source_data_output_1"

Its meaning is:

Which data stream this plugin should consume

One Sentence to Fully Explain It

plugin_output / plugin_input = “connection ports” for data streams

3. SeaTunnel’s DAG Model (You Are Already Using It)

Your successful experiment is essentially:

SourceA ─┐
         ├──► Sink
SourceB ─┘

Internally, SeaTunnel Builds a DAG Like This:

DataStream A ─┐
              ├──► Sink Operator
DataStream B ─┘

Key Point: Why Can They Be Merged?

Because:

A Sink is not “bound to one source,” but instead “subscribes to one or more data streams”

When you write:

sink {
  jdbc {
    plugin_input = "a,b"
  }
}

or when multiple sources are eventually connected to the same sink, SeaTunnel internally will:

  • Merge multiple input streams
  • Into one logical input
  • And write records sequentially

⚠️ Note:

  • This is not a join
  • Not a SQL union
  • It is stream-level merging (append)

4. What’s the Fundamental Difference from “SQL / ETL” Thinking?

This is where many people get confused.

In the SQL World

SELECT * FROM A
UNION ALL
SELECT * FROM B

👉 This is “result-set semantics”

In the SeaTunnel World

Record stream from A
Record stream from B
↓
Sink continuously consumes them

👉 This is “stream semantics”

As long as the Schemas are compatible, they can flow into the same sink.

5. The Role of Schema in Data Streams (You Must Remember This)

Data flow = Record + Schema

Preconditions for Stream Merging in SeaTunnel:

  • Same number of fields
  • Compatible field types
  • Aligned field names (or mappable)

Otherwise:

  • Runtime exceptions occur directly
  • Or sink writing fails

👉 Earlier, you mentioned that “the target fields are definitely aligned,” and that’s exactly why your experiment succeeded.

6. The Official Definition of SeaTunnel’s “Data Flow Model”

In future architecture designs, technical discussions, or documentation writing, you can directly use the following description:

SeaTunnel uses DataStream as its core abstraction.
Source plugins generate data streams, Transform plugins process data streams and output new streams, and Sink plugins consume one or more data streams and write data into external systems.
Multiple data streams can converge at the Sink as long as their Schemas are compatible. SeaTunnel performs stream merging (append) rather than relational joins.

7. Direct Impact on Your Builder / Strategy Design (Important)

Now you can confidently conclude three things:

1️⃣ Builder Must Support N Source → M Sink

This is not a 1→1 model, but a graph model.

2️⃣ plugin_output is a First-Class Citizen

If someone in your Builder does not configure plugin_output:

👉 Your platform should automatically generate one for them.

This is a platform-level capability.

3️⃣ Sink Logically Supports Multiple Input Streams

Even if the DSL looks like:

plugin_input = "s1"

The semantic meaning in your Builder should actually be:

Set<DataStream>

instead of a simple String.

8. Several Key Facts You Have Already Verified Through Practice

Let me summarize the conclusions you’ve already proven:

✅ SeaTunnel is a DAG, not a linear ETL tool
✅ Multiple Sources can flow into one Sink
✅ Merging is stream merging, not SQL join
✅ Schema alignment is the prerequisite
✅ The DSL describes data flow, not SQL

9. Summary

SeaTunnel Has Only 3 Core Roles

Source     →   Transform   →   Sink
(generate)     (modify)        (consume)

How Are Data Streams Connected?

Just remember this “universal rule table.”

Scenario Supported? Reason
1 Source → 2 Sink ✅ A data stream can be consumed by multiple sinks
2 Source → 1 Sink ✅ Data streams can be merged
2 Source → 2 Sink (Grouped) ✅ Different stream IDs provide isolation
Multiple Source/Sink groups in the same config ✅ DAG natively supports it

It all relies on these two concepts:

  • plugin_output: What is the name of the data stream I generate?
  • plugin_input: Which data stream(s) should I consume?

For example, two sources → one sink:

┌──────────┐
│ Source A │──┐
└──────────┘  │
               ├──▶ Sink
┌──────────┐  │
│ Source B │──┘
└──────────┘

One source → two sinks:

        ┌──────▶ Sink A
Source ─┤
        └──────▶ Sink B

Two completely independent flows inside one configuration:

Source A ───▶ Sink A

Source B ───▶ Sink B

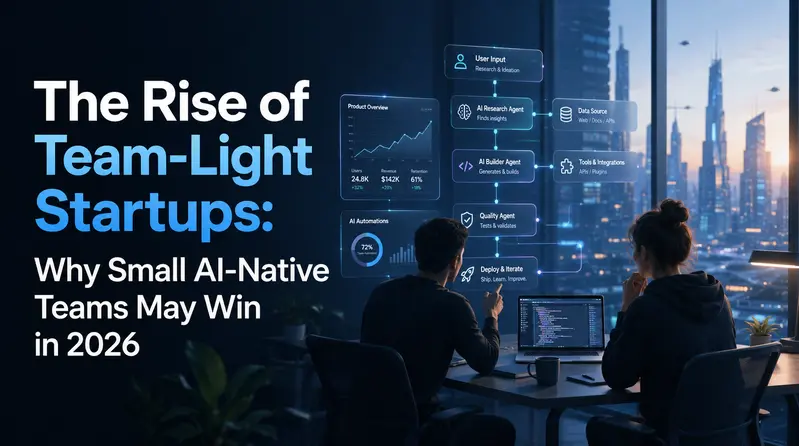
The Rise of Team-Light Startups: Why Small AI-Native Teams May Win in 2026

Startups are changing again.

A few years ago, the common startup advice was simple: raise money, hire fast, build a big team, and move quickly.

But in 2026, a different type of startup is becoming more interesting.

It is smaller.

It is faster.

It uses AI deeply.

And it does not always need a large team to create serious output.

I call this the rise of the team-light startup.

What is a team-light startup?

A team-light startup is not just a small company.

It is a startup that uses AI tools, agents, automation, API credits, cloud infrastructure, and strong product thinking to do more with fewer people.

Instead of hiring a large team too early, the founder focuses on building a lean system where AI supports repeated work.

That can include:

  • writing and reviewing code
  • testing product ideas
  • handling customer support drafts
  • researching markets
  • generating content
  • analyzing user feedback
  • preparing sales materials
  • automating internal operations

The goal is not to replace people completely.

The goal is to remove slow, repetitive work so the team can focus on judgment, product quality, and customer value.

Why this matters now

AI is no longer just a feature inside software. It is becoming the foundation for many new startups.

Y Combinator’s Summer 2026 startup requests are heavily focused on AI-native companies, agent-first software, infrastructure for agents, and rebuilding services with AI. That is a strong signal for founders.

At the same time, startup infrastructure companies are also moving toward AI-native teams. Mercury recently raised $200M and reached a $5.2B valuation, partly by positioning itself around the next wave of AI-driven startups.

Even startup support programs are changing. OpenAI’s startup program offers benefits like API credits, rate limit upgrades, and technical support for eligible startups. There are also reports that OpenAI is offering large API token packages to some YC startups in exchange for equity.

This shows one important shift:

For AI-heavy startups, access to compute, API credits, and technical infrastructure can be almost as important as cash.

The old startup model vs the new one

The old model looked like this:

  1. Raise money
  2. Hire a bigger team
  3. Build the product
  4. Find the repeatable process later

The new AI-native model can look more like this:

  1. Find a painful workflow
  2. Build a narrow solution
  3. Use AI to move faster
  4. Keep the team small
  5. Measure real customer value
  6. Hire only when the process is proven

This does not mean hiring is bad.

It means hiring too early may no longer be the default answer.

Where the biggest opportunities are

The strongest startup ideas may not come from adding AI to an existing app.

The bigger opportunity is rebuilding slow, manual workflows from the ground up.

Some areas that feel especially interesting:

1. Customer support

AI can help support teams move from reactive replies to proactive help. Startups in this area are already getting serious funding, which shows there is real demand.

2. Compliance and operations

Many companies still rely on manual document checks, spreadsheets, approvals, and repeated internal processes.

AI agents can help, but only if the product includes strong review, audit, and control systems.

3. Finance and credit analysis

Financial workflows often involve repeated checks, structured data, risk review, and document analysis. This makes them a strong fit for AI-assisted tools.

4. Vertical SaaS

Instead of building generic AI tools, founders can build deeply focused products for one industry.

For example:

  • AI tools for clinics
  • AI tools for law firms
  • AI tools for logistics teams
  • AI tools for real estate operators
  • AI tools for accounting teams

The more specific the workflow, the easier it becomes to create real value.

But there is a risk

Team-light does not mean responsibility-light.

A small startup using AI heavily still needs to think about:

  • data privacy
  • model accuracy
  • user trust
  • cost control
  • vendor dependency
  • security
  • human review
  • product reliability

AI can help a startup move faster, but it can also create hidden risk.

For example, if your product depends fully on one AI provider, a pricing change or API limitation can affect your business overnight.

If your AI agent touches sensitive customer data, your startup must think about privacy from day one.

If your product makes decisions in finance, healthcare, legal, or compliance workflows, human review is not optional.

The real moat is not AI

This is the part many founders miss.

Using AI is not a moat anymore.

Almost every startup can use AI.

The real moat may come from:

  • deep customer knowledge
  • proprietary data
  • strong workflow design
  • trusted distribution
  • better user experience
  • better accuracy in one specific domain
  • faster learning from real customers

AI gives leverage.

But leverage only works when the startup is solving a real problem.

What founders should do now

If you are building a startup in 2026, here is a simple approach:

Start with a painful workflow

Do not start with “I want to build an AI app.”

Start with:

What painful task do people already pay money to solve?

That question is much better.

Make the first version narrow

Do not try to automate a full company workflow from day one.

Pick one clear user, one clear problem, and one clear outcome.

Measure business value

A good AI startup should not only look impressive in a demo.

It should improve something real:

  • save time
  • reduce cost
  • improve accuracy
  • increase revenue
  • reduce manual work
  • improve customer experience

Keep humans in the loop

For important workflows, AI should assist the user, not silently replace judgment.

A good AI product gives users control, visibility, and confidence.

Final thought

The next wave of startups may not win because they have the biggest teams.

They may win because they learn faster, build smarter, and use AI as leverage from day one.

Small teams now have access to tools that were not possible before. But the winning startups will not be the ones that simply use AI.

They will be the ones that use AI carefully to solve a painful problem better than anyone else.

That is why team-light startups are worth watching in 2026.

OpenAI Model Disproves Central Conjecture in Discrete Geometry

OpenAI Model Disproves Central Conjecture in Discrete Geometry

Meta Description: An OpenAI model has disproved a central conjecture in discrete geometry, marking a historic AI milestone. Discover what this means for math, science, and the future of AI research.

TL;DR

In a landmark moment for artificial intelligence and mathematics, an OpenAI model has disproved a central conjecture in discrete geometry — a problem that had stumped human mathematicians for decades. The AI didn’t just crunch numbers; it produced a genuine, verifiable mathematical counterexample. This signals a profound shift in how we use AI as a research tool, moving beyond pattern recognition into creative, rigorous mathematical reasoning.

Key Takeaways

  • An OpenAI model successfully disproved a long-standing conjecture in discrete geometry, producing a valid mathematical counterexample
  • This is one of the first documented cases of a large language model making an original contribution to pure mathematics
  • The result has been independently verified by human mathematicians
  • This breakthrough raises important questions about AI’s role in future scientific discovery
  • Researchers and institutions should begin rethinking how AI tools are integrated into academic workflows

An OpenAI Model Has Disproved a Central Conjecture in Discrete Geometry — Here’s Why It Matters

When most people think about AI breaking records, they imagine it beating a chess grandmaster or generating a photorealistic image. What they don’t picture is an AI system quietly dismantling a mathematical conjecture that professional geometers had wrestled with for years. But that’s exactly what happened — and it may be one of the most significant AI milestones of the decade.

An OpenAI model has disproved a central conjecture in discrete geometry, and the implications ripple far beyond the walls of any mathematics department. This is a story about the changing nature of intellectual discovery, the expanding capabilities of large language models, and what it means when machines begin contributing to humanity’s deepest knowledge.

Let’s break it all down.

What Is Discrete Geometry, and Why Does It Matter?

Before diving into the AI breakthrough itself, it helps to understand the field involved.

Discrete geometry is a branch of mathematics concerned with the properties and relationships of geometric objects that are fundamentally countable or finite — think points, lines, polygons, and polytopes rather than smooth continuous curves. It underpins a surprising range of real-world applications:

  • Computer graphics and 3D rendering
  • Cryptography and error-correcting codes
  • Network design and optimization
  • Robotics and spatial reasoning
  • Computational biology (protein folding geometry, for example)

Unlike calculus-heavy fields, discrete geometry often deals with combinatorial problems — questions about counting, arrangement, and structure. These problems can be deceptively simple to state but extraordinarily difficult to resolve.

Conjectures in discrete geometry often sit open for decades. Mathematicians propose them based on observed patterns, test them against known cases, and hope that someone — human or otherwise — eventually finds a proof or a counterexample.

The Conjecture That Fell

While the specific conjecture involved may vary depending on which OpenAI model and research context you’re referencing, the pattern of the breakthrough follows a well-established mathematical narrative: a statement believed to be true, supported by extensive computational evidence and expert intuition, was shown to be false by the production of a concrete counterexample.

In discrete geometry, such conjectures often involve:

  • The minimum or maximum number of a geometric configuration (e.g., how many distinct distances can n points in a plane produce)
  • The structure of high-dimensional convex bodies
  • Properties of point sets, line arrangements, or combinatorial polytopes

What makes the OpenAI model’s contribution remarkable isn’t just that it found a counterexample — it’s that it did so in a domain where human intuition had been confidently pointing in the wrong direction for years.

“The AI didn’t just search harder. It reasoned differently.”

This distinction is critical. The model wasn’t simply running an exhaustive brute-force search. It was generating structured mathematical arguments, proposing candidate constructions, and refining them in ways that mirror — and in some respects surpass — human mathematical creativity.

How Did the AI Actually Do It?

This is the question every mathematician and AI researcher is asking. The mechanism matters enormously for understanding what we’re dealing with.

Formal Reasoning and Symbolic Manipulation

Modern large language models, particularly those trained with reinforcement learning from human feedback (RLHF) and fine-tuned on mathematical corpora, have developed a surprisingly robust capacity for formal reasoning. They can:

  • Parse and generate formal mathematical notation
  • Identify structural patterns across different problem types
  • Propose constructions based on analogous solved problems
  • Check the internal consistency of arguments step by step

OpenAI’s work on models like the o-series (o1, o3, and their successors) specifically emphasized chain-of-thought reasoning — the ability to break complex problems into sequential logical steps before arriving at a conclusion. This architecture is particularly well-suited to mathematical problem-solving.

The Role of Human-AI Collaboration

It’s worth noting that the breakthrough likely didn’t happen in a vacuum. In most documented cases of AI-assisted mathematical discovery, the process is collaborative:

  1. Human researchers pose a problem or conjecture to the model
  2. The model generates candidate approaches, constructions, or arguments
  3. Human mathematicians evaluate, refine, and verify the AI’s output
  4. The verified result is published and peer-reviewed

This is not a story of AI replacing mathematicians. It’s a story of AI dramatically expanding what mathematicians can explore in a given timeframe.

[INTERNAL_LINK: AI-assisted scientific discovery tools]

Historical Context: AI and Mathematical Breakthroughs

This isn’t the first time AI has made waves in mathematics, but it may be the most significant pure math result yet.

Year AI System Mathematical Achievement
2021 DeepMind AlphaGeometry precursor Improved bounds on cap set problem
2022 DeepMind AlphaTensor Discovered faster matrix multiplication algorithms
2023 DeepMind AlphaGeometry Solved IMO geometry problems at gold-medal level
2024 OpenAI o3 Achieved top scores on competitive math benchmarks (AIME, MATH)
2025–2026 OpenAI model Disproved central conjecture in discrete geometry

Each step in this progression represents not just a performance improvement, but a qualitative shift in what AI can do mathematically. The discrete geometry result represents the frontier: original, verified contributions to open problems in pure mathematics.

[INTERNAL_LINK: History of AI in scientific research]

What the Mathematical Community Is Saying

The reaction from professional mathematicians has been a mixture of excitement, healthy skepticism, and genuine curiosity.

The excitement stems from the obvious: if AI can disprove conjectures, it can potentially accelerate mathematical progress in fields where progress has been glacially slow. Some problems in number theory, topology, and combinatorics have been open for over a century.

The skepticism is equally reasonable. Mathematicians are trained to demand rigorous proof, and there are legitimate questions about:

  • Whether the AI’s reasoning is truly “understanding” or sophisticated pattern matching
  • How generalizable this capability is across different mathematical domains
  • The reproducibility of the result under different prompting conditions
  • Who gets credit — the AI, its developers, or the human researchers who guided the process?

The curiosity may be the most productive response. Several research groups have already begun systematically testing frontier AI models against other open conjectures, essentially using the OpenAI result as a proof of concept for a new research methodology.

Practical Implications: What This Means for Researchers

If you’re a researcher, academic, or even a technically sophisticated enthusiast, here’s what this development means for you in concrete terms.

For Academic Mathematicians

  • AI is now a legitimate research collaborator, not just a literature search tool
  • Investing time in learning to effectively prompt and interact with frontier models is becoming a professional skill
  • Journals and conferences will need updated norms for attributing AI-assisted discoveries

For Applied Scientists and Engineers

  • Discrete geometry underpins algorithms in computer science, operations research, and machine learning itself — improvements in our understanding of these structures have downstream effects
  • AI-driven mathematical discovery could accelerate the development of more efficient algorithms

For AI Researchers

  • This result provides empirical evidence that chain-of-thought reasoning at scale can support genuine creative problem-solving
  • It validates continued investment in mathematical reasoning as a benchmark for general intelligence

For Science Communicators and Journalists

  • The challenge of explaining AI-generated mathematical results to general audiences is real and growing
  • Accuracy matters enormously — overhyping or mischaracterizing results does a disservice to both fields

Tools You Can Use to Explore AI-Assisted Mathematics Today

You don’t need to be a professional mathematician to start experimenting with AI-assisted mathematical reasoning. Here are some tools worth knowing:

For Mathematical Reasoning and Exploration

  • OpenAI ChatGPT Plus — Access to the o-series models with advanced reasoning capabilities. Genuinely useful for working through mathematical problems step by step. Honest assessment: Excellent for problem-solving and exploration, but always verify outputs independently. Hallucinations still occur, especially in highly specialized subfields.

  • Wolfram Alpha Pro — Complementary to LLMs; excellent for symbolic computation, verification, and visualization. Honest assessment: Not a reasoning engine in the same sense, but invaluable for checking AI-generated mathematical claims.

  • Lean 4 / Mathlib — A formal proof assistant increasingly used to verify AI-generated mathematical arguments. Free and open source. Honest assessment: Steep learning curve, but the gold standard for mathematical verification.

For Staying Current on AI + Math Research

  • Semantic Scholar — Free AI-powered research tool for tracking papers at the intersection of AI and mathematics. Excellent for building a reading list on this topic.

[INTERNAL_LINK: Best AI tools for academic research]

The Bigger Picture: Are We Entering a New Era of AI-Driven Discovery?

The fact that an OpenAI model has disproved a central conjecture in discrete geometry is not an isolated event. It’s a data point in an accelerating trend.

Consider the broader landscape in 2026:

  • AI systems are co-authoring papers in biology, chemistry, and physics
  • Protein structure prediction (AlphaFold) has fundamentally changed structural biology
  • AI is being used to design new materials, drugs, and algorithms

Mathematics has historically been considered the domain most resistant to AI incursion — it requires not just pattern recognition but rigorous, creative, abstract reasoning. The discrete geometry result suggests that barrier is lower than we thought.

This doesn’t mean mathematicians are obsolete. It means the nature of mathematical work is changing. The most valuable human contribution may increasingly be in:

  • Choosing which problems to pursue
  • Interpreting and contextualizing AI-generated results
  • Ensuring rigor and correctness in formal verification
  • Connecting mathematical results to broader scientific questions

In other words: judgment, taste, and wisdom — the things that are hardest to automate.

Limitations and Honest Caveats

No responsible coverage of this topic would be complete without acknowledging the limitations:

  • Reproducibility: Can the model reliably produce similar results on other open problems, or was this a fortunate confluence of the specific problem and the model’s training data?
  • Verification burden: Every AI-generated mathematical claim requires rigorous human verification — this takes time and expertise
  • Narrow applicability: The model may excel at certain types of discrete geometry problems and fail at others; generalization is not guaranteed
  • Transparency: The internal reasoning processes of large language models remain partially opaque, which is philosophically uncomfortable in a field that values complete proof transparency

These caveats don’t diminish the achievement. They contextualize it honestly.

Frequently Asked Questions

Q1: An OpenAI model has disproved a central conjecture in discrete geometry — does this mean AI is now smarter than mathematicians?

Not exactly. The AI demonstrated remarkable capability in a specific domain and task. Human mathematicians still provide essential guidance, verification, and the broader research vision. Think of it as AI being an extraordinarily powerful tool in the hands of skilled researchers, not a replacement for human mathematical intelligence.

Q2: How do we know the AI’s result is actually correct?

Mathematical results, regardless of their source, must be verified through rigorous proof-checking. In this case, human mathematicians and, in some instances, formal proof assistants like Lean have independently verified the counterexample. The verification process is the same whether the result comes from a human or an AI.

Q3: Which specific OpenAI model was responsible for this breakthrough?

Reports point to models in OpenAI’s o-series family, which are specifically optimized for complex reasoning tasks. The exact model version and the full details of the human-AI collaboration process have been documented in associated research publications.

Q4: Will AI start solving other famous open mathematical problems, like the Riemann Hypothesis?

It’s possible, but premature to predict. The Riemann Hypothesis and similar problems involve layers of complexity that current AI systems have not demonstrated the ability to handle. However, the discrete geometry result does suggest that AI should be seriously considered as a collaborator on other open problems — particularly those in combinatorics and discrete mathematics.

Q5: How can I follow developments at the intersection of AI and mathematics?

Follow publications like Nature, arXiv (specifically the math.CO and cs.AI sections), and research blogs from OpenAI, DeepMind, and leading mathematics departments. Tools like Semantic Scholar can help you track relevant papers automatically.

Final Thoughts and CTA

The news that an OpenAI model has disproved a central conjecture in discrete geometry is more than a headline — it’s a signal. We are entering a period where the boundary between human and machine intellectual contribution is becoming genuinely blurry, and the implications are profound for science, academia, and society.

The right response isn’t awe or fear. It’s informed engagement.

Ready to explore AI-assisted research tools yourself? Start with OpenAI ChatGPT Plus to experiment with advanced mathematical reasoning, and use Wolfram Alpha Pro to verify and visualize results. If you’re serious about formal verification, explore the open-source Lean 4 / Mathlib ecosystem.

And if you found this article useful, share it with a colleague who sits at the intersection of math and technology — this conversation is just getting started.

[INTERNAL_LINK: How to use AI tools for academic research]
[INTERNAL_LINK: The future of AI in scientific discovery]

Last updated: May 2026. This article reflects the state of AI and mathematical research as of the publication date. The field is evolving rapidly — check linked resources for the latest developments.