
ShareBox: self-hosted file sharing with video streaming in pure PHP
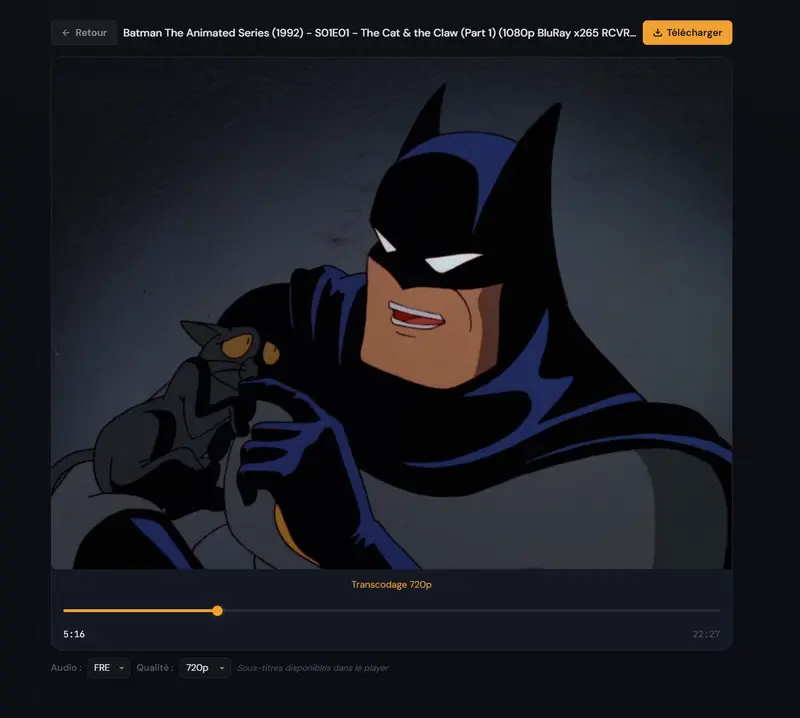
ShareBox integrated video player with seek, quality selection and WebVTT subtitle support

The need was straightforward: share large files — tens of gigabytes of raw footage, project archives, training videos — without going through a third-party cloud. No Google Drive, no WeTransfer, no Dropbox. A dedicated server, files you control, links that expire when you want them to. The result: ShareBox, a self-hosted file sharing platform with integrated video streaming, written in pure PHP 8.1 with no framework.

The repo is on GitHub.

Zero runtime dependencies

The first decision — and the most consequential — was to avoid any framework. No Symfony, no Laravel. Pure PHP, native stdlib, SQLite auto-created on first boot. Composer is present, but only as a dev dependency for PHPUnit. In production, no vendor/ directory is needed.

This constraint is clarifying. Every feature must justify its real implementation cost — not outsourced to a package that does ten times what you need. Manual routing in a few dozen lines, native PHP session handling, SQLite queries via PDO: these are things you implement once and understand completely.

SQLite followed the same logic — no server to configure, no complex migrations, the database file lives next to the code and backs up with a simple cp. For a single-instance tool, it’s more than enough.

The installer follows the same principle — a one-liner for Debian/Ubuntu:

curl -sSL https://raw.githubusercontent.com/ohugonnot/sharebox/main/install.sh | bash

A script that installs system dependencies, configures Apache or nginx, creates the SQLite database, and sets correct permissions. No Docker required, no registry to contact.

The real challenge: video streaming

Sharing a text file or a ZIP archive is trivial. Sharing a video and letting someone watch it directly in the browser — with seek, audio track selection, subtitles — is a different problem.

The first decision was to avoid systematic transcoding. If the file is already in a browser-compatible format (H.264/AAC in an MP4 or MKV container), we do a remux on the fly: repackage the existing streams without re-encoding. FFmpeg takes a few seconds, CPU usage is near zero, and quality is identical to the source.

Full transcoding only kicks in when necessary — typically for HEVC/x265 files, which very few browsers decode natively. In that case, FFmpeg transcodes to H.264 on the fly, with quality selection: 480p, 720p, or 1080p.

Seek in a live-transcoded stream is the trickiest part. A Range: bytes=... request on a classic HLS stream works because segments are pre-generated. Here, the stream is generated in real time — so seek means restarting FFmpeg with -ss at the right timecode, rather than seeking a byte offset in an already-generated file. The code orchestrating this in stream.php is worth reading if you’re tackling a similar problem.

ShareBox integrated video player with seek, quality selection and WebVTT subtitle support

The integrated video player: native seek, quality selection, WebVTT subtitles.

Human-readable slugs

A UUID to identify a share is secure but unusable by humans. Getting /dl/3f7a2c1d-8b4e-4f9a-b2d6-1c5e8f3a7b2c in an email is opaque. ShareBox generates slugs from the filename:

batman-begins-2005.mkv  →  /dl/batman-begins-2005-x7k2

The 4-character random suffix is enough to avoid collisions without sacrificing readability. batman-begins-2005-x7k2 tells you immediately what it contains, is easy to copy by hand, and survives a message or URL without issues.

Slug generation normalizes the string: accent transliteration, lowercase conversion, replacement of spaces and special characters with hyphens, removal of consecutive hyphens. The result is then checked against the database for uniqueness before insertion.

Security without a framework

A framework quietly handles a lot of security concerns — often without the developer being aware of it. Without a framework, these concerns must be addressed explicitly. Four stood out as needing careful attention.

Directory traversal. When serving files from disk, you have to ensure a parameter like ../../../etc/passwd doesn’t get through. The solution: realpath() on the resolved path, then verify the result is a subpath of the allowed upload directory. If the resolved path escapes the target directory, the request is rejected.

CSRF protection. The admin panel exposes destructive actions (file deletion, link revocation). Every POST form includes a CSRF token stored in session, regenerated after each sensitive action.

Session fixation. After authentication, session_regenerate_id(true) is called to invalidate the old session identifier and issue a new one. Without this, an attacker who knows the session ID of an unauthenticated visitor can reuse it after login.

Mail header injection. The email sharing form accepts a destination address. Without strict validation, an attacker can inject additional SMTP headers into the email field and hijack the outgoing message. All user inputs destined for mail headers are filtered to strip newlines before being passed to sending functions.

ShareBox admin panel with list of shared files, stats and management actions

The admin panel: share management, expiration, password protection.

Tests: what’s actually worth covering

44 PHPUnit tests, no mock framework, no external test dependency. The question wasn’t “how to test everything” — it was “what breaks silently if we don’t test it.”

Three categories stood out as particularly valuable:

Slugs. Slug generation is a pure function with many edge cases: names with accents, multiple spaces, Unicode characters, collisions, filenames without extensions. Thorough tests on this function are worth their weight in gold — it’s exactly the kind of code that looks trivial and breaks unexpectedly on real input.

Format detection. The logic deciding whether a video can be remuxed or must be transcoded relies on reading FFprobe metadata. Testing with FFprobe output fixtures for different codecs (H.264, HEVC, VP9, AV1) ensures the remux/transcode decision is correct without needing actual video files in the test suite.

Security. Directory traversal tests, header injection tests, and CSRF token validation tests are the most valuable. These are well-documented attack vectors, easy to test with known payloads, and missing an edge case has direct consequences.

ShareBox folder sharing view with file list and ZIP download button

Folder sharing: file browsing, one-click ZIP download.

Conclusion

The “zero runtime dependencies” philosophy isn’t a stance. It’s a commitment to understanding and maintaining what you build. Every line of code in ShareBox has an explicit reason to exist — no magic hidden in a third-party component whose source you’ve never read.

The concrete lesson from this project: PHP is capable of adaptive video streaming, seek in live transcoding, and correct security — with no framework whatsoever. The difficulty isn’t in the language; it’s in understanding what you’re building.

The code is available at github.com/ohugonnot/sharebox.

XSLT performance tuning without losing readability

Performance problems in XSLT are sneaky. The stylesheet looks clean, the output is correct, but the transform slows down as the input grows. Most of the time this is caused by expensive selections that are repeated in loops, or by deep // searches that scan the entire tree more often than you expect. The good news is that you can usually fix these issues without turning the stylesheet into unreadable micro-optimizations.

The first step is to examine where you are traversing the document. XSLT processors are optimized for template matching, so prefer xsl:apply-templates and specific match patterns over xsl:for-each with // in the select. When you do need a search, limit it to the smallest possible subtree. A single // at the top-level becomes a full-tree scan each time it runs. If it runs inside another loop, the cost can explode.

Keys are the most important performance feature, and they also improve readability. When you define an xsl:key, you turn a repeated search into a fast lookup. This is especially critical for join-like operations where you match a reference value to another document or a secondary section of the same document. Build the key once, and then use key('id', $value) everywhere. The intent becomes clear: you are doing a lookup, not a scan. If you only use keys occasionally, it can feel like overkill, but it is often the biggest win.

Modes are another useful tool. If you use the same templates in multiple contexts, you may end up doing extra work or firing templates that you do not need. A dedicated mode lets you create a focused processing pipeline that touches only the nodes relevant to that output section. This can reduce both runtime and mental overhead. It also makes it easier to reason about precedence: within a mode, you can define more specific templates without worrying about side effects on unrelated parts of the transform.

Consider caching computed values in variables. XSLT variables are immutable, so they are safe to reuse without unintended side effects. If you are computing a complex string or a filtered node set repeatedly, store it once per relevant scope. Just be careful not to define a variable at the top of the stylesheet if it depends on the context; keep it as close as possible to where it is used to avoid confusion.

If you are working in XSLT 2.0 or 3.0, you gain access to xsl:for-each-group and higher-order functions. These can be faster and clearer than manual grouping with keys. For XSLT 1.0, the Muenchian grouping pattern is still effective, and when combined with keys it remains a strong choice. Either way, focus on minimizing passes over large node sets.

Also consider the output method. Serializing large outputs can be a significant part of the runtime. If you do not need pretty-printed XML, avoid indentation to reduce the amount of whitespace and processing time. Similarly, if you are generating text or JSON, use method="text" or structured XSLT 3.0 serialization options rather than building a text string node by node.

I recommend using realistic test data when tuning performance. A transform that runs in 100 milliseconds on a tiny input may take seconds on real data. Use a handful of real documents and measure changes as you apply each improvement. This keeps the optimization process grounded and prevents you from making the code worse without a measurable gain.

Finally, keep a balance between speed and clarity. The fastest stylesheet is useless if it is too hard to maintain. Use a few consistent patterns: keys for lookups, modes for pipelines, variables for repeated values, and limited selection scope. With those in place, the performance usually becomes acceptable without heroics.

If you want a quick way to benchmark different approaches with the same input set, try the online editor at https://xsltplayground.com. It is a convenient place to experiment with keys, modes, and alternative match patterns while keeping your transform readable.

Build a Smart Sport Predictor with Data Science

Predicting the Game: Building a Smart Sport Prediction App with Data Science

The roar of the crowd, the tension of a close match, the unpredictable brilliance of athletes – sports capture our imagination like few other things. But beneath the surface of passion lies a rich tapestry of data, a goldmine for those seeking to forecast outcomes. A sport prediction app, powered by past data and the current form of teams, represents a fascinating intersection of data science, machine learning, and software engineering. This article delves into the technical journey of constructing such an application, exploring its architecture, data challenges, model selection, and practical implementation.

The Predictive Powerhouse: Core Components

At its heart, a sport prediction app aims to leverage historical performance metrics and real-time indicators to estimate the probability of various match outcomes (e.g., Home Win, Draw, Away Win, or specific scorelines). This process demands a robust data pipeline, sophisticated feature engineering, and carefully chosen machine learning models.

Data Acquisition & Preprocessing: The Foundation

The quality of predictions hinges entirely on the quality and breadth of the input data. For sports, this typically includes:

  • Match Results: Historical scores, dates, leagues, participating teams, and outcomes.
  • Team Statistics: Home/away win rates, average goals scored/conceded, clean sheets, disciplinary records (red/yellow cards), possession statistics.
  • Player Statistics: Individual goals, assists, injuries, suspensions, minutes played, form ratings.
  • Head-to-Head Records: Performance of two specific teams against each other.
  • Environmental Factors: Venue, weather conditions (less critical for indoor sports, but vital for outdoor ones).
  • Betting Odds: Historical pre-match odds can serve as a strong baseline predictor and an indicator of public/professional sentiment.

Sources: Dedicated sports data APIs (e.g., Sportradar, Opta, Football-Data.org) are ideal for reliable, structured data. Web scraping can supplement this, though it requires more maintenance.

Preprocessing: Raw data is rarely ready for model consumption. Key steps include:

  • Cleaning: Handling missing values (imputation, removal), correcting inconsistencies (e.g., team name variations).
  • Normalization/Scaling: Ensuring features are on a comparable scale, which is crucial for many ML algorithms.
  • Feature Engineering: This is where the magic truly begins.

Feature Engineering: Beyond Raw Numbers

Effective feature engineering transforms raw data into meaningful predictors. The goal is to capture the underlying dynamics that influence match outcomes.

Examples of powerful features:

  1. Recent Form: How has a team performed in its last N games?

    • HomeTeam_WinRate_Last5: (Wins in last 5 home/all games) / 5
    • AwayTeam_GoalDiff_Last3: Sum of (GoalsFor – GoalsAgainst) in last 3 away/all games.
    • Pseudocode: form_metric = (sum(wins) * 3 + sum(draws) * 1) / total_games_played (weighted points)
  2. Home/Away Advantage: Teams often perform better at their home ground.

    • HomeTeam_HomeWinRate: Win rate specifically for home matches.
    • AwayTeam_AwayWinRate: Win rate specifically for away matches.
  3. Head-to-Head Statistics: The historical rivalry between two specific teams.

    • H2H_HomeTeam_Wins_Against_AwayTeam: Number of times HomeTeam beat AwayTeam in past encounters.
  4. Elo Ratings: A common ranking system in competitive games, constantly updated based on win/loss against opponents of varying strengths. It’s a powerful dynamic feature.

    • Elo_Rating_HomeTeam_Difference: HomeTeam’s Elo rating minus AwayTeam’s Elo rating.
  5. Player Availability/Injuries: Presence or absence of key players can significantly shift probabilities. This requires more dynamic, often text-based, data processing.

  6. Tactical Consistency: Tracking manager changes, consistent formations.

These engineered features provide a richer context than raw match scores, allowing models to learn more nuanced patterns.

Machine Learning Models: The Prediction Engine

With well-engineered features, various supervised learning models can be employed. The task is typically a classification problem (predicting Home Win, Draw, Away Win) or a regression problem (predicting goal difference or exact scores).

Candidate Models:

  1. Logistic Regression: A good baseline for classification, providing probabilities for each outcome. It’s interpretable and computationally efficient.
  2. Random Forests: An ensemble method that builds multiple decision trees. It handles non-linear relationships, is robust to overfitting, and provides feature importance.
  3. Gradient Boosting Machines (XGBoost, LightGBM): Highly powerful and often top-performing algorithms in tabular data challenges. They build trees sequentially, correcting errors of previous trees, leading to strong predictive power.
  4. Support Vector Machines (SVMs): Effective for finding optimal hyperplanes to separate classes, though sometimes less interpretable.
  5. Neural Networks (e.g., Multi-layer Perceptrons): Can capture complex non-linear patterns, especially useful with a large number of features or when combined with embedding techniques for categorical data.

Model Selection & Evaluation:
Models are trained on historical data and evaluated using metrics like accuracy, precision, recall, F1-score, and ROC AUC for classification tasks. Cross-validation is crucial to ensure generalization performance. Often, an ensemble of multiple models (e.g., stacking or blending) can yield superior results by combining their strengths.

Building the App: From Model to User Interface

A predictive model is only valuable when integrated into an accessible application. This requires careful consideration of backend infrastructure, frontend design, and deployment strategy.

Backend Architecture: Serving Predictions

The backend serves as the brain of the operation, managing data, running models, and exposing predictions via an API.

  • Data Lake/Warehouse: A robust storage solution (e.g., PostgreSQL, MongoDB, or a cloud data warehouse like Snowflake) for storing vast amounts of historical match data, player stats, and processed features.
  • ETL Pipeline: Automated scripts (e.g., Python with Airflow or Prefect) to regularly extract new data, transform it into features, and load it into the prediction service. This pipeline also handles model retraining at scheduled intervals (e.g., daily, weekly).
  • Prediction Service: A microservice (e.g., built with Flask, FastAPI, or Node.js) that hosts the trained machine learning models. It receives requests (e.g., for an upcoming match), generates predictions, and returns them.
  • API Gateway: A RESTful API interface that allows frontend applications to query for predictions.
+----------------+     +------------------+     +--------------------+
| Data Sources   | --> | ETL Pipeline     | --> | Feature Store/     |
| (APIs, Scraping)|     | (Ingest, Clean, FE)|     | Data Warehouse     |
+----------------+     +------------------+     +--------------------+
                              |                          |
                              v                          v
                     +--------------------+     +--------------------+
                     | Model Training     | <--- | Historical Data    |
                     | (Scheduled)        |      | (for training)     |
                     +--------------------+      +--------------------+
                              |
                              v
                     +--------------------+
                     | Prediction Service | <---- Requests from API
                     | (Hosts ML Models)  |
                     +--------------------+
                              |
                              v
                     +--------------------+
                     | API Gateway        | <---- Frontend App
                     +--------------------+

Frontend Considerations: User Experience

The frontend is the user’s window into the predictions. It needs to be intuitive, responsive, and capable of visualizing complex data clearly.

  • Platform Choice: Cross-platform frameworks like Flutter or React Native are excellent for developing mobile apps that run on both iOS and Android from a single codebase. Web applications (React, Angular, Vue.js) offer broader accessibility.
  • UI/UX Design:
    • Clear Prediction Display: Show predicted outcomes with confidence scores (e.g., “Home Win: 65%”, “Draw: 20%”, “Away Win: 15%”).
    • Insights & Rationale: Where possible, provide insights into why a prediction was made (e.g., “Home team has strong recent form,” “Away team’s key striker is injured”). This often involves leveraging model interpretability techniques (e.g., SHAP values).
    • Historical Performance: Allow users to review past predictions and their accuracy.
    • Interactive Visualizations: Graphs showing team form over time, head-to-head performance comparisons, or player statistics.

Deployment and Scalability

Deploying such an application requires a cloud-based infrastructure (AWS, GCP, Azure). Services like EC2/Compute Engine for VMs, S3/Cloud Storage for data, RDS/Cloud SQL for databases, and Kubernetes for container orchestration provide the necessary scalability and reliability. Monitoring tools are essential to track application performance, data pipeline health, and model drift.

Challenges and Considerations

Building a sports prediction app is not without its hurdles:

  • Data Quality and Availability: GIGO (Garbage In, Garbage Out) is paramount. Missing or inaccurate data will directly degrade prediction accuracy. Sourcing comprehensive and reliable data can be expensive.
  • Overfitting: Models can become too specialized to the training data, failing to generalize to new, unseen matches. Robust validation techniques are crucial.
  • Dynamic Nature of Sports: Player injuries, manager changes, psychological factors, and unexpected events (e.g., controversial referee decisions) are difficult to quantify and can drastically alter outcomes in ways not easily captured by historical data. Models need frequent retraining and updates to reflect current realities.
  • Ethical Considerations: Such apps border on gambling tools. Developers must be mindful of promoting responsible use and clearly state that predictions are statistical probabilities, not guarantees.
  • Feature Creep: The temptation to add an ever-increasing number of features can complicate models without necessarily improving accuracy. A balance must be struck between complexity and predictive power.

Real-World Applications & Future Enhancements

Beyond direct match prediction, the underlying technology has broader applications:

  • Fantasy Sports Optimization: Providing insights for drafting players and managing teams.
  • Sports Betting Analytics: Offering data-driven insights to inform betting strategies (with appropriate disclaimers).
  • Team Performance Analysis: Helping sports analysts and coaches identify strengths, weaknesses, and potential opponents’ strategies.
  • Live Prediction Updates: Integrating real-time match events to dynamically update probabilities during a game.
  • Advanced Player Tracking: Combining prediction models with computer vision techniques to analyze player movements and actions in real-time, potentially predicting immediate game flow (a sophisticated extension of concepts like “counting exercise repetitions using camera”).
  • Sentiment Analysis: Leveraging NLP to analyze sports news and social media for sentiment around teams and players, integrating qualitative data.

Conclusion

Building a sport prediction app is an exciting venture into the world of data science and machine learning. It demands a systematic approach to data acquisition, rigorous feature engineering, thoughtful model selection, and robust application architecture. While challenges like data quality and the inherent unpredictability of human performance persist, the power of data-driven insights offers a compelling advantage over purely subjective predictions. As data sources become richer and ML models more sophisticated, these applications will continue to evolve, offering increasingly accurate and nuanced perspectives on the beautiful game and beyond. The future of sports analysis is undeniably intelligent, data-powered, and predictive.

Tekirdağ En İyi Oto Expertiz Firmaları – 2026

Tekirdağ’da güvenilir oto ekspertiz hizmeti almak isteyenler için 2026 yılının öne çıkan firmalarını bir araya getirdik. Araç satın almadan önce detaylı kontrol yaptırabileceğiniz en iyi ekspertiz merkezlerini bu listede bulabilirsiniz.

Como Usar Qwen 3.7 Grátis?

Qwen 3.7

A Alibaba lançou o Qwen 3.7 discretamente. Os modelos de prévia Qwen3.7-Max-Preview e Qwen3.7-Plus-Preview apareceram primeiro em uma arena pública de modelos em 14 de maio de 2026, sem post oficial e sem API pública. A confirmação veio no Alibaba Cloud Summit em Hangzhou, em 20 de maio. Se você quer testar o modelo sem pagar, o ponto prático é separar acesso realmente gratuito de testes pagos com rótulo “free”.

Experimente o Apidog hoje

Este guia mostra as formas confirmadas de usar o Qwen 3.7 sem custo em maio de 2026. Para cada caminho, veja o que dá para fazer, quais são os limites e quando vale a pena usar.

💡 Se você pretende integrar o modelo em um app, uma ferramenta como o Apidog ajuda a enviar a requisição, inspecionar respostas em streaming e salvar chamadas antes de levar para produção. Se ainda está avaliando o modelo, veja também o guia sobre o que é o Qwen 3.7, com arquitetura e benchmarks.

TL;DR

Em maio de 2026, o Qwen 3.7 ainda está em prévia. O acesso gratuito real está limitado a:

  1. Qwen Chat (chat.qwen.ai): conta gratuita, modelos de prévia disponíveis e limites de taxa.
  2. Arenas públicas de modelos: testes A/B cegos para comparar respostas e votar.
  3. Créditos de API da Alibaba Cloud: teste por tempo limitado para novas contas, não uma camada gratuita permanente.

O que não existe hoje para o Qwen 3.7:

  • pesos abertos para rodar localmente;
  • execução via Ollama ou LM Studio;
  • camada gratuita no OpenRouter;
  • endpoint público gratuito em agregadores.

Essas opções existem ou existiram para versões anteriores, como Qwen 3.6, mas não para o Qwen 3.7 neste momento.

O que o Qwen 3.7 é

Antes de escolher um caminho de acesso, confirme qual modelo você está testando.

O Qwen 3.7 foi apresentado em duas variantes de prévia:

  • Qwen3.7-Max-Preview: modelo principal, voltado para tarefas longas de agente.
  • Qwen3.7-Plus-Preview: variante menor e mais equilibrada, voltada para raciocínio e codificação com menor custo.

Segundo a Alibaba, o Qwen3.7-Max-Preview sustentou uma tarefa única por cerca de 35 horas e realizou mais de 1.000 chamadas de ferramentas em testes internos. Ambos os modelos têm janela de contexto de 1 milhão de tokens e, durante a prévia, operam apenas no modo de pensamento. Pesquisa na web e interpretador de código estão desativados por enquanto.

Qwen 3.7

O detalhe mais importante: o Qwen3.7-Max-Preview é proprietário. Os pesos não são públicos e a Alibaba não divulgou a contagem de parâmetros. A Alibaba afirmou que a variante Plus será open source, mas, em maio de 2026, nenhum peso do Qwen 3.7 foi lançado.

Portanto, se um tutorial diz para “baixar o Qwen 3.7” e rodar localmente, provavelmente ele está confundindo o modelo com o Qwen 3.6 ou antecipando um lançamento que ainda não ocorreu.

Caminho 1: Qwen Chat

A forma gratuita mais direta de usar o Qwen 3.7 é o app oficial em chat.qwen.ai.

Como usar

  1. Acesse chat.qwen.ai.
  2. Entre como convidado para um teste rápido ou crie uma conta gratuita.
  3. Faça login com Google, GitHub, Apple ou e-mail para obter limites maiores e histórico salvo.
  4. Abra o seletor de modelos.
  5. Escolha Qwen3.7-Max-Preview ou Qwen3.7-Plus-Preview.
  6. Use o modo de pensamento, que durante a prévia é o modo principal disponível.

O que dá para testar

Você pode usar o Qwen Chat para:

  • refatorar funções;
  • revisar código;
  • explicar erros;
  • resumir documentos;
  • analisar imagens;
  • testar prompts longos;
  • comparar raciocínio com outros modelos.

Exemplo de prompt prático para desenvolvedores:

Refatore esta função JavaScript para reduzir complexidade ciclomática.
Explique as mudanças e aponte possíveis efeitos colaterais.

[código aqui]

Outro exemplo:

Analise este contrato de API e identifique inconsistências entre nomes de campos,
tipos esperados e possíveis erros de validação.

[cole o schema ou documentação aqui]

Limites

Há duas limitações principais:

  1. Ferramentas desativadas

    Pesquisa na web e interpretador de código não estão ativos nos modelos de prévia. O modelo não navega em tempo real nem executa código em sandbox.

  2. Limites de taxa

    O Qwen Chat não publica números exatos. Uso intenso pode atingir limite. Conta logada tem mais margem que sessão de convidado, mas nenhuma opção é ilimitada.

Quando usar

Use o Qwen Chat se você quer avaliar qualidade sem escrever integração. É o melhor ponto de partida para desenvolvedores, estudantes, escritores técnicos e equipes comparando modelos.

Se depois você quiser chamar o modelo via código, veja o guia sobre como usar a API do Qwen 3.7.

Caminho 2: arenas públicas de modelos

O Qwen 3.7 apareceu publicamente em placares de arenas antes de ter API pública. Nessas plataformas, você envia um prompt, recebe duas respostas anônimas e vota na melhor.

Como testar

O fluxo típico é:

  1. Abra uma arena pública de modelos.
  2. Escolha o modo “battle” ou comparação lado a lado.
  3. Envie um prompt.
  4. Compare as duas respostas.
  5. Vote na melhor.
  6. Em alguns casos, veja quais modelos responderam depois da votação.

Em modo cego, você não escolhe o modelo. Isso reduz viés, mas também impede garantir que uma resposta específica veio do Qwen 3.7.

Algumas arenas também oferecem modo direto, em que você seleciona um modelo nomeado. Qwen3.7-Max-Preview e Qwen3.7-Plus-Preview apareceram como opções selecionáveis.

Bons prompts para comparar modelos

Use prompts que revelem diferenças práticas:

Explique este bug de concorrência em Go e proponha uma correção segura.

[código aqui]
Escreva um plano de migração de uma API REST para uma arquitetura orientada a eventos.
Inclua riscos, etapas e critérios de rollback.
Compare duas abordagens para cache em uma API Node.js:
Redis compartilhado vs cache local em memória.
Inclua trade-offs operacionais.

Limites

A arena é boa para avaliação, não para produção.

Você não terá:

  • API;
  • upload de arquivos;
  • histórico confiável;
  • controle total do modelo;
  • throughput previsível.

Além disso, em modo cego, uma resposta pode ou não vir do Qwen 3.7.

Quando usar

Use arenas para comparação direta. É útil se você quer saber como o Qwen 3.7 se comporta contra outros modelos de ponta em prompts reais.

Para uma comparação estruturada, veja Qwen 3.7 vs GPT-5.5 vs Opus 4.7.

Caminho 3: execução local com Ollama ou LM Studio

Este caminho ainda não está disponível para o Qwen 3.7.

Por que não funciona

Para rodar um modelo localmente, você precisa dos pesos. Esses arquivos contêm os parâmetros treinados do modelo.

No caso do Qwen 3.7:

  • Qwen3.7-Max-Preview é proprietário;
  • a Alibaba não liberou seus pesos;
  • Qwen3.7-Plus foi prometido como open source;
  • em maio de 2026, nenhum peso do Qwen 3.7 foi publicado.

Logo, não há nada para baixar e nada para carregar no Ollama ou no LM Studio.

Se você encontrar um comando como este:

ollama run qwen3.7

verifique o nome real do modelo. É muito provável que o tutorial esteja apontando para Qwen 3.6 ou para outro modelo da família Qwen.

O que usar localmente hoje

Se você precisa de inferência local, offline e sem custo de API, use a geração anterior. O Qwen 3.6 tem pesos abertos, incluindo:

  • modelo denso de 27B;
  • variante mixture-of-experts de 35B;
  • licença Apache 2.0.

Você pode baixá-los pelo Hugging Face e rodar via Ollama ou LM Studio.

O caminho prático é:

  • quer especificamente Qwen 3.7? Use Qwen Chat.
  • quer um modelo Qwen local e gratuito hoje? Use Qwen 3.6.
  • quer Qwen 3.7 local? Aguarde os pesos do Qwen3.7-Plus.

Quando usar

Execução local é ideal para:

  • requisitos fortes de privacidade;
  • protótipos offline;
  • ambientes sem dependência de API;
  • controle total sobre dados;
  • custo zero por token.

Mas, por enquanto, esse caso é atendido pelo Qwen 3.6, não pelo Qwen 3.7.

Caminho 4: agregadores de API

Agregadores como OpenRouter permitem chamar vários modelos com uma única chave de API. Alguns modelos ficam disponíveis em camadas gratuitas. Para o Qwen 3.7, essa opção ainda não existe.

Estado atual

Em maio de 2026:

  • o OpenRouter lista vários modelos Qwen;
  • as entradas mais recentes param na geração Qwen 3.6;
  • não há Qwen3.7-Max;
  • não há Qwen3.7-Plus;
  • não há endpoint gratuito do Qwen 3.7.

Outros agregadores estão na mesma situação. Uma listagem de terceiros só deve aparecer depois que a API oficial estiver ativa.

O que dá para fazer agora

Você pode construir seu protótipo usando um modelo Qwen mais antigo e deixar o ID do modelo configurável.

Exemplo simples em JavaScript:

const model = process.env.MODEL_ID || "qwen/qwen-3.6";

const response = await fetch("https://api.exemplo.com/v1/chat/completions", {
  method: "POST",
  headers: {
    "Authorization": `Bearer ${process.env.API_KEY}`,
    "Content-Type": "application/json"
  },
  body: JSON.stringify({
    model,
    messages: [
      {
        role: "user",
        content: "Explique este erro e sugira uma correção."
      }
    ]
  })
});

Quando o Qwen 3.7 for listado, você troca apenas a variável:

MODEL_ID=qwen/qwen-3.7-plus-preview

Isso evita acoplar o código a um modelo específico antes da disponibilidade real.

Atenção com camadas gratuitas

Camadas gratuitas em agregadores podem ter:

  • logs de prompts e respostas;
  • capacidade compartilhada;
  • latência variável;
  • limites de taxa;
  • regras diferentes para uso comercial.

Não envie dados confidenciais por endpoints gratuitos sem revisar os termos.

Quando usar

Use agregadores se você quer alternar entre modelos facilmente e prototipar com baixo custo. Para Qwen 3.7, esse caminho é “aguarde”, não “use agora”.

Caminho 5: créditos gratuitos da Alibaba Cloud

A última rota é o teste com créditos para novas contas no Alibaba Cloud Model Studio, plataforma que hospeda a API oficial do Qwen.

O que são esses créditos

Provedores de nuvem normalmente oferecem créditos iniciais ou um bloco de tokens gratuitos para novas contas. Quando a API pública do Qwen 3.7 estiver disponível após o summit, esses créditos deverão poder ser usados para chamadas reais.

Isso permite testar a API sem cobrança imediata.

Mas há uma diferença importante:

Créditos gratuitos não são uma camada gratuita permanente.

Eles expiram. O limite acaba. Depois disso, passam a valer os preços padrão.

A geração estável do Qwen 3.6 já é cobrada por milhão de tokens na mesma plataforma. O preço do Qwen 3.7 deve ser anunciado quando a API estiver disponível.

Como usar de forma segura

Para evitar surpresa de custo:

  1. Crie uma conta separada para teste.
  2. Verifique a validade dos créditos.
  3. Defina alertas de billing.
  4. Defina limites de uso, se a plataforma permitir.
  5. Teste com prompts pequenos antes de enviar contexto longo.
  6. Registre tokens de entrada e saída.
  7. Só depois integre em um fluxo automatizado.

Exemplo de checklist para testes de API:

[ ] Endpoint confirmado
[ ] Modelo correto selecionado
[ ] Chave de API em variável de ambiente
[ ] Timeout configurado
[ ] Retry com backoff
[ ] Logging sem dados sensíveis
[ ] Limite de custo configurado
[ ] Teste com payload mínimo
[ ] Teste com payload real

Quando usar

Use créditos se você já está pronto para escrever integração real e aceita migrar para uso pago caso o modelo funcione bem.

Não use essa opção se seu requisito é custo zero permanente.

A mesma lógica vale para outros provedores. Veja também o guia sobre como usar o Gemini 3.5 gratuitamente.

Comparação dos caminhos gratuitos do Qwen 3.7

Caminho Realmente gratuito? O que você obtém Principais limites Melhor para
Qwen Chat (chat.qwen.ai) Sim Modelo de prévia completo, UI de chat, imagem e documento Limites de taxa; ferramentas desativadas Avaliar o modelo sem código
Arenas públicas Sim Comparação cega ou nomeada em caixa de chat Sem API, sem arquivos, throughput compartilhado Comparar modelos diretamente
Ollama ou LM Studio Não para 3.7 Nada ainda; não há pesos do Qwen 3.7 Pesos não publicados Use Qwen 3.6 localmente
OpenRouter e agregadores Não para 3.7 Nenhum modelo Qwen 3.7 listado Sem API pública disponível Aguarde ou use modelos Qwen anteriores
Créditos Alibaba Cloud Teste temporário Chamadas reais de API dentro do crédito Créditos expiram; depois é pago Testar integração oficial

Decisão rápida

Use esta regra:

Quero testar a qualidade do Qwen 3.7 sem código
→ Qwen Chat

Quero comparar contra outros modelos
→ Arena pública

Quero rodar localmente
→ Não dá com Qwen 3.7; use Qwen 3.6

Quero API gratuita permanente
→ Não existe para Qwen 3.7

Quero testar a API oficial sem custo imediato
→ Créditos Alibaba Cloud, com limite e expiração

Conclusão

O acesso gratuito ao Qwen 3.7 ainda é limitado porque o modelo está em prévia.

O resumo prático:

  • Qwen Chat é o melhor caminho gratuito agora. Use conta gratuita, escolha Qwen3.7-Max-Preview ou Qwen3.7-Plus-Preview e avalie o modelo com prompts reais.
  • Arenas públicas são úteis para comparação. Elas não substituem API, mas ajudam a comparar respostas sem cadastro.
  • Você não pode rodar Qwen 3.7 localmente. Nenhum peso do Qwen 3.7 foi publicado.
  • Não há camada gratuita de API em agregadores. OpenRouter e similares ainda não listam Qwen 3.7.
  • Créditos da Alibaba Cloud são teste, não gratuidade permanente. Use para validar integração, mas acompanhe custos.

Quando a API do Qwen 3.7 estiver totalmente pública, as opções devem aumentar. Até lá, comece pelo Qwen Chat. Se for avançar para API, teste as chamadas no Apidog: envie a requisição, inspecione a resposta, salve como caso reutilizável e gere documentação para sua equipe. Você também pode baixar o Apidog gratuitamente.

I turned my daily job hunt into a semi-automated workflow in Cursor.

Every morning used to look the same: scroll LinkedIn alerts -> open a JD -> tailor my resume -> Easy Apply or an external form -> repeat. Lots of context-switching, easy to miss steps, and hard to track what I already applied to.

So I documented the whole process in a resume + application workspace:

What the agent does

  • Scans today’s LinkedIn job listings (Browser MCP)
  • Saves each JD and scores fit against my base resume
  • Tailors a truthful, JD-aligned resume (no invented experience)
  • Exports a PDF and pre-fills Easy Apply / external forms

What I still do

  • Review the tailored resume and fit score
  • Answer role-specific questions
  • Click Submit (by design – I stay in control)

What’s in the repo

  • base-resume.md — single source of truth
  • RUNBOOK.md — step-by-step daily batch
  • jobs/<company-role>/ — JD, analysis, tailored resume, PDF
  • applications.csv + queue — no duplicate applies
  • Cursor rules so tailoring stays consistent every run

One prompt to start the day:

Run today's job application batch per RUNBOOK.md

It’s not “auto-apply everything.” It’s prep at machine speed, decisions at human speed – which is how I want to job search as a PM.

If you’re job hunting with Cursor, I’d start with a runbook + a base resume + a hard rule: never submit without you.