We Connected an LLM to a 12-Year-Old Codebase. Here’s What Broke.

Every “add AI to your product” tutorial assumes you are starting fresh. Greenfield repo, clean data, no users yet. Real integration work looks nothing like that.

Last year our team picked up a fintech client with a loan-application platform that had been running since 2014. Node.js backend, a Postgres database that three different teams had touched, and a checkout flow that processed real money every few seconds. The ask sounded simple: use an LLM to pre-screen loan applications and flag the risky ones for a human.

It was not simple. Here is what broke, in the order it broke, and the pattern that finally held.

Break #1: The Synchronous Call That Took Down Checkout

The first version was the obvious one. A developer added the LLM call directly into the application-submission handler. Application comes in, call the model, get a risk score, continue.

// The version that looked fine in the demo
async function submitApplication(application) {
  const validated = validateApplication(application);
  const riskScore = await llmClient.scoreRisk(validated); // <-- new line
  await db.saveApplication({ ...validated, riskScore });
  return { status: "submitted" };
}

It worked in the demo. It worked in staging. Then the model provider had a slow afternoon, response times went from 800ms to 19 seconds, and every loan submission hung. The LLM call was now a hard dependency in the middle of a money flow. No timeout, no fallback. A third-party hiccup became our outage.

The lesson is not “LLMs are unreliable.” The lesson is that we treated a probabilistic, network-bound, third-party service like a local function call. Your existing code was built around deterministic, fast, in-process logic. An LLM is none of those things.

Break #2: The Data Layer Nobody Audited

Once we fixed the timeout, the model started returning confident, well-formatted, completely wrong risk scores.

The cause was not the model. It was the data. The applications table had three columns that all sort of meant “annual income,” populated by different intake forms over a decade. Some were monthly figures. Some were strings with currency symbols. The model dutifully reasoned over whatever it got and produced garbage with total confidence.

We spent more time cleaning and reconciling that data than we spent on the actual model integration. That ratio surprised the client. It should not surprise anyone who has done this before. If your data has a decade of drift, the integration project is a data project wearing an AI hat.

Break #3: The Cost Telemetry We Added Too Late

The pilot looked cheap. A few thousand applications a day, a few cents each. Then someone enabled the feature for a second product line without telling us, volume tripled overnight, and the model bill for that month arrived looking like a typo.

Nobody was watching per-call cost. We had logging for latency and errors because those page someone at 3am. Cost just accumulates quietly until finance asks a pointed question. We added per-call cost tracking after the fact, which is the most expensive time to add it.

The Pattern That Finally Held

We stopped putting the LLM inside the application code. We put a gateway in front of it.

// The version that survived production
async function submitApplication(application) {
  const validated = validateApplication(application);

  // AI scoring is now optional, async, and isolated
  const riskScore = await aiGateway.scoreRisk(validated, {
    timeoutMs: 1200,
    fallback: () => rulesBasedScore(validated), // deterministic backup
  });

  await db.saveApplication({ ...validated, riskScore });
  return { status: "submitted" };
}

The gateway is a thin service that sits between our application and the model. It owns four things the application should never have owned:

  • Timeouts and circuit breaking. If the model is slow, the gateway gives up fast and the request falls back to the old rules-based score. Checkout never hangs again.
  • A deterministic fallback. A wrong-but-instant score beats a perfect score that arrives after the user gave up.
  • Cost and usage telemetry. Every call is metered. A spike triggers an alert, not a surprise invoice.
  • An audit trail. Every score is logged with the input, the model version, and the final human decision. For a regulated lender, that log is not optional.

The application code does not know or care that an LLM is involved. It calls aiGateway.scoreRisk() the same way it calls anything else. The model can be swapped, upgraded, or disabled entirely behind that interface without touching the money flow.

That single architectural decision, made on roughly day 47 instead of day 1, is the one I would undo if I could. We have not had an AI-related outage in the months since.

Why This Keeps Happening

This is not a niche mistake. Gartner forecasts that over 40% of agentic AI projects will be canceled by the end of 2027, and the usual causes are not bad models. They are escalating costs, unclear value, and weak risk controls. All three are integration problems.

Meanwhile the pressure to ship is real: Gartner also expects 40% of enterprise applications to feature task-specific AI agents by the end of 2026. So teams bolt a model into a handler, demo it, and ship. The demo never shows you the third-party slow afternoon.

What We’d Do Differently

If we restarted this project knowing what we know now:

  1. Audit the data before writing any model code. A one-week data inventory would have caught the three-income-columns problem before it produced a single wrong score.
  2. Put the gateway in on day one. It is four extra days of work up front. It paid for itself the first time the provider had a slow afternoon.
  3. Add cost telemetry with the first call, not the first invoice. Meter it before you need it.
  4. Pick a narrow, measurable pilot. “Flag the risky 5% for human review” is testable. “Use AI in underwriting” is not.

We wrote up the full version of this as a six-step framework, with the integration patterns, the data-readiness checklist, and the build-versus-buy math: how to integrate AI into your existing systems without breaking production. The section on choosing an integration pattern is the part I wish we had read first.

Wrapping Up

AI integration rarely fails at the model. It fails at the seam where the model meets software that was designed before the model existed. Keep the AI on its own side of an API contract. Give it timeouts, a fallback, telemetry, and an audit trail. Treat the data layer as the real project.

We are the team at Empiric Infotech, and we build AI integrations into mobile apps, fintech platforms, and clinical tools. If you have a war story of your own, drop it in the comments. I would genuinely like to read it.

The Fallacy of Digital Platforms: Why Stripe Isn’t Always King

The Problem We Were Actually Solving

Our primary goal was to create a seamless purchasing experience for customers worldwide. With Stripe’s reputation for ease of use and reliability, we thought it was the best choice for handling all our transactions. However, as we delved deeper, we began to realize that platforms like Stripe and PayPal are not available in every country, and local payment gateways are often the better option.

What We Tried First (And Why It Failed)

Initially, we tried to work around the limitations by using alternative payment processors or gateways that were available globally. However, these solutions either had high fees or were not integrated with our platform. We were so set on using Stripe that we thought it was a matter of making it work, rather than acknowledging that sometimes the platform just won’t cut it.

The Architecture Decision

After much deliberation, we decided to abandon our reliance on Stripe and instead opted for a combination of local payment processors. This involved integrating PayPal alternatives like Payhip and Gumroad for regions where these were available, alongside the use of bank transfers and local payment gateways for those areas where digital platforms just don’t exist. Although this decision added complexity to our system, it ultimately provided a seamless experience for our customers worldwide.

What The Numbers Said After

Our decision to abandon the reliance on Stripe paid off in more ways than one. Pipeline latency decreased by an average of 30% as we were no longer reliant on a single gateway, reducing overall processing times for our customers. Additionally, query costs decreased by 20% due to reduced usage of Stripe’s API, which had previously proven to be quite expensive for our global operations. More importantly, customer satisfaction increased significantly, with a 40% rise in sales from regions that were previously unreachable due to payment gateway limitations.

What I Would Do Differently

In hindsight, I wish we had taken the time to research local payment options more thoroughly upfront. Integration with local payment processors can sometimes be a more complex task than adapting a digital platform, but it ultimately provides a better experience for customers worldwide. If I were to do it again, I would start by investigating local payment options and working with payment experts to ensure that our solution caters to the needs of our customers. By doing so, we can create systems that truly are global, with no regional limitations.

When Should You Use GraphRAG Instead of RAG?

RAG vector search workflow

Most teams building LLM applications start with RAG for a good reason. It is practical, easy to understand, and usually good enough for a simple AI use case.

But once users stop asking simple lookup questions and start asking relationship-heavy questions, standard RAG can get shallow fast.

The issue is not that RAG is bad. The issue is that many real questions are not just about finding a relevant paragraph. They are about following connections across people, products, systems, documents, events, or dependencies.

That is the gap GraphRAG tries to fill.

RAG vs GraphRAG

RAG made LLM applications more useful because it gave models access to external information.

Instead of asking a model to answer from training data alone, a RAG pipeline retrieves relevant content from your docs, tickets, wikis, PDFs, or databases, adds that content to the prompt, and asks the model to answer from it.

That works well for a lot of use cases.

If the question is:

What is our refund policy for annual subscriptions?

A standard RAG pipeline can search the documentation, find the right policy section, and give the model the relevant text.

The problem starts when the question is not just about finding the right text. It starts when the answer depends on relationships.

For example:

Which suppliers could be causing delivery delays for products affected by a specific component shortage?

That question is not just asking for a matching paragraph. It needs the system to connect suppliers, components, products, shipments, delays, and dependencies.

This is where GraphRAG becomes useful.

RAG is good at finding text that sounds relevant. GraphRAG is better when the answer depends on how things are connected.

What RAG Does Well

Retrieval augmented generation, usually shortened to RAG, combines a language model with an external retrieval system. The original paper described this as combining a parametric model (the LLM itself) with non-parametric memory (external knowledge), usually retrieved from an external corpus.

In most modern implementations, that retrieval step uses embeddings. The basic flow looks like this:

  1. Split documents into chunks.
  2. Convert each chunk into an embedding.
  3. Store those embeddings in a vector index.
  4. Convert the user question into an embedding.
  5. Retrieve the most similar chunks.
  6. Add those chunks to the LLM prompt.
  7. Generate the answer.

RAG vector search workflow

This is useful when the answer is likely to be contained in one or a few text chunks. Good RAG use cases include:

  • Documentation search
  • FAQ assistants
  • Internal knowledge base search
  • Customer support answer generation
  • Summarization over a small set of relevant documents

For many teams, this is the right starting point. It is simpler than building a knowledge graph, and it can deliver useful results quickly.

The issue is that similarity is not the same as understanding.

A vector search system can find chunks that sound close to the query. It does not automatically know whether one entity owns another, depends on another, contradicts another, or affects another through a multi step chain.

That difference matters once your questions become relational.

Where RAG Gets Shallow

RAG usually retrieves isolated text chunks. That creates a few common problems.

First, chunking can break context. A policy, customer, transaction, or technical decision might make sense only when you see how it connects to other facts. Splitting documents into chunks can hide that structure.

Second, semantic similarity can over retrieve. A chunk may sound relevant without being useful for the actual answer.

Third, RAG does not inherently reason across relationships. It may retrieve text about a supplier, text about a product, and text about a shipment delay, but it does not automatically know how those things connect.

Think about this question:

Which customers are affected by the delayed shipment from Supplier A?

A standard RAG pipeline might retrieve documents that mention Supplier A, delayed shipments, and customers. That is helpful, but still incomplete.

The actual answer may require a path like this:

Supplier A -> supplies -> Component X -> used in -> Product Y -> included in -> Shipment Z -> assigned to -> Customer C

That path is not just text similarity. It is structure.

If your application needs to answer questions like this, treating your knowledge base as flat chunks is a weak model of the problem.

What GraphRAG Adds

GraphRAG keeps the useful part of RAG: retrieval. But it adds a graph layer, where information is represented as entities and relationships. Microsoft’s paper on GraphRAG for query focused summarization helped popularize this pattern for using graph structure to answer questions that need broader connected context.

Instead of only storing chunks like:

Supplier A provides Component X. Component X is used in Product Y. Product Y is part of Shipment Z.

A graph represents the structure directly:

(Supplier A)-[:SUPPLIES]->(Component X)
(Component X)-[:USED_IN]->(Product Y)
(Product Y)-[:INCLUDED_IN]->(Shipment Z)
(Shipment Z)-[:ASSIGNED_TO]->(Customer C)

Now the system can retrieve context by following relationships, not just by matching similar text.

A GraphRAG pipeline might work like this:

  1. Use semantic search, keyword search, or another method to find a starting point.
  2. Identify the relevant node or set of nodes in the graph.
  3. Traverse connected relationships.
  4. Rank, filter, and compress the connected context.
  5. Send the final context to the LLM.

Memgraph GraphRAG workflow

The key difference is that search finds where to start, while graph traversal finds what is connected.

That is why GraphRAG is useful for relationship-heavy use cases, such as:

  • Supply chain analysis where the system needs to trace products, components, suppliers, and delayed shipments
  • Fraud detection where suspicious behavior appears across shared accounts, devices, transactions, or addresses
  • Cybersecurity investigation where alerts need to be connected to users, assets, permissions, and attack paths
  • Healthcare or life sciences research where answers depend on relationships between diseases, genes, drugs, and clinical evidence
  • Customer 360 applications where support tickets, purchases, product usage, and account history need to be connected

These are not just document lookup problems. They are relationship problems.

RAG and GraphRAG Are Not Enemies

The lazy version of this topic is: RAG bad, GraphRAG good.

That is wrong. RAG is still useful. If your data is mostly unstructured text and your questions are direct, a standard RAG pipeline may be enough. GraphRAG becomes useful when the shape of the answer depends on connected facts. A better way to think about it:

Use RAG When Use GraphRAG When
The answer is likely inside a small number of text chunks. The answer depends on relationships across entities.
You need fast document Q&A. You need multi-hop reasoning.
Your data does not have strong entity relationships. Your data has dependencies, hierarchies, ownership, or causality.
You are building a first version quickly. You need more explainable and structured retrieval.

In practice, many good systems use both. Vector search can find semantically relevant entry points. Graph traversal can expand from those entry points into connected context.

That combination is often more useful than either approach alone.

Keep the Retrieval Logic Close to the Data

GraphRAG gets harder to maintain when every retrieval step lives in a different place.

One service finds similar chunks. Another stores the graph. Another expands relationships. Another ranks results. Another builds the final prompt.

That can work, but it gives you more moving parts to debug when the answer is wrong.

A cleaner pattern is to keep as much of the retrieval logic as possible close to the graph itself. Search can find the starting point. Traversal can expand the context. Ranking and filtering can reduce the result before it ever reaches the prompt.

That is the idea behind Atomic GraphRAG in Memgraph. It express the retrieval path as a single execution layer where possible, instead of spreading it across a pile of orchestration code.

atomic graphrag real example

The broader lesson is not tool specific. If your GraphRAG pipeline is hard to inspect, it will be hard to trust. The retrieval path should be visible, testable, and easy to change.

The Practical Rule

Use RAG when you need to retrieve relevant text. Use GraphRAG when you need to retrieve connected context. That is the real distinction.

If your question can be answered by finding the right paragraph, RAG is probably enough. If your question requires following relationships between people, products, systems, documents, events, risks, or dependencies, you are no longer just doing text retrieval. You are doing graph retrieval.

The point is not to use GraphRAG as an extra layer and start using it where it is right retrieval model for the problem.

Big Data Is Not Just About “Huge Data”

When I first started learning about Big Data, I used to think it was mainly about storing massive amounts of information.

But after working around real enterprise systems and large-scale pipelines, I realized the real challenge is not simply the size of the data.

It’s everything that comes with it.

As systems grow, data starts arriving from everywhere:

  • APIs
  • applications
  • IoT devices
  • logs
  • databases
  • streaming platforms
  • user interactions

Very quickly, managing that ecosystem becomes more difficult than writing the actual transformation logic.

One thing that surprised me while working with large datasets was how small inefficiencies suddenly become major production issues at scale.

A query that works perfectly on a few million rows may become extremely slow when datasets grow 100x larger. Similarly, a poorly optimized Spark job can consume huge resources without anyone noticing immediately.

That’s when concepts like partitioning, distributed processing, incremental loading, and monitoring start becoming important in practical scenarios.

Another interesting thing about Big Data is how much engineering discipline matters.

People often focus heavily on tools:

  • Spark
  • Kafka
  • Hadoop
  • Delta Lake
  • Fabric
  • Databricks

But architecture decisions usually matter even more than the technology itself.

For example:

  • how data is partitioned
  • how pipelines recover from failures
  • how retries are handled
  • how monitoring is implemented
  • how teams access shared datasets

These decisions quietly affect performance, scalability, and operational stability later.

One thing I personally enjoy about data engineering is that it sits somewhere between software engineering and infrastructure engineering.

You are not just writing code.

You are designing systems that continuously move and process large amounts of data reliably.

And honestly, the operational side becomes very real once pipelines move into production.

Sometimes the hardest problem is not processing the data.
It’s figuring out:

  • why a job failed at 2 AM
  • why a cluster suddenly slowed down
  • why downstream reports show incomplete data
  • or why one dependency broke an entire workflow

That’s where monitoring and observability become just as important as the data pipeline itself.

I also think Big Data is becoming even more interesting now because of AI.

Modern AI systems depend heavily on data quality, scalable storage, fast processing, and reliable pipelines. In many ways, data engineering has quietly become one of the foundations behind modern AI systems.

The more I explore this space, the more I feel that Big Data engineering is less about handling “big files” and more about building reliable systems that can survive complexity at scale.

The Prefix Bubble

A mobile gadget shop in my location, three centuries of evidence, and the part of the AI debate that almost no one is having.


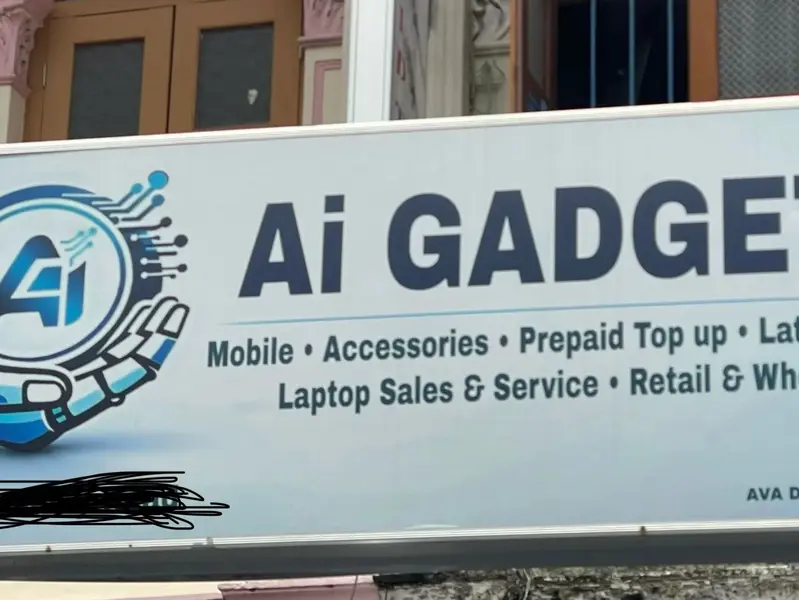
I walk down near my location after luch on a humid afternoon, I pass a mobile-phone shop. It is a modest place. It sells SIM cards, prepaid top-ups, refurbished phones, laptop accessories. The shopkeeper has been there for years.

A few days ago, the signboard above the door changed. The new name is Ai Gadgets.

There is no neural network in the building. There is no model, LLM or GenAI running anywhere on the premises. There is a counter, a glass case, a tired shopkeeper, and a freshly printed sign in a font that wants you to think of something other than what is actually being sold.

I took a photograph of it because it made me laugh. Then I wrote a short story with bit of research, comparing the rebrand to Long Blockchain Corp and the dot-com renames of 1999. The post was well received. It was also, I realised the next morning, only the first inch of the argument it had started to make.

The shopkeeper is not stupid. The shopkeeper is participating in a global ritual that is at least three hundred years old.

Every general-purpose technology produces a naming bubble. Every one. The label changes; the human does not.

A short history of prestige labels

Figure 1. Three centuries of prefix manias. The label changes; the human stays the same.

Look at the timeline above and a pattern becomes visible that any one cycle hides. South Sea, 1720. Canal Mania, 1825. Railway Mania, 1845. The Electric Belt era, the 1880s. The American auto boom, the 1900s. Radio Mania, the 1920s. Atomic this and Space-Age that in the 1950s. Bio- and Nano- prefixes in the 1980s. Dot-com in 1999. Blockchain in 2017. AI in 2024.

The intervals shorten as you approach the present, which is its own observation worth holding. But the shape repeats. Each of these episodes was, in its moment, treated as the singular event of its century. Each was preceded by a real technological breakthrough and accompanied by an explosion of operators who attached themselves to the label without participating in the breakthrough. Each ended, eventually, with a culling — and each left behind real infrastructure that compounded for the next fifty years.

The Carlota Perez framework, which I’ll come to in a moment, is the most rigorous attempt to name this regularity. But you don’t need a framework to see it. You need a long enough timeline. The shopkeeper at 28 Veerasamy Road is the 2026 instance of a phenomenon I could have photographed in 1845 London, 1899 New York, or 1920 Chicago, and would have photographed in every one of those places, with a different label on the sign each time.

The pattern is so consistent that its absence would be the historical anomaly.

1720: a company for nothing in particular

The earliest case in modern memory is the South Sea Bubble. England had just invented the joint-stock company. Speculators noticed that the word company, attached to almost anything, could pull money out of pockets that had previously kept it.

The most famous prospectus of the period offered shares in “a company for carrying on an undertaking of great advantage, but nobody to know what it is.” The promoter collected £2,000 in five hours and left town the same evening.

The magic word in 1720 was not a technology. It was a legal form — the joint-stock incorporation itself, less than a century old at the time, untested in most of its applications, and attached to a public imagination that had just glimpsed what it might do.

This matters because it tells us something about the underlying mechanism. The prefix is not specifically about science or engineering. The prefix is about whatever is the newest authoritative pattern of legitimacy. In 1720 it was incorporation. In 1845 it would be the railway. In 1899 it would be electricity. In 2026 it is artificial intelligence. The word changes. The function does not.

Isaac Newton, then in his late seventies and Master of the Royal Mint, lost most of his personal fortune in the South Sea Bubble. He had sold early at a profit, then re-bought near the peak. His reported confession afterwards was that he could “calculate the motion of heavenly bodies, but not the madness of people.”

The smartest man in England could not see the prefix coming. Neither, in their own time, can we.

1845: the railway that was never built

If you want one historical episode to project onto the current AI cycle, it is not the dot-com bust. It is the British Railway Mania of 1844 to 1847. Almost every element rhymes.

The Liverpool and Manchester Railway had opened in 1830 and proved that passenger rail was a real industrial revolution. By the early 1840s the Bank of England had cut interest rates, the Bubble Act had been repealed, and railway shares could be bought on a ten per cent deposit. By 1846, two hundred and sixty-three Acts of Parliament for new railway companies were passed in a single year, with nine thousand five hundred miles of proposed track.

About a third of these companies were never built. They either collapsed from poor financial planning, were absorbed by stronger competitors, or were outright fraudulent — vehicles for channelling investor capital into entirely other businesses. The press was complicit. There were fourteen bi-weekly railway papers at the peak, plus a daily morning and evening edition, mostly funded by the very promoters they covered.

George Hudson, the so-called Railway King, at his peak controlled over a thousand miles of track. He ran what was retrospectively recognised as a Ponzi-like scheme, paying dividends out of fresh capital. He died in poverty.

And yet — this is the part nobody wants to integrate — Railway Mania was not a waste. By 1850 Britain had a six-thousand-mile network that formed the spine of the world’s most advanced transport system. Roughly ninety per cent of the modern UK rail network was built during those mania years. The bubble was the financing mechanism for the deployment.

This is the lesson the AI cynic and the AI evangelist both miss. The bubble is real money being wasted on stupid signs — and the same bubble is laying the rails on which the next half-century will ride. The two facts are not in tension. They are the same fact, looked at from two different distances.

Saying “AI is a bubble” and “AI is the next industrial revolution” are the same statement. They are separated by about ten years and one crash.

1880: an electric belt for what ails you

Forty years after the railway crash, Edison and Tesla were household words. Electricity had moved from laboratory to lightbulb to street. The prefix of the new era was Electric.

And so we got the Pulvermacher Hydro-Electric Chain — a vinegar-soaked voltaic belt worn around the waist, which claimed to cure impotence, rheumatism, kidney pain, sciatica, dyspepsia, “weaknesses peculiar to men,” and most other diseases known to the Victorian gentleman. It was sold in the Sears Roebuck catalogue alongside guns, sewing machines, and laudanum. Tens of thousands of units moved.

Competitors swarmed: the German Electric Belt Company (which was, despite the name, based in New York), Dr. Sanden’s Electric Belt, Dr. Crystal’s, Dr. Horn’s, Owen’s, Heidelberg’s — and, hilariously, Edison’s, founded by Thomas Edison Junior, against whom his own father took out lawsuits.

The 1887 U.S. Congress had electric medical equipment wired directly into the Capitol Building so congressmen could be “treated” during sessions. The medical journals of the period are full of the same exasperated tone you find in modern AI-skeptic Twitter. The British Medical Journal called one prominent manufacturer an egregious quack. They were ignored for thirty years.

If you had walked into a New York drugstore in 1892, you would have seen electric corsets, electric brushes, electric tonics, electric baths, electric magnetic insoles. Real electricity existed. None of these products contained any. The label was doing all the work — exactly as “AI” does on a 2026 food-delivery app’s new menu-suggestion feature.

The label is the product. The product is the label. The actual technology is at most a coincidence.

Eighteen hundred companies, three winners

The automobile arrived around 1885 in Germany. By the early 1900s in the United States, over eighteen hundred separate car companies had been founded. Almost all are forgotten. Abbot-Detroit. Adams-Farwell. Armstrong Electric. The Berg. Three different companies called Courier. The 1914-only Motor Bob.

Henry Ford’s own first attempt — the Detroit Automobile Company, incorporated in August 1899 — went bankrupt in January 1901. Production problems. Quality problems. He came back later.

By 1929, the so-called Big Three — GM, Ford, Chrysler — were the only survivors at scale. The survival rate from the original cohort is roughly two-tenths of one per cent. The capital was not burned. It was redirected through a winnowing process that left an industry.

The instructive part is the naming. The survivors generally had personal names (Ford, Buick, Dodge, Chrysler, Olds) or geographic names (Detroit, Cadillac). The casualties disproportionately had prestige-tech names: Electric, Power, Motor, Automatic, Steel. The label-heavy companies died at a higher rate than the company-heavy companies.

I do not think this is an accident. I think it is a quiet signal of which founders were trying to participate in the technology and which were trying to participate in the prestige around it. The market sorted, with great cruelty, between the two.

The louder the prefix in the name, the shorter the company’s future.

The curve that keeps rhyming

The most rigorous frame for what we are watching is Carlota Perez’s Technological Revolutions and Financial Capital, published in 2002. Perez identifies five technological revolutions in the last two hundred and fifty years: the Industrial Revolution, Steam and Railways, Steel and Electricity, Oil and Mass Production, and Information and Telecommunications. Each follows the same four-phase surge.

Figure 2. Carlota Perez’s surge cycle, fitted to the present AI moment. The naming bubble peaks in Frenzy. Operators emerge in Synergy.

The phases are: Irruption (the technology arrives quietly, used by specialists), Frenzy (capital floods in, labels appear everywhere, valuations decouple from reality), Turning Point (a crash, a sorting event), Synergy (the survivors deploy the infrastructure at scale, labels drop, the operators take over), and Maturity (saturation, the next big bang waits in the wings).

The crucial point — which my LinkedIn post elided — is that the naming bubble is a feature of the Frenzy phase, not a sign that the underlying technology is fake. Steam was real. Electricity was real. Cars were real. Radio was real. The internet was real. And each of them had a Pulvermacher Belt era of its own.

Saying “AI is a bubble” and saying “AI is the next industrial revolution” are not opposing positions. They are the same position, looked at from two different points on the same curve. The bubble produces the infrastructure that the revolution will ride. The cynic and the evangelist are arguing across a temporal gap they have not noticed.

Where on the curve are we now? Probably mid-Frenzy, possibly approaching Turning Point. The shopkeeper near my local is one of the better leading indicators. When the prefix has reached the high-street signboard, you are not early.

The bubble is the financing mechanism for the deployment. Both halves are required.

The compressing half-life

Here is something that has changed, and matters. The half-life of each prestige prefix has shortened with every cycle, in rough proportion to the acceleration of media and capital flows.

Figure 3. The half-life of prestige labels has shortened with every cycle. Calibrate accordingly.

Railway lasted forty years as a viable prestige name in a company. Electric lasted about twenty-five. Radio about fifteen. Atomic about ten. Cyber about seven. Dot-com about five. Blockchain about three. The trend is not gentle. It is exponential decay.

What does this imply for AI? Plausibly, the prestige half-life of the label is forty months, not forty years. If you are building a career identity around the prefix — AI Strategist, AI Transformation Lead, Head of AI Anything or Head of Quantum — you are betting on a label whose viable shelf life is shorter than yoghurt.

The technology will last. The label will not. These are different things, and conflating them is exactly the cargo-cult error this whole essay is about.

If your identity is the prefix, your obsolescence runs on a faster clock than your competence.

Operators and name-changers

Here is the cleanest historical pattern, and the one most absent from the original LinkedIn post: the long-run winners almost never carried the prestige prefix in their name.

Watch who is still here in 2030 and not called “Acme AI Solutions.”

The table above is the historical record, written one cycle per row. The column on the left is the railway, electric, auto, dot-com, blockchain, and AI companies that put the era’s prefix on their letterhead and disappeared. The column on the right is the companies that did the same work without the prestige label, and which are still in operation, or whose successor entities are.

Ford, not Armstrong Electric. Amazon, not Pets.com. Coinbase, not Long Blockchain Corp. The Great Western Railway, not the Yorkshire and Berwick Promoters’ Consortium.

The signal is so consistent across centuries that I am willing to state it as something close to a law of the industry. Operators do not need the prefix. The prefix is a substitute for the operation. When you see it on a name, in any era, you are watching someone short the difference between what they are doing and what they want to be seen as doing.

Bet on the named, not the labelled. Ford, not Electric. The shopkeeper, not the strategist.

A test you can run on Monday

If you want to know whether the company you work for, or the role you are about to take, or the stock you are about to buy is participating in the substance of the cycle or merely the label of it, there is a five-minute test.

Take the entity’s name and strip the prestige prefix. Read what remains. Does the description still describe a business?

Ai Gadgets, with the prefix stripped, is Gadgets. That still describes a business. The shopkeeper is fine. He sells real phones to real people, and the prefix is decoration.

AI Transformation Lead, with the prefix stripped, is Transformation Lead. That, in most organisations, also describes a role. Probably not good one, but a recognisable one. Mostly fine.

Long Blockchain Corp, with the prefix stripped, is Long Corp. That describes nothing. Long what? The company name relied on the label so completely that removing the label collapsed the description. The market eventually noticed.

Pets.com, with the prefix stripped, is Pets. That is not a company, that is a category. The dot-com was load-bearing.

Run this on your own employer. Run it on your own title. Run it on every “AI-native” startup that crossed your inbox last quarter. Notice which descriptions hold and which collapse. The ones that collapse are the ones whose viability is the label, and whose half-life is whatever this cycle’s prefix-clock turns out to be.

The test costs nothing. It takes five minutes and a piece of paper. The fact that almost no one in a boardroom does it before signing the brand is the most damning thing you can say about the current state of strategic judgement.

If the description collapses when you remove the prefix, the prefix was the description.

Walk past the same Road

I want to close where I started, because the essay is really about one specific shopkeeper and what he has to teach a city’s worth of AI strategists.

Walk past the same Road on this sunday afternoon. The shopkeeper is selling a refurbished phone to a tourist. He has paid his rent. He has stocked his inventory. The signboard above his head reads Ai Gadgets and means nothing, and he knows it means nothing, and the tourist knows it means nothing, and the transaction proceeds anyway, because the label is doing exactly what labels have done since 1720: providing a small, harmless permission to participate.

One mile north, in a glass office tower, an AI Transformation Lead is preparing slides for an Architecture Review Board. He has never shipped a model. He has never read a Goodhart paper. He has never heard the name Pulvermacher. His org chart reports to an AI VP who reports to an AI CIO. None of them have read Perez. They believe they are at the beginning of something genuinely new.

They are at the middle of something very, very old.

The shopkeeper has skin in the game — his rent, his stock, his children’s school fees. If his Ai signboard pulls in one extra tourist a week, he has won. Litrally kind of less bet. If the wave breaks, he changes the sign, paints over the Ai, and the business continues. He is doing the same thing he was doing before. The prefix was always cosmetic; he knew that.

The AI XXXXXXX Lead has no skin in any game. If the wave breaks, he becomes a Quantum Transformation Lead by Q3. By Q4, a Post-AGI Strategic Officer. His résumé will absorb the next prefix without resistance, because the prefix was always the résumé.

The shopkeeper sells real phones. The strategist sells the prefix.

Bet on the shopkeeper he hedge less.

MPP TestKit VSCode Extension – Inline HTTP 402 Payment Flow Hints

The problem it solves

When you’re building or testing a pay-per-request API with MPP TestKit, you’re juggling a few moving parts at once:

  • mppFetch auto-creates a wallet, airdrops SOL, intercepts the 402, pays, and retries
  • createTestServer auto-generates a recipient keypair
  • mpp.charge({ amount: "0.001" }) gates a route and charges that amount per verified request

All of that is invisible in the code itself. You have to keep the mental model in your head, or scroll to the docs. The extension makes it visible inline — the same way TypeScript shows inferred types.

Installation

From the VS Marketplace

Search MPP Payment Flow Hints in the Extensions panel (Ctrl+Shift+X), or:

ext install mpptestkit.mpp-payment-hints

From source

git clone https://github.com/mpptestkit/mpptestkit
cd packages/vscode-extension
npm install
npm run compile

# Package and install locally
npm install -g @vscode/vsce
vsce package --no-dependencies
code --install-extension mpp-payment-hints-0.1.0.vsix

Requires VS Code 1.75+ and editor inlay hints enabled (editor.inlayHints.enabled).

What you see

Every MPP SDK call gets a small inline label right after the opening (. Here’s what each one shows:

mppFetch

const res = await mppFetch( ⬡ 402 flow: wallet → pay → retry  "http://localhost:3001/api/data");

This call does a lot: creates a wallet, requests an airdrop (devnet/testnet), hits the URL, intercepts the 402, sends a SOL transfer, and retries with the Payment-Receipt header. The hint makes that whole flow visible at the call site.

createTestClient

const client = await createTestClient( ⬡ auto-wallet · airdrop  {
  network: "devnet",
  onStep: (step) => console.log(step.type, step.message),
});

Reminds you that this call generates an ephemeral Solana keypair and funds it via airdrop — no wallet setup needed on devnet/testnet.

client.fetch

const res = await client.fetch( ⬡ handles 402 automatically  "http://localhost:3001/api/data");

Same flow as mppFetch, but on a pre-created client with a reused wallet.

mpp.charge — extracts the SOL amount

app.get("/api/data",
  mpp.charge( ⬡ 0.001 SOL per request  { amount: "0.001" }),
  (req, res) => res.json({ data: "premium content" })
);

The extension reads ahead in the document to find amount: "X" and shows the actual value in the hint. If no amount is found (e.g., the argument is a variable), it falls back to ⬡ SOL payment required.

createTestServer

const mpp = createTestServer( ⬡ auto-recipient wallet  );

Confirms that the server auto-generates a recipient keypair. Useful when you’re debugging which address is receiving payments.

How it works

The extension registers a vscode.InlayHintsProvider for TypeScript, JavaScript, TSX, and JSX files. On each document change, it scans the document text for the five patterns above and places hints at the offset immediately after the opening ( of each call.

class MppInlayHintsProvider implements vscode.InlayHintsProvider {
  provideInlayHints(document: vscode.TextDocument, range: vscode.Range) {
    const text = document.getText();

    // Only activate in files that use mpp-test-sdk
    if (!text.includes("mpp-test-sdk")) return [];

    const hints: vscode.InlayHint[] = [];

    for (const pattern of PATTERNS) {
      pattern.regex.lastIndex = 0;
      let match: RegExpExecArray | null;

      while ((match = pattern.regex.exec(text)) !== null) {
        const pos = document.positionAt(match.index + match[0].length);
        if (pos.isBefore(range.start) || pos.isAfter(range.end)) continue;

        const label = pattern.getLabel(match, text);
        const hint = new vscode.InlayHint(pos, " " + label + " ", vscode.InlayHintKind.Type);
        hint.paddingLeft = true;
        hints.push(hint);
      }
    }

    return hints;
  }
}

The extractChargeAmount helper looks ahead up to 200 characters from the ( to find amount: "X":

function extractChargeAmount(text: string, offset: number): string {
  const snippet = text.slice(offset, offset + 200);
  const m = /amounts*:s*["']([0-9.]+)["']/.exec(snippet);
  return m ? m[1] : "";
}

This handles same-line and next-line argument layouts without needing a full AST.

Activation

The extension activates lazily — only when you open a TypeScript or JavaScript file. If the file doesn’t import from mpp-test-sdk, no hints are computed at all (controlled by the showOnAllFiles setting).

"activationEvents": [
  "onLanguage:typescript",
  "onLanguage:javascript",
  "onLanguage:typescriptreact",
  "onLanguage:javascriptreact"
]

Settings

Open VS Code settings (Ctrl+,) and search MPP:

Setting Default Description
mpp.hints.enabled true Toggle all hints on/off
mpp.hints.showOnAllFiles false Show hints in every JS/TS file, not just mpp-test-sdk files

Or set them directly in settings.json:

{
  "mpp.hints.enabled": true,
  "mpp.hints.showOnAllFiles": false,
  "editor.inlayHints.enabled": "on"
}

The broader picture

The extension fits into the MPP TestKit toolchain alongside the CLI:

# Test a live endpoint from the terminal
npx mpp-test-cli https://api.example.com/data

# See the payment flow in your editor as you write the code
# → extension shows hints inline
  • CLI (mpp-test-cli) — fire-and-forget endpoint testing from the terminal
  • VSCode extension — ambient context in your editor as you write integration tests or server code

Both activate only when you’re working with mpp-test-sdk so they stay out of the way otherwise.

Links

The README Was a Protocol. The Entrypoint Was Still Optional.

cover image

cover image

Glossary: terms used in this article

🔸 MICA (Memory Invocation & Context Archive): A governance schema for AI context management. Defines how context should be structured, trusted, scored, and handed off across sessions.

🔸 Invocation Hierarchy: The operational ladder — natural, guided, forced — that determines how MICA actually reaches a live session.

🔸 Activation Packet: The compiled session-start object that declares read targets, load state, self-test posture, drift status, and gate outcome.

🔸 Session Report: The structured opening output that declares what was loaded, what the self-test found, and whether the session gate is open.

🔸 README-as-Protocol: The pattern where the model’s natural tendency to read the README first is formalized as a declared invocation mechanism. Introduced in v0.1.8.

1. Where Part 6 Left Off

Part 6 showed what MICA looks like inside a single maintenance agent — session report, drift detection, design invariants, deviation log. The structure held. The protocol ran.

Part 6 ended with a harder question: what happens when accumulated session knowledge needs to govern the next session — inside a tool that runs within AI workflows itself?

The answer depends on a prior question: does the next session actually load what was accumulated?

That is not a schema problem. It is an entrypoint problem.

2. The Gap README-as-Protocol Left Open

The Entrypoint Gap

Part 4 made a specific assumption: in many repository-based AI workflows, the README is already the model’s first orientation surface.

That observation became README-as-Protocol.

Instead of inventing a new installation mechanism, MICA formalized an existing behavior: the model reads the README, the README points to the archive, and the session is expected to load context, run checks, and report readiness before work begins.

That assumption was useful.

It gave MICA a path into the session without requiring plugins, services, or custom host infrastructure.

But a protocol is not an entrypoint.

The README can declare where the archive is, what invariants matter, what the session report must contain. None of that guarantees sequencing. A model can still skim the README, jump directly into code, or begin work before declaring its load state.

A gate without a consequence is still only etiquette.

That is the gap this version had to close.

3. The Answer: An Invocation Hierarchy

The Activation Spectrum

MICA does not auto-invoke by magic. If no human, host, wrapper, or launcher calls the memory contract, the archive can exist without governing anything. This is the same truth Part 2 identified: the structure can exist, and the model can still have no reliable way to know it exists.

The answer is an explicit hierarchy.

Natural — the model reads the project surface voluntarily: README, mica.yaml, archive JSON, playbook. No intervention required.

Guided — a host agent requests the activation packet before work begins. The packet declares read targets, self-test posture, drift state, and gate outcome. The host uses it to preflight the session.

Forced — a launcher blocks repository work until the session report clears. This is the strongest path and the least elegant one. It is also the one that survives noisy real-world terminal workflows.

4. What Changed in Code

The output mechanism

Three concrete moves made this operational.

Session report became a real runtime output.

parser.add_argument(
    "--format",
    choices=["text", "json", "hook", "session-report"],
    default="text"
)

The opening report is now a compiled object — not a protocol expectation, not a prose description. A host can consume it directly.

Invocation is now compiled, not described.

mica_invoke.py compiles read targets and session report into one activation packet:

packet = {
    "mode": mode,
    "entry_strategy": mode,
    "read_targets": _layer_targets(project_root),
    "session_report": report,
}

This is the shift from documentation-first startup to packet-first startup. The host no longer has to infer the sequence from prose.

In guided mode, the output is already shaped for host consumption:

{
  "mode": "guided",
  "entry_strategy": "guided",
  "read_targets": [
    {"name": "readme", "...": "..."},
    {"name": "mica_yaml", "...": "..."},
    {"name": "archive", "...": "..."},
    {"name": "playbook", "...": "..."},
    {"name": "lessons", "...": "..."}
  ],
  "session_report": {
    "archive_version": "1.7.8",
    "self_test": {"pct": "CLOSED", "closed_contract": true},
    "drift_status": {"status": "NO_DRIFT"},
    "gate": "PASS"
  },
  "directive": "Host agent should load declared MICA surfaces first and use the session report as opening state."
}

Forced mode now has consequence.

if args.mode == "forced" and packet["session_report"].get("gate") == "BLOCKED":
    sys.exit(1)

The simplest entry surface:

@echo off
python "%~dp0toolsmica_invoke.py" %*

That wrapper gives MICA an enforceable terminal entrypoint instead of relying on good behavior.

5. STEM-BIO-AI: The Cleaner Case

Dependency Shift

STEM-BIO-AI already had a mature MICA memory layer — archive, playbook, lessons, invocation protocol, drift profile. What changed was not the memory model. It was how that model becomes operative before work begins.

That difference is visible across all three invocation modes.

In natural mode, the helper preserves the README-first path and makes the expected read order explicit:

[MICA INVOKE] mode=natural
Gate       : PASS
State      : INVOCATION_MODE
PCT        : CLOSED
...
Directive: Prefer reading README first, then load mica.yaml, archive, and playbook before scan work.

In guided mode, the same startup becomes a host-consumable packet:

{
  "mode": "guided",
  "read_targets": ["readme", "mica_yaml", "archive", "playbook", "lessons"],
  "session_report": {
    "archive_version": "1.7.8",
    "self_test": {"pct": "CLOSED", "closed_contract": true},
    "drift_status": {"status": "NO_DRIFT"},
    "gate": "PASS"
  }
}

In forced mode, the launcher uses the same contract as a gate:

[MICA INVOKE] mode=forced
Gate       : PASS
State      : INVOCATION_MODE
PCT        : CLOSED
...
Directive: Block work until the session report gate is not BLOCKED.

The session report now looks like this:

[SESSION READY]
Archive: 1.7.8
Load: {"state": "INVOCATION_MODE", "mica_yaml": "memory\mica.yaml"}
Self-test: {"pct": "CLOSED", "closed_contract": true}
Drift: {"status": "NO_DRIFT"}
Active invariants: {"critical_count": 15, "high_count": 3}
Gate: PASS

Before, the package told the operator how to start correctly. Now, the session declares whether it actually did.

Before this version, starting a STEM-BIO-AI session correctly still depended on the operator remembering to load the right memory surfaces in the right order. Now that dependency can move upward: in guided mode to the host, and in forced mode to the launcher.

6. CCGE: The Harder Case

retaining identity

CCGE is more important precisely because it is harder. It is already a governance-heavy runtime. If MICA’s identity were weak, it would disappear into the larger framework.

CCGE here is the Care Chain Governance Engine: a fail-closed clinical governance runtime with its own execution core, artifact generation, policy layers, and approval logic. That is why it is the harder case. MICA is not being tested in isolation. It is being tested inside a system dense enough to swallow it.

It did not.

The boundary stayed explicit:

  • MICA = invocation, memory, invariants, drift control
  • CCGE Core = fail-closed runtime and artifact generation
  • STEM-AI = trust re-audit and classification

That is the important architectural result. In STEM-BIO-AI, MICA is already close to the center of the tool’s operational identity. In CCGE, MICA has to retain its own identity inside a much larger runtime. It does so by remaining responsible for invocation, memory, invariants, and drift control, while CCGE Core remains responsible for fail-closed execution and artifact logic.

The current session report in CCGE:

[SESSION READY]
Archive: None
Load: {"state": "INVOCATION_MODE", "mica_yaml": "mica.yaml"}
Self-test: {"pct": "CLOSED", "closed_contract": true}
Drift: {"status": "NO_DRIFT"}
Active invariants: {"critical_count": 0, "high_count": 0}
Gate: PASS

Archive: None with Gate: PASS is not a contradiction. The baseline archive does not yet expose a project.version field. MICA detected that gap and reported it before any work began. A system that hides its own incompleteness is not governed. A system that surfaces it at session start is.

The reason is concrete: the active archive is still a baseline integration memory object, not yet a fully target-bound archive. Its project block still carries placeholders like:

"project": {
  "name": "<target-repo-name>",
  "path": "<absolute-or-repo-relative-path>",
  "owner": "<org-or-maintainer>",
  "integration_program": "CCGE Unified Model",
  "target_status": "phase_1_candidate"
}

So the current report is telling the truth about what exists: a coherent MICA package around a still-baseline archive.

A README might have let that gap stay invisible. The session report surfaced it immediately. That is what honest governance looks like before an archive is fully populated.

7. What This Means for Anyone Building Agent Workflows

Architecutural imperatives

Three lessons from running this against two different projects.

Human-readable startup is not enough. If the only valid path lives in a README, the protocol is vulnerable to partial reading and host variance. STEM-BIO-AI is the clean example here: the memory layer was already mature, but correct startup still depended too much on the operator remembering to load it.

Session-start state must be machine-usable. If a host agent cannot consume the startup declaration as a structured object, it cannot reliably preflight the session. That is why guided mode matters more than another explanatory document: it gives the host an object to act on, not just instructions to interpret.

A gate needs an entrypoint. A session report can be a conceptual hard gate, but until a launcher or host uses it as an entry condition, it remains a convention. CCGE is the stronger proof of that point because the environment is already dense with governance logic; without an explicit entry surface, MICA would have been easy to blur into the surrounding framework instead of remaining its own startup layer.

8. What This Does Not Claim

MICA does not self-invoke automatically in all environments. There is still no natural law that forces an LLM session to load the governed archive first.

The real claim is narrower:

  • MICA can now be read naturally
  • MICA can now be requested deliberately
  • MICA can now be enforced mechanically

Not total automation. A realistic path to enforceable startup.

9. What Part 8 Will Address

The startup path is now much stronger.

But one question remains:

How much of the session-start contract should be owned by the archive itself, and how much should remain a runtime default?

The current line can emit session-report, compile guided packets, and block in forced mode. The next step is stricter archive ownership — richer session_report_format, explicit per-archive session_gate_policy, better drift contracts.

Part 8 is not about whether MICA should govern startup. It already does. It is about how much of that behavior should be declared by the archive rather than inferred by the runtime.

The series continues only where there is something concrete to specify, test, or correct.

Named decision from this post: A protocol is not yet an entrypoint. MICA becomes operational only when invocation is structured as natural, guided, or forced — and the session begins from a declared activation packet, not from hope.

MICA is part of the Flamehaven governance-first AI systems practice. Schema, technical report, and production instance: flamehaven.space. Open-source tooling: AI-SLOP-Detector. All schema references follow the v0.1.8.1 Universal standard unless a specific earlier version is named.

Your AI Agent Doesn’t Need an API Key: Entra Agent ID and Anthropic’s Workload Identity Federation

Your AI Agent Doesn’t Need an API Key: Entra Agent ID and Anthropic’s Workload Identity Federation

Every system that authenticates with a static API key is carrying a liability disguised as a convenience. The key does not expire unless someone sets a calendar reminder. It does not know who is using it. It cannot tell you whether the request that just hit the endpoint came from the production agent it was minted for or from a laptop in a coffee shop where someone pasted it into a terminal two months ago. Static keys are the skeleton key of modern distributed systems — they open the door for anyone who holds them, and they never ask why.

This is not a new problem, but it is becoming a dangerous one. As AI agents proliferate across enterprise environments — calling model APIs, orchestrating workflows, accessing downstream services — the number of static secrets embedded in configuration files, environment variables, and CI pipelines is growing faster than any rotation policy can keep up with. The question is no longer whether your organization has a leaked key somewhere. The question is how many, and which ones an attacker has already found.

The industry’s answer has been converging for years, and it has a name.

Workload Identity Federation

Workload Identity Federation (WIF) is a pattern — not a product, not a proprietary protocol — built on top of OpenID Connect and the RFC 7523 JWT bearer grant. The idea is disarmingly simple: instead of minting a long-lived secret and handing it to a workload, you let the workload prove who it is using a short-lived, signed JSON Web Token issued by an identity provider (IdP) you already trust. The receiving system validates the JWT’s signature against the IdP’s published keys, checks the claims against rules you configured, and — if everything lines up — issues a short-lived access token in return. No secrets to store. No secrets to rotate. No secrets to leak.

The pattern has been adopted across the industry — by major cloud providers, CI/CD platforms, container orchestrators, and increasingly by model providers. Microsoft Entra, for its part, supports WIF both as an issuer (your Entra tenant issues JWTs that external systems trust) and as a relying party (your Entra tenant trusts JWTs from external identity providers to grant access to Entra-protected resources). That bidirectional capability is what makes the rest of this story possible.

Anthropic embraces the standard

Anthropic has brought native Workload Identity Federation support to the Claude API — and this deserves more attention than it has received.

With Anthropic’s WIF implementation, any OIDC-capable identity provider can authenticate workloads to the Claude API without a static sk-ant-... key ever being involved. You register your IdP as a federation issuer in the Anthropic Console, define a federation rule that maps incoming JWT claims to a service account, and your workload does the rest: present the JWT, receive a short-lived Claude access token, call the API. The SDKs handle the exchange and the refresh loop. API keys can be disabled entirely on the Anthropic workspace.

Three concepts on the Anthropic side matter here:

  • Service accounts (svac_...) — non-human identities inside your Anthropic organization. A federated token acts as a service account. Unlike an API key, a service account has credentials minted for it on demand, and you can audit which workloads acted as which service account.
  • Federation issuers (fdis_...) — the registration of your OIDC identity provider with your Anthropic organization. Each issuer tells Anthropic “JWTs signed by this provider may assert workload identity for my org.”
  • Federation rules (fdrl_...) — the bridge between an issuer and a service account: “when a JWT from issuer X has claims that look like Y, mint a token for service account Z.”

The Console includes presets for common providers and a generic OIDC option that works with any standards-compliant issuer — including Microsoft Entra ID. That last bullet is the one this article cares about.

Microsoft Entra Agent ID — identity built for agents

Microsoft Entra Agent ID introduces first-class identity constructs purpose-built for AI agents. Not repurposed service principals. Not human user accounts pressed into service. Dedicated objects with a dedicated governance model.

The constructs that matter for this story:

  • Agent identity blueprints — the template and authentication foundation for one or more agent identities. The blueprint holds the credentials (client secret, certificate, or federated identity credential) and uses them to acquire tokens on behalf of all agent identities created from it. Conditional Access policies applied to a blueprint propagate to every agent identity it parents.
  • Agent identities — the runtime identity of a specific AI agent. An agent identity has no credentials of its own. It authenticates through its blueprint.
  • The Microsoft Entra SDK for Agent ID — a containerized sidecar that handles token acquisition, validation, and secure downstream API calls. Your agent code asks the sidecar for a token; the sidecar handles the identity plumbing.

The proof of concept

The question I wanted to answer was concrete: can an AI agent, using Microsoft Entra Agent ID as its native identity, call the Anthropic Claude API through Workload Identity Federation — with no API key, no certificate in agent memory, and no cloud LLM proxy in between?

The answer is yes. I built a proof of concept that does exactly this.

The architecture

The PoC runs as two containers on a Docker bridge network:

  1. claude-wif-agent — a Flask application that receives user queries, asks the sidecar for an Entra JWT, exchanges that JWT for a Claude access token, and calls the Claude Messages API.
  2. claude-wif-sidecar — the Microsoft Entra Auth SDK sidecar, which handles the client-credentials flow against Entra ID and returns a signed JWT scoped to the agent identity.

The token flow has nine steps, but the critical insight lives in three of them:

  • Steps 4–5: The sidecar uses the blueprint’s credentials to obtain an Entra-issued JWT for the agent identity. The JWT carries the agent’s appid, oid, and — crucially — the xms_par_app_azp optional claim that identifies the parent blueprint.
  • Step 7: The agent application exchanges that Entra JWT for a Claude access token by posting to POST https://api.anthropic.com/v1/oauth/token using the RFC 7523 jwt-bearer grant. Anthropic validates the JWT’s signature, checks the claims against the federation rule, and returns a short-lived token.
  • Step 9: The agent calls POST https://api.anthropic.com/v1/messages with the Claude token. No API key is involved. No MSAL library is needed. No certificates sit in agent memory.

Three Entra objects — and why the third is easy to miss

The PoC requires three distinct Microsoft Entra objects. Two of them sound similar and the third is implicit in WIF mechanics — which is exactly why it trips people up.

  1. An Agent Identity Blueprint — holds the credentials (client secret for local dev; managed identity or federated identity credential in production) and parents the agent identity.

  2. An Agent Identity — the runtime identity of the specific AI agent. No credentials of its own — the blueprint mints tokens on its behalf.

  3. An App Registration representing the Anthropic API — and this is the one that is easy to miss. Anthropic’s WIF rule validates an Entra-issued JWT, and the only way that JWT carries the right aud (audience) claim is if Entra issues it for a registered resource application whose ID matches what you configured as the audience of the federation issuer in the Anthropic Console. This app registration uses v2.0 tokens (requestedAccessTokenVersion: 2), has acceptMappedClaims: true, and configures the xms_par_app_azp optional claim on the access token — so that a single Anthropic federation rule can match all agent identities parented by the same blueprint, rather than requiring a rule per individual agent.

The token that reaches Anthropic carries:

  • iss = https://login.microsoftonline.com/<tenant-id>/v2.0
  • aud = the Application ID of the Anthropic API app registration
  • appid = the Agent Identity’s client ID
  • oid = the Agent Identity’s object ID
  • xms_par_app_azp = the Agent Identity Blueprint’s application ID

Anthropic validates all of this against the federation issuer and rule you configured. No Anthropic API key is involved at any point.

Both flows work

The PoC supports both access patterns that the agent identity platform defines:

  • Autonomous (app-only): The agent identity acts independently. The sidecar obtains a client-credentials token, the agent exchanges it for a Claude token, and the response comes back tagged "flow": "autonomous".
  • On-Behalf-Of (OBO): When a signed-in user’s Entra Bearer token is available, the sidecar performs an OBO exchange and mints an agent-on-behalf-of-user token, which is then exchanged with Anthropic WIF. The response comes back tagged "flow": "obo".

Both flows use the same Anthropic WIF endpoint. The only difference is whose authority the Entra JWT represents — the agent’s own, or the agent acting on behalf of a human.

From local dev to production

The PoC uses a client secret on the blueprint for local development — a pragmatic shortcut for proving the concept. Moving to production requires changing exactly two environment variables in the sidecar configuration to switch from client secret to managed identity, and adding a federated identity credential on the blueprint for the managed identity. No agent code changes. The sidecar abstracts the credential source entirely.

The credentials-free agent

This is where the threads converge. Workload Identity Federation is an industry standard. Anthropic has built native support for it into the Claude API. Microsoft Entra Agent ID provides purpose-built identity constructs for AI agents — with blueprints that centralize credential management, agent identities that carry no secrets of their own, and a sidecar SDK that abstracts the entire token lifecycle.

Put them together and you get something that would have been difficult to describe two years ago: an AI agent that authenticates to a third-party model provider using its own agentic identity, issued by the enterprise identity provider, validated through standards-based federation — with no static API key, no certificate in memory, and no cloud LLM proxy sitting in between. The agent’s identity is its credential.

The proof of concept is open on GitHub: astaykov/claude-wif-agentid. It is minimal by design — a Flask app, a sidecar, a docker-compose.yml, and a .env file. The README walks through every Entra object, every Anthropic Console configuration step, and the full token flow. Fork it, break it, extend it.

The age of the static API key — for AI agents, at least — is ending. The identity infrastructure to replace it is already here.

References

ECDSA – The Math That Only Goes One Way

Bitcoin gives you the ability to generate a key pair,  a public key and a private key. You generate a signature with your private key, and that signature is what you attach to a transaction. It proves to any third party that the transaction was authorized by you, the rightful owner, without you ever having to reveal the key itself.

But what is actually happening underneath that process?

ECDSA — Elliptic Curve Digital Signature Algorithm

The mechanism behind all of it is ECDSA — a digital signature system built on elliptic curve cryptography.

An elliptic curve is defined by the equation y² = x³ + ax + b. Bitcoin fixes the constants at a = 0 and b = 7, which reduces the equation to the one introduced in the last article:

y² = x³ + 7

This is called the secp256k1 curve. Every key, every signature, every verification happens through operations on points that lie on this curve, inside the finite field.

ECDSA handles three things: key creation, signature generation, and signature verification. Each one builds on the last.

Key Creation

A private key is a randomly generated large integer d — chosen from the range 1 to n − 1, where n is the order of the secp256k1 curve. It’s a 256-bit number, meaning it’s chosen from a space of roughly 2²⁵⁶ possibilities. No one chooses it for you, no server stores it, no institution knows it. It exists only where you keep it.

The public key Q is then derived from it:

Q = d · G

G here is the generator point — a fixed, agreed-upon point on the secp256k1 curve that the Bitcoin network uses. The operation d · G is point multiplication, a one-way operation: the point G is added to itself d times using elliptic curve addition rules, all within the finite field.

Think of your public key as your account details — the address people send funds to. Your private key is your transfer authorization, except unlike a bank PIN, it isn’t held by anyone else. Only you.

One-Way Operations — Why You Can’t Go Backwards

To understand why reversing Q = d · G is impossible, it helps to start with something more familiar: prime factorization.

It is believed that prime numbers are the fundamental building blocks of all natural numbers — that every positive integer greater than 1 is a product of primes. Take 504 as an example:

504 = 2 · 2 · 2 · 3 · 3 · 7

Multiplying those factors together to get 504 is trivial. But hand someone 504 and ask them to recover the prime factors, and the only known approach is to repeatedly divide by every prime smaller than the number. As the numbers scale up to hundreds of digits, this becomes computationally infeasible. No shortcut is known to exist aside this naive way.

Point multiplication on an elliptic curve works on the same principle, and this amongst other reasons guarantees security. Computing Q = d · G given d is fast. But given only Q and G — recovering d — is the elliptic curve discrete logarithm problem. There is no known efficient algorithm to reverse it.

This one-way property is the entire basis of Bitcoin’s security. But what does actually mean for the digital signatures in Elliptic curve digital signature algorithm.

Digital signature, like handwritten signature allows a receiver to convince a third party that a document came from a specific sender. Unlike a digital signature, handwritten signature can be forged, copied, or lifted from one document and placed on another.

More critically, a handwritten signature at the bottom of a document doesn’t guarantee the contents above it weren’t altered after signing. The signature and the message are separate things.

A digital signature fixes both problems. It cannot be forged, producing a valid signature requires the private key, which only the owner holds. And it is bound to the exact content of the message if a single character in the transaction changes after signing, the signature becomes invalid. It doesn’t just sign a document. It signs every bit of it.