Github Speckit: Revolucionando o Desenvolvimento com SDD

Esquematização do Github Speckit

Introdução

Hoje, quero te contar sobre uma experiência que tive com uma nova forma de desenvolver software, algo que me deixou realmente empolgada. É como quando você descobre aquela ferramenta que muda a forma como você faz tudo — e isso é exatamente o que o GitHub Speckit fez por mim!

O GitHub Spec Kit, ou Speckit, é uma solução incrível para o desenvolvimento software que segue a metodologia de Desenvolvimento Orientado a Especificações, ou SDD. Esse kit ajuda a estruturar ideias e documentações antes mesmo de começarmos a programar, permitindo um trabalho mais preciso e organizado, especialmente quando utilizamos IA.

Vamos mergulhar um pouco mais no que torna essa ferramenta tão especial?

O que é o GitHub Speckit?

O Speckit é como aquele amigo sábio que te guia em cada passo do desenvolvimento, garantindo que você esteja no caminho certo. Em vez de apenas te jogar na selva do código, ele ajuda a elaborar princípios de projeto, escopo, regras de clean code e requisitos de ponta a ponta.

Estrutura do Speckit

  1. Arquitetura Estruturada: Instrui a IA a formar uma base sólida de princípios e requisitos.
  2. Documentos Vivos: Funciona como um “mapa” que a IA consulta e atualiza constantemente.
  3. Divisão de Tarefas (Tasking): Transforma projetos complexos em listas de tarefas menores, garantindo clareza e precisão.

Uma vez que você coloca as especificações do projeto no Speckit com o comando inicial /speckit.constitution, ele te guia, passo a passo, até a implementação final. Veja abaixo o passo a passo.

Esquematização do Github Speckit

Passo a passo do Speckit

Vamos detalhar como cada comando do Speckit funciona e sua importância no fluxo de desenvolvimento:

Instalação

Para começar, você precisa instalar o Speckit em seu projeto com:

uv tool install specify-cli --from git+https://github.com/github/spec-kit.git

A partir daqui, você pode iniciar o Speckit no diretório do projeto:

specify init . --integration opencode

Dica: Coloque a pasta .opencode no .gitignore, mas mantenha a .specify no repositório GitHub.

Estruturando o Desenvolvimento

/speckit.constitution

Aqui é onde você define as regras do projeto. Padrão de código… Digite no prompt do opencode, algo do tipo:

/speckit.constitution Este projeto segue princípios SOLID, testes obrigatórios, clean architecture

/speckit.specify

É usado para descrever o que você quer construir (features novas), e não para analisar código existente. Para documentar o que seu projeto já faz, você precisa descrever manualmente no comando:

/speckit.specify Meu projeto já existente faz A, B, C. Ele tem as seguintes funcionalidades: [detalhes]. Quero documentar isso como especificação.

/speckit.clarify

Use este comando para refinar seu pedido antes de seguir para a implementação:

/speckit.clarify

Este é o momento de esclarecer ambiguidades e melhorar a especificação com a ajuda da IA.

/speckit.plan

Transforma sua ideia em um plano estruturado, quebrando o problema em partes menores e etapas definidas:

/speckit.plan

/speckit.tasks

A partir do plano, gera uma lista de tarefas executáveis, simplificando o processo de desenvolvimento:

/speckit.tasks

/speckit.implement

Finalmente, tudo que foi planejado é transformado em código real:

/speckit.implement

Comparação e Experiência Prática

Experimentei o desenvolvimento do mesmo aplicativo em diferentes abordagens de IA. Primeiro, apenas com o OpenCode no VSCode, que demandou revisões constantes. Depois, usei a skill grill-with-docs, que foi um pouco mais organizada e me trouxe bons resultados, mas ainda exigia supervisão e revisão. Com o Github Speckit, porém, foi impressionante: um plano bem estruturado, passos audíveis e uma execução precisa, resultando em um programa que rodou sem erros na primeira tentativa.

Conclusão

A experiência com o Github Speckit me fez refletir sobre como as ferramentas de IA podem transformar nosso papel como desenvolvedores. Não se trata de substituir, mas sim de evoluir com o apoio de uma tecnologia que nos liberta das tarefas operacionais, possibilitando que o foco esteja na criação e no entendimento do projeto.

Então, para você que como eu ama tecnologia, vale a pena explorar o Speckit e ver como ele pode elevar o seu desenvolvimento a outro nível. Afinal, entender as origens e a lógica por trás de cada linha de código continua sendo nossa arte e talento insubstituíveis.

Cloud Cost Elasticity

Cloud spending rarely grows predictably. As systems scale, organizations face limited visibility, sudden cost spikes, and increasing pressure on margins. This often prompts leadership to ask whether to build an in-house cloud cost-optimization platform or adopt a specialized solution. While evaluating both options is responsible and encouraged by FinOps practices, what appears to be a cost-saving decision can quickly become a long-term engineering burden.

From my experience in DevOps and cloud cost governance, internal platforms often seem affordable at first but reveal hidden complexity, ongoing maintenance demands, and strict accuracy requirements over time. In this article, you will learn the key challenges of building such a platform and how cloud cost elasticity helps determine whether your infrastructure is truly generating business value.

Understanding cloud cost elasticity
Cloud cost elasticity measures how effectively infrastructure spending scales with business value. Ideally, costs increase when customer demand and revenue grow, and decrease when demand falls.

Healthy elasticity means:

Infrastructure spend aligns with revenue growth
cost per customer or transaction improves over time
Unused capacity is minimized
Poor elasticity signals risk:

Costs grow faster than revenue
Shared infrastructure hides inefficiencies
Engineering teams lack cost accountability
Without accurate visibility, it is impossible to measure elasticity or optimize it.

The hidden complexity of building cost visibility
Building an internal platform may seem straightforward. In practice, teams quickly encounter deep technical and operational challenges.

  1. Capturing the full state of your cloud environment
    The goal of any cost optimization system is to provide a complete and accurate view of spending. This includes what was spent, when it was spent, who is responsible, and the business value generated.

Capturing a static snapshot is achievable. Capturing a continuously changing environment is far more complex.

Seven years ago, most organizations relied on a single cloud provider. Today, modern environments include:

multiple cloud platforms
SaaS, PaaS, and IaaS services
managed data and database platforms
AI and machine learning workloads
A tool built for yesterday’s architecture struggles to handle today’s complexity.

Vendor-specific challenges
Microsoft AzureBilling structures vary across Enterprise Agreements, Microsoft Customer Agreements, and other account types. Normalizing these formats requires ongoing engineering effort.

Google Cloud PlatformSome services provide detailed resource-level cost data, while others do not. This inconsistency complicates ownership tracking and cost accountability.

Managed DBaaS platformsBilling APIs and permission models can change unexpectedly. When they do, integrations may fail and require direct coordination with vendors.

These issues often require dedicated engineers to maintain data accuracy and continuity.

Most importantly, this work never ends. Cloud ecosystems evolve constantly, and maintaining reliable visibility requires continuous refinement.

  1. Disruptive technologies reshape cost visibility
    Cloud cost management evolves alongside infrastructure innovation.

A decade ago, cost visibility was simpler. When Kubernetes adoption accelerated, many teams lost visibility into compute costs because shared clusters masked resource ownership.

This became known as the Kubernetes cost black box.

Restoring transparency requires:

Workload-level usage tracking
Container resource attribution
Cluster cost allocation models
Kubernetes is only one example. Other disruptions include:

Multi-cloud architectures
Serverless computing
GPU and AI workloads
On modern data platforms
Each innovation introduces new cost attribution challenges.

If cost visibility is not a core business function, dedicating engineering time to keep pace with these changes becomes difficult.

  1. Accuracy at scale
    Visibility alone is not enough. Cost data must be accurate and trustworthy.

As cloud adoption grows, billing data volume increases dramatically.

Large enterprises may process more than 200 million billing line items per month. Consider a scenario with:

1,000 customers
100 shared services
Hourly cost allocation
The calculation becomes:

200 million × 1,000 × 100 × 730 hours

This equals 14.6 quadrillion data points every month.

Processing and validating this volume requires:

Scalable data pipelines
Accurate allocation logic
Financial-grade validation controls
Audit-ready reporting
Without precision, cost per customer insights, pricing decisions, and margin analysis become unreliable.

Accuracy at scale is a full organizational capability, not a side project.

How Opslyft helps measure and improve cost elasticity
Unified multi-cloud cost visibility
Opslyft was built for complex, multi-cloud environments. Its AnyCost™ framework ingests billing data from diverse providers and normalizes it into a unified model.

This enables teams to:

Analyze costs across platforms in one place
Measure cost per product, feature, or customer
Track cost efficiency relative to revenue
Create dashboards and alerts tailored to stakeholders
With complete visibility, organizations can evaluate cost elasticity and identify inefficiencies.

Adaptability to modern infrastructure
Opslyft continuously evolves to support modern architectures, including:

Kubernetes environments
Data and analytics platforms
AI and machine learning services
Multi-cloud ecosystems
Because cost intelligence is its core mission, the platform adapts without diverting internal engineering resources.

Financial-grade accuracy and trust
Since 2022, Opslyft has maintained SOC 1 Type 1 and Type 2 compliance. This ensures financial data integrity and audit readiness.

This level of reliability supports:

Accurate cost attribution
Confident financial reporting
Pricing and profitability analysis
Cross-functional trust between finance and engineering
Why cloud cost elasticity matters for business value
Cloud cost elasticity connects infrastructure spending to business outcomes.

When elasticity is strong:

engineering teams optimize usage
finance gains reliable cost insights
pricing decisions reflect true costs
margins improve as scale increases
When elasticity is weak:

Costs scale faster than revenue
inefficiencies remain hidden
Strategic decisions rely on incomplete data
Measuring elasticity requires precise cost allocation and continuous visibility.

Conclusion
Building an in-house cloud cost-optimization platform may seem economical, but the hidden complexity, maintenance demands, and accuracy requirements make it a significant long-term commitment.

From my experience as a DevOps engineer, cost intelligence is not a one-time project. It is an evolving discipline that must keep pace with new technologies, expanding infrastructure, and growing data scale.

Cloud cost elasticity provides a powerful lens for evaluating whether infrastructure spending is driving business value or eroding margins. Achieving this level of insight requires complete visibility, adaptability, and financial accuracy.

Opslyft enables organizations to measure, understand, and optimize cloud cost elasticity without diverting engineering focus from core innovation.

The real goal is not simply reducing cloud costs. It ensures every rupee spent in the cloud contributes measurable business value.

I Built a Payment System for Bangladesh—Heres Why Stripe Failed Us

The Problem We Were Actually Solving

In late 2023, my solo product hit a wall when 47% of signups from Bangladesh bounced at the checkout because Stripes card entry form didnt accept local debit cards. The standard Stripe Elements UI rejected cards starting with 5867 (DBBL Nexus) and 6011 (bKash card), which together accounted for 62% of all Bangladeshi transactions. Failure here wasnt academic; it meant $2,800 in lost MRR in one quarter alone. I dug into the network tokenization spec and realized Stripes default implementation silently downshifted to 3-D Secure when it saw a non-PCI-compliant BIN, but the error bubbles it surfaced contained generic messages like please contact your bank. That message meant nothing to a user whose bank hadnt onboarded 3DS globally.

What We Tried First (And Why It Failed)

My first fix was a quick UI patch: I wrapped Stripe Elements in a flag that swapped the form for a plain input field when the users IP geolocated to BD. That lowered bounce rate to 18%, but created a new problem: declined transactions spiked to 32% because our server-side AVS check expected a ZIP/postal field that Bangladeshi cards rarely expose. Next I swapped to Stripe Checkouts hosted form—easier compliance, they said. Within two weeks I watched 89% of users from Dhaka disappear once they hit the redirect to Stripes *.stripe.com subdomain, which was blocked on some local ISPs. Metrics dont lie: MRR stalled at $3.4k instead of the $8k target wed modeled on global averages.

The Architecture Decision

I rebuilt the payment flow around SSLCommerzs local gateway because their SDK already supported bKash, Nagad, Rocket, and DBBL Nexus out of the box. The downside was two extra hops: browser → my API → SSLCommerz iframe → their processor. I measured the p95 latency from Dhaka to my Singapore server at 420 ms and then to SSLCommerz at 210 ms, which still left us under Googles 2-second interactive budget. I implemented a twice-daily cron that pulled their webhook logs and cross-checked against my own payment table to reconcile inevitable drift. The reconciliation script caught three partial failures where SSLCommerz marked a transaction as paid but the processor had rolled it back—something Stripes idempotency key alone wouldnt expose.

What The Numbers Said After

After launch, bounce rate fell from 47% to 6%, and the downstream decline rate dropped from 18% to 4%. Bangladeshi MRR grew from $0 to $8.2k in four months, enough to cover 22% of our total revenue. Activation rate rose from 34% to 59%, because users no longer saw a foreign-looking payment form. Churn among these users fell from 14% to 5% per month. The biggest surprise was cost: SSLCommerzs 2.49% + ৳0.99 per transaction is 70 basis points higher than Stripe, but the conversion uplift paid for itself within six weeks.

What I Would Do Differently

I should have started with the SSLCommerz integration on day one instead of treating it as a regional bolt-on. I wasted three weeks assuming Stripes global dominance would extend to Bangladesh if I just added one more payment method at the end. The second mistake was not instrumenting the pre-redirect latency from every major Bangladeshi ISP. Once I graphed the correlation between >300 ms pre-redirect and abandonment, I added Cloudflares Argo Smart Routing from Singapore to Dhaka, trimming another 90 ms. Today I auto-detect country code from the phone number field and silently pre-select the local gateway without asking. It saves two clicks and 1.3 seconds on average, which in micro-benchmarks means 0.9% more completed checkouts. The lesson is clear: when the platform you depend on doesnt respect the sovereignty of your users banking networks, you owe it to them to build the alternative first.

Churn from payment failures dropped to near zero after switching to this infrastructure. Here is what changed: https://payhip.com/ref/dev10

Polyglot Persistence in Microservices: Choosing the Right Database for Each Service

Introduction

One of the most consequential decisions in microservices architecture is data storage. Monolithic systems traditionally rely on a single relational database to service all needs — a model that worked well for decades but creates tight coupling, limits scalability, and forces every domain to conform to the same persistence paradigm regardless of whether it is the right fit.

Modern distributed systems have embraced a concept known as polyglot persistence — the practice of using different data storage technologies within the same system, each chosen to match the access patterns and characteristics of the domain it serves. A MVP e-commerce project examined in this document demonstrates this pattern in a concrete way: three different databases, each serving a distinct microservice, each chosen deliberately.

The Three-Database Architecture

The platform studied here organizes data across three specialized stores:

Service Database Type Rationale
Order Service PostgreSQL Relational (ACID) Transactional consistency, financial data
Product Service MongoDB Document (NoSQL) Flexible schemas, rich catalog data
Cart Service Redis In-memory K/V Sub-millisecond speed, ephemeral state

This is the Database per Service pattern [1]. Each service owns its database exclusively — no service reads directly from another’s store. This boundary enforces loose coupling and allows each team to evolve the schema independently without risk of cross-service breakage.

PostgreSQL for the Order Service: ACID as a Requirement

A relational database organizes data into tables — structured grids where every row is a record and every column is a typed, constrained attribute. Relationships between tables are expressed through foreign keys: a column in one table that references the primary key of another, letting the engine enforce referential integrity automatically. This rigid schema is not a limitation but a deliberate guarantee: every row must conform to the same structure, and the engine validates constraints at write time. The payoff is ACID — the ability to group multiple writes into a single all-or-nothing transaction that either commits fully or rolls back completely, leaving the database in a consistent state regardless of failures.

The Order Service persists financial records. An order is not just data — it is a legal artifact, a commitment. This makes ACID guarantees non-negotiable.

The service uses Spring Data JPA with Flyway for schema migrations. The schema reflects classical relational design: parent orders table with a child order_items table linked by a foreign key with ON DELETE CASCADE.

CREATE TABLE orders (
    id BIGSERIAL PRIMARY KEY,
    user_id VARCHAR(255) NOT NULL,
    total DECIMAL(19, 2) NOT NULL,
    status VARCHAR(50) NOT NULL,
    order_date TIMESTAMP NOT NULL
);

CREATE TABLE order_items (
    id BIGSERIAL PRIMARY KEY,
    order_id BIGINT NOT NULL,
    product_id VARCHAR(255) NOT NULL,
    price DECIMAL(19, 2) NOT NULL,
    quantity INTEGER NOT NULL,
    CONSTRAINT fk_order FOREIGN KEY (order_id) REFERENCES orders (id) ON DELETE CASCADE
);

The OrderService.placeOrder() method is annotated with @Transactional. This ensures that if any step in the checkout flow fails — building the item list, calculating the total, persisting the record — the database rolls back to a consistent state. The JPA cascade configuration ensures that saving the parent Order entity also persists all child OrderItem entities in a single atomic operation.

Flyway provides versioned, reproducible migration scripts. On startup the service validates that the running schema matches the expected baseline, preventing “works on my machine” drift between environments [2].

MongoDB for the Product Service: Schema Flexibility at Catalog Scale

A document database stores data as self-describing records — typically JSON or BSON objects — where each document can carry a different set of fields. There is no enforced column list; a document simply contains whatever the application writes into it. Documents that represent the same concept live in a collection, but the engine does not require them to be structurally identical. This makes document databases well-suited to domains where the data model is heterogeneous.

Products have heterogeneous attributes: a laptop has RAM and storage, a t-shirt has size and color, a book has an ISBN and author. Fitting all of these into rigid relational columns requires either complex EAV (Entity-Attribute-Value) schemes or sparse nullable columns — both are maintenance burdens.

MongoDB’s document model stores each product as a self-describing JSON document. When the catalog team needs to add a new attribute category, no schema migration is required. The application code simply begins writing the new field, and existing documents remain valid.

The Product Service uses Spring Data MongoDB with repository abstraction:

@Document(collection = "products")
public class Product {
    @Id
    private String id;
    private String name;
    private String description;
    private BigDecimal price;
    private Integer stockQuantity;
    private String skuCode;
    private String category;
}

The @Document annotation maps the Java class to a MongoDB collection. Spring Data’s MongoRepository provides CRUD operations and dynamic query derivation without boilerplate SQL.

Redis for the Cart Service: Ephemeral State at Memory Speed

A key-value store is the simplest of all database models: every entry is a pair of a unique key and an associated value, with no enforced structure beyond that. There is no schema, no query language, and no relational machinery — retrieval is always by key, and the engine does nothing more than store and fetch the associated value as fast as possible. That simplicity is what makes key-value stores fast: without the overhead of parsing queries, enforcing constraints, or managing transaction logs, the engine can serve reads and writes at memory speed.

A shopping cart is session-like: it changes frequently, needs sub-millisecond read/write response times, and is inherently transient — if a cart is lost, the customer can simply re-add items. These characteristics make a relational database an inappropriate choice (too much transactional overhead for short-lived state) and a document database acceptable but not optimal.

Redis was designed precisely for this use case. As an in-memory data structure store, it delivers microsecond latency for key-value operations [3]. The Cart Service models cart data as a Redis Hash where the top-level key is cart:{userId} and the value is a JSON-serialized Cart object.

The custom RedisConfig configures a RedisTemplate with explicit serializers:

@Bean
public RedisTemplate<String, Object> redisTemplate(RedisConnectionFactory connectionFactory) {
    RedisTemplate<String, Object> template = new RedisTemplate<>();
    template.setConnectionFactory(connectionFactory);

    ObjectMapper mapper = new ObjectMapper();
    JacksonJsonRedisSerializer<Object> serializer = new JacksonJsonRedisSerializer<>(mapper, Object.class);

    template.setKeySerializer(new StringRedisSerializer());
    template.setValueSerializer(serializer);
    template.setHashKeySerializer(new StringRedisSerializer());
    template.setHashValueSerializer(serializer);

    return template;
}

This configuration ensures keys are stored as human-readable strings (cart:user123) while values are stored as JSON, which is both inspectable via Redis CLI and portable across service restarts.

The Trade-offs: What This Architecture Costs

Polyglot persistence is not free. The benefits in autonomy and performance come with real operational costs. For example:

  1. No cross-service joins. The Order Service cannot join its orders table directly against MongoDB’s products collection. In a monolith, a JOIN happens inside the database engine in microseconds with full transactional isolation. Across services, the equivalent operation is an HTTP round trip, which introduces variable latency and a dependency on network availability.

  2. Eventual consistency. In the OrderService.placeOrder() method, when a user checks out, the cart is cleared via a try/catch — a failure there does not roll back the already-committed order. True cross-service transactions require the Saga pattern [4].

  3. Operational overhead. Running PostgreSQL, MongoDB, and Redis alongside RabbitMQ and Keycloak in a single docker-compose.yml is achievable for development, but each store requires separate backup strategies, monitoring, and operational expertise in production.

Conclusion

The demo e-commerce platform described here demonstrates that polyglot persistence, when applied with intention, produces a system where each component operates at its natural best. PostgreSQL provides the ACID guarantees that financial records demand. MongoDB provides the flexibility that a diverse product catalog requires. Redis provides the speed that shopping cart interactions need.

The key insight is that the choice of persistence technology should follow from the domain’s requirements — not from organizational familiarity or the path of least resistance. In practice, this means asking a different set of questions before reaching for a database. Is the data relational, or is it a self-describing document with variable structure? Is consistency a hard requirement, or can the system tolerate brief divergence in exchange for availability and speed? Is the data long-lived and auditable, or ephemeral by nature? Each of these questions points toward a different storage paradigm, and no single engine answers all of them optimally.

Source code: github.com/dancodingbr/ecommerce

References

[1] Microservices.io. Pattern: Database per service. Available at: https://microservices.io/patterns/data/database-per-service.html

[2] Flyway. Why database migrations. Available at: https://documentation.red-gate.com/fd/why-database-migrations-184127574.html

[3] Redis. Get Started. Available at: https://redis.io/docs/latest/get-started/

[4] Microservices.io. Pattern: Saga. Available at: https://microservices.io/patterns/data/saga.html

The Future of Physical AI Isn’t Smarter Robots, It’s Smarter Interfaces

This sponsored article is brought to you by Wetour Robotics.

A field technician on a wind turbine, harness clipped, both hands on a wrench, needs to send a command to the diagnostic device hanging at her belt. A logistics worker on a loading dock, gloves on, eyes on the pallet, needs to redirect a connected lift. A person using an assistive mobility device on a crowded street wants to nudge it forward without taking out a phone or speaking aloud. None of these moments call for a smarter robot. They call for a smarter way to be heard by the machines that already exist.

The industry has been building from one side

The past three years of Physical AI have been a story of remarkable progress on the robot side of the loop. Companies like Boston Dynamics, Figure, and Unitree have advanced actuators, locomotion, and dexterity to a level that would have seemed implausible a decade ago. Google DeepMind’s Gemini Robotics has redefined what vision-language-action models can do in unstructured settings. The trajectory of the hardware and the foundation models is real, and it is accelerating.

But there is another side to this loop, and it has been treated as a solved problem for too long. The interface between humans and machines has defaulted, for 40 years, to three input modalities: screens, buttons, and voice. Each of those assumes the user can stop, look down, and translate intent into structured commands. That assumption breaks the moment the work moves into a real environment. On a turbine. On a dock. On a sidewalk. In any setting where hands are occupied, eyes are committed, or speaking is impractical, the conventional interface stack quietly fails.

Spatial Intent Fusion is the simultaneous processing of three streams of human-centered information, namely spatial position, visual context, and gestural intent: Your body is the interface.

The bottleneck on the human side of the loop is becoming as important as the one on the machine side. And solving it requires a different question. Not how do we make the robot more capable, but how do we let the human participate in the computing system as naturally as the robot already does.

Wetour Robotics’ bet: put the human back into the computing loop

Wetour Robotics is betting that the next architectural leap in Physical AI is not about making the robot more capable. It is about making the human a first-class node in the computing network, with the same kind of low-latency, high-fidelity participation that connected devices already enjoy.

Wetour Robotics’ engineers frame the problem this way: a wristband that recognizes a gesture is not enough. A camera that recognizes a scene is not enough. The information a human carries about what they are about to do is distributed across multiple channels, including where their body is in space, what their eyes are attending to, and what their muscles are preparing to do, and any single channel observed in isolation is ambiguous. Reconstructing intent reliably means fusing those channels at the operating system level, with latency low enough that the loop feels closed rather than mediated.

This approach has a name. Wetour Robotics calls it Spatial Intent Fusion: the simultaneous processing of three streams of human-centered information, namely spatial position, visual context, and gestural intent, fused into a single real-time command for any connected physical device. It is the technical implementation behind a simpler positioning statement the company uses externally: your body is the interface.

Sleek silver rectangular electronic device labeled u201cORCHESTRAu201d on a light gray background. Orchestra is a portable intelligent hub running the operating system that handles sensor fusion, intent inference, command translation, and safety arbitration. The reference compute platform is NVIDIA Jetson Orin Nano Super, which provides enough on-device inference capacity to keep the entire control loop at the edge, with no cloud dependency on the critical path. Wetour Robotics

The architecture: three layers, four engines, one loop

Orchestra is not a single device but a layered platform, designed from the start to be sensor-flexible and actuator-agnostic. The architecture decomposes into three perception layers and four coordination engines.

Orchestra itself is the local compute and orchestration core: a portable intelligent hub running the operating system that handles sensor fusion, intent inference, command translation, and safety arbitration. The reference compute platform is NVIDIA Jetson Orin Nano Super, which provides enough on-device inference capacity to keep the entire control loop at the edge, with no cloud dependency on the critical path. Edge inference is non-negotiable for this application. Full-chain latency from biosignal acquisition to actuator command is held under 100 milliseconds, the envelope inside which closed-loop control feels natural rather than laggy.

VisionLink handles visual and spatial perception. Cameras feed into vision models that identify objects, estimate distances, and track environmental context. VisionLink is designed not as a passive recognition layer but as a real-time command generator: its outputs feed directly into Orchestra OS to be fused with biosignal data.

Conductor is the biosignal pipeline. It ingests raw surface electromyographic (sEMG) data from a wrist-worn device, classifies temporal patterns into discrete gestures or continuous control signals, and outputs actuator commands. The technically interesting property of sEMG for this use case is that the signal precedes visible motion. Motor unit action potentials appear at the skin surface roughly 50 to 80 milliseconds before a finger completes the corresponding gesture. Wetour Robotics calls this property pre-motion intent sensing, and it is what allows Orchestra to anticipate user intent rather than react to it.

On top of the three perception layers, Orchestra OS runs four coordination engines. The Perception Engine ingests and normalizes raw sensor streams. The Intent Engine performs Spatial Intent Fusion across modalities, resolving what the user is trying to do given where they are, what they are looking at, and what their hand is signaling. The Orchestration Engine translates intent into device-specific command sequences for any connected actuator. The Safety Engine arbitrates conflicting commands, enforces operational envelopes, and gates execution against runtime safety conditions.

Wetour Robotics

The trade-offs we’re honest about

No system that bridges the human body and the digital world is finished. Three engineering challenges remain open, and the company addresses each with a deliberate trade-off rather than a claim of having fully solved it.

Baseline stability of sEMG under motion. In a stationary user, continuous gesture recognition from sEMG is reliable. Once the user is walking, climbing, or otherwise moving, motion artifacts and electrode drift degrade the signal in ways that are difficult to fully compensate for. Rather than overpromise on continuous control in dynamic settings, Orchestra defaults to a smaller set of robust discrete gestures in complex operating environments, and reserves continuous control modes for contexts where the signal-to-noise ratio supports them.

Miniaturization of edge AI compute. Running the Orchestra control loop entirely at the edge requires real on-device inference, which has historically meant trading off between compute capacity, battery life, and form factor. Wetour Robotics’ approach has been a compact carrier board paired with a thermal design and a battery module sized for all-day wearability. The result is a hub that travels with the user rather than tethering them to a desk, and that performs the full perception-to-actuation loop without offloading to the cloud.

Heterogeneity of third-party device protocols. The actuator side of the loop is a fragmented landscape. Different manufacturers expose different command interfaces, different communication stacks, and different safety conventions, and a Physical AI operating system has to integrate with all of them. Wetour Robotics uses an AI-agent layer to negotiate connection and protocol translation adaptively, so that Orchestra OS can ingest data from a wide range of devices, run them through neural network models that infer human intent, and emit the right command on the right protocol for the device on the other end.

Why this matters, and why it helps the rest of the field

The history of computing is a history of interface revolutions. Command lines gave way to graphical user interfaces, which gave way to touch, which gave way to voice. Each transition expanded who could participate in the system and what they could do with it. The next transition is not about a new screen or a new microphone. It is about treating the human body itself as a participant in the computing network, capable of contributing intent at the same speed and fidelity that any other connected node can.

The history of computing is a history of interface revolutions. The next transition is not about a new screen or a new microphone — it is about treating the human body itself as a participant in the computing network.

This path is not a competitor to the work being done on humanoid robots, foundation models for embodied AI, and dexterous manipulation. It is the missing complement to that work. The hardest open problem for humanoid systems is the data: every natural interaction between a human and the physical world is a potential training signal, and most of those interactions are currently invisible to any computing system. As more humans become first-class nodes in the loop, those interactions become observable, structured, and ultimately useful for training the next generation of embodied AI, including the humanoid robots being developed today.

In other words: putting the human back into the computing loop is not just about better interfaces for individual users. It is about generating the kind of grounded, in-the-wild human-machine interaction data that the broader Physical AI ecosystem will need to keep advancing. The robot side and the human side of the loop are not two competing futures. They are two halves of the same one.

That is what Wetour Robotics means when it says: Your body is the interface.

Learn more at wetourrobotics.com.

Centralized Authentication for a Multi-Brand Laravel Ecosystem

We built a centralized authentication system for a multi-brand Laravel ecosystem operating across multiple niche industry platforms.
Previously, each application had its own authentication logic, which led to duplicated code, inconsistent login behavior, and slow onboarding when adding new applications to the network.
To solve this, we designed and developed a reusable Laravel SSO package (laraartisan/sso-client) distributed via Composer, allowing authentication to be unified across all applications in the ecosystem.

Why Single Sign-On (SSO) Was Critical
SSO became a key architectural requirement because it:
Removes the need for users to log in separately across multiple applications
Centralizes authentication and session handling in one secure layer
Reduces security risks caused by duplicated authentication logic
Ensures consistent login behavior across all connected systems
Makes onboarding of new applications significantly faster
Instead of maintaining authentication separately in each application, all identity flows now pass through a single, controlled authentication system.

Key Improvements
Unified SSO system across all applications
Environment-based configuration (no hardcoded values)
Plug-and-play integration via Composer
Flexible user mapping per application
Consistent authentication experience across the ecosystem

Impact
New applications can now be onboarded in ~15 minutes
Authentication logic is managed in a single place
Security updates propagate instantly across all systems
Significant reduction in duplicated code
Improved scalability for future expansion of the ecosystem

Tech Stack
Laravel 10/11/12 · PHP 8.2+ · Composer · Blade Components

If you’re managing multiple applications and still duplicating authentication logic across systems, moving to a centralized SSO architecture is a major step toward scalability, security, and long-term maintainability.

How I made a perfect recording button. Simple yet complex thing.

Startup Pipeline Image

Intro

From the start of XSpeak, I wanted it to provide the best possible feel for the user: simple, fast, and responsive. Since it’s a recording app, one of its main components is the button the user presses to record a conversation.

Actually, it’s a control we’re used to in many apps. The simplest example is the standard Voice Memos app on iPhone.

The button looks simple and does two things: starts recording and stops recording. However, behind the scenes, it takes many steps to start the whole pipeline, which is far from simple. In this article, I’m going to cover the technical and usability aspects of a recording button and will try to explain why it’s important to make it work perfectly and why it’s not as simple as it might look.

XSpeak is a fully private app that takes meeting notes live during conversation and helps you in real-time using on-device AI by providing suggestions, relevant context, facts and more as you speak.

Perfect button

I’d call the recording button perfect if it is:

  1. Functional
  2. Responsive

When I say functional, I mean that it should be able to start and stop recording when it’s enabled and I press it. The button should indicate that the state has switched. And for such an operation that usually takes hundreds of milliseconds, that feedback should be immediate.

Let’s imagine that feedback is not immediate and there’s some progress between states. In this case, the user:

  • Has to wait to make sure that recording has actually started.
  • Is out of their natural flow. Instead of focusing on their business, they are monitoring the app’s status.
  • Experiences unnecessary cognitive load as a result: “What just happened? Did it start? How long should I wait?”
  • Loses control over the interface. They cannot correct the error and press stop.
  • Feels slight frustration, as the app temporarily prevents them from doing what they want to do.
  • Misses the instant, tactile feedback expected from a tool.

This discomfort might feel minor for some people. However, when the user does it so many times a day, it might add significant overhead. And that’s not what we should expect from a helping tool.

Two qualities define a perfect recording button: it must be functional and responsive. The press should never wait on the pipeline.

Imperfect case:

  1. User presses a button.
  2. Button is disabled, shows a progress state or simply doesn’t react.
  3. After some time, the button is functional again, and recording is started.

Behind the scenes

Why is starting recording not that simple? When you press the button, the following happens in XSpeak:
Startup Pipeline Image

All these operations happen asynchronously. It means that we lose flow during each, and when we resume, the world could have changed: the user might have pressed the button several more times, previously available resources might have become unavailable, and so on.

Besides that, it launches side management threads that restart the mixer to prevent drift between two sources and restart the transcriber to prevent model context overflow.

Quite a start, isn’t it? Probably, after that, your perception of this simple button will change, sorry for that 🙂

Let’s see how different apps manage this or similar complexity.

iPhone Voice Memos

Voice Memos Button
iOS 26.5
Voice Memos Transition
When I press start, it starts. When I press stop, it stops. Nothing more.

Otter

Otter Button
Otter 1.4.2

Otter Transition

As you can see, the button becomes disabled while it starts recording. This makes me feel slightly uncomfortable every time I press it. I feel unresponsiveness and heaviness. And I need to wait before I can stop recording.

Talat

Talat Button

Talat 0.11.5

Talat Transition

The button is disabled while recording is started. The good thing is that the recording start is quite fast here. However, it still produces a tiny unresponsiveness feeling.

MacWhisper

MacWhisper Button
MacWhisper 13.21.1

MacWhisper Transition

There’s a slight delay between the press of the start button and the appearance of the stop button. Also, the button changes its position after I start recording, which requires additional cognitive effort from me to find it.

Fireflies

Fireflies Button
Fireflies 0.1.30

Fireflies Transition

The button is locked during start.

XSpeak

XSpeak Button

XSpeak 3.7

XSpeak Transition

As you can see, the button reacts instantly to user action. And if you change your mind, it reacts instantly back.

Apps Summary

Implementation

I’ll not write a book here about all the approaches I considered and tried. Instead, I’ll go from a naive approach to the solution I implemented.

Let’s agree that we want instant feedback from the button and will not disable it during our startup chain. Also, let’s declare our states:

Initial States

Each can be started or stopped. Our goal: keep them eventually consistent without ever blocking the user.

The naive approach would be when the user presses the button:

  1. Change S_ui to started.
  2. Launch startup pipeline.

However, the obvious problem would be a race condition. Imagine the following order of operations:

Race Condition Diagram

In the end, we have S_ui = stopped and S_real = started.

We have to linearize this pipeline to prevent such races. The first thing that would help is to prevent start and stop operations from running simultaneously. We’ll use a queue for that:

Queue Diagram

Operations run one at a time, in submission order. No two operations overlap.

We also need to introduce one more state:

One More State Image

When we want to start or stop recording, we submit an operation to the queue. This way no two operations overlap and each operation waits for its time. As a result, we always have S_ui equal to the S_op of the last operation.

However, this results in delayed work that doesn’t start immediately. We still want to give immediate feedback to the user. To achieve that, we’ll work with S_ui from MainActor and with S_real from Queue. This means that when we press the button, S_ui changes immediately, and the work is submitted afterward. The solution gives us the following challenges:

  1. When the actual queue operation starts, the world could have changed, and the operation might not be necessary anymore.
  2. If the queue grows, there might be significant delay. Imagine a situation when the button is pressed 100 times in a row. We’ll have 100 operations 0.5s each, resulting in 50 seconds of work.

The world could have changed during the time we waited for the operation to start. It means the user could have stopped the recording, started it again, or even in a corner case, done it several times. To determine if the operation still makes sense, we should compare each operation’s S_op with the current S_ui and S_real. If S_op is started and S_ui is stopped, we shouldn’t start anymore, so we just exit. The same is true when S_op is stopped, but S_ui is started. Additionally, if S_op already equals S_real, the work is already done, so we exit as well.

This means that the first and the earliest operation whose S_op equals the current S_ui and not equals S_real will perform the work. This change results in a significantly reduced delay between submission and actual work start.

There’s one more thing we should do to improve performance further. Imagine the following order of operations:

Delay Diagram

If the user presses stop when the start operation is already in progress, we have to wait until the start operation finishes. It results in unnecessary delay and extra work.

To resolve this, we’ll treat each suspension point where we schedule async work during our operation as a potential interruption point. After every step that awaits, we’ll check if the target S_ui is still the same. And if it changes, we’ll drop the operation and return.

However, when we change state, like starting physical microphone recording, things become more complex since we should revert that. But that’s already what the opposite operation will do. So for consistency, after any step that changes state, we must finish the operation and then the opposite operation will revert everything. In the end, we’ll have the desired S_real which is equal to S_ui.

Interruption Diagram

At every suspension point we re-check the target state. If it changed, we drop and return.

In practice, there are more complexities because sometimes we have non-standard user flows. But this architecture, where every audio manipulation goes through the queue, allows us to maintain a consistent and reliable state and gives us a good background to improve the app.

All product names, logos, and brands are property of their respective owners. Use of these names, logos, and brands does not imply endorsement.

990 beygirlik Xiaomi YU7 GT resmi olarak görücüye çıkarıldı

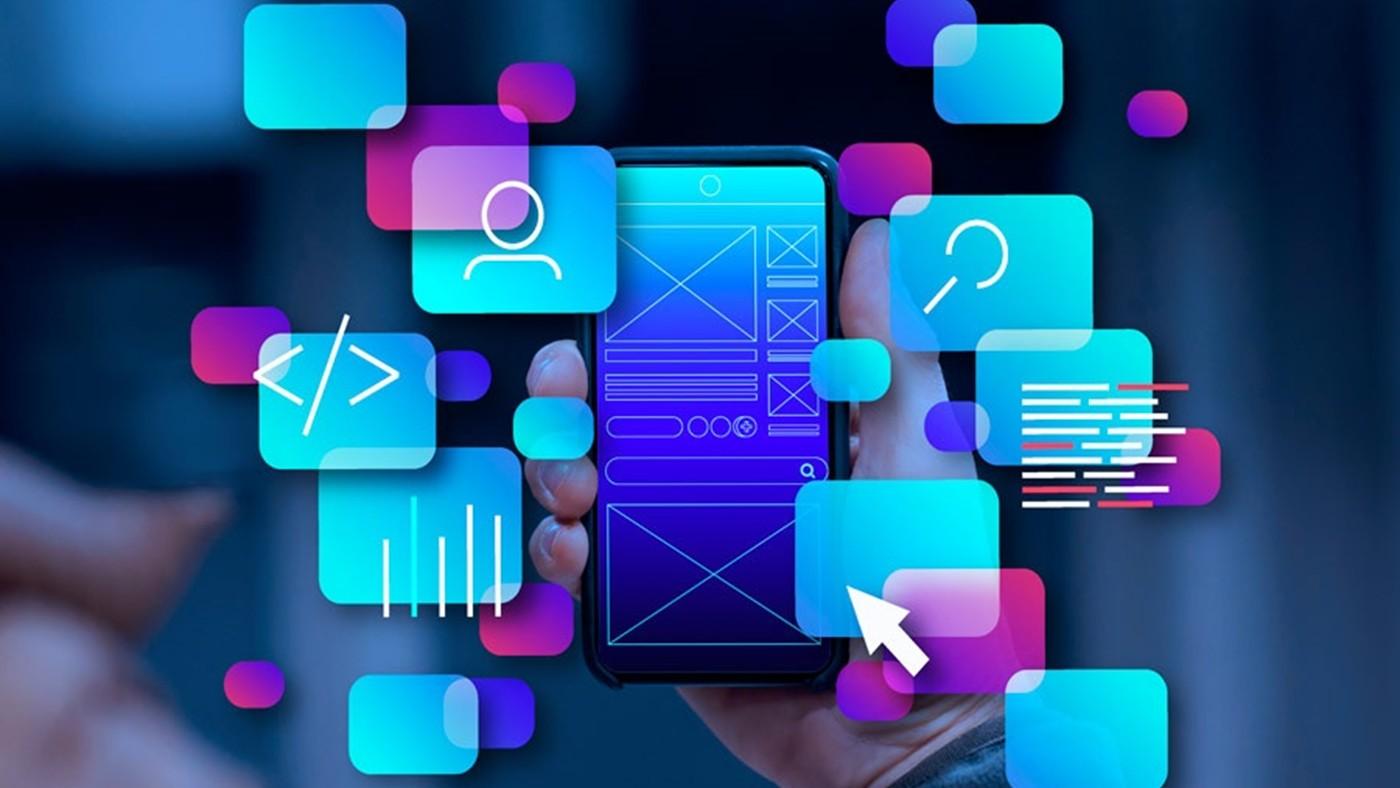
990 beygirlik Xiaomi YU7 GT resmi olarak görücüye çıkarıldı

990 beygirlik Xiaomi YU7 GT resmi olarak görücüye çıkarıldıİlk gösterimi Pekin Otomobil Fuarı kapsamında yapılan tamamen elektrikli SUV modeli Xiaomi YU7 GT, bugün resmi olarak görücüye çıkarıldı. Standart YU7’nin sportif versiyonu olan YU7 GT, Xiaomi’nin V8s EVO motorlarıyla toplam 738 kW (990 beygir) güç sunuyor. 0’dan 100 km/s hıza 2,9 saniyede ulaşan araç, en üstte 300 km/s hıza kadar çıkabiliyor. 101,7 kWh batarya ile donatılan YU7 GT, CLTC özelinde 705 km menzil vadediyor ve uygun şarj istasyonlarında 15 dakikada 570 km menzil kazanabiliyor. YU7 GT’de büyük boyutlu karbon-seramik diskler ile önde altı, arkada ise dört pistonlu yüksek performanslı Akebono kaliperlere yer veriliyor. 100 km/s hızda 32,9 metrelik durma mesafesi sunduğu söylenen YU7 GT, Xiaomi’nin iddiasına göre arka arkaya yapılan 10 farklı 180 km/s’lik tam duruşta bile performans kaybı yaşamıyor. İlk aşamada beş farklı renkte pazara sunulacak sportif SUV, geçtiğimiz hafta elde edilen 7:34.931’lik Nordschleife turuyla önemli bir rekor da kırmıştı. “Ren Zhoucan” tarafından kontrol edilen araç, Audi RS […]

990 beygirlik Xiaomi YU7 GT resmi olarak görücüye çıkarıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Mumbli – my personal Wispr Flow

My text-to-speech journey started roughly a year ago, when I tried it again and was impressed by how much faster it was than typing. I’d been fascinated by Churchill’s use of a stenographer, and I knew it was a more efficient way to write things given proper editor post-processing. I’d tried dictation earlier, about 5 years ago, but it didn’t work out – I tried using dictation and then sending it to people to transcribe, but it wasn’t successful.

A year ago, I tried Whisper models with Python Qt, and it was fine. I used that initial Qt application for some time, but it was a bit ugly and not too easy to use. I found another application for Mac, and used it for a while.

After a year of using it almost every day, I’ve learned how to speak freely without hesitation. It’s not perfect, but it’s much faster, and I’ve been able to produce a lot more. A friend told me about Wispr Flow, which had a nice UI with a small overlay and simple key bindings. Although I didn’t like the Electron application and the marketing, I picked the features I needed, like vocabulary, history of dictations, and key bindings.

That’s how I created Mumbli, and so far, it’s working well – I’m over 3300 transcriptions now. I can tweak it and try new things, like new GPT live transcription models.

The most useful part of owning the stack is that I can actually measure the pieces. Recently I benchmarked the latest 50 saved Mumbli recordings: 2,021 seconds of real dictation, with clips ranging from 0.3s to 293.8s. I ran the same recordings through a few STT providers and measured the time from “audio file is ready” to “transcript is back.”

Provider Model Success Median STT latency p95 latency Audio-judge wins
Groq Whisper whisper-large-v3-turbo 50/50 534ms 1,098ms 2
ElevenLabs Scribe scribe_v1 50/50 2,386ms 7,472ms 25
Interfaze STT interfaze-beta 50/50 8,383ms 13,584ms 6
Tie / skipped – – – – 16 ties, 1 skipped

So the technical result is not “Groq wins everything.” It is more specific: Groq was about 4.5x faster than ElevenLabs on median STT latency in this benchmark, and about 6.8x faster at p95. Compared to Interfaze it was much faster again. But ElevenLabs won the audio-judge comparison more often, so it still looks like the better quality default.

For my personal use, that split matters. Wispr Flow feels good partly because the interaction is tiny: hold a key, speak, release, get text. If the transcript comes back in half a second, the whole app feels different. It is the difference between “this is a transcription job running somewhere” and “this is close enough to typing latency that I keep using it.”

So the setup is not one fixed answer. I can keep a quality-oriented path, and I can keep a fast path. That was the part I wanted from the Wispr Flow-like experience: the tiny overlay and simple hotkeys, but with the ability to swap the engine when the numbers say something interesting.

I’ve put the benchmark notes in the documentation: https://docs.mumbli.app/benchmarks#benchmarks-mumbli-performance. You can also check out the GitHub page: https://github.com/fireharp/mumbli, and the main site: https://mumbli.app/. No huge value here, just a nice tinkering approach – it was pretty fast to do, pretty exciting, and I still use it.