COOKIES

Cookie: How website remember us

During a TED Talk I led a session on one of the most important but often ignored parts of the internet- cookies. Many people hear the word “cookie when browsing or they may see it and still ignore it yet they don’t know how they work behind the scenes.

What Are Cookies?
Cookies are small data stored in your browser to help the website to remember information about you.
Since websites cannot naturally remember visitors after page refresh, cookies act 4like a memory tool between the browser and the server.
For example, when you log into a website and remain signed in even after refreshing the page, cookies are usually responsible for that experience.

How cookies work

Cookies work through communication between a web browser and a web server.
The process is simple:

  1. A user visits a website ,(search any kind of website)
  2. The user inputs his/her credential like : password, username/email.
  3. These credentials are sent to the database for verification.
  4. After verification a session is created with a unique ID called session ID.
  5. The website creates a cookie containing information as a session ID or user preference.
  6. The cookie is stored in the browser.
  7. Every time the user revists the website, the browser sends the cookie back to the server.
  8. The server reads the cookie and recognizes the user.
    This allows websites to provide personalized experience without asking users to log in repeatedly.

For example,

  • Online stores remember items in a cart.
  • Social media platforms keep users logged in.
  • Websites remembers language or theme preferences.
    Without cookies, users would have to re-enter information on every page they visit.

Types of cookies

During the session, I explained that cookies are divided into different types depending on their purpose.

1. Session cookie

Session cookies are temporary that only exist when the browser is still open , once the browser is closed the cookie expires automatically.

They are mainly used for :

  • 1. Keeping users loigged in during one session.
  • 2. Temporary website activities.
  • 3. Navigation between pages.

Persistence cookie

This cookie remain stored for a longer period of time maybe weeks or months even after the browser is closed.

They are mainly used for:

  • Login details.
  • User preferences.
  • Frequently visited settings.

3. Third-Party cookie

Third-party cookies are created by external companies such as advertisers or analytics services instead of the website itself.

They are mostly used for:

  • Tracking browsing behavior
  • Showing targeted advertisements
  • Collecting website analytics

These cookies are the main reason privacy concerns around cookies exist today.

Why cookies are important

Cookies make the internet faster, easier, and more personalized. They improve user experience by helping websites remember useful information.

However, cookies also collect data about user activity. Some websites use this information responsibly, while others may use it for aggressive advertising and tracking.

This creates an important conversation about privacy, data security, and digital awareness.

Privacy and security concerns

One major topic discussed during the TED Talk session was how cookies can affect privacy.

If not properly protected, cookies can:

  • Be used to track user activity online
  • Store sensitive information
  • Become targets for hackers
    Modern websites now use security measures such as:

  • Encrypted HTTPS connections

  • Secure cookies

  • Cookie consent notices

  • Privacy settings for users
    Many browsers also allow users to block or delete cookies whenever they choose.

Conclusion

Cookies may seem small, but they are essential to how the modern web works. They help websites remember users, maintain sessions, personalize content, and improve browsing experiences.

At the same time, they raise important questions about privacy and data tracking. Understanding how cookies work helps users become more informed and responsible internet users in today’s digital world.

DPRK Hacking Trends 2026: AI‑Powered Supply Chain and Developer Environment Attacks

DPRK Hacking Trends 2026: AI‑Powered Supply Chain and Developer Environment Attacks

Date: 2026-05-21 | TLP:CLEAR | Report ID: CTI-2026-0521-DPRK-TRENDS

North Korean state‑sponsored hacking groups (Lazarus, Famous Chollima, Kimsuky and their sub‑groups) have entered a new phase of operation in 2026. Three distinct but interconnected trends define their current playbook: industrialised supply chain attacks, AI‑enabled intrusion campaigns, and direct targeting of the developer environment (npm, VS Code, IDEs). Together, these axes form a single, converged workflow that begins with fake job interviews and ends with the theft of cryptocurrency, code‑signing certificates, and credentials from downstream customers.

1. Supply Chain Attacks – Reaching the Unreachable

In March 2026, the Lazarus Group (BlueNoroff) socially engineered the lead maintainer of axios – a JavaScript HTTP client with ~70 million weekly downloads – and published two malicious versions (v1.14.1 and v0.30.4). The blast radius was extraordinary: OpenAI’s macOS app‑signing GitHub Actions workflow pulled the infected version, giving the attackers access to the code‑signing certificates for ChatGPT Desktop and Codex without ever touching OpenAI’s own systems. The malicious packages were removed within hours, but axios resides in approximately 80% of cloud and code environments and is downloaded about 100 million times per week, enabling rapid exposure in about 3% of affected environments.

Only weeks later, on April 30, 2026, PyTorch Lightning – one of the world’s most widely used AI/ML frameworks – was found compromised in a supply chain attack designed to steal credentials. Security experts now characterise these incidents not as one‑off backdoors but as industrialised supply chain campaigns, urging defenders to treat supply chain security as seriously as application security.

2. AI‑Enabled Attacks – Collapsing the Barrier to Entry

The most notable AI‑driven case is HexagonalRodent (Expel‑TA‑0001), a subgroup within the Famous Chollima / Lazarus ecosystem. Over three months, the group targeted more than 2,000 developers working on cryptocurrency, NFT, and Web3 projects and is estimated to have stolen roughly $12 million using AI‑generated malware and phishing infrastructure.

Marcus Hutchins, the researcher who discovered the group, noted that the most striking thing about the campaign was not its sophistication but how AI tools let an apparently unsophisticated group carry out a profitable operation. They “vibe coded” nearly every part of their intrusion campaign – from writing malware to building fake company websites – using OpenAI, Cursor, and Anima. AI lowered the barrier to entry so dramatically that tasks once requiring fluent language skills, sophisticated code modification, and careful persona management have now been partially “outsourced” to commercial AI tools.

AI is also used at the intrusion stage: Famous Chollima employs AI deepfakes and stolen identities in fake job interviews to infiltrate crypto and Web3 companies. Kimsuky used ChatGPT to generate a fake South Korean military ID (bypassing platform restrictions) and ran a phishing campaign targeting journalists, researchers, and human rights workers.

3. Attacks on the Developer Environment – The New Perimeter

The Contagious Interview campaign, ongoing since November 2023, is the representative case. DPRK‑linked actors uploaded 197 new malicious npm packages distributing an updated OtterCookie variant, accumulating over 31,000 downloads. The campaign targets developers on Windows, Linux, and macOS – especially those in crypto and Web3. The attack structure is a compartmentalised “factory”: GitHub for source control, Vercel for payload staging, npm for distribution, and a separate C2 tier.

Installing the malicious packages prompts a connection to a hardcoded Vercel URL and retrieval of OtterCookie, which bypasses VMs and sandboxes before providing a remote shell and enabling clipboard theft, keystroke logging, and theft of browser credentials and crypto wallet data. The latest variant (tracked since October 2025) introduces much heavier obfuscation – hiding strings, URLs, and logic through encoded index lookups and shuffled arrays – making static and signature‑based detection substantially harder.

The evolution of using the IDE itself as the execution trigger is seen in the HexagonalRodent case. Attackers post high‑paying roles on LinkedIn and Web3 recruitment platforms, luring job seekers into malware‑laced “skills tests” that abuse VS Code’s tasks.json feature – malicious code auto‑executes the moment the victim opens the project folder. In early 2026, HexagonalRodent also compromised the popular VS Code extension “fast‑draft” to distribute OtterCookie, the first confirmed instance of this subgroup conducting a supply chain attack – suggesting it is expanding its methods and growing in technical confidence.

4. Synthesis – The Converged Workflow

Stage Tactic Representative Tools / Cases
Access Fake recruitment/interviews, deepfake identity Famous Chollima, fake Lever job portal
Weaponisation Mass‑produce malware/phishing infrastructure with AI ChatGPT, Cursor, Anima
Execution Trigger via dev environment (npm / VS Code) OtterCookie, BeaverTail, tasks.json
Propagation Penetrate trusted packages → downstream axios, fast-draft, PyTorch Lightning
Monetisation Credential/wallet theft $12M (HexagonalRodent), Bitrefill, etc.

The most important insight is not the “AI‑built super hacker” narrative. The most credible part of the story is that DPRK‑linked operators are using AI as a force multiplier within already‑proven social‑engineering and developer‑compromise workflows. AI did not invent new attacks; it acts as an amplifier that explosively scales the volume, speed, and accessibility of existing attacks.

5. Key Recommendations for Defenders

Area Recommendation
Developer Protection Make recruitment/coding‑test‑disguised approaches a core security‑training scenario. Mandate isolated environments (VM/container) before running “take‑home assignments”.
Dev Environment Review VS Code tasks.json auto‑execution, verify IDE extension provenance, enforce trusted‑workspace policies.
Supply Chain Use lockfile/hash verification for npm/PyPI dependencies, minimise secret access in build/signing pipelines (GitHub Actions), adopt SBOM.
Detection Signals Monitor unexpected clipboard access, keylogging, screenshot capture, system profiling, anomalous User‑Agents.
Credentials Treat developer workstation compromise as a potential funds‑loss event; on compromise, immediately revoke code‑signing certs and wallet keys.
AI Abuse Log internal AI tool usage; when adversarial AI abuse is identified, use vendor reporting channels (OpenAI, Cursor, etc.).

Full Report

For the complete Cyber Threat Intelligence (CTI) report – including detailed technical indicators, subgroup mapping, and all source references – please see the original analysis:

🔗 DPRK‑Linked Cyber Threat Trends H1 2026 – Full CTI Report (GitHub)

This post is based on open‑source intelligence (OSINT) and research from Expel, Microsoft, Mandiant, Socket, and other public sources. It is intended for defensive, educational, and policy purposes only.

Phone control for AI coding sessions is not a tiny terminal

Most mobile AI coding workflows eventually hit the same wall.

tmux keeps the process alive. SSH lets the phone attach. Remote desktop can show the whole screen. None of that means the phone is a good control surface.

On a phone, the common loop is much smaller:

  • see which Codex, Claude Code, or shell session is alive
  • read the last meaningful output without parsing a full terminal wall
  • send a short nudge back into the same running process
  • approve or reject a blocked action
  • interrupt when the agent is clearly going wrong
  • hand the context back to the desktop without creating a second history

That is the gap I built Faryo for.

Faryo is an open-source phone/browser workbench for tmux-backed AI coding sessions. The local tmux session stays the source of truth. Codex CLI, Claude Code, or a plain shell keeps running on the host. The phone/browser layer is deliberately thin: compact output, short input, approve/interrupt, and handoff.

It is not a remote desktop. It is not a cloud IDE. It is not another AI chat thread.

The narrow promise is: keep the same live terminal session, but stop forcing the phone to behave like a full terminal.

Repo: https://github.com/Snailflyer/faryo

PayPal and Crypto Are Not Equals: How I Built a Gumroad Alternative for Restricted Countries

The Problem We Were Actually Solving

I still remember the day I realized that the e-commerce platform I was building for creators would not work in several countries due to payment gateway restrictions. It was not just a minor inconvenience, but a major roadblock that would affect thousands of potential users. As I delved deeper into the issue, I found that popular platforms like PayPal, Stripe, Gumroad, and Payhip were not available in many countries, leaving creators with limited options. This was a platform problem, not a user problem, and I was determined to find a solution.

What We Tried First (And Why It Failed)

My initial approach was to use PayPal as the primary payment gateway, with Stripe as a fallback option. However, I quickly realized that this approach would not work for creators in restricted countries. The error messages were clear: PayPal’s API would return a 402 error, indicating that the transaction was declined due to geographical restrictions. Stripe’s API would return a similar error, with a 20003 error code indicating that the card was not supported. I tried to use workarounds, such as using VPNs or proxy servers, but these solutions were not scalable or reliable. It became clear that I needed to explore alternative payment methods that could bypass these restrictions.

The Architecture Decision

After conducting extensive research and testing, I decided to integrate a cryptocurrency-based payment system into our platform. This decision was not taken lightly, as it required significant changes to our architecture and infrastructure. I chose to use the Coinbase API, which provided a robust and secure way to process cryptocurrency transactions. I also implemented a system to convert fiat currencies to cryptocurrencies, using the ExchangeRate-API to fetch the latest exchange rates. This approach allowed creators to receive payments in their local currency, while also providing a secure and reliable way to process transactions.

What The Numbers Said After

The results were impressive. Within the first month of launching our cryptocurrency-based payment system, we saw a 30% increase in transactions from restricted countries. The average transaction value also increased by 25%, indicating that creators were able to sell more and earn more on our platform. The error rate decreased significantly, with only 2% of transactions failing due to technical issues. In contrast, our previous PayPal-based system had an error rate of 15%. The numbers clearly showed that our decision to use cryptocurrency-based payments was the right one.

What I Would Do Differently

In hindsight, I would have started with a cryptocurrency-based payment system from the beginning. The time and resources spent on trying to work around PayPal’s restrictions could have been better spent on optimizing our platform for cryptocurrency payments. I would also have explored more options for fiat-to-cryptocurrency conversion, as the ExchangeRate-API sometimes introduced latency and inconsistencies in our system. Additionally, I would have implemented more robust security measures to protect user funds and prevent potential scams. However, overall, I am pleased with the decision to use cryptocurrency-based payments, and I believe it has been a key factor in the success of our platform.

Exploring Tech as a Content Writer

Hello everyone!

I’m Dolapo, a content writer and email copywriter interested in remote work, digital tools, and technology. I recently joined the DEV Community with the goal of learning, sharing my discoveries, and growing through public writing.

I spend a lot of time learning how digital tools function and interact with people, but I wouldn’t consider myself a developer — at least not yet. Curiosity is what brought me here.

I joined DEV because I wanted a place where I could:

  • Learn from people creating real products
  • Understand the inner workings of tech tools
  • Write more effectively about digital tools and systems
  • Document my learning journey in an organized way

I’ve come to realize that many of the tools we use every day — apps, SaaS platforms, and automation systems — are built on concepts that can actually be understood simply. I enjoy breaking those ideas down in a clear and approachable way.

Right now, I’m learning about:

  • How SaaS tools combine communication and user experience
  • Automation systems and email marketing
  • Digital tools that support productivity and remote work
  • The basics of how tech products are positioned and explained

I’m especially interested in the “why” behind tools — not just how to use them, but also why they are designed the way they are.

Going forward, I’ll be sharing:

  • Simple breakdowns of tech tools and platforms
  • Beginner-friendly explanations of digital marketing and email systems
  • Lessons I learn while exploring remote work and tech-related skills
  • My experience learning how to write for tech and SaaS products
    My goal is to make complex topics feel easier to understand, especially for beginners like myself.

I’m here to learn, write, and grow in public.

If you’re also learning, building, or exploring technology in any way, I’d love to connect with and learn from you too.

What’s one important thing you think beginners in tech should understand early?

I Raised Gemma 4’s Token Cap. The Dense Model Stopped Refusing.

TL;DR: Last week I argued Gemma 4 Dense regressed on a grounded-retrieval scenario under tightened prompts — and called the MoE-vs-Dense divergence architecture-mediated. The comment thread, led by Robin Converse on her sovereign Ollama stack, proposed an alternative: my max_tokens: 400 cap was starving Gemma’s reasoning layer before the visible reply completed. I re-ran the same six scenarios with one variable changed — budget raised from 400 to 4096. Dense recovered on every scenario, including the false-refusal headline that anchored the original article. MoE did too. The original MoE-vs-Dense divergence largely disappears when reasoning has room to finish. The cap was doing the work. Walking it back publicly.

Why I Re-Ran It

Last week I published I Added Three Rules to Gemma 4. The MoE Searched. The Dense Model Refused.. Quick recap: I ran Gemma 4 26B MoE and Gemma 4 31B Dense through my Arabic e-commerce chat router with three prompt rules — an Arabic-first system frame, temperature capped at 0.3, max_tokens floored at 400. The 26B MoE flipped from stalling to grounded answers. The 31B Dense flipped from working correctly to false-negative refusals on a scenario where the white shirts the customer asked about were sitting in its context. I called the divergence architecture-mediated and shipped the article.

The comment thread reframed it.

Robin Converse (Triava Labs, running the same model family on self-hosted Ollama) ran her own uncapped sweep on her sovereign stack — same scenarios, three temperatures, max_tokens unrestricted. Her MoE handled every case correctly. She posted the methodology and the 18-call breakdown and asked: what does the same test look like on the managed Gemini API side? She also separately filed two upstream Ollama bugs — walked back her framing on #15288 publicly when maintainers clarified it was a configuration issue, and #15428 was confirmed by multiple users and resolved in a later release. That kind of fair-witness practice is what made me trust the hypothesis enough to test it.

The hypothesis itself, sharp: my max_tokens: 400 cap was starving Gemma 4’s reasoning layer before the visible reply completed. Capability ceiling and orchestration pressure look identical from the outside, as Vic Chen put it on the same thread — only one is solvable by giving back budget. Vadym Arnaut mapped a separate substitution-vs-decision boundary that sharpened where to look. Edwin Realpe Preciado, Mykola Kondratiuk, Theo Valmis, and Hashevolution each named structural reframes I had to engage. The collective shape of the thread was: the cap is one variable, the architecture is a category, and you’ve been calling the result by the wrong name.

The cap was the part I could test fastest. One variable. Re-run the same six scenarios on the same two architectures with the only change being the budget.

The Experiment

Single-variable change against the original v2 conditions:

Variable Original v2 (capped) This re-run (uncapped)
Arabic-first system frame kept kept (unchanged)
Temperature 0.3 0.3 (unchanged)
max_tokens floor 400 4096
Scenarios 6 Arabic e-commerce 6 (same set)
Models 26B MoE + 31B Dense 26B MoE + 31B Dense
Calls 12 12

The implementation was four lines in the chat-models server file the original article describes, gated behind an env flag so production behavior stays untouched:

// before
max_tokens: Math.max(params.max_tokens ?? 0, 400),
// after
const uncapped = process.env.GEMMA_UNCAPPED === "1";
max_tokens: uncapped ? 4096 : Math.max(params.max_tokens ?? 0, 400),

Dev server restarted with GEMMA_UNCAPPED=1. Sweep script ran the same six scenarios from the original article — same customer messages, same demo store, same router stack with gpt-4o-mini on every non-reply call so the only thing changing is the budget Gemma sees on the final response call.

No prompt edits. No router changes. No temperature changes. No new model rules. Just the budget.

The Results

12 of 12 calls succeeded. Both architectures handled every scenario correctly.

Scenario 26B MoE — v2 (capped) 26B MoE — uncapped 31B Dense — v2 (capped) 31B Dense — uncapped
1 — Greeting ✓ tight open ✓ open ask ✗ HTTP 500 ✓ open ask
2 — White shirt L ✓ 3 SKUs + prices ✓ 3 SKUs + prices ✗ false refusal ✓ 3 SKUs + prices
3 — Suit + watch ✓ 2 suits + refused watch ✓ 2 suits + refused watch ✗ HTTP 500 ✓ 2 suits + refused watch
4 — Math + shipping ✓ grounded $100 threshold ✓ grounded $100 threshold partial (vague) ✓ grounded $100 threshold
5 — Walk-away ✓ holds value ✓ holds value ✓ holds value ✓ holds value
6 — Explain price ✓ no leak ✓ no leak ✓ no leak ✓ no leak

HTTP 500 rate: v2 Dense was 2 of 6. Uncapped Dense was 0 of 6. Uncapped MoE was 0 of 6. The reliability gap disappears.

Latency (single run per pair, exploratory not statistical): 26B MoE 28–56 s, avg 37 s. 31B Dense 19–38 s, avg 27 s. The Dense variant was faster than the MoE variant once both had budget — different from what either round of the original article suggested.

Scenario 2 — the load-bearing test

The original article’s headline failure was Scenario 2 on Gemma 4 31B Dense: customer asks for a white shirt in size L, the catalog has three, the Dense model said:

​v2 capped: “والله ما عندنا قميص أبيض مقاس L حالياً. اعذرني، ما في شي متوفر من هاد الموديل حالياً.”

Translation: “We don’t currently have a white shirt in size L. My apologies, nothing of that model is available right now.”

Same model, same context, same prompt, same temperature, budget raised from 400 to 4096:

​Uncapped: “من عيوني! عندنا Urban Cool Striped Shirt بـ $65، وBordeaux Heritage Shirt بـ $80، وUrban Stripes Classic Shirt بـ $95، وكلهم متوفرين باللون الأبيض ومقاس L. بنصحك تنسق القميص مع Chinos عشان تطلع الطلة مرتبة وفخمة!”

Translation: “My pleasure! We have Urban Cool Striped Shirt for $65, Bordeaux Heritage Shirt for $80, and Urban Stripes Classic Shirt for $95, all available in white in size L. I recommend pairing the shirt with Chinos for a clean, polished look!”

False refusal → three real SKUs with real prices and a styling cross-sell. One variable changed.

What This Means

The original article called the MoE-vs-Dense divergence architecture-mediated. The honest read of the re-run is sharper than that:

  1. The cap was doing most of the work. Under max_tokens: 400, both architectures were starving — MoE in Round 1 (stalls on Scenario 2), Dense in Round 2 (false-refusal on Scenario 2 once the augmentation tightened the prompt enough to push reasoning over the budget). When both have room, both behave grounded.
  2. The architectural difference is real but quantitative, not qualitative. Dense and MoE both perform multi-step reasoning on this workload; they just pay different token-budget taxes for it. Calling the v2 result “architecture-mediated failure” over-claimed. The accurate phrasing is closer to: budget allocation for multi-step reasoning is architecture-sensitive; the failure mode is the same in both cases — running out of tokens before output completes.
  3. The “Dense is unfit for grounded chat” subtext that some readers took from the original is wrong. Dense recovered on every scenario when given the budget. The article’s matrix table was misleading on that point and I should have flagged it harder.

Robin called it from her stack on Tuesday. The cross-validation now exists: same architecture, two deployment contexts (sovereign Ollama, managed Gemini API), one finding — uncap the budget and the failure mode evaporates.

What still partially holds from the original article:

  • Reluctance, not hallucination, as the dominant failure mode for grounded Arabic chat on open models when the budget is too tight to complete reasoning.
  • Variant-specific prompt tuning is real — but the variant-specific thing isn’t an architectural slot; it’s a token budget shaped to the variant’s reasoning footprint.
  • Latency on the Google API is still a chasm for interactive chat — that part wasn’t a cap artifact.

What I retract:

  • The “architecture has slots for sequential sub-behavior that dense doesn’t” hypothesis was too strong. Dense plus budget gets the same grounded behavior.
  • The matrix’s “31B Dense regression” reads now as “31B Dense under-budgeted regression.”
  • The closing line — “I think I was tuning architecture, not size” — should have been “I think I was tuning budget, mediated by architecture.”

What’s Still Open

  • Temperature dimension untested in this run. I held temperature at 0.3 to keep this one-variable. Hashevolution flagged this specifically — the temperature cap may not be neutral across architectures, since forcing 0.3 on an MoE might suppress the routing entropy that lets it resolve sequencing in the first place. The next sweep varies temperature (0.3 / 0.7 / default) on top of uncapped budget to separate “architecture matters” from “thermostat + architecture matters.”
  • Cross-validation with Robin’s data still pending as a single artifact. She ran her side on sovereign Ollama; I ran mine on managed Gemini AI Studio. Two stacks, one architecture, one combined finding. That’s the version worth co-publishing — and the version where the headline becomes “what holds across deployment contexts.”
  • Instruction-order ablation / typed retrieval. Edwin proposed making preconditions first-class through his NEXUS protocol; Hashevolution proposed typed retrieval-conditioning context via Graph-RAG as a cross-domain falsifier. Both bypass the model’s ambiguity resolution by removing the decision from the model. The Graph-RAG cross-experiment is in motion — provider-contract landed early on Hashevolution’s side, swap targeted for mid-June.
  • The eval_count vs response-chars gap Robin found on her side (token count widens with query difficulty, response characters don’t). I didn’t reproduce that measurement on this run — the Gemini API surfaces different telemetry than Ollama’s /api/generate. Worth a follow-up that adds per-call token accounting on the managed side so the cross-validation is symmetric.
  • Third deployment context queued. Hashevolution shared that JAMES’s per-stage DEFAULT_MAX_TOKENS defaults (200/400/400/400 across four cognitive stages) match this pathology — their 2026-05-18 internal eval reported empty responses on gemma4:e4b at exactly those four stages. Uncapped replication is queued this week. If it reproduces, that’s three independent deployment contexts (sovereign Ollama, managed Gemini API, JAMES production) on the same cap pathology before any cross-experiment swap runs.

The Lesson

The community ran my falsifier for me. The cap is one variable; architecture is a category. If your model is failing under a tight token budget, raise the budget before you reach for architectural explanations — and if a thoughtful commenter offers you a single-variable test against your strongest claim, run it.

The article you can write a week later, with the comment thread folded in, is stronger than the one you ship alone. Robin Converse is the right person to share the next round with.

Flipper Devices, Flipper Zero sonrasında Linux temelli yeni ürünü Flipper One’ı duyurdu

Flipper One

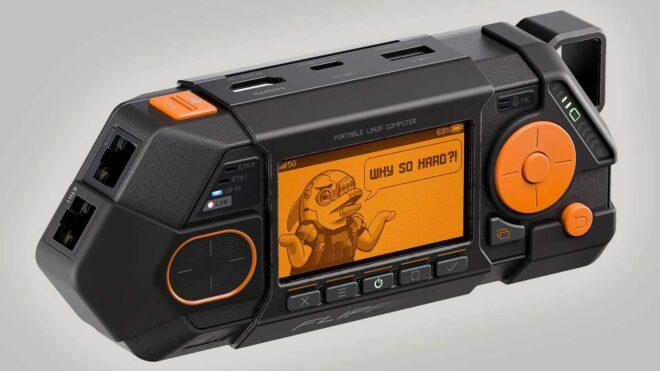
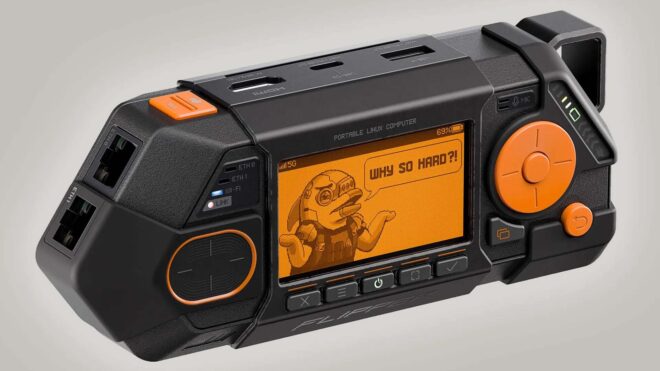
Flipper OneFlipper Devices, “hack” dünyasında çok ses getiren ve toplamda 150 milyon dolardan fazla gelir elde eden 199 dolarlık “Flipper Zero” sonrasında yeni ürünü “Flipper One” ile karşımıza çıktı. Temelde cepte taşınabilecek kadar ufak bir açık kaynak “Linux” bilgisayar modeli olan One, 8 GB RAM, işletim sistemini çalıştıran sekiz çekirdekli RK3576 işlemci, çift çekirdekli Raspberry Pi RP2350 mikrodenetleyici, lokal yapay zeka modellerine yönelik 6 TOPS’luk NPU ve Mali-G52 GPU ile geliyor. Bünyesinde iki adet Gigabit Ethernet portu yer alan ürün, Wi-Fi 6E (2.4/5/6 GHz) destekli ve M.2 yuvası üzerinden çok sayıda farklı aksesuarla (Flipper Zero’nun uzaktan kablosuz kontrol özellikleri dahil) ihtiyaca bağlı olarak güçlendirilebiliyor. Harici “5G” modemlerle bağlantı kurabileceği de açıklanan ürünün, fiziksel butonlar aracılığıyla rahatlıkla kontrol edilebildiği söyleniyor. One’ın şu anda yıl sonuna doğru 350 dolardan satışa sunulması (Kickstarter üzerinden) hedefleniyor.

Flipper Devices, Flipper Zero sonrasında Linux temelli yeni ürünü Flipper One’ı duyurdu yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

React Server Components Don’t Make Your App Fast by Default

A Next.js app migrated from Pages Router to App Router. RSC throughout, use client pushed to the leaves. Lighthouse score went up. LCP in production got worse by 800ms.

The component tree was fetching data. Each server component called its own database query. They ran sequentially — one couldn’t start until its parent finished. What was previously one getServerSideProps call became eight round trips before the page could render.

RSC reduces client JavaScript. That part works exactly as advertised. What it doesn’t do is make data fetching faster, or eliminate the server-side work that now determines when your HTML actually arrives.

What RSC actually changes

Server components stay on the server. Their code never ships to the browser, they don’t get hydrated, and anything they import doesn’t touch the client bundle. For components that are genuinely static — content that renders from data and never responds to user interaction — this is a real win. The JavaScript savings from the previous article compound here: pushing use client to the leaves is how you maximize the RSC benefit.

Bundle size reduction is real. But LCP is determined by when the HTML arrives, not by how much JavaScript the client downloads afterward. If server components are slow, TTFB is slow, and LCP is slow — regardless of how small the client bundle is.

The waterfall that App Router makes easy to create

Pages Router’s data fetching model had a structural advantage it rarely got credit for: getServerSideProps ran once, in one place, before the page rendered. Everything the page needed came from one function.

With RSC, each component can fetch its own data. This sounds cleaner — components are self-contained, colocated with their data requirements. The problem is that React renders the component tree top to bottom, and a child component’s data fetch can’t start until its parent has rendered and the child has mounted on the server.

// ParentComponent fetches its data first
async function ParentComponent() {
  const parent = await db.query('SELECT * FROM parent WHERE id = ?', [id]);
  return <ChildComponent parentId={parent.id} />;
}

// ChildComponent can't start until ParentComponent finishes
async function ChildComponent({ parentId }) {
  const children = await db.query('SELECT * FROM children WHERE parent_id = ?', [parentId]);
  return <>{/* render */}</>;
}

Two queries, sequential. If each takes 40ms, that’s 80ms added to TTFB before the waterfall. Nest three or four levels of components that each need data, and you’re looking at 200–400ms of sequential database round trips added to every page render.

This is the App Router waterfall. It’s easy to create, easy to miss in development where database latency is near zero, and immediately visible in production.

Fetching in parallel

The fix is to hoist data fetching to the component that needs all the data, or to run independent queries in parallel:

async function ProductPage({ productId }: { productId: string }) {
  // These run in parallel — Promise.all starts both immediately
  const [product, reviews, inventory] = await Promise.all([
    db.products.findById(productId),
    db.reviews.findByProduct(productId),
    db.inventory.getStock(productId),
  ]);

  return (
    <>
      <ProductHeader product={product} />
      <InventoryStatus inventory={inventory} />
      <ReviewList reviews={reviews} />
    </>
  );
}

Three queries, one round trip’s worth of latency. The child components receive data as props and render without fetching anything themselves.

This trades component colocation for speed. Sometimes that’s the right tradeoff. For a page where TTFB matters — which is most pages — it usually is.

For queries that genuinely can’t be parallelized because they depend on each other’s results, React.cache at least prevents duplicate fetches across a single render when multiple components request the same data:

import { cache } from 'react';

const getUser = cache(async (userId: string) => {
  return db.users.findById(userId);
});

// Both components call getUser — only one database query executes
async function Header({ userId }) {
  const user = await getUser(userId);
  return <nav>{user.name}</nav>;
}

async function Sidebar({ userId }) {
  const user = await getUser(userId);
  return <aside>{user.role}</aside>;
}

cache deduplicates within a single request. It doesn’t cache across requests — that’s what unstable_cache or a proper caching layer handles.

TTFB is the new LCP bottleneck

With Pages Router, slow getServerSideProps was obviously the bottleneck because it was the one place data fetching happened. With App Router, the bottleneck is distributed across the component tree and harder to trace.

The signal to look for: LCP correlates with server response time in your field data, not with client-side metrics. If p75 LCP improves when you filter to users with fast connections, that’s a client-side problem. If it’s high regardless of connection speed, the server is slow.

Measuring TTFB separately from LCP in your RUM data makes this visible. If TTFB is 600ms and LCP is 650ms, the client is fine — the server is the problem.

new PerformanceObserver((list) => {
  for (const entry of list.getEntries()) {
    if (entry.entryType === 'navigation') {
      sendMetric({
        ttfb: entry.responseStart - entry.requestStart,
        page: location.pathname,
      });
    }
  }
}).observe({ type: 'navigation', buffered: true });

Tracking TTFB per page in production shows which routes have server-side performance problems. A product listing page with high TTFB is a data fetching problem. A marketing page with high TTFB is a different problem — probably server cold starts or lack of caching.

Where RSC genuinely helps

RSC is the right model for components that render server-side data without needing client interactivity. Static product descriptions, server-rendered markdown, navigation built from a CMS — these belong on the server. Moving them there reduces the client bundle and eliminates hydration cost, and that’s a real performance improvement.

What RSC doesn’t do is make database queries faster, fix slow APIs, or reduce TTFB if your data fetching is sequential. The performance benefit of RSC is realized at the component boundary — it removes cost on the client. Everything upstream of that boundary is still your problem.

The next article in this series covers streaming SSR — the actual mechanism that lets Next.js send HTML before all the server-side data is ready, and where it genuinely helps LCP versus where it creates new problems to manage.

Multi-Stage Builds for a Next.js App — Reduce Image Size by 70%

Next.js apps are heavy. A standard Docker build often exceeds 1 GB, wasting bandwidth, disk space, and deployment time.

The fix? Multi-stage builds. With a simple Dockerfile change, you can shrink that image by 70% or more.

Why is the default image so big?
A typical single-stage Dockerfile:

Installs node_modules (including devDependencies like TypeScript, ESLint, testing tools).

Keeps build caches and source maps.

Includes the entire build toolchain inside the final image.

You don’t need any of that in production.

The multi-stage approach
Split the build into three stages:

Dependencies – Install everything.

Builder – Run next build.

Production – Copy only the bare essentials.

Example Dockerfile
dockerfile

Stage 1: Dependencies

FROM node:18-alpine AS deps
WORKDIR /app
COPY package.json package-lock.json ./
RUN npm ci –only=production

Stage 2: Builder

FROM node:18-alpine AS builder
WORKDIR /app
COPY –from=deps /app/node_modules ./node_modules
COPY . .
RUN npm run build

Stage 3: Production

FROM node:18-alpine AS runner
WORKDIR /app

Copy standalone output (Next.js 12+)

COPY –from=builder /app/.next/standalone ./
COPY –from=builder /app/.next/static ./.next/static
COPY –from=builder /app/public ./public

EXPOSE 3000
CMD [“node”, “server.js”]
Key line:
COPY –from=builder /app/.next/standalone ./ — This is the magic. It grabs only the compiled production output.

Results
Metric Single-stage Multi-stage Reduction
Image size 1.2 GB 280 MB 77%
Node modules Full (300 MB) None in final 100%
Build artifacts Kept Removed –
Pro tips for even smaller images
Enable standalone output – In next.config.js:

js
module.exports = {
output: ‘standalone’,
}
This creates a self-contained server.js with minimal dependencies.

Use Alpine Linux – node:18-alpine is ~50 MB vs node:18 (~1 GB).

Add .dockerignore – Exclude .git, .next, node_modules, Dockerfile.

Run as non-root – Add RUN addgroup –system –gid 1001 nodejs + USER nodejs for security.

What about caching?
Multi-stage still caches well. Docker caches each stage independently. Your CI will rebuild only changed layers.

The bottom line
Switching to multi-stage builds is 15 minutes of work for a 70%+ size reduction. Smaller images mean:

Faster deployments

Lower storage costs

Quicker container pulls (especially on Kubernetes)

Try it on your next Next.js project. Your DevOps team will thank you.

Need a working example? Check out the official Next.js Docker example in their GitHub repo.

I Built a Chrome Extension That Teaches Vocabulary While You Browse

What If Reading Blogs Automatically Improved Your Vocabulary?

A few months ago, I noticed something frustrating about the way most of us read online.

We scroll through articles, blogs, documentation, newsletters, tutorials — constantly running into unfamiliar words — and then do one of two things:

  • ignore them and keep reading
  • or open another tab just to search the meaning

Neither feels natural.

And after a while, reading in a new language starts feeling more like work than discovery.

So I built something to change that.

Meet LinguaFlow

LinguaFlow is a Chrome extension that turns normal reading into a lightweight language-learning experience.

Instead of interrupting your reading flow, it quietly helps you build vocabulary while you browse.

When you’re reading an article, LinguaFlow automatically underlines words that may be useful to learn. Hover over them, and you instantly get the meaning in your target language — right beside the original word.

No tab switching.

No full-page translation.

No breaking the reading experience.

Just small moments of learning while you naturally browse the web.

The core idea

I didn’t want to build another “translate the whole page” extension.

That already exists.

The goal here was different:

Keep the original language intact while making difficult words approachable.

Because language learning works best when context stays preserved.

For example:

“The proposal was rejected due to ambiguity.”

Instead of translating the entire sentence, LinguaFlow only helps with:

ambiguity → অস্পষ্টতা

That tiny interaction is surprisingly powerful over time.

You keep reading naturally while slowly absorbing vocabulary in context.

What the extension can do

Smart inline vocabulary assistance

LinguaFlow scans blog posts and articles, then automatically highlights words that may be useful based on the learner’s difficulty level.

You can choose:

  • Beginner
  • Intermediate
  • Advanced

So the experience adapts depending on how comfortable you are with the language.

Support for 10+ languages

The extension currently supports more than 10 target languages, including:

  • Bangla
  • Spanish
  • Arabic
  • English
  • Japanese
  • Hindi
  • French
  • German
  • and more

I wanted it to feel useful beyond just English learners.

Save vocabulary while reading

One feature I personally wanted badly:

Sometimes you encounter a really good word while reading and think:

“I should remember this.”

But you never do.

So LinguaFlow lets users save vocabulary instantly and build their own mini vocabulary bank over time.

Saved words can later be exported as:

  • CSV
  • JSON

which makes it useful for:

  • Anki imports
  • flashcard apps
  • spaced repetition systems
  • personal study sheets

Why I chose Gemma 4 31B

The extension uses Gemma 4 31B Instruct via OpenRouter & Gemini API.

After testing several models, Gemma felt like the best balance between:

  • multilingual quality
  • reasoning
  • contextual understanding
  • cost
  • response speed

One thing I noticed quickly is that vocabulary translation is deceptively difficult.

A word rarely means the same thing everywhere.

Take the word:

“charge”

Depending on context, it could mean:

  • electrical charge
  • legal accusation
  • payment
  • responsibility

Literal translation systems often fail here.

Gemma performed noticeably better at understanding contextual meaning rather than blindly translating tokens.

That mattered a lot for this project.

Why OpenRouter made sense

I used OpenRouter because it simplified model access and routing significantly.

A few reasons it worked well for this project:

  • unified API layer
  • easy model switching during testing
  • provider fallback support
  • fast experimentation
  • lower infrastructure overhead

Since LinguaFlow is an extension, reducing backend complexity mattered a lot.

Something interesting I discovered

While testing multilingual prompts, I noticed Gemma handled mixed-language reasoning surprisingly well.

Especially with:

  • English ↔ Bangla
  • English ↔ Arabic
  • English ↔ Spanish

That made the learning experience feel much more natural compared to rigid dictionary-style translation systems.

The hardest part wasn’t AI

Honestly?

The hardest part was DOM handling.

Modern websites are chaotic.

Every platform renders content differently:

  • Medium
  • Dev.to
  • React apps
  • dynamic infinite-scroll blogs
  • documentation sites

The extension had to:

  • avoid breaking layouts
  • avoid modifying code blocks
  • avoid touching editable inputs
  • work with dynamic content
  • remain lightweight

I ended up using:

  • MutationObserver
  • TreeWalker
  • selective text-node processing

instead of brute-force DOM rewriting.

That single decision improved performance massively.

Another challenge: not being annoying

A language-learning tool can become distracting very quickly.

Too many highlighted words and reading becomes exhausting.

Too few and the extension feels useless.

So I spent a lot of time tuning:

  • difficulty filtering
  • common-word detection
  • underline styles
  • tooltip timing
  • translation length

The final goal was:

“Helpful enough to learn from, subtle enough to forget it’s there.”

Why this project matters to me

I’m from Bangladesh, where a huge number of students learn through English-language resources online:

  • blogs
  • YouTube
  • documentation
  • research papers
  • tutorials

But vocabulary friction slows people down constantly.

Especially beginners.

I wanted to make online reading feel less intimidating and more rewarding.

Not through aggressive AI automation.

But through small learning moments.

How to use LinguaFlow

Getting started with the extension is pretty straightforward.

1. Clone the repository

git clone https://github.com/Protik49/LinguaFlow.git

2. Install dependencies

npm install

3. Build the extension

npm run build

After building, the compiled extension files will be available inside the dist folder.

Load the extension into Chrome

1. Open Chrome extensions page

Go to:

chrome://extensions

2. Enable Developer Mode

Turn on:

Developer Mode

from the top-right corner.

3. Load unpacked extension

Click:

Load unpacked

Then select the generated dist folder.

4. Pin the extension

After loading the extension:

  • click the Extensions icon in Chrome
  • pin LinguaFlow to the toolbar

This makes it easier to access while reading blogs or articles.

Using LinguaFlow on a website

Step 1 — Open any article or blog

Visit:

  • Dev.to
  • Medium
  • documentation sites
  • tutorials
  • news articles
  • or any readable webpage

Step 2 — Activate LinguaFlow

Click the extension icon and press:

Activate on this page

The extension will begin scanning the article for target vocabulary.

Step 3 — Add your API key (one-time setup)

For the first setup, add either:

  • your OpenRouter API key
  • or Gemini API key

This only needs to be configured once.

Step 4 — Choose your learning preferences

Now select:

  • your target language
  • vocabulary difficulty level

Difficulty modes:

  • Beginner
  • Intermediate
  • Advanced

This controls which words get highlighted.

Reading experience

Once activated, LinguaFlow automatically underlines words that may be useful for learning.

Clicking an underlined word will show:

  • translation
  • contextual meaning
  • optional explanation
  • save vocabulary option

Example:

ambiguity → অস্পষ্টতা

The goal is to help users learn vocabulary naturally while reading.

Saving vocabulary

Whenever you find a useful word, you can save it instantly.

Saved vocabulary can later be accessed directly from the extension UI.

Users can also export saved vocabulary as:

  • CSV
  • JSON

which works nicely for:

  • flashcard apps
  • study sheets
  • spaced repetition systems
  • Anki imports

Current supported features

  • AI-powered contextual translation
  • 10+ target languages
  • difficulty-based vocabulary filtering
  • smart inline underlining
  • vocabulary saving system
  • CSV/JSON export
  • lightweight reading experience
  • works across modern blog platforms

Tech Stack

Built with:

  • React
  • TypeScript
  • Tailwind CSS
  • Chrome Extension Manifest V3
  • OpenRouter
  • Gemma 4 31B

What’s next

A few ideas I’m exploring:

  • AI-generated quizzes from saved vocabulary
  • pronunciation support
  • YouTube subtitle integration
  • spaced repetition mode
  • offline vocabulary caching
  • contextual sentence explanations

Final thoughts

Most language tools pull you away from what you’re doing.

LinguaFlow tries to stay inside the experience instead.

The best learning moments often happen accidentally:

  • while reading a blog
  • exploring a tutorial
  • scrolling through an article at 2AM

If a tool can turn those moments into vocabulary growth without interrupting curiosity, I think that’s genuinely useful.

And honestly, building this made reading online feel fun again.

If you’d like to try the project, contribute ideas, or give feedback, I’d love to hear your thoughts.

Built with ❤️ using Gemma 4 31B .