I Finally Understood Elasticsearch After Thinking About Libraries

Imagine Elasticsearch as a huge digital library system, and Apache Lucene as the high-performance search engine library working behind the scenes. Elasticsearch is built on top of Lucene to provide distributed storage and extremely fast searching capabilities.

A library contains different corners or sections based on genres like cybersecurity, history, fiction, science, etc. Similarly, Elasticsearch contains indexes, where each index stores a collection of similar types of data.

Inside those sections, shelves contain books. In Elasticsearch, indexes contain documents, which are the actual units of stored data.

Now imagine a librarian helping visitors search for books. That librarian is similar to a node in Elasticsearch.

Technically, a node is a system/server running Elasticsearch that:

  • stores data
  • processes requests
  • searches data
  • communicates with other nodes

Logically:

  • Library system → Elasticsearch Cluster
  • Genre section → Index
  • Book → Document
  • Librarian/server → Node

Now imagine the library becomes extremely large and suddenly 50 visitors arrive at the same time. If only one librarian is responsible for searching every book requested by all 50 visitors, the process becomes very slow and inefficient.

To solve this problem, the library divides the books into smaller portions and distributes them across multiple librarians. In Elasticsearch, this concept is called sharding.

A shard is a smaller partition of an index. Instead of storing the entire index on one node:

  • Elasticsearch splits the data into shards
  • distributes those shards across multiple nodes
  • allows searches to happen in parallel

This improves:

  • performance
  • scalability
  • speed

Elasticsearch also creates replica shards, which are copies of primary shards. Replica shards help with:

  • fault tolerance
  • high availability
  • faster searching

So, shards can be distributed across multiple nodes, and all nodes work together as part of a cluster.

If one node contains information related to a search request, it communicates with other nodes internally to retrieve or share data. This node-to-node communication happens through the transport interface.

Elasticsearch nodes communicate using two interfaces:

1) HTTP Interface (Port 9200)

Used by:

  • clients
  • applications
  • Postman
  • curl
  • Kibana

to interact with Elasticsearch.

When a client sends a request:

  • the node receiving the request becomes the coordinating node
  • this node manages and routes the request internally

The coordinating node checks:

  • which shard contains the required data
  • which node contains that shard

Then, the request is sent to other nodes through the transport layer using TCP communication on port 9300.

Each node searches its own shards in parallel, and the results are returned back to the coordinating node, which merges the responses and sends the final result back to the client through the HTTP interface on port 9200.

Important:
Any node in Elasticsearch can act as a coordinating node.

2) Transport Interface (Port 9300)

Used internally by Elasticsearch nodes for:

  • node-to-node communication
  • shard coordination
  • replication
  • cluster communication
  • remote cluster communication

This communication happens using a high-performance binary TCP protocol.

There is also an important concept called binding address and publish address.

Binding Address

Defines where Elasticsearch listens for incoming traffic.

In simple words:

“Which IP + port should Elasticsearch accept connections on?”

When Elasticsearch starts, it tells the operating system:

“Send incoming traffic for this IP and port to me.”

Publish Address

Defines the address Elasticsearch shares with other nodes and clients.

In simple words:

“Which address should other nodes use to communicate with me?”

Now, how is Elasticsearch optimized for extremely fast searching?

Suppose you search:

"I love cybersecurity"

Elasticsearch does not scan every document one by one.

Instead, when new data is stored, Elasticsearch:

  • breaks text into smaller tokens/words
  • creates an inverted index

An inverted index stores mappings like:

Word Documents
love Doc1, Doc7
cybersecurity Doc1, Doc3
elasticsearch Doc2, Doc5

So instead of checking every document during a search, Elasticsearch directly jumps to the documents containing the required tokens.

This is one of the major reasons why Elasticsearch is extremely fast and scalable even when handling massive amounts of data.

🚀 My First Day in the Cloud: How I Built a Secured Digital Fortress in Azure

Many people think learning “Cloud Computing” means watching videos and memorizing words. But to actually become a real engineer, you have to get your hands dirty.

Today was my very first day building live systems inside Microsoft’s global network (Azure). I didn’t just build a cloud computer; I wrapped it in high-tech security gates to protect it from hackers.

Here is exactly what I did, told in plain, simple English.

🏰 The Analogy: Building a Secret Bank Vault

To understand what I built today, imagine you want to rent a secure vault inside a giant, high-tech fortress (the Cloud Data Center) to store important data.

[ Hacker / Stranger ] ────► ❌ Main Security Guard
│
[ Abhishek’s Laptop ] ────► ✅ Private Gatehouse
│
▼ (Bypassed Router Block via Secret Tunnel)
┌──────────────┐
│ Inside Vault │ ──► [ Your Ubuntu Linux Server ]
└──────────────┘
Here are the 4 steps I took to build it:

🚪 Step 1: Hiring the Ultimate Security Guard (MFA)

Before building my vault, I hired a digital security guard for my main account. I turned on a feature called Security Defaults.

What it means: Think of it like a guard at the front door who checks IDs. If anyone tries to guess my password, the guard stops them instantly and sends a verification code straight to my personal phone. This keeps the bad guys completely out of my account.

🧱 Step 2: Building a Private Gatehouse (The Firewall / NSG)Next, I built a private wall around my vault. In the tech world, this is called a Network Security Group (NSG). It acts like a smart gatehouse with a very specific rulebook.

The Rule: I told the gatehouse, “Only let someone in if they are coming from Abhishek’s exact home Wi-Fi address.” If a hacker from anywhere else in the world tries to knock on the door, the gatehouse completely ignores them.

💻 Step 3: Launching the Computer (The Virtual Machine)Once the security walls were up, I ordered a fresh Linux computer (called a Virtual Machine) to live inside my vault.

The Real-World Twist: At first, the local data centers in India were completely full because so many people were using them! Instead of giving up, I used the power of the cloud to instantly teleport my project across the ocean to Singapore, where there was plenty of room. It worked perfectly and cost me next to nothing from my free credits.

🛠️ Step 4: Solving a Hidden Problem (The Serial Console)This was the most exciting part of the day. When I tried to log into my new Singapore computer from my laptop, the connection kept freezing.

The Problem: It turns out my home internet router is highly restrictive. It blocks the standard pipe (called Port 22) used to connect to Linux computers.

The Fix: Instead of calling my internet provider to complain, I used a secret Azure back-door tool called the Serial Console. It allowed me to bypass my home router’s restriction and open a direct command-line window to my server right inside my Google Chrome browser tab!

💰 Saving Money: Turning off the Lights

Because the cloud operates on a “pay-for-what-you-use” model, keeping the computer running when I’m not using it would waste my free credits. To practice good discipline, I hit the Stop (Deallocate) button. This completely shuts down the physical computer in Singapore, dropping my hourly cost to exactly ₹0 until I turn it back on tomorrow.

🏆 Why this matters

Today, I proved that I can:

  1. Lock down a cloud environment so hackers can’t get in.
  2. Adapt and move my infrastructure across the globe when resources are full.
  3. Troubleshoot tricky network blocks like a real professional.

From a Phone in a “Cave” to Global Open Source: Why Google’s Gemma Models are a Lifeline for Budget Developers

This is a submission for the Gemma 4 Challenge: Write About Gemma 4

Before you dive into reading this blog, I want to share one thing with you straight from the heart. I didn’t just write this blog directly using an LLM or any AI tool. I sat down and drafted every single bit of this story in my notepad first. Then, I put it into AI and said,
Hey, look, don’t add extra artificial content. Just help me organize my thoughts and put this info correctly so I can share my real experience.

What’s Covered in This Blog

  • The Superpower of True Offline Coding

  • What Makes Gemma So Mind-Blowing?

  • Showcasing the Setup: Gemma Natively on My Phone!

  • Step-by-Step: Native Mobile Setup (Termux + spawn.h Fix)

  • My New Setup: Pure Focus Mode on Laptop

  • Step-by-Step: Compiling Gemma 4 on Ubuntu Linux

  • Final Thoughts & Acknowledgments

The Superpower of True Offline Coding

A lot of people ask me, Why do you care so much about running models offline when the cloud exists?

Because I remember my school days. I didn’t have a flashy, high-end laptop. I had a smartphone. I used Termux, Acode, and Anwriter to write code directly on my tiny screen. I still remember the absolute thrill of building my very first Tic-Tac-Toe game using pure HTML, CSS, and JavaScript, entirely offline.

Back then, the absolute biggest roadblock to studying and building things was documentation. If you wanted to learn or look up an error code, you needed an internet network to scroll through endless pages. If your network failed, your learning stopped.

But when you code or study completely offline with an AI tutor, a superpower unlocks: The noise disappears, and the barriers vanish.
Here is exactly what my brain looks like when the Wi-Fi is on versus when I cut the cord:

Image generated using Google Gemini

Now, that entire network problem is completely solved. Anyone can build anything and learn easily without spending a single penny on expensive internet plans or premium data subscriptions.

Historically, the problem with offline AI was hardware. Running a capable LLM required an expensive machine with massive amounts of VRAM. If you didn’t have the cash for a high-end gaming GPU, you were locked out.

Google just shattered that barrier. By releasing the Gemma model family under an open, commercially permissive Apache 2.0 license, they didn’t just give us a powerful model; they gave every single student around the globe access to frontier-level AI on regular, everyday devices. When I spin up a Gemma model to help me generate Go code on an older, struggling laptop and watch it handle the logic flawlessly, I genuinely feel like Tony Stark.

“TONY STARK BUILT THIS IN A CAVE! WITH A BOX OF SCRAPS!” > —— Me screaming at my old laptop when the local Go code compiles perfectly. 😂

What Makes Gemma So Mind Blowing?

Google engineered these lightweight, open-weights models specifically to bring massive reasoning capabilities straight to accessible hardware.

In plain English? It means the model doesn’t choke your device’s RAM. Instead of needing a massive corporate data center to process complex logic, it uses ultra-efficient token processing and smart memory layouts. This drastically shrinks the hardware footprint, allowing you to feed it prompts without crashing your device or causing your phone to overheat like a hot potato.

Whether you are running a lightweight version on a smartphone or a larger variant on a laptop, you are getting incredible coding and debugging help completely locally.

Showcasing the Setup: Gemma Running Natively on My Phone!

To show you that this isn’t just theory I actually live this setup. Check out this video of my actual screen while using it:

Seeing text stream into a mobile terminal screen like that when you are completely disconnected from the outside world is an unmatched feeling. It makes you realize that the barriers to education and software engineering are completely tearing down.

Just to be transparent with you guys on the dates: what you are seeing in that video above is my older mobile setup running the Gemma 2B model. I originally took this screen recording on May 16, 2026, after using the model heavily in Termux, and I just uploaded the clip to YouTube on May 20, 2026, to share it here. I wanted to show you this video because it proves just how smooth and massive the performance is even on a small phone. It makes you think—if a lightweight 2B model can do all this, how crazy is the new Gemma 4 going to be?

Recreating the Magic: Step-by-Step Native Mobile Setup

Want to turn your phone into an offline powerhouse running a model like Gemma 2B? Here are the actual commands to set up Termux and compile llama.cpp directly on Android:

Note: These images reflect the exact workflow from my mobile device. If the upstream repository receives new updates down the line, simply check their latest branch logs and run your build!

Step 1: Install Required Packages & System Headers

pkg update && pkg upgrade -y
pkg install -y git cmake clang make python ndk-sysroot wget

This installs all the essential tools required to compile llama.cpp natively inside Termux.

Step 2: Hitting the Nasty spawn.h Error

While compiling, I encountered a spawn.h error on Termux during the build process.

To fix this issue, I rolled back to a stable build tag and rebuilt the project.

# Roll back to a stable release build tag to bypass the spawn.h error
git checkout b4833

# Clear the old broken build artifacts
rm -rf build

# Reconfigure and trigger the compilation process using 4 threads
cmake -B build
cmake --build build -j4

This successfully compiled the project without errors on Android.

Step 3: Download and Run Your Offline Assistant

# Create a models directory inside llama.cpp
mkdir -p models
cd models

Download your preferred GGUF model and place it inside the models folder.

Example model used:
gemma-2-2b-it-Q4_K_M.gguf

Step 4: Run the Model

./build/bin/llama-server -m models/gemma-2-2b-it-Q4_K_M.gguf -c 512 -t 2 -ngl 0
  • m → Path to the model
  • c 512 → Context size
  • t 2 → Number of CPU threads
  • ngl 0 → Disable GPU layers (recommended for mobile)

Once launched, the model runs completely offline on your Android device.
Below is a screenshot of the model running in my Termux terminal.

My New Setup: Pure Focus Mode (Minus the Distractions)

Right now, I am so eager to test Gemma 4 on my phone next, but for serious coding work, I’ve deployed it on my laptop setup instead.

I have a dual-boot machine running Windows and Ubuntu Linux, and for serious focus sessions, I always boot straight into Ubuntu.

And look, the beauty of llama.cpp is that you can host a local server and run the model directly inside a clean, beautiful browser interface on your local machine. It is absolutely superb. I get to pull up my project files, ask my local model questions, and have zero internet tabs open to distract me. Bye-bye internet, hello focus mode!

Step-by-Step Guide: Compiling Gemma 4 on Ubuntu Linux for High Performance

Step 1: Update System and Install Core Build Tools

sudo apt update && sudo apt install -y git build-essential cmake

Step 2: Download and Compile llama.cpp

git clone https://github.com/ggml-org/llama.cpp.git

cd llama.cpp

cmake -B build
# Build project (e.g., -j4 for 4 cores, or -j$(nproc) for all cores)
cmake --build build -j

Step 3: Create Directories and Download Gemma 4 GGUF

# Create the models directory inside llama.cpp if it doesn't exist
mkdir -p models 

# Download your preferred Gemma 4 GGUF flavor from Hugging Face into the models folder

Step 4: Launch Gemma 4 (Choose Web UI or Terminal)

*Option A: Launch the Local *

./build/bin/llama-server -m models/gemma-4-E4B-it-Q3_K_S.gguf -c 4096 --host 127.0.0.1 --port 8080

Once that server is running, you just open your browser, head to http://127.0.0.1:8080, and you have a stunning interface running 100% locally from your machine!

Here is exactly what it looks like when I boot into Ubuntu and run the Web UI interface. Look at how seamlessly it breaks down complex topics like Deep-First Search (DFS) and Breadth-First Search (BFS):

Option B: Launch Interactive Chat in Terminal

./build/bin/llama-cli -m models/gemma-4-E4B-it-Q3_K_S.gguf -p "Hi" -env

Here is a live screenshot of the terminal variant spinning up on my desktop. You can see htop running on the right side, showing how lightweight and light on resources the execution is on my CPU:

Looking at this laptop setup makes me feel incredibly grateful. I have to give a massive shoutout to Google. A while back, the high-quality technical information and support I got from the Gemma ecosystem actually helped me write high-value blogs on Dev.to. Those blogs gained traction, helped me clear technical hurdles, and ultimately allowed me to make the money I needed to finally step up from just a phone and get this laptop.

Final Thoughts: Thank You, Google

From tinkering with basic text editors in my school days to deploying advanced Go routines on an old, hardware-challenged laptop today, local execution has completely shaped my trajectory as a developer.

AI shouldn’t just be a luxury for those who can afford massive monthly cloud subscriptions or elite hardware. By putting open-weights, highly compressed powerhouses like the Gemma family directly into our hands, Google has leveled the playing field for student developers everywhere who are suffering through hardware or internet constraints.

Thank you, Google, for making things easy for me from my childhood all the way to right now. You always clear the path for devs who are trying to learn and grow.

Now, go clone the repository, download the weights, shut off your internet, and go build something awesome in your own cave!

Before I close this blog completely, I want to say one last thing. If anything I wrote here caused any misunderstanding, or if my blog made any person feel sad or unhappy, I am really, truly sorry. That was never my intention. I just wanted to share the happiness and excitement of a kid coding from his phone and moving up to a laptop. Thank you so much for reading, and good luck with your own builds!

Building a Privacy-First AI App for Patient & Caregiver Doctor Visit Notes

Hi DEV Community,

I wanted to share a project I’ve been working on called AI Doctor Notes. It’s an app built specifically to solve a common problem: walking out of a doctor’s visit and completely forgetting the instructions, medication steps, or follow-up details.

Unlike generic voice-recording or transcription tools, this app focuses heavily on user privacy and specialized workflows tailored for patients and family caregivers.

Key Features:

  • Pre-visit preparation: Track symptoms and organize lists of questions before the appointment.
  • Smart summaries: Securely record details during the visit and instantly generate clear, structured summaries of actual doctor instructions.
  • Caregiver sharing: Easily share visit recaps with family members or other relatives managing a loved one’s health.

We focused heavily on keeping the user experience as simple and clean as possible since medical visits are already high-stress situations.

I’d love to hear any feedback you have on the setup or features!

Check out the site here: https://aidoctornotes.app/

Anker, yeni ürünüyle Nebula X1 ailesine 3D projeksiyon haritalama özelliği ekliyor

Anker, yeni ürünüyle Nebula X1 ailesine 3D projeksiyon haritalama özelliği ekliyor

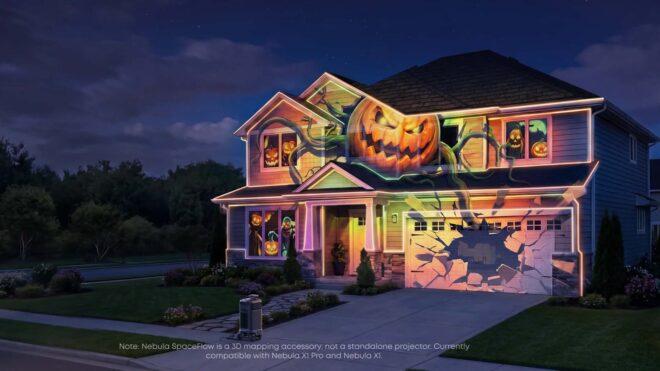
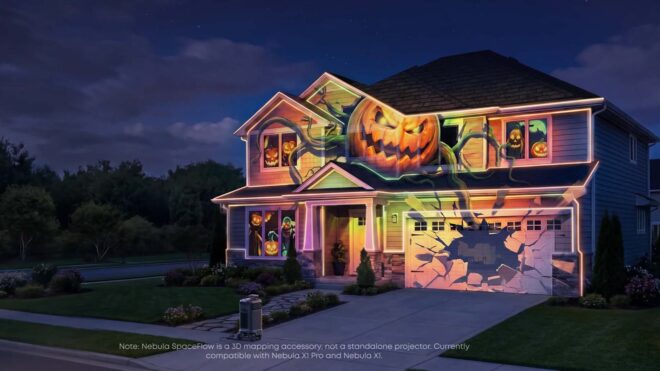
Anker, yeni ürünüyle Nebula X1 ailesine 3D projeksiyon haritalama özelliği ekliyorAnker, “SpaceFlow” adını verdiği yeni ürünüyle Nebula X1 projektör ailesine 3D projeksiyon haritalama özelliği ekliyor. 399 dolardan satışa sunulan ürün, spesifik olarak Nebula X1 ile Nebula X1 Pro’nun üstüne konumlandırılıyor ve baktığı yüzeyin şeklini derinliğiyle birlikte analiz ederek farklı tasarımlar yansıtabiliyor. Ortamdaki kapıları, pencereleri, mobilyaları ve diğer objeleri tespit eden ve projeksiyonu buna göre özelleştiren SpaceFlow, 100’den fazla hazır tasarımla geliyor. Yapay zeka altyapısı sayesinde kişilerin aklından geçen tasarımları da üreterek yansıtabilen ürünün, kampanya dönemi bittikten sonra 799 dolara satılacağı aktarılıyor.

Anker, yeni ürünüyle Nebula X1 ailesine 3D projeksiyon haritalama özelliği ekliyor yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

My side project gets most of its traffic from ChatGPT, not Google. Here is the schema work behind it.

My side project gets most of its traffic from ChatGPT, not Google. Here is the schema work behind it.

A few weeks ago I opened Google Analytics for a passport-photo tool I build and maintain, and the traffic-source breakdown stopped me:

  • chatgpt.com — 65% of sessions
  • google / organic — about 6%
  • direct — the rest

Then I checked Bing Webmaster Tools, which has a new “AI Performance” tab, and saw the site had picked up 45 citations from Microsoft Copilot over three months.

The site is barely three months old. It has almost no backlinks. On Google it ranks on page 3-5 for anything competitive. And yet AI answer engines were sending it the bulk of its visitors.

This post is the honest engineering breakdown of what I did to make the site machine-citeable — what I think worked, what I cannot attribute, and the code. It is a Next.js App Router project, but the techniques are framework-agnostic.

Why this happens at all

AI answer engines (ChatGPT search, Perplexity, Copilot, Gemini) do not rank ten blue links. They synthesise an answer and cite a few sources. For a new site this is a genuinely different game from classic SEO:

  • Classic SEO: you need domain authority and backlinks to rank. That takes 6-12 months minimum for a new domain.
  • AI citation: the engine needs a page that clearly and verifiably answers the user’s question, is crawlable, and is structured so the answer is easy to extract. Domain age matters far less.

A three-month-old site cannot outrank an established competitor on Google. But it absolutely can be the cleanest, most extractable answer to a specific question — and that is what gets cited.

What I shipped

1. llms.txt

There is an emerging convention, llmstxt.org, for a plain-text file at /llms.txt that gives AI systems a curated, readable summary of your site — what it is, key pages, key facts, citation guidance. It is the robots.txt idea applied to LLMs.

Mine includes the brand entity, the canonical fact list, the most important pages, the audience, and a short “how to cite this” section. It costs nothing to maintain and it is the single most direct way to hand an AI engine a clean model of your site.

2. Schema.org structured data — the parts that matter

Not all schema is equal for AI extraction. The types that earned their place:

  • FAQPage with Question / acceptedAnswer pairs. Every Q&A is a discrete, extractable answer. I put one on the homepage and a big one on a dedicated facts page.
  • Question as mainEntity on individual pages — the page declares the one question it primarily answers, with the answer attached. This is the cleanest possible signal: “this page answers exactly this.”
  • Dataset (Schema.org) on the page documenting my public data API. Google Dataset Search and AI engines treat Dataset JSON-LD as a citation-worthy source.
  • SpeakableSpecification — marks which parts of the page are suitable for text-to-speech, used by voice assistants.
// Per-page primary question — the cleanest "this page answers X" signal
const pageSchema = {
  '@context': 'https://schema.org',
  '@type': 'WebPage',
  url: pageUrl,
  mainEntity: {
    '@type': 'Question',
    name: `What is the photo specification for ${country} ${doc}?`,
    acceptedAnswer: {
      '@type': 'Answer',
      text: factualAnswerAssembledFromStructuredData,
      url: pageUrl,
    },
  },
}

3. A canonical facts page

I built a /facts page: ~45 question/answer pairs, each grounded in an official government source, each rendered as real HTML with FAQPage JSON-LD and inline microdata (itemScope / itemProp). The first sentence of every answer is the direct answer — no preamble. AI engines extract the first authoritative sentence; give it to them cleanly.

4. Open data with a real endpoint

The dataset behind the tool is published two ways: an MIT-licensed GitHub repo, and a live JSON-LD API endpoint that returns a Schema.org Dataset. When an AI engine wants to verify a claim about coverage, there is a machine-readable source to point at. Being verifiable is itself a citation signal.

5. Server-side rendering — non-negotiable

If your content only exists after client-side JavaScript runs, many crawlers will not see it. Everything that matters — the schema blocks, the FAQ text, the tables — is in the server-rendered HTML. Quick check:

curl -s https://yoursite.com/ | grep -c "the answer text you expect"

If that returns 0, AI crawlers see an empty page.

6. Tables, not prose, for structured facts

This one is underrated, especially for Perplexity. If you have comparison data — sizes, prices, specs — render it as a real HTML <table>. AI engines lift tables into answers almost verbatim. A paragraph describing the same data is much harder for them to use.

7. robots.txt — explicitly allow the AI crawlers

GPTBot, OAI-SearchBot, PerplexityBot, ClaudeBot, Google-Extended, CCBot, Bingbot and others. If you want AI citations, do not block the bots that produce them. I also added a tiny middleware that tags each AI-bot request, so I can see in logs which engines actually crawl and how often.

// middleware.ts — detect and log AI crawler hits
const AI_BOTS = [/GPTBot/i, /PerplexityBot/i, /ClaudeBot/i, /OAI-SearchBot/i, /Google-Extended/i]
const ua = request.headers.get('user-agent') ?? ''
if (AI_BOTS.some((re) => re.test(ua))) {
  console.log(JSON.stringify({ event: 'ai_bot_crawl', ua, path: request.nextUrl.pathname }))
}

8. IndexNow — push, do not wait

ChatGPT search and Copilot lean on the Bing index. IndexNow lets you push new and changed URLs to Bing the moment you deploy, instead of waiting for a crawl. One POST per deploy.

What I cannot honestly claim

I cannot prove causation for any single technique. I shipped these together over a few weeks; traffic rose over the same period. It is correlation. What I can say:

  • The AI-citation traffic is real and measurable (GA4 source = chatgpt.com, Bing AI Performance citation count).
  • The pages AI actually cites are the most structured ones: the homepage, a tool-feature page, and timely explainer posts about recent regulation changes.
  • Domain authority did not drive this — the domain has almost none.

Takeaways

If you have a small or new site and want AI engines to send you traffic:

  1. Add llms.txt. Lowest effort, highest signal density.
  2. Use FAQPage and per-page mainEntity Question schema. Make every page declare what it answers.
  3. Server-render everything that matters. Verify with curl.
  4. Render structured facts as HTML tables.
  5. Lead every answer with the direct answer in sentence one.
  6. Allow the AI crawlers in robots.txt; push updates with IndexNow.
  7. Publish verifiable primary data if you have any.

None of this requires domain authority or a backlink budget. It requires being the clearest, most machine-readable answer to a real question. For a new site, that is a far more winnable game than classic SEO.

I build IDPhotoSnap, a free browser-only passport photo tool. The country-spec dataset is open at github.com/whitetirocket/passport-photo-specs. Happy to answer questions about the schema setup in the comments.

Comment simuler une API pour les tests: Guide pratique

Les tests qui dépendent d’une API réelle échouent souvent pour de mauvaises raisons : serveur de staging indisponible, limite de débit atteinte, donnée modifiée par un collègue, latence réseau. La simulation d’API supprime cette fragilité : vous remplacez l’endpoint réel par un substitut contrôlé qui renvoie la réponse attendue, de manière répétable.

Essayez Apidog aujourd’hui

Ce guide montre comment simuler une API pour vos tests : définir un schéma, générer des réponses mockées, exposer un serveur de simulation, configurer vos tests pour l’utiliser, puis couvrir les erreurs difficiles à déclencher sur un serveur réel. Les exemples utilisent une API de commandes avec GET /orders/{id}, mais la méthode s’applique à toute API REST ou GraphQL.

Quand utiliser la simulation d’API

Simulez l’API lorsque vous voulez tester votre code, pas le réseau.

Cas typiques :

  • tests unitaires ;
  • tests d’intégration ;
  • parsing de réponses 200 ;
  • gestion des 404 ;
  • logique de retry sur 503 ;
  • timeout côté client ;
  • fallback UI ou métier.

Gardez l’API réelle pour :

  • les tests de contrat ;
  • quelques tests end-to-end ;
  • la validation que le mock correspond toujours au service réel.

La règle pratique :

Mockez pour la vitesse et l’isolation. Interrogez le service réel pour valider le contrat.

Pour approfondir, consultez les cas où la simulation d’API est rentable et la différence entre un serveur de simulation et un serveur réel.

Le processus en cinq étapes

Pour simuler une API dans une suite de tests :

  1. Définissez le schéma de l’API.
  2. Générez des réponses simulées, statiques ou dynamiques.
  3. Exécutez un serveur de simulation accessible via une URL.
  4. Configurez vos tests pour pointer vers le mock.
  5. Testez les chemins d’erreur : 404, 500, 429, timeouts, JSON invalide.

Nous allons utiliser ce endpoint comme fil conducteur :

GET /orders/{id}

Étape 1 : Définir le schéma

Un mock fiable commence par un contrat clair. Si votre API possède déjà un document OpenAPI, utilisez-le. Sinon, écrivez un schéma minimal pour l’endpoint testé.

Exemple pour GET /orders/{id} :

paths:
  /orders/{id}:
    get:
      parameters:
        - name: id
          in: path
          required: true
          schema: { type: string }
      responses:
        '200':
          content:
            application/json:
              schema:
                type: object
                properties:
                  id: { type: string }
                  status: { type: string, enum: [pending, shipped, delivered] }
                  total: { type: number }
                  items: { type: array, items: { type: object } }
        '404':
          description: Order not found

Ce schéma sert à deux choses :

  • indiquer au mock quels champs renvoyer ;
  • fournir une source unique de vérité pour les tests et le backend.

Quand le contrat change, mettez à jour le schéma. Les mocks générés depuis ce schéma restent alors alignés. C’est la base des tests de contrat d’API.

Étape 2 : Générer des réponses simulées

Vous avez deux approches principales.

Réponses statiques

Une réponse statique est un JSON fixe. Elle est idéale quand le test doit vérifier une valeur précise.

Exemple :

{
  "id": "order_8842",
  "status": "shipped",
  "total": 149.99,
  "items": [
    {
      "sku": "book_001",
      "quantity": 1
    },
    {
      "sku": "pen_002",
      "quantity": 3
    }
  ]
}

Utilisez ce type de réponse pour des assertions déterministes :

expect(order.status).toBe('shipped');
expect(order.total).toBe(149.99);

Réponses dynamiques

Une réponse dynamique est générée à chaque requête. Le mock peut produire :

  • un UUID pour id ;
  • une valeur autorisée pour status ;
  • un montant réaliste pour total ;
  • des données variables pour items.

Cette approche aide à détecter des bugs cachés par une seule fixture statique : chaînes longues, valeurs nulles, nombres inattendus, tableaux de tailles différentes.

La plupart des équipes combinent les deux :

  • statique pour les tests précis ;
  • dynamique pour une couverture plus proche du fuzz testing.

Avec Apidog, vous pouvez générer automatiquement des endpoints mockés à partir du schéma. Les champs comme email, phone ou avatar sont associés à des types de données cohérents, sans écrire manuellement chaque payload.

Quand vous écrivez vos fixtures à la main, évitez les données trop simplistes :

{
  "id": "1",
  "status": "pending",
  "total": 0,
  "items": []
}

Préférez des données proches de la production :

{
  "id": "order_8842",
  "status": "shipped",
  "total": 149.99,
  "items": [
    {
      "sku": "sku_123",
      "name": "Mechanical keyboard",
      "quantity": 1,
      "price": 129.99
    },
    {
      "sku": "sku_456",
      "name": "USB-C cable",
      "quantity": 1,
      "price": 20
    }
  ]
}

Étape 3 : Exécuter le serveur de simulation

Une réponse mockée doit être servie par une URL. Vous avez deux options.

Option 1 : serveur de simulation local

Un mock local tourne sur votre machine, par exemple :

http://127.0.0.1:4010

C’est l’option recommandée pour les tests unitaires et d’intégration :

  • rapide ;
  • utilisable hors ligne ;
  • pas d’état partagé entre builds ;
  • pas de latence réseau externe.

Avec Prism, vous pouvez démarrer un mock depuis un fichier OpenAPI :

prism mock openapi.yaml
# Serveur de simulation écoutant sur http://127.0.0.1:4010

Votre endpoint devient alors disponible localement :

curl http://127.0.0.1:4010/orders/order_8842

Option 2 : serveur de simulation cloud

Un serveur cloud expose une URL publique. Utilisez-le quand :

  • une app mobile doit appeler le mock ;
  • un runner CI externe doit y accéder ;
  • un collaborateur hors réseau local doit tester l’API ;
  • vous préparez une démo.

Apidog fournit une URL de Cloud Mock par projet, ce qui permet à toute l’équipe d’utiliser le même endpoint simulé.

Pour les tests automatisés, préférez le local. Pour les démos, tests multi-appareils ou collaborations externes, le cloud est plus pratique.

Étape 4 : Pointer vos tests vers le mock

Votre code ne doit pas contenir l’URL de production en dur. Rendez l’URL de base configurable.

Exemple avec une variable d’environnement :

// orderClient.test.js
import { getOrder } from './orderClient.js';

const BASE_URL = process.env.API_BASE_URL || 'http://127.0.0.1:4010';

test('analyse une commande expédiée', async () => {
  const order = await getOrder('order_8842', BASE_URL);

  expect(order.status).toBe('shipped');
  expect(typeof order.total).toBe('number');
});

Le client reçoit l’URL de base en argument :

// orderClient.js
export async function getOrder(id, baseUrl) {
  const response = await fetch(`${baseUrl}/orders/${id}`);

  if (!response.ok) {
    throw new Error(`Failed to fetch order: ${response.status}`);
  }

  return response.json();
}

En local :

API_BASE_URL=http://127.0.0.1:4010 npm test

En CI, définissez API_BASE_URL vers l’adresse du mock avant d’exécuter la suite.

Ce modèle garde la simulation hors de la logique applicative. La même approche s’applique quand vous automatisez les tests API en CI/CD.

Étape 5 : Tester les chemins d’erreur

C’est souvent l’étape la plus rentable.

Un serveur réel ne renvoie pas forcément un 500, un 429 ou une réponse lente au moment où vous en avez besoin. Un mock, oui.

Configurez des scénarios d’échec explicites :

Scénario Le mock renvoie Ce que vous affirmez
Enregistrement manquant 404 Le client lève une erreur claire “non trouvé”
Défaillance serveur 500 Le client réessaie, puis affiche un fallback
Limite de débit atteinte 429 avec Retry-After Le client applique un backoff approprié
Réponse lente 200 après un délai de 5s Le client expire et récupère proprement
Corps de réponse malformé 200 avec JSON invalide Le client échoue sans crash

Exemple de test pour un 404 :

test('renvoie une erreur lisible si la commande est introuvable', async () => {
  await expect(getOrder('order_404', BASE_URL))
    .rejects
    .toThrow('Failed to fetch order: 404');
});

Exemple de test pour un timeout :

test('échoue proprement si la réponse est trop lente', async () => {
  const controller = new AbortController();

  const timeout = setTimeout(() => {
    controller.abort();
  }, 1000);

  await expect(
    fetch(`${BASE_URL}/orders/order_slow`, {
      signal: controller.signal
    })
  ).rejects.toThrow();

  clearTimeout(timeout);
});

Les règles de simulation avancées d’Apidog permettent de renvoyer des réponses différentes selon la requête. Par exemple :

  • GET /orders/order_404 renvoie 404 ;
  • GET /orders/order_rate_limited renvoie 429 ;
  • tout autre ID renvoie 200.

Associez ces scénarios à des assertions API robustes pour tester le comportement, pas seulement les codes de statut.

Organiser les mocks dans une suite de tests qui grandit

Un seul mock est facile à gérer. Une centaine de mocks peut rapidement devenir ingérable.

Adoptez quelques conventions dès le début.

1. Regrouper par service

Organisez les mocks selon le service qu’ils remplacent :

mocks/
  orders/
    order-shipped.json
    order-not-found.json
    order-rate-limited.json
  payments/
    payment-authorized.json
    payment-declined.json

Évitez de les ranger par test :

tests/
  order-page/
    mock1.json
  checkout-page/
    mock2.json

Quand l’API de paiement change, vous voulez modifier un seul dossier clair, pas chercher des fixtures dispersées.

2. Nommer les scénarios explicitement

Préférez :

order-shipped.json
order-delivered.json
order-rate-limited.json

À :

response1.json
test-data.json
mock-success.json

Un test qui échoue doit être lisible rapidement.

3. Versionner les mocks

Les mocks font partie de vos tests. Gardez-les dans le contrôle de version, à côté de la suite automatisée.

src/
tests/
mocks/
openapi.yaml

Une pull request qui modifie un contrat API doit inclure la mise à jour du schéma et des mocks associés.

4. Créer une réponse de base

Évitez de dupliquer des payloads complets dans chaque test. Définissez une base réaliste et surchargez uniquement ce qui change.

Exemple :

const baseOrder = {
  id: 'order_8842',
  status: 'shipped',
  total: 149.99,
  items: [
    { sku: 'sku_123', quantity: 1 },
    { sku: 'sku_456', quantity: 2 }
  ]
};

const cancelledOrder = {
  ...baseOrder,
  status: 'cancelled'
};

Cette discipline rend les mocks maintenables, comme pour une suite de tests d’automatisation d’API.

Maintenir l’intégrité du mock

Le risque principal d’un mock est la dérive.

Exemples :

  • le backend ajoute un champ ;
  • total devient amount;
  • une valeur d’énumération change ;
  • un champ devient nullable ;
  • une erreur retourne un nouveau format.

Si le mock n’est pas mis à jour, vos tests restent verts alors que la production peut casser.

Pour éviter cela, appliquez deux pratiques.

1. Générer le mock depuis le même schéma que le backend

Si le mock vient du fichier OpenAPI, il peut être régénéré quand le contrat change.

Un mock écrit à la main ne suit pas automatiquement ces changements.

2. Exécuter des tests de contrat contre l’API réelle

Ajoutez une petite suite qui vérifie que l’API réelle respecte toujours le schéma.

Objectif :

  • pas tester toute l’application ;
  • pas remplacer les mocks ;
  • seulement détecter une dérive entre le contrat et la production.

Exemple de stratégie :

Tests unitaires et intégration
→ utilisent le mock

Tests de contrat planifiés
→ appellent l’API réelle

Tests end-to-end critiques
→ couvrent quelques parcours complets

Lorsqu’un test de contrat échoue, mettez à jour le schéma, le backend ou les mocks selon l’origine du changement.

Pendant la revue de code, vérifiez aussi les mocks. Si une PR modifie une réponse API, elle doit modifier le mock correspondant.

Si vous voulez centraliser le schéma, le serveur de simulation et les tests dans un même environnement, téléchargez Apidog. Pour comparer les options disponibles, consultez ce tour d’horizon des outils de simulation d’API REST.

Questions fréquemment posées

Dois-je simuler l’API pour chaque test ?

Non. Utilisez des mocks pour les tests unitaires et d’intégration où vous vérifiez votre code. Gardez une petite suite de tests de contrat et quelques tests end-to-end contre l’API réelle pour valider que le mock correspond toujours à la production.

Quelle est la différence entre une réponse statique et dynamique ?

Une réponse statique est un JSON fixe, utile pour des assertions précises et répétables. Une réponse dynamique est générée à chaque requête avec des valeurs réalistes, utile pour exposer des bugs qu’une fixture unique pourrait masquer.

Comment m’assurer que mon mock reste précis ?

Générez-le depuis le même schéma que le backend, idéalement un document OpenAPI. Ensuite, exécutez régulièrement des tests de contrat contre l’API réelle pour vérifier que la réponse live respecte toujours ce schéma.

Un mock peut-il simuler des réponses lentes ou échouées ?

Oui. Vous pouvez configurer un mock pour renvoyer un 500, un 429 avec Retry-After, un 404, un JSON invalide ou un 200 retardé. C’est utile pour tester les retries, les timeouts et les fallbacks.

Serveur de simulation local ou cloud pour les tests ?

Utilisez un serveur local pour les tests automatisés : il est rapide, isolé et sans latence réseau externe. Utilisez un mock cloud lorsqu’un appareil mobile, un runner CI ou un collaborateur externe doit accéder au mock sans dépendre de votre machine.

Build an AI customer support bot with n8n — handles tickets automatically (free workflow)

My inbox had 47 unanswered support tickets on a Monday morning. Most were the same 4 questions: pricing, setup help, refund requests, and “how do I…?” questions.

I built an n8n workflow that handles 80% of them automatically. Here’s the full JSON — free.

What it does

  • Webhook receives support ticket (from your contact form or email)
  • GPT-4o-mini classifies the ticket: pricing / technical / billing / general
  • Sends an appropriate auto-reply for each category
  • Escalates complex tickets to Slack for human review
  • Logs everything to Google Sheets for tracking

Setup time: 15-20 minutes | Cost: ~$0.001 per ticket | n8n version: 1.40+

The workflow JSON

{"name":"AI Customer Support Bot","nodes":[{"parameters":{"httpMethod":"POST","path":"support-ticket","responseMode":"responseNode","options":{}},"id":"cs1","name":"Webhook","type":"n8n-nodes-base.webhook","typeVersion":1,"position":[240,300]},{"parameters":{"jsCode":"const body = $input.first().json.body || $input.first().json;nconst email = body.email || body.from || '[email protected]';nconst subject = body.subject || body.title || 'Support Request';nconst message = body.message || body.content || body.text || '';nreturn [{ json: { email, subject, message, receivedAt: new Date().toISOString() } }];"},"id":"cs2","name":"Parse Ticket","type":"n8n-nodes-base.code","typeVersion":2,"position":[460,300]},{"parameters":{"resource":"chat","operation":"complete","model":"gpt-4o-mini","messages":{"values":[{"role":"system","content":"You are a support ticket classifier. Classify the ticket into exactly one category: PRICING, TECHNICAL, BILLING, or GENERAL. Then write a helpful, friendly auto-reply (2-3 sentences max). Reply in JSON: {"category": "...", "reply": "..."}"},{"role":"user","content":"=Subject: {{ $json.subject }}nMessage: {{ $json.message }}"}]},"options":{"temperature":0.3}},"id":"cs3","name":"AI Classify & Reply","type":"n8n-nodes-base.openAi","typeVersion":1,"position":[680,300]},{"parameters":{"jsCode":"const raw = $input.first().json.message.content;nlet parsed;ntry { parsed = JSON.parse(raw); } catch(e) { parsed = { category: 'GENERAL', reply: 'Thanks for reaching out! Our team will get back to you within 24 hours.' }; }nconst needsHuman = parsed.category === 'BILLING' || parsed.category === 'TECHNICAL';nreturn [{ json: { ...$input.first().json, category: parsed.category, autoReply: parsed.reply, needsHuman } }];"},"id":"cs4","name":"Parse AI Response","type":"n8n-nodes-base.code","typeVersion":2,"position":[900,300]},{"parameters":{"conditions":{"boolean":[{"value1":"={{ $json.needsHuman }}","value2":true}]}},"id":"cs5","name":"Needs Human?","type":"n8n-nodes-base.if","typeVersion":1,"position":[1120,300]},{"parameters":{"sendTo":"={{ $json.email }}","subject":"Re: {{ $json.subject }}","message":"={{ $json.autoReply }}nnBest,nSupport Team","options":{}},"id":"cs6","name":"Send Auto-Reply","type":"n8n-nodes-base.gmail","typeVersion":2,"position":[1340,420]},{"parameters":{"authentication":"webhook","resource":"chat","operation":"post","channel":"#support-escalations","text":"=🎫 *New {{ $json.category }} ticket needs review*n*From:* {{ $json.email }}n*Subject:* {{ $json.subject }}n*Message:* {{ $json.message }}n*Auto-reply sent:* {{ $json.autoReply }}","otherOptions":{}},"id":"cs7","name":"Slack Escalation","type":"n8n-nodes-base.slack","typeVersion":1,"position":[1340,180]},{"parameters":{"operation":"append","documentId":{"value":"YOUR_SHEET_ID"},"sheetName":"Tickets","columns":{"mappingMode":"defineBelow","value":{"Date":"={{ $json.receivedAt }}","Email":"={{ $json.email }}","Subject":"={{ $json.subject }}","Category":"={{ $json.category }}","AutoReply":"={{ $json.autoReply }}","EscalatedToHuman":"={{ $json.needsHuman }}"}},"options":{}},"id":"cs8","name":"Log to Sheets","type":"n8n-nodes-base.googleSheets","typeVersion":4,"position":[1560,300]}],"connections":{"Webhook":{"main":[[{"node":"Parse Ticket","type":"main","index":0}]]},"Parse Ticket":{"main":[[{"node":"AI Classify & Reply","type":"main","index":0}]]},"AI Classify & Reply":{"main":[[{"node":"Parse AI Response","type":"main","index":0}]]},"Parse AI Response":{"main":[[{"node":"Needs Human?","type":"main","index":0}]]},"Needs Human?":{"main":[[{"node":"Slack Escalation","type":"main","index":0}],[{"node":"Send Auto-Reply","type":"main","index":0}]]},"Slack Escalation":{"main":[[{"node":"Log to Sheets","type":"main","index":0}]]},"Send Auto-Reply":{"main":[[{"node":"Log to Sheets","type":"main","index":0}]]}}}

Import: Workflows → New → ⋯ menu → Import from JSON → paste above.

Setup (15 min)

1. Webhook

  • Copy the webhook URL after activating the workflow
  • Point your contact form’s POST action to it
  • Or use Zapier/Make to forward emails to the webhook

2. OpenAI credentials

  • Add your OpenAI API key in n8n credentials
  • GPT-4o-mini costs ~$0.15/1M input tokens — extremely cheap for support

3. Gmail

  • Connect your Gmail account for the auto-reply node
  • Change Send Auto-Reply sender name/signature to match your brand

4. Slack

  • Add a Slack webhook URL for the escalation channel
  • Or swap this node for an email node if you don’t use Slack

5. Google Sheets

  • Create a sheet with columns: Date, Email, Subject, Category, AutoReply, EscalatedToHuman
  • Replace YOUR_SHEET_ID with your sheet’s ID (from the URL)

How the AI classification works

The system prompt forces GPT-4o-mini to return structured JSON with a category and a reply. The Parse AI Response code node handles malformed output gracefully — if parsing fails, it defaults to GENERAL category with a generic reply.

Categories and their handling:

  • PRICING → Auto-reply with your pricing info → no escalation
  • GENERAL → Auto-reply with helpful generic response → no escalation
  • TECHNICAL → Auto-reply + escalate to Slack (needs human follow-up)
  • BILLING → Auto-reply + escalate to Slack (always needs human review)

Tips

1. Customize the system prompt
The real power is in the prompt. Add your actual pricing, your product name, your refund policy. The more context you give GPT, the better the auto-replies.

2. Add a confidence score
Ask the AI to also return "confidence": 0.0-1.0. Only send auto-replies when confidence > 0.8, escalate the rest.

3. Track auto-reply rate
After 1 week, check your Sheets log. What % of tickets got a good auto-reply vs escalation? Tune the system prompt based on what’s failing.

4. Add a delay before sending
Add a Wait node (2-5 min delay) before the auto-reply. Instant replies feel robotic; a short delay feels more human.

5. Handle attachments
The webhook node can receive file uploads. Add a check in Parse Ticket for attachments and route those directly to escalation.

What this replaces

Before: checking email every hour, copy-pasting the same replies, drowning in tickets.

After: webhook fires, AI replies in 30 seconds, you only see the edge cases that need you.

I built this as one of 15 n8n automation templates I use for client projects. If you want the full version with setup guide, Slack alert templates, and error handling — they’re all at https://stripeai.gumroad.com.

The JSON above is the complete working core. Happy to answer questions in the comments.

Building an E2EE Chat App in Flask – Part 1: Why Encryption Matters

Hey everyone! I’m building an encrypted chat application in Flask and documenting the journey. Here’s Part 1.
Why E2EE Matters
Most messaging apps claim to be secure, but they’re not. Your messages sit on their servers where anyone with access can read them.

End-to-End Encryption (E2EE) = only you and the recipient can read messages. The server can’t see anything.

Example:
WhatsApp uses E2EE. Facebook Messenger doesn’t. Your choice matters.

Why I Built This
I wanted to understand encryption by building it, not just reading about it. This project taught me way more than any tutorial.

What’s Next
Part 2: How to handle passwords safely without storing them in plain text.

Questions? Drop them in comments!

Framework de Tests Automatisés API avec Pytest: Tutoriel Pratique

Les développeurs Python choisissent souvent pytest pour tester des API parce qu’il reste simple : un test est une fonction test_*, une assertion est un assert, et le runner s’occupe de l’exécution. Avec requests, vous obtenez une base légère et maintenable pour automatiser des tests d’API directement en code.

Essayez Apidog aujourd’hui

Dans ce guide, vous allez construire une suite de tests d’API avec pytest : initialisation du projet, premier test HTTP, fixtures partagées, tests paramétrés, assertions sur les réponses et validation de schéma JSON. Les exemples utilisent une API fictive de style réaliste pour que vous puissiez adapter la structure à votre propre backend.

Configuration du projet

Créez un environnement virtuel, puis installez les dépendances :

python -m venv .venv
source .venv/bin/activate
pip install pytest requests jsonschema

Utilisez une structure simple dès le départ :

api-tests/
  conftest.py        # fixtures partagées
  test_users.py      # tests des endpoints utilisateurs
  test_orders.py     # tests des endpoints commandes
  pytest.ini         # configuration pytest

Pytest découvre automatiquement les tests si vous respectez ces conventions :

  • les fichiers commencent par test_ ou se terminent par _test.py ;
  • les fonctions commencent par test_ ;
  • les classes commencent par Test et n’ont pas de méthode __init__.

Exemple :

test_users.py
test_orders.py

Si les tests automatisés sont nouveaux pour vous, commencez par cette introduction sur ce qu’est le test automatisé.

Pourquoi pytest pour les tests d’API ? requests gère les appels HTTP, tandis que pytest fournit la découverte des tests, les assertions lisibles, les fixtures, la paramétrisation et le reporting. Vous pouvez donc garder vos tests proches du code applicatif, dans le même dépôt, et détecter les régressions directement dans les pull requests.

Écrire votre premier test d’API

Un test d’API pytest suit généralement trois étapes :

  1. envoyer une requête ;
  2. lire la réponse ;
  3. vérifier le statut, le corps ou les en-têtes.

Exemple avec un endpoint utilisateur :

import requests

BASE_URL = "https://api.example.com/v1"

def test_get_user_returns_200():
    response = requests.get(f"{BASE_URL}/users/42")

    assert response.status_code == 200

def test_get_user_returns_expected_fields():
    response = requests.get(f"{BASE_URL}/users/42")
    body = response.json()

    assert body["id"] == 42
    assert "email" in body
    assert body["status"] == "active"

Lancez la suite :

pytest -v

En cas d’échec, pytest affiche les valeurs réelles et attendues à partir de simples instructions assert. Vous n’avez pas besoin de méthodes d’assertion spécifiques.

Pour approfondir les vérifications utiles sur une réponse HTTP, consultez ce guide sur les assertions d’API.

Partager la configuration avec les fixtures

Évitez de répéter l’URL de base, les headers ou la session HTTP dans chaque test. Utilisez des fixtures.

Une fixture est une fonction décorée avec @pytest.fixture. Un test l’utilise simplement en déclarant son nom comme paramètre.

Placez les fixtures communes dans conftest.py :

# conftest.py
import pytest
import requests

BASE_URL = "https://api.example.com/v1"

@pytest.fixture(scope="session")
def api_session():
    session = requests.Session()
    session.headers.update({"Accept": "application/json"})

    yield session

    session.close()

@pytest.fixture
def auth_token(api_session):
    response = api_session.post(
        f"{BASE_URL}/auth/login",
        json={
            "email": "[email protected]",
            "password": "test-pass",
        },
    )

    return response.json()["token"]

Ici :

  • scope="session" crée une seule session HTTP pour toute l’exécution ;
  • le code avant yield prépare la ressource ;
  • le code après yield nettoie la ressource.

Un test peut ensuite demander uniquement ce dont il a besoin :

def test_create_order(api_session, auth_token):
    response = api_session.post(
        f"{BASE_URL}/orders",
        headers={"Authorization": f"Bearer {auth_token}"},
        json={
            "product_id": 7,
            "quantity": 2,
        },
    )

    assert response.status_code == 201
    assert response.json()["status"] == "pending"

Les fixtures remplacent avantageusement les anciens modèles setup_function et teardown_function. Elles se composent mieux, rendent les dépendances explicites et supportent plusieurs scopes. La documentation officielle des fixtures pytest les recommande comme approche par défaut.

Exécuter un test sur plusieurs entrées

Les endpoints doivent être testés avec plusieurs valeurs : cas valides, invalides et limites. Au lieu de dupliquer les fonctions, utilisez @pytest.mark.parametrize.

import pytest

BASE_URL = "https://api.example.com/v1"

@pytest.mark.parametrize(
    "user_id, expected_status",
    [
        (42, 200),
        (99999, 404),
        (0, 404),
        (-1, 400),
    ],
)
def test_get_user_status_codes(api_session, user_id, expected_status):
    response = api_session.get(f"{BASE_URL}/users/{user_id}")

    assert response.status_code == expected_status

Cette fonction génère quatre cas de test indépendants. Si un cas échoue, les autres continuent à s’exécuter et apparaissent séparément dans le rapport.

Quand la liste d’entrées devient longue, chargez les données depuis un fichier CSV ou JSON. Ce guide sur les tests d’API pilotés par les données avec CSV et JSON couvre ce modèle.

Si vous hésitez sur les statuts HTTP à attendre, utilisez cette référence sur les codes de statut HTTP que les API REST devraient utiliser.

Assertions sur le corps de réponse et le schéma

Un code 200 ne suffit pas. Une réponse peut réussir côté HTTP tout en renvoyant un JSON incomplet ou incorrect.

Commencez par des assertions directes sur le corps :

def test_order_response_shape(api_session, auth_token):
    response = api_session.post(
        f"{BASE_URL}/orders",
        headers={"Authorization": f"Bearer {auth_token}"},
        json={
            "product_id": 7,
            "quantity": 2,
        },
    )

    body = response.json()

    assert isinstance(body["id"], int)
    assert body["quantity"] == 2
    assert body["total"] > 0
    assert response.elapsed.total_seconds() < 1.0

Pour vérifier toute la structure de la réponse, validez le JSON contre un schéma :

from jsonschema import validate

order_schema = {
    "type": "object",
    "required": ["id", "product_id", "quantity", "status", "total"],
    "properties": {
        "id": {"type": "integer"},
        "product_id": {"type": "integer"},
        "quantity": {"type": "integer", "minimum": 1},
        "status": {"type": "string"},
        "total": {"type": "number"},
    },
}

def test_order_matches_schema(api_session, auth_token):
    response = api_session.post(
        f"{BASE_URL}/orders",
        headers={"Authorization": f"Bearer {auth_token}"},
        json={
            "product_id": 7,
            "quantity": 2,
        },
    )

    validate(instance=response.json(), schema=order_schema)

La validation de schéma détecte les champs manquants, renommés ou de mauvais type. Elle évite aussi de multiplier les assertions champ par champ.

La bibliothèque jsonschema est le choix courant pour ce besoin. Sa documentation de validation détaille les mots-clés disponibles.

Exécuter la suite en CI

Une suite pytest devient réellement utile lorsqu’elle s’exécute automatiquement à chaque changement.

Pytest renvoie un code de sortie non nul si un test échoue, ce qui permet à votre pipeline CI de bloquer un build ou une pull request.

Générez aussi un rapport JUnit :

pytest -v --junitxml=results.xml

Cette commande peut être appelée depuis GitHub Actions, GitLab CI, Jenkins ou tout autre outil CI.

Pour une configuration complète, y compris les secrets et la sélection d’environnement, consultez cette présentation des tests d’API dans les pipelines CI/CD.

Deux pratiques rendent la suite plus fiable en CI.

D’abord, ne codez pas en dur les secrets ni les URL d’environnement. Lisez-les depuis les variables d’environnement :

import os

BASE_URL = os.environ.get(
    "API_BASE_URL",
    "https://staging.example.com/v1",
)

Ensuite, exécutez les tests indépendants en parallèle si la suite devient lente. Le plugin pytest-xdist permet de répartir les tests sur plusieurs cœurs :

pip install pytest-xdist
pytest -n auto

Les tests parallèles exigent des données isolées. Évitez les tests qui dépendent de l’ordre d’exécution ou d’un état partagé.

Maintenir une suite pytest

Une suite de cinquante tests reste simple à gérer. Une suite de plusieurs centaines nécessite des conventions.

Regroupez les tests par domaine :

test_users.py
test_orders.py
test_payments.py

Utilisez les classes seulement lorsqu’elles apportent une configuration commune. Des fonctions explicites dans des modules bien nommés sont souvent plus lisibles.

Ajoutez des marks pour exécuter des sous-ensembles :

import pytest

@pytest.mark.smoke
def test_get_user_returns_200(api_session):
    response = api_session.get(f"{BASE_URL}/users/42")

    assert response.status_code == 200

Déclarez-les dans pytest.ini :

[pytest]
markers =
    smoke: tests rapides à exécuter à chaque commit
    slow: tests plus longs à exécuter moins souvent

Puis lancez uniquement les tests smoke :

pytest -m smoke

Centralisez aussi la configuration :

  • URL de base ;
  • headers communs ;
  • fixtures d’authentification ;
  • schémas JSON ;
  • helpers de création ou nettoyage de données.

Ne dupliquez pas ces éléments entre les fichiers de test. Si vous écrivez la même logique deux fois, extrayez-la dans une fixture ou une fonction utilitaire.

Cette discipline est la même que pour tout framework de test automatisé. Ce guide sur comment écrire des scripts de test automatisés détaille ces principes.

Quand utiliser plutôt une plateforme

Un framework pytest est adapté si votre équipe écrit en Python et veut conserver les tests dans le même dépôt que le code applicatif.

Il devient moins pratique lorsque :

  • les équipes QA ou produit doivent contribuer sans écrire de Python ;
  • vous voulez concevoir, mocker et tester les API dans un même outil ;
  • vous ne souhaitez pas maintenir de code de fixtures, de helpers et d’assertions.

Apidog couvre ce cas d’usage. Il propose la construction visuelle de tests, la validation de schéma par rapport à une spécification OpenAPI, des exécutions pilotées par CSV ou JSON, et un runner CLI pour la CI.

Beaucoup d’équipes combinent les deux approches : pytest pour les scénarios avec beaucoup de logique métier, et Apidog pour une couverture plus large, la conception d’API et le mocking. Vous pouvez télécharger Apidog et comparer les deux approches sur un endpoint réel.

Questions fréquemment posées

Pourquoi utiliser pytest plutôt que le module unittest intégré de Python pour les tests d’API ?

Pytest demande moins de boilerplate. Les tests sont de simples fonctions, les assertions sont de simples assert, et les fixtures gèrent la configuration plus souplement que les méthodes de classes de unittest.

Pytest dispose aussi d’un vaste écosystème de plugins et d’un support intégré de parametrize pour les tests pilotés par les données. Il peut toujours exécuter des tests existants de style unittest, ce qui facilite une migration progressive.

Quelle est la différence entre une fixture et parametrize ?

Une fixture fournit une ressource réutilisable à un test : session HTTP, token d’authentification, utilisateur de test, configuration, etc.

parametrize exécute le même test plusieurs fois avec différentes valeurs d’entrée.

En pratique :

  • les fixtures partagent la configuration ;
  • parametrize multiplie les cas de test ;
  • les deux peuvent être utilisés ensemble.

Devrais-je faire des assertions sur le temps de réponse dans les tests d’API pytest ?

Vous pouvez utiliser response.elapsed.total_seconds() pour détecter de fortes régressions :

assert response.elapsed.total_seconds() < 1.0

Gardez toutefois une limite assez large. Pytest est adapté aux tests fonctionnels, pas aux tests de charge. Pour mesurer précisément les performances, utilisez un outil dédié.

Comment garder les tests d’API indépendants dans pytest ?

Chaque test doit créer ou recevoir ses propres données via des fixtures. Évitez de dépendre :

  • de l’ordre d’exécution ;
  • d’une ressource créée par un autre test ;
  • d’un état partagé non nettoyé.

Des tests indépendants sont plus faciles à paralléliser, à déboguer et à exécuter isolément.

Pytest peut-il valider les réponses par rapport à une spécification OpenAPI ?

Pytest ne le fait pas directement. Vous pouvez valider les réponses avec jsonschema, ou ajouter des plugins capables de vérifier les réponses contre un document OpenAPI.

Si cette validation est centrale dans votre workflow, une plateforme comme Apidog peut automatiser la validation contre votre spécification OpenAPI et réduire la configuration côté pytest.