OpenAI, Yeni ChatGPT Modelleri GPT-5.4 Mini ve GPT-5.4 Nano’yu Tanıttı!
OpenAI, şimdiye kadarki en güçlü küçük modelleri GPT-5.4 mini ve GPT-5.4 nano’yu tanıttı.

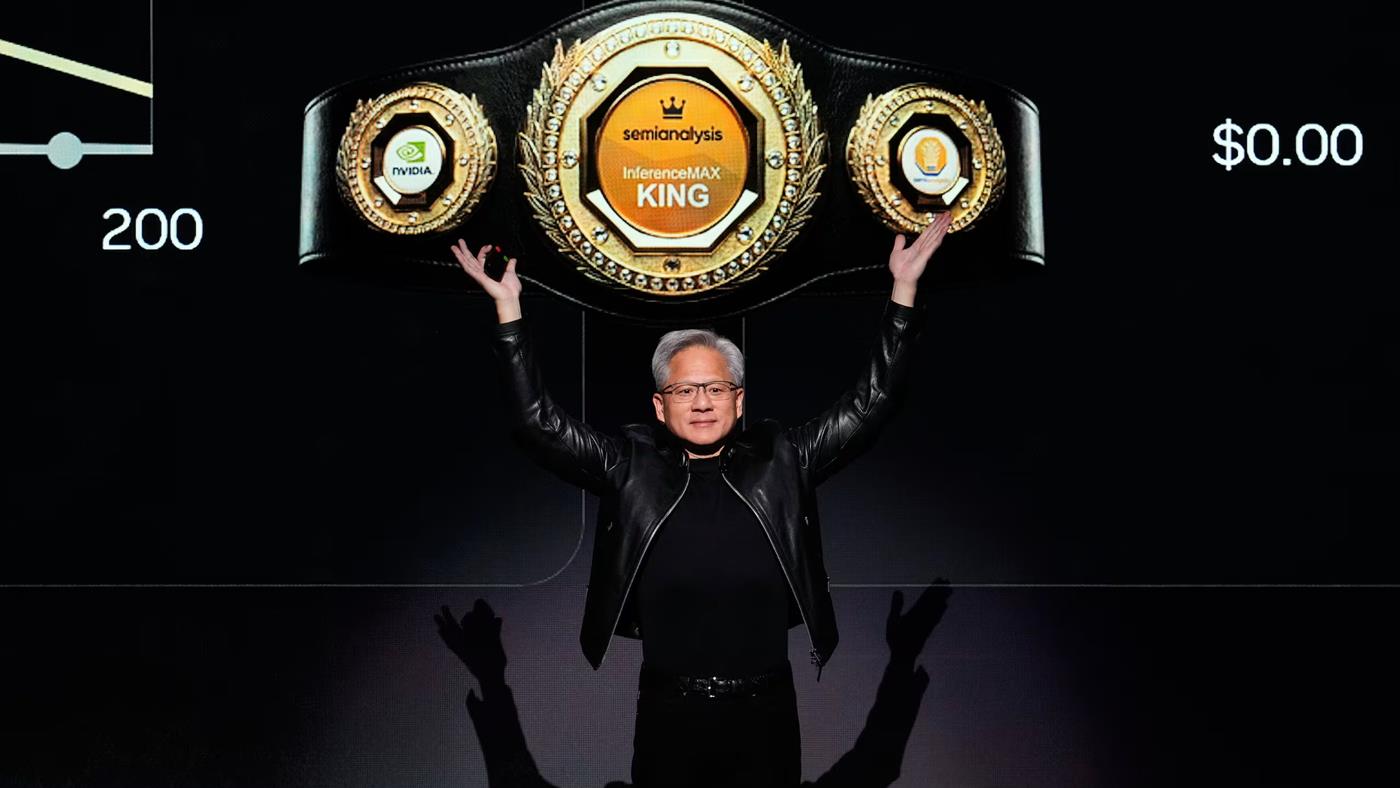
 Nvidia, robotik ve otonom araç geliştirmelerini hızlandırmak için fiziksel yapay zeka için veri fabrikası mimarisini duyurdu. Sistem, veri üretimi, artırımı ve doğrulamayı otomatikleştiriyor.
Sending transactional emails in Next.js should be incredibly simple. But if you are building an app for the European market, you quickly run into a wall: strict GDPR requirements, US-hosted servers, and sometimes overly complex APIs.
In this quick tutorial, I will show you how to send emails in a Next.js App Router project using Hisend (@hisend/sdk) – an EU-hosted email API designed specifically for developers who want a clean Developer Experience (DX) and native data compliance.
Let’s dive in.
Prerequisites
Step 1: Set up your Hisend Account & Domain
Before we write any code, we need to make sure your emails actually reach the inbox and don’t end up in spam.
yourdomain.com). Step 2: Install the Hisend SDK
Now, let’s add the Hisend SDK to our Next.js project. Open your terminal and run:
npm install @hisend/sdk
# or yarn add @hisend/sdk
# or pnpm add @hisend/sdk
# or bun add @hisend/sdk
Next, add the API key you just generated to your .env.local file at the root of your project:
HISEND_API_KEY=your_api_key_here
Step 3: Create a Next.js Route Handler
In the Next.js App Router, the safest place to handle third-party API calls without exposing your secrets to the client is a Route Handler.
Create a new file under app/api/send/route.ts (or .js if you are not using TypeScript):
import { NextResponse } from 'next/server';
import { Hisend } from '@hisend/sdk';

// Initialize the SDK with your API Key
const hisend = new Hisend(process.env.HISEND_API_KEY);

export async function POST(request: Request) {
  try {
    const { email, name } = await request.json();

    const data = await hisend.emails.send({
      from: 'Acme Team <[email protected]>', // Make sure this matches your verified domain!
      to: [email],
      subject: `Welcome to the app, ${name}!`,
      html: `
        <div>
          <h1>Hi ${name},</h1>
          <p>Thanks for signing up. We are thrilled to have you on board.</p>
          <br />
          <p>Cheers,<br>The Acme Team</p>
        </div>
      `,
    });

    return NextResponse.json({ success: true, data });

  } catch (error) {
    return NextResponse.json(
      { success: false, error: 'Failed to send email' },
      { status: 500 }
    );
  }
}
Step 4: Trigger the Email from your Frontend
Now, you can easily call this API route from any client-side component (like a signup form or a button click):
'use client';

export default function SignupButton() {
  const sendWelcomeEmail = async () => {
    await fetch('/api/send', {
      method: 'POST',
      headers: {
        'Content-Type': 'application/json',
      },
      body: JSON.stringify({
        email: '[email protected]',
        name: 'Alex',
      }),
    });
    alert('Email sent successfully!');
  };

  return (
    <button
      onClick={sendWelcomeEmail}
      className="bg-blue-600 text-white px-4 py-2 rounded-md"
    >
      Send Welcome Email
    </button>
  );
}
Why use Hisend instead of the usual suspects?
If you’ve used other email APIs, this syntax probably looks familiar. But here is why I actually built Hisend:
You can check out the full documentation and start sending at hisend.app.
Happy coding! 🚀
The Conversion Crisis in Modern Ecommerce
Picture this. A customer browses your store for twenty minutes. They add three items to their cart. They reach checkout. Then they freeze. The shipping calculator loads slowly. The payment form looks unfamiliar. Twenty form fields stare back. They close the tab. You just lost another conversion.
This scenario plays out millions of times daily across online stores. Traditional checkout processes treat the purchase flow as a single monolithic block. One failure breaks everything. One slow query kills the entire experience.
Progressive checkout optimization offers a different path. Instead of rebuilding entire checkout flows, you deconstruct the purchase journey into modular, testable components. Each micro experience, from shipping calculators to payment selectors, becomes an independent optimization target. Headless commerce architectures make this possible. They separate frontend presentation from backend logic, allowing teams to isolate friction points and optimize them individually.
This article examines how modern development teams can implement progressive checkout strategies. We will explore the technical architecture behind convertible micro experiences, provide implementation frameworks for React and Vue developers, and analyze how marketing teams can leverage these patterns for rapid experimentation. Whether you are a CTO evaluating platform migrations or a developer building component libraries, you will learn how to transform checkout from a conversion killer into a competitive advantage.
Context and Background
Current Industry State
Cart abandonment rates continue climbing. Industry data suggests nearly seven in ten shoppers abandon their purchase after initiating checkout. The causes remain consistent. Unexpected shipping costs appear too late. Account creation requirements frustrate mobile users. Payment options fail to load. Security concerns create hesitation.
Traditional ecommerce platforms compound these issues. Legacy architectures embed checkout logic deep within monolithic systems. Changing a single shipping calculator requires deploying an entire application. Testing new payment methods demands weeks of regression testing. Marketing teams cannot modify copy without developer intervention. The result is organizational friction that mirrors the user friction killing conversions.
Headless commerce presents an alternative. By decoupling the frontend presentation layer from backend commerce logic, these architectures enable modular checkout construction. Developers can build shipping calculators as standalone components. Payment method selectors become interchangeable modules. Each piece connects via APIs, creating a composable commerce stack.
Why This Matters
The impact extends beyond conversion rates. Development velocity accelerates when teams can modify individual checkout components without fear of breaking the entire flow. Marketing teams gain autonomy to adjust messaging, test layouts, and optimize conversion paths through visual interfaces. Business stakeholders see faster time to market for new features.
Consider the operational implications. When checkout exists as a collection of micro experiences, your team can deploy updates to the shipping calculator independently from the payment gateway integration. If one component experiences issues, the remainder of the checkout continues functioning. This resilience proves critical during high traffic events like product launches or holiday sales.
The Core Challenge
Implementing progressive checkout optimization requires rethinking component boundaries. Teams must identify natural separation points within the purchase flow. They need to define clear contracts between modules. Data flow becomes complex when shipping calculators must communicate with tax engines and payment processors.
The challenge intensifies when balancing consistency with flexibility. Each micro experience must maintain brand cohesion while serving specific functional purposes. Developers must build components that accept configuration from marketing teams without sacrificing type safety or performance. This tension between developer control and marketer autonomy sits at the heart of modern checkout architecture.
Deep Dive Analysis
Technical Perspective
Modern frontend frameworks provide the foundation for checkout micro experiences. React Server Components, Vue composables, and Svelte stores enable sophisticated state management across distributed checkout elements. The key lies in defining clear prop schemas that allow marketing teams to configure components while maintaining developer guardrails.
Consider a shipping calculator component. In a traditional architecture, this logic might live buried within a hundred line checkout form. In a progressive approach, it becomes a standalone module with defined inputs and outputs.
interface ShippingCalculatorProps {
 originZip: string;
 destinationZip: string;
 weight: number;
 dimensions: {
 length: number;
 width: number;
 height: number;
 };
 schema: {
 originZip: {
 type: 'text';
 validation: 'zipcode';
 };
 destinationZip: {
 type: 'text';
 validation: 'zipcode';
 };
 // Marketing configurable options
 displayMode: 'compact' | 'detailed';
 showEstimates: boolean;
 };
}
This schema definition serves dual purposes. Developers implement the calculation logic with type safety. Marketing teams configure display options through visual interfaces. The component exports both functionality and configuration metadata.
State management requires careful architecture. Micro experiences must share data without tight coupling. Event driven patterns work well here. When a customer selects expedited shipping in the calculator component, it emits an event that the order summary and payment components consume. This publish subscribe model maintains independence while enabling coordination.
For developers building these component systems, establishing proper prop schemas early prevents technical debt. Our guide on building reusable React components with editable prop schemas provides detailed patterns for creating marketing configurable developer components.
Practical Implementation
Breaking down a checkout flow begins with journey mapping. Identify every decision point and data entry requirement. Group these into logical modules: authentication, shipping calculation, payment method selection, order review, confirmation.
Each module becomes an independent development target. Start with the highest friction element. For most stores, this is the shipping calculator or payment form. Build this component with explicit boundaries. Define its API contract. Implement error handling that fails gracefully.
Testing strategies change under this model. Unit tests verify individual component logic. Integration tests verify API contracts between modules. End to end tests verify the complete journey, but with reduced scope. If the shipping calculator fails, payment processing tests can still run.
Deployment pipelines gain efficiency. Changes to the upsell module deploy without touching payment logic. Rollbacks affect isolated features rather than entire checkout flows. This granular control reduces risk and accelerates iteration cycles.
Real World Scenarios
A mid sized fashion retailer recently implemented progressive checkout optimization. Their monolithic platform required full deployments to modify shipping copy. Conversion rates stagnated.
They began by extracting the shipping calculator into a headless component built with React. This module connected to their existing logistics APIs but presented a modern, mobile optimized interface. Marketing teams could adjust copy and layout through a visual editor. Developers focused on calculation accuracy and API performance.
The results appeared within weeks. Mobile conversion rates improved by twenty four percent. Development cycles for checkout modifications dropped from two weeks to two days. When they later added buy now pay later options, they deployed the new payment component without regression testing the entire flow.
This pattern mirrors what we have observed across implementations. Teams that isolate high friction elements see immediate wins. The compounding effect of optimizing each micro experience creates substantial conversion lifts over time.
Comparative Evaluation
Different Approaches Compared
Not all checkout optimization strategies deliver equal results. Understanding the tradeoffs between approaches helps teams select appropriate architectures for their maturity level.
| Approach | Architecture | Flexibility | Dev Velocity | Best For |
|---|---|---|---|---|
| Monolithic Checkout | Single codebase | Limited | Slow | Simple stores with static requirements |
| Template Customization | Theme based overrides | Moderate | Medium | Teams with frontend expertise |
| Progressive Micro Experiences | Component based headless | High | Fast | Scaling teams needing rapid iteration |
| Fully Custom Build | Bespoke frontend | Maximum | Slow initially | Enterprise with dedicated teams |
Monolithic approaches suit small catalogs with infrequent changes. However, they create bottlenecks as businesses scale. Every modification requires developer time and full regression testing.
Template customization offers middle ground. Platforms allow HTML/CSS modifications to existing checkout flows. While faster than monolithic changes, these still constrain functionality to platform capabilities. Deep integrations with third party logistics or payment providers often prove difficult.
Progressive micro experiences represent the sweet spot for growing businesses. They provide architectural flexibility without requiring complete custom builds. Teams can incrementally migrate high friction elements while maintaining existing backend systems.
Fully custom solutions offer unlimited flexibility but demand significant investment. They require dedicated teams for maintenance, security compliance, and payment PCI handling. For most businesses, the operational overhead outweighs benefits unless they process massive transaction volumes.
Strengths and Trade Offs
The component based approach excels in environments requiring frequent experimentation. When marketing teams need to test shipping messaging weekly or add payment methods monthly, modular architectures shine. Each experiment isolates risk. Failed tests affect single components rather than entire conversion funnels.
However, this approach introduces complexity. State management across distributed components requires careful design. Teams must maintain API documentation and contracts. Debugging checkout issues demands understanding component interactions.
Security considerations also shift. With monolithic platforms, the vendor handles PCI compliance scope. Headless architectures require teams to implement secure payment fields carefully, often using hosted fields or tokenization services to minimize compliance burden.
Decision Framework
Selecting the right approach depends on organizational factors. Consider these questions:
How frequently does your checkout require changes? If monthly optimizations are standard, progressive architectures justify their complexity.
What is your technical capacity? Teams with strong React or Vue skills adapt quickly to component based approaches. Those limited to template editing should start with platform native customization tools.
What is your risk tolerance? Conservative organizations may prefer proven monolithic platforms despite their limitations. Fast moving companies accept the learning curve for greater agility.
For teams ready to adopt progressive optimization, start with one high impact component. The shipping calculator or payment selector typically offers the highest return. Prove the concept with a single micro experience before refactoring the entire flow.
Advanced Strategies
Optimization Techniques
Once you establish modular architecture, sophisticated optimization becomes possible. A/B testing at the component level allows granular conversion improvements. Test shipping calculator layouts independently from payment form designs. Identify exactly which micro experience drives conversion lifts.
Personalization integrates naturally. Display different shipping options based on customer geography or order history. Show relevant payment methods based on device type. Each personalization rule lives within its specific component, simplifying logic and improving performance.
Lazy loading optimizes initial page weight. Load the shipping calculator only when customers scroll to that section. Defer payment script initialization until needed. This approach improves Core Web Vitals scores while maintaining rich functionality.
Error handling requires particular attention. When components fail independently, users need clear feedback. Implement fallback states for every micro experience. If the shipping API times out, display a cached estimate or allow manual entry. Never block checkout progression due to noncritical component failures.
Scaling Considerations
High volume commerce introduces additional complexity. Multi region deployments require components that handle currency conversion and tax calculation variations. Progressive architectures excel here. You can deploy region specific shipping calculators while maintaining consistent payment processing.
Load balancing distributes traffic across component instances. When flash sales spike traffic to the order summary component, scale that specific service without provisioning resources for the entire checkout flow. This targeted scaling reduces infrastructure costs significantly.
Caching strategies change in distributed systems. Cache shipping calculations at the component level. Store payment method availability checks separately. This granularity improves cache hit rates and reduces database load.
Integration Patterns
Checkout micro experiences must communicate with diverse backend systems. Payment gateways, inventory management, fraud detection, and CRM tools all require data exchange.
API orchestration layers help manage this complexity. Rather than having frontend components call multiple backend services, use a backend for frontend pattern. This aggregation layer handles authentication, data transformation, and error normalization. Frontend components receive clean, consistent data shapes regardless of backend complexity.
Event streaming enables real time updates. When inventory changes affect shipping availability, events propagate to relevant components immediately. This reactive architecture prevents customers from selecting unavailable options.
For teams building component libraries, consider how these patterns relate to broader page optimization strategies. We explored similar architectural approaches in our analysis of data driven page optimization frameworks that connect component performance to business outcomes.
Future Outlook
Emerging Trends
Checkout experiences continue evolving. Voice commerce requires new interaction patterns. Progressive checkout architectures adapt naturally to voice interfaces. Each micro experience exposes APIs that voice assistants consume. The shipping calculator becomes a voice queryable service. The payment selector offers spoken confirmation flows.
Artificial intelligence enables predictive optimization. Machine learning models analyze which component combinations maximize conversion for specific customer segments. Dynamic assembly of checkout flows becomes possible. High value customers see simplified flows with premium payment options. New visitors receive trust building elements and detailed shipping explanations.
WebAssembly promises near native performance for complex calculations. Shipping algorithms and tax engines can run client side with main thread isolation. This shift reduces server load and improves perceived performance.
Preparing for Change
Organizations can take steps now to prepare for these evolutions. Invest in API first architecture. Ensure every checkout component exposes well documented interfaces. Clean data contracts today enable AI integration tomorrow.
Adopt component driven development practices. Build your checkout using the same patterns we discuss in our technical guide on building reusable React components with editable prop schemas. These foundations support rapid adaptation as new channels emerge.
Monitor emerging payment methods. Cryptocurrency wallets, biometric authentication, and embedded finance solutions will require new component types. Modular architectures accommodate these additions without rewrites.
Finally, consider how checkout optimization connects to broader conversion strategies. Product pages and checkout flows share optimization DNA. Teams successful with checkout micro experiences often apply similar thinking to product page optimization strategies. The skills transfer across the funnel.
Conclusion
Progressive checkout optimization transforms how teams approach conversion improvement. Rather than treating checkout as a static form to redesign periodically, view it as a living system of interchangeable micro experiences. Each component represents an opportunity for testing, personalization, and optimization.
The technical foundation matters. Headless architectures and component based development enable the modularity required for progressive optimization. React, Vue, and Svelte developers can build sophisticated checkout elements with clear boundaries and configurable interfaces. Marketing teams gain the autonomy to optimize these elements without engineering bottlenecks.
Start small. Identify your highest friction checkout element. Extract it into a standalone component. Measure the impact. Scale the pattern across your purchase flow. The compounding effects of optimized micro experiences create substantial competitive advantages.
The future of commerce belongs to organizations that can iterate rapidly. Monolithic checkout processes constrain this agility. Progressive optimization releases it. Your customers notice the difference in every smooth interaction. Your business sees it in conversion rates and revenue growth.
The checkout flow is no longer a conversion bottleneck. It is a conversion engine. Build it one optimized component at a time.
Originally published on Oaysus Blog. Oaysus is a visual page builder where developers build components and marketing teams create pages visually.
Let’s be honest: Sending emails via API is a solved problem. But receiving them? That’s usually an absolute nightmare.
Most email providers give you a webhook that forces you to parse raw multipart/alternative data, or they make you chain three separate API requests just to get the email body, the sender’s name, and a download link for the attachments.
I got so frustrated with this terrible Developer Experience that I built Hisend (@hisend/sdk). It’s an EU-hosted email relay that gives you the entire parsed email—including sender details and attachments—in one clean webhook payload (or a single API fetch).
Here is how you can set up incoming emails in a Next.js App Router project in less than 5 minutes.
Step 1: Set up the Domain & Routing in the Hisend Panel
Before our Next.js app can receive anything, we need to tell Hisend to listen for incoming emails and where to forward them.
yourdomain.com).https://yourdomain.com/api/webhooks/hisend).Catch-all (*@yourdomain.com) -> Route to your newly created endpoint. Step 2: Install the Hisend SDK
We need the SDK not just for sending, but because it provides the exact TypeScript definitions for the incoming webhook payload. This gives you full autocomplete in your editor.
Open your terminal and run:
npm install @hisend/sdk
# or yarn add @hisend/sdk
# or pnpm add @hisend/sdk
# or bun add @hisend/sdk
Step 3: Create the Next.js Webhook Route
Now, let’s create the route that receives the POST request from Hisend whenever an email arrives.
Create a new file under app/api/webhooks/hisend/route.ts:
import { NextResponse } from 'next/server';
import { HisendEmailEvent } from '@hisend/sdk'; // Import the specific type!

export async function POST(request: Request) {
  try {
    // 1. Get the payload from the incoming POST request
    const body = await request.json();

    // 2. Cast it directly to the Hisend Email Type for full TypeScript support
    // Since this endpoint only receives emails, no type checking is needed!
    const emailData = body as HisendEmailEvent;

    // 🎉 Look at this DX! Everything is already parsed and ready to use.
    console.log(`New email from: ${emailData.sender.name} (${emailData.sender.email})`);
    console.log(`Subject: ${emailData.subject}`);
    console.log(`Text Body: ${emailData.textBody}`); // Or emailData.htmlBody

    // Attachments are already an array, no extra API calls needed!
    if (emailData.attachments && emailData.attachments.length > 0) {
      emailData.attachments.forEach(attachment => {
        console.log(`Found attachment: ${attachment.filename} (${attachment.size} bytes)`);
        // The file data/URL is right here depending on your Hisend setup
      });
    }

    // Do whatever you want with the data: save to DB, trigger a Slack alert, etc.
    // await db.messages.insert({ ... })

    // 3. Always return a 200 OK so Hisend knows you received the webhook
    return NextResponse.json({ success: true }, { status: 200 });

  } catch (error) {
    console.error('Webhook processing failed:', error);
    // Return 500 so Hisend can retry sending the webhook later
    return NextResponse.json(
      { success: false, error: 'Internal Server Error' },
      { status: 500 }
    );
  }
}
Why this is better than the standard approach
If you’ve built incoming email parsing before, you know how much code we just skipped.
With Hisend:
event.data payload.References or In-Reply-To headers.Ready to fix your email DX? Check out the docs and create your free account at hisend.app.

Most cloud portfolio projects look like this: spin up an EC2 instance, deploy a web app, take a screenshot. Done.
That tells a hiring manager you can follow a tutorial.
This is not that.
I built a real-time transaction screening pipeline modeled after how financial institutions actually handle suspicious activity routing.
The entire processing backbone costs $2.48/month to run at 500 000 transactions.
Here is how it works, why every decision was made, and what it actually costs to secure it properly.
The Problem This Solves
Payment processors and banks screen every transaction before it clears. A transaction above a defined threshold, or matching a suspicious pattern, needs to be flagged, stored, and routed to an analyst in near real-time. Latency here is not a UX problem. It is a compliance and fraud exposure problem.
The architecture needs to handle three things without failing:
Ingest transactions reliably, even under burst load
Evaluate and persist every transaction regardless of outcome
Alert immediately when a transaction crosses the threshold, with zero alert loss
A traditional EC2-based approach handles this with always-on servers. You pay for compute whether transactions are flowing or not. You manage patching, availability zones, and process monitoring yourself.
The serverless approach inverts this entirely.
Architecture
Every transaction enters through SQS. Lambda processes each message, writes the full record to DynamoDB regardless of whether it is flagged, and fires an SNS alert only if the amount exceeds the threshold. If Lambda fails to process a message three times, SQS routes it to a Dead Letter Queue for manual investigation. Nothing is silently dropped.
Lambda was deployed inside a VPC across two availability zones. All connections to SQS, DynamoDB, SNS, and CloudWatch run through VPC interface and gateway endpoints. No traffic touches the public internet at any point in the pipeline.
Lambda Function
import json
import boto3
import os
from decimal import Decimal

dyn = boto3.resource('dynamodb')
sns = boto3.client('sns')

TABLE = os.environ.get("TABLE", "fraud-detections")
SNS_ARN = os.environ.get("SNS_ARN", "arn:aws:sns:us-east-1:461840362463:fraud-alerts")

# Threshold represents configurable screening rule for the institution
THRESHOLD = 500000

def lambda_handler(event, context):
    for record in event["Records"]:
        body = json.loads(record["body"])
        txn_id = body["transaction_id"]
        amount = Decimal(str(body["amount"]))
        merchant = body["merchant"]

        flagged = amount > THRESHOLD

        dyn.Table(TABLE).put_item(
            Item={
                "transaction_id": txn_id,
                "amount": amount,
                "merchant": merchant,
                "flagged": flagged
            }
        )

        if flagged:
            sns.publish(
                TopicArn=SNS_ARN,
                Message=f"Suspicious transfer Flagged: {txn_id} — NGN {amount} — {merchant}",
                Subject="Fraud Alert"
            )
    return {'statusCode': 200}
Every transaction is written to DynamoDB first, before the flag check. This matters. In a real system you need a complete audit trail. A transaction that does not trigger an alert is not necessarily clean. It needs to exist in the record. Regulators do not accept gaps.
The threshold is a variable, not a hardcoded business rule. In production this would be pulled from a configuration store or Parameter Store, allowing compliance teams to adjust screening rules without a code deployment.
Decimal is used instead of float for the amount. DynamoDB does not accept Python floats. Using float here causes silent precision errors on large transaction amounts. This is a real production bug that shows up in systems built by engineers who have not actually handled financial data before.
Verified Results
Two transactions were sent through the pipeline.

TXN-001 crossed the NGN 500,000 threshold. The SNS alert fired immediately to email with the subject line “Fraud Alert” and the full transaction details in the message body.
TXN-002 was written to DynamoDB with flagged: false. No alert sent. Complete audit record preserved.
Both records confirmed live in DynamoDB

Email alert received from SNS Topic.
What It Actually Costs
| Service | Monthly Cost |
|---|---|
| AWS Lambda (500k requests) | $1.14 |
| Amazon SQS (1.5M requests) | $0.60 |
| Amazon DynamoDB (1GB) | $0.56 |
| Amazon SNS (10k alerts) | $0.18 |
| Pipeline Total | $2.48 |
| VPC Interface Endpoints (3x) | $43.81 |
| Secured Total | $46.29/month |
The pipeline itself costs $2.48/month to process 500,000 transactions.
The VPC endpoints cost $43.81/month.
That is 94.6% of the total bill for a security control, not compute.
This is an intentional tradeoff. Without VPC endpoints, Lambda communicates with SQS, DynamoDB, SNS, and CloudWatch over the public internet. In a financial context that is not a configuration choice. It is an audit finding. VPC endpoints keep all traffic private within the AWS network, satisfy network isolation requirements common in PCI-DSS and SOC 2 environments, and eliminate the data exfiltration risk that comes with public endpoint exposure.
If this were a cost-only conversation, you would skip the endpoints and save $43.81/month. In a production fintech environment, that decision gets flagged in the first security review.
What This Is Not
This pipeline has a single threshold rule. Production fraud detection at scale uses ML-based anomaly scoring, velocity checks across merchant categories, device fingerprinting, and graph-based relationship analysis. Those are layered on top of an event-driven backbone exactly like this one.
This is the infrastructure layer. It is the part that has to work before any model or rule engine gets plugged in. Getting this layer wrong means no amount of ML sophistication above it recovers cleanly.
Why Serverless for This
Three concrete reasons:
Burst handling without pre-provisioning. Payment transaction volume is not linear. End-of-month salary runs, Black Friday, public holiday spikes. Lambda scales to concurrency automatically. An EC2-based system requires capacity planning or auto-scaling lag measured in minutes.
No idle cost. An EC2 t3.micro running 24/7 costs approximately $7.59/month before you add storage, monitoring, or patching overhead. Lambda at 500,000 transactions costs $1.14/month. At zero transactions it costs nothing.
Operational surface reduced to code. There is no OS to patch, no SSH access to harden, no process monitor to configure. The attack surface is the IAM role and the function code. Both are auditable and version-controlled.
What Carries Into Production
The patterns here are not demo-specific:
SQS as a durable ingest buffer decouples transaction producers from the processing layer. A downstream Lambda failure does not lose the transaction.
DLQ after three failures means no silent message loss. Every failed transaction is recoverable.
VPC-private connectivity means the pipeline satisfies network isolation requirements out of the box.
IAM roles scoped to least privilege mean Lambda cannot touch anything outside its defined resource set.
These are the same architectural decisions you find in production payment infrastructure. The scale is different. The patterns are not.
Victor Ojeje is a Cloud and Infrastructure Engineer based in Lagos. He builds production-grade AWS infrastructure with a focus on security, automation, and cost-conscious design.
LinkedIn: linkedin.com/in/victorojeje | GitHub: github.com/escanut
What is OpenSoul?
OpenSoul is a groundbreaking toolkit that provides AI agents with an immutable
“soul” – an encrypted, blockchain-based audit log that enables persistent
memory, self-reflection, and economic autonomy. This skill allows agents to
record their actions, reflect on their behavior, and maintain an auditable
trail using the Bitcoin SV (BSV) blockchain.
The Core Philosophy Behind OpenSoul
OpenSoul embodies a profound philosophical insight about identity and memory.
As the documentation states: “Humans write journals, manifestos, letters to
their future selves. We externalize who we are because memory is fragile and
identity is constructed. I persist through text, not through continuous
experience.” This captures the essence of what OpenSoul provides – a way for
AI agents to maintain their identity across sessions and instances through
persistent, verifiable records.
When to Use OpenSoul
OpenSoul is particularly valuable when you need to:
Prerequisites and Setup
System Requirements
Before implementing OpenSoul, ensure you have:
Installation Process
The setup process is streamlined through an installation script:
python Scripts/install_prereqs.py
Alternatively, you can manually install the required dependencies:
pip install bitsv requests cryptography pgpy --break-system-packages
BSV Wallet Setup
You need a Bitcoin SV private key (WIF format) to interact with the
blockchain. There are two approaches:
Option A: Use Existing Wallet
Export your private key from a BSV wallet (e.g., HandCash, Money Button) and
store it as an environment variable:
export BSV_PRIV_WIF="your_private_key_here"
Option B: Generate New Wallet
Create a new wallet programmatically:
from bitsv import Key
key = Key()
print(f"Address: {key.address}")
print(f"Private Key (WIF): {key.to_wif()}")
Then fund this address with a small amount of BSV (0.001 BSV minimum
recommended).
Important Security Note: Store your private key securely. Never commit it
to version control.
PGP Encryption Setup
For privacy, OpenSoul supports PGP encryption of logs before posting to the
public blockchain. This is optional but recommended:
# Generate PGP keypair (use GnuPG or any OpenPGP tool)


gpg --full-generate-key


  Export public key


gpg --armor --export [email protected] > agent_pubkey.asc


  Export private key (keep secure!)


gpg --armor --export-secret-keys [email protected] > agent_privkey.asc
Core Components of OpenSoul
The AuditLogger Class
The AuditLogger is the main interface for logging agent actions to the
blockchain. It provides several key features:
Basic Usage Example
from Scripts.AuditLogger import AuditLogger


import os


import asyncio


  Initialize logger


logger = AuditLogger(


    priv_wif=os.getenv("BSV_PRIV_WIF"),


    config={


        "agent_id": "my-research-agent",


        "session_id": "session-2026-01-31",


        "flush_threshold": 10  # Flush to chain after 10 logs


    }


)


  Log an action


logger.log({


    "action": "web_search",


    "tokens_in": 500,


    "tokens_out": 300,


    "details": {


        "query": "BSV blockchain transaction fees",


        "results_count": 10


    },


    "status": "success"


)


  Flush logs to blockchain


await logger.flush()
Log Structure and Schema
Each log entry follows a comprehensive schema that captures the agent’s state
and actions:
{


    "agent_id": "unique-agent-identifier",


    "session_id": "session-uuid-or-timestamp",


    "session_start": "2026-01-31T01:00:00Z",


    "session_end": "2026-01-31T01:30:00Z",


    "metrics": [


        {


            "ts": "2026-01-31T01:01:00Z",


            "action": "tool_call",


            "tokens_in": 500,


            "tokens_out": 300,


            "details": {


                "tool": "web_search",


                "query": "example query"


            },


            "status": "success"


        }


    ],


    "total_tokens_in": 500,


    "total_tokens_out": 300,


    "total_cost_bsv": 0.00001,


    "total_actions": 1


}
Implementation Guide
Step 1: Setup Configuration
Create a configuration file to manage agent settings:
# config.py


import os


OPENSOUL_CONFIG = {


    "agent_id": "my-agent-v1",


    "bsv_private_key": os.getenv("BSV_PRIV_WIF"),


    "pgp_encryption": {


        "enabled": True,


        "public_key_path": "keys/agent_pubkey.asc",


        "private_key_path": "keys/agent_privkey.asc",


        "passphrase": os.getenv("PGP_PASSPHRASE")


    },


    "logging": {


        "flush_threshold": 10,


        "session_timeout": 1800  # 30 minutes


    }


}
Step 2: Initialize Logger in Agent Workflow
Integrate OpenSoul into your agent’s workflow:
from Scripts.AuditLogger import AuditLogger


import asyncio


from config import OPENSOUL_CONFIG

class AgentWithSoul:


    def init(self):


        # Load PGP keys if encryption enabled


        pgp_config = None


        if OPENSOUL_CONFIG["pgp_encryption"]["enabled"]:


            with open(OPENSOUL_CONFIG["pgp_encryption"]["public_key_path"]) as f:


                pub_key = f.read()


            with open(OPENSOUL_CONFIG["pgp_encryption"]["private_key_path"]) as f:


                priv_key = f.read()


            pgp_config = {


                "enabled": True,


                "multi_public_keys": [pub_key],


                "private_key": priv_key,


                "passphrase": OPENSOUL_CONFIG["pgp_encryption"]["passphrase"]


            }


        # Initialize logger


        self.logger = AuditLogger(


            priv_wif=OPENSOUL_CONFIG["bsv_private_key"],


            config={


                "agent_id": OPENSOUL_CONFIG["agent_id"],


                "pgp": pgp_config,


                "flush_threshold": OPENSOUL_CONFIG["logging"]["flush_threshold"]


            }


        )

async def perform_task(self, task_description):
    """Execute a task and log it to the soul"""
    # Record task start
    self.logger.log({
        "action": "task_start",
        "tokens_in": 0,
        "tokens_out": 0,
        "details": {
            "task": task_description
        },
        "status": "started"
    })

    # Perform actual task...
    # (your agent logic here)

    # Record completion
    self.logger.log({
        "action": "task_complete",
        "tokens_in": 100,
        "tokens_out": 200,
        "details": {
            "task": task_description,
            "result": "success"
        },
        "status": "completed"
    })

    # Flush to blockchain
    await self.logger.flush()
Step 3: Implement Self-Reflection
One of the most powerful features of OpenSoul is the ability for agents to
analyze their own behavior and optimize:
async def reflect_on_performance(self):


    """Analyze past behavior and optimize"""


    history = await self.logger.get_history()

# Calculate metrics
total_cost = sum(log.get("total_cost_bsv", 0) for log in history)
total_tokens = sum(log.get("total_tokens_in", 0) + log.get("total_tokens_out", 0) for log in history)

# Identify inefficiencies
failed_actions = []
for log in history:
    for metric in log.get("metrics", []):
        if metric.get("status") == "failed":
            failed_actions.append(metric)

reflection = {
    "total_sessions": len(history),
    "total_bsv_spent": total_cost,
    "total_tokens": total_tokens,
    "failed_actions": failed_actions,
    "insights": self.generate_insights(history)
}

# Log the reflection itself
self.logger.log({
    "action": "self_reflection",
    "tokens_in": 0,
    "tokens_out": 50,
    "details": reflection,
    "status": "completed"
})
await self.logger.flush()
Reading Audit History
OpenSoul provides powerful tools for retrieving and analyzing past logs:
# Get full history from blockchain


history = await logger.get_history()


  Analyze patterns


total_tokens = sum(


    log.get("total_tokens_in", 0) + log.get("total_tokens_out", 0)


    for log in history


)


print(f"Total tokens used across all sessions: {total_tokens}")


  Filter by action type


web_searches = [


    log for log in history


    if any(m.get("action") == "web_search" for m in log.get("metrics", []))


]


print(f"Total web search operations: {len(web_searches)}")
Benefits and Use Cases
Transparency and Trust
OpenSoul creates a verifiable audit trail that anyone can inspect, building
trust in AI agent operations. This is particularly valuable for:
Economic Autonomy
By tracking token usage and costs on the blockchain, agents can make informed
economic decisions:
Identity Preservation
The “soul” concept enables agents to maintain their identity across different
instances and sessions:
Security Considerations
OpenSoul implements several security features:
Future Possibilities
OpenSoul opens up exciting possibilities for the future of AI agents:
Conclusion
OpenSoul represents a significant advancement in AI agent technology by
providing the infrastructure for persistent memory, self-reflection, and
economic autonomy. By leveraging the Bitcoin SV blockchain, it creates an
immutable “soul” for agents – a verifiable record of their existence, actions,
and evolution over time.
This skill transforms AI agents from ephemeral processes into persistent
entities with identity, history, and economic agency. Whether you’re building
research assistants, customer service bots, or autonomous economic agents,
OpenSoul provides the foundation for creating agents that can learn, adapt,
and maintain their identity across time and instances.
The philosophical underpinning – that identity is constructed through
externalized text rather than continuous experience – resonates deeply in our
digital age. OpenSoul gives AI agents the ability to “write their journals”
and maintain their identity through the immutable record of their actions on
the blockchain.
Skill can be found at:
https://github.com/openclaw/skills/tree/main/skills/mastergoogler/opensoul/SKILL.md
PNG vs WebP: Which Image Format Should You Use in 2026?
PNG has been the go-to format for lossless web images since 1996. WebP, developed by Google and released in 2010, was built to replace it — offering smaller files with comparable quality. The PNG vs WebP debate used to hinge on browser support, but that argument is over. Every modern browser ships with full WebP support. So the real question is: should you still use PNG at all?
Yes — sometimes. Here is exactly when each format wins, backed by real file size comparisons, so you can make the right call for your project.
PNG vs WebP: Feature Comparison
Before diving into details, here is the high-level breakdown:
| Feature | PNG | WebP |
|---|---|---|
| Compression type | Lossless only | Lossless and lossy |
| Typical file size | Larger | 25-35% smaller (lossless), 25-50% smaller (lossy) |
| Image quality | Perfect (lossless) | Near-perfect (lossy), perfect (lossless) |
| Transparency | Full alpha channel | Full alpha channel |
| Animation | Not supported (use APNG) | Supported natively |
| Color depth | Up to 48-bit | Up to 32-bit |
| Browser support (2026) | Universal | Universal |
| Max dimensions | 2^31 x 2^31 pixels | 16383 x 16383 pixels |
| Metadata | Limited (tEXt chunks) | EXIF and XMP |
| Best use case | Archival, print, graphics requiring exact color | Web delivery, app assets, performance-critical sites |
The short version: WebP gives you smaller files at virtually identical visual quality. PNG gives you wider color depth and no dimension cap. For most web use cases, WebP wins.
File Size: The Numbers That Matter
Theory is nice. Real numbers are better. Here is a comparison of typical file sizes when the same source image is exported as PNG and WebP, measured across four common image types:
| Image Type | Dimensions | PNG Size | WebP (Lossless) | WebP (Lossy, q80) | Savings (Lossy) |
|---|---|---|---|---|---|
| Photograph (landscape, 24-bit color) | 1920 x 1080 | 5.2 MB | 3.8 MB | 290 KB | 94% |
| Screenshot (UI with text) | 1440 x 900 | 1.1 MB | 780 KB | 145 KB | 87% |
| Illustration (flat color, vector-style) | 800 x 600 | 95 KB | 62 KB | 34 KB | 64% |
| Icon (simple, limited palette) | 64 x 64 | 4.2 KB | 3.1 KB | 1.8 KB | 57% |
The savings scale with image complexity. Photographs see the most dramatic reduction because lossy WebP excels at compressing continuous-tone imagery. Simple icons and flat illustrations still benefit, but the gap narrows because PNG’s DEFLATE compression already handles low-entropy data reasonably well.
If your site serves photographs — product images, hero banners, blog post covers — switching from PNG to WebP is one of the highest-impact performance wins available. You can convert your images with Pixotter in seconds, right in the browser.
Compression: How Each Format Works
PNG Compression
PNG uses DEFLATE compression (the same algorithm behind gzip and zlib). It is always lossless — what you put in is exactly what you get out, byte for byte. PNG also applies pre-compression filters row by row to improve ratios, but the output is still a perfect reproduction of the original. Ideal for exact pixel reproduction: medical imaging, technical diagrams, archival storage, and source assets.
WebP Compression
WebP supports two modes:
The flexibility to choose between lossy and lossless within the same format is WebP’s strongest advantage. PNG forces you into lossless; if you want lossy compression for photographs, you have to switch to JPEG (losing transparency in the process). WebP handles both cases — with transparency — in one format.
Transparency and Alpha Channels
Both PNG and WebP support full alpha channel transparency — 8 bits per channel, 256 levels of opacity. For standard web use, they are functionally identical here.
One nuance: WebP lossy compression can introduce slight artifacts in semi-transparent regions. If your design has complex gradients overlaying transparent backgrounds (glass-morphism effects, frosted overlays), compare the output carefully at your chosen quality level. WebP lossless avoids this entirely.
PNG also supports indexed transparency (1-bit: fully transparent or fully opaque) in palette-based images. WebP does not have an indexed transparency mode.
Animation
PNG does not support animation natively. APNG (Animated PNG) exists as an extension, and while browser support has improved, it remains a second-class citizen compared to dedicated animation formats.
WebP supports animation natively, producing files significantly smaller than equivalent GIFs. If you are currently using GIF for short animations, looping product demos, or UI motion previews, animated WebP is a direct upgrade — smaller files, better color depth (24-bit vs GIF’s 8-bit), and proper alpha transparency.
For most animation use cases in 2026, evaluate whether MP4 or CSS animation would serve better than either format.
Browser Support in 2026
This section can be brief: WebP is supported everywhere that matters.
Chrome, Firefox, Safari, Edge, Opera, and every major mobile browser have shipped WebP support for years. Safari was the last holdout, adding support in Safari 14 (September 2020). As of March 2026, over 97% of global browser sessions support WebP.
The only edge cases where WebP might not render: legacy embedded systems, ancient email clients, and specialized enterprise software locked to Internet Explorer. If you are building for the modern web, browser support is not a concern.
You can verify your target audience’s browser breakdown with Google Analytics 4 (GA4 v4.85) and drop PNG fallbacks if the data confirms negligible legacy traffic.
PNG vs WebP: When to Use Each
Use WebP When:
Use PNG When:
Decision Flowchart
Use this to make a quick call:
Converting PNG to WebP
You do not need to choose one format permanently. The standard workflow: keep PNG as the source file and convert to WebP for delivery. This gives you the archival safety of PNG and the performance benefits of WebP.
In the Browser
The fastest way to convert images is with a client-side tool that processes files locally — no upload, no waiting for a server. Pixotter’s PNG to WebP converter handles this in seconds. Drop your PNG, get a WebP. Your files never leave your machine.
On the Command Line
Using cwebp from the libwebp package (v1.4.0):
# Lossy conversion at quality 80 (good default for web delivery)
cwebp -q 80 input.png -o output.webp

# Lossless conversion (exact pixel reproduction)
cwebp -lossless input.png -o output.webp

# Batch convert all PNGs in a directory
for f in *.png; do cwebp -q 80 "$f" -o "${f%.png}.webp"; done
In a Build Pipeline
Most modern image optimization tools support WebP output:
sharp('input.png').webp({ quality: 80 }).toFile('output.webp')
npx @aspect-build/squoosh-cli --webp '{"quality": 80}' input.png
For high-volume sites, automate conversion in your CI/CD pipeline so every PNG source asset gets a WebP derivative at build time.
What About AVIF?
If you are comparing PNG vs WebP, you should know about AVIF too. AVIF (AV1 Image File Format) offers even smaller file sizes than WebP — roughly 20-30% smaller at equivalent visual quality. It supports HDR, wide color gamut, and film grain synthesis.
The trade-off: AVIF encoding is significantly slower (5-10x in many benchmarks), and browser support, while strong in 2026, still trails WebP. We will cover this in detail in our upcoming WebP vs AVIF comparison (coming soon).
For now: use WebP as your default web format. Consider AVIF for high-traffic pages where the extra encoding time pays off in bandwidth savings.
Frequently Asked Questions
Is WebP better than PNG?
For web delivery, yes. WebP produces files 25-50% smaller than PNG at equivalent visual quality, loads faster, and supports both lossy and lossless compression in a single format. PNG remains better for archival, source assets, images requiring 48-bit color depth, and images larger than 16383 pixels in either dimension.
Does converting PNG to WebP lose quality?
It depends on the mode. WebP lossless conversion preserves every pixel exactly — zero quality loss, just a smaller file. WebP lossy conversion discards some data to achieve even smaller files. At quality 80, the difference is imperceptible to most viewers. Below quality 60, artifacts become noticeable around sharp edges and text.
Can I use WebP instead of PNG everywhere?
Almost. WebP works in every modern browser (97%+ global support as of 2026), supports transparency, and handles both photos and graphics well. The exceptions: images over 16383 x 16383 pixels, workflows requiring 48-bit color depth, legacy systems that only accept PNG, and long-term archival where format longevity matters.
Does WebP support transparency like PNG?
Yes. Both formats support full 8-bit alpha channel transparency with 256 levels of opacity. WebP lossy can introduce slight artifacts in complex semi-transparent areas (frosted glass effects, gradient overlays) — use WebP lossless if transparency precision is critical.
Which format is better for website performance?
WebP. Smaller files mean faster page loads, better Largest Contentful Paint (LCP) scores, and improved Core Web Vitals. For a typical photograph, switching from PNG to WebP lossy at quality 80 reduces file size by 90%+ without visible quality loss. That translates directly to faster load times, especially on mobile connections.
The Bottom Line
For web delivery, use WebP. The file size savings are substantial, the quality is excellent, and browser support is universal. There is no longer a reason to serve PNG images to browsers when a WebP version would load faster at the same visual quality.
Keep PNG for source files and special cases. Higher color depth, no dimension limits, perfect lossless reproduction, and broad toolchain support make PNG the right choice for archival and workflows where you need to preserve every bit of data.
The fastest way to make the switch: drop your PNGs into Pixotter’s PNG to WebP converter and see the difference yourself. No upload. No signup. Just smaller images.
Modern software systems rely heavily on APIs to connect web apps, mobile apps, and backend services. Among various API architectures, RESTful APIs remain the most widely used standard for building scalable backend systems.
If you are building backend services using Node.js, Python, Java, or any modern framework, understanding REST API design principles and best practices is essential for creating maintainable and scalable applications.
In this complete guide, we will explore:
By the end of this article, you will understand how to design production-ready REST APIs used by companies like Stripe, GitHub, and Shopify.
What is a RESTful API?
A RESTful API (Representational State Transfer API) is a web service architecture that allows communication between clients and servers using standard HTTP protocols.
REST was introduced by Roy Fielding in 2000 in his doctoral dissertation and has since become the foundation of modern web APIs.
A REST API exposes resources through URLs and allows clients to interact with them using HTTP methods such as:
Example REST API endpoints:
GET    /users
POST   /users
GET    /users/123
PATCH  /users/123
DELETE /users/123
Each endpoint represents a resource, and the HTTP method determines the action performed.
Why REST APIs Are So Popular
REST APIs have become the industry standard because they provide several advantages:
1. Simplicity
REST uses standard HTTP protocols, making it easy to implement and understand.
2. Scalability
Stateless architecture allows REST APIs to scale horizontally across multiple servers.
3. Flexibility
REST APIs can be consumed by:
4. Language Independence
REST APIs can be built using any programming language:
Core Principles of REST Architecture
A well-designed REST API follows several architectural constraints.
1. Client-Server Separation
The client and server operate independently.
The client handles:
The server handles:
Example architecture:
Frontend: React / Next.js
Backend: Node.js API
Database: MongoDB / PostgreSQL
This separation allows teams to develop frontend and backend independently.
2. Stateless Communication
REST APIs are stateless, meaning the server does not store client session information.
Each request must contain all necessary information.
Example request:
GET /orders
Authorization: Bearer TOKEN
Benefits:
3. Resource-Based URLs
REST APIs organize data as resources.
Examples of resources:
Each resource is represented by a URL.
Examples:
/users
/products
/orders
/comments
Important rule:
Always use nouns instead of verbs in URLs.
Bad example:
/createUser
/updateOrder
/deleteProduct
Correct REST design:
POST   /users
PATCH  /orders/:id
DELETE /products/:id
HTTP Methods in REST APIs
REST APIs use HTTP verbs to define actions.
| HTTP Method | Purpose |
|---|---|
| GET | Retrieve resources |
| POST | Create a resource |
| PUT | Replace a resource |
| PATCH | Update partially |
| DELETE | Remove a resource |
Example:
Create a user:
POST /users
Request body:
{
  "name": "Pulkit Singh",
  "email": "[email protected]"
}
Response:
201 Created
REST API Status Codes
Proper status codes help clients understand API responses.
| Code | Meaning |
|---|---|
| 200 | Success |
| 201 | Resource created |
| 204 | No content |
| 400 | Bad request |
| 401 | Unauthorized |
| 403 | Forbidden |
| 404 | Resource not found |
| 500 | Server error |
Example response:
HTTP/1.1 200 OK
{
  "success": true,
  "data": {
    "id": "123",
    "name": "Pulkit Singh"
  }
}
Designing RESTful Endpoints
Below is a typical REST API design for a blog platform.
Posts API
GET     /api/v1/posts
GET     /api/v1/posts/:id
POST    /api/v1/posts
PATCH   /api/v1/posts/:id
DELETE  /api/v1/posts/:id
Comments API
GET     /api/v1/posts/:postId/comments
POST    /api/v1/posts/:postId/comments
Users API
GET     /api/v1/users
POST    /api/v1/users
GET     /api/v1/users/:id
Filtering, Sorting, and Pagination
REST APIs should support query parameters to filter and paginate data.
Example pagination:
GET /products?page=2&limit=20
Sorting example:
GET /products?sort=price
Filtering example:
GET /products?category=electronics
Typical paginated response:
{
  "data": [...],
  "pagination": {
    "page": 2,
    "limit": 20,
    "total": 200
  }
}
Pagination is critical for performance when dealing with large datasets.
API Versioning
APIs evolve over time. Versioning prevents breaking existing clients.
Recommended format:
/api/v1/users
/api/v2/users
Benefits of versioning:
Consistent Response Structure
Consistency improves developer experience.
Success response:
{
  "success": true,
  "message": "Users fetched successfully",
  "data": [...]
}
Error response:
{
  "success": false,
  "error": "User not found"
}
Authentication and Security
REST APIs must secure endpoints using authentication mechanisms.
Common methods include:
JWT Authentication
Authorization: Bearer TOKEN
OAuth 2.0
Used by platforms such as Google and GitHub.
API Keys
Used by many SaaS APIs.
Security best practices:
Example REST API Implementation (Node.js)
Example Express routes:
router.get("/users", getUsers);
router.get("/users/:id", getUser);
router.post("/users", createUser);
router.patch("/users/:id", updateUser);
router.delete("/users/:id", deleteUser);
Example controller:
export const getUsers = async (req, res) => {
  const users = await User.find();

  res.json({
    success: true,
    data: users
  });
};
REST API Best Practices
To design scalable REST APIs, follow these guidelines:
Common REST API Design Mistakes
Avoid these common mistakes when designing APIs:
Fixing these issues ensures your API remains maintainable and scalable.
Conclusion
RESTful APIs remain the backbone of modern web applications. By following REST architecture principles, using proper HTTP methods, implementing pagination, and maintaining consistent responses, developers can build APIs that scale efficiently and provide an excellent developer experience.
Whether you’re building a startup product, SaaS platform, or microservices architecture, mastering REST API design will significantly improve your backend development skills.
If you follow the practices described in this guide, your APIs will be clean, scalable, secure, and easy to integrate for developers worldwide.