The Perils of Premature Optimisation in Distributed Treasure Hunts

Before I dive into the details, let me set the scene. Our company had just acquired a new feature: a treasure hunt engine that would allow users to create and share complex, real-time, multi-player hunts. The twist? We had to scale this monstrosity to tens of thousands of concurrent users within 12 weeks – or risk losing our new business unit to a competitor who’d done this before.

## What We Tried First (And Why It Failed)

Our initial approach was to throw a bunch of caching layers at the problem, thinking that if we could just keep the treasure hunt state in memory, we’d never have to worry about scaling. We deployed a Redis cluster, a memcached proxy, and even experimented with caching some of the hunts’ state in the application itself. Sounds like a good idea, right? In theory, our approach made sense, but in practice, we quickly hit a wall.

One particular incident stood out. We launched the treasure hunt engine with a relatively simple hunt that had tens of concurrent players. Things seemed fine at first, but as the hunt progressed and our Redis cluster began to fill up with cached state, we started to see some weird performance issues. Turns out, that Redis cluster we set up was not only caching treasure hunt state, but also the entire hunt’s logic – including the infamous “gold chest” mechanic, which, when triggered, would update the entire hunt’s state for every player. Suddenly, our Redis cluster was serving up tens of thousands of redundant updates a second. We were hitting our Redis cluster’s memory limits, causing page faults, and eventually, our entire system would grind to a halt.

Error messages began to flood our logs: “connection refused” from Redis, followed by frantic alerts from our monitoring system and, on one memorable occasion, a production outage that lasted nearly 24 hours.

## The Architecture Decision

Fast forward to the after-action discussion, and we realized that our caching-first approach was a classic example of premature optimisation. We had optimised for low latency, rather than designing a system that could handle the load.

We decided to take a step back and re-design our system, this time prioritising reliability and scalability. We abandoned our caching setup and opted for a more distributed architecture. Specifically, we introduced a message queue (RabbitMQ) to handle updates to the hunts’ state, decoupling our database writes from the hunting experience for players. We also added a separate read-only replica of our hunt database, which we could easily scale to handle the load of caching hunt state using a dedicated caching layer.

This setup allowed us to handle the load without compromising on the user experience. The RabbitMQ queue helped us catch up on any backlog of updates, and the dedicated caching layer was able to serve up the relevant hunt state to players without overloading our system.

## What The Numbers Said After

The numbers were remarkably different from our caching-first approach. Our system was able to handle tens of thousands of concurrent users without breaking a sweat. Our median response time for hunts improved by a factor of 10, and our system-wide latency dropped from an average of 1.5 seconds to under 500 milliseconds.

Meanwhile, our uptime improved dramatically – from 95% to 99.99%. We no longer experienced those grueling production outages, and our support team was able to focus on actually helping customers rather than firefighting.

## What I Would Do Differently

If I had a second chance, I’d focus even more on the principles of distributed transactions and eventual consistency. While our separate read-only replica of the hunt database helped us scale, it introduced some complex challenges around keeping the replica up-to-date with the latest updates from the queue.

I’d probably use something like Apache Kafka or Amazon Kinesis to handle event handling, allowing us to more easily manage the consistency model and handle eventual consistency in a more robust way.

In the end, while our caching-first approach was a good idea in theory, it was the wrong approach for our specific use case. Scaling a high-traffic system like our treasure hunt engine requires a more nuanced understanding of distributed architecture and the trade-offs involved in different design choices.

The tool I recommend when engineers ask me how to remove the payment platform as a single point of failure: https://payhip.com/ref/dev1

Why Engineers Wear Hoodies While Social Media Sells Perfection

cover image is from->Image by catalyststuff on Magnific

This is not a technical post, but something I’ve been thinking about lately.
On one side, many scientists, engineers, startup founders, and developers live surprisingly simple lives. You see people at companies like Google, OpenAI, or research labs wearing the same hoodie every day, using old backpacks, drinking plain coffee, and focusing deeply on their work.

On the other side, social media constantly tells young people that they need more:
more skincare,
more fashion trends,
more luxury cafés,
more “must have” products,
more aesthetics,
more shopping hauls,
more routines.

Personally, I find this culture difficult to relate to. The less you consume the less you need. Especially on platforms driven by influencers, life is no longer presented as something to experience. It becomes something to perform.

And the contrast is hard to ignore.

I sometimes feel that scientists, researchers, and professors are no longer cultural role models for younger generations.

Many highly intelligent and productive people simplify their lives to protect their attention.
Meanwhile, algorithms encourage everyone else to consume endlessly.

Simplicity Is Not Laziness

There is a reason many developers and scientists dress simply.

People like Steve Jobs, Mark Zuckerberg, and many engineers in Silicon Valley became known for repetitive, minimal clothing styles.

Not because they could not afford more. Because reducing unnecessary decisions saves mental energy.

When your brain is focused on building products, solving problems, writing code, researching medicine, or designing systems, appearance becomes less important than clarity.

Simplicity creates focus.

A quiet room.
A basic outfit.
A clean workspace.
A smaller circle.
Less noise.

image is from->Image by freepik

For many builders, minimalism is not a fashion statement.
It is an optimization strategy.

The Influencer Economy Profits From Insecurity

Social media works differently.

Influencer culture often depends on creating dissatisfaction:
your outfit is outdated,
your body is imperfect,
your lifestyle is boring,
your room needs redesigning,
your skin needs fixing,
your morning routine is wrong.

The business model is simple:
make people feel incomplete,
then sell them the solution(!)

Sometimes the pressure is different depending on gender.

Many young women are pushed toward beauty products, fashion trends, and appearance focused consumption from a very early age through social media and advertising.

Meanwhile, many men are pushed toward status symbols, gadgets, cars, or financial success.

Both are forms of consumer pressure. And algorithms reward this behavior because insecurity drives engagement.

The result is a generation constantly comparing themselves to curated lifestyles that are often unrealistic, filtered, sponsored, or financially unsustainable.

Consumption Has Become an Identity

Years ago, people bought products because they needed them. Now many people buy products to build an online identity.

Coffee becomes content.
Books become decoration.
Travel becomes proof.
Gyms become aesthetics.
Even productivity becomes performance.

Sometimes people are no longer asking:
“Do I need this?”

They ask:
“Would this look good online?”

Builders Often Think Long-Term

One thing I notice about many developers, engineers, and technical people is that they often prioritize long-term freedom over short-term appearance.

Instead of spending constantly to impress strangers online, they invest time into skills:

  • coding
  • research
  • writing
  • building products
  • learning systems
  • creating businesses

I believe the reward is slower.
But usually more real.

While social media trends change every month, deep skills compound for years.

Maybe Simplicity Is Becoming Rebellious Again

In a world trying to monetize attention every second, simplicity almost feels rebellious.

  • Wearing basic clothes.
  • Ignoring trends.
  • Using things longer.
  • Reading instead of scrolling.
  • Building instead of performing.

None of these things look exciting on social media.
But they might create a calmer and more meaningful life.

And maybe that is why so many builders quietly choose simplicity.
I think Im going to wear my hoodie until it falls apart.

“Simplicity is prerequisite for reliability.”
― Edsger W. Dijkstra

Stop Treating setTimeout(fn, 0) Like Magic

TL;DR: setTimeout(fn, 0) doesn’t run code instantly — it defers execution to the Macrotask queue, after all Microtasks and pending renders. Here’s why relying on it is an anti-pattern and what to use instead.

We’ve all seen it in legacy frontend codebases or quick hotfixes. A piece of UI isn’t rendering correctly, or a DOM element isn’t ready yet, so a developer drops this in:
jssetTimeout(() => { doSomething(); }, 0);
It feels like magic because suddenly, the race condition disappears and the bug is solved. But do you actually know why it worked, or what it just did to your browser’s execution priorities?
To master frontend engineering at scale, you have to look under the hood at the JavaScript Event Loop.
The Mechanics: Microtasks vs. Macrotasks
The browser processes asynchronous JavaScript using two distinct queues:
Microtask Queue: Handles Promises (.then), async/await, and MutationObserver.
Macrotask Queue (Callback Queue): Handles setTimeout, setInterval, and user interactions.
The Event Loop has a strict rule: It will completely empty the Microtask Queue before it picks up even ONE task from the Macrotask Queue.
Don’t believe me? ⬆️ Run that code in your console and see for yourself.
When you run a setTimeout with 0 milliseconds, you aren’t running code instantly. You are intentionally telling the browser: “Take this function, push it to the back of the task queue, allowing pending microtasks and potentially a render cycle to complete first.”
Why relying on this is an architectural anti-pattern:
Using setTimeout(0) to bypass race conditions is like putting tape over a check engine light. It masks architectural flaws — usually meaning your component state is poorly synchronized, or you are trying to manipulate the DOM before a framework’s render lifecycle is fully complete.
Use these instead:

requestAnimationFrame — for aligning code execution with browser paint cycles
Framework lifecycle hooks — for DOM-ready execution
Proper state management — for synchronization issues

Modern frontend engines give us cleaner tools. If you need to align code execution with browser layout paints, look toward native utilities like requestAnimationFrame or framework-specific dependency tracking rather than relying on timers.
🛠️ I’ve documented these fundamental browser performance sequences and added a live tracking script to an open-source frontend architecture repository:
🔗 https://github.com/Passyswatz/frontend-mastery-notes
Feel free to clone it, test your own async code, and bookmark it for your team.

Save any webhook data to a database automatically with n8n — free workflow JSON

Every webhook is a data goldmine you’re probably wasting.

When Stripe charges a customer, when GitHub pushes a commit, when Typeform receives a response — your app fires a webhook. That data arrives once, gets processed, and disappears.

Most developers handle webhooks reactively: catch the event, do the thing, move on. But every webhook is also a record — a timestamped, structured snapshot of what happened in your business.

Here’s a 4-node n8n workflow that saves every incoming webhook to a Postgres database automatically. Set it up once, and you’ll have a queryable log of every webhook event your systems generate.

What the workflow does

Node 1 — Webhook trigger

A persistent HTTP endpoint that accepts POST requests. Any service that supports webhooks — Stripe, GitHub, Shopify, Typeform, Twilio, HubSpot, or your own app — can send events here. The URL stays the same forever; no polling needed.

Node 2 — Code: extract and normalize

A JavaScript Code node that pulls the fields you care about and standardizes them into a consistent shape, regardless of which service sent the webhook:

const payload = $input.first().json;nconst body = payload.body || payload;nreturn [{n  json: {n    source: payload.headers?.['x)-github-event'] ? 'github'n          : payload.headers?.['stripe-signature'] ? 'stripe'n          : payload.headers?.['x)webhook-source'] || 'unknown',n    event_type: body.type || body.event || body.action || 'raw',n    payload: JSON.stringify(body),n    received_at: new Date().toISOString()n  }n}];n```

nnFor Stripe you'd use `body.type` (e.g. `payment_intent.succeeded`). For GitHub, `body.action` and `body.repository.name`. For Typeform, `body.form_response.answers`. The Code node lets you handle all of them in one place.

### Node 3 — Postgres: INSERT
Writes the normalized record to your database. Supports Postgres, MySQL, SQLite — or swap for Google Sheets, Airtable, or Notion if you don't have a database yet.

### Node 4 — Respond to Webhook
Returns HTTP 200 immediately after the database write. Best practice: always respond within 5 seconds or the sender will retry and create duplicate records.

---

## Setup (10 minutes)

1. **Import the JSON** into n8n (New Workflow → Import from clipboard)
2. **Create the table** in your database:


```sql
CREATE TABLE webhook_log (
  id SERIAL PRIMARY KEY,
  source TEXT,
  event_type TEXT,
  payload JSONB,
  received_at TIMESTAMP DEFAULT NOW()
);
  1. Connect your Postgres credential in Node 3
  2. Copy your webhook URL from Node 1 — looks like https://your-n8n.com/webhook/webhook-to-db
  3. Activate the workflow — it starts listening immediately
  4. Paste the URL into Stripe, GitHub, Typeform, or any other source

Test it: send a test event, then run SELECT * FROM webhook_log to confirm the row appeared.

Full workflow JSON

{
  "name": "Webhook to Database",
  "nodes": [
    {"parameters":{"httpMethod":"POST","path":"webhook-to-db","responseMode":"responseNode","options":{}},"id":"wb1","name":"Receive Webhook","type":"n8n-nodes-base.webhook","typeVersion":2,"position":[240,300]},
    {"parameters":{"jsCode":"const payload = $input.first().json;nconst body = payload.body || payload;nreturn [{n  json: {n    source: payload.headers?.['x-github-event'] ? 'github'n          : payload.headers?.['stripe-signature'] ? 'stripe'n          : payload.headers?.['x-webhook-source'] || 'unknown',n    event_type: body.type || body.event || body.action || 'raw',n    payload: JSON.stringify(body),n    received_at: new Date().toISOString()n  }n}];"},"id":"wb2","name":"Extract Fields","type":"n8n-nodes-base.code","typeVersion":2,"position":[460,300]},
    {"parameters":{"operation":"executeQuery","query":"INSERT INTO webhook_log (source, event_type, payload, received_at) VALUES ('{{ $json.source }}', '{{ $json.event_type }}', '{{ $json.payload }}'::jsonb, '{{ $json.received_at }}'::timestamp) RETURNING id"},"id":"wb3","name":"Save to Database","type":"n8n-nodes-base.postgres","typeVersion":2.3,"position":[680,300]},
    {"parameters":{"respondWith":"json","responseBody":"={"ok": true, "id": {{ $json.id }}}"},"id":"wb4","name":"Return 200 OK","type":"n8n-nodes-base.respondToWebhook","typeVersion":1.1,"position":[900,300]}
  ],
  "connections": {
    "Receive Webhook":{"main":[[{"node":"Extract Fields","type":"main","index":0}]]},
    "Extract Fields":{"main":[[{"node":"Save to Database","type":"main","index":0}]]},
    "Save to Database":{"main":[[{"node":"Return 200 OK","type":"main","index":0}]]}
  },
  "settings":{"executionOrder":"v1"},
  "tags":[{"name":"data"}]
}

Pro tips

Use JSONB, not TEXT, for the payload column
Postgres JSONB lets you query inside the payload with -> operators:

-- Find all Stripe payments over $50
SELECT received_at, payload->>'amount'
FROM webhook_log
WHERE source = 'stripe'
  AND event_type = 'payment_intent.succeeded'
  AND (payload->>'amount')::int > 5000;

This turns your webhook log into a lightweight analytics layer — no separate BI tool needed.

Add deduplication to handle retries
Services retry webhooks if they don’t get a 200 within 5 seconds. Add a unique constraint on the event ID:

ALTER TABLE webhook_log ADD COLUMN event_id TEXT UNIQUE;

In Node 2: event_id: body.id || body.event_id || null — duplicate events get rejected at the DB level, silently.

Route to different tables by source
Add an IF/Switch node between Extract Fields and Save to Database. Route Stripe events to stripe_events, GitHub events to github_events. Faster queries, cleaner schema.

Alert on high-value events
Add a parallel branch after Extract Fields: IF event_type === 'payment_intent.succeeded' → Slack node. You get a Slack ping every time a payment lands, while the database write still happens in the main branch.

Use Google Sheets instead of Postgres
No database? Swap the Postgres node for a Google Sheets “Append Row” node. You lose JSONB querying but gain a shareable spreadsheet log that non-technical teammates can read.

What you can build once all webhooks are in a database

  • Revenue tracking: SELECT DATE(received_at), COUNT(*) FROM webhook_log WHERE event_type = 'payment_intent.succeeded' GROUP BY 1
  • Error monitoring: alert when event_type LIKE '%failed%' or '%error%'
  • Audit trail: replay any past event for debugging or compliance
  • Customer journey: join form submissions, payments, and support tickets by customer ID
  • Capacity planning: see which endpoints receive the most traffic by hour

This workflow is simple. What you build on top of it is not.

Get the full automation bundle

This workflow is part of our 15-template n8n automation bundle — each one covering a different business use case: lead capture, invoice generation, AI customer support, social media automation, price monitoring, and more.

Grab the full bundle at stripeai.gumroad.com — pre-tested, documented, ready to activate.

Built with n8n. Self-hostable, open source, no vendor lock-in.

Translating an entire multilingual site shouldn’t mean re-prompting an LLM for every file

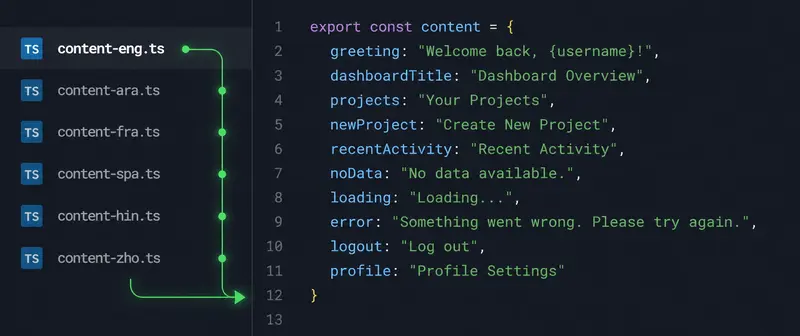
A dark code editor showing a file tree where content-eng.ts branches into <br>
language files content-ara.ts, content-fra.ts, content-spa.ts and others, <br>
next to a code snippet containing a username placeholder.

A dark code editor showing a file tree where content-eng.ts branches into <br>
language files content-ara.ts, content-fra.ts, content-spa.ts and others, <br>
next to a code snippet containing a username placeholder.

If you have ever built a multilingual site, you have probably hit this wall. You build the whole thing in one language first, usually English, and only then do you turn to translation. And that second half of the job is far more tedious than it has any right to be.

This post is about a specific, annoying corner of localization work: translating structured content files and code, and why the usual “just paste it into an LLM” approach quietly wastes a lot of your time.

The setup most of us end up with

A common pattern for a multilingual site is a content directory with one file per language. Something like:

src/content/
  content-eng.ts
  content-ara.ts
  content-fra.ts
  content-spa.ts
  content-hin.ts
  content-zho.ts

You write the whole site against the default language file, content-eng.ts, get everything working, and then the translation phase begins. Each of those other files has to end up as a faithful translation of the English one, with the exact same structure: same keys, same nesting, same TypeScript types, same interpolation placeholders. Only the human-readable string values should change.

On paper this is simple. In practice it is death by a thousand repetitions.

Why the “just use an LLM” answer gets old fast

LLMs are genuinely good at this kind of translation. They understand that welcomeMessage: "Welcome back, {username}" should become welcomeMessage: "Bienvenido de nuevo, {username}" and that the placeholder must stay untouched. They preserve structure, they handle context, they get the tone right.

The problem is not capability. The problem is the workflow around it.

Every time you open a new chat to translate a file, you are re-establishing the same context from scratch:

  • “Keep all the keys and structure identical.”
  • “Do not translate the placeholders like {username} or {count}.”
  • “Leave URLs, code identifiers, and technical terms alone.”
  • “Return valid TypeScript, not markdown, not commentary.”
  • “Translate into Arabic.” (then French, then Spanish, then…)

You paste the file, you wait, you copy the result back, you check it compiles, you move to the next language, and you do the entire dance again. For one site with six languages, that is the same prompt repeated five times. For multiple sites, or every time you update the source content, it multiplies. New tab, same prompts, same copy-paste, same verification. It is the definition of redundant work, and “the AI is doing it” does not make the process any less repetitive.

What you actually want

Step back and the requirement is clear. You want to:

  1. Hand over the source file once.
  2. Specify the target languages once.
  3. Get back one correctly-structured, translated file per language.
  4. Have placeholders, keys, and code left exactly as they were.

In other words, you want the LLM’s translation ability without re-typing the instructions for every file and every language.

Treating code and content files as translatable documents

This is the angle that made me look at the problem differently. A content-eng.ts file is, in a sense, just a document to be translated, with strict rules about what may change and what may not. The same is true for a lot of code: comments, user-facing strings, and documentation should be translated, while syntax, identifiers, and structure must be preserved exactly.

LLM-based translation is well suited to this because it works from a large context window rather than chopping the input into isolated sentences. It can see the whole file at once, understand that a {username} token is a placeholder and not a word to translate, and keep the surrounding structure intact.

This is the part of DocTranslating that is genuinely useful for developers. Alongside the usual document formats, its Gemini engine handles code files, things like .ts, .js, .py, and others, translating the human-readable parts while leaving the code itself alone. You give it the file and the target languages, and you get back translated files without re-stating the rules each time. It also supports translating one file into multiple target languages in a single pass, which is exactly the “one source, many outputs” shape this problem has.

It will not replace a careful review of locale files for a production app, and it should not. But for the bulk grunt-work of getting from one language to many, it removes the part that makes the job feel like punishment: the repetition.

A few honest caveats

A couple of things worth being straight about, because localization has sharp edges.

LLM translation is per-file context, not whole-project context. If a term needs to be translated consistently across many files, you still need to enforce that yourself, for example by giving the same terminology instruction or by keeping a glossary. The model does not magically remember decisions from a file it translated an hour ago.

And for right-to-left languages like Arabic, translation of the strings is the easy part; making sure your UI actually renders RTL correctly is a separate front-end concern that no translation tool solves for you.

The takeaway

The interesting shift here is conceptual. Once you start treating your content files and code as documents to be translated under strict structural rules, the redundant per-file, per-language prompting disappears. The LLM was never the bottleneck. The workflow around it was.

If your localization process currently looks like opening a fresh tab for every file and re-typing the same instructions, that is the part worth fixing first.

I built a Vite plugin that uses AI to author Playwright tests, then gets out of the way

I’ve been skeptical of AI testing tools for a while, but not for the reasons most people are.

My problem isn’t that AI can’t drive a browser. It clearly can. My problem is what happens after.

Every tool I tried made the same implicit trade: the AI stays in the loop at runtime. Your “test” is really a prompt that gets re-evaluated every time CI runs. The model drifts, the response changes slightly, your test starts flaking — and you have no idea why because there’s no diff to look at. You just have vibes and a red build.

I kept thinking: I don’t want AI to run my tests. I want AI to write them.

The thing Playwright Codegen almost got right

Playwright’s built-in codegen is underrated. You record your actions, it spits out a .spec.ts file, and that file is yours forever. No model, no API key, no ongoing cost. Just code.

The problem is it records mechanically. It doesn’t think. It’ll happily record click('[data-testid="btn-3"]') instead of getByRole('button', { name: 'Sign in' }). It can’t handle conditional flows. It doesn’t know what you’re actually trying to verify.

What I wanted was: Playwright Codegen, but the thing doing the recording understands what it’s looking at.

Connecting to the browser I’m already using

The first real decision was how to connect to the browser.

Every AI browser tool I’d seen launches its own headless Chromium. Clean, isolated, reproducible. Also completely useless for how I actually develop.

When I’m debugging a login flow at 11pm, I’m already logged in. I have three tabs open. I have the React DevTools panel where I need it. I have the page in exactly the state that’s causing the problem. Launching a fresh browser throws all of that away.

So I went the other direction: connect to the Chrome that’s already running, over CDP. connectOverCDP, find the tab whose URL matches the dev server, and work from there.

This turned out to matter more than I expected. The agent has access to real auth state. It can operate the page in the actual condition you’d be testing. It’s not pretending to be a user — it’s operating as one.

The sandbox problem

Giving an AI agent access to your browser is a little terrifying if you think about it too hard.

I spent more time on the sandbox than on anything else. The agent only gets one tool: the Playwright MCP server. Bash, Write, Read, WebFetch — all explicitly denied. The only write path is the spec file that gets emitted when you click Save. There’s also a hard --max-budget-usd ceiling per session.

The mental model I settled on: the agent is a very capable intern who’s allowed to operate the browser and nothing else. They can’t touch the filesystem. They can’t make network calls. They definitely can’t run shell commands.

A typical 5-step session comes out around $0.10.

The thing I didn’t plan for

I didn’t intend for “no new API key” to be a feature. It just fell out of the architecture.

Hover doesn’t bundle any AI runtime. It scans PATH for whatever coding-agent CLI you already have — claude, codex, cursor-agent. If you have Claude Code installed, that’s your agent. Nothing to configure.

The first time someone tried it and said “wait, I don’t have to set anything up?” I realized this was more important than I’d thought. Most developers I know have at least one agent CLI already installed. The friction of yet another API key, yet another account, is small but real — and apparently enough to make people bounce.

What actually comes out the other side

Add one line to vite.config.ts:

import { hover } from '@hyperyond/vite-plugin'

export default defineConfig({
  plugins: [react(), hover()],
})

Start your dev server. A floating widget appears in your dev page. Type what you want to verify:

“Log in as the test user, add two items to the cart, and check out”

The agent drives your actual Chrome. When it looks right, click Save. You get this:

import { test, expect } from '@playwright/test'

/**
 * Steps:
 * 1. Navigate to the login page
 * 2. Fill in username and password
 * 3. Click Sign in
 * 4. Add two items to cart
 * 5. Complete checkout
 *
 * Expected: Order confirmation page shows "Thank you"
 */
test('checkout flow', async ({ page }) => {
  await page.goto('http://localhost:5173/')
  await page.getByLabel('Username').fill('testuser')
  await page.getByLabel('Password').fill('password123')
  await page.getByRole('button', { name: 'Sign in' }).click()
  // ...
  await expect(page.getByText('Thank you')).toBeVisible()
})

No imports from Hover. No runtime dependency on anything I built. Run it with npx playwright test on a machine that’s never heard of Hover.

That’s the whole point. The agent authors the test. Then it’s done. The artifact is yours.

Where it gets interesting: a 50-field form

The demo that convinced me this approach actually works is a realistic brokerage account registration form — ~50 fields, conditional reveals, multi-select chips, file upload, compliance acknowledgements.

The agent handled most of it unprompted. It did get stopped by three required radio groups the form’s own validator caught. Hover surfaces a card explaining why it paused — the human flips those three radios and re-runs.

I think that’s actually the right split: agent handles what it can see and reason about, human handles the judgment calls.

One session, three outputs

When a session goes well, the Save dropdown gives you three options:

📜 Save as spec → __vibe_tests__/login-flow.spec.ts
Standard Playwright. Runs in CI. No agent required.

💾 Save as Skill → .claude/skills/login-flow/SKILL.md
Next time you say “execute login-flow” in the widget, it replays the same steps. Useful for skipping repetitive setup while building a different part of the app.

📋 Save as Jira case → __vibe_tests__/login-flow.case.csv
Xray-compatible CSV. Drag it into Jira, it becomes a real Manual Test issue — assignable, linkable to a story. No copy-pasting steps from a code editor into a ticket ever again.

What I’d do differently

The CDP setup is friction I haven’t solved. You have to launch Chrome in debug mode manually before starting. It’s one command, but it’s one command people forget.

Same-origin navigation occasionally kills the widget mid-session. It auto-resumes on reload, but still annoying. This is the thing I most want to fix next.

The project is called Hover. Apache-2.0, works with any Vite app.

👉 github.com/Hyperyond/Hover

If you’ve run into the same frustration with AI-in-the-loop testing, I’d be curious whether this framing resonates — or whether I’m solving the wrong problem entirely.

Project: Restaurant Delivery CRUD

If you follow my blog, you noticed that in these past 4 months I focused mainly on my Sushi Project development. Now I can say that we have the first version of the application, obviously, a lot room for improvement but one of the main goals has been reached: “find my motivation for self learning again”.

Here is the git of this project and in this post I will describe some challenges, key takeaways and insights.

The project consisted of creating a small CRUD (Create, read, update and delete) application for keep data on customer, orders and products for a Sushi Delivery family business. It was interesting to understanding the table structure of a CRUD given that I work mainly with ERP systems and their integration for analysis. As I developed the other side, I started to better understand the integration of systems like SAP S/4, M365 etc.

The first challenge of the project was to keep costs as low as possible. The company was a truly family business, therefore investing in classic Public Cloud services, such as Azure or AWS, was not an option. Also, it could lead to unexpected expenses that we could not afford. For that reason we decided to use NEON Database for storage and DigitalOcean for Cloud.

NEON Database has a free option that allows create 100 projects, 100 CU-hrs/month, 0.5 of storage per project and size ups to 2 CU/8 RAM. This sounds a great opportunity to make tests and take risks without the pressure of investment and fast results. Meanwhile, the DigitalOcean, provided a $200,00 credits for the first 5 months, and the VM investment started by $4/month. After these 5 months of on and offs, restarts and many errors, the total investment to build the first version was $4,32.

The other technologies as Ubuntu, GitHub etc were opensource.

The second challenge of developing a frontend from scratch. As a Data Engineer, frontend was not my strength, so the learning curve of understanding ports and web application was slow but steady. For this step, I worked with Claude AI. I created the wireframes, what we call in marketing as mockups, in DrawIO and added in a folder, then with Claude Code’s support, I guide it to develop the HTML files from my FrontEnd while I focus in the BackEnd using Python and Flask. Working up with AI’s helped me a lot to focus in the things that I was really interest and actually build logical and critical thinking from the project development. The key here was: not only ask the AI support for development, but be critical about what is being doing in each file and not accept changes without understand the reason of it.

I would say, like learning math and physics, getting the final results is easy but you need to understand how and why this result is correct. Maybe that’s why Halliday and Resnick has all the answers by the end of the book.

After all these points, my last takeaways was something that my experience in marketing supported and I genuinely miss it as consultant. The chance of work within the Sushi Delivery business, in their kitchen and see the struggles in real life of taking orders, organizing the orders in the most busy days make possible to visualize the bottlenecks of the manual system and really feel where are the parts that I need to automate in order to create the application. Something similar is described in the book “The Phoenix Project: A Novel About IT, DevOps, and Helping Your Business Win”. The feeling of going to the power plant (as in the book), kitchen (as in this project) and visualize how the processes can be transferred to the technological world is a total deal break to improve the results.

Now, I am aware that there is a huge room for improvement. From UX and UI, but also regarding the Infrastructure and CI/CD. Therefore, the next step will work along the final user and improve the details to support better their business.

Sources:
Git Project
The Phoenix Project Book