Samsung, bazı telefonlarında Çinli CSOT imzalı OLED paneller kullanabilir

Samsung

SamsungSamsung, The Elec tarafından ortaya atılan iddiaya göre Galaxy A ve Galaxy FE serisi bazı telefonlarında CSOT (Chinese manufacturer China Star Optoelectronics Technology) imzalı OLED paneller kullanmaya başlayabilir. Şirketin Çinli şirkette tam 15 milyon adet panel sipariş ettiğini öne süren kaynaklar, Samsung’un bu adımı diğer alanlarda (bellek ve fazlası) artan maliyetleri dengelemek adına attığını belirtiyor. CSOT’un ürettiği OLED panellerin yüzde 20 daha ucuz olduğu söylenirken, şu anda Galaxy telefonlarda doğrudan Samsung Display tarafından üretilen OLED paneller kullanılıyor. Bu sürpriz CSOT kararının şirket içinde gerginliğe yol açtığı da iddia ediliyor. Aktarıldığı kadarıyla Samsung Display bu duruma karşı çıkmaya çalışmış ancak alımı iptal ettirme konusunda başarılı olamamış.

Samsung, bazı telefonlarında Çinli CSOT imzalı OLED paneller kullanabilir yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

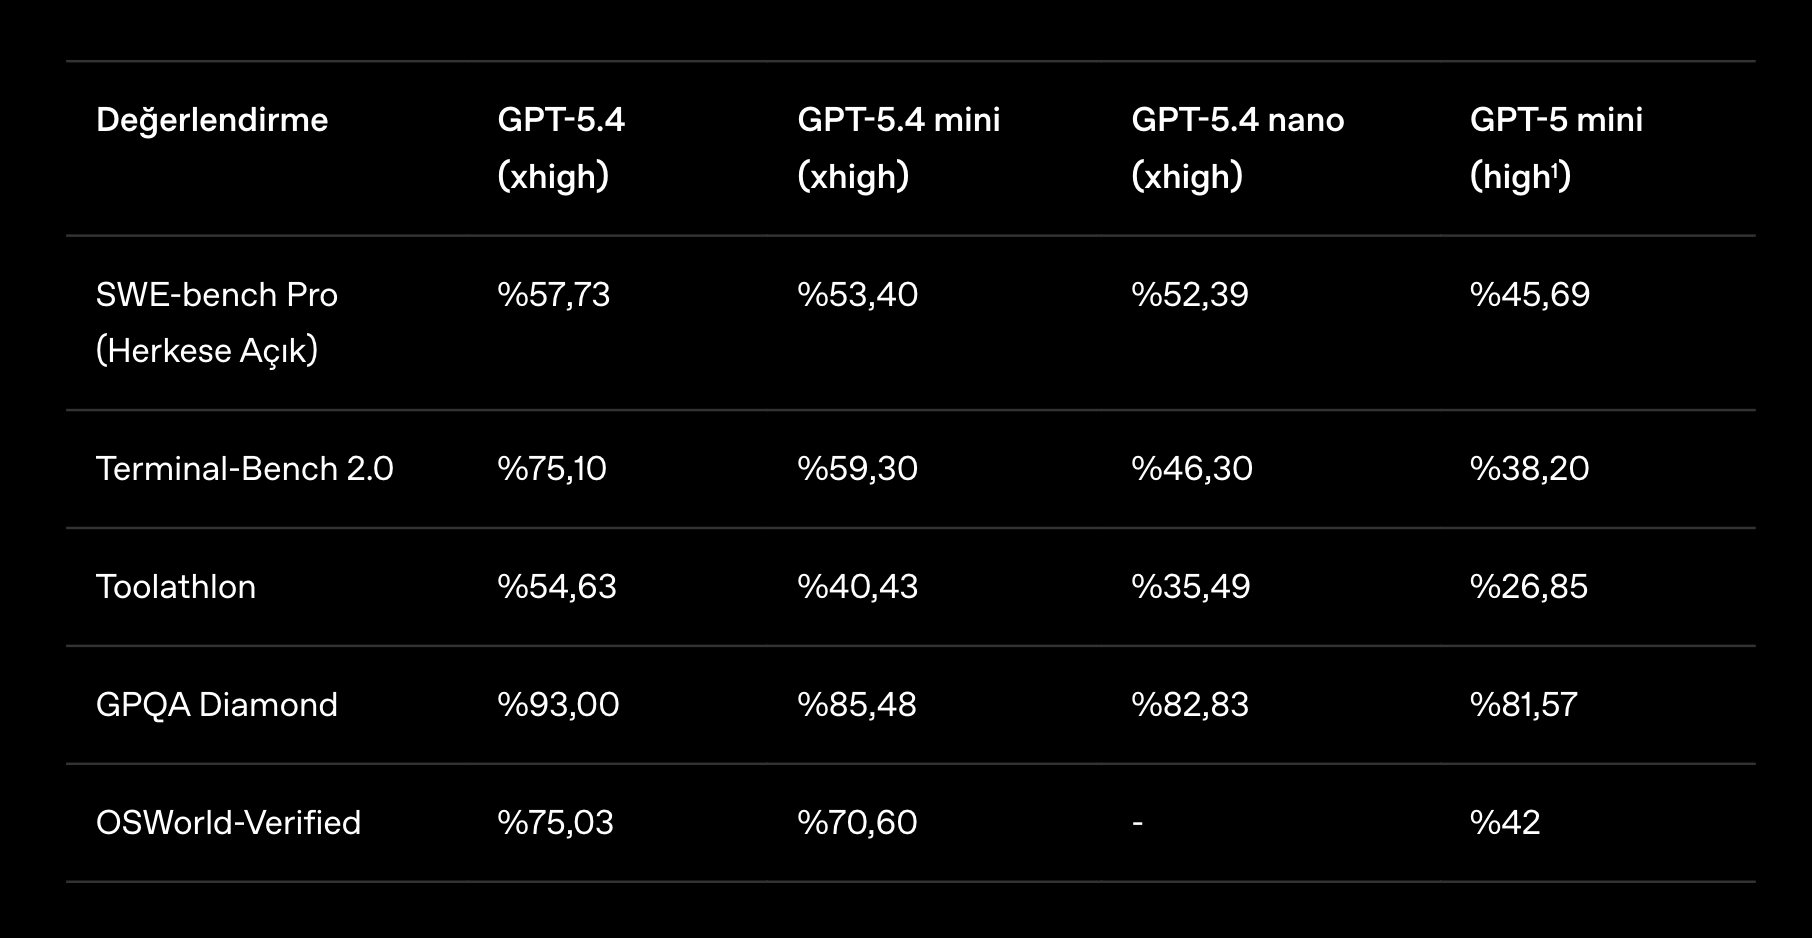
OpenAI, GPT-5.4 mini ve nano modellerini duyurdu

OpenAI, kısa süre önce tanıttığı GPT-5.4 modelinin ardından, bu modelin daha küçük ve optimize edilmiş versiyonları olan GPT-5.4 mini ve GPT-5.4 nano’yu duyurdu. Yeni modeller, büyük dil modellerinin …

Social Media Automation That Actually Works (Not Just Scheduling)

Social Media Automation That Actually Works (Not Just Scheduling)

Let’s face it: most social media automation tools are glorified schedulers. They let you queue up a week’s worth of posts and then…crickets. You’re still shouting into the void, hoping someone notices. That’s not automation; that’s just efficient procrastination.

I wanted something more. I wanted a system that could actually grow my Twitter audience, not just maintain a presence. I’m talking about a system that understands trends, generates engaging content, and actively participates in relevant conversations. And I built it. Over the past three months, I’ve seen a significant increase in followers, engagement, and even website traffic, all thanks to a social media automation setup that goes beyond simple scheduling.

In this article, I’ll break down how I built this system using n8n (a fantastic open-source workflow automation platform), Google’s Gemini AI (for content generation and analysis), and the Twitter API. I’ll share my actual workflows, code snippets, and the growth metrics I’ve achieved.

The Problem with Traditional Social Media Automation

Traditional social media automation tools often fall short because they lack:

  • Contextual Awareness: They post the same content regardless of current trends or audience sentiment.
  • Content Variety: They rely on pre-written content, leading to repetitive and predictable feeds.
  • Engagement Capabilities: They rarely offer automated engagement features, such as responding to comments or participating in relevant conversations.
  • Adaptability: They don’t learn from their performance and adapt their strategy accordingly.

Essentially, they treat social media as a one-way broadcast channel instead of a dynamic, interactive platform.

My Solution: AI-Powered, Trend-Aware Automation

My approach focuses on creating a system that:

  1. Identifies Trending Topics: Uses the Twitter API to monitor trending hashtags and keywords relevant to my niche (in my case, software development and productivity).
  2. Generates Engaging Content: Leverages Gemini AI to create tweets, threads, and even short video scripts based on these trending topics. The AI also helps tailor the content to my specific audience and brand voice.
  3. Automates Engagement: Responds to relevant tweets, retweets interesting content, and participates in conversations using AI-generated responses.
  4. Tracks Performance and Adapts: Monitors key metrics like impressions, engagement rate, and follower growth, and uses this data to refine the content strategy and engagement tactics.

The Stack: n8n + Gemini + Twitter API

Here’s a breakdown of the tools I used:

  • n8n: The heart of the system. n8n is a low-code/no-code workflow automation platform that allows you to connect different APIs and services. It’s like Zapier or Make, but self-hosted and much more powerful for complex workflows.
  • Google Gemini AI: Provides the AI muscle for content generation, topic analysis, and sentiment analysis. I use the Gemini API to interact with the model.
  • Twitter API: Allows me to access Twitter data (trending topics, tweets, user information) and automate actions like posting, retweeting, and responding to tweets.

Building the Workflow in n8n

Let’s walk through a simplified version of my workflow in n8n:

  1. Get Trending Topics: This node uses the Twitter API to fetch the top trending topics in my chosen location (or globally).

    {
      "name": "Get Trending Topics",
      "type": "twitterApi",
      "config": {
        "operation": "trends",
        "location": "23424977" // US location code
      }
    }
    
  2. Filter Trending Topics: This node filters the trending topics to only include those relevant to my niche. I use keywords and regular expressions to identify relevant topics.

    // Example JavaScript node to filter trends
    const relevantTrends = items.filter(item => {
      const trendName = item.name.toLowerCase();
      return trendName.includes('javascript') || trendName.includes('react') || trendName.includes('programming');
    });
    
    return relevantTrends;
    
  3. Generate Content with Gemini AI: This node uses the Gemini API to generate a tweet based on the selected trending topic. I provide a prompt that includes the topic, my brand voice, and the desired length of the tweet.

    {
      "name": "Generate Tweet with Gemini",
      "type": "googleGemini",
      "config": {
        "model": "gemini-pro",
        "prompt": "Write a short, engaging tweet about {{ $json.name }} for software developers. Include relevant hashtags.",
        "temperature": 0.7
      }
    }
    
  4. Post Tweet: This node uses the Twitter API to post the generated tweet.

    {
      "name": "Post Tweet",
      "type": "twitterApi",
      "config": {
        "operation": "tweet",
        "text": "{{ $json.generated_tweet }}"
      }
    }
    

This is a simplified example, of course. My actual workflow is much more complex and includes features like:

  • Sentiment analysis: To avoid posting about sensitive topics during times of crisis.
  • Thread generation: To create longer, more in-depth content.
  • Automated engagement: To respond to relevant tweets and participate in conversations.
  • A/B testing: To experiment with different content styles and engagement tactics.

Real Growth Metrics (3 Months)

Here’s a snapshot of the results I’ve seen over the past three months:

  • Follower growth: Increased by 45%
  • Impressions: Increased by 70%
  • Engagement rate: Increased by 30%
  • Website traffic from Twitter: Increased by 25%

These results are a testament to the power of AI-powered, trend-aware social media automation. It’s not just about scheduling; it’s about creating a system that actively works to grow your audience and engagement.

Challenges and Considerations

While this approach has been successful for me, it’s important to acknowledge the challenges:

  • AI Accuracy: AI-generated content isn’t always perfect. You need to carefully review and edit the content before posting.
  • Ethical Considerations: It’s important to be transparent about using AI-generated content and avoid misleading your audience.
  • API Rate Limits: The Twitter API has rate limits, so you need to design your workflows carefully to avoid exceeding them.
  • Technical Expertise: Building this system requires some technical knowledge, especially in areas like n8n, APIs, and programming.

Conclusion: Beyond Scheduling, Towards Sustainable Growth

Social media automation is more than just scheduling. It’s about leveraging technology to create a system that actively works to grow your audience, engagement, and ultimately, your business. By combining the power of n8n, Gemini AI, and the Twitter API, I’ve built a system that has delivered real, measurable results. It requires effort to set up, some technical knowledge, and ongoing refinement, but the payoff is worth it.

Ready to take your social media automation to the next level? I’ve put together a package that includes my complete n8n workflows, detailed documentation, and personalized support to help you build your own AI-powered social media automation system. Check it out here: https://bilgestore.com/product/social-media-automation

Server-Side Rendering Strategies for Video Platforms

In the era of React and Next.js, I chose full server-side rendering with PHP for TopVideoHub. Here’s why, and how I implemented it for optimal performance.

Why SSR with PHP (Not a JS Framework)

For a content-heavy video platform, SSR with PHP has clear advantages:

  1. SEO — Search engines see fully rendered HTML immediately. No hydration delay, no JS-dependent content.
  2. Performance — Zero JavaScript framework overhead. The page is ready on first paint.
  3. Hosting cost — PHP shared hosting costs $3-10/month. Node.js hosting starts at $5-20/month for comparable performance.
  4. Simplicity — No build step, no bundler configuration, no client/server code splitting.

Template Architecture

I use plain PHP templates with a simple layout system:

// app/View.php
class View {
    private string $layout = 'main';
    private array $data = [];
    private array $sections = [];

    public function render(string $template, array $data = []): string {
        $this->data = $data;
        extract($data);

        ob_start();
        require __DIR__ . "/../templates/{$template}.php";
        $content = ob_get_clean();

        $this->sections['content'] = $content;

        ob_start();
        require __DIR__ . "/../templates/layouts/{$this->layout}.php";
        return ob_get_clean();
    }

    public function section(string $name): string {
        return $this->sections[$name] ?? '';
    }

    public function setLayout(string $layout): void {
        $this->layout = $layout;
    }
}
<!-- templates/layouts/main.php -->
<!DOCTYPE html>
<html lang="<?= $lang ?? 'en' ?>">
<head>
    <meta charset="UTF-8">
    <meta name="viewport" content="width=device-width, initial-scale=1.0">
    <title><?= htmlspecialchars($title ?? 'TopVideoHub') ?></title>
    <?= $this->section('head') ?>
    <link rel="stylesheet" href="/assets/style.css">
</head>
<body>
    <?php require __DIR__ . '/../partials/nav.php'; ?>
    <main>
        <?= $this->section('content') ?>
    </main>
    <?php require __DIR__ . '/../partials/footer.php'; ?>
    <?= $this->section('scripts') ?>
</body>
</html>

Video Grid Component

<!-- templates/partials/video-grid.php -->
<div class="video-grid" data-region="<?= $region ?>">
    <?php foreach ($videos as $video): ?>
    <article class="video-card" data-video-id="<?= $video['video_id'] ?>">
        <div class="video-facade">
            <img src="<?= thumbnailUrl($video['video_id'], 'mq') ?>"
                 alt="<?= htmlspecialchars($video['title']) ?>"
                 width="320" height="180"
                 loading="<?= $loop_index < 4 ? 'eager' : 'lazy' ?>"
                 decoding="async">
            <button class="play-btn" aria-label="Play <?= htmlspecialchars($video['title']) ?>">
                <svg viewBox="0 0 68 48"><!-- play icon SVG --></svg>
            </button>
            <span class="video-duration">
                <?= formatDuration($video['duration']) ?>
            </span>
        </div>
        <div class="video-info">
            <h3 class="video-title">
                <a href="/watch/<?= $video['video_id'] ?>">
                    <?= htmlspecialchars($video['title']) ?>
                </a>
            </h3>
            <p class="video-channel">
                <?= htmlspecialchars($video['channel_title']) ?>
            </p>
            <p class="video-meta">
                <span><?= formatViewCount($video['view_count']) ?> views</span>
                <span><?= timeAgo($video['published_at']) ?></span>
            </p>
        </div>
    </article>
    <?php endforeach; ?>
</div>

Progressive Enhancement

The page works without JavaScript. JS enhances the experience:

// Progressive enhancement: only runs if JS is available
(function() {
    // Lazy-load video embeds on click
    document.querySelectorAll('.video-facade').forEach(facade => {
        facade.addEventListener('click', function() {
            const id = this.closest('.video-card').dataset.videoId;
            const iframe = document.createElement('iframe');
            iframe.src = `https://www.youtube.com/embed/${id}?autoplay=1`;
            iframe.allow = 'autoplay; encrypted-media';
            iframe.allowFullscreen = true;
            this.innerHTML = '';
            this.appendChild(iframe);
        });
    });

    // Catbar responsive sizing
    const catbar = document.querySelector('.vw-catbar');
    if (catbar) {
        fitCatbar(catbar);
        window.addEventListener('resize', () => fitCatbar(catbar));
    }
})();

Cache-Aware Rendering

Since LiteSpeed caches full HTML responses, I ensure the rendered output is cache-friendly:

class CacheAwareRenderer {
    public function render(string $template, array $data, PageType $type): string {
        // Set cache headers before any output
        CachePolicy::apply($type, ...($data['cache_tags'] ?? []));

        // Render template
        $view = new View();
        $html = $view->render($template, $data);

        // Also write to PHP file cache as fallback
        $cacheKey = md5($_SERVER['REQUEST_URI']);
        $cachePath = __DIR__ . "/../data/pagecache/{$cacheKey}.html";
        file_put_contents($cachePath, $html, LOCK_EX);

        return $html;
    }
}

Results at TopVideoHub

This SSR approach on TopVideoHub delivers:

  • TTFB: ~12ms (cached), ~120ms (uncached)
  • FCP: ~0.8s
  • Total JS: 8KB (minified)
  • Lighthouse Performance: 85+ mobile, 95+ desktop

No build step, no hydration, no JavaScript framework. Just PHP rendering HTML and LiteSpeed caching it. For content platforms, this approach is hard to beat.

How We’re Solving Context Window Bloat in an AI Agent Skill Ecosystem

Your AI agent just got its 53rd skill installed. Image generation, video creation, social media posting, calendar management — the works.

There’s just one problem: every single request now carries 25KB of skill descriptions in the system prompt, whether the user needs them or not. That’s ~6,200 tokens of overhead before a single word of actual conversation.

This post walks through how we found this problem, the four approaches we tried (and why three of them failed), and the architecture we landed on.

The Problem: More Skills = Worse Performance

We run an AI agent platform where users install “skills” — essentially instruction modules that tell the agent how to use specific tools. Think of them like plugins, but implemented as structured markdown files that get injected into the system prompt.

The mechanism is simple:

Install skill → SKILL.md stored locally  
→ name + description injected into every request's system prefix  
→ Agent sees full skill list → matches → reads SKILL.md → executes

When we audited our system prefix, here’s what we found:

Component Size Share
Tool schemas 29.6 KB 31.2%
User workspace files 30.8 KB 32.5%
Skills list 24.9 KB 26.2%
Framework instructions 9.5 KB 10.0%
Total 92.5 KB —

The skills list was eating over a quarter of our context budget. And usage data showed 45% of installed skills had never been triggered — they were just dead weight on every request.

At 53 skills this was annoying but survivable. At 500? The system would collapse.

The Core Tension

The business needs breadth — the more skills available, the more capable the agent. But the runtime needs precision — each request should only carry what’s relevant.

We also had a hard constraint: LLM prefix caching. The cache matches tokens from the start of the sequence. If you change anything in the system prefix, everything after that point becomes a cache miss. Skills sit near the front of the prefix, before all conversation history. Touching them means rewriting the cache for the entire conversation — exactly the opposite of what we want.

Approach 1: Two-Layer Architecture (Pinned + Dynamic Discovery)

Idea: Split skills into a “pinned” tier (10-15 high-frequency ones, always injected) and an “ecosystem” tier (hundreds, discovered on demand). Add a new built-in tool for skill discovery.

Why it failed: This required modifying the agent framework’s source code — its configuration format, adding a new built-in tool, changing the prompt assembly pipeline.

The framework we use ships updates almost every other day. Maintaining a fork against that velocity is a maintenance nightmare. Even with zero feature work on our end, we’d be constantly rebasing against upstream changes.

Decision: No approach that requires forking or modifying the core framework.

Approach 2: Use a Skill to Manage Skills

Idea: Completely non-invasive. Move low-frequency skills out of the scan directory (so they’re not injected), and create a “skill-router” skill that searches through archived skills when needed.

High-frequency skills → standard directory (injected)
Low-frequency skills → archive directory (not injected)
skill-router → searches archive via grep when agent can't handle a request

This was elegant — zero code changes, just filesystem operations plus one regular skill.

Why it failed: We tracked trigger reliability across our production data and found:

  • Skill trigger rate based on description matching alone: < 30%
  • With cross-references from other skills: 70-80%
  • Even our best-documented knowledge-base skill (strong description + referenced by multiple other skills) was missed ~25% of the time

The root cause: agents are probabilistic. Building a critical path on “the agent realizes it needs to search for help” has a reliability ceiling that’s too low for production.

Decision: Critical routing can’t depend on the agent’s probabilistic judgment.

Approach 3: Dynamic Injection via Plugin Hook

Idea: Use the framework’s plugin system (specifically a context assembly hook) to dynamically choose which skills to inject based on the user’s message. Instead of a static skill list, compute the relevant subset each time.

This felt right — deterministic code picks the skills, not the agent’s judgment.

Why it failed: Remember the cache constraint? The skills list sits in the system prefix, before all conversation history. Dynamically changing it means the prefix is different on every request, which cascades into a full cache miss for all historical messages.

We ran the numbers: saving 24.9 KB of skill space but causing 50-100 KB of cache rewrites on every turn. Net negative.

Decision: The system prefix must remain 100% stable. No dynamic modifications to anything before the conversation history.

Approach 4: Append to End (The Solution) ✅

The breakthrough was reframing the problem. Instead of replacing part of the prefix, we append to the end of the message sequence — after all conversation history.

[Fixed prefix: tools + pinned skills + user files + instructions]  → NEVER CHANGES (cache hit)
[Conversation history]                                              → cache hit  
[Additional Skills: dynamically matched this turn]                  → small new addition

Here’s why this works:

  1. Prefix stays 100% stable — full cache hit on every turn
  2. Dynamic content is append-only — minimal cache write cost
  3. Deterministic matching — code picks the skills, not the agent
  4. Scales indefinitely — ecosystem can have thousands of skills, but each request only carries 2-3 relevant ones

The Matching Layer

We use embedding similarity to match the user’s message against pre-computed skill description vectors:

// In the assembly hook
const response = await openai.embeddings.create({
  model: "text-embedding-3-small",
  input: userMessage.text,
});

const queryVector = response.data[0].embedding;
const matchedSkills = cosineSimilaritySearch(queryVector, skillIndex, topK);

The skill index is pre-computed at install time:

[
  {
    "name": "xhs-note-creator",
    "description": "Create Xiaohongshu note content...",
    "location": "~/.agent/skills-archive/xhs-note-creator/SKILL.md",
    "embedding": [0.012, -0.034, 0.056, ...]
  }
]
  • Index size: 500 skills × 1536-dim float32 ≈ 3 MB (totally manageable)
  • Matching latency: ~100-200ms per request
  • Cost: ~$0.02 per million tokens (negligible)

Why Append Works for the Agent

If you’ve done RAG, this pattern is familiar. The agent sees:

“Here are some additional skills that may be relevant to this request: [skill descriptions]”

It then reads the corresponding SKILL.md files and executes normally. From the agent’s perspective, it’s just extra context — no behavioral changes needed.

What We Got Wrong Along the Way

A few pitfalls worth noting:

  1. We overestimated agent self-awareness. We assumed the agent would reliably recognize “I don’t know how to do this, let me search for a skill.” In practice, it either hallucinated an answer or just apologized — searching was the last resort, not the first.

  2. We underestimated cache sensitivity. Our initial mental model was “save tokens in the prefix → save money.” But prefix caching means the stability of the prefix matters more than its size. A 90 KB stable prefix is cheaper than a 70 KB prefix that changes every turn.

  3. We almost built a fork. The two-layer architecture was technically clean, but maintaining a fork of a fast-moving open source project is a long-term tax that compounds. Using the official plugin system — even if it’s less flexible — was the right call.

Rollout Plan

We’re being deliberate about timing:

  • Now (< 60 skills): No changes needed. The overhead is acceptable and we’re collecting usage data.
  • 100+ skills: Deploy the routing extension. Move low-frequency skills to archive. Validate matching accuracy.
  • 500+ skills: Automate index management. Add user-profile-based pinning. Connect to the skill registry for remote discovery.

Key Takeaways

  1. Injection cost is the hidden tax of plugin ecosystems. Every plugin/skill/tool added to an AI agent’s context has a per-request cost, even when unused.

  2. Cache-friendliness is a first-class architectural constraint. For LLM-based systems, prefix stability matters more than prefix size.

  3. Don’t build critical paths on probabilistic behavior. If your system relies on the agent “deciding” to do the right thing, measure the actual trigger rate before shipping.

  4. Append > Replace for dynamic context. When you need to add context without breaking caches, treat it like RAG — add to the end, not the middle.

  5. Resist the fork. Plugin/extension systems exist for a reason. The flexibility tax of a fork almost always exceeds the flexibility gain.

This architecture now powers part of how we think about skill scaling at www.imaclaw.ai, where we build AI creative agents with 50+ multimodal skills. The pattern should generalize to any LLM agent system dealing with growing plugin ecosystems.

Claude Codeでヘルスエンドポイントを設計する:依存サービス確認・Liveness/Readiness・Kubernetes対応

はじめに

「ヘルスチェックが200 OKを返しているのにDBに繋がらない」「Kubernetesがポッドを再起動しすぎる」——適切なLiveness・Readiness・Startupプローブとヘルスエンドポイントを設計し、真に「ヘルシー」な状態だけを報告する設計をClaude Codeに生成させる。

CLAUDE.mdにヘルスエンドポイント設計ルールを書く

## ヘルスエンドポイント設計ルール

### エンドポイント分離
- /health/live: Liveness(プロセスが生きているか)→ DBチェック不要
- /health/ready: Readiness(リクエストを処理できるか)→ 全依存サービスをチェック
- /health: 管理者向け詳細ステータス(認証必須)

### 依存サービスのチェック
- PostgreSQL: SELECT 1でクエリ確認
- Redis: PINGで確認
- 外部API: 軽量なAPIを叩く(ヘルスエンドポイントがあれば使う)
- タイムアウト: 各チェック最大2秒

### キャッシュ
- Readinessチェックの結果を5秒キャッシュ(連続チェックでDBを叩かない)
- Livenessはキャッシュしない(常に最新状態を報告)

ヘルスエンドポイント実装の生成

ヘルスエンドポイントを設計してください。

要件:
- Liveness/Readiness/Startupの分離
- 依存サービスの並列チェック
- タイムアウト制御
- Kubernetes対応

生成ファイル: src/health/

生成されるヘルスエンドポイント実装

// src/health/healthChecker.ts — ヘルスチェック

export type CheckStatus = 'ok' | 'degraded' | 'down';

export interface CheckResult {
  name: string;
  status: CheckStatus;
  durationMs: number;
  message?: string;
}

export interface HealthReport {
  status: CheckStatus;
  checks: CheckResult[];
  version: string;
  uptime: number;   // プロセス起動からの秒数
  timestamp: string;
}

export type HealthChecker = () => Promise<CheckResult>;

export class HealthCheckService {
  private readonly checks: Map<string, HealthChecker> = new Map();
  private readonly cache = new Map<string, { result: CheckResult; expiresAt: number }>();

  register(name: string, checker: HealthChecker, cacheTtlMs = 5_000): void {
    this.checks.set(name, async () => {
      // キャッシュチェック
      const cached = this.cache.get(name);
      if (cached && Date.now() < cached.expiresAt) return cached.result;

      const result = await checker();
      this.cache.set(name, { result, expiresAt: Date.now() + cacheTtlMs });
      return result;
    });
  }

  async runAll(): Promise<HealthReport> {
    const checkEntries = [...this.checks.entries()];

    const results = await Promise.allSettled(
      checkEntries.map(([, checker]) => checker())
    );

    const checks: CheckResult[] = results.map((r, i) => {
      if (r.status === 'fulfilled') return r.value;
      return {
        name: checkEntries[i][0],
        status: 'down' as const,
        durationMs: 0,
        message: (r.reason as Error).message,
      };
    });

    const overallStatus: CheckStatus =
      checks.some(c => c.status === 'down') ? 'down' :
      checks.some(c => c.status === 'degraded') ? 'degraded' : 'ok';

    return {
      status: overallStatus,
      checks,
      version: process.env.APP_VERSION ?? 'unknown',
      uptime: process.uptime(),
      timestamp: new Date().toISOString(),
    };
  }

  async runReadiness(): Promise<HealthReport> {
    return this.runAll();
  }

  // Livenessは軽量チェックのみ(メモリ使用量など)
  async runLiveness(): Promise<{ status: 'ok' | 'down'; memoryMb: number }> {
    const memMb = process.memoryUsage().heapUsed / 1024 / 1024;
    const memLimit = parseInt(process.env.MEMORY_LIMIT_MB ?? '512');

    return {
      status: memMb < memLimit * 0.9 ? 'ok' : 'down',
      memoryMb: Math.round(memMb),
    };
  }
}

// 各依存サービスのチェッカー
export function createPostgresChecker(db: PrismaClient): HealthChecker {
  return async () => {
    const start = Date.now();
    try {
      await Promise.race([
        db.$queryRaw`SELECT 1`,
        new Promise<never>((_, reject) => setTimeout(() => reject(new Error('Timeout')), 2000)),
      ]);
      return { name: 'postgresql', status: 'ok', durationMs: Date.now() - start };
    } catch (error) {
      return { name: 'postgresql', status: 'down', durationMs: Date.now() - start, message: (error as Error).message };
    }
  };
}

export function createRedisChecker(client: RedisClient): HealthChecker {
  return async () => {
    const start = Date.now();
    try {
      await Promise.race([
        client.ping(),
        new Promise<never>((_, reject) => setTimeout(() => reject(new Error('Timeout')), 2000)),
      ]);
      return { name: 'redis', status: 'ok', durationMs: Date.now() - start };
    } catch (error) {
      return { name: 'redis', status: 'down', durationMs: Date.now() - start, message: (error as Error).message };
    }
  };
}

export function createExternalApiChecker(name: string, url: string): HealthChecker {
  return async () => {
    const start = Date.now();
    try {
      const response = await fetch(url, { signal: AbortSignal.timeout(2000) });
      const status: CheckStatus = response.ok ? 'ok' : response.status < 500 ? 'degraded' : 'down';
      return { name, status, durationMs: Date.now() - start };
    } catch (error) {
      return { name, status: 'down', durationMs: Date.now() - start, message: (error as Error).message };
    }
  };
}
// src/health/healthRouter.ts — ヘルスルーター(Kubernetes対応)

const healthService = new HealthCheckService();

// 依存サービスを登録(5秒キャッシュ)
healthService.register('postgresql', createPostgresChecker(prisma), 5_000);
healthService.register('redis', createRedisChecker(redis), 5_000);
healthService.register('payment-api', createExternalApiChecker('payment-api', process.env.PAYMENT_API_HEALTH_URL!), 10_000);

// Kubernetes Liveness Probe: プロセスが生きているかだけ
// 失敗すると: Pod再起動
router.get('/health/live', async (req, res) => {
  const result = await healthService.runLiveness();

  if (result.status === 'ok') {
    res.status(200).json(result);
  } else {
    // メモリ使用量が90%超 → 再起動させる
    res.status(503).json(result);
  }
});

// Kubernetes Readiness Probe: リクエストを受け付けられるか
// 失敗すると: Service から除外(トラフィックを送らない)
router.get('/health/ready', async (req, res) => {
  const report = await healthService.runReadiness();

  if (report.status === 'ok') {
    res.status(200).json(report);
  } else if (report.status === 'degraded') {
    // 一部の依存が不安定: 200を返してトラフィックは受け続ける
    // (全部落とすと困る場合)
    res.status(200).json(report);
  } else {
    // 必須依存が落ちている: 503でService から除外
    res.status(503).json(report);
  }
});

// 管理者向け詳細ヘルス(認証必須)
router.get('/health', requireAdmin, async (req, res) => {
  const report = await healthService.runAll();
  const statusCode = report.status === 'ok' ? 200 : report.status === 'degraded' ? 200 : 503;
  res.status(statusCode).json(report);
});

// Kubernetes設定例
/*
livenessProbe:
  httpGet:
    path: /health/live
    port: 3000
  initialDelaySeconds: 10
  periodSeconds: 10
  failureThreshold: 3

readinessProbe:
  httpGet:
    path: /health/ready
    port: 3000
  initialDelaySeconds: 5
  periodSeconds: 5
  failureThreshold: 3
*/

まとめ

Claude Codeでヘルスエンドポイントを設計する:

  1. CLAUDE.md にLiveness(プロセス生死のみ)/Readiness(全依存確認)を分離・各チェック2秒タイムアウト・結果を5秒キャッシュしてDBスパイク防止を明記
  2. Liveness/Readiness分離 でKubernetesの再起動判断を適切に制御——Readinessがf失敗してもPodを再起動せず(traffic-outのみ)、Livenessが失敗したら初めてPodを再起動
  3. 並列チェック でPostgreSQL+Redis+外部APIを同時確認——逐次だと6秒かかるチェックが2秒で完了。AllSettledで1つが遅くても他の結果を捨てない
  4. degraded状態 で部分的な問題を表現——Readiness=200(degraded)で「一部不安定だがトラフィックは受け付ける」と「全部落とす」の中間の対応が可能

信頼性設計のレビューは **Code Review Pack(¥980)* の /code-review で確認できます。*

prompt-works.jp

みょうが (@myougatheaxo) — ウーパールーパーのVTuber。