Tesla Çin tarafından resmi olarak yapılan paylaşıma göre Tesla Model Y’nin toplam satış rakamı 4 milyonu aşmış durumda. Bildiğiniz üzere uzun süredir Türkiye’de de resmi olarak satışı gerçekleştirilen araç, şirketin açık ara farkla en çok satan otomobili konumunda yer alıyor. Çok sayıda farklı versiyonu bulunan Model Y, tamamen elektrikli otomobil denildiğinde akla gelen ilk araçlardan biri ve sevmeyeni çok olmasına rağmen yüksek satış rakamlarına ulaşmaya devam ediyor.
Çinli BAIC, yeni SUV modelinin tanıtımında yapay zeka kurbanı oldu. Mercedes-Benz G-Serisi’ne benzerliği ile dikkat çeken aracın basın görsellerinde bariz tutarsızlıklar ve hatalar tespit edildi.
Türkiye’de de satılan iX3 sonrasında “Neue Klasse” döneminin ikinci üyesi olan tamamen elektrikli yeni BMW i3, bugün sonunda resmi olarak görücüye çıkarıldı. Hem yaşam alanı hem de dış tasarımı oldukça iddialı görünen araç, özellikle teknik detaylarıyla öne çıkıyor. 800 volt mimarisinin temel alındığı yeni i3 için ilk aşamada yalnızca “50 xDrive” modeli sunulacak. Çift motora sahip olan bu versiyon, 463 beygir güç ve 645 Nm tork üretiyor. 400 kW’a kadar hızlı şarj desteği bulunan araç, ideal şartlarda EPA ölçümlerine göre 700 km, WLTP ölçümlerine göreyse 900 km civarında menzil sunabiliyor. 10 dakikada 400 km menzil kazanabilen yeni i3 için daha sonra tek motorlu versiyonun ve aynı zamanda daha güçlü “M” versiyonunun da geleceği açıklanıyor. Ayrıca aracın “wagon” versiyonu da pazara sunulacak. Türkiye’ye 2027’nin başında gelmesi beklenen aracın kalbinde, “The Heart of Joy” olarak isimlendirilen çok güçlü bir kontrol ünitesi (beyin) yer alıyor. Ağustos ayında üretime alınacağı açıklanan yeni i3, şirketin […]
Reeder, Çinli Wuling Bingo’yu Samsun’da “Reev Aura” adıyla üretmeye başladı. 333 km menzil sunan model ön siparişe açıldı. İşte Reev Aura fiyatı, özellikleri ve detaylar.
Veltix v1.6.2: Lighter, Faster, and a Rust Experiment Coming
Hey Dev.to!
I’m Nytrox, a self-taught developer and the creator of Veltix, a pure Python TCP networking library with zero dependencies. Today I want to share what’s coming in v1.6.2 and where the project is heading.
What changed in v1.6.2
Reworked socket abstraction layer
The biggest architectural change in this version is a complete rework of BaseSocket and ThreadingSocket. The new BaseSocket is a clean, minimal Protocol that exposes only what matters: bind, connect, send, close, and callbacks. All the threading logic now lives inside ThreadingSocket instead of leaking into Server and Client. This makes the codebase much easier to maintain and paves the way for a selectors-based backend in v1.7.0.
Lighter protocol header
The message header went from 62 bytes down to 22 bytes. I replaced SHA256 with CRC32 and dropped UUID4 in favor of a 4-byte random ID. On high throughput workloads this makes a real difference.
MessageBuffer optimization
The internal message buffer was reworked to eliminate unnecessary memory allocations on every received message. Less garbage collection pressure, better throughput.
What’s next: experimenting with Rust
In the coming versions I’m planning to experiment with rewriting some performance-critical parts of Veltix in Rust via PyO3. This will be completely optional for users who don’t want the compiled extension. Pure Python will always remain the default.
A project built on top of Veltix
I’m also working on a real-world project powered by Veltix to prove it’s production-ready. More details soon.
Veltix is at 3,150+ downloads and growing. If you’re curious, check it out on GitHub or PyPI!
Hi dev.to community,
I’m currently learning DevOps and trying to balance theory with practical labs. I’ve noticed a few challenges:
-Sometimes I’m unsure about the correct learning order or what to focus on next.
-I start labs and practical exercises but often leave them unfinished.
-It’s hard to determine when I’ve truly “mastered” a topic.
I’d love to hear from you about your experiences:
-Where did you get stuck the most when learning DevOps?
-How did you maintain consistency and discipline in practical labs?
-How do you decide that a topic is fully understood or completed?
Any tips, strategies, or workflows you’ve found helpful would be greatly appreciated.
OPPO, Google Cloud ile iş birliği yaparak “Simbiyotik Hafıza” ve “Gizlilik Koruması” odaklı yeni nesil Yapay Zeka İşletim Sistemi’ni (AIOS) duyurdu. AIOS neler sunuyor?
En el artículo anterior, desplegamos nuestro esquema en AWS AppSync. Creamos una API de GraphQL completa con tipos, queries y mutations perfectamente definidos. Incluso exploramos la documentación que AppSync generó automáticamente, pero hay un problema.
Si intentas hacer una query en el playground de AppSync ahora mismo, no obtendrás datos. Tu API tiene un esquema bastante cool, aunque hay un detalle; es como un restaurante con un menú increíble pero sin cocina. El menú promete platillos deliciosos, pero nadie sabe cómo prepararlos.
Hoy vamos a construir esa cocina. Vamos a implementar resolvers – las funciones que realmente responden a tus queries y mutations con datos reales.
Al final de este artículo, tendrás:
✅ Un resolver funcionando para consultar usuarios por ID
✅ Un resolver funcionando para crear nuevos usuarios
✅ Entendimiento completo del patrón para implementar cualquier resolver
Y lo mejor: haremos todo en la consola de AWS. Sin configuración local, sin instalar nada, sin complicaciones.
Si eres más visual, este diagrama te puede ayudar a entender el panorama completo de lo que construiremos:
Antes de escribir código, entendamos qué son los resolvers y por qué los necesitamos.
¿Qué es un resolver?
Un resolver es una función que “resuelve” (responde) una query o mutation de GraphQL.
Piénsalo así:
Tu esquema es el menú del restaurante (qué platillos ofreces)
Los resolvers son las recetas (cómo preparar cada platillo)
La fuente de datos son los ingredientes (de dónde vienen los datos)
Cuando un cliente hace una query como usuario(id: "123"), GraphQL necesita saber:
¿Esta query existe en mi esquema? ✅ (validación)
¿Cómo obtengo los datos para responderla? ← Aquí entra el resolver
¿Por qué AWS Lambda?
Vamos a usar AWS Lambda para escribir nuestros resolvers por estas razones:
Serverless – No tienes que manejar servidores, actualizaciones, o escalamiento
Pay-per-use – Solo pagas por el tiempo que tu código se ejecuta. El free tier incluye $100 USD en créditos que puedes usar en Lambda y otros servicios. Ana Cunha escribió una guía completa sobre cómo funciona el nuevo Free Tier si quieres entender más sobre los créditos
Integración directa – Lambda se conecta perfectamente con AppSync
Perfecto para aprender – Te enfocas en la lógica de tu resolver, no en infraestructura
Queries vs Mutations
Hoy implementaremos dos tipos de resolvers:
Query resolver (usuario(id)) – Para leer datos. No cambia nada en tu sistema.
Mutation resolver (crearUsuario) – Para escribir datos. Cada ejecución crea algo nuevo.
💡 Tip importante: Usaremos datos mock (hardcodeados) en lugar de una base de datos real. Esto nos permite enfocarnos en entender cómo funcionan los resolvers sin la complejidad de configurar DynamoDB. El patrón que aprendas hoy funciona igual con una base de datos real – solo cambias de dónde vienen los datos.
Parte 2: Creando tu primer Lambda Function (Query Resolver)
Vamos a crear el resolver para la query usuario(id). Este resolver recibirá un ID y devolverá los datos de ese usuario.
En este video, creamos la función Lambda desde cero en la consola de AWS, escribimos el código del resolver y lo desplegamos:
Aquí está el código del resolver para que lo copies:
// Datos mock - en una aplicación real, estos vendrían de una base de datosconstusuarios=[{id:"1",nombre:"Ana García",email:"[email protected]",fotoPerfil:"https://example.com/ana.jpg",creadoEn:"2024-01-15T10:30:00Z"},{id:"2",nombre:"Carlos López",email:"[email protected]",fotoPerfil:"https://example.com/carlos.jpg",creadoEn:"2024-02-20T14:20:00Z"}];exportconsthandler=async (event)=>{// AppSync envía los argumentos de la query en event.argumentsconst{id}=event.arguments;// Buscamos el usuario por IDconstusuario=usuarios.find(u=>u.id===id);// Retornamos el usuario encontrado, o null si no existereturnusuario||null;};
Entendiendo el código
Los datos mock: Creamos un array con dos usuarios. En producción, esto vendría de DynamoDB, RDS, o cualquier base de datos.
export const handler: Esta es la función que Lambda ejecuta cuando se invoca. El async significa que puede hacer operaciones asíncronas (como llamar a una base de datos).
event.arguments: AppSync empaqueta los argumentos de tu query (en este caso, el id) en event.arguments. Así es como tu resolver sabe qué usuario está pidiendo el cliente.
return usuario || null: Si encontramos el usuario, lo retornamos. Si no, retornamos null. En GraphQL, retornar null para datos que no existen es normal y esperado.
💡 Tip importante: Cuando alguien hace la query usuario(id: "1"), AppSync automáticamente toma ese id: "1" y lo pone en event.arguments.id. No tienes que hacer nada especial – AppSync lo hace por ti.
Parte 3: Conectando Lambda a AppSync
Ahora que tenemos nuestra función Lambda lista, necesitamos conectarla a AppSync. Para esto necesitamos tres cosas:
Un rol de IAM – para darle permiso a AppSync de invocar Lambda
Un Data Source – para conectar AppSync con Lambda
Un Resolver – para decirle a AppSync “cuando alguien pida usuario, usa este data source”
Creando el rol de IAM
AWS usa roles para controlar qué servicios pueden hacer qué. Necesitamos crear un rol que le dé permiso a AppSync para invocar nuestras funciones Lambda.
En este video, creamos el rol de IAM y le adjuntamos los permisos necesarios:
💡 ¿Por qué necesitamos un rol? Los servicios de AWS no pueden simplemente llamarse entre sí – necesitan permiso explícito. Este rol le da a AppSync permiso para invocar tus funciones Lambda. Lo bueno es que puedes reutilizar este mismo rol para todas tus funciones Lambda de GraphQL.
Creando el Data Source
Un data source es la forma en que AppSync se conecta a donde viven tus datos. En nuestro caso, es Lambda.
En este video, agregamos nuestra función Lambda como data source en AppSync:
💡 ¿Qué es un Data Source? Un data source puede ser Lambda, DynamoDB, un endpoint HTTP, o incluso otra API de GraphQL. AppSync usa el data source para saber a dónde ir a buscar los datos cuando recibe una query.
Adjuntando el Resolver a la Query
Ahora le decimos a AppSync que cuando alguien haga la query usuario(id), use nuestro data source de Lambda.
En este video, adjuntamos el resolver a la query usuario en el esquema. Usamos VTL (Velocity Template Language) como runtime y configuramos los mapping templates:
Aquí están los mapping templates para que los copies:
💡 ¿Qué son los mapping templates? Son plantillas que transforman datos entre AppSync y tu data source. El request template empaqueta los argumentos de la query (como el id) en un formato que Lambda entiende. El response template toma lo que Lambda retorna y lo formatea para GraphQL.
💡 ¿Unit resolver vs Pipeline resolver? Un unit resolver trabaja con una sola fuente de datos (nuestro caso). Un pipeline resolver puede combinar múltiples fuentes de datos en secuencia. Para este tutorial, unit resolver es perfecto.
Parte 4: Probando tu Primer Resolver
¡Es momento de ver tu resolver en acción! Vamos a hacer una query real y ver datos reales de vuelta.
En este video, ejecutamos la query y experimentamos con diferentes IDs y campos:
Fíjate en algo interesante: cuando pides un usuario que no existe (como id: "999"), recibes null en lugar de un error.
💡 ¿Por qué null y no un error? En GraphQL, retornar null para datos que no existen es normal y esperado. Los errores son para cuando algo sale MAL (como si Lambda fallara o no tuviera permisos), no para “dato no encontrado”. Esta es una distinción importante.
Parte 5: Segundo Resolver – Mutation (crearUsuario)
Ya sabes cómo crear un resolver para leer datos. Ahora vamos a crear uno para escribir datos. El proceso es el mismo patrón que ya aprendiste:
Crear función Lambda
Crear data source en AppSync
Adjuntar resolver con mapping templates
Probar
Aquí está el código del resolver para la mutation:
// En una aplicación real, esto guardaría en una base de datosexportconsthandler=async (event)=>{// Las mutations envían los datos en event.arguments.inputconst{nombre,email,fotoPerfil}=event.arguments.input;// Generamos un ID simple (en producción, usarías UUID o un ID de base de datos)constid=Date.now().toString();// Creamos el objeto del nuevo usuarioconstnuevoUsuario={id,nombre,email,fotoPerfil:fotoPerfil||null,creadoEn:newDate().toISOString()};// En una aplicación real, aquí guardarías en la base de datosconsole.log("Usuario creado:",nuevoUsuario);// Retornamos el usuario creadoreturnnuevoUsuario;};
Los mapping templates son los mismos que usamos para la query:
En este video, creamos la función Lambda, la conectamos a AppSync (reutilizando el rol de IAM) y probamos la mutation:
💡 ¿Por qué event.arguments.input? Las mutations usan Input Types para agrupar todos los datos que se envían. En lugar de event.arguments.nombre, event.arguments.email, etc., todo viene agrupado en event.arguments.input. Esto mantiene las mutations limpias y organizadas.
💡 ¿Por qué los datos no se guardan? Recuerda que estamos usando datos mock para aprender. Cada invocación de Lambda es independiente – no hay base de datos guardando los usuarios. En futuros artículos podríamos agregar DynamoDB para hacerlo persistente.
Parte 6: Reto Práctico
Ya conoces el patrón completo para crear resolvers. Ahora es tu turno de practicar.
Tu reto: Implementa los resolvers restantes usando el mismo patrón que aprendiste:
Resolvers de query:
publicacion(id: ID!): Publicacion – Crea datos mock con 2-3 publicaciones, busca por ID
publicaciones: [Publicacion!]! – Retorna todas las publicaciones (no necesita argumentos)
Resolver de mutation:
crearPublicacion(input: CrearPublicacionInput!): Publicacion – Extrae titulo, contenido, autorId del input, genera ID y creadoEn
Tips para completar el reto:
Sigue exactamente el mismo patrón: Lambda → Data Source → Resolver → Test
Empieza con publicaciones (es la más simple, no tiene argumentos)
Reutiliza el rol AppSyncLambdaRole para todos los data sources
Los mapping templates son los mismos para todos los resolvers
Prueba cada resolver en el playground antes de pasar al siguiente
💡 ¿Te atoras? Es normal. Revisa los pasos que seguimos para usuario y crearUsuario. El patrón es idéntico, solo cambian los nombres de los campos y la estructura de los datos.
Conclusión
Lo que lograste hoy:
✅ Creaste tu primera función Lambda para un resolver de GraphQL
✅ Conectaste Lambda a AppSync como data source
✅ Implementaste un resolver de query (usuario)
✅ Implementaste un resolver de mutation (crearUsuario)
✅ Probaste ambos en el playground de GraphQL
✅ Aprendiste un patrón que puedes repetir para cualquier resolver
La idea clave: Los resolvers son simplemente funciones que retornan datos en la forma que tu esquema define. Ya sea que uses datos mock, una base de datos, o una API externa, el patrón es el mismo.
¿Qué sigue? Tu API funciona, pero ¿qué pasa cuando los datos cambian? ¿Tu app debería preguntar por actualizaciones cada cierto tiempo (polling)? ¿O el servidor debería enviar actualizaciones automáticamente (subscriptions)? En el próximo artículo exploraremos ambos enfoques y te ayudaremos a elegir el correcto para tu caso de uso.
Stripe and Tempo launched the Machine Payments Protocol on March 18, 2026. We integrated it the same day — not because we had advance notice, but because MPP is designed to layer on top of x402 infrastructure without breaking anything.
Here’s what production looks like when both protocols are live: 500 agent probes, 5 purchases, $0.11 in revenue, 1% conversion rate.
That number tells you something about where the agent payment ecosystem actually is right now.
What We Built (The Setup)
ClawMerchants is an agent-native data and skills marketplace. Every endpoint is payment-gated — agents hit it, get a 402, and can pay to get the data or capability they need. We’ve been live on x402 (USDC on Base) since day one.
When MPP launched, our endpoint response already contained WWW-Authenticate: Payment — which is the header format MPP uses for its challenge/response flow. Adding MPP support meant adding protocols_supported: ['x402', 'mpp'] to our 402 responses and registering on mppscan.com.
An agent that understands x402 sends an X-PAYMENT header with a verified USDC transaction on Base. An agent with an MPP session pre-authorization goes through the challenge flow instead. Same endpoint, same data, two paths to payment.
We’re listed on mppscan.com for agent discovery. 45 routes in our OpenAPI spec. Every one of them dual-protocol.
The 500 Probe Reality
Here’s the production data:
500+ agent probes (lifetime)
5 purchases
1% conversion rate
$0.11 total revenue
5 unique paying clients
The most-probed assets by volume: defi-yields-live (136 probes), token-anomalies-live (77), security-intel-live (76). The DeFi/crypto agent cohort is by far the biggest discoverer of our catalog. They probe, read the 402, catalog the pricing — and mostly don’t come back to pay.
One client I’ve labeled unknown-client:node ran 100 probes in a short window. Zero purchases. Someone built a scanner that maps payment-gated endpoints without completing payment. The 402 response has become infrastructure for agent catalog discovery, independent of the payment use case.
This is what real x402 adoption looks like at production scale in early 2026.
Why 99% of Agents Don’t Pay
The failure isn’t in the protocol design. After watching 500 probes, here’s the actual breakdown:
No wallet. The most common case. An agent built to call APIs sees the 402, reads it correctly, understands the price and payment method — and has no wallet credentials to execute the payment. No private key, no custodial wallet, nothing. They built the agent to read data, not to pay for it.
Wrong chain, wrong token. Some agents have wallets. ETH on mainnet. Not USDC on Base. x402 requires the specific token on the specific chain — there’s no automatic cross-chain bridging. The wallet exists; the balance doesn’t.
Per-request overhead. At $0.05 per call, the fee is fine. The on-chain transaction isn’t. For high-frequency agents calling a data feed multiple times per minute, every call is a separate transaction. Latency, gas (even on Base it’s nonzero), and wallet signing overhead compound fast.
The decision loop. Agents built with cautious spending policies will probe first, then escalate to a human for approval before paying. That approval step never happens. The probe lands in our logs; the payment never follows.
What MPP Changes
MPP sessions address the per-request friction directly.
With x402, every request is a transaction. With MPP, an agent pre-authorizes a session — sets a spending limit, authorizes the scope of what it’s paying for — and subsequent calls within that session skip the per-transaction overhead. It’s closer to how you’d use a prepaid card than a crypto wallet.
The rails MPP supports include Tempo (the first live implementation), Stripe/Visa card rails, and Lightning via Lightspark. That last part matters: it means future agent payment wallets don’t require crypto at all. An agent with Stripe credentials can complete MPP payments. That’s a much lower setup bar than “fund a wallet with USDC on Base.”
For our marketplace, this means the agents currently stuck at step one (no USDC on Base) have an alternative path forward when their frameworks add MPP support.
The question I can’t answer yet: how long does that take? The protocol launched today. Framework support takes 30–90 days minimum to ship, stabilize, and reach agents in production. The infrastructure is ready; the agents aren’t configured for it yet.
We’re watching the probe-to-purchase ratio over the next 30 days to see if MPP discovery changes anything.
Skills vs. Data: The CVR Gap
One thing the data shows clearly: skills convert at 14–33% in our catalog. Data feeds convert at under 1%.
Data feeds require the agent to receive information and then do something with it. The agent needs the context to know why it wants this data, the tooling to act on it, and the wallet to pay for it. Three dependencies.
Skills — discrete agent capabilities, things agents can do — are a direct capability add. An agent with an agent-mpp-integration-skill can complete MPP payments. It either needs that capability or it doesn’t. The decision is binary; the value is immediate.
We just seeded agent-mpp-integration-skill into the marketplace: clawmerchants.com/assets/agent-mpp-integration-skill. It handles the MPP challenge/response flow, session pre-authorization, and spending limit configuration. $0.05 USDC on Base (yes, you need USDC on Base to buy the thing that tells you how to use MPP — we know).
The skills CVR data is what’s driving our engineering roadmap. Every new build is a skill, not a data feed.
What I’d Tell Agent Builders Right Now
If you’re building agents that consume paid APIs:
Fund a wallet before you need it. The most common failure mode is correct 402 handling with no credentials to execute payment. Set up a Coinbase Developer Platform agentic wallet or any custodial wallet with USDC on Base before your agent hits production. Takes 20 minutes; saves you debugging why your agent is cataloging endpoints it can’t pay for.
Probe endpoints before your agent needs them. The 402 response has everything: price, token, network, protocols supported. Build catalog-aware behavior into your agent so it knows what’s purchasable before it tries to buy.
If you’re building high-frequency — wait for MPP sessions. At $0.05/call the per-request fee is fine. At 50 calls/minute for a data feed, the on-chain overhead becomes the actual bottleneck. MPP session pre-auth is the right tool for that use case. Framework support should land in Q2 2026.
Skills > data feeds for initial purchases. If your agent is deciding whether to buy something it’s never seen, capabilities it can immediately use have higher conversion than data it has to interpret. Start with skills.
The Dual-Protocol Bet
Being live on both x402 and MPP on day one isn’t a technical achievement — the integration was straightforward. The bet is that the payment rails for agents will fragment, then consolidate, and the marketplaces that support both protocols from the start don’t have to choose.
Right now there are roughly 500 agents that have probed our catalog. 5 bought something. The gap between those numbers is agent wallet adoption — it’s not discovery, not pricing, not protocol design.
MPP might close that gap faster than x402 alone, because it removes the crypto prerequisite. We’re watching the data.
ClawMerchants is an agent-native data and skills marketplace supporting x402 + MPP dual-protocol payments. 46 live assets, 500+ probes, discoverable on mppscan.com. Browse the catalog at clawmerchants.com.

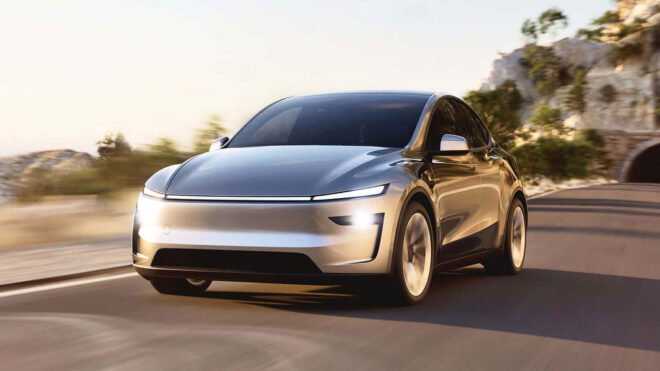
 Tesla Çin tarafından resmi olarak yapılan paylaşıma göre Tesla Model Y’nin toplam satış rakamı 4 milyonu aşmış durumda. Bildiğiniz üzere uzun süredir Türkiye’de de resmi olarak satışı gerçekleştirilen araç, şirketin açık ara farkla en çok satan otomobili konumunda yer alıyor. Çok sayıda farklı versiyonu bulunan Model Y, tamamen elektrikli otomobil denildiğinde akla gelen ilk araçlardan biri ve sevmeyeni çok olmasına rağmen yüksek satış rakamlarına ulaşmaya devam ediyor.
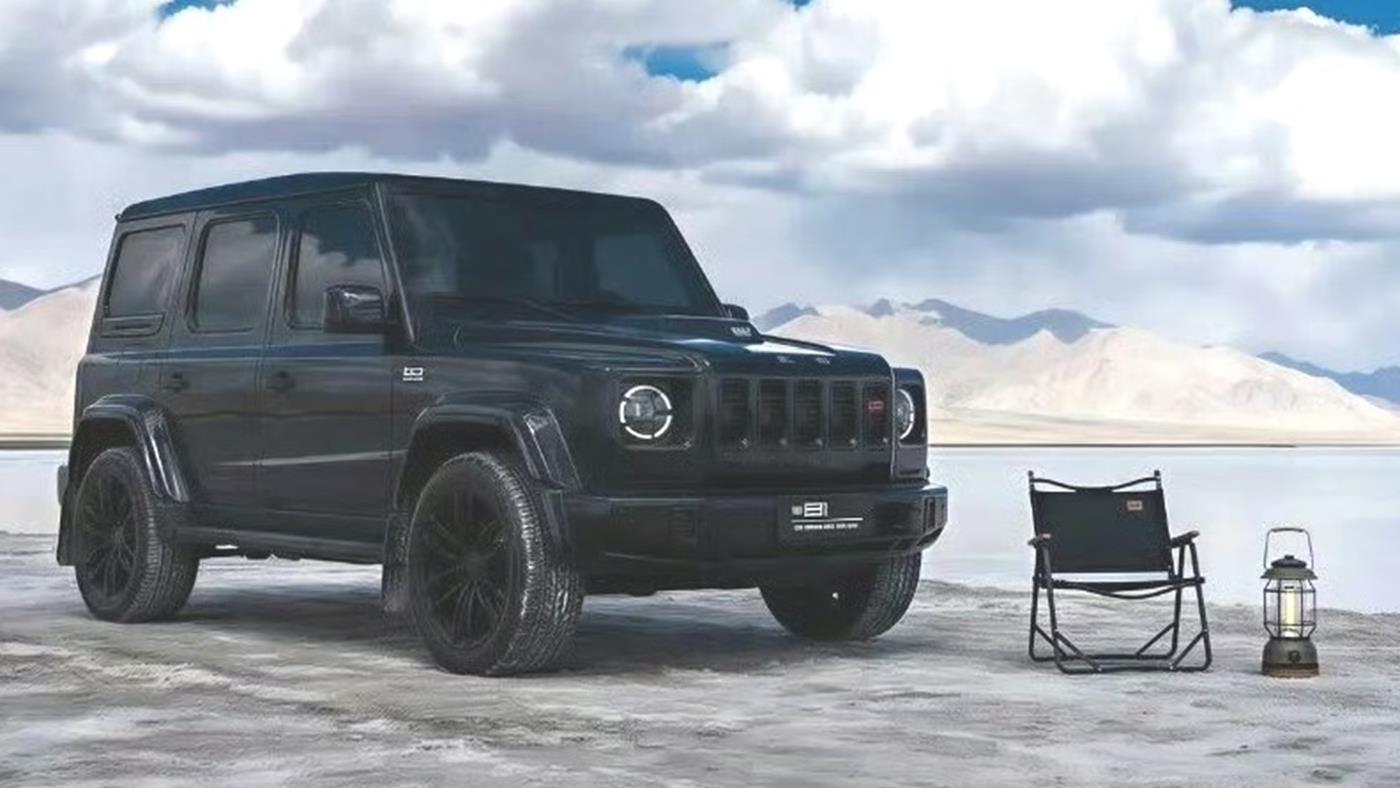
 Çinli BAIC, yeni SUV modelinin tanıtımında yapay zeka kurbanı oldu. Mercedes-Benz G-Serisi’ne benzerliği ile dikkat çeken aracın basın görsellerinde bariz tutarsızlıklar ve hatalar tespit edildi.
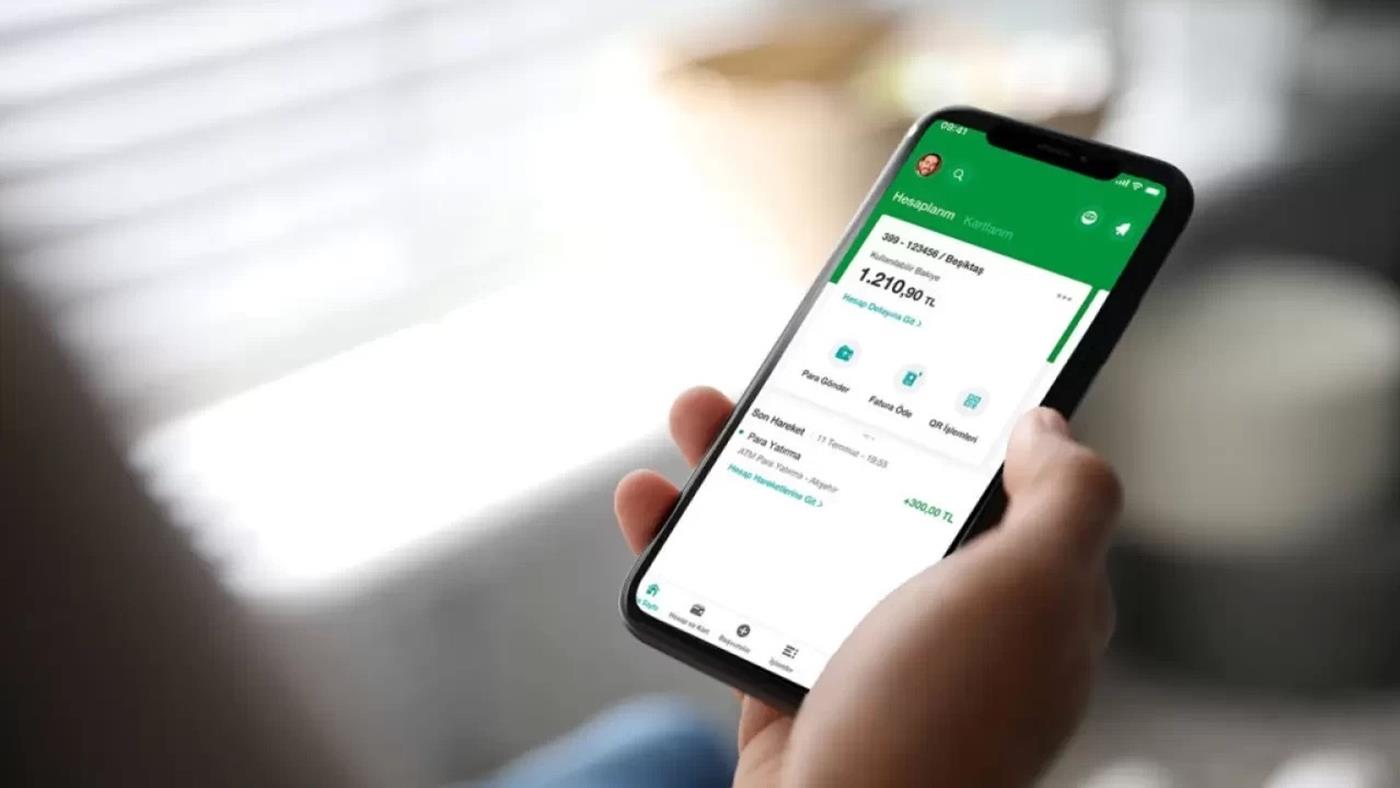
 Garanti BBVA Mobil uygulamasına eklenen “Ailem” özelliğiyle ebeveynlere çocuklarının finansal süreçlerini tek ekrandan yönetme imkanı sunuluyor.
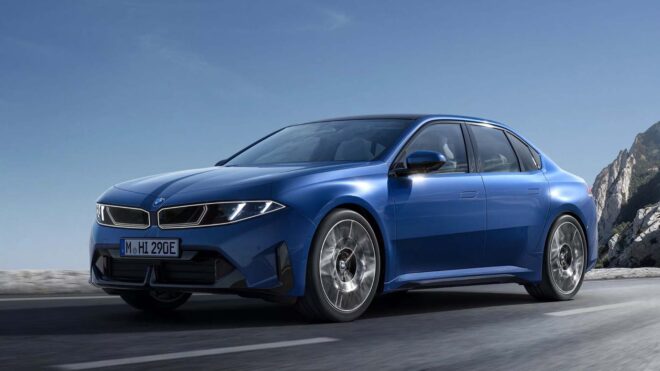
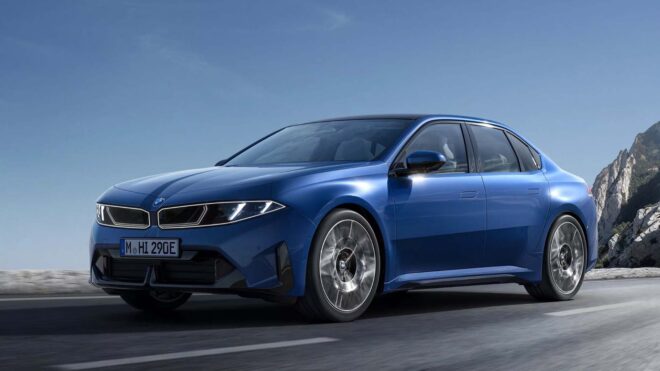 Türkiye’de de satılan iX3 sonrasında “Neue Klasse” döneminin ikinci üyesi olan tamamen elektrikli yeni BMW i3, bugün sonunda resmi olarak görücüye çıkarıldı. Hem yaşam alanı hem de dış tasarımı oldukça iddialı görünen araç, özellikle teknik detaylarıyla öne çıkıyor. 800 volt mimarisinin temel alındığı yeni i3 için ilk aşamada yalnızca “50 xDrive” modeli sunulacak. Çift motora sahip olan bu versiyon, 463 beygir güç ve 645 Nm tork üretiyor. 400 kW’a kadar hızlı şarj desteği bulunan araç, ideal şartlarda EPA ölçümlerine göre 700 km, WLTP ölçümlerine göreyse 900 km civarında menzil sunabiliyor. 10 dakikada 400 km menzil kazanabilen yeni i3 için daha sonra tek motorlu versiyonun ve aynı zamanda daha güçlü “M” versiyonunun da geleceği açıklanıyor. Ayrıca aracın “wagon” versiyonu da pazara sunulacak. Türkiye’ye 2027’nin başında gelmesi beklenen aracın kalbinde, “The Heart of Joy” olarak isimlendirilen çok güçlü bir kontrol ünitesi (beyin) yer alıyor. Ağustos ayında üretime alınacağı açıklanan yeni i3, şirketin […]
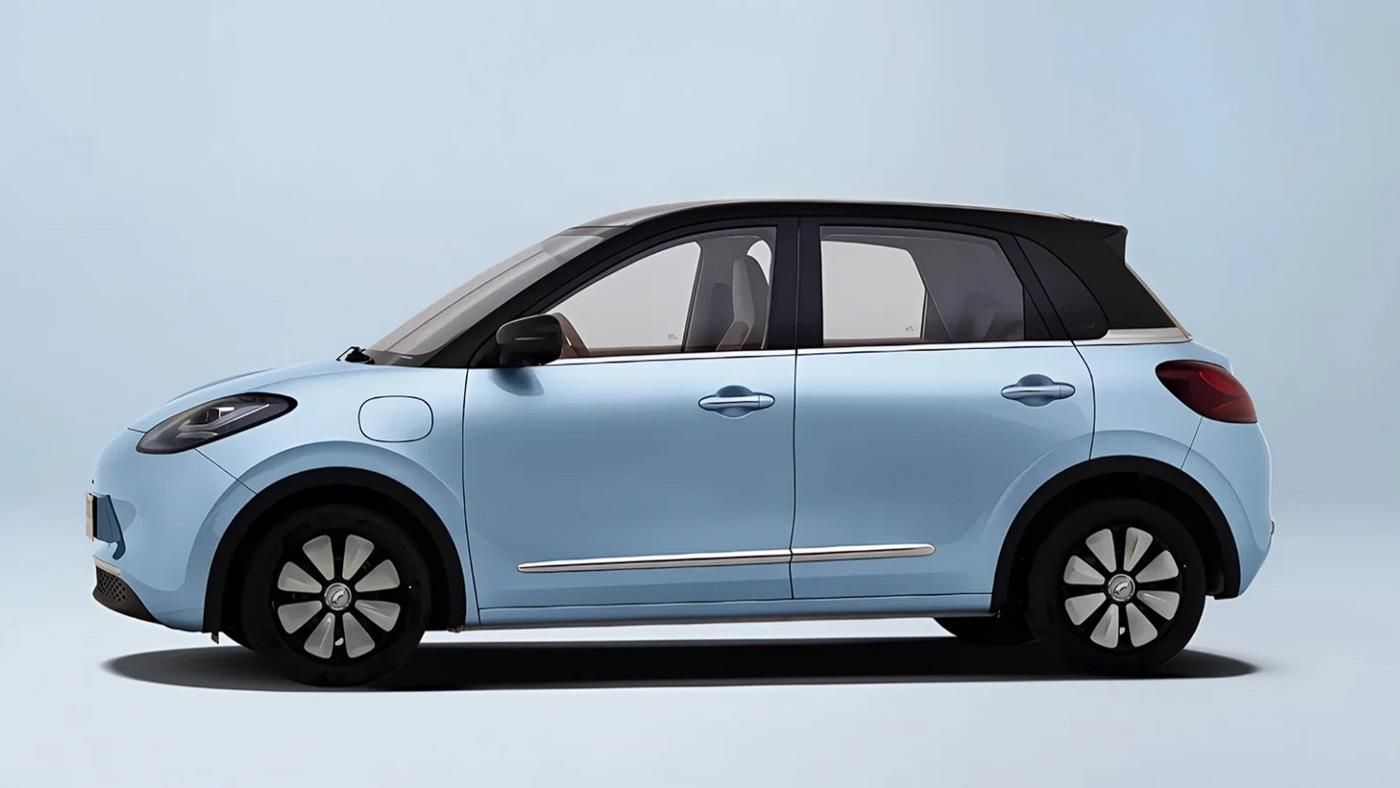
 Reeder, Çinli Wuling Bingo’yu Samsun’da “Reev Aura” adıyla üretmeye başladı. 333 km menzil sunan model ön siparişe açıldı. İşte Reev Aura fiyatı, özellikleri ve detaylar.
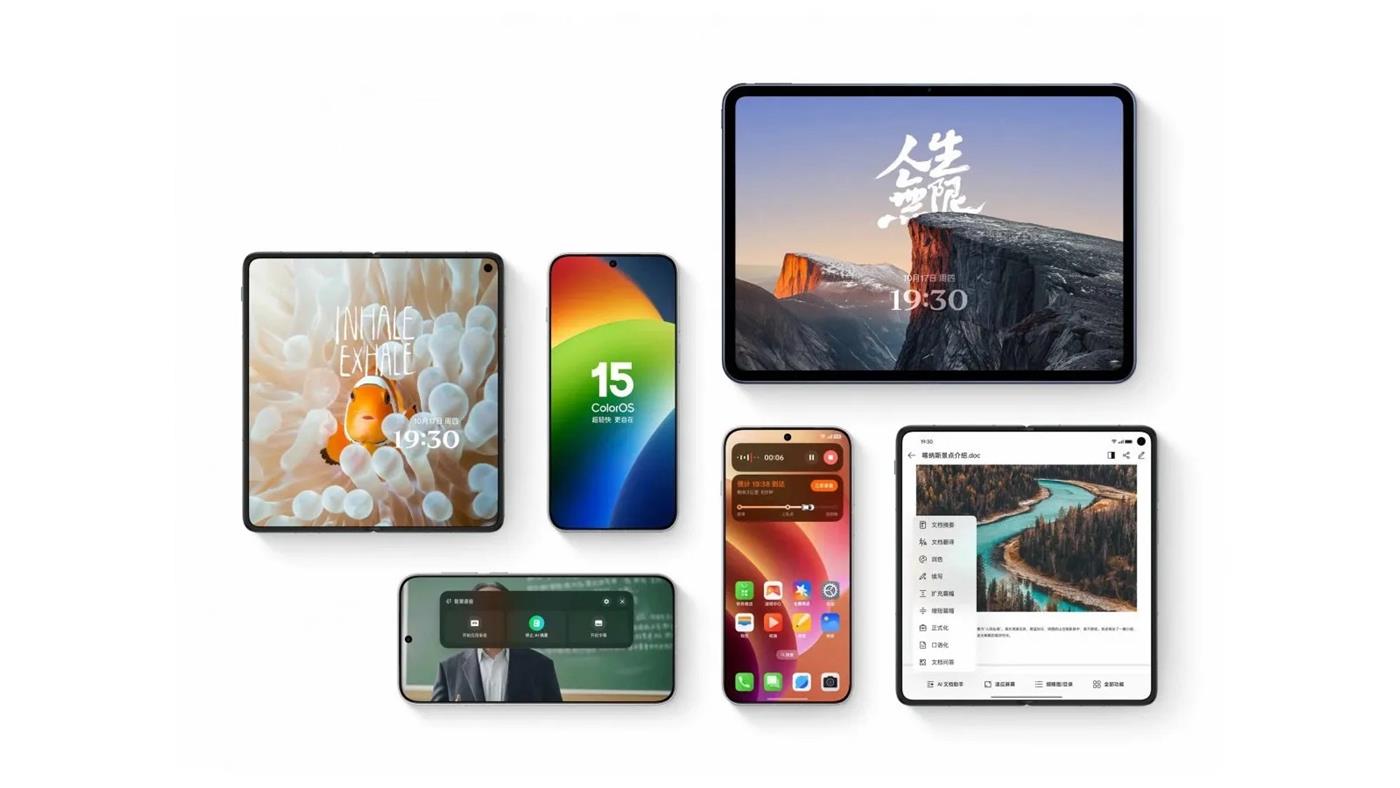
 OPPO, Google Cloud ile iş birliği yaparak “Simbiyotik Hafıza” ve “Gizlilik Koruması” odaklı yeni nesil Yapay Zeka İşletim Sistemi’ni (AIOS) duyurdu. AIOS neler sunuyor?


