Remote work is no longer optional for call centers. Whether you are scaling into new geographies, hiring from a broader talent pool, or maintaining business continuity, your VICIdial deployment needs to handle agents who are not sitting on the same LAN as your Asterisk server. The challenge is that VoIP was designed for local networks, and the moment you introduce NAT, consumer firewalls, and variable internet connections, things break in ways that are difficult to diagnose.
This guide walks through every layer of remote agent configuration in VICIdial: choosing between SIP and WebRTC, solving NAT traversal, tuning Asterisk, locking down security, and optimizing audio quality for agents working from home.
SIP vs. WebRTC for Remote Agents
Before touching any configuration, you need to decide how remote agents will connect their audio. There are two paths, and each has real trade-offs.
Traditional SIP Softphones
With SIP, agents install a softphone application (Zoiper, MicroSIP, Linphone, or similar) on their workstation. The softphone registers to your Asterisk server over SIP (UDP 5060 or TCP 5060) and sends/receives RTP audio on a range of UDP ports.
Advantages:
- Mature technology with decades of optimization
- Lower CPU overhead on the server
- Codec flexibility (G.711, G.729, Opus)
- Works with hardware SIP phones if needed
- Better call quality ceiling when properly configured
Disadvantages:
- Requires NAT traversal configuration on both ends
- Agents must install and configure software
- Firewall rules are more complex (SIP signaling + RTP range)
- ALG (Application Layer Gateway) on consumer routers frequently mangles SIP packets
- Harder to troubleshoot remotely when an agent’s home network is the problem
WebRTC (Built-in Browser Phone)
VICIdial has included WebRTC support since version 2.14. Agents connect audio through their web browser using the same interface they already use for the agent screen. No softphone installation required.
Advantages:
- Zero software installation for agents
- Automatically traverses NAT (WebRTC was designed for it)
- Uses DTLS-SRTP encryption by default
- Single port (443/TCP for HTTPS, plus TURN relay if needed)
- Dramatically simpler agent onboarding
Disadvantages:
- Higher server CPU usage (transcoding between WebRTC codecs and carrier codecs)
- Opus codec may need transcoding to G.711 for PSTN handoff
- Browser updates can occasionally break WebRTC behavior
- Slightly higher latency compared to well-configured SIP
- Requires valid TLS certificates on the VICIdial web server
Our Recommendation
For centers with 25+ remote agents, we generally recommend WebRTC as the primary path. The reduction in support tickets from NAT and firewall issues more than offsets the slight audio quality trade-off. Keep SIP as a fallback for agents who have persistent WebRTC issues or who need hardware phones.
NAT Traversal: The Core Problem
When an agent sits behind a home router, their SIP phone sends packets with a private IP address (like 192.168.1.50) in the SIP headers and SDP body. Your Asterisk server sees the packet arriving from the router’s public IP, but the SIP protocol itself contains the private IP. This mismatch causes one-way audio, registration failures, and calls that connect but drop after 30 seconds.
How NAT Breaks SIP
Here is what happens step by step:
- Agent’s softphone sends a SIP REGISTER with
Contact: <sip:[email protected]:5060>
- The home router NATs this to the public IP, say
74.125.20.100:12345
- Asterisk receives the packet from
74.125.20.100:12345 but the SIP header says 192.168.1.50:5060
- Asterisk tries to send RTP audio to
192.168.1.50:5060 — which is unreachable
- Result: one-way audio or no audio
STUN Servers
STUN (Session Traversal Utilities for NAT) lets the client discover its own public IP address. The softphone sends a binding request to a STUN server, which responds with the public IP and port it sees. The softphone then uses this information in its SIP headers.
For SIP softphones, configure the STUN server in the softphone settings:
STUN Server: stun.l.google.com:19302
Or run your own STUN server using coturn:
# Install coturn
yum install coturn -y

# /etc/turnserver.conf
listening-port=3478
listening-ip=0.0.0.0
external-ip=YOUR_PUBLIC_IP
realm=your-vicidial-domain.com
server-name=your-vicidial-domain.com
fingerprint
lt-cred-mech
user=vicidial:a-strong-password-here
no-tls
no-dtls
# Only enable STUN, not TURN (we'll add TURN later if needed)
no-tcp-relay
TURN Servers
STUN fails in roughly 15% of NAT scenarios (symmetric NAT, strict corporate firewalls). TURN (Traversal Using Relays around NAT) is the fallback. It relays all media through the TURN server, which guarantees connectivity at the cost of additional server bandwidth and latency.
For WebRTC, TURN is essential. Browsers will attempt direct connections first, then fall back to TURN automatically via the ICE (Interactive Connectivity Establishment) framework.
# /etc/turnserver.conf (full STUN + TURN config)
listening-port=3478
tls-listening-port=5349
listening-ip=0.0.0.0
external-ip=YOUR_PUBLIC_IP
relay-ip=YOUR_PUBLIC_IP
realm=your-vicidial-domain.com
server-name=your-vicidial-domain.com
fingerprint
lt-cred-mech
user=vicidial:a-strong-password-here
total-quota=100
stale-nonce=600
cert=/etc/letsencrypt/live/your-domain/fullchain.pem
pkey=/etc/letsencrypt/live/your-domain/privkey.pem
cipher-list="ECDHE-RSA-AES256-GCM-SHA512:DHE-RSA-AES256-GCM-SHA384"
no-multicast-peers
Start and enable the service:
systemctl enable coturn
systemctl start coturn
Asterisk NAT Configuration
Asterisk needs to be told how to handle NATted endpoints. The two critical settings live in your SIP peer configuration.
The nat= Parameter
In /etc/asterisk/sip.conf (or in the peer definition within VICIdial’s admin interface under Phones), set:
[remote-agent-template](!)
type=friend
host=dynamic
nat=force_rport,comedia
qualify=yes
qualifyfreq=30
Here is what each nat option does:
-
force_rport: Asterisk ignores the port in the SIP Via header and instead uses the port the packet actually arrived from. This solves the “SIP says port 5060, but NAT mapped it to port 23456” problem.
-
comedia: Short for “connection-oriented media.” Asterisk ignores the IP/port in the SDP (media description) and instead sends RTP to the IP/port where it receives RTP from the agent. This solves one-way audio.
Together, force_rport,comedia tells Asterisk: “Don’t trust what the SIP headers say about where this agent is. Look at where the packets are actually coming from, and send responses there.”
The externip and localnet Settings
In the [general] section of sip.conf:
[general]
externip=YOUR_PUBLIC_IP
localnet=192.168.0.0/255.255.0.0
localnet=10.0.0.0/255.0.0.0
localnet=172.16.0.0/255.240.0.0
This tells Asterisk: “If a SIP endpoint is NOT on one of these local networks, use externip in the SIP headers instead of the internal IP.” Without this, Asterisk sends its private IP to remote agents, causing the same NAT problem in reverse.
If your public IP changes (dynamic IP from your ISP), use externhost instead:
externhost=sip.your-domain.com
externrefresh=60
RTP Port Range
Define a manageable RTP port range in /etc/asterisk/rtp.conf:
[general]
rtpstart=10000
rtpend=20000
This gives you 10,000 ports, enough for 5,000 concurrent calls. For a 25-50 agent center, you could narrow this to 10000-12000, which simplifies firewall rules.
WebRTC Setup with VICIdial
VICIdial’s built-in WebRTC support uses the WebPhone feature. Here is how to configure it end to end.
Step 1: Enable WebRTC in Asterisk
Add the WebSocket transport to sip.conf or http.conf:
; In /etc/asterisk/http.conf
[general]
enabled=yes
enablestatic=yes
bindaddr=0.0.0.0
bindport=8088
tlsenable=yes
tlsbindaddr=0.0.0.0:8089
tlscertfile=/etc/letsencrypt/live/your-domain/fullchain.pem
tlsprivatekey=/etc/letsencrypt/live/your-domain/privkey.pem
In sip.conf, allow the WebSocket transport:
[general]
transport=udp,ws,wss
Step 2: Configure Phone Entries for WebRTC
In VICIdial Admin, go to Phones and create or edit phone entries for remote agents. Key settings:
Phone Type: WebPhone
Protocol: SIP
Registration: Dynamic
NAT: force_rport,comedia
Transport: wss
Encryption: yes
AVPF: yes
ICE Support: yes
Or directly in the Asterisk peer config:
[webrtc-agent](!)
type=friend
host=dynamic
transport=wss
nat=force_rport,comedia
encryption=yes
avpf=yes
icesupport=yes
dtlsenable=yes
dtlsverify=fingerprint
dtlscertfile=/etc/asterisk/keys/asterisk.pem
dtlssetup=actpass
disallow=all
allow=opus
allow=ulaw
Step 3: Enable WebPhone in VICIdial
In the VICIdial Admin interface:
- Go to System Settings and set
WebPhone URL to your WSS endpoint
- Under User Groups, enable
WebPhone for the remote agent groups
- In Phones, set the phone entry to use WebPhone with the appropriate server
The agent login screen will show a “WebPhone” checkbox. When enabled, audio runs through the browser via WebRTC instead of requiring an external softphone.
Step 4: TURN Server Integration
Configure VICIdial to pass TURN credentials to the WebRTC client. In the system settings or the WebPhone configuration:
TURN Server: turn:your-domain.com:3478
TURN Username: vicidial
TURN Password: a-strong-password-here
This ensures agents behind symmetric NAT can still connect.
Firewall Rules and Security
Remote agents mean your Asterisk server is exposed to the internet. This is the single biggest security risk in any VoIP deployment. SIP brute-force attacks and toll fraud are constant threats.
Required Ports
For SIP-based remote agents:
# SIP signaling
iptables -A INPUT -p udp --dport 5060 -j ACCEPT
iptables -A INPUT -p tcp --dport 5060 -j ACCEPT

# RTP media
iptables -A INPUT -p udp --dport 10000:20000 -j ACCEPT

# STUN/TURN
iptables -A INPUT -p udp --dport 3478 -j ACCEPT
iptables -A INPUT -p tcp --dport 3478 -j ACCEPT
For WebRTC-only remote agents:
# HTTPS (WebRTC signaling via WSS)
iptables -A INPUT -p tcp --dport 443 -j ACCEPT

# TURN relay (TCP fallback)
iptables -A INPUT -p tcp --dport 3478 -j ACCEPT
iptables -A INPUT -p udp --dport 3478 -j ACCEPT

# TURN TLS
iptables -A INPUT -p tcp --dport 5349 -j ACCEPT
Notice that WebRTC needs far fewer open ports. This is a significant security advantage.
Fail2Ban for SIP
Install and configure Fail2Ban to block SIP brute-force attempts:
# /etc/fail2ban/jail.local
[asterisk]
enabled = true
port = 5060,5061
filter = asterisk
logpath = /var/log/asterisk/messages
maxretry = 3
bantime = 86400
findtime = 600
The Asterisk filter (/etc/fail2ban/filter.d/asterisk.conf) should catch failed registration attempts:
[Definition]
failregex = NOTICE.* .*: Registration from '.*' failed for '<HOST>:.*' - Wrong password
            NOTICE.* .*: Registration from '.*' failed for '<HOST>:.*' - No matching peer found
            NOTICE.* .*: Registration from '.*' failed for '<HOST>:.*' - Username/auth name mismatch
            NOTICE.* <HOST> failed to authenticate as '.*'
            NOTICE.* .*: No registration for peer '.*' (from <HOST>)
            NOTICE.* .*: Host <HOST> failed MD5 authentication for '.*'
SIP Peer Security
Never use weak passwords for SIP peers. Generate strong credentials:
In the peer configuration:
[1001]
secret=kX7mN2pQ9vR4sW8yA3bF6hJ0  ; generated, not guessable
deny=0.0.0.0/0.0.0.0
permit=0.0.0.0/0.0.0.0            ; allow from anywhere (remote agents)
call-limit=2                       ; prevent toll fraud abuse
For environments where agents have static IPs (office-based remote sites), lock down the permit field to those specific IPs.
Rate Limiting with iptables
Add rate limiting to slow down SIP scanning bots:
iptables -A INPUT -p udp --dport 5060 -m recent --set --name SIP
iptables -A INPUT -p udp --dport 5060 -m recent --update --seconds 60 --hitcount 20 --name SIP -j DROP
Audio Quality Optimization for Remote Workers
Home internet connections are unpredictable. Here is how to maximize audio quality despite variable network conditions.
Codec Selection
For remote agents, codec choice matters more than in a LAN environment:
| Codec |
Bandwidth |
Quality |
CPU |
Best For |
| G.711 (ulaw) |
87 kbps |
Excellent |
Low |
LAN, stable connections |
| G.729 |
31 kbps |
Good |
Medium |
Low bandwidth, licensed |
| Opus |
6-510 kbps |
Excellent |
Medium |
WebRTC, variable bandwidth |
For SIP remote agents, use G.711 if bandwidth is sufficient (most home connections have plenty). G.729 saves bandwidth but adds transcoding overhead and requires a license per concurrent channel.
For WebRTC agents, Opus is the native codec and adapts its bitrate dynamically. It is the best choice for variable home internet.
Configure codec priority in the peer:
[remote-sip-agent]
disallow=all
allow=ulaw
allow=alaw
allow=g729    ; fallback for bad connections

[remote-webrtc-agent]
disallow=all
allow=opus    ; native WebRTC codec
allow=ulaw    ; fallback
Jitter Buffer Configuration
Jitter (variation in packet arrival time) is the primary quality killer for remote agents. Configure Asterisk’s jitter buffer:
; In sip.conf [general] or per-peer
jbenable=yes
jbforce=yes
jbmaxsize=200       ; max buffer in ms
jbresyncthreshold=1000
jbimpl=adaptive      ; adapts to network conditions
jblog=no             ; disable in production for performance
The adaptive jitter buffer adjusts its size based on observed network conditions, which is critical for home internet connections that vary throughout the day.
QoS and DSCP Marking
While you cannot control the agent’s home network QoS, you can mark packets leaving your server so that any QoS-aware network equipment along the path gives VoIP traffic priority:
; In /etc/asterisk/rtp.conf
[general]
tos_audio=ef         ; Expedited Forwarding (DSCP 46)
cos_audio=5

; In sip.conf
tos_sip=cs3          ; SIP signaling
cos_sip=3
Agent Network Requirements
Document minimum requirements for remote agents:
-
Download speed: 1 Mbps minimum (5 Mbps recommended)
-
Upload speed: 512 Kbps minimum (2 Mbps recommended)
-
Latency: Under 150ms to server
-
Jitter: Under 30ms
-
Packet loss: Under 1%
-
Connection type: Wired Ethernet strongly recommended (Wi-Fi adds jitter)
Provide agents with a quick test they can run:
# Ping test to VICIdial server
ping -c 100 your-vicidial-server.com

# Check for packet loss and latency variation
# Look for: avg latency < 150ms, 0% packet loss
Troubleshooting Common Remote Agent Issues
One-Way Audio
Symptom: Agent can hear the customer but customer cannot hear the agent (or vice versa).
Diagnosis:
# On the Asterisk server, check RTP flow during an active call
asterisk -rx "rtp set debug on"

# Check if Asterisk is sending RTP to the correct address
asterisk -rx "sip show channel <channel-name>"
Common fixes:
- Verify
nat=force_rport,comedia is set
- Check
externip is correct
- Ensure RTP port range is open in firewall
- Disable SIP ALG on the agent’s home router (this is the #1 cause)
To disable SIP ALG, agents typically need to access their router admin panel. Common locations:
- Netgear: Advanced > WAN Setup > Disable SIP ALG
- Linksys: Security > Firewall > Disable SIP ALG
- TP-Link: Advanced > NAT Forwarding > ALG > Disable SIP ALG
Registration Drops
Symptom: Agent phone registers successfully but drops after 30-120 seconds.
Diagnosis:
asterisk -rx "sip show peers" | grep "remote-agent"
# Look for Qualify: OK vs. UNREACHABLE
Common fixes:
- Set
qualifyfreq=25 (keep-alive interval, must be less than NAT timeout)
- Enable
qualify=yes on the peer
- On the softphone, set registration expiry to 60 seconds (not 3600)
- Check if the agent’s firewall is blocking inbound UDP after a timeout
Audio Choppy or Robotic
Symptom: Audio cuts in and out or sounds distorted.
Diagnosis:
# Check for packet loss on the server side
asterisk -rx "rtp set debug on"

# Monitor system load (transcoding overhead)
top -bn1 | head -20
Common fixes:
- Switch from Wi-Fi to wired Ethernet
- Reduce codec bitrate (switch to G.729 or lower Opus bitrate)
- Increase jitter buffer size
- Have the agent close bandwidth-heavy applications
- Check if the agent’s ISP is throttling UDP traffic
WebRTC Connection Failures
Symptom: Agent clicks WebPhone but audio never connects.
Diagnosis:
- Open browser developer tools (F12) > Console tab
- Look for WebSocket connection errors or ICE negotiation failures
Common fixes:
- Verify TLS certificates are valid and not expired
- Check that WSS port (8089 or 443) is accessible
- Ensure TURN server is running and credentials are correct
- Try a different browser (Chrome and Firefox have the best WebRTC support)
- Check that the agent is not on a network that blocks WebSocket connections (some corporate VPNs do this)
Echo or Feedback
Symptom: The customer or agent hears an echo of their own voice.
Common fixes:
- Require agents to use headsets (not laptop speakers/mic)
- Enable echo cancellation in the softphone settings
- In Asterisk, enable
echocancel=yes on the channel if using DAHDI
- Reduce the agent’s speaker volume (echo is often caused by the mic picking up speaker output)
Scaling Remote Agent Deployments
When scaling beyond 50 remote agents, consider these architectural decisions:
Dedicated Media Proxy
Run RTPproxy or RTPengine as a dedicated media relay. This offloads RTP processing from Asterisk and gives you a single point to handle NAT traversal:
# Install RTPengine
yum install rtpengine -y

# /etc/rtpengine/rtpengine.conf
[rtpengine]
interface=YOUR_PUBLIC_IP
listen-ng=127.0.0.1:2223
port-min=30000
port-max=40000
log-level=5
Geographic Distribution
For agents spread across time zones or countries, consider placing Asterisk servers or media proxies in multiple regions to reduce latency. A hub-and-spoke model with IAX2 trunking between servers keeps centralized management while distributing media handling.
Monitoring
Deploy monitoring that catches remote agent issues before they cause missed calls:
# Check registration status for all remote agents
asterisk -rx "sip show peers" | grep -c "OK"

# Alert if registration count drops below expected
EXPECTED=50
ACTUAL=$(asterisk -rx "sip show peers" | grep -c "OK")
if [ "$ACTUAL" -lt "$EXPECTED" ]; then
    echo "WARNING: Only $ACTUAL of $EXPECTED agents registered"
fi
How ViciStack Helps
Configuring remote agents involves touching Asterisk SIP settings, NAT traversal, firewall rules, codec selection, jitter buffers, TURN servers, and WebRTC — all of which interact in ways that are difficult to predict. A misconfiguration in one layer often manifests as a symptom in another, and troubleshooting across dozens of agents’ home networks is time-consuming.
ViciStack manages the entire remote agent stack for VICIdial centers running 25+ agents:
-
NAT traversal configuration tuned to your specific network topology
-
TURN server deployment and management so WebRTC agents always connect
-
Asterisk peer templates optimized for remote connections with proper
nat, qualify, and codec settings
-
Firewall hardening with Fail2Ban rules and rate limiting specific to your deployment
-
Audio quality monitoring that catches degradation before agents report it
-
24/7 troubleshooting for the one-way audio calls and registration drops that eat into your connect rates
We have configured remote agent setups for over 100 VICIdial call centers. We know which consumer routers mangle SIP, which ISPs throttle UDP, and which WebRTC edge cases will burn hours if you hit them unprepared.
Get a free analysis of your VICIdial remote agent setup. We will review your Asterisk configuration, identify NAT traversal gaps, and show you exactly where audio quality is being lost.
Request your free ViciStack analysis — response in under 5 minutes.
Related Articles

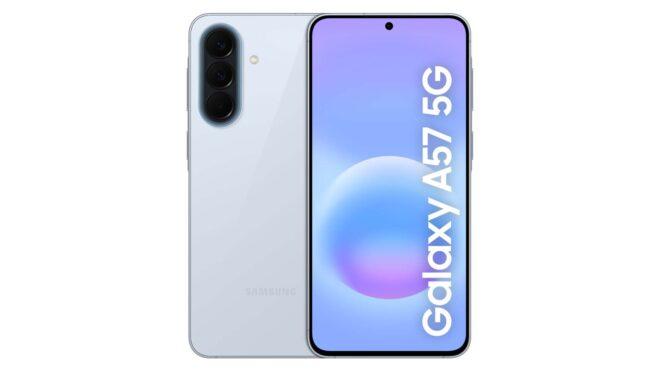
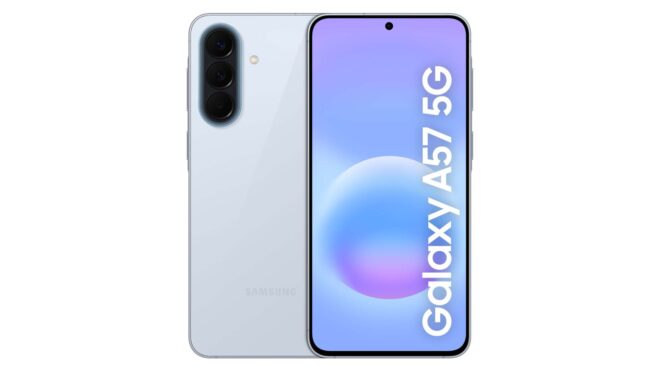 Yapılan sızıntılar sayesinde tasarımsal ve teknik açıdan sürprizin kalmadığı Samsung Galaxy A57 ve Galaxy A37, bugün yapılan resmi açıklamaya göre 25 Mart tarihinde tanıtılacak. Türkiye’de de satılacak telefonlardan Galaxy A37, teknik olarak bakarsak 6,7 inç boyutunda 120 Hz AMOLED ekran, Exynos 1480 işlemci, 6 / 8 GB RAM seçenekleri, 128 / 256 GB depolama seçenekleri, 45W şarj destekli 5.000 mAh batarya ve 12 megapiksel selfie kamerası ile geliyor. 162,9 x 78,2 x 7,4 mm gövde ölçüleri ve 196 gram ağırlığa sahip olan telefonun arkasında ise 50 megapiksel geniş açı, 12 megapiksel ultra geniş açı ve 5 megapiksel makro kameralar yer alıyor. Galaxy A57 ise 6,7 inç boyutunda 120 Hz AMOLED ekran, Exynos 1680 işlemci, 6 / 8 GB RAM seçenekleri, 128 / 256 GB depolama seçenekleri, 45W şarj destekli 5.000 mAh batarya ve 12 megapiksel selfie kamerası ile geliyor. 161,5 x 76,9 x 6,9 mm gövde ölçüleri ve 192 gram ağırlığa […]
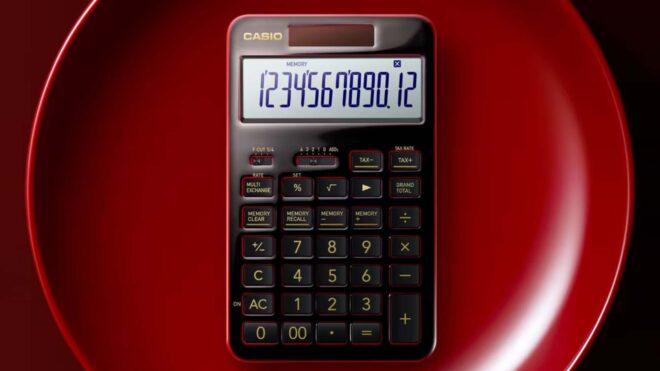
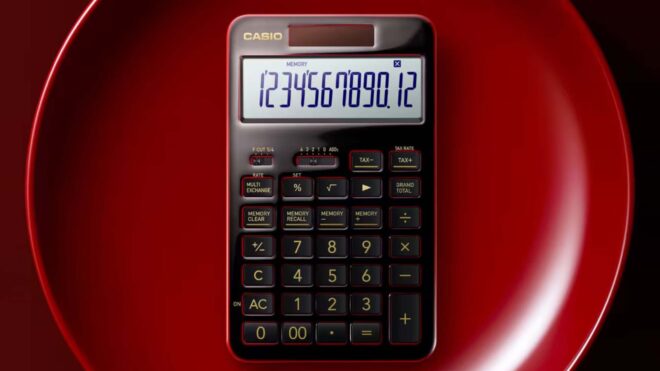 Casio, 2026 yılında halen hesap makinesi üretimine devam ediyor ve Japon şirket bu sefer toplamda 650 adet üretilecek özel modeliyle ses getiriyor. “S100X-JC1-U” model adının kullanıldığı ve geleneksel Japon lake sanatı olan Urushi’nin temel alındığı bu özel versiyon, lake ağacı özü kullanılarak hazırlanan parlak siyah gövdesi ve kenarlardaki kırmızı detaylarıyla fark yaratıyor. Yaklaşık 620 dolarlık satış fiyatına sahip olan ürün, aktarıldığı kadarıyla temel özellikler yanında para birimi dönüştürme ve vergi hesaplama gibi işlevler de içeriyor. 12 basamaklı FSTN LCD ekranla donatılan ürün, uzun yıllar boyunca şarj gerektirmeyecek bir seçenek konumunda. Entegre güneş paneli ve taşıdığı düğme pil ile birlikte modelin günde yaklaşık bir saatlik kullanımla tam yedi yıla kadar dayanabileceği açıklanıyor.
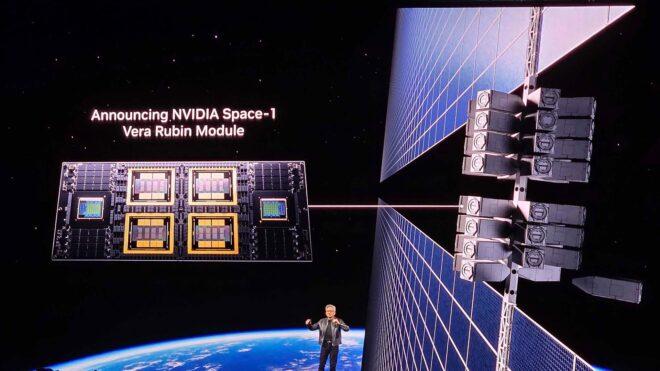
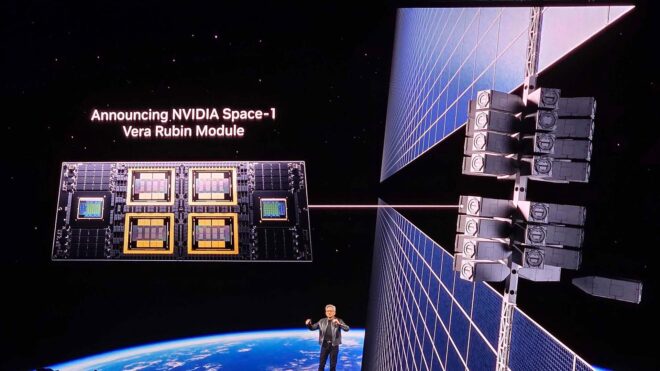 Geçtiğimiz yıl katıldığı bir etkinlikte açıklamalarda bulunan Amazon’un kurucusu Jeff Bezos, önümüzdeki 10 ila 20 yıl içinde yörüngede son derece büyük ölçekli veri merkezlerinin inşa edileceğini öngördüğünü belirtmişti. Bezos, bu merkezlerin hem soğutma hem de güneşten enerji elde etme konusunda çok verimli olacağına inandığını aktarmıştı. Bunun üstüne önemli bir adım atan Bezos’un özel uzay şirketi Blue Origin, yaklaşık 52 bin adet uyduyu uzayda yapay zeka odaklı bir veri merkezi oluşturmak amacıyla göndermek için FCC’ye başvuruda bulundu. Peki uzaydaki veri merkezlerine tam olarak ne güç verecek? Nvidia CEO’su Jensen Huang geçtiğimiz günlerde düzenledikleri GTC 2026 etkinliğinde bu konuda önemli bir duyuru gerçekleştirdi. Uzayda kurulacak veri merkezlerine güç verecek “Vera Rubin Space-1 Module” isimli bir yapay zeka işlem birimi üzerinde çalışmaya başladıklarını açıklayan Huang, yeni sistem için henüz herhangi bir teknik detay paylaşmadan, “Uzayda konveksiyon yok, sadece radyasyon var. Bu yüzden sistemleri uzayda nasıl soğutacağımızı çözmemiz gerekiyor. Şu anda bunun için alanında […]
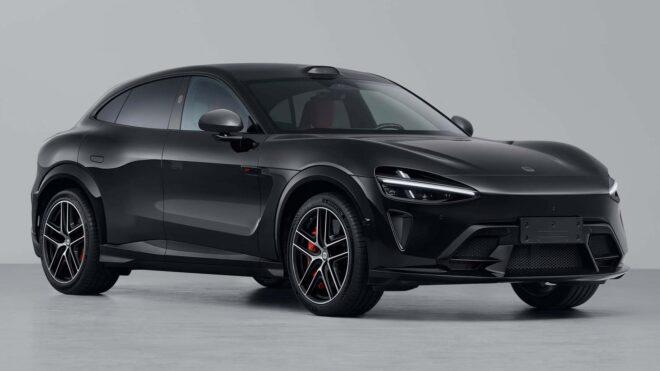
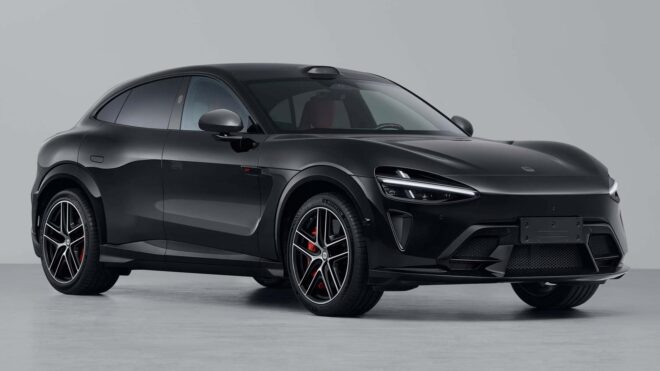 Tamamen elektrikli SUV modeli Xiaomi YU7’nin “GT” versiyonu için yeni detaylar paylaşıldı. Çin’in resmi Ministry of Industry and Information Technology (MIIT) kayıtlarına giren Xiaomi YU7 GT, 101,7 kWh kapasiteli büyük bir batarya taşıyor. Tam 666 kg ağırlığa sahip olduğu aktarılan bu batarya ile aracın 700 km civarında menzil (CLTC) sunabileceği belirtiliyor. Önde 288 kW, arkada ise 450 kW gücünde iki farklı elektrik motorunu bir araya getirecek yaklaşık 990 beygir (738 kW) gücündeki YU7 GT, performans konusunda 681 beygirlik standart YU7’yi ciddi şekilde geride bırakacak. 300 km/s hıza çıkabileceği de açıklanan 2.460 kg’lık modelde, yüksek performanslı frenlere yer verilecek.
 Nothing şirketinin CEO’su Carl Pei, SXSW etkinliğinde mobil dünyanın geleceği için dikkat çeken açıklamalarda bulundu. Yapay zeka ajanlarının her şeyi yapabileceği bir geleceğin bizleri beklediğini söyleyen Pei, “Bence artık uygulamaların tarih olacağını herkesin anlaması gerekiyor. Eğer girişiminiz tüm olayı sadece bir uygulamadan ibaretse, isteseniz de istemeseniz de bu düzen değişecek. Çok güçlü bir markanız veya dağıtım ağınız varsa süreci biraz erteleyebilirsiniz ama onun dışında herkese bakış açısını değiştirmesini öneriyorum. Mesela gelecek, işleri sizin yerinize halleden yapay zeka ajanlarındaysa, neden uygulamanızı bu ajanların rahatça kullanabileceği bir API ya da MCP sistemine açmıyorsunuz? Bazı şirketlerin akıllı telefonlarda insanların kullanımlarını taklit etmeye çalıştığını görüyorum. Örneğin bir yapay zeka ajanı Uber uygulamasını açıp adresi tek tek yazmaya çalışıyor. Gelecek bu değil. Gelecek, ajanların insan arayüzlerini kullanması değil. Ajanların kullanması için özel bir arayüz oluşturmanız gerekiyor. Bence kalıcı olmanın yolu buradan geçiyor.” ifadelerini kullandı. Pei, geçtiğimiz yıl verdiği bir röportajda gelecekte uygulama kullanmayacağımızı, bunun yerine […]
 Apple, paylaşılan yeni bir rapora göre 2025’te yapay zeka uygulamalarından yaklaşık 900 milyon dolar kazandı. App Store komisyonları/kesintileri üzerinden elde edilen bu gelirin yüzde 75’inin doğrudan ChatGPT aboneliklerinden geldiği aktarılıyor. Yapay zeka yarışının oldukça gerisinde kalan ancak buna rağmen alandan büyük paralar kazanmaya devam eden şirket, geçtiğimiz aylarda Siri’yi geleceğe taşımak, gerçekten faydalı ve akıllı bir asistana dönüştürmek için Google ile iş birliği yaptığını duyurmuştu. Yıllık 1 milyar dolar civarında olduğu iddia edilen anlaşma kapsamında yeni nesil Siri’ye doğrudan Gemini için hazırlanan yapay zeka modellerinden biri güç verecek. Şirket Bloomberg’den Mark Gurman’ın iddiasına göre Siri’nin ChatGPT ile benzer şekilde iletişim kurulabilecek bir sürümünü de hazırlayacak.