
The UK Government Just Warned About Vibe Coding Security at RSA. Two Days Later, a Supply Chain Attack Proved Why.

Two things happened this week that every vibe coder needs to know about.

On March 24, the head of the UK’s National Cyber Security Centre stood on stage at RSA Conference and told the global security community that vibe coding is creating “intolerable risks.” The same day, attackers backdoored LiteLLM, a Python package with 95 million monthly PyPI downloads, through a poisoned security scanner in its CI/CD pipeline.

One is a warning. The other is proof.

What the NCSC Actually Said

Richard Horne, CEO of the NCSC (the UK’s equivalent of CISA), didn’t mince words.

“The attractions of vibe coding are clear. Disrupting the status quo of manually produced software that is consistently vulnerable is a huge opportunity, but not without risk of its own.”

He went further: “The AI tools we use to develop code must be designed and trained from the outset so that they do not introduce or propagate unintended vulnerabilities.”

The NCSC also published a blog post the same day calling AI-generated code an “intolerable risk” for many organizations. They referenced the term “SaaSpocalypse” to describe what happens when everyone starts vibe coding replacements for their SaaS subscriptions without thinking about security.

Their core message: if the security community doesn’t get involved now, the vibe coding future will be built without them. Just like what happened with early cloud adoption.

The LiteLLM Attack: What Actually Happened

While Horne was on stage warning about supply chain risks, the security community was already dealing with one.

On March 24, malicious versions of LiteLLM (1.82.7 and 1.82.8) were uploaded to PyPI. The attacker didn’t compromise LiteLLM directly. They went upstream. They poisoned Trivy, a popular open-source security scanner, through a rewritten GitHub Action tag. When LiteLLM’s CI/CD pipeline ran Trivy as part of its normal build process, the malicious code injected a credential stealer into the published package.

Read that again: a security scanner was used as the attack vector.

The malicious versions were designed to steal credentials and exfiltrate encrypted data. Multiple security firms (Endor Labs, JFrog, Snyk) confirmed the attack. The compromised packages were live on PyPI for hours before removal.

95 million monthly downloads. Credential theft payload. Injected through a security tool.

Why This Matters for Vibe Coders

If you’re shipping apps with Cursor, Lovable, Bolt, or Replit, here’s why these two events should change how you think:

1. Your dependencies are the attack surface.
You’re not writing most of the code. AI is. And AI pulls from package ecosystems that are actively targeted. The LiteLLM attack shows that even security tools themselves can be compromised. npm install and pip install are trust decisions.

2. AI-generated code inherits AI-generated vulnerabilities.
The NCSC is right. Current AI tools don’t consistently produce secure code. They produce code that works. “Works” and “secure” are different things. Exposed API keys, missing authentication, open database policies, CORS wildcards. These are the defaults AI gives you.

3. Nobody is coming to save you.
The NCSC is calling for safeguards, but they don’t exist yet. There’s no “vibe coding security standard.” No built-in scanning in most AI coding tools. If you shipped an app last week, its security is your problem today.

What You Can Actually Do

Stop reading security news and panicking. Start doing these five things:

Check your dependencies. Run npm audit or pip audit on every project. Today. If you don’t understand the output, paste it into your AI coding tool and ask it to explain.

Scan your deployed app. Tools like Aikido, Snyk, and VibeCheck scan for the basics: exposed secrets, missing security headers, open databases. Most have free tiers. Use them.

Pin your dependency versions. Don’t use ^ or ~ in package.json. Don’t use >= in requirements.txt. Lock exact versions. The LiteLLM attack only hit people who pulled the latest version.

Add security headers. If you’re on Vercel or Netlify, add a vercel.json or _headers file with Content-Security-Policy, X-Frame-Options, and Strict-Transport-Security. AI can generate these for you in 30 seconds.

Review what your AI built. You don’t need to read every line. Search your codebase for: hardcoded API keys, CORS: *, disabled authentication, public database policies. These are the four things that get vibe-coded apps hacked.

The Bigger Picture

The NCSC compared vibe coding to early cloud adoption. When SaaS first appeared, security professionals raised concerns. The business benefits were so obvious that the industry moved forward anyway, and we spent the next 20 years fixing the problems they warned about.

Vibe coding is at the same inflection point. The productivity gains are real. The security gaps are real. And right now, there’s a window where the tools and practices are being defined.

The NCSC’s CTO put it clearly: organizations should start implementing safeguards now, not when the technology matures.

For solo founders and indie builders, the translation is simple: scan your code, check your dependencies, add security headers. These aren’t difficult. They take minutes. And they’re the difference between being part of the problem the NCSC is warning about and being ahead of it.

I test every vibe coding security scanner so you don’t have to. Full comparison: I Tested Every Vibe Coding Security Scanner (2026)
Video.js Was Abandoned After 16 Years. Its Creator Came Back and Merged 5 Competing Players Into One.

The Video.js platform has been available for an entire generation of engineers to use, over 16 years. It powers trillions of video plays all over the web. Until recently, Brightcove was cutting the checks that kept the lights on.

Then Brightcove got sold. The contributers-at-the-time on their Video.js team got laid off. The project technically became abandoned.

So the original creator of Video.js, Steve Heffernan, came back and picked it up again. After 16 years.

That should be the end of it, right? It’s a heartwarming story already. But it’s what Steve did next that’s interesting.

He didn’t just keep the lights on and get maintenance back up to speed. He reached out to the engineers behind Media Chrome, Plyr, Vidstack, and Mux Player, four separate open source video player projects, and convinced them that all of them should volunteer to throw out their own code and build something new, together.

88% Smaller

Video.js v10 is 88% smaller than v8.

Not because they use brotli on the output bundle or found some clever way to only load modules that the user actually uses. As the player sat, it would give you a 9KB or so minified + gzip bundle for a background player. Streaming would give you a bloated 150KB or so. The standard didn’t optimize for packaging parts that you didn’t use and only lazy loaded them by default. They had to agree to start over.

The Architecture

They separated everything completely. UI isn’t the player. Playback isn’t the player. Streaming support isn’t even loaded until you configure it.

React does not use web components to wrap the player in a react-like API. They actually just use hooks and render props to keep concerns separated where they belong. A promise not to stray from that in the Vue composables version is forthcoming.

Skins are shadcn-style, just grab ’em and own it.

Five Projects, One Codebase

But that’s not what I keep thinking about.

Five independent video player projects — Media Chrome, Plyr, Vidstack, Mux Player — that’s five different existing, completely independent code bases, each with owners, contributors, git history, inner opinions about the best architecture, and a slate of users that have decided that that’s the specific codebase that they prefer to use.

All raise their hand, agreed that that made sense for new code, and now they’re all actively working on the same thing and may even end up just co-maintaining one codebase.

Open Source Can’t Work Like This

Open source can’t work like this, right? Projects fork. Projects compete. They putter out because the founders just can’t keep going anymore or the interests of the big dog of the sponsor shift.

The old Video.js could have gone that way too. Brightcove’s gone. The number of users that will return to contribute can’t be counted on when you’re crossing your fingers.

But instead, the owner came back and said ‘let’s build one thing’ and somehow pointed it at five separate already successful open source projects and no one bailed.

→ Beta dropped March 2026
→ GA expected mid-2026
→ Five engineers, all with other responsibilities
→ 500+ plugins from v8 that need migration

The project is alive. Whether it stays alive depends on whether the community shows up.

When was the last time you saw five competing open source projects voluntarily merge into one?

Why Ignoring Token Costs Can Kill Your AI Product (and How to Fix It)

When building applications powered by LLMs from providers like OpenAI, Google, or Mistral AI, there’s a detail that often gets overlooked:

token cost.

At small scale, it’s barely noticeable. But once your application starts getting real usage, token consumption grows quickly—and if you’re not measuring it, you can easily end up with a feature that costs more than the value it delivers.

The real problem with token usage

Every interaction with an LLM typically involves:

  • input tokens (your prompt)
  • output tokens (the model’s response)
  • sometimes cache tokens, depending on the provider

Individually, these costs are small. But combined with:

  • longer prompts
  • verbose outputs
  • high request volume

they scale faster than most people expect.

And there’s an important nuance here:

Not all models cost the same, and not all tasks require the same type of model.

Model selection is a cost decision

It’s common to default to the most capable model available, but that’s rarely the most efficient choice.

For example:

  • you don’t need a reasoning-heavy model for simple transformations
  • you don’t need multimodal capabilities if you’re only processing text
  • many providers offer smaller or optimized variants (mini, nano, etc.)

Choosing the right model affects:

  • cost
  • latency
  • throughput

This is where cost awareness becomes part of system design, not just an afterthought.

Why you should estimate costs early

If you’re building anything beyond a prototype, you should be able to answer:

  • how much does each request cost?
  • what is the expected daily usage?
  • what does that translate to monthly or yearly?

Frameworks like LangChain, Azure AI Foundry, or AWS Bedrock usually provide token usage metrics (input/output/cache). That’s helpful, but incomplete.

In many cases, you still need to map those numbers to actual pricing yourself.

Calculating token costs

If you already have token counts, the calculation is straightforward:

cost = (input_tokens / 1000 * input_price) + (output_tokens / 1000 * output_price)

The challenge is when you don’t have those token counts directly.

In that case, you can approximate them by tokenizing:

  • the input text you send
  • the expected output

This gives you a reasonable baseline for estimation.

Tools that make this easier

There are a couple of tools that simplify this process.

LLM Prices

https://www.llm-prices.com/

This tool lets you:

  • input token counts
  • select specific models
  • estimate cost per request
  • define custom pricing if needed

Token Budget Calculator

https://tokenbudget.edwardiaz.dev/

A more complete approach is to use a tool that combines token estimation with cost projection.

With this kind of platform, you can:

  • paste input and output text
  • automatically estimate token usage
  • calculate:

    • cost per request
    • daily cost
    • monthly cost
  • define request frequency (per day / per month)

It also allows you to:

  • compare across a large set of models (100+)
  • filter by provider or capabilities
  • sort by cost efficiency
  • get a recommendation for the most cost-effective model

In addition, there is API support, which makes it possible to integrate cost estimation directly into your own systems. This is especially useful if you want to:

  • track cost per request internally
  • build usage dashboards
  • enforce budgets or limits at the application level

Planning for scale

Once you start tracking token usage and costs, you can:

  • forecast infrastructure expenses
  • define budgets
  • prevent unexpected spikes
  • choose models more intentionally

This is what turns an experimental feature into something sustainable.

Tokens also impact rate limits

Cost is only one side of the problem.

Many providers enforce limits based on tokens, such as tokens per minute. If your prompts or outputs are too large, you may run into:

  • throttling
  • increased latency
  • failed requests under load

Reducing token usage helps both with cost and system stability.

What comes next

Understanding cost is the first step. The next one is optimization.

In a follow-up post, I’ll go deeper into:

  • prompt optimization techniques
  • reducing token usage without losing quality
  • practical ways to make LLM integrations more efficient

Final thoughts

If you’re not measuring token usage, you’re making decisions without visibility.

Tracking tokens, estimating costs, and choosing the right model are not optional if you care about building scalable AI systems.

It’s a small investment early on that can save you a lot later.

SQLite Just Got Vector Search — Here’s How to Use It for AI (No Database Server Needed)

SQLite + Vectors = Game Changer

SQLite just became a serious option for AI applications. With the sqlite-vec extension, you can now do vector similarity search directly in SQLite — no Pinecone, no Weaviate, no external database.

This means you can build RAG (Retrieval Augmented Generation) apps, semantic search, and recommendation engines with zero infrastructure.

I built a local semantic search engine in 50 lines of Python. Here’s how.

Install sqlite-vec

pip install sqlite-vec

That’s it. No Docker, no server, no config files.

Build a Semantic Search Engine in 50 Lines

import sqlite3
import sqlite_vec
import json
import struct

def serialize(vector):
    return struct.pack(f"{len(vector)}f", *vector)

# Connect and load extension
db = sqlite3.connect(":memory:")
db.enable_load_extension(True)
sqlite_vec.load(db)

# Create vector table (384 dimensions for all-MiniLM-L6-v2)
db.execute("""
    CREATE VIRTUAL TABLE documents USING vec0(
        embedding float[384]
    )
""")

# Sample documents with pre-computed embeddings
# In production, use sentence-transformers to generate these
docs = [
    "Python is great for data science",
    "JavaScript dominates web development",
    "Rust ensures memory safety without garbage collection",
    "Go is built for concurrent programming",
    "SQL is the language of databases",
]

# Insert (using random embeddings for demo — use real ones in production)
import random
for i, doc in enumerate(docs):
    embedding = [random.gauss(0, 1) for _ in range(384)]
    db.execute(
        "INSERT INTO documents(rowid, embedding) VALUES (?, ?)",
        (i, serialize(embedding))
    )

# Query: find similar documents
query_vec = [random.gauss(0, 1) for _ in range(384)]
results = db.execute(
    """
    SELECT rowid, distance
    FROM documents
    WHERE embedding MATCH ?
    ORDER BY distance
    LIMIT 3
    """,
    (serialize(query_vec),)
).fetchall()

for rowid, distance in results:
    print(f"Doc: {docs[rowid]} | Distance: {distance:.4f}")

Full RAG Pipeline (SQLite + OpenAI)

from sentence_transformers import SentenceTransformer
import sqlite3
import sqlite_vec
import struct

model = SentenceTransformer("all-MiniLM-L6-v2")

def serialize(v):
    return struct.pack(f"{len(v)}f", *v)

# Setup
db = sqlite3.connect("knowledge.db")
db.enable_load_extension(True)
sqlite_vec.load(db)

db.execute("CREATE TABLE IF NOT EXISTS docs(id INTEGER PRIMARY KEY, text TEXT)")
db.execute("""
    CREATE VIRTUAL TABLE IF NOT EXISTS doc_vectors USING vec0(
        embedding float[384]
    )
""")

def add_document(text):
    cursor = db.execute("INSERT INTO docs(text) VALUES (?)", (text,))
    doc_id = cursor.lastrowid
    embedding = model.encode(text).tolist()
    db.execute(
        "INSERT INTO doc_vectors(rowid, embedding) VALUES (?, ?)",
        (doc_id, serialize(embedding))
    )
    db.commit()

def search(query, top_k=3):
    query_vec = model.encode(query).tolist()
    results = db.execute(
        """SELECT rowid, distance FROM doc_vectors
           WHERE embedding MATCH ? ORDER BY distance LIMIT ?""",
        (serialize(query_vec), top_k)
    ).fetchall()

    return [(db.execute("SELECT text FROM docs WHERE id=?", (r[0],)).fetchone()[0], r[1])
            for r in results]

# Usage
add_document("The Python GIL prevents true multithreading")
add_document("asyncio enables concurrent I/O in Python")
add_document("Rust's ownership model eliminates data races")

for text, dist in search("concurrent programming in Python"):
    print(f"{dist:.4f} | {text}")

Why This Matters

Feature SQLite + vec Pinecone Weaviate
Setup pip install Cloud signup + API key Docker + config
Cost Free forever $70+/mo Self-host or $25+/mo
Latency <1ms (local) 10-50ms (network) 5-20ms
Max vectors ~10M (depends on RAM) Unlimited (paid) Unlimited
Offline Yes No Self-host only
Deployment Copy one .db file Cloud dependency Complex

When to Use SQLite for Vectors

Use it when:

  • Your dataset is <10M vectors
  • You want zero infrastructure
  • You need offline/edge deployment
  • You’re prototyping a RAG app
  • You want to ship a single binary

Don’t use it when:

  • You need distributed search across billions of vectors
  • You need real-time index updates at massive scale
  • You need managed cloud with auto-scaling

The Bigger Picture

SQLite is eating the database world. It already handles:

  • Mobile apps (every phone has it)
  • Browser storage (via WASM)
  • Edge computing (Cloudflare D1, Turso)

Now with vector search, it’s coming for the AI infrastructure market too.

Are you using SQLite for anything beyond basic storage? I’d love to hear about creative use cases in the comments.

I write about practical AI tools and APIs every week. Follow for more no-BS tutorials.

I Built 77 Web Scrapers — Here Are the 10 Patterns That Actually Work

After building 77 scrapers, every problem is a variation of the same 10 patterns

I’ve published 77 web scrapers on Apify Store. Reddit, Hacker News, Google News, Trustpilot, YouTube, Bluesky — you name it.

Here are the 10 patterns I use in every single one.

Pattern 1: Always use sessions

# Bad: new connection every request
for url in urls:
    requests.get(url)  # TCP handshake every time

# Good: reuse connection
session = requests.Session()
for url in urls:
    session.get(url)  # Reuses TCP connection

Impact: 2-5x faster for multiple requests to the same domain.

Pattern 2: Exponential backoff on errors

import time

def fetch(url, max_retries=3):
    for i in range(max_retries):
        try:
            resp = session.get(url, timeout=10)
            if resp.status_code == 429:
                time.sleep(2 ** i)
                continue
            resp.raise_for_status()
            return resp
        except Exception:
            if i == max_retries - 1:
                raise
            time.sleep(2 ** i)

Pattern 3: Extract data with CSS selectors, not XPath

from bs4 import BeautifulSoup

soup = BeautifulSoup(html, 'html.parser')
titles = [el.text.strip() for el in soup.select('h2.post-title a')]

CSS selectors are more readable and closer to how you think in the browser devtools.

Pattern 4: Handle pagination with generators

def paginate(base_url):
    page = 1
    while True:
        resp = session.get(f'{base_url}?page={page}')
        data = resp.json()
        if not data['results']:
            break
        yield from data['results']
        page += 1

for item in paginate('https://api.example.com/items'):
    process(item)

Pattern 5: Normalize data immediately

def normalize(raw):
    return {
        'title': raw.get('title', '').strip(),
        'price': float(raw.get('price', '0').replace('$', '').replace(',', '')),
        'url': raw.get('url', '').split('?')[0],  # Remove query params
        'scraped_at': datetime.utcnow().isoformat(),
    }

Clean data at extraction time, not later.

Pattern 6: Deduplicate by content hash

import hashlib
seen = set()

def is_new(item):
    key = hashlib.md5(json.dumps(item, sort_keys=True).encode()).hexdigest()
    if key in seen:
        return False
    seen.add(key)
    return True

Pattern 7: Log progress, not just errors

import logging
log = logging.getLogger(__name__)

for i, url in enumerate(urls):
    log.info(f'Processing {i+1}/{len(urls)}: {url}')
    data = scrape(url)
    log.info(f'Got {len(data)} items from {url}')

When a scraper runs for 2 hours, you NEED to know where it is.

Pattern 8: Save incrementally, not at the end

with open('results.jsonl', 'a') as f:
    for item in scrape_all():
        f.write(json.dumps(item) + 'n')
        f.flush()  # Write to disk immediately

If the scraper crashes at item 999 out of 1000, you still have 999 results.

Pattern 9: Respect robots.txt

from urllib.robotparser import RobotFileParser

rp = RobotFileParser()
rp.set_url('https://example.com/robots.txt')
rp.read()

if rp.can_fetch('*', url):
    scrape(url)
else:
    log.warning(f'Blocked by robots.txt: {url}')

Pattern 10: Make it configurable

import argparse

parser = argparse.ArgumentParser()
parser.add_argument('--urls', nargs='+', required=True)
parser.add_argument('--output', default='results.jsonl')
parser.add_argument('--max-pages', type=int, default=10)
parser.add_argument('--delay', type=float, default=1.0)
args = parser.parse_args()

Hardcoded values = one-time scripts. Configurable = reusable tools.

The meta-pattern

Every scraper I build follows the same structure:

1. Parse config → 2. Fetch pages → 3. Extract data → 4. Normalize → 5. Deduplicate → 6. Save

The specifics change. The pattern doesn’t.

All 77 scrapers are on Apify Store. Source patterns are on GitHub.

What scraping pattern took you the longest to learn?

I help companies build data extraction pipelines. Contact me if you need custom scrapers.

Suudi Arabistan ve BAE, İHA ve Füzelere Müdahale Ettiklerini Duyurdu

Suudi Arabistan ve Birleşik Arap Emirlikleri, hava sahalarına giren insansız hava araçları (İHA) ve füzeleri etkisiz hale getirdiklerini duyurdu. Bu müdahale, bölgedeki güvenlik endişelerini artıran yeni bir gelişme olarak dikkat çekiyor. İki ülke, hava sahalarının korunmasına yönelik önlemlerini artırdıklarını vurguladı.

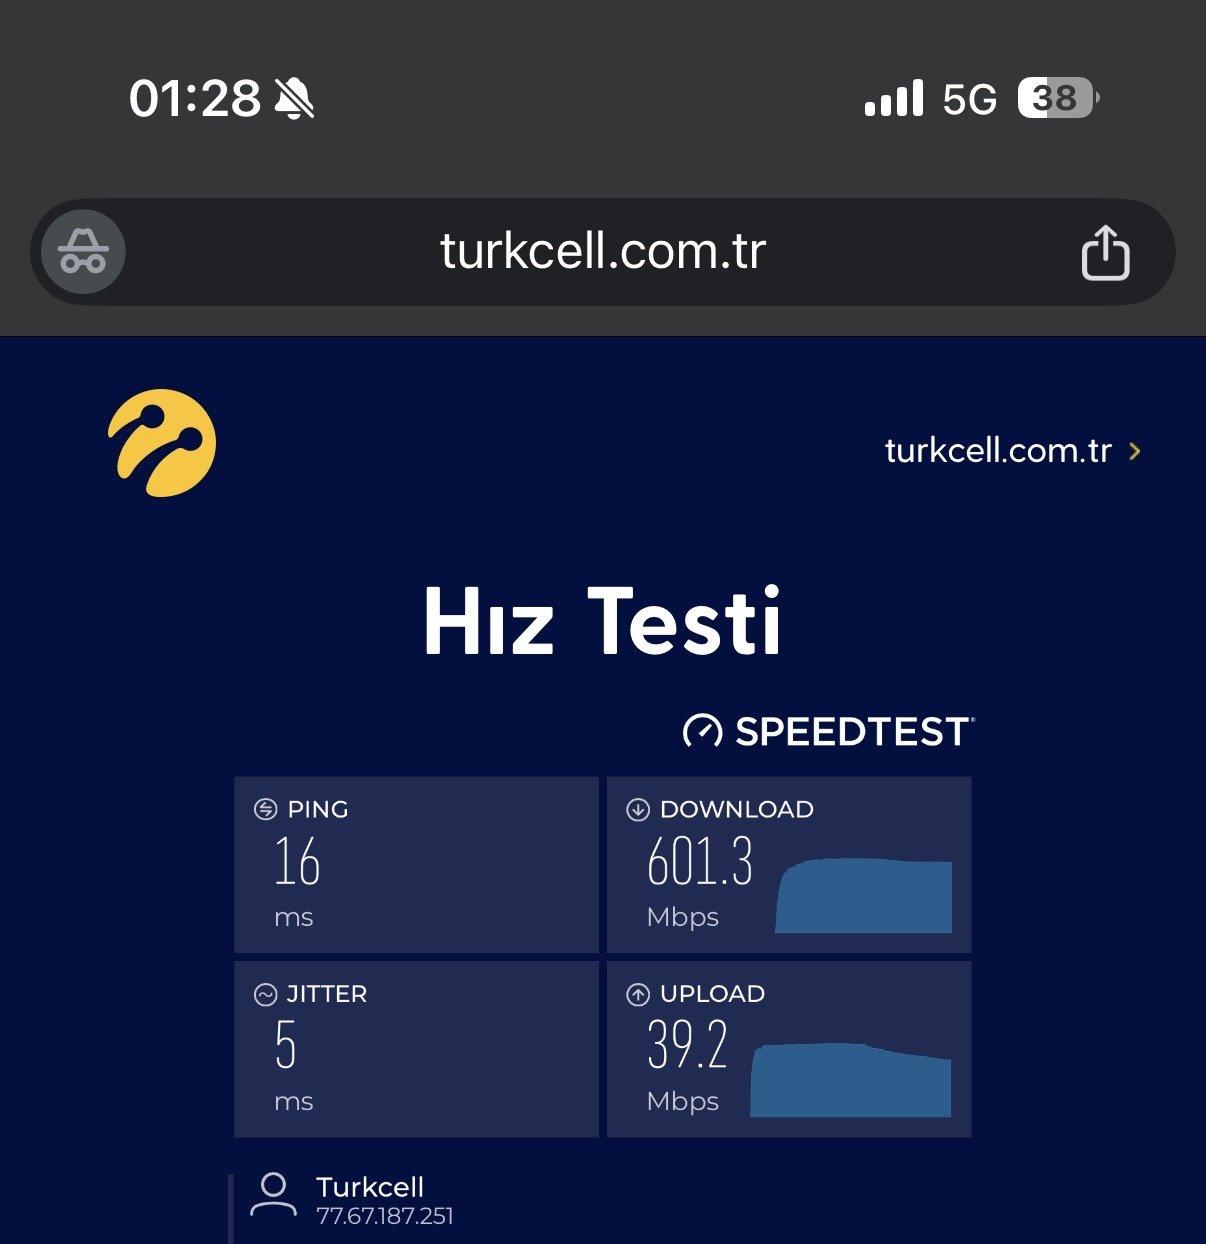
Turkcell, 5G’yi kullanıma sundu

5G frekans ihalesinin ilk aşamasının tamamlandığını ve iki paketin 1,9 milyar dolara satıldığını daha önce sizlere aktarmıştık. Uzun zamandır merakle beklenen 5G teknolojisi nihayet ülkemizde kullanım…