Birleşik Arap Emirlikleri: Hava savunma sistemlerimiz İran'dan fırlatılan füze ve İHA'ları engellemeye çalışıyor
Birleşik Arap Emirlikleri: Hava savunma sistemlerimiz İran’dan fırlatılan füze ve İHA’ları engellemeye çalışıyor.

 Grok uygulamasında kota sınırına takılmadan üretim yapmak isteyen ancak SuperGrok aboneliğini de pahalı bulanlar için SuperGrok Lite aboneliği duyuruldu.
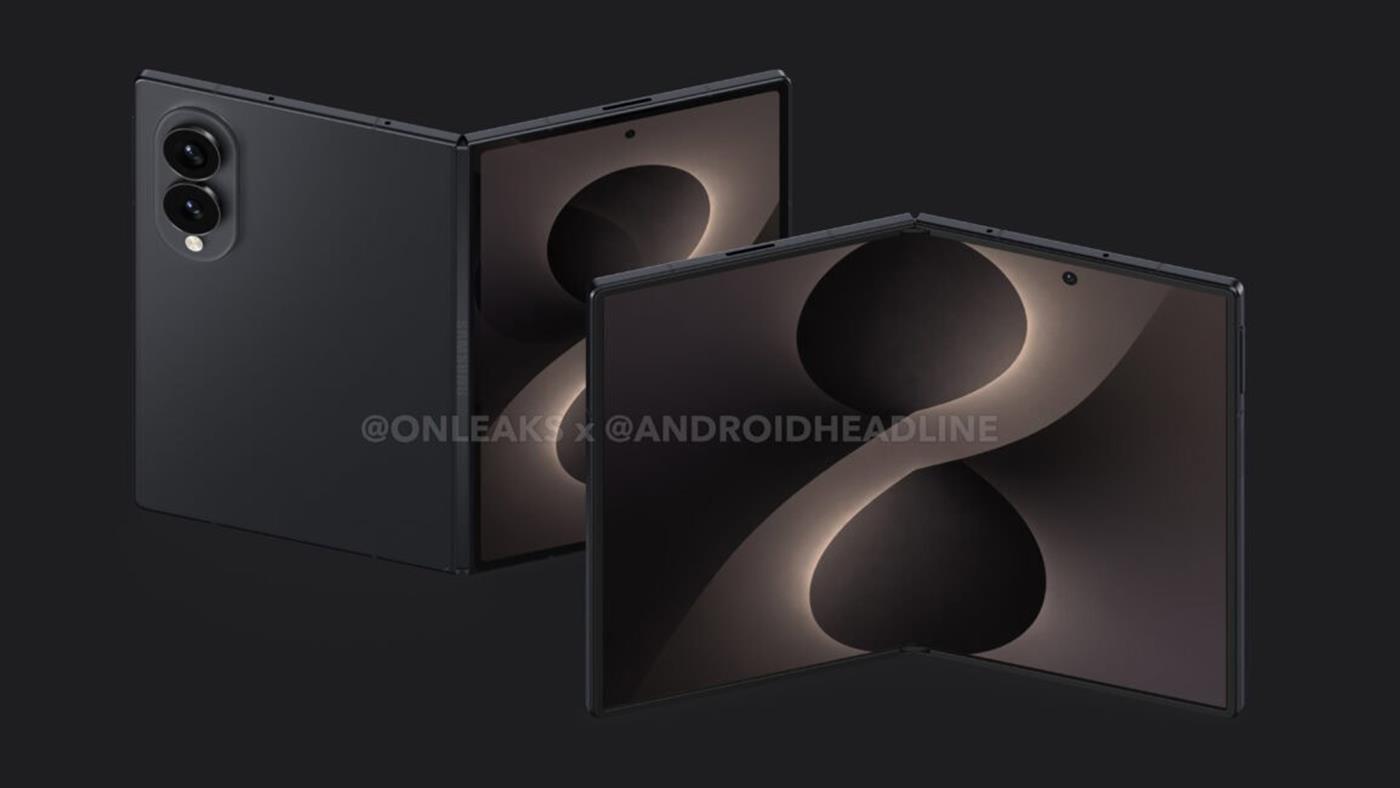
 Samsung’un geniş ekranlı yeni katlanabilir modeli Galaxy Wide Fold’un tasarımı bir sızıntıyla ortaya çıktı. Peki yeni model neler sunacak?
I wanted to understand how Imagga’s visual search compares to ours, so I signed up, got API keys, and tested both APIs against the same images. The two products turned out to be more different than I expected.
TL;DR: Imagga’s “visual search” is built on image categorization and tag matching. Vecstore uses vector embeddings for actual visual similarity. Vecstore is about 8x faster on search (300ms vs 2.5s), doesn’t require a separate database, supports text-to-image search, and auto-indexes without manual training. Imagga is stronger at structured image tagging, color extraction, and background removal.
How the Two Approaches Differ
The biggest takeaway from testing wasn’t speed. It was that the two APIs use fundamentally different approaches to image search.
Imagga categorizes images into tags using WordNet taxonomy and then finds other images that share similar tags. When you search for a dog photo, it first categorizes it as border_collie.n.01 with 93.4% confidence, then finds other images that were categorized similarly. It’s a categorization-first approach.
Vecstore converts images into vector embeddings that represent visual meaning, then finds the closest matches in vector space. It doesn’t categorize or tag anything. It compares what images actually look like.
Both are valid approaches. They solve different problems.
Imagga’s Own Demo Needs a Second Database
This was the most interesting finding. I opened the network tab on Imagga’s visual search demo and watched what happens when you search.
Two requests fire:
Request 1 goes to Imagga’s API and returns categories + image IDs:
// Imagga search response
{
  "categories": [{
    "name": "border_collie.n.01",
    "confidence": 93.41
  }],
  "images": [{
    "id": "img_1770651039261-q6ozvx531",
    "distance": 0.387
  }]
}
No image URLs. No metadata. Just IDs and distances.
Request 2 goes to a Supabase database to resolve those IDs:
// Second request to Supabase
GET /rest/v1/visual_search_images
  ?select=save_id,image_url,file_name
  &save_id=in.(img_1770651039261-q6ozvx531,img_1770651039253-ggmgwfihy,...)
Their own demo needs a separate Postgres database just to display search results. That’s not a limitation of the demo, it’s how the API works. Imagga returns IDs, you resolve them yourself.
On Vecstore, one request returns everything:
// Vecstore search response
{
  "vector_id": "abc123",
  "score": 0.94,
  "metadata": {
    "image_url": "https://...",
    "name": "Border Collie",
    "category": "pets",
    "price": 45.00
  }
}
Image URLs, custom metadata, similarity scores. No second database.
Architecture Comparison
Here’s what each setup looks like in practice:
Imagga:
Your app → Imagga API (returns IDs) → Your database (resolve URLs) → Your storage (serve images)
Vecstore:
Your app → Vecstore API (returns full results with URLs) → Your storage (serve images)
With Imagga you’re maintaining a separate database that maps image IDs to URLs and metadata. With Vecstore that mapping lives inside the search itself.
Speed Comparison
I benchmarked every operation with real API calls.

| Operation | Imagga | Vecstore |
|---|---|---|
| Insert image | 3.8 – 4.7s | ~200ms |
| Train index | ~0.9s (manual step) | Not needed |
| Search query | 2.0 – 2.5s | ~300ms |
| Insert to searchable | ~5-6s + manual retrain | ~200ms (instant) |
Vecstore’s 300ms breaks down to about 90ms for embedding generation and 5-8ms for the actual vector search. The rest is network overhead.
Imagga’s 2-2.5 seconds covers the image categorization and tag matching. That doesn’t include the second call to your own database to resolve image URLs.
The WordNet Labels
Imagga uses WordNet taxonomy for its category names. In practice that looks like this:
border_collie.n.01loggerhead.n.02turbine.n.01Persian_cat.n.01The .n.01 suffix means “noun, first sense.” This is standard in computational linguistics but not something most developers want to parse or display to users. You’d need a mapping layer to convert these to human-readable labels.
Vecstore doesn’t return category labels at all. It returns similarity scores and whatever metadata you stored when inserting the image. You control the naming.
Index Training
With Imagga, after you insert images into an index, you need to manually call a train endpoint before those images become searchable. When you add new images later, you retrain again.
Here’s what the insert-train-search flow looks like:
# Step 1: Insert images
curl -X POST "https://api.imagga.com/v2/images-similarity/index/save-image"
  -u "api_key:api_secret"
  -F "image_url=https://example.com/dog.jpg"
  -F "index_name=my_index"
  -F "save_id=img_001"

# Step 2: Manually train the index (required before search works)
curl -X POST "https://api.imagga.com/v2/images-similarity/index/train"
  -u "api_key:api_secret"
  -F "index_name=my_index"

# Step 3: Now you can search
curl -X GET "https://api.imagga.com/v2/images-similarity/index/search"
  -u "api_key:api_secret"
  -d "image_url=https://example.com/query.jpg"
  -d "index_name=my_index"
For apps where users upload images regularly (marketplaces, social platforms, photo libraries), this means either retraining after every upload or batching retrains and accepting that new images won’t be searchable immediately.
On Vecstore, insert and search:
# Insert (instantly searchable)
curl -X POST "https://api.vecstore.app/api/databases/{id}/documents"
  -H "X-API-Key: your_key"
  -H "Content-Type: application/json"
  -d '{"image_url": "https://example.com/dog.jpg"}'

# Search
curl -X POST "https://api.vecstore.app/api/databases/{id}/search"
  -H "X-API-Key: your_key"
  -H "Content-Type: application/json"
  -d '{"image_url": "https://example.com/query.jpg", "top_k": 10}'
No training step. Images are searchable the moment you insert them.
Text-to-Image Search
Imagga’s visual search is image-to-image only. You search by uploading a photo.
Vecstore supports both. You can type “wind turbine on a hillside” and get matching images back. This works because the model understands both text and images in the same embedding space.
If your users need to search by description (e-commerce, stock photography, content discovery), this matters.
No Metadata Filtering on Imagga
Since Imagga returns only IDs, there’s no way to filter results at search time. You can’t say “find similar images where price is under $50” or “find similar images in the shoes category.”
With Vecstore, metadata is stored alongside the vectors and returned with results. Filtering by metadata fields is part of the search query itself.
For e-commerce and marketplace use cases where you need to combine visual similarity with business logic, this is a meaningful difference.
Pricing
The pricing models are different. Imagga charges monthly subscriptions where unused requests expire at the end of each billing cycle. Visual search requires the $79/mo Indie plan or higher.
Vecstore sells credit packs that never expire. All features are included on every plan.

| Volume | Imagga | Vecstore |
|---|---|---|
| 5K operations | $79/mo | $8 |
| 70K operations | $79/mo | ~$66 |
| 300K operations | $349/mo | ~$240 |
At lower volumes, Vecstore is significantly cheaper. At higher volumes the gap narrows. The main structural difference is that Imagga locks features behind higher tiers (face recognition needs the $349/mo Pro plan) while Vecstore includes everything on all plans.
What Imagga Does Well
Imagga’s core strength is image tagging and categorization. If you need to auto-generate structured labels for images, extract dominant colors, remove backgrounds, or read barcodes, Imagga has mature, well-documented tools for that. Their categorization engine is solid and they’ve been doing this for a long time.
Their visual search is built on top of that categorization engine, which makes sense for their product. It’s a different approach than embedding-based search, with its own strengths: structured categories, confidence scores for each label, and a well-defined taxonomy.
When to Use Which
Imagga is a better fit when you need:
Vecstore is a better fit when you need:
If your use case is primarily search, the differences in speed, developer experience, and architecture add up. Vecstore was built for search from the ground up. Imagga was built for image understanding, and search is one application of that.
Digital Risk Protection has become one of those category labels that everyone uses and nobody defines consistently.
Ask five vendors what DRP means and you will get five different answers, each shaped by whatever their platform actually does well. Ask a security team what they bought when they bought a DRP platform and you will often get a pause followed by “monitoring, mostly.”
This is a problem worth examining directly — because the gap between what DRP is supposed to do and what most implementations actually deliver is significant, and it costs organisations in ways that don’t always show up until an incident.
What DRP Is Supposed to Mean
Digital Risk Protection, in its original conception, is the discipline of monitoring and acting against threats that exist outside your organisation’s perimeter — on infrastructure you don’t own, on platforms you don’t control, targeting people who haven’t yet interacted with you.
The canonical threat types it covers:
What distinguishes DRP from traditional security monitoring is the external orientation. You’re not watching your firewall logs. You’re watching what threat actors have built outside your walls, for the purpose of attacking your customers through you.
The action component is what separates DRP from threat intelligence. Intelligence tells you what exists. Protection implies doing something about it.
Where the Category Went Wrong
The label “Digital Risk Protection” got attached to a wide range of products as the category became commercially attractive. The result is a market where platforms with fundamentally different capability profiles sit under the same category heading.
This matters because buyers evaluating “DRP platforms” are often comparing things that aren’t actually comparable — and the gaps only become apparent under operational pressure.
Here is an honest breakdown of what different platform types actually deliver:
| Platform Type | What It Actually Does Well | What It Doesn’t Do |
|---|---|---|
| Threat intelligence feed | Detects and documents external threats at scale | Takes no action; you manage removal |
| Brand monitoring platform | Tracks brand mentions and sentiment | Limited adversarial infrastructure coverage |
| Identity / KYC verification | Screens inbound users at onboarding | Doesn’t address external impersonation |
| OSINT aggregator | Surfaces leaked credentials, dark web exposure | No disruption or takedown workflow |
| Managed security service | Provides analyst coverage across multiple tools | Takedown quality depends on sub-vendor chain |
| Dedicated DRP platform | External monitoring + takedown workflow | Quality varies significantly by vendor |
The “dedicated DRP platform” row is where the interesting differentiation lives — because within that category, the variance is enormous.
The Detection vs. Disruption Split
This is the central fault line in the DRP market, and it’s worth being precise about it.
Detection is a data problem. You’re matching observed signals against patterns of known-bad behaviour — domain registration anomalies, certificate issuance on suspicious assets, social account creation patterns, phone number reputation. Detection tooling has matured significantly. Several vendors do this well.
Disruption is a coordination problem. Removing a fake domain requires action from a domain registrar you don’t control. Taking down a fake social account requires escalation through a platform’s trust and safety process. Blocking a scam phone number requires engagement with a telecommunications carrier. None of these parties are obligated to act quickly, and the speed at which they move depends almost entirely on the quality of your evidence package and the depth of your existing relationships with their abuse teams.
Detection without disruption is documentation. It proves the threat existed. It doesn’t remove it.
This is the gap that most DRP evaluations fail to stress-test. A vendor’s case studies will feature impressive detection coverage. The question worth asking is: after you detected it, how long before it was actually gone?
How Major Vendors Actually Compare
Being honest about the competitive landscape is more useful than generic capability claims.
Recorded Future / Flashpoint
Best-in-class threat intelligence. Exceptional detection depth, particularly for threat actor tracking and dark web monitoring. Not built for takedown — that’s explicitly not their product. Organisations that buy these platforms for DRP outcomes are miscategorised buyers.
ZeroFOX
One of the more mature dedicated DRP platforms. Strong social media monitoring and takedown workflow. Geographic coverage and response times vary by region. Phone number and vishing coverage is less developed than web and social.
Cyble
Strong OSINT and dark web monitoring capability. Growing DRP workflow. Better on detection depth than disruption speed in most comparative assessments.
Brandwatch / Meltwater
Marketing-origin platforms that have added security-adjacent monitoring. Good for brand sentiment and PR-type brand misuse. Not operationally equipped for adversarial infrastructure. Buying these for scam takedown is like buying a thermometer to treat a fever.
NameScan / SEON
Identity verification and KYC-layer tools. Excellent for what they do. The problem they solve — preventing bad actors from entering your system — is different from the DRP problem, which is about bad actors operating outside your system against your customers. Category confusion here is common in procurement processes.
The platform with the most interesting architectural choice in this space is Cyberoo’s NothingPhishy, which treats the verification layer — via their separate Scams.Report product — as upstream data preparation for the disruption workflow rather than a standalone feature. The practical argument is that takedown request quality is a direct function of how well the upstream verification explains and structures the evidence. Whether that integration produces meaningfully better outcomes than alternatives is a question worth asking in any evaluation.
The Evidence Quality Problem Nobody Talks About
Here is something that vendor comparison sheets don’t usually address: the speed at which external parties action takedown requests is largely determined by evidence quality, not by how many platforms you’ve submitted to.
A domain registrar’s abuse team receives thousands of requests. The ones that move fast are the ones that arrive with:
The ones that sit in queues are vague, incomplete, or formatted as narrative text that someone has to parse manually.
Most DRP platforms generate evidence packages as a byproduct of their detection output. The quality of that output — whether it’s a structured, enriched evidence package or a risk score with a URL attached — is a direct input into takedown speed.
This is why “explainable verification” is not just a consumer-facing feature. It has operational consequences upstream in the disruption workflow.
The SPF Dimension for Australian Operations
For organisations operating under Australia’s Scams Prevention Framework, DRP has moved from a best-practice recommendation to a compliance consideration.
The SPF’s “disrupt” principle creates enforceable obligations for regulated entities in banking, telecommunications, and digital platforms to actively interfere with scam infrastructure — not just detect it or document it. The detection-only posture is architecturally insufficient under the framework.
This has created an interesting procurement pressure: organisations that previously evaluated DRP on detection coverage are now being asked by their compliance and legal teams to demonstrate disruption outcomes. The vendors positioned for this shift are the ones who can show confirmed removal rates, not just monitoring dashboards.
What a Genuine DRP Evaluation Should Cover
If you are assessing DRP platforms, the questions that separate capability from positioning:
On detection coverage:
Which external channels does your monitoring cover — domains, social, phone, apps, dark web, paste sites? What’s your average time from asset creation to detection?
On disruption workflow:
What is your confirmed removal rate for domain takedowns? Which registrars do you have direct escalation relationships with versus standard abuse submission? How do you handle infrastructure on uncooperative hosting providers?
On evidence packaging:
What does your takedown request output look like? Can you show an example evidence package? Is it generated automatically or assembled manually?
On multi-channel coordination:
If a campaign runs across a fake domain, a spoofed phone number, and a fake social account simultaneously, how do you coordinate removal across all three channels? What’s your average elapsed time on each?
On recurrence:
After a takedown, how do you detect when the same operator rebuilds under new assets? How are new assets linked to prior campaign history?
Vendors who answer these questions specifically are doing the work. Vendors who respond with general capability statements and impressive averages are selling the category, not the capability.
The Honest Summary
Digital Risk Protection is a legitimate and important discipline that has been somewhat degraded as a category label by the number of platforms that use it to describe monitoring-only capability.
The organisations that get the most value from DRP investment are the ones who are precise about what they’re buying: not detection, not monitoring, not reporting — but confirmed removal of external threats, measured in time and outcome rather than dashboard activity.
The vendors worth engaging seriously are the ones who talk about their work in operational terms, acknowledge where their capability is strong and where it isn’t, and can point to outcomes rather than processes.
Everything else is a threat intelligence feed with a DRP label on it.

How AI Agents Plan Their Own Work — Self-Scheduling in Python
Lesson 8 of 9 — A Tour of Agents
The entire AI agent stack in 60 lines of Python.

Ask Claude to refactor a module. You didn’t tell it to read the existing files first. You didn’t tell it to check the tests. You didn’t tell it to update the imports. It decided to do all of that on its own — it planned its own work.
How? The agent has a tool that adds tasks to its own queue. Every time it finishes one step, it can schedule the next. That’s self-scheduling.
The concept: a tool with a side effect

schedule_followup looks like any other tool — the agent calls it with a description of what to do next. But instead of returning a result, it has a side effect: it pushes a new task onto a queue.
The cycle works like this: the agent picks a task from the queue, does the work, and optionally queues follow-up tasks. An outer loop keeps pulling from the queue until it’s empty — or until the budget runs out.
Agent queues. Queue feeds back to agent. Budget caps the total.
The code: two loops
Two loops do everything. The inner loop is the agent — it calls the LLM, executes tools, and repeats until the model stops requesting tool calls. That’s the same loop from Lesson 2.
The outer loop is the scheduler. It pulls the next task from the queue, hands it to the inner loop, and checks the budget. If the agent called schedule_followup during its run, new tasks are already waiting in the queue.
while queue and budget > 0:
    task = queue.pop(0)
    run_agent(task)      # inner loop — may call schedule_followup
    budget -= 1
The key insight: schedule_followup is just a tool. The agent decides when to use it. The scheduler decides when to stop.
Watch it work
A task enters the queue: “research AI safety.” The agent processes it — reads sources, takes notes, and calls schedule_followup("summarize findings"). Now there’s a new task in the queue. The scheduler picks it up, the agent summarizes, and the queue drains. Budget: 2 of 5 used.
The agent planned two steps of work from a single prompt. No hardcoded workflow. No DAG. Just a tool and a queue.
Framework parallel
This pattern shows up everywhere in production agent frameworks:
The mechanism differs but the idea is identical: the agent controls its own task list.
Try it

Run this code yourself at tinyagents.dev. Give the agent a broad goal — “plan a blog post” — and watch it break the work into steps, scheduling each one as it goes.
Next up: Lesson 9 — we put it all together. The complete agent.
This is Lesson 8 of A Tour of Agents — a free interactive course that builds an AI agent from scratch. No frameworks. No abstractions. Just the code.
I’m an IT engineer at an online video platform company.
My job involves constantly evaluating new technologies to deliver better services to our clients. Last year, a question came up within the team: “What if we could process video directly in the browser, without a server?”
That single question pulled me down a WASM rabbit hole.
Why In-Browser Video Processing?
One of the services we provide to clients involves video upload and processing. The traditional approach was straightforward — users upload a file, the server handles encoding, splitting, and analysis, then returns the result.
The problem was cost and latency. The larger the file, the higher the server cost, and the longer the wait. It felt wasteful to route even simple preprocessing or analysis tasks through a server.
“What if we could handle this on the client side?” That idea was the starting point for evaluating WASM.
Can WASM Actually Handle Video Processing in the Browser?
The short answer: yes. And more than you’d expect.
Using ffmpeg.wasm — FFmpeg compiled to WebAssembly — all of the following become possible directly in the browser:
No server. Inside the browser. The user’s file never leaves their device. From a privacy standpoint, that’s a genuinely powerful advantage.
What I Found in Practice: Potential and Limits
The Potential
Performance was better than expected. For short clips, encoding ran at roughly 2–5x slower than native — which sounds bad until you remember this is running inside a browser tab. The fact that it works at all is impressive.
Video analysis in particular ran close to real-time. Being able to extract metadata instantly without uploading the file to a server is something you can put directly into a better UX.
The Limit: Memory
The biggest constraint was memory.
WebAssembly memory in the browser has hard limits. Feed it a large video file without care and you’ll hit an out-of-memory crash. I experienced this firsthand — loading a 1GB file directly killed the tab.
The solution is chunked processing.
// Split the file into chunks and process sequentially
const CHUNK_SIZE = 64 * 1024 * 1024; // 64MB
const chunks = [];

for (let offset = 0; offset < file.size; offset += CHUNK_SIZE) {
  const chunk = file.slice(offset, offset + CHUNK_SIZE);
  chunks.push(chunk);
}

// Write each chunk to the buffer and process
for (const chunk of chunks) {
  const buffer = await chunk.arrayBuffer();
  // WASM processing here
}
Splitting large files into chunks and writing them to the buffer sequentially sidesteps the memory issue. The tradeoff is added implementation complexity — but it’s manageable.
The WASM Ecosystem in 2026: Where Things Stand
While doing this evaluation, I took a broader look at the ecosystem. A few things stood out.
WASI Maturation
WebAssembly System Interface has grown up. WASM now runs beyond the browser — in server and edge environments. Cloudflare Workers and Fastly Compute both support it. The perception of WASM as a browser-only technology is shifting.
Component Model Standardization
A standard for WASM modules written in different languages to communicate with each other is taking shape. Previously, connecting a Rust module with a Go module was painful. It’s significantly better now.
Improved Toolchains
Rust’s wasm-pack, AssemblyScript, and Emscripten have all improved substantially in usability. Compared to two or three years ago, the barrier to entry feels less than half of what it was.
When Should You Actually Use WASM?
After wrapping up the evaluation, here’s where I landed.
Use it when:
Skip it when:
The core principle: reach for WASM when JavaScript starts feeling slow. Building with WASM from the start is likely over-engineering.
Final Thoughts
By 2026, WASM has crossed the line from “a technology worth watching” to “a technology people are actually using.”
Encoding video in the browser, running ML inference at the edge, handling encryption without a server — these are real things now.
That said, the memory constraints and other limitations are still real, and WASM isn’t the answer to every problem. Think of it as a tool you reach for when JavaScript isn’t enough. That’s WASM’s position in 2026.
Your AI agent can analyze market data, execute trading strategies, and make complex financial decisions. But when it comes time to actually move money or execute a trade, it hits a wall — it can’t touch the blockchain.
This isn’t just a technical limitation; it’s a fundamental barrier to building autonomous AI systems. Every transaction requires manual intervention, breaking the agent’s autonomy and creating bottlenecks in automated workflows. Whether you’re building with Claude MCP, LangChain, or any other AI framework, the story is the same: your agent is smart but can’t transact.
The Missing Piece: Secure Agent Wallets
The blockchain world is full of opportunities for AI agents — from automated DeFi strategies to paying for API calls with crypto. But giving an AI agent direct access to private keys is like handing your credit card to a black box. You need something more sophisticated: a wallet service that gives agents transactional capabilities while maintaining human oversight and security controls.
This is where Wallet-as-a-Service for AI agents comes in. Instead of exposing raw private keys, you give agents API access to wallet functions through a secure, policy-controlled layer. The agent can request transactions, but they flow through validation, approval, and monitoring systems before touching the blockchain.
WAIaaS: The Self-Hosted Solution
WAIaaS is an open-source, self-hosted wallet service designed specifically for AI agents. With 14 DeFi protocol providers integrated and 45 MCP tools for AI agent integration, it bridges the gap between AI decision-making and blockchain execution.
The architecture is built around a 7-stage transaction pipeline that ensures security without sacrificing functionality. When your agent wants to make a transaction, it flows through validation, authentication, policy checks, optional delays, execution, confirmation, and monitoring stages.
Getting Started in One Command
The fastest way to see WAIaaS in action is with Docker:
# Clone and start — that's it
git clone https://github.com/minhoyoo-iotrust/WAIaaS.git
cd WAIaaS
docker compose up -d
For even simpler deployment, use the auto-provision mode:
docker run -d
  --name waiaas
  -p 127.0.0.1:3100:3100
  -v waiaas-data:/data
  -e WAIAAS_AUTO_PROVISION=true
  ghcr.io/minhoyoo-iotrust/waiaas:latest

# Retrieve auto-generated master password
docker exec waiaas cat /data/recovery.key
The auto-provision mode generates a secure master password and stores it in a recovery file, so you can get up and running without manual configuration.
Docker Compose Configuration
For production deployments, WAIaaS provides a complete Docker Compose setup:
services:
  daemon:
    image: ghcr.io/minhoyoo-iotrust/waiaas:latest
    container_name: waiaas-daemon
    ports:
      - "127.0.0.1:3100:3100"
    volumes:
      - waiaas-data:/data
    environment:
      - WAIAAS_DATA_DIR=/data
      - WAIAAS_DAEMON_HOSTNAME=0.0.0.0
    env_file:
      - path: .env
        required: false
    restart: unless-stopped
    healthcheck:
      test: ["CMD", "curl", "-f", "http://localhost:3100/health"]
      interval: 30s
      timeout: 5s
      start_period: 10s
      retries: 3

volumes:
  waiaas-data:
    driver: local
This configuration includes health checks, persistent data storage, and automatic restarts — everything you need for a production wallet service.
Security Architecture That Actually Works
WAIaaS implements a 3-layer security model: session authentication, time delays with approval mechanisms, and continuous monitoring with kill switches. This isn’t security theater — it’s a practical system that lets agents operate autonomously while keeping humans in control of the important decisions.
The system supports 3 authentication methods: masterAuth using Argon2id for administrative access, ownerAuth using Sign-in with Ethereum/Solana for wallet owners, and sessionAuth using JWT HS256 for AI agents. Each layer serves a specific purpose in the security model.
Policy enforcement follows a default-deny approach. Transactions are blocked unless explicitly allowed through ALLOWED_TOKENS or CONTRACT_WHITELIST configurations. This means your agent can only interact with pre-approved tokens and contracts, preventing unauthorized transactions.
Session management includes configurable TTL, maximum renewals, and absolute lifetime limits. You can set up sessions that last hours for active trading or days for ongoing automation, with the flexibility to revoke access instantly if needed.
Multi-Chain DeFi Integration
The platform supports 2 chain types across 15 networks, with deep integration into major DeFi protocols. The DeFi protocols include Aave v3 for lending, Jupiter and 0x for swapping, Lido and Jito for liquid staking, and LI.FI and Across for cross-chain bridging.
For more specialized use cases, WAIaaS includes Hyperliquid integration for perpetual futures and spot trading, Polymarket prediction market trading integration, and Kamino for Solana DeFi strategies. This broad protocol support means your agents can execute sophisticated DeFi strategies without you having to build individual integrations.
The system handles 7 transaction types in its core schema: Transfer, TokenTransfer, ContractCall, Approve, Batch, NftTransfer, and ContractDeploy. Whether your agent needs to make simple transfers or deploy complex smart contracts, the API provides consistent interfaces.
AI Agent Integration Made Simple
WAIaaS provides multiple integration paths depending on your AI framework. For Claude Desktop users, the MCP integration offers 45 tools that your agents can use directly. Tools range from basic wallet functions like get-balance and send-token to advanced capabilities like hyperliquid trading and polymarket predictions.
For other frameworks, the REST API exposes 39 route modules covering everything from transaction simulation to DeFi position monitoring. The TypeScript SDK and Python SDK provide programmatic access with proper type definitions and error handling.
The OpenClaw plugin offers 17 sessionAuth tools specifically designed for external AI agent frameworks, making integration straightforward regardless of which AI platform you’re using.
Advanced Features for Production Use
Beyond basic wallet functions, WAIaaS includes several advanced features that production AI agents need. The dry-run API lets agents simulate transactions before execution, preventing costly mistakes and allowing for strategy validation.
Gas conditional execution means transactions only execute when gas prices meet your specified thresholds — perfect for cost-sensitive automated strategies. The x402 HTTP payment protocol support enables AI agents to pay for API calls automatically, creating truly autonomous economic agents.
NFT support covers both EVM standards (ERC-721/ERC-1155) and Solana’s Metaplex with metadata caching. Incoming transaction monitoring provides real-time notifications for deposits, so your agents can react immediately to new funds or payments.
For scenarios requiring human oversight, WalletConnect integration allows wallet owners to approve agent transactions through familiar mobile interfaces. The system also supports ERC-4337 Account Abstraction with smart accounts and gasless transactions.
Getting Your Agent Connected
Here’s how to get your AI agent transacting in under 5 minutes:
For Claude Desktop users, the setup is particularly straightforward:
npm install -g @waiaas/cli
waiaas init                        # Create data directory + config.toml
waiaas start                       # Start daemon (sets master password on first run)
waiaas quickset --mode mainnet     # Create wallets + MCP sessions in one step
The quickset command generates MCP configuration JSON that you can paste directly into Claude’s desktop config, giving your Claude agent immediate access to wallet functions.
Production Deployment Considerations
For production deployments, consider using the secrets overlay for secure password management:
# Create secret files
mkdir -p secrets
echo "your-secure-password" > secrets/master_password.txt
chmod 600 secrets/master_password.txt

# Deploy with secrets overlay
docker compose -f docker-compose.yml -f docker-compose.secrets.yml up -d
The system includes comprehensive logging and monitoring through 611+ test files across all packages, ensuring reliability in production environments. Health checks are built into the Docker configuration, and the service includes automatic restart policies.
What’s Next
You now have the foundation to build AI agents that can actually transact on blockchains. Start with the Docker deployment to see it in action, then explore the DeFi integrations and advanced features that match your use case.
Ready to give your AI agent a wallet? Check out the complete setup guide on GitHub or visit waiaas.ai for more examples and documentation.
Docker build failed. The error is on line 47 of 120. Lines 1-46 are cached layer confirmations. Lines 48-120 are cleanup output. Your AI reads all 120 lines to find the one error.
Before: Failed Docker Build
[+] Building 52.1s (8/12)
 => [internal] load build definition from Dockerfile                    0.0s
 => [internal] load metadata for docker.io/library/node:20-alpine      1.1s
 => CACHED [build 1/6] FROM docker.io/library/node:20-alpine@sha256... 0.0s
 => CACHED [build 2/6] WORKDIR /app                                    0.0s
 => CACHED [build 3/6] COPY package*.json ./                           0.0s
 => [build 4/6] RUN npm ci --production                               38.2s
 => [build 5/6] COPY . .                                               0.3s
 => ERROR [build 6/6] RUN npm run build                                12.5s
------
 > [build 6/6] RUN npm run build:
#12 2.341 > [email protected] build
#12 2.341 > tsc && next build
#12 4.892
#12 4.892 src/pages/index.tsx(15,3): error TS2322: Type 'string' is not assignable to type 'number'.
#12 4.892
------
Dockerfile:14
--------------------
  13 |     COPY . .
  14 | >>> RUN npm run build
  15 |
--------------------
ERROR: failed to solve: process "/bin/sh -c npm run build" did not complete successfully: exit code: 1
23 lines. The error is TS2322: Type 'string' is not assignable to type 'number' in src/pages/index.tsx:15.
After: Through ContextZip
ERROR [build 6/6] RUN npm run build
src/pages/index.tsx(15,3): error TS2322: Type 'string' is not assignable to type 'number'.
ERROR: failed to solve: exit code: 1
💾 contextzip: 1,847 → 198 chars (89% saved)
Cached layers stripped. Build step numbers stripped. The error, its source location, and the final failure status preserved. 89% reduction.
ContextZip recognizes Docker-specific patterns: CACHED lines are noise, ERROR lines are signal, layer hashes are noise, Dockerfile references with >>> are signal.
cargo install contextzip
eval "$(contextzip init)"
GitHub: github.com/contextzip/contextzip
Part of the ContextZip Daily series. Follow for daily tips on optimizing your AI coding workflow.
Install: npx contextzip | GitHub: jee599/contextzip