PlayStation Store’un dinamik fiyatlandırma sistemi Türkiye’ye de geldi

PlayStation Store

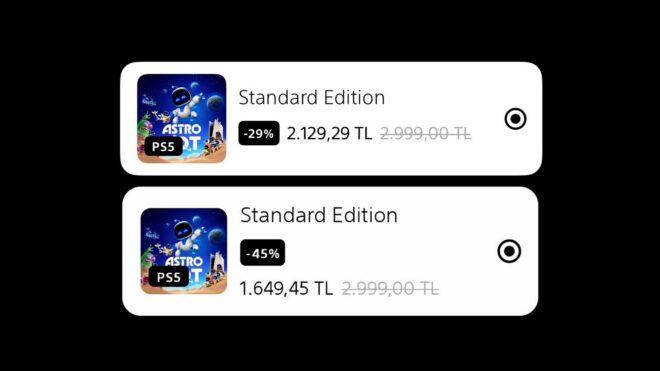
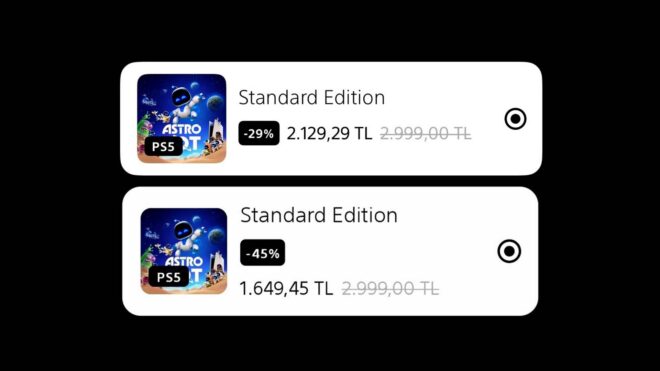
PlayStation StoreSony, kullanıcılar tarafından yapılan paylaşımlara göre PlayStation Store’un oyunlara yönelik dinamik fiyatlandırma sistemini Türkiye’ye de getirdi. Bu altyapıda oyunlara uygulanan indirim seviyeleri kişiden kişiye değişiyor. Örneğin, Türkiye’deki bazı kullanıcılar şu anda “Astro Bot” oyununda yüzde 45, bazı kullanıcılar ise yüzde 25 indirim görüyor. Sony, çok fazla öne çıkarmadığı bu konuda Kasım 2025’ten bu yana küresel olarak testler gerçekleştiriyor. Dinamik fiyatlandırmayı bir süredir kendi büyük yapımlarında da test eden şirket, bu altyapı nedeniyle tepki çekiyor çünkü oldukça adaletsiz bir durum oluşuyor. İndirim oranının tam olarak neye göre belirlendiği henüz bilinmezken, çok sık oyun satın alan kişilere de yüksek indirim oranlarının uygulandığı görülüyor. Yani şirket yüksek indirim oranlarıyla az oyun satın alan kişilerin ilgisini çekmeye çalışmıyor. Bana da % 45 yapmış, hemen aldım… 😄 pic.twitter.com/opd0qMPXYx — Ahmet Demiroğlu (@a__demiroglu) March 25, 2026

PlayStation Store’un dinamik fiyatlandırma sistemi Türkiye’ye de geldi yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Container monitoring just got broader: Docker Swarm and Podman support is here

Docker Swarm monitoring

Container infrastructure has never been more diverse. Some teams rely on Docker Swarm to orchestrate services at scale. Others have moved to Podman because it doesn’t require a root daemon, which matters in regulated or zero-trust environments. In practice, many organizations run both.

Until now, getting full observability across these environments meant stitching together multiple tools. We’re closing that gap with native support for Docker Swarm and Podman monitoring in Applications Manager!

Docker Swarm monitoring: Visibility from cluster to container

Running a Swarm cluster at scale means managing services across many nodes simultaneously. In a cluster of any real size, a problem that goes unnoticed for even a few minutes can affect more services than expected.

Applications Manager’s Docker Swarm monitor gives a multi-tier view of your entire cluster, from high-level node health down to per-container resource consumption, without requiring agents on your hosts. It connects via the Swarm REST API and is straightforward to configure.

Docker Swarm monitoring

Podman monitoring: Security-first observability

Podman’s daemonless, rootless architecture is its defining strength and its main observability challenge. Traditional monitoring tools that depend on daemon access or privileged APIs don’t fit the model. The Podman monitor in Applications Manager is built to work within Podman’s security constraints rather than around them.

“Rootless containers in production deserve the same observability as anything else in your stack.”

Applications Manager connects via the Podman REST API and collects metrics without requiring elevated permissions, keeping the security setup your team put in place intact.

Podman monitoring

Monitoring coverage that keeps up with how you build

Container infrastructure rarely follows a single path. Some teams standardize on Swarm for orchestration at scale. Others choose Podman because it doesn’t require a persistent daemon, which matters in environments with strict security requirements. Many teams end up running both for different workloads within the same organization.

Applications Manager now monitors both natively, without needing separate tools for each. As container strategies evolve and architectural choices multiply, observability coverage can now keep pace.

How to get started

Docker Swarm and Podman monitoring are available in the latest version of Applications Manager. Upgrade your console to enable both, or download a 30-day, free trial to explore now!

The Hidden Cost of Dev Environments: Why Your Staging Cluster Runs 24/7 (And How to Stop It)

The Hidden Cost of Dev Environments: Why Your Staging Cluster Runs 24/7 (And How to Stop It)

The Bill That Nobody Owns

Most cloud cost conversations start with production. The load balancers, the database replicas, the CDN egress that’s where engineering leadership looks when the AWS bill arrives. Staging, QA, and developer environments sit below the fold. Someone provisioned them, and they’ve been running ever since.

This is where the hidden cost lives.

Across mid-size engineering organizations, non-production environments consume 30-45% of total cloud spend. At a company paying $200,000/month for cloud, that’s $60,000-$90,000 going toward clusters that developers use for 35% of each working day and not at all on nights and weekends.

The math is uncomfortable. A typical 10-node staging cluster on EKS costs around $12,000/month at on-demand pricing. That cluster sits idle for roughly 128 hours out of every 168-hour week: nights, weekends, and the gaps between active testing sessions. You’re paying full price for 76% idle time.

Nobody owns this number. Developers don’t see it on their sprint board. Platform teams didn’t budget for it. Finance sees it in the cloud bill but has no way to attribute it to a team or a decision. It persists because the cost of noticing it is higher than the cost of ignoring it until a FinOps review makes it impossible to ignore.

Environment Type Typical Monthly Cost % of Time Active Effective Cost per Active Hour
Production $90,000 100% $125/hr
Staging $12,000 35% $48/hr (billed) vs $17/hr (actual use)
QA / Integration $8,000 25% $27/hr (billed) vs $7/hr (actual use)
Developer sandboxes $6,000 20% $8/hr (billed) vs $1.60/hr (actual use)

Why Clusters Never Sleep

The root cause isn’t laziness. It’s the way non-production environments get provisioned.

When a team stands up a staging cluster, they copy the production configuration. Same instance types, same node count, same availability expectations. The mental model is “staging should behave like production so we can catch production issues.” That’s correct. But it leads to a silent assumption: staging should run like production always on, never suspended.

Kubernetes doesn’t help. There is no native kubectl suspend namespace command. The platform has no built-in concept of an environment lifecycle. If you want to stop paying for idle pods, you either delete the namespace (and rebuild it for every test run) or scale every deployment to zero replicas manually. Neither is ergonomic. So teams don’t bother.

Environment sprawl makes it worse. A 50-person engineering team typically has one staging cluster per team, plus a shared integration environment, plus individual developer namespaces that were created for a sprint and never cleaned up. No one owns the decommissioning process, so environments accumulate.

The result is a cluster billing continuously for workloads that are actively used for a fraction of each week.

What 65 Hours of Idle Compute Costs You

Let’s build the actual math.

A typical EKS staging cluster for a 30-engineer team runs 10 nodes: 8x m5.xlarge for application workloads and 2x m5.2xlarge for data-adjacent services. At us-east-1 on-demand pricing, that’s approximately $0.192/hr and $0.384/hr respectively.

Monthly compute cost (720 hours): $11,612.

Now count the hours developers are actually using it. Business hours in a month: roughly 160 hours. Subtract meetings, code review, non-testing work. Developers are actively hitting staging for perhaps 56 hours per month roughly 7.8% of the month.

The remaining 664 hours are idle. The cluster is sitting at 8-12% CPU utilization, warming nobody’s requests, validating no deployments, serving no purpose except preserving the state of the last test run.

If you suspended that cluster outside business hours nights (6pm-9am) and weekends you’d eliminate roughly 450 hours of monthly billing. At the same pricing, that’s a $7,300/month reduction on that one cluster. One cluster.

Cluster Size Always-On Monthly Cost Suspended Monthly Cost Annual Savings
Small (5 nodes, m5.large) $2,628 $985 $19,716
Medium (10 nodes, m5.xlarge) $11,612 $3,484 $98,736
Large (20 nodes, m5.2xlarge) $55,296 $16,589 $463,284

A 200-person engineering organization with 8-12 non-production clusters of mixed sizes can realistically recover $500,000-$1,200,000 annually. That’s not a rounding error. It’s a headcount decision.

The DIY Trap: Why CronJob Scaling Breaks

The first instinct is to write a CronJob. Scale all deployments in the staging namespace to zero replicas at 6pm. Scale them back to one at 9am. Cost: a few hours of platform engineering time. Done.

This works for exactly one sprint.

The first problem is stateful workloads. Databases, message queues, and caches don’t scale to zero cleanly. Postgres replicas lose WAL position. Kafka consumers lose partition assignment. Redis clusters need a clean shutdown sequence. A naive scale-to-zero CronJob corrupts state and breaks the next morning’s test run. The platform team gets paged. The CronJob gets disabled.

The second problem is developer friction. A developer who pushes a hotfix at 8pm and needs to validate it in staging hits a scaled-to-zero cluster. They wait 10 minutes for pods to restart. Then they need the database to finish recovery. Then the integration service needs to reconnect. By the time the environment is functional, they’ve context-switched twice and are angry at the platform team. The fix they make is to annotate their namespace with suspend: never and tell everyone on their team to do the same.

The third problem is no observability. The CronJob runs. Did it work? Are all deployments actually at zero? Did any fail to scale? Nobody knows until someone checks manually and nobody does.

CronJob-based suspension fails because it treats all workloads identically, ignores developer workflows, and provides no feedback loop. The platform team abandons it. The clusters run 24/7 again.

Suspension That Developers Actually Tolerate

A suspension system that engineers actually keep enabled needs three properties.

First, wake-on-demand. When a developer pushes code, the environment should start waking before they open the PR. When a test pipeline triggers a staging deploy, the cluster should already be coming up. The developer should not wait for a manual action and should not notice the suspension happened. A smarter approach is to hook into the CI/CD event stream: a push event triggers a wake signal before the deploy job starts, so warm-up happens in parallel with the build.

Second, stateful-aware shutdown. The suspension system needs to understand which workloads have shutdown dependencies. Databases get a graceful shutdown sequence. Message queue consumers drain their partitions. Only after dependent services confirm clean state does the orchestrator scale the primary workload to zero. This eliminates the corruption scenarios that kill CronJob-based approaches.

Third, team-level controls with guardrails. Individual teams should be able to configure their own suspension schedules a team doing a late-night release can disable suspension for 24 hours without filing a ticket. But guardrails prevent marking everything as never-suspend. Production-adjacent environments require approval. Cost impact is shown before the override takes effect.

The warm-up window matters too. A cluster that takes 18 minutes to become ready after a push is still a friction source. The target is under 4 minutes for pod readiness after a wake trigger achievable with pre-warmed node pools and readiness probe tuning.

The Numbers After You Ship It

We measured adoption and cost impact across implementations that met the friction bar above.

Adoption rate when developers notice the environment is absent: 23%. Adoption rate when the environment wakes automatically before they need it: 91%. The difference is entirely friction. Remove the friction, and most developers don’t object to suspension at all they never see it.

Cost reduction on non-production spend: 62% on average. Some teams see more (those with large weekend-heavy idle patterns). Some see less (teams with global distribution across timezones that genuinely use environments around the clock). The 62% figure holds for single-region teams with standard business-hours development patterns.

For a 200-person org with $26,000/month in non-production compute:

Metric Before After
Monthly non-prod cost $26,000 $9,880
Annual savings — $193,440
Active hours billed 720/month 274/month
Developer complaints about environment availability 12/month (slow clusters) 2/month (warm-up wait)
Environment suspension adoption 0% 91%

The remaining $9,880 covers the hours environments are genuinely active plus the PVC storage for suspended clusters. Storage is cheap. Idle compute is not.

Non-production environments are a solvable problem. The spending persists because it’s invisible and nobody is accountable for it
not because eliminating it is technically hard. The first step is making the cost visible. The second is suspending environments in a way developers won’t bypass.

The clusters that run 24/7 don’t have to.

Stop Crashing Your Browser: How I Built a Server-Side Engine to Generate 1 Million SQL Rows Instantly

Every full-stack developer has been there. You just finished designing a beautiful new database schema. Now, you need to test it with a massive amount of data to see if your complex JOIN queries hold up or if your pagination breaks under load.

So, what do you do? You probably spend the next 30 minutes writing a throwaway script using a library like Faker to generate dummy users.

The Old Way: Memory Leaks and Freezing Tabs
Usually, developers try to generate this data locally or using client-side JavaScript tools. The code looks something like this:

JavaScript
// The classic way that will crash your browser tab
const massiveDataset = [];
for (let i = 0; i < 1000000; i++) {
massiveDataset.push({
id: i,
name: generateRandomName(),
email:
user${i}@test.com
});
}

// 💥 Result: Browser Tab Froze / Aw, Snap! Error
If you need 100 rows, JS is fine. But if you need to generate 1 million rows, your local server will throw a “Memory size exhausted” error, or your browser tab will completely freeze. Client-side processing simply cannot handle enterprise-level data generation efficiently.

⚡ The Solution: Offloading the Heavy Lifting to the Server
I got tired of my browser freezing every time I needed to test database performance. So, I built The Data Forge — an enterprise-grade dummy data generator with a powerful backend engine designed to do the heavy lifting for you.

Instead of crashing your machine, Data Forge processes the massive loops securely on my optimized server infrastructure.

Here is why a server-side approach completely changes the workflow:

  1. Zero Impact on Your RAM
    By shifting the generation logic to a highly optimized backend architecture (built with PHP), your browser does zero work. You simply define the columns (Names, UUIDs, Dates, Phone Numbers, etc.), enter the number of rows, and hit generate. The server handles the massive arrays and streams the result back to you.

  2. Lightning Fast Streaming & Exports
    Instead of holding 1 million rows in the server’s memory (which would crash the server too), the backend engine dynamically streams the generated data directly into a downloadable file. You get your .sql dump, .csv, or .json file instantly without waiting for a loading screen.

  3. Complex & Realistic Data Patterns
    Because we have the raw power of the server, we can run complex randomization algorithms to generate highly realistic, relational data (like matching city names with correct zip codes) much faster than a standard client-side script.

🛠️ Try It Yourself (No Sign-up Required)
As a developer, I hate paywalls and forced sign-ups just to use a utility. That is why I made The Data Forge completely free to use. You get raw server power, zero bloat, and instant downloads.

You can stop writing fake data scripts and let my server do the hard work for your next test database here:
👉 Try Data Forge on https://zlvox.com/tools/data-forge

Whether you need 500 rows for a quick UI mock or 1 million rows to test your MySQL indexing, this tool will save you hours of manual work.

Have you ever crashed your browser trying to loop too much data? Let me know your worst memory-leak story in the comments below! 👇

Asset-Based Data Orchestration: Lessons from Building a Multi-State Social Data Platform

Asset based data orchestration high level architecture

Building reliable data platforms rarely fails because of scale alone.
More often, reliability collapses under heterogeneity: multiple data providers, inconsistent schemas, partial updates, and unclear ownership.

While building a multi-state social data platform ingesting resource data from dozens of organizations, we discovered that reliability is not a property of pipelines. It is a property of data artifacts and their relationships.

1. Why Reliability Becomes a Systems Problem at Scale

The accompanying essay frames trust as something earned through consistent system behavior under real-world pressure. What that framing leaves implicit, but what became unavoidable in practice, is that reliability stops being a property of individual components very early on. Once multiple organizations, jurisdictions, and publishing surfaces are involved, reliability becomes an emergent property of the entire system.

For us, this meant that no single pipeline, connector, or database could be made “reliable enough” in isolation. Failures were rarely total. They were partial, localized, and often silent. The engineering challenge was not preventing all failure, but designing the system so that failures were isolated, detectable, and explainable.

That requirement drove nearly every architectural decision that followed.

2. System Overview

Technically, the platform ingests social service resource data from independent organizations operating across multiple U.S. states. Each organization exposes data via a different source system (for example iCarol, WellSky, VisionLink, RTM), with varying schemas, update cadences, and quality guarantees.

At a high level, the system consists of:

  1. Writers – per-tenant ingestion and transformation projects that:

    • Fetch raw data from source systems via connector adapters
    • Persist raw data into Snowflake source schemas
    • Normalize and standardize data via DBT
    • Apply enhancements such as geocoding or translations
  2. Readers – publisher processes that:

    • React to completed writer runs, either bulk or incremental
    • Publish curated artifacts to OpenSearch, MongoDB, and optionally Postgres

Snowflake acts as the system of record for intermediate and normalized datasets. Dagster coordinates the execution and materialization of data assets. DBT is used explicitly for set-based transformations, not orchestration.

Scale is not extreme in raw volume, but complexity is high: dozens of tenants, hundreds of tables per tenant, and frequent partial updates.

High-Level Architecture

The following diagram illustrates the writer → Snowflake → DBT → asset orchestration → readers pattern.

Asset based data orchestration high level architecture

The platform is designed around asset lineage and normalization contracts, not pipelines.

3. Source Heterogeneity as the Dominant Constraint

The hardest constraint was not throughput or storage. It was heterogeneity.

Each data provider differed along several axes simultaneously:

  • Schema shape: even when nominally “the same” entities existed, fields varied
  • Semantics: identical fields often meant subtly different things
  • Update cadence: some sources updated continuously, others weekly or ad hoc
  • Quality guarantees: missing fields, stale records, or partial exports were common

Early on, we underestimated how strongly these differences would dominate system design. Attempting to treat ingestion as a uniform, pipeline-shaped process led to brittle assumptions and cross-tenant coupling.

The system only became manageable once heterogeneity was treated as fundamental, not incidental.

4. Normalization (HSDS, SDOH or Equivalent) as an Architectural Contract

Normalization into an HSDS-like model was not implemented as a downstream convenience. It became an architectural contract.

All downstream consumers, internal and external, implicitly rely on the guarantees of the normalized model: stable fields, predictable relationships, and documented semantics. That meant normalization could not be “best effort” or delayed until the end of a pipeline.

In practice:

  • Raw source data is written verbatim into Snowflake source schemas
  • DBT ELT projects transform this raw data into standardized intermediate models
  • DBT STAGE projects apply tenant-specific adaptations while preserving the contract

This separation made it explicit where interpretation happens. If a field is wrong in the normalized model, the question becomes which contract was violated, not “what broke in the pipeline”.

5. What We Got Wrong Initially

Several early assumptions did not survive contact with reality.

Pipeline-first thinking

We initially modeled work as long-running jobs. This obscured which intermediate datasets were durable, reusable, or safe to depend on. Debugging often meant rerunning more than necessary.

Manual validation

Data quality checks lived outside the orchestration layer. Engineers and analysts manually inspected outputs, which worked at small scale but failed under concurrency and time pressure.

Shared failure domains

Multiple tenants often shared execution paths. A failure in one tenant’s ingestion could block or delay others, even when their data was unrelated.

None of these issues were catastrophic individually. Together, they made reliability depend on human attention.

6. Transitioning to Asset-Based Data Orchestration with Dagster

The shift to asset-based orchestration was driven less by tooling preference and more by a change in mental model.

Instead of asking “what jobs should run?”, we started asking:

  • What data artifacts must exist?
  • What do they depend on?
  • How fresh do they need to be?
  • What constitutes success or failure for this artifact?

Dagster assets provided a way to encode those questions directly.

A simplified example from a writer project shows how DBT models are treated as assets rather than opaque steps:

# writer-xyz/assets.py (excerpt)
from dagster_dbt import load_assets_from_dbt_project

dbt_elt_assets = load_assets_from_dbt_project(
    project_dir="dbt_elt",
    profiles_dir="dbt_elt",
)

This does not explain how DBT runs. It declares that the resulting tables are first-class assets with lineage and state.

Once assets replaced jobs as the primary abstraction, freshness, lineage, and partial recomputation became explicit rather than implicit.

7. Partitioning for Failure Isolation

Partitioning was critical for isolating failures.

We partitioned primarily along tenant and state boundaries, not time. This reflected operational reality: data issues almost always affected a single organization or region.

In Dagster terms, this meant:

  • Separate writer projects per tenant
  • Independent schedules and sensors
  • Asset materializations scoped to a tenant’s data domain

A failure in one writer no longer blocked publishing for others. More importantly, remediation could be targeted and auditable.

8. Data Quality Embedded in the Asset Graph

Data validation moved into the asset graph itself.

Instead of post-hoc checks, validations became explicit dependencies. If a validation asset failed, downstream assets simply did not materialize.

An example pattern used across writers:

@asset
def validate_staging_tables(staging_tables):
    assert staging_tables.count_missing_ids() == 0

This is intentionally simple. The key point is not the check itself, but that failure is structural. The system records that an expected artifact does not exist, rather than silently publishing bad data.

This shifted failure detection earlier and reduced the blast radius of errors.

9. Operational Outcomes

Day-to-day operations changed in several concrete ways:

  • On-call work shifted from rerunning pipelines to inspecting asset lineage
  • Partial backfills became routine rather than exceptional
  • Publishing delays were easier to attribute to specific upstream causes
  • New tenants could be added without increasing shared operational risk
  • None of this eliminated operational effort. It made that effort more focused and less reactive.

10. Open Trade-offs and Unresolved Questions

Some challenges remain unresolved:

  • Cross-tenant schema evolution still requires coordination and discipline
  • Observability across Snowflake, DBT, Dagster, and downstream stores is fragmented
  • Cost attribution at the asset level is still coarse-grained
  • Human review remains necessary for certain semantic validations

With more time, we would invest earlier in unified observability and more formal schema versioning.

11. Why These Lessons Matter Beyond This Platform

These lessons are not unique to this system.

Any platform operating in civic tech, govtech, or environmental data shares similar constraints: multiple data producers, uneven quality, and real-world consequences for failure.

The core takeaway is not “use asset-based orchestration”, but treat data artifacts as obligations. Once that shift happens, many architectural decisions become clearer.

Reliability stops being something you hope for and becomes something you can reason about.

Final Thoughts

The biggest lesson from this platform was not about any particular tool. It was about how we model the system itself.

Once data artifacts became the core abstraction, many reliability problems became easier to reason about. Failures became visible, dependencies became explicit, and operational work shifted from firefighting pipelines to managing data contracts.

For data platforms operating across heterogeneous sources, this shift can be the difference between a system that merely runs – and one that can be trusted.

FAQ

What is asset-based data orchestration?

Asset-based data orchestration treats data artifacts (tables, datasets, models) as the primary units of orchestration instead of pipelines or jobs. Systems like Dagster allow teams to define dependencies between assets, enabling better lineage tracking, partial recomputation, and failure isolation.

Why is asset-based orchestration useful for complex data platforms?

In large systems with many data producers and consumers, failures are rarely binary. Asset-based orchestration makes dependencies explicit, allowing teams to:

  • isolate failures
  • recompute only affected datasets
  • track lineage across transformations
  • enforce data quality checks before publishing

How does Dagster differ from traditional pipeline orchestrators?

Traditional orchestrators schedule jobs or workflows. Dagster emphasizes data assets and lineage. This enables better visibility into:

  • what datasets exist
  • what produced them
  • what depends on them
  • whether they meet freshness or quality requirements

When should teams adopt asset-based orchestration?

Asset-based orchestration becomes particularly valuable when systems have:

  • many data sources
  • heterogeneous schemas
  • multiple downstream consumers
  • partial or incremental updates
  • strict reliability requirements

These conditions are common in multi-tenant data platforms and civic tech systems.

Does asset-based orchestration replace tools like DBT?

No. Asset-based orchestration complements transformation tools like DBT. In many architectures:

  • DBT performs set-based transformations
  • Dagster manages asset lineage, dependencies, scheduling, and validation

This separation keeps orchestration and transformation responsibilities clear.

Most Developers Can Build Apps — But DevOps Breaks Them

Most Developers Can Build Apps — But DevOps Breaks Them

If you’ve built a side project or SaaS before, you probably experienced this:

Your app works perfectly on localhost.

But the moment you deploy it, everything starts breaking.

• Docker container fails
• Server crashes
• Environment variables missing
• CI/CD pipeline errors
• Random 500 errors in production

Suddenly debugging infrastructure takes longer than building the feature itself.

And for many developers who are not DevOps specialists, this part becomes frustrating.

The Real DevOps Struggles Developers Face

From my experience and conversations with other developers, the most common problems are:

  1. Server Errors With No Clear Cause

You open logs and see errors like:

502 Bad Gateway
Connection refused
Service unavailable

But figuring out the actual root cause can take hours.

  1. Missing DevOps Setup

Many projects are missing important infrastructure pieces:

• Dockerfile
• CI/CD pipeline
• health checks
• monitoring
• logging

Developers usually realize this only after deployment fails.

  1. Debugging Production Issues

When something breaks in production, developers often:

• SSH into servers
• check logs manually
• restart services
• guess possible fixes

This process is slow and stressful.

What If Debugging DevOps Was Faster?

Recently I started experimenting with an idea.

A tool that can:

• monitor server health in real time
• analyze logs when errors happen
• suggest commands to fix problems
• scan repositories for missing DevOps setup

Instead of spending hours investigating issues manually.

Example Scenario

Imagine this situation:

Your server suddenly crashes.

Instead of manually searching logs, the system detects something like:

Error detected: Nginx 502 Bad Gateway
Possible cause: backend service not running
Suggested fix: restart backend service

And gives a command like:

sudo systemctl restart backend.service

You copy, paste, and the server is back online.

Another Useful Feature: Repo DevOps Analysis

Another experiment I’m exploring is analyzing a repository and checking if important DevOps pieces are missing.

For example:

DevOps readiness score: 45%

Missing components:
• Dockerfile
• CI/CD pipeline
• health monitoring

This can help developers make projects production ready faster.

Curious How Others Handle DevOps

I’m curious how other developers approach infrastructure problems.

Do you usually:

• set up full monitoring tools like Prometheus or Datadog?
• debug issues manually through logs?
• keep infrastructure minimal for side projects?

Would love to hear what your DevOps workflow looks like.

How Don Norman’s framework applies to sustainable UX and digital product design

Don Norman coined the term “User Experience.”

Then he spent his later career arguing that designers have been solving the wrong problems.

In Design for a Better World (2023), he lays out a framework called Circular Design. Here’s the core of it:

The world runs on a linear model:
Take raw materials → Make products → Discard as waste.

Waste happens at every stage. Not just at the end.
Half of all waste is produced before a product is even manufactured: in mining, refining, and transportation alone.

The materials we design with take 20 to 500 years to biodegrade.
More than 1 million species are now threatened with extinction.
84% of global energy still comes from fossil fuels.

These are not environmental stats. These are design consequences.

Norman defines three types of planned obsolescence:
→ Breakdown: components fused so repair is impossible
→ Progress: new standards that make old products incompatible
→ Fashion: cosmetic changes that make the old feel outdated

And three principles of circular design to counter them:
→ Treat waste and pollution as design flaws
→ Design products to last, to be repaired, to be reused
→ Design so end-of-life materials regenerate, not degrade

These principles apply to digital products:

An app that drops OS support to push upgrades ?
That’s planned obsolescence through progress.

A redesign that forces users to relearn everything ?
That’s the digital equivalent of a glued-together coffee cup.

Features that pile up until the only fix is a full rebuild ?
That’s take-make-waste applied to software.

It is too late to stop the damage, but it is not too late to slow it down and reverse its progress.

Full article covering the complete framework, the recycling myth, and how circular design applies to UX.