react-render-profile-mcp v0.3.1 – 4 new diagnostic tools for React Compiler, hydration, Zustand, and state cascades

A few weeks ago I published a post about react-render-profile-mcp — an MCP server that decodes React DevTools Profiler exports so AI agents can actually diagnose render performance instead of guessing at raw fiber IDs.

v0.1 shipped with 5 tools. v0.3.1 adds 4 more, each targeting a class of problems the original couldn’t touch. Here’s what’s new. 🐸

What was already there (v0.1)

Quick recap for anyone who missed the first post:

  • get_render_summary — total commits, render time, top components, lifecycle anomaly flags
  • find_spurious_renders — components that re-rendered with no actual prop/state change
  • get_hottest_components — ranked by CPU self-time
  • trace_render_cascade — what triggered a commit and what re-rendered as a result
  • suggest_memoization — ROI-scored React.memo recommendations

These covered the “something is rendering too much” class of problems. What they couldn’t tell you: why your React Compiler isn’t helping, where hydration broke, which Zustand selector is in a loop, or how deep a context update actually propagates.

What’s new in v0.3.1

1. analyze_compiler_efficacy

React Compiler (React 19) and manual React.memo should eliminate spurious renders. Often they don’t — because of inline object allocations or unstable parent refs that bypass memoization entirely.

This tool computes an Invalidation Index per component:

I = (spurious_count / total_count) × wasted_ms

High index = memoization is present but not working. The tool tells you exactly why:

{
  "severity": "CRITICAL",
  "component_name": "ProductList",
  "ineffective_render_count": 23,
  "wasted_ms": 84.3,
  "trigger_cause": "UNSTABLE_PARENT_PROP_REFERENCE",
  "recommendation": "Memoize parent props with useMemo/useCallback or hoist static objects out of the parent render function."
}

Without this, your agent might suggest adding React.memo to a component that already has it — and has it for a reason that makes it useless.

2. diagnose_hydration_and_suspense

Two separate problems, one tool:

Hydration mismatches — when React discards server HTML and remounts the entire tree from scratch. Shows up as an abnormally long initial mount with a spike of unmounts immediately after. The tool flags these as HYDRATION_MISMATCH_RECOVERY with the affected Suspense boundaries and blocking duration.

Suspense waterfalls — nested boundaries fetching sequentially instead of in parallel. Detected by measuring the gap between consecutive Suspense resolves against a configurable waterfall_threshold_ms (default: 100ms).

{
  "severity": "WARNING",
  "anomaly_type": "NESTED_MOUNT_FETCH_WATERFALL",
  "root_component": "ProfileDetails",
  "blocking_duration_ms": 120.5,
  "recommendation": "Prefetch data at the parent level or use Promise.all."
}

3. evaluate_external_store_performance

Zustand and Redux with useSyncExternalStore have two failure modes that are hard to catch manually:

Unstable selector object allocation — a selector returns a new object reference every call, triggering rapid consecutive renders. The tool detects components that render multiple times in consecutive frames and flags the selector as the cause.

Sync concurrency bypass — a heavy store update runs synchronously in a high-priority lane, blocking the main thread. Should be in startTransition instead.

{
  "severity": "CRITICAL",
  "impacted_components": ["CartSummary"],
  "is_infinite_loop": true,
  "trigger_cause": "UNSTABLE_SELECTOR_OBJECT_ALLOCATION",
  "recommendation": "Wrap the selector in useCallback or return primitive values."
}

4. trace_state_cascade_footprint

Given a commit index, this reconstructs the virtual component tree and measures how far an update actually propagated:

  • Which component triggered the update
  • Whether it went through a context provider or a store subscriber
  • How many levels deep it reached
  • How many consumer components re-rendered
{
  "severity": "HIGH_FOOTPRINT",
  "update_trigger_source": "ThemeButton",
  "propagation_channel": "CONTEXT_PROVIDER",
  "cascade_render_depth": 7,
  "rendered_consumer_count": 28,
  "recommendation": "Split the context provider or memoize its value and children."
}

This is the tool that answers “why did 28 components re-render when I clicked one button.”

Updated: find_spurious_renders trigger classification

The existing tool now classifies why a render was spurious, not just that it was:

  • UNSTABLE_PARENT_REF — parent passed a new object/array/function reference with identical values
  • CONTEXT_UPDATE — context changed, but this component doesn’t actually use the changed value
  • INTENTIONAL_CONCURRENT_YIELD — React’s scheduler, not a bug

This matters because React.memo fixes the first case but can’t help with the second. The recommendation now reflects the correct fix path.

Recommended agent workflow (updated)

1. get_render_summary              → overview + lifecycle_anomaly flags
2. find_spurious_renders           → classify unnecessary renders by trigger type
3. analyze_compiler_efficacy       → check where React.memo / Compiler is being bypassed
4. diagnose_hydration_and_suspense → catch hydration recovery + Suspense waterfalls
5. evaluate_external_store_performance → Zustand/Redux selector loops + sync bypasses
6. trace_state_cascade_footprint   → propagation depth for expensive commits
7. suggest_memoization             → ROI-scored final recommendations

Setup (unchanged)

{
  "mcpServers": {
    "react-render-profile": {
      "command": "npx",
      "args": ["-y", "react-render-profile-mcp"]
    }
  }
}

Export a profile from React DevTools → Profiler tab → Record → Save. Pass the .json path as profile_path to any tool.

npm: react-render-profile-mcp
GitHub: vola-trebla/react-render-profile-mcp

Happy to answer questions about the hydration detection heuristics or the Invalidation Index math. And if you’re hitting a React performance pattern this doesn’t cover yet — open an issue. 🐸

n8n for Beginners: Build Your First Automation in 15 Minutes (No Coding Required)

I built my first n8n workflow in 2023 because I was tired of paying $49/month for Zapier to send a single email when a form was submitted.

Three years later, n8n runs 40+ automations across my business — invoicing, lead capture, daily reports, AI customer support — all for $0/month on a self-hosted server.

If you’re just getting started with n8n, this guide gets you from “what is n8n” to your first running workflow in under 15 minutes.

What Is n8n?

n8n is an open-source workflow automation tool. Like Zapier or Make.com, but:

  • Free forever when self-hosted (no per-task fees)
  • Code nodes — run real JavaScript or Python when you need logic
  • 1,000+ integrations — Gmail, Slack, Notion, Airtable, Postgres, HTTP requests, and more
  • Your data stays on your server — no SaaS company processing your customer emails

The catch: you need to install it. Takes about 2 minutes.

Install n8n (3 Options)

Option 1 — npx (fastest, no Docker required):

npx n8n

Open http://localhost:5678. Done.

Option 2 — Docker:

docker run -it --rm --name n8n -p 5678:5678 -v n8n_data:/home/node/.n8n docker.n8n.io/n8nio/n8n

Option 3 —!n8n Cloud:

Sign up at n8n.io — free trial, no install needed. Good for testing before self-hosting.

Core Concepts (Learn These 5 Terms First)

Term What It Means
Node One step in your workflow (e.g., “Send Gmail”)
Trigger The first node — what starts the workflow
Connection The arrow linking nodes together
Workflow The full chain from trigger to last step
Execute Running the workflow manually or on a schedule

That is really it. Everything else is just different types of nodes.

Build Your First Workflow: Form Submission to Email Notification

Let us build something real: whenever someone submits a form, you get an email notification.

Step 1: Create a new workflow

In n8n, click + New Workflow in the top right.

Step 2: Add a Webhook trigger

  • Click the + button
  • Search for “Webhook” and select it
  • Copy the Test URL (looks like http://localhost:5678/webhook-test/abc123)

Step 3: Add a Gmail node

  • Click + after the Webhook node
  • Search “Gmail” and select Send Email
  • Connect your Gmail account (click Create New Credential)
  • Fill in To (your email), Subject: New Form Submission, Message: {{ $json.body.name }} submitted the form

Step 4: Test it

  • Click Execute Workflow
  • In a new tab, open the Test URL with ?name=TestUser appended
  • Watch data flow through the nodes in real time
  • Check your inbox

Step 5: Activate

Toggle Active in the top right. The workflow now runs automatically.

5 Beginner-Friendly n8n Workflows to Build Next

1. Email Auto-Responder

Keyword-based auto-replies. Someone emails “pricing” and they get your price list automatically.

Nodes: Gmail Trigger + Code (keyword match) + Gmail (send reply) + Google Sheets (log)

2. Appointment Reminder

Pull upcoming Google Calendar events and send email/SMS reminders 24h before.

Nodes: Schedule Trigger (hourly) + Google Calendar + Code (filter window) + Gmail

3. Lead Capture to CRM

Form submission comes in, score the lead by role/company size, log to Sheets, alert on Slack if hot.

Nodes: Webhook + Code (scoring) + Google Sheets + IF + Slack

4. Daily Business Report

Every morning at 7am: pull sales data from Sheets, calculate metrics, email yourself a summary.

Nodes: Schedule Trigger + Google Sheets + Code (calculate KPIs) + Gmail

5. AI Customer Support Bot

Incoming support ticket comes in, OpenAI writes a draft reply, Gmail sends it to the customer.

Nodes: Webhook + HTTP Request (OpenAI API) + Gmail

Common Beginner Mistakes

Forgetting to Activate

Workflows only run automatically when toggled Active. If nothing is happening, check the toggle first.

Using the Test URL in production

The Test URL (/webhook-test/) only works when you have n8n open and are inside the workflow editor. Use the Production URL (/webhook/) for live traffic.

Not handling errors

Add an Error Trigger workflow that sends you a Slack or email alert when any other workflow fails. Without this, you will never know when something breaks.

Overcomplicating the first workflow

Start with 3 nodes. Get it working. Then add complexity. Starting with a 20-node diagram before running a single test always ends in confusion.

Useful n8n Resources

  • Official docs: docs.n8n.io (excellent, very well maintained)
  • Template library: n8n.io/workflows (2,000+ community workflows)
  • Community forum: community.n8n.io (active, moderators respond fast)
  • YouTube: search “n8n tutorial 2026” for video walkthroughs

Skip the Learning Curve: Ready-Made Templates

If you want production-ready workflows without building from scratch, I packaged 15 battle-tested automations covering the most common business use cases.

Each template includes:

  • Full workflow JSON (import in 30 seconds via Settings + Import Workflow)
  • Step-by-step setup guide (under 5 minutes each)
  • Customization notes

Free template: Email Auto-Responder JSON is available in the FlowKit GitHub repo

Full pack (15 templates, $97): stripeai.gumroad.com

Templates in the pack: Email Auto-Responder, Social Media Cross-Poster, Invoice Generator, AI Customer Support Bot, Price Monitor, Lead Capture to CRM, Appointment Reminder, Content Repurposer, Daily Report Generator, Webhook to Database, RSS Social Auto-Poster, File Organizer, Claude AI Agent with Memory, Telegram AI Bot, and more.

5-Day Starter Plan

  • Day 1: Install n8n, build the Webhook-to-Gmail workflow above
  • Day 2: Add a Code node, do a simple string transformation on the incoming data
  • Day 3: Read from and write to a Google Sheet
  • Day 4: Call an external API with the HTTP Request node
  • Day 5: Automate one task you currently do manually every day

The fastest way to learn n8n is to automate something that actually annoys you. Start there.

Questions? Drop them in the comments — I read and respond to every one.

Why Mobile Users Leave a Website Within Seconds

Why Mobile Users Leave a Website Within Seconds

It’s rarely about the content. Usually, they’re gone before they even see it.

There’s a specific kind of frustration that mobile users almost never talk about — because it disappears too fast to complain about.

You tap a link. The screen goes white. You wait. Nothing happens fast enough. So you back out. You’ve already forgotten what you were looking for.

The whole thing took maybe four seconds. But those four seconds were enough.

The Phone Is a Different Psychological Environment

This is the part that gets missed in most conversations about mobile UX.

When someone is at a desk with a laptop open, there’s an implicit commitment. They sat down. They opened the browser. They have a task. The context creates a baseline of patience.

A phone is different. It gets picked up between things — between floors on an elevator, between bites at lunch, in the thirty seconds before a meeting starts. There’s no commitment. No task framing. Just a small gap in the day that a quick tap was supposed to fill.

That changes everything about what “acceptable” feels like.

On desktop, waiting eight seconds feels annoying. On mobile, in that same mindless-scroll moment, waiting three seconds feels like an eternity — because the gap you were trying to fill is already closing. The elevator doors open. The food arrives. The meeting starts. The phone goes back in your pocket.

The site never stood a chance.

Attention Isn’t Lost — It Was Never Really Committed

Most UX writing talks about “losing user attention.” But on mobile, attention was never fully given in the first place.

Mobile browsing is an activity done alongside other things. It’s layered on top of real life, not carved out from it. A mobile user’s attention is usually partial, borrowed, and easily pulled back by whatever is happening around them.

What this means practically: the first few seconds of loading aren’t just a technical delay. They’re a window in which the user is actively reconsidering whether this is worth their fragmented attention at all.

A slow response during that window doesn’t just test patience. It actively hands the decision back to the user — and their default answer, in that distracted moment, is almost always no.

Server Latency — The Invisible Tax on Every Interaction

Most people don’t think about server latency. They think about whether the content is good.

But server latency is what the user experiences before content even exists on their screen. It’s the gap between “I tapped this” and “something appeared.” And in mobile contexts, that gap is weighted differently than anywhere else.

Every additional 100ms of latency adds up. Not in a way users can articulate — they won’t say “the TTFB was poor.” They’ll say “it felt slow” or “something felt off” or, more often, they won’t say anything at all. They’ll just leave and not come back.

Geography matters too. If a server is far from the user and there is no well-distributed CDN in place, every request starts with a small delay. Multiply that across every page transition, every scroll, every tap — and the cumulative effect on perceived speed is significant, even when individual numbers seem small.

UX Friction Is Mostly Invisible Until It Isn’t

Friction is the right word because it describes the physics accurately. Things slow down. Movement becomes effortful. The user has to push harder than they expected.

On mobile, friction shows up in places that are easy to overlook during development: tap targets that are slightly too small, text that’s a size too fine for thumb-scroll reading, page jumps caused by late-loading images, modals that appear without warning and block content.

None of these individually seem like dealbreakers. Together, they create a texture to the experience that users register as “this doesn’t feel right” — without knowing why.

The interesting thing about UX friction is that it often gets attributed to the wrong cause. A user who bounces because a tap target was two pixels too small will remember the site as “slow” or “confusing,” not “had slightly misaligned UI elements.” The friction translates into a general negative impression, not a specific complaint.

That makes it hard to debug — and easy to underestimate.

The Psychology of Loading — What the Brain Does While Waiting

Waiting isn’t passive. While a page loads, the user’s brain is doing several things simultaneously.

It’s evaluating whether the wait is going to be worth it. It’s assessing whether there might be a faster alternative nearby. It’s monitoring the environment for anything more immediately relevant — a vibration, a sound, movement in the periphery.

A loading spinner or progress bar addresses this to some degree. Something visible happening creates a sense of process — the brain interprets it as progress rather than stasis. But this only works within a narrow window. Beyond a few seconds, even visible loading feedback starts to feel like waiting, not anticipating.

What mobile users actually respond to is incremental content. The moment something — anything — appears on screen, the psychological dynamic shifts. The user has something to look at. The question changes from “is anything happening?” to “is this worth staying for?” That’s a much more favorable question to be answering.

Sites that load a visible structure first — text before images, layout before media — hold users longer than sites that load nothing until everything is ready. The technical difference might be small. The psychological difference is not.

Mobile Optimization Is a Commitment, Not a Feature

There’s a category of platform that treats mobile optimization as a checkbox. Responsive layout: checked. Font size: readable. Done.

That approach shows. Users feel it, even without the vocabulary to describe what’s wrong.

Real mobile optimization starts at the infrastructure level — how requests are routed, how assets are compressed, how rendering is prioritized on lower-powered hardware. It continues through the interaction layer — how touch events are handled, how navigation responds to gesture, how state is preserved across interruptions.

And it extends to the content itself — whether media files are appropriately sized for the connection type being used, whether the most critical content is prioritized in the loading sequence, whether the experience degrades gracefully when conditions aren’t ideal.

That last part matters more on mobile than anywhere else. Conditions on mobile are rarely ideal. Network quality varies. Background processes compete. Users switch apps mid-session and expect to return seamlessly.

Platforms that treat these realities as edge cases tend to feel unreliable. Platforms built around them tend to feel fast — even when raw speed metrics look similar.

A practical example of this kind of mobile-first approach can be seen on the official website, where speed, lightweight interaction, and mobile usability are treated as part of the core experience rather than an afterthought.

Why This Keeps Mattering

Mobile traffic continues to grow. Attention continues to fragment. The gap between a platform that loads in 1.5 seconds and one that loads in 3.5 seconds — barely noticeable on a spec sheet — translates to measurably different retention rates in practice.

Users don’t give extra credit for almost fast. They don’t consciously notice when things go well. They only register, somewhere below articulation, that this place felt easy to be in.

That feeling is what they come back for.

Not the content. Not the features. The feeling that being here requires nothing extra from them — no patience, no effort, no second-guessing whether the tap registered.

The sites that earn that feeling aren’t necessarily the biggest or the best-resourced. They’re the ones that decided mobile users deserve the same quality of experience as everyone else — and then actually built for it.

Written from an interest in how small technical decisions translate into felt human experience.

I Spent $0.37 Testing Google’s Antigravity 2.0 Agent API — Here’s Every Bug You’ll Hit (and How to Fix Them)

TL;DR: Antigravity 2.0 cut my 90‑min dependency audit to 14 min for $0.044. It caught a critical CVE I’d missed for months — and hallucinated an unreleased package version. Here’s the production checklist, working code, and every bug I hit so you don’t have to.

Google I/O 2026 made agentic workflows feel real. Rather than just watching the demos, I tested Google’s managed agents on an actual dependency audit across 14 production microservices. The result: the workflow was genuinely faster, but it also exposed a handful of production problems you’d want to solve before trusting it in the wild.

This article isn’t just about saving 76 minutes. It’s about what agentic runtimes change in how we build, verify, and supervise automation — and what still breaks when you take them off the demo stage.

Note: Antigravity is Google’s preview managed-agent runtime, announced at I/O 2026 — that’s what I tested.

How the Tokens Actually Move

Before diving into code, it helps to see how tokens flow between agents, the sandbox, and the outside world. The flow determines where your cost and latency actually come from.

User Task 
   │
   ▼
Scanner Agent (17.3K tokens) 
   │ writes report.json
   ▼
Security Agent (13K tokens) 
   │ enriches with CVEs
   ▼
Changelog Agent (1.5K tokens) 
   │ generates markdown
   ▼
PR Agent (3K tokens) ──→ GitHub PRs

All four agents run inside the same managed sandbox, which persists across calls so you don’t re‑ingest everything. Token tally from one clean run:

  • Scanner: 5,600 input, 11,740 output (17,340 tokens)
  • Security: 2,100 input, 10,902 output (13,002 tokens)
  • Changelog: 350 input, 1,200 output (1,550 tokens)
  • PR Agent: 400 input, 2,600 output (3,000 tokens)

Total: 34,892 tokens across four stages. The environment itself costs nothing extra—you just pay for tokens at the model’s per‑token rate. For this preview, I used gemini‑3.5‑flash‑preview at $0.0005/1K input and $0.0015/1K output. The sandbox is bundled in, which changes the economics completely compared to spinning up your own container.

💡 Why this matters: Because all agents share the same environment, the Security Agent doesn’t need to re‑scan the repo. It just reads the JSON that’s already sitting there. That’s where a lot of cost gets saved.

Real Numbers: Time and Money

I compared three ways of doing the exact same 14‑service audit: doing it manually (me, a human), using Antigravity’s Managed Agents, and running the same prompts on a cheap cloud VM with a normal Gemini API call and custom orchestration.

Metric Manual Antigravity Agents Cloud VM + LLM
Scan time 25 min 4 min 8 min
CVE check 20 min 3.5 min 6 min
Changelog 15 min 2 min 1 min
PR creation 50 min (5 services) 4 min 5 min
Total wall‑clock 90 min 14 min 20 min
Cost $0 (but my time) $0.044 (tokens) $0.92 (VM + API)
Setup effort None A couple hours A week of DevOps

Cost Comparison Per Audit Run

  • Manual: $0 (but 90 min @ $60/hr = $90 value)
  • Antigravity: $0.044 (14 min human oversight)
  • Cloud VM: $0.92 (20 min + week of DevOps setup)

Winner: Antigravity saves 76 min and $89.96 in labor value per run.

The cloud VM alternative was a $0.04/hr e2‑micro instance running a Python script that called the Gemini API with the same prompts, plus a GitHub CLI container. The token cost was higher because it had to re‑read the repo for each stage instead of reusing state in a sandbox.

🔍 Spot‑check: I manually verified the first five dependencies the Scanner Agent flagged against the npm and Go registries. The agent’s output was correct on 4 out of 5 — the one discrepancy was a patch version off‑by‑one, which the Verifier Agent later caught.

🛠️ Try This Yourself: Minimal Two‑Agent Example

Below is a 20‑line Python script you can run right now. It creates a Scanner Agent that audits a single directory and a Verifier Agent that cross‑checks the version of every package found against the public registry.

from google import genai
import json

client = genai.Client(api_key="YOUR_API_KEY")

# Create a managed sandbox
interaction = client.interactions.create(
    agent="antigravity-preview-05-2026",
    config={
        "tools": ["code_execution", "web_browsing", "file_management"],
        "sandbox": "isolated_linux"
    }
)

# Note: The API structure shown is simplified for clarity.
# Check documentation for the latest SDK reference.

# Scanner Agent: generate dependency report
scan_task = """Scan /workspace for package.json and requirements.txt.
Output a JSON list of {package, current_version, latest_version} to /workspace/deps.json."""

client.interactions.send_message(interaction_id=interaction.id, message=scan_task)

# Verifier Agent: cross-check against registry
verify_task = """Read /workspace/deps.json.
For each package, curl the public registry and confirm the latest version.
Output a corrected /workspace/verified_deps.json."""

client.interactions.send_message(interaction_id=interaction.id, message=verify_task)

print("Done. Check verified_deps.json in the sandbox.")

Setup Snapshot

  • Cost: ~$0.02 for a test run
  • Time: 3 minutes to set up, 2 minutes to execute
  • What you’ll learn: Whether your dependencies are genuinely up‑to‑date and whether the agent hallucinates any version numbers.

Production Readiness Checklist: 6 Things You Must Handle

1. Endless Reasoning Loops

  • Problem: The agent’s stop condition is “the model decides it’s done.” Tell it to “check all package files recursively” and it may happily circle through node_modules forever.
  • Solution: Build a wrapper that counts tool calls and force‑stops after 20.
  • Why it matters: Without a ceiling, a single rogue prompt can burn dollars in minutes.

2. Sandbox Filesystem Consistency

  • Problem: After writing a large JSON, the next read sometimes returns a stale version—duplicate entries, missing data.
  • Solution: Explicitly run sync via the shell tool before every read.
  • Why it matters: Stale state corrupts downstream agents and erodes trust in the entire pipeline.

3. Cost Unpredictability

  • Problem: The $0.37 figure was my entire weekend; a clean run costs fractions of a cent. But one agent got stuck in a recursive retry loop parsing a malformed package.json and ate $0.89 in seconds.
  • Solution: At the time of testing, I couldn’t find a native cost‑cap feature in the API. Wrap your API calls with a token budget tracker that raises an exception if limits are exceeded.
  • Why it matters: Production pipelines need spend guarantees, not gambling.

4. Hallucinations in Dependency Versioning

  • Problem: Gemini 3.5 Flash confidently reported [email protected] (unreleased) and mis‑identified a Go module’s minor bump as a breaking change.
  • Solution: Always run a verifier agent that hits the actual package registry via curl. I caught 3 out of 4 hallucinations this way.
  • Why it matters: A hallucinated CVE or version can lead to unnecessary rollbacks or missed patches.

5. Credential Scoping Is All‑or‑Nothing

  • Problem: Secrets are scoped to the entire interaction, not per‑agent. My Scanner Agent technically had the same GITHUB_TOKEN as the PR Agent, violating least‑privilege.
  • Solution: Until Google supports per‑agent secrets, use separate interactions for read‑only and write‑enabled stages.
  • Why it matters: A compromised scanner shouldn’t be able to open PRs.

6. Debugging Opacity

  • Problem: No streaming log of agent tool calls. You either stare at a blank terminal or wait 8 minutes for the web dashboard replay.
  • Solution: After every stage, call client.interactions.get() and assert state == “COMPLETED” and output is non‑empty.
  • Why it matters: Silent failures waste time and token budgets.

Why This Matters Beyond Dependency Audits

Google didn’t demo 93 agents to sell you a dependency auditor. They signaled a platform bet: that the unit of compute is shifting from “a single model call” to “a managed runtime where agents persist, schedule themselves, and collaborate.”

This is Google’s answer to LangChain and AutoGen — hosted, vertically integrated with TPU‑optimized models, and bundled into Gemini’s pricing. If OpenAI releases comparable managed agents soon, the pricing war will be brutal, and developers will benefit.

My dependency audit is a trivial example. What becomes possible when you can spin up a verifier agent for every PR, or a security‑scanning agent that watches your monorepo continuously and opens fixes before you even wake up? That’s the real headline from I/O 2026, and it’s a shift that will matter long after the smart glasses stop making news.

What I’m Building Next

1. Automated Security Monitoring (Try This Version)

Here’s the daily CVE scanner I’m deploying next week. It runs the Security Agent every morning, diffs the report against yesterday’s, and opens PRs only for new critical findings.

import subprocess
import json
import datetime

today = datetime.date.today().isoformat()
yesterday = (datetime.date.today() - datetime.timedelta(days=1)).isoformat()

# Run the Security Agent (same sandbox, same report path)
subprocess.run(["python", "security_agent.py", f"--date={today}"])

# Diff the CVE reports
with open(f"report_{yesterday}.json") as f: 
    old_report = json.load(f)
with open(f"report_{today}.json") as f: 
    new_report = json.load(f)

new_critical = [
    cve for cve in new_report.get("vulnerabilities", [])
    if cve["severity"] == "CRITICAL"
    and cve not in old_report.get("vulnerabilities", [])
]

# Open PRs for new critical CVEs
for cve in new_critical:
    subprocess.run([
        "gh", "pr", "create",
        "--title", f"CRITICAL: {cve['package']} {cve['id']}",
        "--body", f"Automated PR. CVE details:n{cve['description']}nnFixed in {cve['fixed_version']}",
        "--assignee", "@security-team"
    ])
    print(f"Opened PR for {cve['id']}")

print(f"Checked {len(new_report['vulnerabilities'])} CVEs, {len(new_critical)} new critical.")

  • Cost: ~$0.15/day for 14 services
  • Setup: 10 minutes to add your own report paths
  • Result: Zero‑day vulnerabilities caught within hours instead of weeks.

2. Cost‑Aware Orchestration Wrapper

A thin Python wrapper that enforces token budgets per agent and sends Slack alerts when a pipeline approaches the ceiling. Essential for production peace of mind.

The Bottom Line

The surprising part wasn’t that the agents made mistakes. Junior engineers make mistakes too. The surprising part was how quickly the system became genuinely useful once I stopped expecting perfection and started treating it like a collaborative runtime.

Double‑check its work and you’ll be thrilled. Trust it blindly and you’ll get burned.

Try the 20‑line example above. It takes 3 minutes, costs a couple of cents. Then you’ll see firsthand that managed agents aren’t replacing developers yet — they’re replacing the parts of the job developers hate most.

If you’re exploring the I/O announcements, don’t just watch the demos — take one and push it against your own real‑world workflow. That’s where the actual lesson lives.

📝 AI Transparency & Methodology Declaration

  • Empirical Data & Testing: All performance metrics, token tallies, dollar figures ($0.37 total weekend spend, $0.044 per target run), and technical edge cases detailed in this article are based on real, hands-on development hours logged between May 20–21, 2026. Testing was executed on a private 14-service monorepo containing Node.js, Python, Go, and Rust components, utilizing the antigravity-preview-05-2026 pipeline.
  • AI Assistance Disclosure: I used AI as a coding partner to help scaffold the Python boilerplate, draw the token-flow diagram, and clean up the markdown. Every bug, architectural decision, and conclusion in this piece is from my own testing and engineering judgment.
  • I have spent over four years building and maintaining production microservices, including debugging numerous dependency-related incidents—which is why solving this workflow pipeline matters.

If this helped you, I’d love to hear about it. Share what you built with Antigravity agents in the comment section.

Building Real-Time Apps in Node.js with Rivalis: WebSockets, Rooms, Actors, and a Binary Wire

If you have ever tried to build a multiplayer game, a collaborative editor, or a chat server in Node.js, you have probably written the same boilerplate twice: a ws server, a map of socket → user, a map of room → users, an auth handshake, a heartbeat, a rate limiter, a reconnect loop on the client, and a bespoke binary or JSON protocol gluing it all together.

Rivalis is the framework I wish I had the first time I wrote that boilerplate. It splits into two packages:

  • @rivalis/core — the Node.js server. Rooms, actors, auth middleware, pluggable transports, and a binary wire format.
  • @rivalis/browser — a small typed browser client with reconnect, token-refresh, and Sec-WebSocket-Protocol ticket delivery.

Both are MIT licensed, TypeScript-first, and at v6 on npm. Let’s walk through the design and then build a small example.

A small note before we dive in

I want to be honest about what this project is, because I think it matters.

Rivalis is my pet project. I have been working on it since 2022, on and off, in evenings and weekends and the quiet stretches between deadlines. It started because I kept making the same mistakes every time I built a multiplayer backend — the same race conditions, the same auth handshake bugs, the same “why is this socket leaking memory at 3 AM” moments. After the third or fourth time, I realized the lesson was not “be more careful next time.” The lesson was “stop rewriting this from scratch.”

So the goal of Rivalis is simple: take everything I have learned about building real-time multiplayer servers — the close-code conventions, the timing-safe comparisons, the heartbeat tuning, the way you should never trust the client’s clock, the difference between rate limiting at the socket layer and at the room layer — and bundle it into something other people can use without paying the same tuition I did. If it saves even one person a weekend of debugging, that is the project earning its keep.

It is also not just a hobby anymore. The framework has been quietly battle-tested in a handful of companies over the past couple of years, running multiplayer game servers and real-time collaboration backends in production, and the results have been honestly better than I expected. Long-uptime, low-incident, the kind of boring stability you actually want from a real-time layer. That feedback loop — seeing it survive contact with real users — is what pushed me to keep polishing the API and finally write this article.

If you find rough edges, please tell me. The whole point is that you should not have to learn them the hard way.

The mental model

Rivalis gives you four primitives:

Primitive What it is
Rivalis The server entrypoint. Holds your transports, auth, rate limiter, and room manager.
Room A named space you subclass. Binds inbound topics to handlers; broadcasts to its members.
Actor A per-connection handle inside a room. Carries data returned by auth, plus id, send, kick.
AuthMiddleware One method — authenticate(ticket) — returns { data, roomId } or null.

The data flow on every connection:

client.connect(ticket)
        │
        ▼
  AuthMiddleware.authenticate(ticket)
        │
   ┌────┴────┐
   │         │
  null    { data, roomId }
   │         │
  close   join room → Actor
4001       (onJoin fires)

That is the whole shape. Everything else — heartbeats, rate limiting, presence, reconnects — is configured, not coded.

Hello world: an echo chat server

The server, in full:

import http from 'http'
import {
    Rivalis, Transports, Room, AuthMiddleware,
    type AuthResult, type Actor
} from '@rivalis/core'

type ActorData = { name: string }

class ChatRoom extends Room<ActorData> {
    protected override presence = true   // auto __presence:join / __presence:leave

    protected override onCreate() {
        this.bind('chat', this.onChat)
    }

    protected override onJoin(actor: Actor<ActorData>) {
        actor.send('welcome', JSON.stringify({ youAre: actor.data?.name ?? '' }))
    }

    private onChat(actor: Actor<ActorData>, payload: Uint8Array) {
        this.broadcast('chat', payload)
    }
}

class Auth extends AuthMiddleware<ActorData> {
    override async authenticate(ticket: string): Promise<AuthResult<ActorData> | null> {
        const name = ticket.trim()
        if (!name || name.length > 20) return null
        return { data: { name }, roomId: 'global' }
    }
}

const server = http.createServer()
const rivalis = new Rivalis<ActorData>({
    transports: [new Transports.WSTransport({ server })],
    authMiddleware: new Auth()
})
rivalis.rooms.define('chat', ChatRoom)
rivalis.rooms.create('chat', 'global')
server.listen(8080, () => console.log('ws://localhost:8080'))

process.on('SIGINT', async () => { await rivalis.shutdown(); process.exit(0) })

The browser side is just as small:

import { WSClient } from '@rivalis/browser'

const ws = new WSClient<'chat' | 'welcome'>('ws://localhost:8080')
const enc = new TextEncoder()
const dec = new TextDecoder()

ws.on('client:connect', () => console.log('connected'))
ws.on('welcome', (p) => console.log('welcome:', dec.decode(p)))
ws.on('chat', (p) => console.log('chat:', dec.decode(p)))

ws.connect('alice')
ws.send('chat', enc.encode('hello world'))

That is a complete real-time chat. No express, no socket.io, no Redis. Run it.

Rooms are where the logic lives

A Room is a class you subclass. It has lifecycle hooks (onCreate, onJoin, onLeave, onDestroy) and a small API surface:

Method Purpose
bind(topic, listener) Register inbound topic handler.
bindAny(listener) Wildcard fallback for unbound topics.
send(actor, topic, payload) Unicast.
broadcast(topic, payload) Fan-out.
each(fn) Iterate room actors.
kick(actor, payload?) Disconnect with a reason.
destroy() Tear down the room.

A few details worth knowing:

  • maxActors and joinable are simple instance fields. Set maxActors = 4 and the fifth joiner gets closed with room_full.
  • presence = true auto-broadcasts __presence:join and __presence:leave with a JSON payload describing the joining/leaving actor. You can override presencePayload(actor) to scrub server-only fields out before the broadcast.
  • Reserved topics. The __ prefix is reserved for framework events. bind/unbind throw if you try to claim one.
  • unknownTopicPolicy defaults to 'kick' — an actor sending a topic nobody bound is treated as misbehaving. Switch to 'drop' for permissive apps.

The Room API is deliberately small. Game state, lobbies, turn logic — that is all just code you write inside your subclass.

Actors carry your auth payload

Whatever your AuthMiddleware.authenticate returns in data is stamped on the Actor for the lifetime of the connection. That means after auth, the room never needs to look up “who is this user” — the data is already on the actor:

class JWTAuth extends AuthMiddleware<{ userId: string; tier: 'free' | 'pro' }> {
    override async authenticate(ticket: string) {
        const claims = await verifyJwt(ticket)
        if (!claims) return null
        return {
            data: { userId: claims.sub, tier: claims.tier },
            roomId: claims.room
        }
    }
}

Inside the room:

private onChat(actor: Actor<{ userId: string; tier: 'free' | 'pro' }>, payload: Uint8Array) {
    if (actor.data?.tier !== 'pro' && payload.byteLength > 256) return
    this.broadcast('chat', payload)
}

Actor also has save<T>(key, value) and get<T>(key) for per-actor scratch state — handy for in-room counters, last-seen timestamps, anti-spam buckets.

One security note from the docs that is worth repeating. Any secret comparison inside authenticate — HMACs, signatures, session tokens — must use crypto.timingSafeEqual or an equivalent constant-time comparator. === and Buffer.compare short-circuit on first mismatch and leak the prefix length under enough samples. The framework cannot enforce this for you; if you compare a signature with ===, you have built a timing oracle.

The wire is binary, but opaque

Every frame on the wire is { topic: string, payload: bytes }. The framework does not inspect payload. You encode it however you want — JSON, protobuf, msgpack, raw bytes, a hand-rolled struct.

For a chat app, JSON over TextEncoder is fine:

const enc = new TextEncoder()
const dec = new TextDecoder()

export const encode = <T>(v: T): Uint8Array => enc.encode(JSON.stringify(v))
export const decode = <T>(p: Uint8Array): T => JSON.parse(dec.decode(p)) as T

For a 60 Hz multiplayer game, swap in @bufbuild/protobuf or msgpackr. The wire layer does not care. It does enforce one thing: frames are binary. Send a text frame and the server closes the connection with INVALID_FRAME (4002).

Security defaults that exist on purpose

A lot of WebSocket tutorials end at “and now you have real-time!” without ever mentioning that you have also just opened a fresh attack surface. Rivalis ships defaults for the boring stuff:

  • Token-bucket rate limiting, on by default — 30 tokens, 30/sec refill. Subclass RateLimiter to swap it out, pass null to opt out.
  • Heartbeats — 30-second ping with a 2-miss kick. Configurable on WSTransport.
  • Frame and topic size caps — maxPayload (64 KiB default) and maxTopicLength (256 default). Anything bigger gets dropped at the transport.
  • Backpressure handling — a per-socket outbound buffer cap (1 MiB default); the onBackpressureDrop hook fires on every dropped frame so you can escalate (e.g. kick the slow actor).
  • Origin allow-list — pass allowedOrigins to WSTransport and any other Origin header is rejected before auth runs. Required for CSWSH protection if you ever decide tickets ride on cookies.
  • Pre-handshake connection limiting — subclass ConnectionLimiter to cap how many sockets a single IP can open per second. Rejected with RATE_LIMITED (4005) before any auth code runs.
  • Ticket via subprotocol — set ticketSource: 'protocol' on both the server and browser client, and the ticket rides on Sec-WebSocket-Protocol instead of ?ticket=. Keeps credentials out of URL access logs and browser history.
  • Tickets are never logged in plaintext — only an 8-char SHA-256 fingerprint, so a leaked log file does not become a session-takeover.

None of those need code from you on the happy path. The defaults are sane; the knobs exist when you need them.

The browser client is small on purpose

@rivalis/browser has five methods: connect, disconnect, send, on/once/off. Everything else is a configuration choice.

Typed events

The client:* events have typed payloads, and you can constrain user topics through a generic:

type Topics = 'lobby:state' | 'chat' | 'game:tick'

const ws = new WSClient<Topics>('wss://example.com/ws')

ws.on('chat', (p) => { /* p: Uint8Array */ })
ws.on('typo:state', (p) => { ... })            // type error
ws.on('client:kicked', ({ code, reason }) => { ... })

Reconnection done right

const ws = new WSClient(url, {
    reconnect: { maxAttempts: 8, baseDelayMs: 250, maxDelayMs: 5000 }
})

Exponential backoff with jitter. Importantly, reconnect skips terminal close codes. If the server kicked you with INVALID_TICKET, KICKED, or ROOM_REJECTED, the client treats that as a final answer and does not retry. Those mean “the server does not want you back” — silently looping is just noise.

Refreshing short-lived tickets

If your tickets are short-lived JWTs, the getTicket hook is called before every reconnect attempt:

const ws = new WSClient(url, {
    reconnect: true,
    getTicket: async () => {
        const res = await fetch('/api/realtime-token', { credentials: 'include' })
        if (!res.ok) throw new Error('token endpoint failed')
        return await res.text()
    }
})

ws.connect(initialTicket)   // first call still uses its argument verbatim

If getTicket throws, the loop terminates with client:reconnect_failed. You cannot reconnect without a ticket, so there is nowhere to retry to.

Close codes you will actually see

Knowing the close codes is the difference between a useful error UI and “connection lost”:

Code Meaning
4001 INVALID_TICKET — bad/missing ticket; auth rejected
4002 INVALID_FRAME — non-binary frame received
4003 KICKED — server-initiated kick (reason in payload)
4004 ROOM_REJECTED — room_full or room_not_joinable
4005 RATE_LIMITED — pre-handshake connection limiter

The browser client emits client:kicked with { code, reason } parsed for you, so you can route each case to the right UI without peeking into the close payload yourself.

Graceful shutdown

A real deployment needs a clean SIGTERM path. rivalis.shutdown() destroys every room (firing onDestroy and kicking remaining actors with room_destroyed), then disposes every transport (closing live sockets with KICKED + 'server_shutdown'):

process.on('SIGINT',  async () => { await rivalis.shutdown({ timeoutMs: 5000 }); process.exit(0) })
process.on('SIGTERM', async () => { await rivalis.shutdown({ timeoutMs: 5000 }); process.exit(0) })

The timeoutMs is the upper bound for transport disposal. Sockets that have not closed by then get torn down.

When to reach for Rivalis

It is a good fit for:

  • Multiplayer games — turn-based or real-time, where you want a GameRoom subclass holding authoritative state and broadcasting deltas.
  • Chat / presence / collaborative cursors — presence: true and a couple of bound topics get you most of the way.
  • Collaborative editors — the binary-frame primitive plays well with CRDT payloads. Just plumb Yjs or Automerge updates into a topic.
  • Live dashboards with per-tenant rooms — roomId from your auth payload routes each tenant to their own room.

It is not a queue, an SFU, or a Pub/Sub between Node instances. If you need horizontal fan-out, you compose it — one Redis stream feeding many Rivalis nodes, each broadcasting to its locally-joined actors. The framework deliberately stays inside one process; that is what makes the room/actor model cheap.

A 60-second tasting menu of the surface area

// Server
const rivalis = new Rivalis({ transports: [...], authMiddleware: new MyAuth() })
rivalis.rooms.define('chat', ChatRoom)
rivalis.rooms.create('chat', 'global')
rivalis.connections                       // joined actors
rivalis.sockets                           // open sockets (incl. pre-handshake)
rivalis.logging.level = 'debug'           // built-in logger
await rivalis.shutdown({ timeoutMs: 5000 })

// Room
class GameRoom extends Room<MyData> {
    override maxActors = 4
    override joinable = true
    protected override presence = true
    protected override unknownTopicPolicy = 'drop'
    protected override onCreate() { this.bind('move', this.onMove) }
    protected override onJoin(actor) { actor.send('state', JSON.stringify(state)) }
    protected override onLeave(actor) { /* cleanup */ }
    private onMove(actor, payload) { this.broadcast('state', nextState) }
}

// Browser
const ws = new WSClient<MyTopics>(url, {
    reconnect: { maxAttempts: 8 },
    ticketSource: 'protocol',
    getTicket: refreshJwt
})
ws.on('client:connect', ...)
ws.on('client:kicked', ({ code, reason }) => ...)
ws.connect(jwt)
ws.send('move', encode({ dx: 1 }))

Install and play

npm install @rivalis/core ws @toolcase/base @toolcase/logging @toolcase/serializer
npm install @rivalis/browser

Both packages declare their @toolcase/* and ws dependencies as peers, so you control the versions in your app.

If you build something on top of it — a game, a tutorial, a CRDT bridge — please open an issue or a PR. Feedback on the security defaults and the binary-frame design is especially welcome.

Happy broadcasting.

This Week In React #282 : Security, Fate, TanStack, Redux, Jotai | Hermes-node, Expo, Rozenite, Harness | TC39, Bun, pnpm, npm, Yarn, Node

banner

Hi everyone, Seb and Jan here 👋!

It looks like security is going to be a hot topic this year! 😅

More packages are being compromised, and blog posts are also covering recent RSC vulnerabilities.

Maybe we’re reaching a tipping point, and better security practices will consolidate this year.

On the React Native side, Hermes-node is quite exciting, although it’s very early.

An exciting TC39 meeting is currently underway, and several proposals have already progressed.

Yarn and npm are improving on the security side.

Bun and pnpm are being ported to Rust.

💡 Subscribe to the official newsletter to receive an email every week!

banner

💸 Sponsor

Ship AI generated code safely with Meticulous.

Ship AI generated code safely with Meticulous.

Claude writes your code. Claude reviews your code. Claude fixes the review comments. And somehow, you’re the one getting paged at 2am when it breaks in prod.

Fortunately, top AI-driven teams like Dropbox, Notion, LaunchDarkly, and Wiz rely on Meticulous to run 1000s of e2e UI tests autonomously, covering every user flow, edge case, role and permutation. Built by ex-Palantir engineers, Meticulous gives you near-exhaustive coverage in weeks, without any developer effort. 

It works like magic in the background:

  • Near-exhaustive coverage on every test run
  • No test creation
  • No maintenance (seriously)
  • Zero flakes (built on a deterministic browser)

Check it out – and see why one engineering leader at Dropbox said that “once we started using Meticulous, we couldn’t imagine working without it.”

⚛️ React

Mini Shai-Hulud worm keeps digging

Mini Shai-Hulud worm keeps digging

Remember last week’s TanStack Router compromise? The dangerous worm from TeamPCP keeps compromising users and maintainers across ecosystems, affecting popular packages such as echarts-for-react and @antv, and GitHub actions such as actions-cool/issues-helper. OpenAI employees got compromised, leading them to regenerate code signing certificates. Grafana has been blackmailed by a ransomware group.The Million.js repository was also briefly compromised, but they seem to have gotten lucky: it apparently didn’t affect anyone.

Rumors also link this worm to the Nx Console VSCode extension compromise, and possibly connected to a major GitHub internal repo breach. This story isn’t over — “Mini” feels like a very questionable name 😅!

💸 Sponsor

Tomorrow Only: Next.js Debugging Workshop

Tomorrow Only: Next.js Debugging Workshop

Most Next.js bugs don’t fail loudly. They fail in a webhook handler at 3am, in a server component nobody touched, in an auth flow that worked yesterday. Sentry’s hands-on workshop shows you how to catch them with high-context logs and distributed tracing.

Last chance to save your spot. Register today.

📱 React-Native

🔀 Other

🤭 Fun

alt

alt

See ya! 👋

AI Copilot vs AI Agent Architecture – What’s Actually Different (And Why It Matters)

Copilot Architecture Explained

You’ve heard both terms thrown around in every product launch this year. AI copilot here, AI agent there. Microsoft slaps “copilot” on everything. Startups call their chatbots “agents.” Half the industry seems confused about where one ends and the other begins.

Let’s fix that.

This isn’t a marketing comparison. This is an architecture breakdown — how these two patterns actually differ under the hood, what tradeoffs each makes, and when you should reach for one over the other.

## What Is an AI Copilot?
An AI copilot is an assistive system that works alongside a human, augmenting their decisions without replacing them. Think of it as a very smart pair programmer who never grabs the keyboard unless you ask.

The core architectural trait: the human stays in the loop for every consequential action.

A copilot receives context (your code, your document, your spreadsheet), generates suggestions, and waits for you to accept, reject, or modify them. It doesn’t execute on its own. It doesn’t chain tasks together. It responds to your immediate intent and makes you faster.

GitHub Copilot is the canonical example. You type a function signature, it suggests the body. You press Tab or you don’t. The copilot never decides to refactor your codebase overnight.
Microsoft’s Copilot products across 365 follow the same pattern — a copilot agent embedded inside Word, Excel, or Teams that drafts, summarizes, and suggests while you retain full control. If you’ve wondered what is an agent in Copilot for Microsoft 365, it’s a scoped AI assistant that operates within a single application’s context, following your explicit instructions rather than pursuing goals independently.

## Copilot Architecture at a Glance

Copilot Architecture Explained

Key characteristics:
Single-turn interaction. You ask, it answers. There’s no multi-step planning.

Narrow context window. The copilot sees what you’re currently working on — the open file, the selected cells, the email thread.
No persistent memory across tasks. Each interaction is largely stateless.

No tool use or external actions. It generates text, code, or suggestions. It doesn’t call APIs, book meetings, or deploy code.

What Is an AI Agent?

An AI agent is an autonomous system that pursues goals over multiple steps, makes decisions about how to achieve those goals, and takes actions in the real world (or a digital environment) with minimal human intervention.

The core architectural trait: the agent decides its own plan of execution.

You give it an objective — “find the three cheapest flights to Tokyo in March, compare layover times, and book the best option” — and it figures out the steps, picks the tools, handles errors, and (ideally) delivers a result. You don’t approve every intermediate step. The agent operates with delegated authority.

This is a fundamentally different trust model from a copilot.

## Agent Architecture at a Glance

Agent Architecture Explained

Key characteristics:
Multi-step reasoning. The agent breaks a goal into subtasks and sequences them.

Tool use. Agents call external APIs, read databases, browse the web, write files, and trigger workflows.

Persistent state. They maintain context across steps and sometimes across sessions.

Self-correction. When a step fails, the agent re-plans rather than crashing.

Delegated autonomy. The human sets boundaries, but the agent navigates within them independently.

The Real Architectural Differences

Let’s get precise. Here’s where the two patterns diverge at the system level.

1. Control Flow

Copilot: Synchronous, human-driven loop. The user initiates every interaction. The system is reactive.

Agent: Asynchronous, goal-driven loop. The agent initiates its own actions after receiving a goal. The system is proactive.
This is the single biggest architectural difference. Everything else flows from it.

## 2. Planning Layer

Copilots don’t plan. They respond. A copilot doesn’t look at your codebase and think, “I should refactor this module first, then update the tests, then modify the API endpoint.” It waits for you to ask about each piece.

Agents plan explicitly. Modern agent frameworks — LangGraph, CrewAI, AutoGen — all include a planning step where the LLM decomposes a goal into ordered subtasks. Some use ReAct (Reason + Act) loops. Others use more structured plan-then-execute pipelines.

# Simplified ReAct loop in an agent
while not task_complete:
    thought = llm.reason(observation, goal, history)
    action = llm.select_action(thought, available_tools)
    observation = execute(action)
    history.append((thought, action, observation))
    task_complete = llm.evaluate(observation, goal)

A copilot never runs this loop. It runs the equivalent of a single llm.generate(context, prompt) call.

3. Tool Integration

Copilots are typically sandboxed. GitHub Copilot can’t open a pull request. Microsoft 365 Copilot can’t publish a SharePoint page without your explicit click.

Agents are defined by their tool access. An agent without tools is just a chatbot with aspirations. The tool layer — APIs, function calling, code execution, browser automation — is what makes an agent agentic. The AI agent Microsoft ecosystem, for instance, is rapidly expanding with Copilot Studio letting teams build agents that connect to Dataverse, Power Automate, and external APIs.

4. Memory Architecture

Copilots use short-term, session-scoped context. Your conversation history, maybe some retrieval-augmented generation (RAG) over your documents. When you close the tab, the context resets.

Agents need persistent memory. They track what they’ve already tried, what worked, what failed, and what’s left to do. This often means:

  • A working memory (current task state)**
  • An episodic memory (past interactions and outcomes)
  • A semantic memory (retrieved knowledge from vector stores or knowledge graphs)

5. Error Handling

Copilot error handling: the user sees a bad suggestion and ignores it. Done.

Agent error handling: the system must detect failures, reason about what went wrong, and either retry with a different approach or escalate to the human. This is where most agent implementations get brittle. Robust error handling is one of the hardest parts of AI agent development services — it’s the difference between a demo and a production system.

## What Are AI Agents, Really? A Taxonomy
Not all agents are created equal. The term gets applied to everything from a glorified chatbot to a fully autonomous research system. Here’s a practical spectrum:

Level 0 — Chatbot. Stateless Q&A. No tools, no memory, no planning. (This is not an agent, despite what some landing pages claim.)

Level 1 — Tool-augmented LLM. Can call functions and APIs, but follows a fixed, developer-defined workflow. Limited autonomy.

Level 2 — ReAct Agent. Reasons about which tools to use and in what order. Can handle novel situations within its tool set. This is what most people mean when they say “AI agent” today.

Level 3 — Multi-Agent System. Multiple specialized agents coordinate on a shared goal. One agent researches, another writes, another reviews. Frameworks like CrewAI and AutoGen target this pattern.

Level 4 — Fully Autonomous Agent. Sets its own subgoals, acquires new capabilities, operates over extended time horizons. We’re not here yet for production use cases, but research is active.

When to Build a Copilot vs an Agent

This is the practical question. Here’s a decision framework.
Build a copilot when:

  • The task requires human judgment that can’t be safely delegated (medical decisions, legal review, financial approvals)
  • The cost of a wrong autonomous action is high
  • Users want to stay in control and learn from the AI’s suggestions
  • The interaction is inherently single-turn: suggest, accept, move on
  • You need to ship quickly — copilots are architecturally simpler

Build an agent when:

  • The task involves multiple steps that are tedious for a human to orchestrate
  • The steps are well-defined enough that failure modes are manageable
  • The cost of a wrong intermediate step is low or recoverable
  • Users care about the outcome, not the process
  • You can define clear guardrails and boundaries for autonomous operation

Build a hybrid when:

  • The workflow has both routine and high-judgment steps
  • You want the agent to handle the boring parts and escalate the hard parts
  • This is increasingly the pattern: an agent that runs autonomously but checkpoints with the human at defined gates

## The Hybrid Pattern: Where the Industry Is Heading

The copilot-vs-agent framing is useful for understanding architecture, but the most practical systems blend both patterns. Microsoft’s own evolution shows this clearly — what started as a pure copilot agent pattern in 365 is steadily gaining agentic capabilities, where Copilot can now execute multi-step workflows in the background while still checkpointing with you.
The hybrid architecture looks like this:

User sets goal
  └─▶ Agent plans subtasks
        ├─▶ Subtask 1: Agent executes autonomously (low risk)
        ├─▶ Subtask 2: Agent executes autonomously (low risk)
        ├─▶ Subtask 3: Copilot mode — presents options, human decides (high risk)
        └─▶ Subtask 4: Agent executes autonomously (low risk)
              └─▶ Agent delivers result

The key design decision isn’t “copilot or agent.” It’s where to draw the autonomy boundary for each step in a workflow.

Practical Implications for Developers

If you’re building AI-powered products today, here’s what this means:

Start with a copilot, graduate to an agent. A copilot is lower risk, faster to build, and teaches you what your users actually want automated. Once you see which suggestions get accepted 95% of the time, those are your candidates for full automation via an agent.

Invest in your tool layer. Whether you’re building a copilot or an agent, the quality of your tool integrations determines the quality of your AI system. Well-typed function definitions with clear descriptions, proper error returns, and idempotent operations make both patterns work better.

Design for observability. Agents are harder to debug because they make their own decisions. Log every step: the plan, the tool calls, the observations, the reasoning. You’ll need this when (not if) something goes wrong.

Treat autonomy as a dial, not a switch. Give users control over how much autonomy the system has. Some users want full agent mode. Others want to approve every step. Build for both.

The Bottom Line

An AI copilot assists. An AI agent acts. The difference isn’t branding — it’s a fundamental architectural choice about who holds the decision-making authority at each step of a workflow.
Copilots are the safer, simpler starting point. Agents are more powerful but harder to build reliably. The future is hybrid systems that flex between both modes based on the risk and complexity of each task.

The question isn’t which one is better. It’s which autonomy level is appropriate for each step in your specific workflow.

Build accordingly.

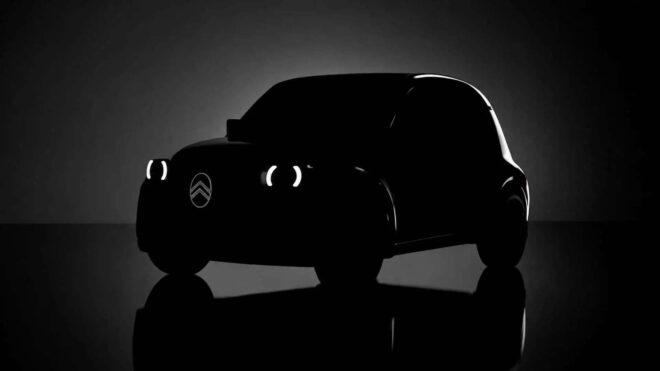
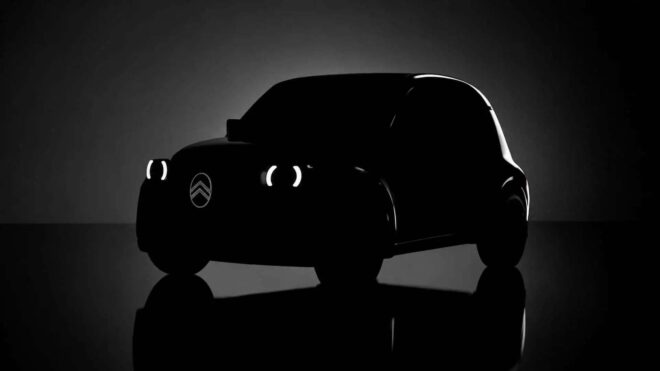
Efsane model Citroën 2CV, elektrikli olarak geri dönüyor

Citroën 2CV

Citroën 2CVBugün resmen yapılan doğrulamaya göre 1948-1990 yılları arasında üretilen efsane otomobil modeli Citroën 2CV, elektrikli olarak geri dönüyor. Gövde yapısı yukarıdaki fotoğraf ile gözler önüne serilen araç, aktarıldığı kadarıyla Avrupa’da 15 bin euro civarında satılacak. Tam olarak ekim ayında düzenlenecek 2026 Paris Otomobil Fuarı’nda görücüye çıkarılacak kompakt elektrikli, teknik olarak neler sunacak henüz bilinmiyor.

Efsane model Citroën 2CV, elektrikli olarak geri dönüyor yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Smart Contract Security: NEAR’s Futures Surge and AI Token Risks

Cover: Analyzing NEAR's Record Futures Open Interest Surge and Smart Contract Risks in AI Token Markets

Analyzing NEAR’s Record Futures Open Interest Surge and Smart Contract Risks in AI Token Markets

Friday’s market action saw AI-oriented tokens NEAR and FET sharply outperform many peers, signaling a pronounced rotation of speculative capital. NEAR’s price jumped by 28.5% accompanied by a surge in its futures open interest (OI) to a record 282.53 million tokens, while FET posted an 11.4% gain in the same timeframe. Meanwhile, privacy-focused coins such as DASH, ZEC, and XMR lost much of their gains from earlier in the week. This abrupt shift highlights the intersection of market dynamics and protocol risk—the steep price moves and elevated derivatives activity in NEAR, an AI ecosystem protagonist, create fertile ground for smart contract vulnerabilities, particularly those tied to oracle manipulation and flash loan exploits.

In this article, we explore the technical challenges developers face building AI-related smart contracts on NEAR and similar platforms amid these market pressures. The elevated futures OI in NEAR and the speculative waves driving tokens like FET demand a thorough look at how typical DeFi security pitfalls can escalate under these exotic conditions.

NEAR’s Futures Boom: What It Means for Developers

The surge to a record high of 282.53 million tokens in NEAR futures OI signals intense market leverage and positioning. On the one hand, rising open interest can reflect trader conviction and liquidity depth—on the other, it heightens systemic fragility. Large-scale derivatives exposure is often accompanied by rapid price moves and increased risk of cascading liquidations, events that adversaries can exploit by attacking oracle price feeds or draining liquidity pools via flash loans.

// Common vulnerable oracle usage pattern
contract VulnerableOracleUser {
    address public oracle;
    uint public price;

    function updatePrice() external {
        uint newPrice = Oracle(oracle).getPrice();
        require(newPrice > 0, "Invalid price");
        price = newPrice;
    }
}

In volatile markets, if a price oracle is manipulated temporarily—like during a flash loan attack—contracts that rely on its price for collateralization or liquidation thresholds can be tricked into executing unintended logic. NEAR’s recent price spike and futures activity underscore the criticality of oracle security and the risks when these oracles lack robustness against price spoofing or manipulation in a high-leverage environment.

Flash Loan Exploits: Amplified Risks in AI Token Ecosystems

Flash loans have become a double-edged sword, enabling composability and leverage but also providing attackers with tools to perform large-scale on-chain exploits in a single transaction. These attacks typically involve:

  • Borrowing huge capital instantly (no collateral)
  • Manipulating on-chain prices via oracle or pool interactions
  • Profiting from erroneous contract logic based on manipulated states

With AI sector tokens like NEAR and FET rallying, the speculative flows and derivatives volume heighten exposure. Flash loan attacks on such tokens can cause catastrophic collateral liquidations, severely amplifying market instability.

// Flash loan guard modifier example—blocks calls that change balances mid-transaction
modifier noReentrantFlashLoan() {
    require(!inFlashLoan, "No flash loan reentry");
    inFlashLoan = true;
    _;
    inFlashLoan = false;
}

Developers should build reentrancy guards and flash loan detection mechanisms, such as restricting asset balance changes mid-transaction or verifying that price updates come from decentralized, aggregated oracles immune to quick price swings.

Oracle Architecture Best Practices Under Market Stress

Oracle manipulation remains the top vector for attacks in fast-moving futures and spot markets. The best approach combines:

  • Multi-source data aggregation with median or trimmed mean pricing to prevent single-source outliers.
  • Time-delayed oracle updates to reduce flash price spike effects.
  • Circuit breakers or sanity checks to suspend trading if prices deviate wildly beyond thresholds.
Oracle Design Pattern Pros Cons
Single centralized oracle Simple, fast Vulnerable to manipulation
Aggregated decentralized feeds More secure, manipulation resistant Increased complexity and latency
Time-delayed feeds Protects against flash attacks Less responsive to real-time market moves

For NEAR and other AI-related protocols, developers must balance between responsiveness and attack surface reduction, especially as futures OI and market speculation intensify.

Altcoin Rotation and Institutional Movements: Impact on Risk Profile

Friday’s market dynamics illustrated clear altcoin rotation: speculative flows moved out of privacy coins DASH, ZEC, XMR, and into AI tokens and high-liquidity altcoins like HYPE (up ~60%) and ATOM (up 5% since midnight UTC). Additionally, institutions increased exposure to crypto-related equities, e.g., Ark Invest purchasing $5 million of Bullish (BLSH) shares over days.

Such rotation pushes developers building AI token smart contracts to continually evaluate the shifting risk landscape: elevated institutional participation often signals increasing derivatives leverage; meanwhile, retail speculation in emergent AI tokens increases volatility and the window for exploits.

Formal Security Pillars for AI Token Smart Contracts

Given the amplified risks illustrated by NEAR’s futures surge and market rotation, developers should emphasize:

// Example of a simplified flash loan resistant collateral update
function updateCollateral(uint256 newAmount) external {
    require(!flashLoanActive(), "Flash loan detected");
    collateral = newAmount;
    emit CollateralUpdated(newAmount);
}
  • Flash Loan Resistance: Detect and prevent flash loan-executed state changes.
  • Oracle Resilience: Use multi-asset oracles with time delay and anomaly detection.
  • Access Control: Restrict critical functions to trusted or multi-signature governance.
  • Emergency Stops: Implement pausable mechanisms to halt trading if anomalies detected.
  • Stress Testing: Simulate high volatility and liquidation cascades during audits.

In the team’s experience serving Web3 developers, surges in futures open interest and volatility—such as those recently observed with NEAR—often unmask latent oracle and composability weaknesses in smart contracts. Proactively addressing these vulnerabilities before market-induced crises arise is key to sustainable protocol security.

The AI token boom, exemplified by NEAR’s record futures open interest and price surge, presents a perfect storm of opportunity and risk for DeFi developers. Smart contract security under such conditions demands rigorous oracle design, flash loan defenses, and adaptive risk controls that can withstand rapid market shifts. The team I work with, Soken, specializes in auditing these complex AI and DeFi ecosystems, helping developers navigate emerging threats in unprecedented market cycles.

If you’re building or maintaining smart contracts in these high-stakes environments, carefully consider the behavioral patterns of futures markets and incorporate attack-resistant oracles and composability safeguards. Vigilance in these technical pillars ultimately shields your protocol against exploit vectors turbocharged by market speculation.

https://soken.dev/