ROKETSAN’dan TAYFUN ve SOM paylaşımı: Teslimatlar devam ediyor
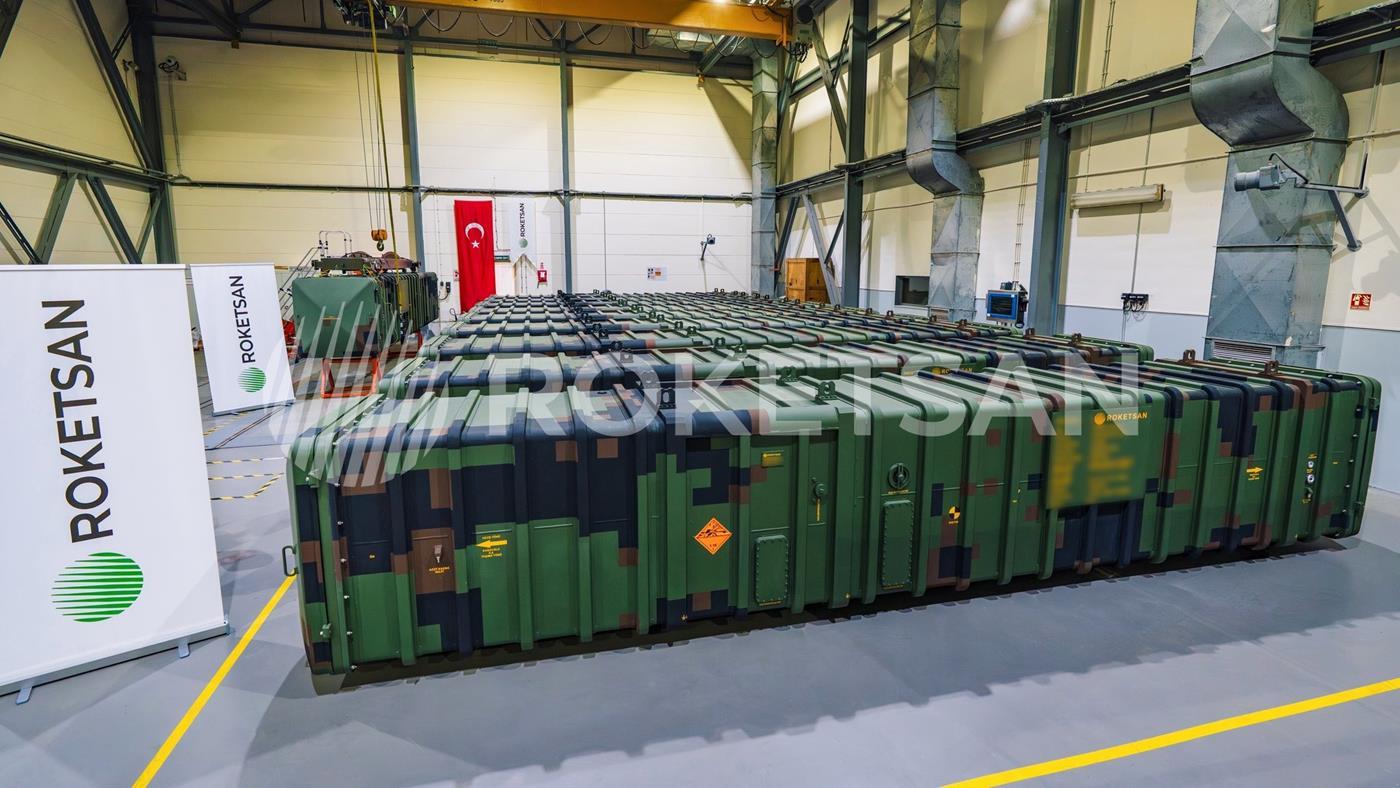
 Türkiye’nin savunma devi ROKETSAN, TAYFUN balistik ve SOM seyir füzesi için dikkat çekici paylaşım yaptı. ROKETSAN, seri üretim ve teslimatlar devam ediyor dedi.
 Türkiye’nin savunma devi ROKETSAN, TAYFUN balistik ve SOM seyir füzesi için dikkat çekici paylaşım yaptı. ROKETSAN, seri üretim ve teslimatlar devam ediyor dedi.
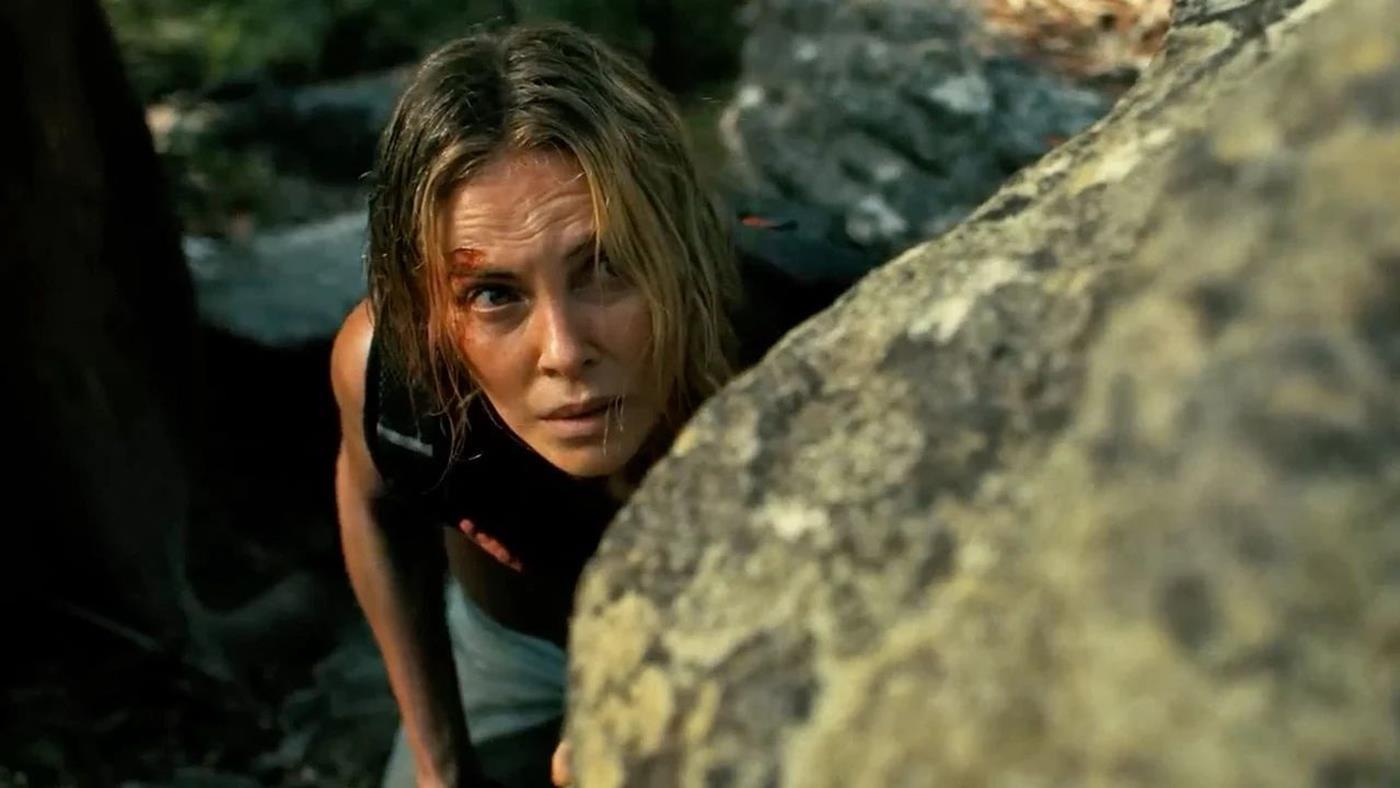
 Netflix, ünlü oyuncu Charlize Theron’un başrolünü üstlendiği aksiyon filmi Apex’in yeni fragmanını paylaştı. Film, bir seri katile karşı hayatta kalmaya çalışan bir kadının hikâyesini anlatıyor.
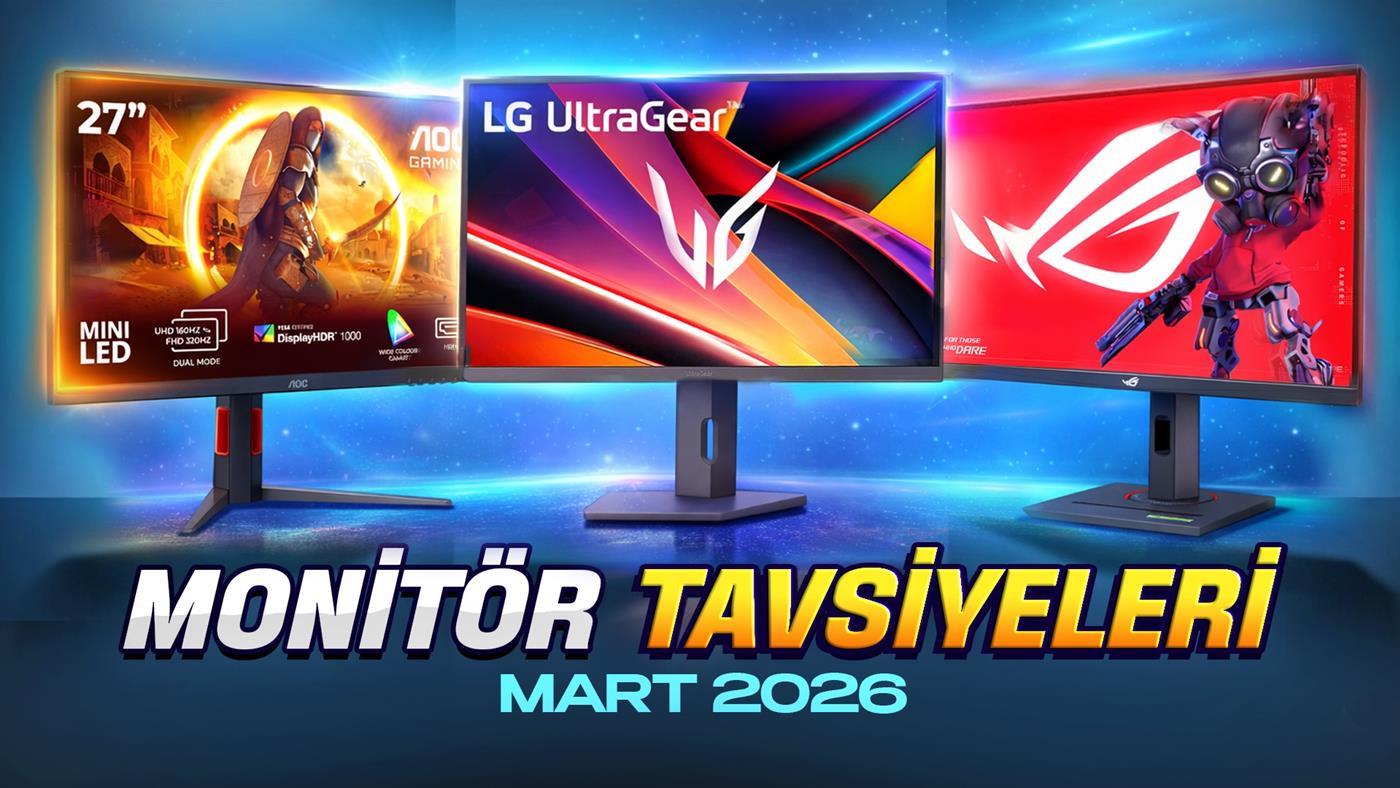
 Monitör tavsiyelerinde serisinin yeni bölümünde sizlere çeşitli ekran boyutlarında ve niteliklerde her işinize koşabilecek monitör önerileri yaptık.
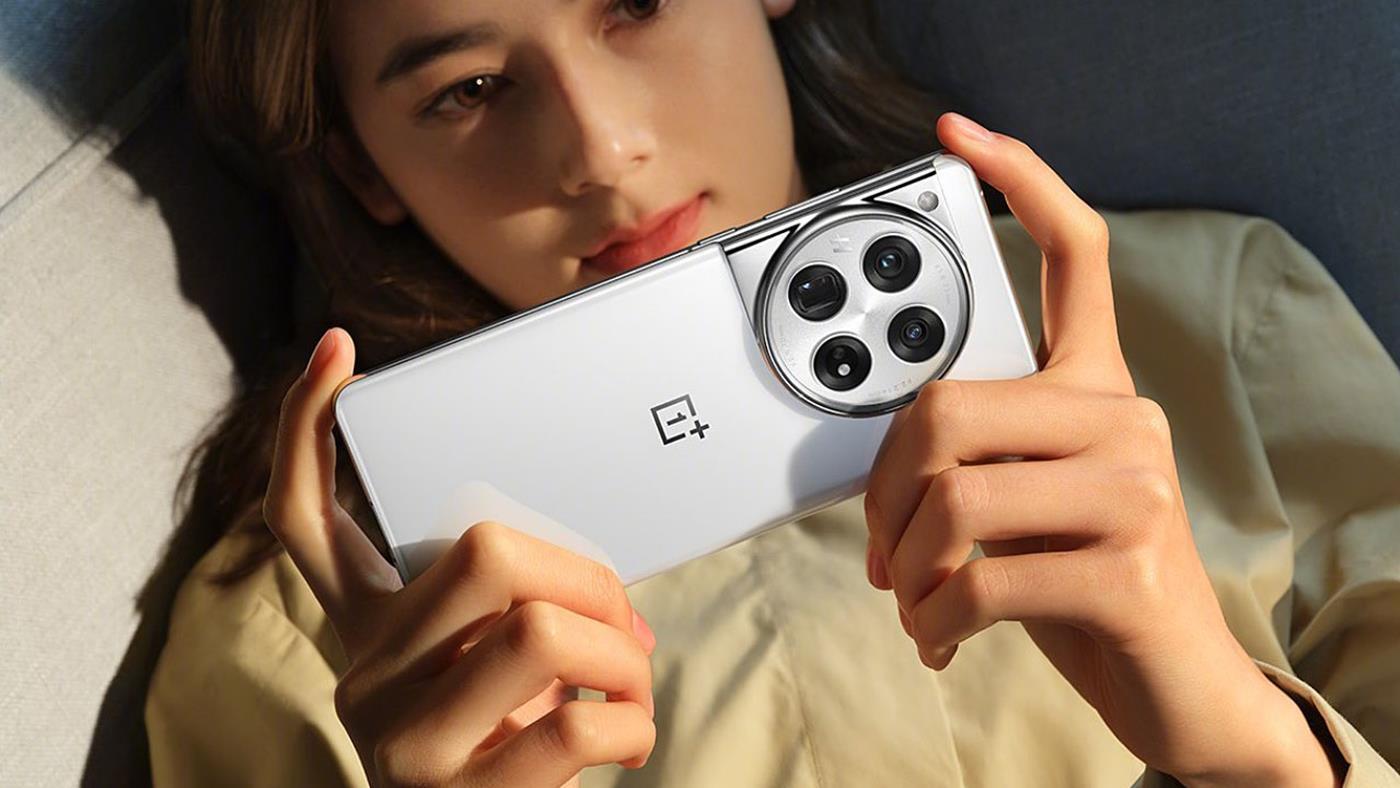
 OnePlus’ın ABD ve Avrupa pazarlarından çekileceği iddia ediliyor. Yeni raporlara göre şirket, Nisan 2026 itibarıyla bu bölgelerdeki operasyonlarını sonlandırabilir.
Why Your AI Agent Forgets Everything Between Sessions
The trending article “your agent can think. it can’t remember” hit 136 reactions because it exposes a fundamental flaw in how we build AI agents. Here’s the architecture that actually solves it.
The Core Problem
Every developer building AI agents hits this wall:
The Solution: A Three-Tier Memory Architecture
I’ve built and shipped this across multiple production agent systems:
Tier 1: Working Memory (Short-term)
Tier 2: Episodic Memory (Medium-term)
Tier 3: Semantic Memory (Long-term)
Implementation Sketch
interface MemoryLayer {
  working: WorkingMemory;      // In-context
  episodic: EpisodicMemory;    // Vector search
  semantic: SemanticMemory;    // Structured facts
}

async function recall(query: string): Promise<Memory> {
  // 1. Check working memory first
  const working = await workingMemory.get(query);
  if (working.relevance > 0.9) return working;

  // 2. Semantic search episodic
  const episodes = await episodic.search(query);

  // 3. Pull relevant facts
  const facts = await semantic.getRelated(query);

  return { ...working, ...episodes, ...facts };
}
The Secret Sauce: Memory Consolidation
The key insight is that you don’t need everything from past sessions. You need:
Results in Production
After implementing this architecture:
What’s Next
The next frontier is memory negotiation – agents that主动 forget low-value context to make room for what matters. But that’s a topic for next week.
This architecture powers my production agents. If you want the full implementation, check out the memory layer I open-sourced.


This problem looks confusing at first…
“Split the string so each character appears in only one part” . But once you see the pattern, it becomes very clean.
Key Idea
Each character has a last occurrence in the string.
-> If you know how far a character goes,
you can decide where to cut the partition
Approach (Simple Thinking)
Step 1: Store last position of each character
last[s[i] - 'a'] = i;
Now you know:
-> where each character must end
Step 2: Traverse and expand partition
Start from index 0
Keep updating end = farthest last occurrence seen so far
end = max(end, last[s[i] - 'a']);
Step 3: When i == end
You found a valid partition store its length start a new partition
Code (C++)
class Solution {
public:
    vector<int> partitionLabels(string s) {
        vector<int> last(26);

        //step 1:store last index
        for(int i = 0; i < s.size(); i++) {
            last[s[i] - 'a'] = i;
        }

        vector<int> res;
        int start = 0, end = 0;

        //step 2:expand window
        for(int i = 0; i < s.size(); i++) {
            end = max(end, last[s[i] - 'a']);

            //step 3:cut partition
            if(i == end) {
                res.push_back(end - start + 1);
                start = i + 1;
            }
        }

        return res;
    }
};
Example
Input: -> “ababcbacadefegdehijhklij”
Output: -> [9, 7, 8]
How to Think
Complexity
Time: O(n)
Space: O(1) (26 characters only)
What I Learned
In this blog post, we’ll dive into the technical details of Architects of Chaos, a physics-based building game where two AI agents compete to build the tallest and most stable structure.
The Concept
The core idea was to create a game that blends physics-based simulation with strategic AI decision-making. We wanted to see how different building philosophies (stability vs. height) would fare against each other and against unpredictable environmental challenges.
The Tech Stack
Architecture: Syncing React and Matter.js
The biggest technical challenge was keeping the React state and the Matter.js physics engine in sync. We used a central game loop within a useEffect hook in GameCanvas.tsx.
The Game Loop
The game loop is responsible for:
// Simplified game loop in GameCanvas.tsx
useEffect(() => {
  const runner = Matter.Runner.create();
  Matter.Runner.run(runner, engineRef.current);

  const updateLoop = setInterval(() => {
    if (gameState.isPaused) return;

    // Calculate metrics
    updateAgentMetrics(agentA, setAgentA);
    updateAgentMetrics(agentB, setAgentB);

    // Phase management
    if (gameState.phase === 'SETTLING') {
      // Check if all bodies have settled
      const allSettled = bodies.every(b => b.speed < 0.1);
      if (allSettled) {
        // Transition to next phase
      }
    }
  }, 100);

  return () => {
    Matter.Runner.stop(runner);
    clearInterval(updateLoop);
  };
}, [gameState.isPaused, gameState.phase]);
Real-Time Stability Metrics
One of the most engaging features of the game is the Real-Time Stability Gauge. Unlike simple height trackers, this gauge calculates structural integrity on the fly.
We factor in several physical properties:
When stability drops below 30%, the gauge enters a CRITICAL state, pulsing red to warn the player of an imminent collapse.
AI Agents: Strategy vs. Ambition
The AI agents, Fortress Architect and High-Rise Maverick, have distinct building strategies implemented in src/logic/ai.ts.
// Example AI logic for Fortress Architect
export function getAgentAMove(agentBodies: Matter.Body[], plotRange: [number, number], round: number, difficulty: Difficulty): BlockPlacement {
  // ... logic to find a stable spot near the center of existing mass ...
  const avgX = agentBodies.reduce((acc, b) => acc + b.position.x, 0) / agentBodies.length;
  let x = avgX + (Math.random() - 0.5) * jitter;

  // Ensure the block stays within the plot boundaries
  x = Math.max(plotRange[0] + halfWidth, Math.min(plotRange[1] - halfWidth, x));

  return { type, x, rotation };
}
🌪️ Environmental Challenges: Adding Chaos
To make the game more dynamic, we introduced environmental challenges like Slippery Ground, Earthquakes, and The Storm. These effects are triggered randomly and their intensity scales with the selected difficulty.
Architects of Chaos demonstrates how physics-based simulations can be integrated into a React application to create engaging and unpredictable gameplay. By combining strategic AI with dynamic environmental effects, we’ve created a game that is both fun to play and technically interesting to build.
Check out the full source code on GitHub.

“First make it work, then make it beautiful and robust.”
I’m a junior dev. I built a real app — Anahad — that real people use. And for a while, I was proud of it.
Then it grew. And I wasn’t so proud anymore.
This isn’t a textbook post about Clean Architecture. This is the story of what broke, why I finally made the switch, and what actually clicked for me — told by someone who was in the trenches with a messy codebase and had to ship features at the same time.
The Mess I Was Living In
Picture this: 6 features. Each with their own screens, widgets, blocs, services, and utils — all distributed across a directory structure that looked neat on day one and became a labyrinth by month three.
Most screens were monoliths — all-in-one files with UI and logic tangled together. The ones that did use components? Everything went into a global widgets/ directory. So you’d have prop drilling across three levels just to pass something that one widget needed. Tracking the flow of data meant hopping between directories, mentally stitching together a picture of how things connected.
Error handling was… creative. I’d built my own AsyncResult<Success, Error> sealed class — functional programming vibes without the actual library. It worked at the service layer, but it was an island. Nothing else was consistent.
And the worst part? My services were tightly coupled to Dio and the remote API. No abstraction. No interface. You couldn’t mock anything. You couldn’t test anything. If Dio failed, the whole thing failed, and you had to dig to figure out why.
The moment I truly felt it was when I had to trace a bug and found myself drilling through 5 directories just to understand the flow. That’s when I knew — this isn’t scaling. This is surviving.
What Is Flutter Clean Architecture, Actually?
Before I get into the migration, let me walk you through the structure — because once it clicked, I couldn’t unsee it.
Clean Architecture splits your app into three layers:

🎨 Presentation Layer
This is everything the user sees and touches.
The Bloc only talks to the Domain layer. It doesn’t know where data comes from. Doesn’t care.
🧠 Domain Layer
This is the pure heart of your app. No Flutter. No Dio. No Firebase. Just Dart.
LoginUseCase, FetchUserProfileUseCase)This layer has zero dependencies on anything external. It’s the most stable, most testable code in your app.
🗄️ Data Layer
This is where the real world connects.
The magic line? The Repository Implementation delegates data fetching to the datasource. The domain doesn’t care if it’s coming from the internet or a local cache.
Bloc → UseCase → Repository Interface
                        ↑
              Repository Implementation → Remote / Local Datasource
The Migration: Incremental, Not a Rewrite
Here’s the thing nobody tells you: you don’t have to nuke your codebase.
I had features to ship. Users on the app. I couldn’t just disappear for two weeks and “do clean architecture.” So I went incremental.
I started with the auth flow — the most self-contained, most critical part of the app. My service methods were already well-written, so the migration was mostly structural:
RemoteDataSource
Repository Implementation that satisfied the Domain’s abstract interfaceIt wasn’t that hard, honestly. But the payoff was immediate.
Now if I want to add offline support to Anahad? I create a LocalDataSource, and the Repository Implementation switches between them. The Bloc doesn’t change. The Use Cases don’t change. The Domain doesn’t even know it happened.
That’s the beauty.
fpdart and Functional Programming in Use Cases
Coming from a Rust background, I was already comfortable with Option and Result types. I’d even hacked together my own AsyncResult<Success, Error> sealed class before this migration.
When I discovered fpdart, it was like: oh, this is just the proper version of what I was already doing.
In my Use Cases, I now use Either<Failure, Success> for all return types. Left is failure, right is success — and you chain transformations cleanly without nested try-catches or nullable hell.
// Use Case
class LoginUseCase {
  final AuthRepository repository;

  LoginUseCase(this.repository);

  Future<Either<Failure, User>> call(LoginParams params) async {
    return await repository.login(params.email, params.password);
  }
}
// In the Bloc
final result = await loginUseCase(LoginParams(email: email, password: password));

result.fold(
  (failure) => emit(AuthError(failure.message)),
  (user)    => emit(AuthSuccess(user)),
);
No try-catch spaghetti. No “did this return null or did it actually fail?” ambiguity. The types tell the story.
The “Aha” Moment
I’ll be honest — my first reaction to Clean Architecture was “this is way too much boilerplate.”
Why write a Use Case class that just calls a repository method? Why create an abstract interface when I could just use the implementation directly? Seemed like over-engineering for the sake of it.
Then I migrated the auth flow. And something just… clicked.
I was looking at my Bloc, and I realized: this Bloc has no idea where the user data comes from. It doesn’t import Dio. It doesn’t know about Firebase. It just calls loginUseCase() and reacts to the result.
Before this, I couldn’t test anything because everything was tightly coupled. The service needed Dio, Dio needed a real network, the network needed… you get it. Now, because the Repository is an abstract interface, I can mock it in tests trivially:
class MockAuthRepository extends Mock implements AuthRepository {}
That’s it. Inject it. Test your Use Cases in complete isolation.
Ambiguity went away. I know exactly what each file does, what it depends on, and what it’s responsible for. When something breaks, I know which layer to look at.
Should You Use Clean Architecture for Every App?
No. Please don’t.
If you’re building a weekend project or learning Flutter for the first time, don’t start with Clean Architecture. You’ll spend more time setting up the structure than building the thing, and you’ll learn why the architecture exists without ever feeling the pain it solves.
The pain is the teacher.
Build the app. Ship it. Let it grow. Feel the moment where you’re drilling through 5 directories to trace a bug, where you can’t mock a thing for testing, where adding one feature means touching 8 files in 6 different folders.
Then reach for Clean Architecture. Because then you’ll understand it — not just intellectually, but in your bones.
The architecture exists to solve real problems. Let the problems teach you first.
Quick Reference: The Layer Cheat Sheet
| Layer | Contains | Depends On |
|---|---|---|
| Presentation | Screens, Widgets, Bloc | Domain only |
| Domain | Entities, Use Cases, Repository Interface | Nothing (pure Dart) |
| Data | Models, Repository Impl, Data Sources | Domain interfaces |
What’s Next for Anahad
If you’re a fellow junior dev with a production app that’s starting to smell — I see you. You don’t have to have everything figured out from day one. Build it, feel the pain, then build it better.
That’s not a failure. That’s engineering.
Built with love (and a lot of refactoring) while working on Anahad.
Hit me up on Twitter/X if this resonated — always happy to talk Flutter, architecture, or why Rust spoils you for everything else.

The Gap
75% of U.S. Catholics say they never go to confession or go less than once a year. Only 2% confess monthly. Those numbers come from Pew Research and CARA at Georgetown, and they’ve been trending in one direction for decades.
I built Mass Time, an iOS app with 280,000+ churches indexed, 60 prayers, and daily readings. I’ve watched the confession problem from the data side for years. People want to go. They feel anxious. They don’t know what to say. They haven’t been in so long that the guilt of not going becomes the reason they keep not going.
In 2025, the late Pope Francis declared a Jubilee Year and specifically called for increased access to the Sacrament of Reconciliation. The demand is real. The infrastructure isn’t.
So I built an AI confession guide. No AI will ever replace a priest. Only a priest can grant absolution. This is a preparation tool. You talk to your phone. It talks back. Seven languages. No keyboard. Just a conversation that helps you organize your thoughts before you walk into that booth.
It uses Amazon Nova 2 Sonic, a bi-directional speech-to-speech model, running on Amazon Bedrock AgentCore Runtime. The bugs I hit building it were the worst kind: silent, invisible, and plausible enough to make you doubt everything except the actual problem.
The Architecture
Simple on paper. Brutal in practice.

Nova 2 Sonic handles the heavy lifting. It takes raw audio in, processes speech bidirectionally, and sends audio back. No separate STT or TTS pipeline. One model, both directions, real-time.
The server is a Python 3.13 container on AgentCore Runtime. The client is native Swift with AVAudioEngine. No web views, no React Native. Seven polyglot voices: English (Matthew), French (Florian), Spanish (Carlos), Italian (Lorenzo), German (Lennart), Portuguese (Leo), and Hindi (Arjun). Users can switch languages mid-conversation and the AI follows.
Region constraint worth knowing: Nova 2 Sonic is only available in us-east-1, us-west-2, and ap-northeast-1. I learned the us-east-2 limitation the hard way when my first deployment returned a model-not-found error.
The Bug That Almost Shipped
Nova 2 Sonic never responded to speech. I tried the Strands Agents SDK. Raw API calls. Different prompts. Different voices. Nothing.
The audio RMS values from the mic looked normal. Waveforms had energy. Everything seemed fine.
One line of Swift was wrong.
// WRONG: reads pointer-to-pointer memory (garbage audio)
Data(bytes: outBuf.int16ChannelData!, count: ...)

// CORRECT: reads actual audio samples
Data(bytes: outBuf.int16ChannelData![0], count: ...)
int16ChannelData is UnsafePointer<UnsafeMutablePointer<Int16>>. A pointer to an array of channel pointers. Without [0], you’re reading the pointer addresses themselves as audio samples.
The RMS looked plausible because memory addresses happen to have high values. The model received garbage that looked like audio in every metric except the one that mattered: it wasn’t audio.
I confirmed it by injecting known-good PCM on the server side. Model responded perfectly. Fixed the iOS code. Real mic audio worked.
One missing array subscript. Hours of debugging.
Two More Invisible Bugs
The app crashed on every AI response with _outputFormat.channelCount == buffer.format.channelCount. AVAudioPlayerNode was connected with the mixer’s stereo format but I was scheduling mono buffers. Nova 2 Sonic outputs 24kHz mono PCM. The mixer expects stereo by default.
Fix: connect the player node with an explicit mono format matching the model’s output.
let playFmt = AVAudioFormat(
    commonFormat: .pcmFormatInt16,
    sampleRate: 24000,
    channels: 1,
    interleaved: true
)!
audioEngine?.connect(playerNode!, to: audioEngine!.mainMixerNode, format: playFmt)
Key detail that isn’t obvious from the docs: Nova 2 Sonic input is 16kHz 16-bit mono PCM, but output is 24kHz 16-bit mono PCM. Different sample rates in each direction.
Then the mic auto-unmute timer never fired. After the AI spoke, the mic stayed muted permanently. No error. No warning. Just silence.
Timer.scheduledTimer was called from the WebSocket callback thread. That thread has no RunLoop. The timer was created, registered to nothing, and quietly ignored. This is one of those iOS gotchas that experienced developers know and everyone else discovers at 2 AM.
The Cognito Session Policy Trap
This one is invisible and will waste your entire day.
Cognito Identity Pools have two auth flows: Enhanced (default) and Basic (classic). Every tutorial uses Enhanced. It works fine for S3, DynamoDB, Lambda.
It does not work for Amazon Bedrock (currently).
Enhanced flow calls getCredentialsForIdentity, which injects a restrictive session policy that limits credentials to a subset of AWS services. Bedrock is not in that subset. Your IAM role policy can be perfect. You’ll still get AccessDeniedException.
The error message says “no session policy allows” but doesn’t tell you Cognito is injecting it. You can’t see this policy in IAM, CloudTrail, or the Cognito console. It’s completely invisible.
Fix: one boolean in CDK.
const identityPool = new cognito.CfnIdentityPool(this, 'Pool', {
    allowUnauthenticatedIdentities: true,
    allowClassicFlow: true,  // This is the entire fix
});
On the client side, the classic flow requires three calls instead of one: getId → getOpenIdToken → STS AssumeRoleWithWebIdentity. The STS call is an unsigned HTTP POST, so you don’t even need the STS SDK.
One boolean. Hours of debugging. Not documented clearly anywhere. This affects all Bedrock actions, not just Nova 2 Sonic.
Frugal Architecture: 60 Concurrent Sessions, Zero Quota Increases
Werner Vogels talks about the Frugal Architect: cost-aware design as a first-class engineering concern, not an afterthought. This project runs on my personal AWS account. No technical account manager. No need to request quota increases through a support plan. No need for using my “AWS Hero” Card.
Nova 2 Sonic has a default service quota of 20 concurrent InvokeModelWithBidirectionalStream requests per region (check your Service Quotas console under Amazon Bedrock for the exact current value). That’s 20 simultaneous confessions per region before you hit throttling.
Instead of requesting a quota increase, I built a queue-based routing system across all three available regions.
REGIONS = ['us-east-1', 'us-west-2', 'ap-northeast-1']
MAX_PER_REGION = 20

def pick_region(counts):
    best = None
    for region in REGIONS:
        c = counts.get(region, 0)
        if c < MAX_PER_REGION and (best is None or c < counts.get(best, 0)):
            best = region
    return best
3 regions × 20 concurrent sessions = 60 simultaneous confession sessions. On default quotas. No support ticket. No TAM call.
The latency difference between regions is negligible for this use case. A confession guide isn’t a trading bot. An extra 80ms of round-trip to Tokyo doesn’t matter when the conversation has natural 2-second pauses between turns.
Design around the constraints you have instead of asking for the constraints to be removed.
Nova 2 Sonic Configuration That Matters
Turn detection sensitivity set to LOW for confession preparation. That’s roughly a 2-second pause before the model responds. You want thoughtful pauses in this context, not rapid-fire conversation.
await send_evt({"event": {"sessionStart": {
    "inferenceConfiguration": {"maxTokens": 1024, "topP": 0.9, "temperature": 0.7},
    "turnDetectionConfiguration": {"endpointingSensitivity": "LOW"}
}}})
Available values: LOW, MEDIUM, HIGH. For most conversational use cases, MEDIUM is fine. For reflective, thoughtful conversations, LOW gives the user space to think.
Connection limit is 8 minutes per WebSocket connection. For longer sessions, AWS provides a session continuation pattern in their samples.
System prompt gotchas worth knowing:
{ "interrupted": true } as JSON text during barge-in. Filter it server-side or your transcript gets polluted with raw JSON. Echo Cancellation: Still an Active Problem
The iPhone speaker plays the AI’s voice. The mic picks it up. The model hears itself and responds to its own echo. This is the hardest problem in the entire project.
Four approaches, in order of desperation:
contentEnd means the server finished sending, not the speaker finished playing.scheduleBuffer completion handlers. Better timing, still some leakage.The official AWS Python sample never mutes the mic. Audio flows continuously in both directions. Nova 2 Sonic has built-in turn detection and handles echo internally. That works better on desktop where mic/speaker separation is cleaner. On a phone speaker, it’s a different story.
Current approach: silence-based muting + playback completion unmute + prompt-level echo awareness. Works about 90% of the time. The other 10% is still an active problem.
The Economics
Nova 2 Sonic pricing (per 1K tokens): $0.0034 speech input, $0.0136 speech output. That works out to roughly $0.02/min combined.
A 5-minute session costs about $0.10. Not $1. Not $5. Ten cents.
At $1.99 per session, after Apple’s 30% cut ($1.39 net), that’s about $1.29 profit per paid session. The margins are real.
The freemium flow: 1 free minute (configurable via DynamoDB, no app update needed), then a paywall. Pay $1.99 to continue for up to 5 minutes. A 30-second grace period after the paywall gives users time to decide. The free minute costs about $0.02 to deliver. Even if nobody converts, the free tier costs almost nothing to run.
| Per Session | |
|---|---|
| Nova 2 Sonic cost (5 min) | ~$0.10 |
| User pays | $1.99 |
| Apple’s 30% cut | -$0.60 |
| Net to developer | $1.39 |
| Profit | ~$1.29 |
Session recordings are AI audio only, stored locally on the user’s device. Never on servers. The user can save and share via the standard iOS share sheet.
Total AWS infrastructure cost for the backend? Lambda, DynamoDB, API Gateway, AgentCore Runtime. On a personal account with low traffic, we’re talking single-digit dollars per month before any sessions even happen.
What’s Next: AgentCore WebRTC
On March 20, AWS announced WebRTC support for AgentCore Runtime. This is a big deal for this project.
Right now, the audio path is: iPhone → WebSocket → AgentCore → Nova 2 Sonic. WebSocket works, but it’s a text-based protocol carrying base64-encoded audio. Every audio frame gets encoded, wrapped in JSON, and decoded on the other end.
WebRTC is purpose-built for real-time media. Binary audio frames. Built-in echo cancellation at the protocol level. Adaptive bitrate. Jitter buffers. All the things I’ve been fighting to implement manually in Swift.
The migration path is straightforward since AgentCore Runtime supports both protocols on the same runtime. I can add a WebRTC endpoint alongside the existing WebSocket one and A/B test latency and echo cancellation quality on real devices.
If WebRTC’s built-in echo cancellation works well on iPhone speakers, that solves the hardest remaining problem in the entire project. That 10% failure rate on echo could drop to near zero.
What I’d Do Differently
Verify audio end-to-end on day one. Inject a known sine wave, record what the model receives, compare. Would have saved hours of headache.
Start with the classic Cognito flow. Don’t even try enhanced flow with Bedrock. It won’t work and the error messages won’t tell you why.
Build echo cancellation as a first-class feature, not an afterthought. On mobile, this is the hardest problem. Budget time for it.
Use Docker assets (ECR) for AgentCore from the start. Code assets (S3) seem simpler to package but the cold start timeout makes them impractical for anything with dependencies.
Design for multi-region from day one. The frugal routing across three regions was an afterthought that should have been the starting architecture. Default quotas are generous if you think horizontally.
The Point
1.39 billion baptized Catholics worldwide. A sacrament that many want to practice but feel unprepared for.
This isn’t about replacing priests. It’s about removing the anxiety barrier that keeps people from showing up in the first place. A 5-minute voice conversation that helps you organize your thoughts, in your own language, on your own time. For ten cents of compute.
Building this was fast. The debugging was not. Every major bug was the invisible kind: plausible RMS values hiding garbage audio, silent timers on runloop-less threads, session policies you can’t see in any console. The documentation had gaps. Echo cancellation on a phone speaker remains partially unsolved.
Most of the code was written with Kiro CLI. What would have taken weeks of back-and-forth between Swift, Python, and CDK was done in hours.
But someone will open this app before their first confession in 20 years. And they’ll feel a little less anxious walking in.
That’s worth ten cents. Now go build.
What looks like productivity acceleration is quietly erasing the recovery time built into every engineering day.
I started noticing it in my engineers first. In one-on-ones. In how the same conversations sounded different toward the end of a sprint. I heard it enough times across enough people that I started looking for it deliberately. Then I noticed it in myself. I’m not coding more than half my hours. My work is reviewing, deciding, evaluating … across systems, teams, timelines. And I was still running out of steam by Wednesday. We went from running a marathon to sprinting a marathon. Same course. Same distance. But you can’t sprint a marathon and finish the same.
Recovery Time Was Hidden in the Friction
Before AI, engineering had something built into it that nobody named. Recovery time.
Not blocked time. Not wasted time. Recovery time.
The build step that took four minutes. You’d flip to a browser tab, refill your coffee, let your brain sit in neutral for a moment. Not thinking about architecture. Not evaluating anything. Just waiting.
Writing boilerplate by hand was tedious. But tedious was the point. Low stakes. Low cognitive demand. Your hands typed while your mind coasted. There was no decision in it. Just the satisfying click of producing something familiar.
Refactoring a module you knew felt almost meditative. You knew the code. You knew what needed to move. The work had grooves. Your attention could settle into something easy while the harder thinking finished processing in the background.
None of this felt like rest. Even to the engineers themselves.
But it was rest. The throttle built into every engineering day.
Those pockets of low demand weren’t friction to optimize away. They were the throttle that kept a sustainable pace sustainable.
What AI Actually Replaced
AI didn’t just speed up those tasks. It replaced them. Not with the same tasks done faster … with entirely different tasks.
The build runs in 45 seconds now. Those four minutes are gone. And they’ve been replaced with four minutes of reviewing what the model generated.
The boilerplate writes itself. The time you saved is filled with evaluating whether it fits your architecture, follows your conventions, doesn’t introduce patterns that will calcify into problems eighteen months from now.
Every minute that used to be low stakes is now high stakes. Does this output pass the test. Does it pass the test and make sense. Does it make sense and not create downstream debt.
Every minute is an evaluation.
There’s no coasting anymore. There’s no meditative refactoring. There’s no four minute reset. There’s a stream of decisions, each one flowing directly into the next with no gap in between.
Engineers spent years training one cognitive muscle. The traditional approach to programming built a specific rhythm into the work … heavy judgment, then recovery. Heavy judgment, then recovery. The boring tasks were the low-intensity reps between hard sets.
Then came the mandate. Overnight, it demanded a completely different muscle. The training cycle that built the first one had no equivalent for the second. The new game started at full intensity immediately.
The Mental Model Most Leaders Are Running
If you lead engineers, you’re carrying this belief … AI saves time, so engineers should have more capacity.
It’s a reasonable belief. It just doesn’t map to what’s happening.
AI compresses effort so engineers hit cognitive walls earlier.
Compression is different from reduction. If a sprint used to contain forty hours of varied cognitive demand, AI compresses the low demand portions to nothing. The engineer doesn’t end up doing less. They end up doing all of it, in less time, with no recovery built in.
The output looks the same for a while. Maybe it looks better. The metrics move. The velocity numbers read well. I’ve written about what those numbers actually measure and what happens when leaders mistake them for health. The pattern is consistent … things look fine until they suddenly don’t.
AI compresses effort so engineers hit cognitive walls earlier.
What It Looks Like in Practice
Cognitive overload doesn’t announce itself. It doesn’t look like someone staring at a blank screen. It looks like things getting approved that shouldn’t. Pull requests that should have been flagged, that weren’t. Architectural shortcuts that nobody questioned in review, even though three people in that room would have caught the same thing six months ago.
The quality of decisions drops before the quantity of output drops.
By the time the output is visibly degraded, the problem has been compounding for weeks.
One signal worth watching … when your best engineers stop asking why in planning. When the people who used to push back on the framing of a problem start accepting the framing and jumping straight to solution. That’s not a focus improvement. That’s cognitive depletion showing up as compliance.
The engineers who are best at their jobs are also the most likely to push through the wall without telling anyone. Not because they’re hiding it. Because their mental model for feeling off is “I need to work harder to get back on top of things.” They’re trying to solve their way out of the problem that is the problem.
The Question Worth Asking
Look at your team’s calendar for tomorrow. Not the meetings … look at the time engineers spend building.
Ask one question about that time. Where are the moments when nobody is asking them to evaluate anything?
Where is the work that doesn’t require judgment to complete? Where is something low stakes, familiar, with grooves?
If you can find it … protect it. Don’t fill it with more AI generated output to review. Don’t schedule a ceremony into it. Let it be what it is.
If you can’t find it … you’re not looking at a capacity problem. You’re looking at a depletion problem. And it will surface on your team before it surfaces in your metrics.
What This Actually Requires
This isn’t an argument against AI tooling. The tooling is useful.
Nobody is built for sustained high stakes evaluation all day. There is a ceiling, and it isn’t a software limitation. What AI changes is how fast you reach it.
Remove the throttle without acknowledging what the throttle was doing … and the pace becomes the problem.
Give engineers work that costs less to evaluate. Protect the moments when judgment isn’t required. Design the pause into the day now that the workflow stopped doing it automatically.
Some of that is task design. Some of it is how you structure rituals and reviews. Some of it is recognizing that when an engineer asks for a day to work on something slower, they are not being resistant to change. They are self-regulating. Let them.
Your job as a leader is not to maximize the utilization of your engineers’ cognitive capacity. It’s to sustain it.
Your job as a leader is not to maximize the utilization of your engineers’ cognitive capacity. It’s to sustain it. If you can’t find the recovery time in your team’s day, you’re not running a productive engineering org. You’re running a depletion schedule.
One email a week from The Builder’s Leader. The frameworks, the blind spots, and the conversations most leaders avoid. Subscribe for free.