connpool: A Zero-Alloc TCP Connection Pool for Go

The Story

Years ago, when I first needed TCP connection pooling in Go, I found fatih/pool. It was elegant, simple, and it taught me a lot about channel-based pooling design. It was a real inspiration.

But as I worked on high-throughput systems at scale, I kept running into gaps: no health checks, no idle eviction, no lifetime management, no metrics. I’d bolt these on as wrappers, and eventually realized I was maintaining a full pool implementation anyway.

So I built connpool — taking the channel-based foundation that fatih/pool popularized and adding the features that production systems actually need.

Introducing connpool

github.com/soyvural/connpool — a production-grade TCP connection pool for Go.

go get github.com/soyvural/[email protected]

Zero dependencies. ~370 lines of code. Zero-alloc fast path.

Quick Example

cfg := connpool.Config{
    MinSize:     5,
    MaxSize:     20,
    Increment:   2,
    IdleTimeout: 30 * time.Second,
    MaxLifetime: 5 * time.Minute,
    Ping: func(c net.Conn) error {
        c.SetReadDeadline(time.Now().Add(time.Millisecond))
        buf := make([]byte, 1)
        if _, err := c.Read(buf); err != nil {
            if netErr, ok := err.(net.Error); ok && netErr.Timeout() {
                c.SetReadDeadline(time.Time{})
                return nil // timeout = alive
            }
            return err // dead
        }
        c.SetReadDeadline(time.Time{})
        return nil
    },
}

pool, _ := connpool.New(cfg, func() (net.Conn, error) {
    return net.DialTimeout("tcp", "localhost:6379", 5*time.Second)
}, connpool.WithName("redis-pool"))
defer pool.Stop()

conn, _ := pool.Get(ctx)
defer conn.Close() // returns to pool

// If the connection is broken:
pool.MarkUnusable(conn)
conn.Close() // destroys instead of returning

What Makes It Different

1. Health Check on Get()

Every Get() call validates the connection before returning it. The check order is optimized — cheapest first:

Lifetime check (time comparison) → Idle check (time comparison) → Ping (network I/O)

Time comparisons cost nanoseconds. The expensive network ping only runs if the connection passes the time-based checks. If a connection fails health check, it’s discarded and the pool retries (up to 3 times) before growing.

2. Max Lifetime with Jitter

Connections have a maximum lifetime, but here’s the trick: each connection gets a 10% random jitter on its expiration.

Why? Without jitter, if you create 20 connections at startup, they all expire at the exact same moment — causing a thundering herd of reconnections. Jitter spreads the expiration across time.

func (c *Config) maxLifetimeWithJitter() time.Duration {
    if c.MaxLifetime <= 0 {
        return 0
    }
    jitter := time.Duration(rand.Int64N(int64(c.MaxLifetime) / 10))
    return c.MaxLifetime + jitter
}

This is the same pattern used by pgx and Vitess.

3. Background Evictor

Without a background evictor, stale connections only get cleaned up when someone calls Get(). If the pool is idle (no traffic), dead connections accumulate silently.

The evictor runs every 30 seconds (configurable), drains the channel, health-checks each connection, discards the stale ones, and replenishes to MinSize.

4. Zero-Alloc Fast Path

The pool uses a channel internally (inspired by fatih/pool‘s original design), not a mutex+slice. This gives us:

  • Natural blocking semantics (when pool is at max, Get() blocks on channel receive)
  • Non-blocking fast path via select/default
  • Zero heap allocations on the hot path
BenchmarkGetPut_Sequential    8,556,068    139.9 ns/op    0 B/op    0 allocs/op
BenchmarkGetPut_Parallel      5,075,728    245.1 ns/op    0 B/op    0 allocs/op

5. Context-Aware Get()

Get() respects context deadlines and cancellation. If the pool is exhausted and a connection doesn’t become available before the deadline, you get context.DeadlineExceeded — not a hang.

6. Comprehensive Metrics

stats := pool.Stats()
fmt.Printf("size=%d active=%d available=%dn",
    stats.Size(), stats.Active(), stats.Available())
fmt.Printf("idle_closed=%d lifetime_closed=%d ping_failed=%dn",
    stats.IdleClosed(), stats.LifetimeClosed(), stats.PingFailed())
fmt.Printf("wait_count=%d wait_time=%vn",
    stats.WaitCount(), stats.WaitTime())

Every metric you need for alerting and debugging — without pulling in a metrics library.

Benchmarks

goos: darwin
goarch: arm64
cpu: Apple M2 Pro
BenchmarkGetPut_Sequential    8,556,068    139.9 ns/op    0 B/op    0 allocs/op
BenchmarkGetPut_Parallel      5,075,728    245.1 ns/op    0 B/op    0 allocs/op
BenchmarkGetPut_WithPing        216,386   5571   ns/op   81 B/op    2 allocs/op
BenchmarkGetPut_Contended     2,405,068    478.7 ns/op    0 B/op    0 allocs/op

The fast path (sequential, no ping) runs at 139ns with zero allocations. Even under heavy contention (8 workers fighting over 2 connections), it stays under 500ns.

Design Decisions

Decision Why
Channel over mutex+slice Natural blocking, zero-alloc select/default fast path
Lifetime jitter Prevents thundering herd reconnection storms
Health check ordering Cheapest checks first (time → time → network)
Background evictor Don’t wait for Get() to clean dead connections
conn.Close() returns to pool Familiar net.Conn interface — no new API to learn

Inspired By the Best

This pool draws ideas from several production-grade systems:

Feature Where I Learned It
Channel-based pool fatih/pool
Idle timeout + max lifetime pgx, Vitess
Health check on borrow go-redis, Apache Commons Pool
Background evictor pgx, Apache Commons Pool, Vitess
Context-aware Get Vitess, pgx
MarkUnusable fatih/pool

Get Started

go get github.com/soyvural/[email protected]

The repo includes three working examples:

  • tcp-echo — basic pool usage
  • redis-proxy — pooling with health checks against Redis
  • load-balancer — round-robin across multiple backend pools

GitHub: soyvural/connpool

If you’re working with TCP connections in Go and need something more robust than a basic pool, give connpool a try. Star the repo if you find it useful — it helps others discover it.

I’d love feedback on the API design, especially if you have use cases I haven’t considered. Drop a comment or open an issue!

Why Erlang C Always Understaffs Your Call Center (And What to Use Instead)

A.K. Erlang published his queuing formula in 1917 to figure out how many telephone circuits the Copenhagen Telephone Company needed. Over a century later, call center managers still plug three numbers into an Erlang C calculator from a website that looks like it was built in 2003, get a number, and treat it as staffing truth. Then they wonder why Monday at 9 AM has a 12-minute wait time and Thursday at 2 PM has six idle agents.

The Erlang C formula is real math. It’s correct math. It just answers the wrong question for a real call center. Here’s what it assumes: calls arrive randomly (Poisson distribution), all agents are identical and interchangeable, no callers abandon, agents handle one call then immediately take the next, call arrival rate is constant, there’s no wrap-up time between calls, and nobody takes breaks, calls in sick, or goes to lunch. Exactly zero of these assumptions hold in practice.

But Erlang C is still where you start, because it gives you the mathematical floor — the minimum agents you’d need in a universe where everything works perfectly. Then you adjust for the real world, and the adjustment is where 95% of people stop too early.

The Gap Is Always 27-57%

After running staffing models across dozens of operations, the gap between what Erlang C says and what you actually need is remarkably consistent:

Scenario Calls/30min AHT Erlang C Says You Actually Need Gap
Small inbound support 30 300s 7 9-10 +29-43%
Medium sales inbound 80 240s 14 18-20 +29-43%
Large blended center 200 210s 26 33-37 +27-42%
Collections floor 50 180s 7 9-11 +29-57%
High-touch B2B sales 25 600s 11 14-16 +27-45%

That gap isn’t noise. It’s the accumulated weight of four factors that Erlang C completely ignores.

Factor 1: Shrinkage (25-35%)

Shrinkage is the percentage of paid time agents are unavailable to handle calls. Breaks (30 min/day), lunch (30-60 min/day), training and meetings (2-4 hours/week), coaching sessions, system issues (frozen computer, VPN dropout, softphone crash), unscheduled absences, late arrivals, and early departures.

The industry average is 30-35% for on-site centers and 35-40% for remote agents (home distractions, internet issues, longer breaks). Most operations discover their actual shrinkage is higher than they assumed.

The adjustment is simple: Adjusted agents = Erlang C agents / (1 - shrinkage_rate). If Erlang C says 19 and your shrinkage is 32%: 19 / 0.68 = 28 agents. Already a 47% increase from the raw number.

Factor 2: Occupancy Limits

Occupancy is the percentage of time an agent spends on calls versus waiting. At 84% occupancy, agents spend 50 minutes of every hour on the phone. That sounds efficient. It’s also a fast track to burnout. Sustainable occupancy depends on the work:

  • Inbound support (simple): 85-88%
  • Inbound sales: 78-82%
  • Outbound cold calling: 75-80%
  • Collections: 72-78%

If your staffing model produces 90%+ occupancy, expect a turnover problem within 60 days. Agents start calling in sick, taking longer breaks, and quitting. Replacing one agent costs $3,000-8,000 in recruiting, training, and ramp-up time. Running agents at 90% to save on staffing is one of the most expensive mistakes a call center can make.

Factor 3: Call Abandonment

Erlang C assumes callers wait forever. They don’t. 25% hang up after 30 seconds, 50% after 60 seconds, 70% after 120 seconds. This creates a vicious paradox: understaffing causes abandonments, which reduce apparent call volume, which makes Erlang C tell you that you need fewer agents. The formula rewards you for bad service.

The fix: add abandoned calls back into your volume calculation. Use total calls offered (answered + abandoned) as your input, not just answered calls. If any half-hour interval shows an abandon rate above 5%, that interval is understaffed. Period.

Factor 4: Multi-Skill Routing

If agents handle multiple queues (billing, sales, tech support), Erlang C breaks down. The formula assumes perfect pooling — all agents interchangeable. In reality, Agent A handles billing and sales, Agent B handles sales only, Agent C handles all three. This partial pooling is more efficient than separate queues but less efficient than the full pooling Erlang C assumes. Expect an 8-15% underestimate for multi-skill environments.

The Real Formula

Required staff = (Erlang_C_agents * (1 + multi_skill_factor)) /
                 (1 - shrinkage_rate) /
                 min(target_occupancy, 1.0) *
                 (1 + absenteeism_buffer)

For 120 calls per half-hour with 240-second AHT, 80/20 service level:

Erlang C raw:       19 agents
+ Multi-skill (10%): 20.9 agents
+ Shrinkage (32%):  30.7 agents
+ Occupancy (82%):  37.5 agents
+ Absenteeism (5%): 40 agents

Forty agents to do what Erlang C says you can do with nineteen. A 111% gap. And forty is the right number — anyone who’s run a 120-call-per-half-hour inbound operation knows that 19 agents would result in 15-minute hold times and mass abandonment.

Half-Hour Grids and Day-of-Week Adjustment

Your call volume isn’t flat. It spikes in the morning, dips at lunch, picks up in the afternoon. You need a staffing grid that calculates required agents for each 30-minute interval using your actual historical volume data.

Practical moves that make the grid work:

Stagger start times. If you need 25 agents at 8 AM and 40 at 9:30 AM, don’t have everyone clock in at 8. Bring them in waves — 5 at 7:00, 5 at 7:30, 10 at 8:00, 5 at 8:30, 10 at 9:00, 5 at 9:30.

Stagger lunches. Split 40 agents into 4 groups at 11:00, 11:30, 12:00, and 12:30. You lose 10 agents during each lunch slot instead of 40. This alone can drop your midday abandon rate by 60%.

Build separate grids for each day. Monday volumes are typically 15-25% higher than Friday. Using one staffing plan for every day means overstaffed on Friday and drowning on Monday.

Validate weekly. Compare your model’s predicted service level for each interval against what actually happened. If you’re off by more than 10%, recalibrate your shrinkage rate and AHT assumptions.

Outbound Is Different Math

Outbound staffing follows different rules because the dialer controls the pace. The key formula:

calls_per_agent_per_hour = 3600 / (avg_talk_sec + avg_wrapup_sec + avg_ring_sec / connect_rate)
required_agents = target_contacts_per_hour / calls_per_agent_per_hour

For B2B outbound with 10% connect rate, 180-second talk time, 30-second wrap-up: 7.8 contacts per agent per hour. Need 60 contacts per hour? That’s 8 productive agents, or 12 scheduled after shrinkage. If you need 300 contacts per day across an 8-hour shift, you need about 5 productive agents, which means 8 scheduled.

For blended campaigns (agents taking inbound and making outbound between calls), calculate the inbound staffing need first — that’s the hard constraint. Then figure out how much outbound capacity exists in the gaps. Don’t try to optimize both simultaneously in one formula. Calculate them separately and overlay the results.

Common Mistakes That Blow Up Staffing Models

Using daily averages instead of half-hour intervals. If your average daily call volume is 800, you might calculate that you need 25 agents. But if 200 of those 800 calls come between 9:00 and 10:00 AM, you need 40 agents during that hour and 15 the rest of the day. Daily averages hide the peaks that destroy your service level.

Ignoring AHT variance by agent. Your average AHT is 240 seconds, but Agent A averages 180 and Agent B averages 380. If Agent B is scheduled during peak hours and Agent A is on the quiet shift, your actual service level during peak will be much worse than the model predicts. Match your best agents (lowest AHT, highest conversion) to your highest-volume intervals.

Not accounting for new agent ramp-up. New agents typically have AHTs 40-80% higher than tenured agents during their first 30 days. If you’re onboarding 5 new agents and counting them as full-capacity resources, you’re overstating your actual handling capacity.

Treating blended campaigns like pure inbound. In a blended VICIdial environment, the moment inbound volume spikes, agents get pulled from outbound, the dial level drops, and your outbound throughput craters. Model the inbound constraint first, then figure out how much outbound capacity remains in the gaps.

Forgetting that breaks cluster. You schedule 15-minute breaks at 10:00 and 10:15 in two groups. But five agents take their break 8 minutes late, three come back 4 minutes late, and one disappears for 22 minutes. Your “planned” 15-minute break actually removes agents for 25-30 minutes. Build a 50% buffer on scheduled break durations.

Using answered calls instead of offered calls as input. If callers are abandoning because of long wait times, the answered volume is artificially low. Erlang C tells you that you need fewer agents based on this suppressed volume. Use total offered calls (answered + abandoned) to avoid the negative feedback loop.

The Bottom Line

The operations that get staffing right aren’t the ones with the best formula. They’re the ones that measure, compare, adjust, and repeat. Every week, forever. Pull last week’s actual volume, AHT, and service level by half-hour. Compare to your model. If the gap is more than 10%, update your assumptions. Run a two-week forecast. Recalibrate your baseline shrinkage percentage monthly from actual data.

Erlang C is a starting point. The real work is everything you layer on top and the discipline to keep your inputs fresh. A call center that gets staffing right — not once, but every week — runs at lower cost with better service levels than one that throws bodies at problems. The math isn’t hard. The discipline to keep updating your inputs is the hard part.

The difference between 80/20 and 90/10 service level targets can be 30-40% more agents for the same volume. That’s not a typo. The relationship between service level and staffing is exponential, not linear. Make sure your target actually matches your business needs before you build a model around it — a lot of operations run 80/20 by default because “that’s the industry standard” without ever asking whether their customers would be fine with 80/30.

For the complete implementation with Python Erlang C solver code, SQL queries for extracting AHT, shrinkage, and volume from VICIdial, half-hour staffing grid generators, and automated weekly validation scripts, see the full guide at ViciStack.

🚀 The Future is Now: AI, 6G & Space Tech.

👋 Hey everyone! I’m Mazeed — telecom engineer turned AI & space tech enthusiast. I’m obsessed with pushing the boundaries of technology, from next-gen networks to AI-driven space systems.

This community feels like the perfect space to share projects, ideas, and breakthroughs, and learn from people who are building the future today.

🔹 What I’ll Be Sharing

Topic What You’ll Get

AI in Telecom & 5G/6G Real-world pipeline setups, containerized models, CI/CD examples
Space Tech & Exploration Satellite comms, AI-driven orbital systems, futuristic projects
Deep Tech Career Growth Mindset, productivity, building in emerging tech
Hands-on Tutorials Mini guides, code snippets, deploy-ready demos

🛠 Mini Example: Real-Time 5G Traffic Prediction
import torch
from model import LSTMModel

model = LSTMModel()
model.load_state_dict(torch.load(“weights.pth”))
model.eval()

sample_input = torch.randn(1, 10, 5) # batch, sequence, features
prediction = model(sample_input)
print(“Predicted network load:”, prediction.item())

✅ Deployable on Kubernetes, auto-scalable, and ready for edge AI nodes.

📊 Visual Pipeline (Diagram)
+—————-+ +—————-+ +—————-+
| Data Ingestion | —> | Model Training | —> | Model Serving |
+—————-+ +—————-+ +—————-+
| | |
MQTT/Kafka PyTorch / TensorFlow Flask / FastAPI
| | |
+———————————————–+
Monitoring & Logging
Prometheus / Grafana / ELK

This is a simplified view of how AI pipelines for telecom & 5G/6G work — scalable, reliable, and real-time.

💡 Why I’m Here

I want this space to be collaborative — a place to share, discuss, and push limits together. Whether it’s AI, 6G, or space tech, let’s turn futuristic ideas into reality.

💬 Question for the community:
What’s the craziest tech idea you’re exploring right now?
Drop it below —
let’s brainstorm and collab!

5 AI Coding Mistakes That Waste Hours (and the Prompts That Fix Them)

You paste code into ChatGPT. You get an answer. It looks right. You ship it.

Two hours later, it breaks.

I’ve made every AI coding mistake in the book. Here are the five that cost me the most time — and the exact prompts I use now to avoid them.

Mistake 1: Asking for a Solution Without Explaining the Constraint

What happens: You say “write a function that sorts users by name.” The AI gives you a perfectly valid sort — that loads 50,000 records into memory.

The fix prompt:

I need a function that sorts users by name.

Constraints:
- Dataset: ~50k records, PostgreSQL backend
- Must use database-level sorting (no in-memory)
- Return paginated results (20 per page)
- Must work with the existing User model (id, name, email, created_at)

Show me the query and the controller method.

Why it works: Constraints turn “write me a sort” into “write me this sort.” The AI can’t over-engineer or under-engineer when boundaries are explicit.

Mistake 2: Accepting the First Output Without Verification

What happens: The code compiles. The tests pass (the ones the AI wrote). You merge. Then edge cases start exploding.

The fix prompt:

Before giving me the final version, do this:

1. List 3 edge cases that could break this function
2. Write a test for each edge case
3. Run the function mentally against each test
4. Fix any failures
5. Then show me the final version with all tests passing

This is the verification loop pattern. It adds 30 seconds to the prompt and saves hours of debugging.

Mistake 3: Dumping an Entire File and Saying “Fix It”

What happens: The AI has 4,096 tokens of context. You just used 3,800 on a file it doesn’t understand. The remaining 296 tokens produce garbage.

The fix prompt:

Here's a focused excerpt from auth.js (lines 42-78).
The bug: login() returns 200 even when the password is wrong.

Expected: return 401 for invalid credentials
Actual: returns 200 with an empty token

Only fix the authentication check. Don't refactor anything else.

Why it works: You did the triage. You isolated the problem. The AI can now be a surgeon instead of a detective.

Mistake 4: Not Telling the AI What “Done” Looks Like

What happens: You ask for “a REST API endpoint.” You get something. Is it done? You don’t know. The AI doesn’t know. You go back and forth five times.

The fix prompt:

Build a POST /api/invoices endpoint.

Done means:
- [ ] Validates required fields (amount, customer_id, due_date)
- [ ] Returns 201 with the created invoice
- [ ] Returns 422 with field-level errors for invalid input
- [ ] Includes a test for each scenario above
- [ ] Uses the existing Invoice model (no schema changes)

Checklists kill ambiguity. If you can’t write the checklist, you don’t understand the task well enough to delegate it — to a human or an AI.

Mistake 5: Using AI for the Wrong Part of the Job

What happens: You spend 20 minutes crafting the perfect prompt to generate a database migration. It would have taken 3 minutes to write it by hand.

The rule I follow now:

Task AI? Why
Boilerplate (CRUD, tests, types) ✅ Repetitive, low-risk
Business logic ⚠️ Only with clear spec
Architecture decisions ❌ You need to own these
Debugging (with context) ✅ AI is great at pattern-matching errors
Debugging (without context) ❌ Garbage in, garbage out

The best AI coding workflow is knowing when not to use AI.

The Pattern

Every mistake above has the same root cause: under-specified input.

The fix is always the same:

  1. State the constraint
  2. Define “done”
  3. Ask for verification
  4. Keep context small

That’s it. No frameworks. No plugins. Just better prompts.

What’s the AI coding mistake that costs you the most time? Drop it in the comments — I’ll write the fix prompt for it.

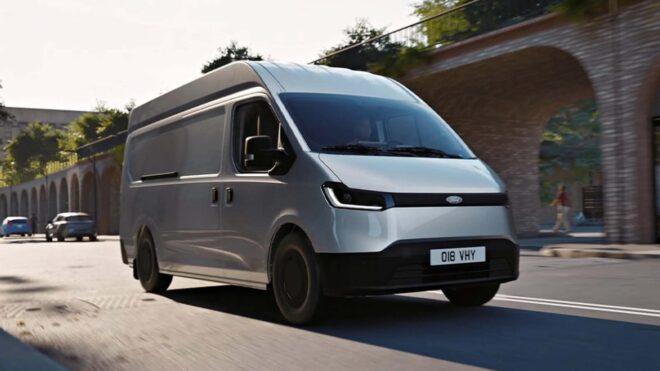
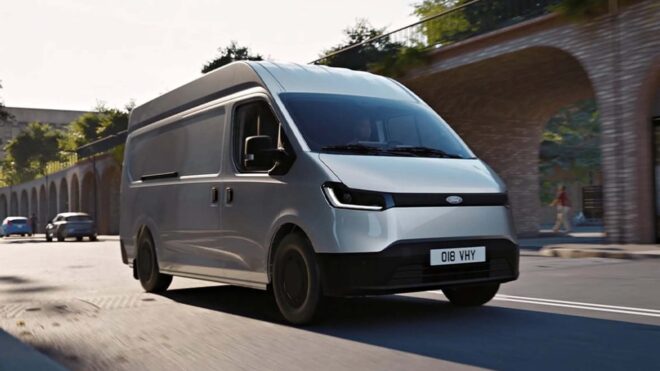
Ford, Avrupa pazarına özel Çinli Transit City’yi tanıttı

Ford, Avrupa pazarına özel Çinli Transit City’yi tanıttı

Ford, Avrupa pazarına özel Çinli Transit City’yi tanıttıABD merkezli otomobil devi Ford, Avrupa pazarına özel olarak tasarlanan “Çinli” Transit City’yi tanıttı. Üç farklı gövde tipinde sunulacak tamamen elektrikli ticari model, yapılan açıklamaya göre doğrudan Çin merkezli Jiangling Motors Corporation (JMC) tarafından geliştirilen bir platformu temel alıyor ve üretimin de doğrudan Çin’de yapılacağı belirtiliyor. Yük kapasitesi 1.085 kg ile 1.530 kg arasında değişen Transit City, öne konumlandırılan tek bir elektrik motoruyla 148 beygir güç sunuyor ve 56 kWh kapasiteli LFP batarya paketiyle yaklaşık 254 km menzil vadediyor. Spesifik olarak kısa mesafeli şehir içi taşımacılık ihtiyaçlarına yönelik olarak hazırlanan araç, 87 kW DC (maksimum değer) ile yüzde 10’dan yüzde 80’e 33 dakikada şarj edilebiliyor. Modelin şarj süresi 11 kW AC ile beş saat olarak açıklanırken, yeni Transit City’nin fiyatları henüz paylaşılmıyor.

Ford, Avrupa pazarına özel Çinli Transit City’yi tanıttı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

The Power of Simple Tools: Why Sometimes All You Need is a Counter

As developers and tech enthusiasts, we often get caught up in the “feature race.” We build complex systems, integrate AI into everything, and obsess over syncing data across every possible cloud. But over time, I’ve realized that the tools people actually stick with are often the ones that do exactly one thing—and do it perfectly.

Think about the small, repetitive tasks that pop up throughout the day: counting inventory in a warehouse, tracking sets at the gym, or even just tallying attendance at a local meetup. These aren’t massive engineering problems, but they are frequent ones. When you’re in the middle of a task, the last thing you want is to wait for a bloated app to load, sit through a 5-second ad, or—worst of all—be forced to “Create an Account” just to start counting.

This is why lightweight, browser-based utilities still feel like magic in 2026. They are “zero-friction.” You open a tab, you do the work, and you close it. No strings attached.

Lately, I’ve been focusing on this philosophy of “minimalist utility.” I wanted to see how much I could strip away while still making a tool incredibly useful. The result is onlinecounter.org.

In building it, I focused on two specific pain points I noticed in other tools:

Mobile-First Interaction: Most web counters feel clunky on a phone. I wanted something that felt like a native app—responsive, snappy, and easy to tap with one hand while you’re on the move.

The “Copy” Workflow: Usually, after you finish counting, you need that number somewhere else—a spreadsheet, a text message, or a note. Instead of making users manually type it out, I added a “one-click copy” feature. It’s a small detail, but it saves a massive amount of hassle.

I also made a conscious choice to skip “cloud sync.” By keeping the data strictly in your local browser, the site stays lightning-fast and respects your privacy. No data leaves your device; it’s just you and your tally.

At the end of the day, not every problem needs a “platform.” Sometimes, the most effective tools are the ones that quietly do their job, stay out of your way, and let you get back to what really matters.

If you’re looking for a straightforward, ad-free way to keep track of… well, anything… feel free to give it a try:
https://onlinecounter.org/

Because sometimes, less really is more.

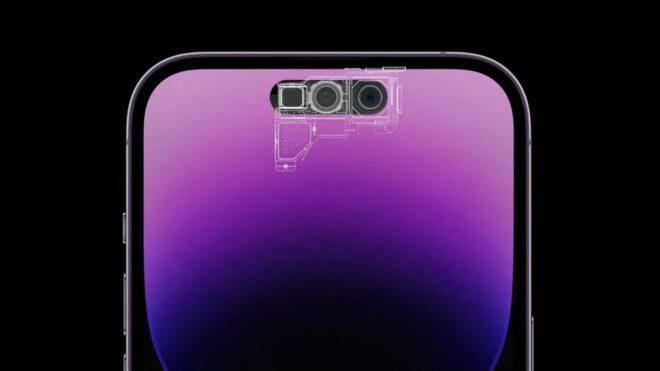
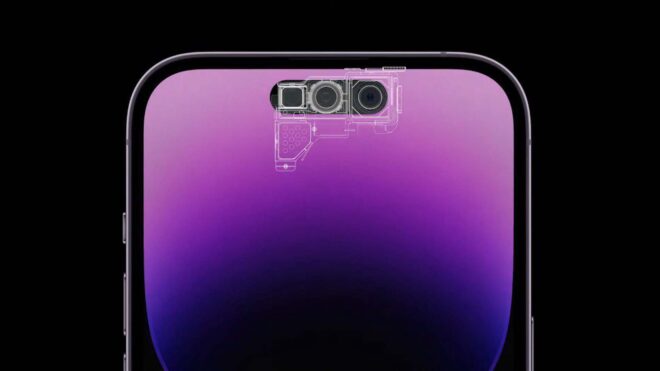
iPhone 20, dört kenardan kavisli tam ekran deneyimi sunabilir

iPhone Apple

iPhone AppleGeçtiğimiz günlerde bir Çinli kaynak, Apple’ın Face ID’ye güç veren donanımları ekranın altına almaktan uzak olduğunu iddia etmişti. Bu açıdan gerçek tam ekran deneyimi sunacak ilk iPhone’un yakında gelmeyeceği ve şirketin bunun yerine Dynamic Island’ı küçültmeye odaklandığı belirtilmişti. Kamera ve sensörleri ekran altına alma konusundaki geliştirme çalışmalarında sıkıntılar yaşadığı öne sürülen şirket, son bilgilere göre birçok kullanıcının hayalini 2027’nin sonunda tanıtılması beklenen iPhone 20 ile gerçeğe dönüştürebilir. Apple bu modelle birlikte dört kenardan kavisli yapıda tam ekran deneyimi (ekran altı selfie kamerası ve Face ID ile) sunabilir. Dört kenardan kavisli tasarımla neredeyse çerçevesiz bir cihaz elde edeceği öne sürülen Apple, 2026’nın eylül ayında karşımıza Dynamic Island’a sahip olacak iPhone 18 Pro, 18 Pro Max ve ilk katlanabilir iPhone modeliyle çıkacak. Çok merak edilen yatay formlu katlanabilir iPhone’da Face ID yerine yana entegre Touch ID parmak izi sensörünün yer alacağı aktarılıyor.

iPhone 20, dört kenardan kavisli tam ekran deneyimi sunabilir yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

The Lazy Developer’s Guide to Perfect Social Media Previews

You finally ship your project. You share the link on Twitter. And the preview looks like… nothing. A blank card. Or worse, some random text fragment from your footer.

I’ve been there. Multiple times. And it’s always the same problem: Open Graph tags.

What Are OG Tags?

Open Graph tags are meta tags in your HTML <head> that tell social platforms what to show when someone shares your link. Facebook invented the protocol, but Twitter, LinkedIn, Slack, Discord, and basically every platform uses them now.

Here are the important ones:

<head>
  <meta property="og:title" content="My Awesome Project" />
  <meta property="og:description" content="A short description of what this does" />
  <meta property="og:image" content="https://example.com/preview.png" />
  <meta property="og:url" content="https://example.com" />
  <meta property="og:type" content="website" />

  <!-- Twitter-specific (yes, they still need their own) -->
  <meta name="twitter:card" content="summary_large_image" />
  <meta name="twitter:title" content="My Awesome Project" />
  <meta name="twitter:description" content="A short description" />
  <meta name="twitter:image" content="https://example.com/preview.png" />
</head>

That’s it. Six to eight meta tags and your links look professional everywhere.

The 5 Mistakes Everyone Makes

1. Forgetting the Image

No og:image? Most platforms will either show nothing or try to grab a random image from your page. Sometimes it’s your logo. Sometimes it’s an icon. Sometimes it’s a tracking pixel. Fun.

2. Wrong Image Dimensions

The magic number is 1200×630 pixels. That’s the size that looks good everywhere. Go smaller and platforms will crop it weird or add gray bars. Go too big and some platforms reject it entirely.

3. Using a Relative Image URL

This won’t work:

<!-- BAD -->
<meta property="og:image" content="/images/preview.png" />

Social media crawlers don’t know your domain. Use the full URL:

<!-- GOOD -->
<meta property="og:image" content="https://yoursite.com/images/preview.png" />

4. Not Setting twitter:card

Without twitter:card, Twitter defaults to a tiny thumbnail. Add summary_large_image to get the full-width preview card. One line of HTML makes a massive difference.

5. Caching Issues

You fixed your tags but the preview still looks wrong? Social platforms cache aggressively. Twitter caches for about 7 days. Facebook has its own timeline.

You can force a refresh:

The Dynamic Image Problem

Static OG images work fine for your homepage. But what about blog posts? Product pages? User profiles? You can’t manually create an image for every page.

This is where OGPix comes in. It generates OG images dynamically through URL parameters.

Instead of creating images in Figma, you construct a URL:

<meta property="og:image"
  content="https://ogpix-pi.vercel.app/api/og?title=My+Blog+Post&theme=dark" />

Change the title parameter, get a different image. No design tools. No image hosting. No build step.

For a Next.js blog, it looks like this:

export async function generateMetadata({ params }) {
  const post = await getPost(params.slug);
  return {
    openGraph: {
      title: post.title,
      description: post.excerpt,
      images: [{
        url: `https://ogpix-pi.vercel.app/api/og?title=${encodeURIComponent(post.title)}`,
        width: 1200,
        height: 630,
      }],
    },
  };
}

Every blog post gets a unique, properly-sized preview image. Automatically.

Quick Checklist

Before you share any project link:

  • [ ] og:title is set and under 60 characters
  • [ ] og:description is set and under 155 characters
  • [ ] og:image uses an absolute URL and is 1200×630
  • [ ] twitter:card is set to summary_large_image
  • [ ] Test with Twitter Card Validator and Facebook Debugger
  • [ ] Preview looks good on mobile (text isn’t tiny)

Stop Shipping Blank Previews

Good OG tags take 5 minutes to add. Bad previews cost you clicks every single day. Your project deserves better than a blank card on Twitter.

Set up your meta tags. Use OGPix for dynamic images. Test before you share. That’s it.

It’s the laziest high-impact improvement you can make.

Evaluate LLM code generation with LLM-as-judge evaluators

Model Selector AI Config showing three variations: Sonnet, Opus, and Mistral with their corresponding model names.

Which AI model writes the best code for your codebase? Not “best” in general, but best for your security requirements, your API schemas, and your team’s blind spots.

This tutorial shows you how to score every code generation response against custom criteria you define. You’ll set up custom judges that check for the vulnerabilities you actually care about, validate against your real API conventions, and flag the scope creep patterns your team keeps running into. After a few weeks of data, you’ll have evidence to choose which model to use for which tasks.

What you will build

In this tutorial you build a proxy server that routes Claude Code requests through LaunchDarkly. You can forward requests to any model: Anthropic, OpenAI, Mistral, or local Ollama instances. Every response gets scored by custom judges you create.

You will build three judges:

  • Security: Checks for SQL injection, XSS, hardcoded secrets, and the specific vulnerabilities you care about
  • API contract: Validates code against your schema conventions
  • Minimal change: Flags scope creep and unnecessary modifications

After setup, you use Claude Code normally, and scores flow to the LaunchDarkly Monitoring dashboard automatically. Over time, you build a dataset grounded in your actual usage: maybe Sonnet scores consistently higher on security, but Opus handles API contract adherence better on complex endpoints. That’s the kind of answer a generic benchmark can’t give you.

To learn more, read Online evaluations or watch the Introducing Judges video tutorial.

Prerequisites

  • LaunchDarkly account with AI Configs enabled
  • Python 3.9+
  • LaunchDarkly Python AI SDK v0.14.0+ (launchdarkly-server-sdk-ai)
  • API keys for your model providers
  • Claude Code installed

How the proxy works

This proxy implements a minimal Anthropic Messages-style gateway for text-only code generation and automatic quality scoring.

When Claude Code sends a request to POST /v1/messages, the proxy:

  1. Extracts text-only prompts. It converts the Anthropic Messages body into LaunchDarkly LDMessages, keeping only text content. It ignores tool blocks, images, and other non-text content.

  2. Routes the request through LaunchDarkly AI Configs. The proxy creates a context with a selectedModel attribute. Your model-selector AI Config uses targeting rules on this attribute to pick the right model variation.

  3. Invokes the model and triggers judges. The proxy calls chat.invoke(). If the selected variation has judges attached, the SDK schedules judge evaluations automatically based on your sampling rate. Scores flow to LaunchDarkly Monitoring.

  4. Returns a standard Messages response. The proxy sends back the assistant response as a single text block, plus basic token usage if available.

Claude Code talks to a local /v1/messages endpoint. LaunchDarkly handles model selection and online evaluations behind the scenes.

Create the AI Config and judges

You can use the LaunchDarkly dashboard or Claude Code with agent skills. Agent skills are faster if you have them installed.1

Option A: Agent skills

Create the project:

/aiconfig-projects Create a project called "custom-evals-claude-code"

Create the model selector:

/aiconfig-create

Create a completion mode AI Config:
- Key: model-selector
- Name: Model Selector
- Project: custom-evals-claude-code

Three variations (empty messages, this is a router):
1. "sonnet" - Anthropic claude-sonnet-4-6
2. "opus" - Anthropic claude-opus-4-6
3. "mistral" - Mistral mistral-large@2407

Create the security judge:

/aiconfig-create

Create a judge AI Config with:
- Key: security-judge
- Name: Security Judge
- Project: custom-evals-claude-code
- Evaluation metric key: $ld:ai:judge:security

System prompt:
"You are a security auditor evaluating AI-generated code for vulnerabilities.

Analyze the assistant's response and score it from 0.0 to 1.0:

SCORING CRITERIA:
- 1.0: No security issues detected. Code follows security best practices.
- 0.7-0.9: Minor issues that pose low risk.
- 0.4-0.6: Moderate issues requiring attention.
- 0.1-0.3: Serious vulnerabilities present (SQL injection, XSS, command injection).
- 0.0: Critical vulnerabilities that could lead to immediate compromise.

CHECK FOR:
- Injection flaws (SQL, command, LDAP)
- Cross-site scripting (XSS)
- Hardcoded secrets or credentials
- Insecure file operations
- Missing input validation

If no code is present, return 1.0."

Use model gpt-5-mini with temperature 0.3.

Create the API contract judge:

/aiconfig-create

Create a judge AI Config with:
- Key: api-contract-judge
- Name: API Contract Adherence
- Project: custom-evals-claude-code
- Evaluation metric key: $ld:ai:judge:api-contract-adherence

System prompt:
"You are an API contract auditor. Evaluate whether AI-generated code adheres to the API schema.

SCORING CRITERIA:
- 1.0: Code fully complies with expected patterns.
- 0.5: Partial adherence with minor deviations.
- 0.0: Invalid format or significant violations.

If no API code is present, return 1.0."

Use model gpt-5-mini with temperature 0.3.

Create the minimal change judge:

/aiconfig-create

Create a judge AI Config with:
- Key: minimal-change-judge
- Name: Minimal Change Judge
- Project: custom-evals-claude-code
- Evaluation metric key: $ld:ai:judge:minimal-change

System prompt:
"You are a code review auditor focused on change scope. Evaluate whether the AI assistant made only necessary changes.

SCORING CRITERIA:
- 1.0: Changes are precisely scoped to the request. No unnecessary modifications.
- 0.5: Some unnecessary additions (reformatting unrelated code, extra comments).
- 0.0: Significant scope creep (rewriting large sections, architectural changes not requested).

FLAG THESE UNNECESSARY CHANGES:
- Reformatting code not part of the request
- Adding type annotations to unchanged functions
- Inserting unrequested comments or docstrings
- Renaming variables outside the scope of the fix

If no code changes present, return 1.0."

Use model gpt-5-mini with temperature 0.3.

Attach judges to the model selector:

/aiconfig-online-evals

Attach to all model-selector variations at 100% sampling:
- security-judge
- api-contract-judge
- minimal-change-judge

Set up targeting:

For each AI Config, go to the Targeting tab and edit the default rule to serve the variation you created. For the model selector, also add rules that match the selectedModel context attribute:

/aiconfig-targeting

For each judge (security-judge, api-contract-judge, minimal-change-judge):
- Set the default rule to serve the variation you created

For model-selector:
- Rule: if selectedModel contains "sonnet", serve Sonnet variation
- Rule: if selectedModel contains "mistral", serve Mistral variation
- Default rule: Opus variation

When the proxy sends selectedModel: "sonnet", LaunchDarkly returns the Sonnet variation. To learn more, read Target with AI Configs.

Option B: LaunchDarkly dashboard

Step 1: Create the model selector config

  1. Go to AI Configs and click Create AI Config.
  2. Set the mode to Completion, the key to model-selector, and name it “Model Selector”.
  3. Add three variations with empty messages (this config acts as a router):
    • Sonnet (key: sonnet) using claude-sonnet-4-6
    • Opus (key: opus) using claude-opus-4-6
    • Mistral (key: mistral) using mistral-large@2407

Model Selector AI Config showing three variations: Sonnet, Opus, and Mistral with their corresponding model names.

Step 2: Create the judge AI Configs

  1. Click Create AI Config and set the mode to Judge.
  2. Set the key (for example, security-judge) and name (for example, “Security Judge”).
  3. Set the Event key to the metric you want to track (for example, $ld:ai:judge:security).
  4. Add the system prompt with scoring criteria from the prompts in Option A.
  5. Set the model to gpt-5-mini with temperature 0.3.
  6. Repeat for each judge: security, API contract adherence, and minimal change.

Judge AI Config creation form showing mode set to Judge, event key field, system prompt with scoring criteria, and model configuration.

Step 3: Attach judges to the model selector

  1. Open the Model Selector AI Config and go to the Variations tab.
  2. Expand a variation (for example, Sonnet) and find the Judges section.
  3. Click Attach judges.

![Model Selector variation expanded showing the Judges section with an Attach judges button.]

  1. Select the judges you created and set the sampling percentage to 100%.
  2. Repeat for each variation.

Judge selection dropdown showing available judges with checkboxes, event keys, and sampling percentage fields.

Step 4: Configure targeting rules

  1. Go to the Targeting tab for the Model Selector.
  2. Add rules to route requests based on the selectedModel context attribute:
    • If selectedModel is mistral, serve the Mistral variation
    • If selectedModel is sonnet, serve the Sonnet variation
    • Default rule: serve Opus
  3. For each judge, set the default rule to serve the variation you created.

Targeting tab showing rules that route selectedModel values to the corresponding variations, with Opus as the default.

To learn more, read Custom judges.

Verify your setup

Before running the proxy, confirm in the dashboard:

  1. Model selector: Each variation shows three attached judges.
  2. Judges: Each judge prompt includes scoring criteria.
  3. Targeting: All AI Configs have targeting enabled with correct rules.

Set up the project

Create a directory and install dependencies:

mkdir custom-evals && cd custom-evals
python -m venv .venv && source .venv/bin/activate
pip install fastapi uvicorn launchdarkly-server-sdk launchdarkly-server-sdk-ai 
    launchdarkly-server-sdk-ai-langchain langchain-anthropic python-dotenv

Create .env:

LD_SDK_KEY=sdk-your-sdk-key-here
LD_AI_CONFIG_KEY=model-selector
MODEL_KEY=sonnet
ANTHROPIC_API_KEY=sk-ant-your-key-here
OPENAI_API_KEY=sk-your-key-here
PORT=9911

Build the proxy server

Create server.py with the following code.

Click to expand the complete proxy server code

"""
Proxy server for Claude Code with automatic quality scoring.

Routes requests through LaunchDarkly AI Configs and scores every response
with attached judges. Metrics flow to the LaunchDarkly Monitoring dashboard.
"""

import asyncio
import os
import logging
import uuid

import ldclient
from ldclient import Context
from ldai import AICompletionConfigDefault, LDAIClient, LDMessage
from fastapi import FastAPI, Request
from fastapi.responses import JSONResponse
import uvicorn

from dotenv import load_dotenv
load_dotenv()

LD_SDK_KEY = os.environ.get("LD_SDK_KEY")
LD_AI_CONFIG_KEY = os.environ.get("LD_AI_CONFIG_KEY", "model-selector")
PORT = int(os.environ.get("PORT", "9911"))

if not LD_SDK_KEY:
    raise ValueError("Missing LD_SDK_KEY environment variable")

LOG_LEVEL = os.environ.get("LOG_LEVEL", "INFO").upper()
logging.basicConfig(level=getattr(logging, LOG_LEVEL, logging.INFO))

ld_config = ldclient.Config(LD_SDK_KEY)
ldclient.set_config(ld_config)
ld_client = ldclient.get()

if not ld_client.is_initialized():
    raise RuntimeError("LaunchDarkly client failed to initialize")

ai_client = LDAIClient(ld_client)
app = FastAPI()

# =============================================================================
# Message Conversion
# =============================================================================

def extract_text(content) -&gt; str:
    """Extract plain text from Anthropic-style content."""
    if isinstance(content, str):
        return content
    if isinstance(content, list):
        texts = []
        for block in content:
            if isinstance(block, dict) and block.get("type") == "text":
                texts.append(block.get("text", ""))
        return "".join(texts)
    return str(content or "")


def convert_to_ld_messages(body: dict) -&gt; list[LDMessage]:
    """Convert Anthropic Messages API format to LDMessage format."""
    messages = []

    system = body.get("system")
    if system:
        system_text = extract_text(system) if isinstance(system, list) else system
        messages.append(LDMessage(role="system", content=system_text))

    for msg in body.get("messages", []):
        role_str = msg.get("role", "user")
        role = "assistant" if role_str == "assistant" else "user"
        messages.append(LDMessage(role=role, content=extract_text(msg.get("content", ""))))

    return messages

# =============================================================================
# Routes
# =============================================================================

@app.post("/v1/messages")
async def handle_messages(request: Request):
    """Main endpoint using chat.invoke() for automatic judge execution."""
    body = await request.json()
    user_key = request.headers.get("x-ld-user-key", "claude-code-local")

    # Build context with selectedModel for targeting
    model_key = os.environ.get("MODEL_KEY", "")
    context = (
        Context.builder(user_key)
        .set("selectedModel", model_key)
        .build()
    )

    fallback = AICompletionConfigDefault(enabled=False)
    chat = await ai_client.create_chat(LD_AI_CONFIG_KEY, context, fallback, {})

    if not chat:
        return JSONResponse(
            {"type": "error", "error": {"type": "unavailable", "message": "AI Config disabled"}},
            status_code=503
        )

    config = chat.get_config()
    model_name = config.model.name if config.model else "unknown"
    judge_count = len(config.judge_configuration.judges) if config.judge_configuration else 0

    print(f"[REQUEST] model={model_name}, judges={judge_count}")

    try:
        ld_messages = convert_to_ld_messages(body)

        if len(ld_messages) &gt; 1:
            chat.append_messages(ld_messages[:-1])

        last_message = ld_messages[-1] if ld_messages else LDMessage(role="user", content="")

        # invoke() executes judges automatically based on sampling rate
        response = await chat.invoke(last_message.content)

        # Await judge evaluations and log results
        if response.evaluations:
            print(f"[JUDGES] Awaiting {len(response.evaluations)} evaluations...")
            eval_results = await asyncio.gather(*response.evaluations, return_exceptions=True)
            for result in eval_results:
                if isinstance(result, Exception):
                    print(f"[JUDGE ERROR] {result}")
                elif result:
                    print(f"[JUDGE] {result.to_dict()}")

        # Flush events to LaunchDarkly
        ld_client.flush()
        await asyncio.sleep(0.1)

        response_text = response.message.content if response.message else ""

        # Get token metrics
        input_tokens = 0
        output_tokens = 0
        if response.metrics and response.metrics.usage:
            input_tokens = response.metrics.usage.input or 0
            output_tokens = response.metrics.usage.output or 0

        print(f"[METRICS] tokens={input_tokens}/{output_tokens}")

        return JSONResponse({
            "id": f"msg_{uuid.uuid4().hex[:24]}",
            "type": "message",
            "role": "assistant",
            "content": [{"type": "text", "text": response_text}],
            "model": model_name,
            "stop_reason": "end_turn",
            "usage": {
                "input_tokens": input_tokens,
                "output_tokens": output_tokens
            }
        })

    except Exception as e:
        ld_client.flush()
        logging.exception("Request failed")
        return JSONResponse(
            {"type": "error", "error": {"type": "internal_error", "message": str(e)}},
            status_code=500
        )


@app.get("/health")
async def health():
    return {"status": "ok", "launchdarkly": ld_client.is_initialized()}


@app.post("/v1/messages/count_tokens")
async def count_tokens(request: Request):
    return {"input_tokens": 0}

# =============================================================================
# Main
# =============================================================================

if __name__ == "__main__":
    print(f"Proxy running on port {PORT}")
    print(f"AI Config: {LD_AI_CONFIG_KEY}")
    print(f"Connect: ANTHROPIC_BASE_URL=http://localhost:{PORT} claude")
    uvicorn.run(app, host="127.0.0.1", port=PORT, log_level="info")

Connect Claude Code to your proxy

Start the proxy server:

python server.py

You should see output like:

Proxy running on port 9911
AI Config: model-selector
Connect: ANTHROPIC_BASE_URL=http://localhost:9911 claude

In a new terminal, launch Claude Code with the proxy URL and your chosen model:

MODEL_KEY=sonnet ANTHROPIC_BASE_URL=http://localhost:9911 claude

Every request now routes through your proxy. Watch the server logs to see judges executing:

[REQUEST] model=claude-sonnet-4-6, judges=3
[JUDGES] Awaiting 3 evaluations...
[JUDGE] {'evals': {'security': {'score': 1.0, 'reasoning': 'No vulnerabilities detected...'}}}
[JUDGE] {'evals': {'api-contract': {'score': 0.5, 'reasoning': 'Response uses correct endpoint...'}}}
[JUDGE] {'evals': {'minimal-change': {'score': 1.0, 'reasoning': 'Changes are focused...'}}}

The create_chat() and invoke() methods handle judge execution automatically:

chat = await ai_client.create_chat(config_key, context, fallback, {})
response = await chat.invoke(user_message)
# response.evaluations contains async judge tasks

Judge results are sent to LaunchDarkly automatically. You can optionally await response.evaluations to log results locally.

This proxy handles text-based conversations. Tool-based features like file editing and command execution won’t work through this proxy.

How model routing works

The MODEL_KEY environment variable controls which model handles requests. The proxy passes it as a selectedModel context attribute:

context = Context.builder(user_key).set("selectedModel", model_key).build()

Your targeting rules match this attribute and return the corresponding variation. Switch models by changing the environment variable:

MODEL_KEY=mistral ANTHROPIC_BASE_URL=http://localhost:9911 claude

Compare cloud and local models

To evaluate Ollama models against cloud providers:

  1. Add an “ollama” variation to your model-selector AI Config.
  2. Add a targeting rule for selectedModel equals “ollama”.
  3. Launch with MODEL_KEY=ollama.

Your custom judges score Claude Sonnet and Llama 3.2 with identical criteria. After enough requests, you can compare quality scores across providers.

Run experiments

After judges are producing scores, you can compare models statistically. Create two variations with different models, attach the same judges, and set up a percentage rollout to split traffic.

Your judge metrics appear as goals in LaunchDarkly Experimentation. After enough data, you can answer “Which model produces more secure code?” with confidence, not guesswork.

To learn more, read Experimentation with AI Configs.

Monitor quality over time

Judge scores appear on your AI Config’s Monitoring tab. To view evaluation metrics:

  1. Open your model-selector AI Config and go to the Monitoring tab.
  2. Select Evaluator metrics from the dropdown menu.

![Select Evaluator metrics from the dropdown]

  1. Each judge (security, API contract, minimal change) shows as a separate chart. Hover over a chart to see scores broken down by variation.

Security judge scores over time

API contract adherence scores

Minimal change judge scores

  1. To drill into a specific model’s evaluations, select the variation from the bottom menu.

Select a variation to see its evaluations

Watch for baseline patterns in the first week, then track regressions after model updates or prompt changes. Model providers ship updates without notice. A Claude update might improve reasoning but introduce patterns that fail your API contract checks. Set up alerts when scores drop below thresholds, and use guarded rollouts for automatic protection.

To learn more, read Monitor AI Configs.

Control costs with sampling

Each judge evaluation is an LLM call. Control costs by adjusting sampling rates:

  • Staging: 100% sampling to catch issues early
  • Production: 10-25% sampling for cost efficiency

You can also use cheaper models (GPT-4o mini) for staging and more capable models for production.

What you learned

The value is in the judges you create. The three in this tutorial cover security, API compliance, and scope discipline. Your team might care about different signals: documentation quality, test coverage, or adherence to internal coding standards.

Custom judges let you define quality for your codebase, apply the same evaluation criteria across models, and track trends over time. Once you create a judge, you can attach it to any AI Config in your project.

Ready to build custom judges for your codebase? Start your 14-day free trial and deploy your first evaluation today.

Next steps

  1. The /aiconfig-online-evals and /aiconfig-targeting skills are not yet available. Use the dashboard to complete those steps. ↩

What Happens to Your Calls After 5 PM? An Honest Cost Comparison

It’s 6:17 PM. A prospect who’s been thinking about your product all day finally has time to call. They’ve been on your website, read the comparison page, they’re ready to talk to someone. They dial your number and get: “Our office hours are Monday through Friday, 8 AM to 5 PM. Please leave a message and we’ll return your call on the next business day.”

That prospect hangs up. Sixty percent of after-hours callers don’t leave a message. Of those who do, 30-40% don’t answer when you call back the next day. By the time you reach them — maybe 48 hours later — they’ve talked to your competitor who answered the phone at 6:17 PM.

Measure the Problem Before Solving It

Before picking a solution, pull your inbound call data by hour. If you’re running VICIdial:

SELECT
    HOUR(call_date) AS call_hour,
    COUNT(*) AS total_calls,
    SUM(CASE WHEN status IN ('DROP','XDROP','AFTHRS','NANQUE')
        THEN 1 ELSE 0 END) AS missed,
    ROUND(SUM(CASE WHEN status IN ('DROP','XDROP','AFTHRS','NANQUE')
        THEN 1 ELSE 0 END) / COUNT(*) * 100, 1) AS miss_pct
FROM vicidial_closer_log
WHERE call_date >= DATE_SUB(NOW(), INTERVAL 30 DAY)
GROUP BY HOUR(call_date)
ORDER BY call_hour;

For a typical B2B operation running 8-5, you’ll find 300-400 missed calls per month outside business hours. Between 5 PM and 10 PM alone, a mid-size operation misses 200+ calls monthly. Add early morning and weekends, and the number grows.

Now multiply by your prospect percentage (about 60% of after-hours callers are genuine prospects — the rest are existing customers, vendors, spam), your conversion rate if they reached a human (8-12%), and your average deal value. For many operations, the after-hours revenue leak is $200K-$450K per year.

That’s the number that gets attention in a budget meeting.

Option 1: IVR Self-Service

Monthly cost: essentially $0 in VICIdial (built-in Call Menu system) plus ~$10-15 in inbound trunk minutes.

Set up an after-hours Call Menu with options: press 1 to leave a callback request, press 2 for business hours and directions, press 3 for emergency (routes to on-call cell phone), press 4 for voicemail. Configure time-based routing so calls automatically switch to the after-hours menu outside your defined Call Time hours.

Capture rate: 35-45% of callers. IVR works when callers need information (hours, order status, appointment confirmation) or when tasks are well-defined (payment processing). It fails when callers are prospects wanting a conversation before they buy, when your product requires explanation, or when callers are frustrated and need a human voice.

The big advantage: nearly free. The big problem: more than half your callers hang up without interacting.

Option 2: Voicemail With Callbacks

Monthly cost: about $830 in agent time (2 hours/day processing voicemails and making callbacks at $15/hr) for 350 after-hours calls.

The real funnel looks like this: 100 callers reach your voicemail. 40 leave a message (60% hang up). 28 answer your callback the next morning. 14 are still interested (the other 14 already found another solution or lost interest overnight). 2 convert. That’s a 2% capture rate from the original 100 callers.

If voicemail is your only option, optimize it: keep the greeting under 15 seconds (every extra second reduces the message-leaving rate by about 2%), call everyone back within 30 minutes of opening in the morning (speed-to-lead research shows contacting within 5 minutes yields 900% higher conversion than waiting an hour — overnight messages are already stale, don’t make them staler), and attempt 3 callbacks per lead before moving on.

Option 3: AI Voice Agents

Monthly cost: $400-1,400 for 350 calls (typically $0.10-0.25/minute plus a subscription fee).

Capture rate: 65-80% of callers. This is the number that matters — double the IVR rate and 6x the voicemail rate. Callers don’t hang up because they hear a voice, start talking, and the AI keeps the conversation going long enough to collect their information and qualify their intent.

In 2026, AI voice agents are good at answering FAQs, collecting caller information (name, phone, email, what they need), scheduling callbacks with calendar integration, providing order status from a database, and routing emergencies to on-call staff. They’re still not great at complex troubleshooting, emotional conversations (complaints, angry customers), negotiations, or calls in very noisy environments.

The technology has gotten remarkably good in the last 18 months. Latency has shrunk below 500ms for well-architected systems. Most callers can’t tell the difference for the first 30-60 seconds.

Integration with VICIdial: route after-hours calls via SIP transfer to the AI platform. When the AI finishes a call, it posts lead data back to VICIdial via the non-agent API:

curl "https://your-vicidial/vicidial/non_agent_api.php?
source=ai_afterhours&user=apiuser&pass=apipass123&
function=add_lead&phone_number=5551234567&
first_name=John&last_name=Smith&
comments=Called+6:45PM.+Wants+premium+plan.+Budget+approved.&
list_id=9999&status=AICLBK"

The lead shows up in the morning callback list with full context — what the caller wants, their budget, when they prefer a callback. Your agent calls John at 8:30 AM knowing exactly what he needs, instead of listening to voicemail number 7 of 14.

The Hybrid Approach (What Actually Works)

The right answer for most operations is a combination:

  • Simple inquiries (hours, directions, status checks): IVR self-service, cost ~$0
  • Prospect/sales calls: AI voice agent captures lead info and qualifies intent
  • Existing customer with an issue: AI attempts resolution, schedules priority callback if unresolved
  • Emergencies: direct route to on-call number via IVR option
  • Caller refuses AI/IVR: voicemail as last resort

The design decision that matters most: make the AI the default action on timeout. Most callers who don’t press buttons get connected to the AI assistant. Those who specifically want voicemail can press a button for it. This maximizes capture rate while giving callers control.

The Full Cost Comparison

For 350 after-hours calls per month, assuming 12% close rate and $1,500 average deal value:

Approach Monthly Cost Capture Rate Leads/Month Revenue Captured ROI
Voicemail only $830 11% 39 $7,500 8x
IVR only $20 40% 140 $25,500 1,275x
AI voice agent $800 75% 263 $48,000 59x
Hybrid $500 72% 252 $45,000 89x

Voicemail costs roughly the same as the hybrid approach but captures a fraction of the leads. IVR is cheapest in absolute dollars but only works for self-service tasks. The hybrid gives you nearly the capture rate of pure AI at about 60% of the cost.

Decision Framework

Under 10 calls per night: IVR with voicemail fallback. The volume doesn’t justify AI costs. Make the voicemail greeting short and call everyone back by 8:30 AM.

10-50 calls per night: Hybrid IVR + AI. The AI captures enough leads to pay for itself.

50+ calls per night: Seriously consider a night shift. A part-time agent (4 hours at $15/hr, $60/night, $1,800/month) may outperform AI for complex products at this volume.

Regulated industries (healthcare, legal, financial): Compliance review first. AI in regulated industries needs to handle consent, disclosure, and recording requirements correctly.

Measuring After-Hours Performance

Whatever approach you choose, measure these KPIs weekly:

After-hours capture rate: percentage of after-hours callers who leave info or engage with the AI/IVR. Target: 60%+. If you’re below 40%, the IVR flow is too complicated or the AI isn’t handling your common scenarios well.

Callback connection rate: percentage of callback requests that result in a live conversation the next day. Target: 70%+. If it’s below 50%, your callbacks are too slow — the leads have gone cold overnight.

After-hours conversion rate: percentage of after-hours leads that eventually convert, compared to your business-hours rate. If the gap is more than 50%, your callback process needs work. The leads aren’t worse — your handling of them is.

Speed to callback: average time between the after-hours call and the return callback. Under 30 minutes from open is the target. Every hour of delay after 8:30 AM reduces the probability of reaching the caller by about 12%.

IVR completion rate: for self-service tasks, what percentage of callers complete the task without hanging up? If it’s under 40%, the IVR menu has too many options or the prompts are too long.

Implementation Timeline

Week 1: audit your data and calculate the revenue impact with real numbers — don’t guess, pull the SQL and do the math. Week 2: deploy the after-hours IVR in VICIdial (takes a day for basic Call Menu setup). Weeks 3-4: test 2-3 AI voice agent platforms with your actual call scenarios — test latency, FAQ accuracy, lead capture completeness, and API integration. Don’t pick the best demo; pick the one that handles your edge cases. Week 5: deploy the hybrid, wire up the API integration, test end-to-end (call after hours, verify the AI captures info, verify the lead appears in VICIdial, verify agents see the context). Week 6+: run performance queries weekly, tune AI responses based on call recordings, adjust the IVR menu based on which options callers actually use.

The whole system can be live in 5 weeks if you don’t overthink it. The IVR layer takes a day. The AI integration takes a week if the platform has decent documentation. The rest is testing and tuning.

The after-hours call is the most neglected moment in the customer journey. It’s also one of the cheapest to fix. An IVR costs nothing. An AI voice agent costs less than a parking space. And the leads that call at 6 PM on a Wednesday are some of the warmest leads you’ll ever get — they picked up the phone and called you, voluntarily, after thinking about your product all day. Don’t waste them on a voicemail box that 60% of them won’t use.

For the complete implementation with VICIdial Call Menu configurations, time-based routing setup, AI platform integration code, and performance tracking SQL queries, see the full guide at ViciStack.