
How To Prevent Website Downtime
Downtime can happen for many reasons: infrastructure failures, network issues, software bugs, or simple configuration mistakes. Some of these problems are unavoidable, but most can be prevented by understanding how websites work and where failures typically occur.
In this article, we’ll break down how downtime happens, how traffic reaches your website, and what can go wrong along the way. More importantly, we’ll look at practical ways to reduce risk through better architecture, multiple environments, and effective monitoring. The goal is not just to react faster to outages, but to prevent them from happening in the first place.
How Downtime Happens
Downtime occurs when your website is unable to respond correctly to incoming requests. This doesn’t always mean the server is completely offline. A website can be considered “down” when it returns errors, times out, or becomes so slow that users effectively can’t use it.
In many cases, downtime is the result of a chain of failures rather than a single event. A small configuration change, an unexpected spike in traffic, or a failing dependency can cascade into a full outage. Because modern websites are made up of multiple components, a problem in any one of them can make the entire site unreachable.
It’s also important to distinguish between partial and total downtime. Partial downtime might affect only certain pages, users, or regions, while total downtime means no one can access the site at all. Both are damaging, but partial outages are often harder to detect without proper monitoring in place.
Understanding how downtime happens is the first step toward preventing it. To do that, it helps to look at how traffic actually reaches your website and how many points of failure exist along that path.
How Traffic Reaches Your Website
When a user visits your website, a lot happens behind the scenes before a page is displayed. It normally goes so fast that you probably don’t even notice how many things are happening. Each step in this process introduces a potential point of failure, which is why understanding the request flow is essential for preventing downtime.
It starts with a DNS lookup. When someone types your domain name in their browser a lookup takes place. The user’s browser must know where to go to reach your website. This is done through the Domain Name System (DNS) which returns the IP address of your server.
If DNS is misconfigured or unavailable, the request never reaches your infrastructure at all. Incorrect changes can also leave your site unavailable as DNS updates are slow and can take hours.
Once the correct IP address is found, the browser establishes a network connection to your server. This connection passes through multiple networks and routers before reaching your hosting provider. Even if your server is healthy, network issues along this path can prevent users from connecting.
After the connection is established, the web server processes the request. This may involve application logic, databases, external APIs, or background services. If any of these components fail or respond too slowly, the request can time out or return an error.
Finally, the server sends a response back to the user’s browser. If everything works as expected, the page loads. If not, the user experiences an error, a blank page, or excessive loading times which are often perceived as downtime.
Because traffic depends on so many interconnected systems, preventing downtime means identifying which parts are most likely to fail and preparing for those failures in advance.
Where Things Can Go Wrong
Now that we understand how traffic reaches your website, it becomes clear how many things can fail along the way. Even simple websites depend on multiple layers of infrastructure and software, and a problem in any of these layers can result in downtime.
Most website outages fall into three broad categories: server failures, network failures, and website code failures. While the symptoms may look similar to users, errors, timeouts, or blank pages the underlying causes are very different. Identifying which category a problem belongs to is crucial for preventing it from happening again.
Let’s look at each of these failure types in more detail, starting with server-related issues.
Server Failures
Server failures are one of the most common causes of website downtime. Even when your code is correct and your network is stable, the underlying machine running your website can still fail.
A server can go down for many reasons. Hardware issues, operating system crashes, or forced reboots by the hosting provider can instantly make your website unavailable. In virtualized or cloud environments, servers may also be terminated or migrated without warning if resource limits are exceeded.
Resource exhaustion is another frequent cause. When a server runs out of CPU, memory, or disk space, it may slow down dramatically or stop responding altogether. This often happens during traffic spikes, background jobs running at the wrong time, or memory leaks in long-running processes.
Misconfiguration can be just as damaging. Incorrect web server settings, broken service dependencies, or failed updates can prevent the server from starting properly. In these cases, the server may be online, but unable to serve requests correctly.
Because servers are a single point of execution for your application, failures at this level tend to have an immediate and visible impact. Reducing downtime means not only choosing reliable infrastructure, but also monitoring server health and preparing for failure rather than assuming stability.
Network Failures
Network failures occur when users are unable to reach your server, even if the server itself is running correctly. These issues are often harder to diagnose because the problem may exist outside of your direct control.
One common cause is DNS-related problems. Incorrect DNS records, expired domains, or outages at DNS providers can prevent traffic from resolving to your server’s IP address. When this happens, users never reach your infrastructure at all.
Routing issues between networks can also cause downtime. Traffic on the internet passes through multiple autonomous systems before reaching your hosting provider. If a routing path is misconfigured or temporarily unavailable, users in certain regions may experience outages while others do not. This is why it’s important to monitor from multiple locations around the world.
Firewalls and security rules are another frequent source of network-related downtime. Overly strict rules, accidental IP blocks, or misconfigured rate limits can block legitimate traffic. From a user’s perspective, this looks exactly like the website is down.
Because network failures can be regional or intermittent, they are easy to miss without external monitoring. Preventing these issues requires careful configuration, redundancy where possible, and visibility into how your website is accessed from different locations.
Website Code Failures
Website code failures happen when the application itself is unable to handle requests correctly. Unlike server or network issues, these failures often occur immediately after a change is made, such as a deployment or configuration update. But with aggressive caching it may also take some time for issues to reach users.
Bugs in application logic can cause errors that prevent pages from loading or APIs from responding. An unhandled exception, infinite loop, or missing dependency can crash a process or return repeated server errors. In some cases, a single faulty request can degrade performance for all users.
Changes to code or configuration are a common trigger. Deployments that haven’t been properly tested may introduce breaking changes, incompatible library versions, or invalid settings. Even small changes can have large effects if they impact core request handling or database access.
External dependencies can also cause code-related downtime. If your application relies on third-party APIs, payment providers, or authentication services, failures in those systems can cascade into your own application. Without proper timeouts and fallbacks, your website may hang or fail entirely.
Because code failures are often self-inflicted, they are also among the most preventable. Clear deployment practices, proper testing, and good error handling significantly reduce the risk of taking a website offline through software changes.
How to Prevent Each Type of Problem
Preventing website downtime starts with addressing each failure category directly. While no system can be made completely failure-proof, you can significantly reduce both the frequency and impact of outages by designing for failure and adding safeguards at every layer.
Instead of relying on a single fix, effective prevention combines infrastructure choices, configuration discipline, and operational practices. The goal is to detect problems early, limit their blast radius, and recover quickly when something does go wrong.
Below, we’ll look at practical steps to prevent downtime caused by server issues, network problems, and website code failures.
Preventing Server Failures
Reducing server-related downtime begins with eliminating single points of failure. Relying on one server means that any crash, reboot, or resource issue will immediately take your website offline. Using multiple servers or managed platforms with built-in redundancy greatly improves resilience.
Monitoring server health is equally important. Tracking CPU usage, memory consumption, disk space, and running processes helps identify problems before they cause outages. Automated alerts allow you to respond quickly when thresholds are exceeded.
Automated recovery can further reduce downtime. Restarting crashed services, replacing unhealthy instances, or scaling resources during traffic spikes can often resolve issues without manual intervention. These mechanisms ensure that short-lived problems don’t turn into prolonged outages.
Finally, keep servers predictable. Apply updates carefully, document configuration changes, and avoid unnecessary complexity. Stable, well-understood systems fail less often and are easier to recover when they do.
Preventing Network Failures
Preventing network-related downtime is about ensuring users can reach your website reliably, even when parts of the network experience issues. While you can’t control every network between your server and users, careful configuration and monitoring can reduce risks.
Start with a solid DNS setup. Use reputable DNS providers and ensure redundancy with multiple authoritative name servers. Correct configuration and monitoring DNS records help to know when something is modified.
Pay close attention to firewall and security rules. Overly strict rules, accidental IP blocks, or misconfigured access controls can prevent legitimate users from reaching your site. Logging and monitoring network traffic helps identify these issues before they affect users.
Routing problems within your own network or hosting provider can also cause outages. Redundant network interfaces, proper routing configurations, and regular connectivity checks help ensure traffic continues to flow even when part of the network fails. Choose a reliable hosting provider for this.
Finally, monitor accessibility from multiple locations. Network failures can be regional, and relying on a single test point may not reveal them. Multi-location monitoring ensures you catch problems that affect only some users.
Preventing Website Code Failures
Preventing downtime caused by website code requires discipline in development, testing, and deployment. Unlike server or network issues, these failures are often within your control, which makes them highly preventable.
The first step is thorough testing. Unit tests, integration tests, and automated end-to-end tests help catch errors before they reach production. Testing should cover both expected use cases and edge cases that could cause failures under load or unusual conditions.
Staged deployments are also critical. Deploying changes first to a development or staging environment allows you to verify functionality and performance before affecting real users. This minimizes the risk of introducing breaking changes directly to production.
Version control and rollback strategies provide safety nets. If a deployment introduces an unexpected bug, having a tested rollback plan allows you to restore the previous working version quickly, minimizing downtime.
Finally, implement robust error handling in your code. Timeouts, retries, and graceful degradation prevent single points of failure from crashing the entire application. Even when something goes wrong, your website can continue serving users without a full outage.
Setup Multiple Environments
One of the most effective ways to prevent downtime is to use multiple environments for your website: development, staging, and production. Each environment serves a distinct purpose and provides a controlled space to test changes before they affect real users.
Development environments are where new features and bug fixes are built. Developers can experiment, run tests, and identify issues without risking production downtime.
Staging environments mirror production as closely as possible. This is where you validate deployments, test integrations, and simulate real-world traffic. Staging allows you to catch configuration mistakes, performance issues, or code regressions before they reach your live site.
Production is where your website serves real users. By the time code reaches this environment, it should already be thoroughly tested and verified in development and staging.
Using multiple environments creates a safety net. Problems are discovered earlier, deployments become more predictable, and the risk of downtime caused by human error or unforeseen bugs is greatly reduced. It also supports better monitoring and rollback strategies, since you can test fixes in staging before applying them to production.
Monitoring: The Key to Prevention
Even with strong infrastructure and careful development practices, issues can still happen. That’s why monitoring isn’t just a safety net. It’s a core part of preventing downtime. Monitoring gives you visibility into your site’s health so you can detect and respond to problems before your users notice.
One powerful tool for this is Vigilant, a monitoring platform designed to watch your website from outside your infrastructure and alert you instantly when something goes wrong. Unlike simple “is it online” checks, Vigilant helps you spot real problems that affect your users and your business.
Instant Uptime Alerts
Vigilant continuously checks your website from multiple global locations and alerts you as soon as your site stops responding. Because it verifies outages from more than one location before notifying you, you avoid false alarms and only act on real issues. This ensures you know about actual downtime quickly before customers notice or conversions are lost.
Historical Data and Reliability Metrics
Knowing when and how often downtime happens is critical to improving reliability. Vigilant stores detailed historical data with timestamps that help you identify patterns, measure uptime percentages, and track whether your prevention efforts are working over time.
Beyond Uptime
Good monitoring goes beyond simple reachability. Vigilant includes additional checks that help catch the kinds of failures that don’t always look like downtime but still harm user experience:
- Link issue detection to catch broken internal URLs
- DNS monitoring so misconfigurations or unexpected changes don’t take your site offline
- Certificate monitoring to warn you before HTTPS certificates expire and trigger browser warnings
- Performance tracking (Lighthouse) to spot slowdowns that lead to churn
These extended checks broaden your visibility and help prevent subtle failures from becoming major outages.
Smart, customizable Notifications
A monitoring system is only useful if you actually see its alerts. Vigilant supports notifications through the channels you already use. Email, Slack, and others so you can react in minutes instead of hours when something goes wrong.
Easy to Set Up and Use
Vigilant is designed to get started quickly. You simply add your site and configure the monitors you want, and Vigilant begins tracking uptime and other metrics almost immediately. Its sensible defaults mean you don’t need deep expertise to begin protecting your site.
Advanced Options
For websites with high traffic or strict uptime requirements, there are additional strategies that go beyond basic monitoring and environment separation. These advanced options help your site remain available even under unusual conditions or extreme load.
Distributed or Multi-Region Architecture
Deploying your website across multiple regions reduces the impact of a single server or datacenter failing. If one region experiences an outage, traffic can be routed to another region, keeping your site online for most users. This approach is especially useful for global websites where downtime in one area can affect a large number of users.
Load Balancers & Failovers
Load balancers distribute incoming traffic across multiple servers, preventing any single server from becoming a bottleneck. They can automatically reroute traffic to healthy servers if one fails, providing seamless failover. Combined with redundant infrastructure, this ensures that individual failures don’t result in visible downtime.
Do ensure you have multiple load balancers, otherwise you’re just moving the single point of failure 😉
Auto-Scaling to Handle Traffic Spikes
Unexpected spikes in traffic are a common cause of downtime, especially for events, product launches, or viral content. Auto-scaling automatically adds server capacity when load increases and scales down during quieter periods. This ensures your site remains responsive without over-provisioning resources all the time.
These advanced techniques require careful planning and investment, but they significantly increase resilience and reduce the risk of downtime. They are most beneficial for sites where availability is critical to revenue, reputation, or user trust.
Conclusion
Website downtime can happen to anyone, but most outages are preventable. By understanding how traffic reaches your website and where failures can occur, you can take proactive steps to protect your site.
Start with solid infrastructure and multiple environments, implement careful deployment and testing practices, and use vigilant monitoring to catch issues before they affect users. For high-traffic or mission-critical websites, advanced strategies like multi-region deployments, load balancing, and auto-scaling provide an additional layer of resilience.
Ultimately, preventing downtime isn’t about avoiding every possible problem, it’s about designing systems, processes, and monitoring in a way that allows you to detect issues quickly, respond effectively, and keep your website online and performing for your users.
Originally published at https://govigilant.io on March 25, 2026.

 Samsung, Windows için Samsung Browser’ı duyurdu. Yeni tarayıcı, mobil ile PC arasında kesintisiz geçiş ve Perplexity destekli yapay zekâ özellikleriyle dikkat çekiyor.
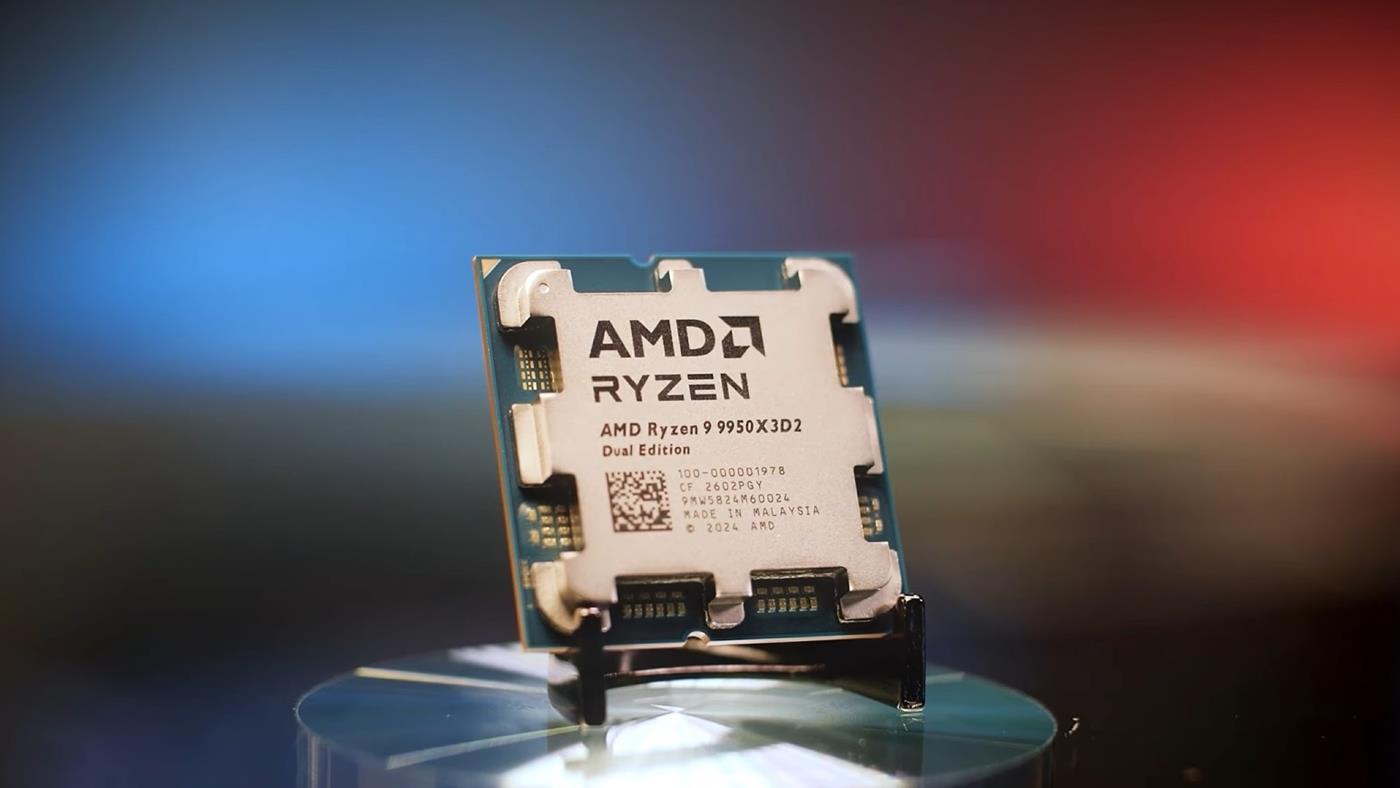
 AMD, Zen 5 mimarili Ryzen 9 9950X3D2 Dual Edition işlemciyi tanıttı. Çift CCD’de 3D V-Cache ile donatılan işlemci, 208 MB önbellek ve 200 W TDP ile bu bahar satışa çıkacak.
 Android 17 beta artık Google Pixel telefonlarla sınırlı değil. Motorola, OnePlus ve Oppo dahil olmak üzere farklı markalardan birçok üçüncü parti telefon Android 17 beta güncellemelerini alacak.
 Michael Jackson biyografisi, yeni Super Mario filmi, Robert Pattinson ve Zendaya’lı Drama, Lee Cronin’den Mumya… Nisan ayında sinemaseverleri dikkat çekici filmler bekliyor.