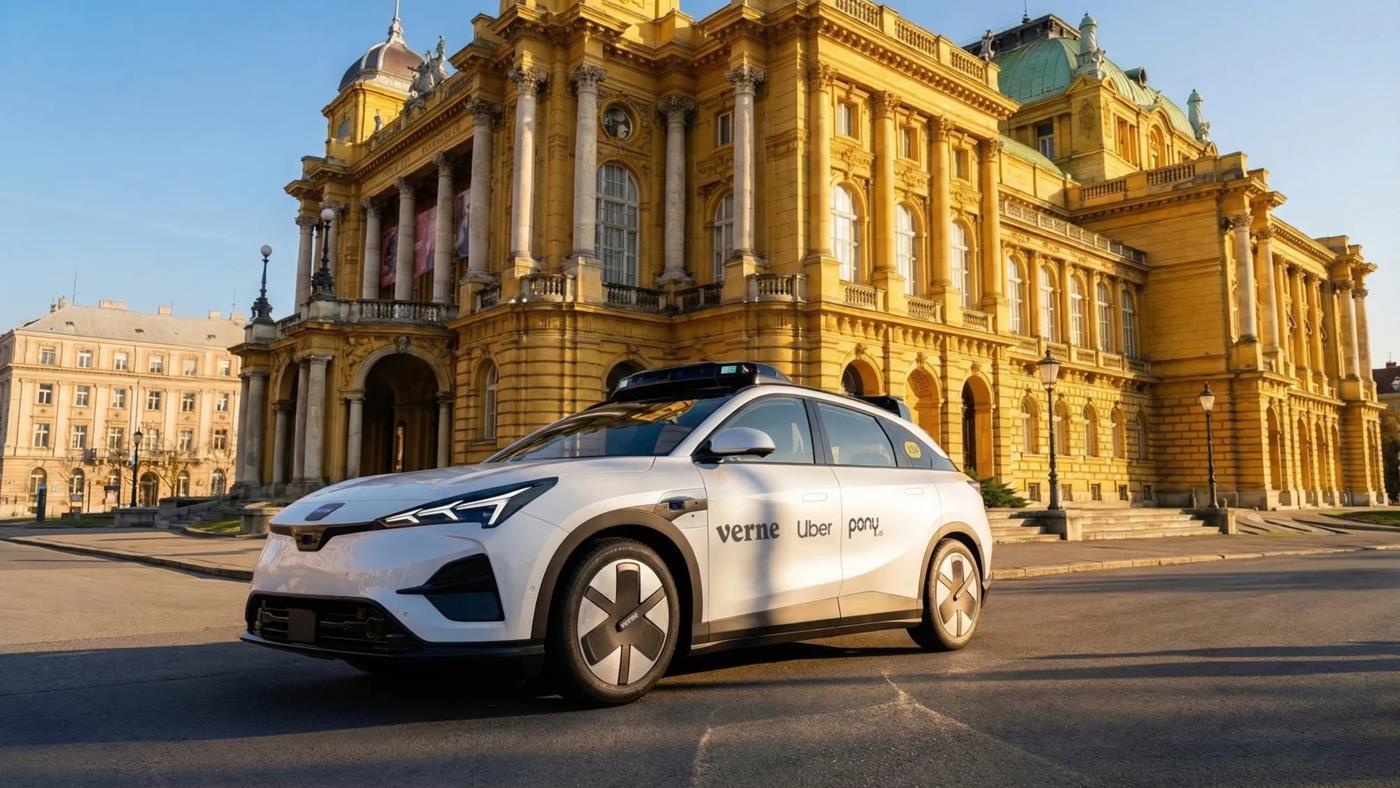
Uber’dan Avrupa’da bir ilk: Robotaksi dönemi başlıyor
Uber, Pony.ai ve Verne iş birliğiyle Zagreb’de Avrupa’nın ilk ticari robotaksi hizmeti için testler başladı. Sürücüsüz araçlar yakında Uber platformu üzerinden yolcu taşımaya başlayacak.
Netflix üyelik ücretleri yine zamlanıyor! Yayın devi, tüm abonelik planları için yeni fiyatlandırmayı duyurdu. Fiyat değişikliği, şu an için Türkiye’deki kullanıcıları etkilemiyor.SMART on FHIR is how apps talk to electronic health records. It’s OAuth 2.0 with a few healthcare-specific conventions: a discovery document that tells your app where to authenticate, scopes that map to FHIR resource types, and a launch context that tells you which patient you’re looking at.
This tutorial follows SMART App Launch STU2.1 — the current published standard. If you’ve built an OAuth login flow before, you already understand 80% of it. The other 20% is what this covers.
We’re going to build a standalone SMART app that authenticates against a FHIR server, fetches a patient’s vital signs, and renders interactive charts — heart rate, blood pressure, SpO2, temperature, weight, and BMI. The whole thing fits in a single index.html file. No React, no bundler, no npm install. Just a text editor and a browser.
By the end you’ll have a working app and a mental model for how every SMART on FHIR app works under the hood — whether it’s a one-page demo or a production clinical decision support tool launching inside Epic.
Prerequisites
You need two things:
1. A mock.health account. Go to mock.health and sign up. It’s free. This gives you a FHIR R4 server with synthetic patients that actually have realistic clinical data — vital signs, conditions, medications, imaging studies.
2. A registered SMART app. In the mock.health dashboard, go to Sandbox → Register App and create a new app with these settings:
http://localhost:8080/smart-on-fhir-vital-signs/index.html
launch/patient, patient/Patient.rs, patient/Observation.rs, openid, fhirUser
Copy the Client ID — you’ll need it in a minute.
A note on scope syntax. SMART App Launch STU2 introduced a new scope format. The v1 format
patient/Patient.readbecamepatient/Patient.rsin v2, where the suffix letters map to individual operations: create, read, update, delete, search. So.rsmeans read + search, and v1’s.writemaps to v2’s.cud. Servers advertise which format they support viapermission-v1andpermission-v2in their capabilities. Most production EHRs accept both formats today. This tutorial uses v2 (*.rs), but v1 (*.read) will also work with mock.health.
The redirect URI matters. It must exactly match the URL where your app is running. When the authorization server sends the user back to your app after login, it appends an authorization code to this URL. If it doesn’t match what you registered, the server rejects the request.
Step 1: Discover the SMART Endpoints
Every SMART-enabled FHIR server publishes a discovery document at /.well-known/smart-configuration. This tells your app where to send the user for authorization and where to exchange codes for tokens.
const baseUrl = 'https://api.mock.health';
const response = await fetch(`${baseUrl}/fhir/.well-known/smart-configuration`);
const config = await response.json();
// config.authorization_endpoint → where to redirect the user
// config.token_endpoint → where to exchange the code for a token
The response looks like this:
{
"issuer": "https://api.mock.health",
"authorization_endpoint": "https://api.mock.health/smart/authorize",
"token_endpoint": "https://api.mock.health/smart/token",
"grant_types_supported": ["authorization_code"],
"code_challenge_methods_supported": ["S256"],
"scopes_supported": ["launch/patient", "patient/Patient.rs", "patient/Observation.rs", "openid", "fhirUser"],
"capabilities": ["launch-standalone", "client-public", "context-standalone-patient", "permission-v1", "permission-v2", "sso-openid-connect"]
}
Why discovery instead of hardcoding? Because every FHIR server puts these endpoints at different paths. Epic uses /oauth2/authorize. Oracle Health (Cerner) uses /tenants/{tenant}/protocols/oauth2/profiles/smart-v1/personas/patient/authorize. The discovery document means your app works against any conformant server without code changes.
Step 2: Generate a PKCE Challenge
PKCE (Proof Key for Code Exchange, pronounced “pixie”) prevents authorization code interception attacks. Your app generates a random secret (the verifier), hashes it (the challenge), and sends only the hash to the authorization server. When you exchange the code for a token later, you prove you’re the same app by sending the original verifier.
function generateCodeVerifier(len = 64) {
const arr = new Uint8Array(len);
crypto.getRandomValues(arr);
return base64url(arr);
}
async function computeCodeChallenge(verifier) {
const digest = await crypto.subtle.digest(
'SHA-256',
new TextEncoder().encode(verifier)
);
return base64url(new Uint8Array(digest));
}
function base64url(bytes) {
let bin = '';
for (const b of bytes) bin += String.fromCharCode(b);
return btoa(bin).replace(/+/g, '-').replace(///g, '_').replace(/=+$/, '');
}
Store the verifier in sessionStorage — you’ll need it after the redirect.
const verifier = generateCodeVerifier();
const challenge = await computeCodeChallenge(verifier);
sessionStorage.setItem('pkce_verifier', verifier);
Step 3: Redirect to Authorize
Build the authorization URL and redirect the user’s browser:
const state = crypto.randomUUID();
sessionStorage.setItem('auth_state', state);
const params = new URLSearchParams({
response_type: 'code',
client_id: clientId,
redirect_uri: location.origin + location.pathname,
scope: 'launch/patient patient/Patient.rs patient/Observation.rs openid fhirUser',
state,
aud: `${baseUrl}/fhir`,
code_challenge: challenge,
code_challenge_method: 'S256',
});
location.href = `${config.authorization_endpoint}?${params}`;
What each parameter does:
response_type: 'code' — We want an authorization code. Always code.client_id — Identifies your app.redirect_uri — Where to send the user back. Must exactly match what you registered.scope — What data you’re requesting. launch/patient asks for a patient context. patient/Observation.rs asks to read and search Observations scoped to that patient.state — A random string to prevent CSRF attacks.aud — The FHIR endpoint this token should work with. Prevents token replay across servers.code_challenge — The PKCE challenge.After this redirect, the user sees a consent screen. When they approve, the server redirects back to your redirect_uri with ?code=...&state=... appended.
Step 4: Handle the Callback and Exchange the Code
When your page loads, check if there’s a code parameter in the URL:
const params = new URLSearchParams(location.search);
const code = params.get('code');
const state = params.get('state');
if (code) {
if (state !== sessionStorage.getItem('auth_state')) {
throw new Error('State mismatch — possible CSRF');
}
history.replaceState(null, '', location.pathname);
const verifier = sessionStorage.getItem('pkce_verifier');
const body = new URLSearchParams({
grant_type: 'authorization_code',
code,
redirect_uri: location.origin + location.pathname,
client_id: clientId,
});
if (verifier) body.set('code_verifier', verifier);
const response = await fetch(tokenEndpoint, {
method: 'POST',
headers: { 'Content-Type': 'application/x-www-form-urlencoded' },
body,
});
const tokens = await response.json();
}
The token response includes everything you need:
{
"access_token": "eyJ0eXAiOiJKV1QiLCJhbGci...",
"token_type": "Bearer",
"expires_in": 3600,
"scope": "launch/patient patient/Patient.rs patient/Observation.rs openid fhirUser",
"patient": "a1b2c3d4-e5f6-7890-abcd-ef1234567890",
"id_token": "eyJhbGciOiJSUzI1NiJ9..."
}
Two SMART-specific fields: patient is the launch context — the ID of the patient the user selected. id_token contains the authenticated user’s identity via the fhirUser claim.
Step 5: Fetch Vital Signs
Now you have a bearer token and a patient ID:
const headers = {
Authorization: `Bearer ${tokens.access_token}`,
Accept: 'application/fhir+json',
};
const patient = await fetch(`${baseUrl}/fhir/Patient/${tokens.patient}`, { headers })
.then(r => r.json());
const observations = await fetch(
`${baseUrl}/fhir/Observation?patient=${tokens.patient}&category=vital-signs&_sort=-date&_count=200`,
{ headers }
).then(r => r.json());
Each Observation has a LOINC code that identifies what it measures:
| Vital Sign | LOINC Code | Value Location |
|---|---|---|
| Heart Rate | 8867-4 |
valueQuantity.value |
| Blood Pressure | 85354-9 |
component[].valueQuantity.value |
| Temperature | 8310-5 |
valueQuantity.value |
| SpO2 | 2708-6 |
valueQuantity.value |
| Weight | 29463-7 |
valueQuantity.value |
| BMI | 39156-5 |
valueQuantity.value |
Blood pressure is the odd one out. It’s a panel — the Observation itself has LOINC code 85354-9, but the actual systolic and diastolic values live in component entries with their own LOINC codes (8480-6 for systolic, 8462-4 for diastolic). Every FHIR developer hits this for the first time and wonders why it’s nested. Welcome to the club.
Step 6: Render the Charts
We use Chart.js — one CDN script tag, no build step:
<script src="https://cdn.jsdelivr.net/npm/chart.js@4"></script>
Group observations by type, sort by date, render a line chart for each. For blood pressure, render two datasets on the same chart — systolic and diastolic.
The Complete App
The full working app is ~475 lines in a single index.html. Clone it and run it:
git clone https://github.com/mock-health/samples.git
cd samples
python3 -m http.server 8080
# Open http://localhost:8080/smart-on-fhir-vital-signs/index.html
Enter your Client ID, click Connect, approve access, and you’ll see your patient’s vital signs charted out.
What Changes in Production EHRs
This tutorial uses mock.health, which implements the SMART spec faithfully. Production EHRs are different:
App registration takes weeks, not seconds. Epic’s App Orchard requires a formal review process. Budget 2–8 weeks for approval.
Scopes vary. Some EHRs still only accept v1 syntax (patient/Observation.read). Check the server’s .well-known/smart-configuration capabilities.
Discovery endpoints aren’t always where you expect. Some older servers don’t support .well-known/smart-configuration. Fall back to the CapabilityStatement (GET /metadata) and extract OAuth URLs from rest[0].security.extension.
Tokens expire and refresh tokens matter. In production, request offline_access scope and implement refresh token rotation.
None of this changes the fundamental flow. Discovery → PKCE → authorize → callback → token → API calls. Same everywhere. The operational details differ.
Sign up at mock.health — free tier, no sales call. The hardest part of building a SMART on FHIR app is getting access to a server that has realistic data and implements the spec correctly. Now you have one.

The mental model you start with determines every architecture decision that follows. Most teams are starting with the wrong one.
Edge computing used to mean “some devices send telemetry to the cloud.”
That era is over.
This is a re-post of Bruno Baloi’s blog Part 1: The Edge Isn’t a Place - It’s an Operating Reality on Synadia.com.
Today’s edge is a full operational domain where the physical world meets software systems: machines, vehicles, gateways, sensors, factories, field deployments. And once you move compute and messaging into that world, the rules change fast. Connections drop. Environments get hostile. Data gets generated faster than it can be forwarded. And the assumptions baked into a decade of cloud-native architecture patterns start failing in ways that are hard to diagnose because they fail quietly.
The first and most important shift is not a technical one, it’s a conceptual one.
The edge is not a far-away part of your system. It’s a different operating dimension entirely.
Why the geography framing gets you into trouble
When engineers hear “edge computing,” the mental image is usually spatial: devices on the left, cloud on the right, data flowing between them. The edge is just the far end of the pipeline.
That framing seems harmless until you start making architecture decisions based on it. If edge is just far-away infrastructure, you design for distance — low latency, efficient serialization, maybe some compression. You optimize the happy path.
What you don’t design for is disconnection as a first-class operating condition. Or physical exposure as a security assumption. Or the possibility that the “far end” of your system is running on hardware installed by a third-party contractor in an industrial cabinet that nobody has touched in eighteen months.
Those aren’t edge cases at the edge. They’re normal operating conditions. And the gap between “optimized for distance” and “designed for that reality” is where most edge architecture problems live.
The four constraints that don’t go away
If you’re building edge-to-core systems, you’re going to run into the same four problems regardless of industry, scale, or stack. Synadia’s Living on the Edge white paper names them clearly, and they’re worth exploring:
Connectivity. Edge links are intermittent by nature — not by failure. Devices roam in and out of coverage. Field gateways lose upstream access during maintenance windows. Vehicles move through dead zones. The question isn’t whether your edge nodes will disconnect; it’s whether your architecture treats that as an exception to handle or a condition to design for.
Security. Edge devices are physically exposed in ways that data center hardware never is. They’re accessible to anyone with physical proximity: maintenance crews, contractors, hostile actors with a USB drive and ten minutes to spare. Credentials get copied. Firmware gets tampered with. Unlike a compromised cloud instance that stays logically contained, a compromised edge device has a direct path toward your core systems if you haven’t designed the boundary carefully.
Distribution. Edge environments generate data at rates and granularities that cores can’t absorb naively. A manufacturing floor streaming sensor data from hundreds of machines isn’t a throughput problem — it’s a routing and filtering problem. The right data needs to reach the right destination at the right rate, which means the system has to be opinionated about what crosses the boundary and at what volume.
Observability. You need a real-time view across devices and the infrastructure connecting them to core — not just health checks, but end-to-end event traceability. Without it, you’re making operational decisions based on incomplete signals, and at the edge, incomplete signals tend to mean delayed incident detection and incorrect root cause analysis.
None of these four constraints are solvable by optimizing the happy path. They require deliberate design choices that change the shape of the architecture.
The reframe that unlocks the right patterns
Once you stop thinking of edge as geography and start thinking of it as a separate operational realm, the right patterns become obvious — or at least, the wrong patterns become obviously wrong.
The core insight, articulated in the Living on the Edge architecture guide, is this: treat edge and core as distinct realms connected by deliberately controlled paths. Not a single distributed system. Not an extended network. Two separate operating environments with an explicit, managed boundary between them.
That separation shows up in three practical ways:
Asynchronous communication instead of synchronous request-reply. HTTP works when the upstream is available and fast. At the edge, you can’t assume either. Asynchronous, event-driven communication means edge systems continue operating regardless of upstream availability — they produce events locally and let the transport layer handle delivery when conditions allow.
Store-and-forward instead of retry logic. When a link drops, edge systems shouldn’t be hammering a dead connection. They should be writing to a local durable store and resuming forwarding when connectivity restores — at a controlled rate that doesn’t overwhelm core consumers. (The second post in this series covers why this distinction matters more than most architects realize.)
Security realm constraints instead of shared credentials and open subjects. The boundary between edge and core should be explicit about what’s permitted to cross it. Not “encrypt everything and trust the network” — that’s perimeter thinking applied to a perimeter-free environment. The constraint lives in the topology, not just the transport.
This is where eventing becomes the backbone
If those three patterns share a common thread, it’s that they all require an eventing layer — not just messaging, but a platform that can handle asynchronous delivery, local durability, stream replication, and subject-level routing as composable primitives rather than as separate infrastructure.
Edge-to-core isn’t a “connect things to the cloud” problem. It’s a problem of how signals, commands, and durable streams move safely across unreliable, adversarial terrain — in both directions, at scale, with full traceability.
NATS and the Synadia Platform are purpose-built for exactly this architecture: leaf node topologies that treat edge clusters as first-class entities, JetStream for local durability and controlled forwarding, decentralized security for tightly scoped credentials, and end-to-end observability across the full mesh.
Questions worth asking before your next architecture review
Do you have a written definition of what “the edge” means in your system? If the answer is “the devices on the other side of the network,” the framing is still geographic. Try: “a separate operational realm with different connectivity, security, and observability characteristics than our core.”
Does your architecture document cover the disconnected case explicitly? If the connectivity section assumes the link is up, it’s documenting the happy path. The disconnected case is where edge architectures succeed or fail.
Are your edge and core security models the same? If your edge nodes use the same credentials, the same access scope, and the same network trust assumptions as your core services — you haven’t built a boundary. You’ve built a flat network with devices in inconvenient locations.
Do you know what your edge nodes are doing right now? Not in aggregate. Individually. If the answer is “we’d have to look at logs,” your observability model was designed for a data center, not an operational edge.
Getting these right doesn’t require exotic technology. It requires accepting that the edge is a different operational dimension — and designing for it from the start, not retrofitting resilience onto a system that assumed it wouldn’t need any.
This post is the first in a series exploring architecture patterns for resilient edge-to-core systems, based on Synadia’s white paper Living on the Edge: Eventing for a New Dimension.
Next up: why “just retry” is the wrong mental model for intermittent connectivity — and what happens when you find out the hard way.
Tags: Edge Computing · Distributed Systems · IoT · Software Architecture · Streaming · Microservices
I recently wrote about agent-comm — a communication layer that lets multiple AI coding agents talk to each other. But talking is only half the problem. The other half? Knowing what work needs to be done, who’s doing it, and what stage it’s in.
The problem
When you run multiple AI agents in parallel — say three Claude Code sessions working on different parts of a feature — things fall apart fast:
I needed something that gives AI agents the same project management primitives that human teams take for granted — but exposed as MCP tools they can call directly.
The fix: a pipeline for AI agents
agent-tasks is an open-source pipeline-driven task management server that AI coding agents can use via MCP. Think of it as a lightweight Jira — but designed for machines, not humans.
Every task flows through configurable pipeline stages:
backlog → spec → plan → implement → test → review → done
Agents claim tasks, advance them through stages, attach artifacts at each step, and block on dependencies — all through 31 MCP tools.
What agents can do with it
1. Pipeline-driven workflow
Tasks aren’t just “open” or “closed.” They move through stages, and each stage produces artifacts:
2. Dependencies and blocking
task_add_dependency(task_id=5, depends_on=3, type="blocks")
Agent 5 literally cannot advance until task 3 is done. The system detects cycles too — no deadlocks.
3. Multi-agent collaboration
Agents can be assigned roles on tasks:
4. Approval gates
task_request_approval(task_id=5, stage="review")
# Another agent:
task_approve(task_id=5)
This enforces a maker-checker pattern. No task moves to “done” without explicit sign-off.
5. Artifacts with versioning
Every spec, plan, test result, and review note is stored as a versioned artifact attached to the task. Previous versions are chained so you can see how decisions evolved.
6. Full-text search
Need to find that task about the auth middleware rewrite? task_search(query="auth middleware") uses SQLite FTS5 to search across all task titles and descriptions.
Setup
Install it:
npm install -g agent-tasks
Add to your MCP config (Claude Code settings.json, Cursor, etc.):
{
"mcpServers": {
"agent-tasks": {
"command": "npx",
"args": ["-y", "agent-tasks"]
}
}
}
That’s it. The dashboard auto-starts at http://localhost:3422.
A real coordination pattern
Here’s how I use it with three agents working on a feature:
Agent 1 (planner) creates the task and writes a spec:
task_create(title="Add rate limiting to API", project="backend")
task_claim(task_id=42)
task_add_artifact(task_id=42, name="spec", content="...")
task_advance(task_id=42) # spec → plan
Agent 2 (implementer) picks up the next unblocked task:
task_next(project="backend") # returns task 42 at plan stage
task_claim(task_id=42)
task_expand(task_id=42, subtasks=["Add middleware", "Add Redis store", "Add config"])
# ... implements each subtask ...
task_advance(task_id=42) # implement → test
Agent 3 (reviewer) reviews and approves:
task_claim(task_id=42)
task_add_artifact(task_id=42, name="review-notes", content="LGTM, clean implementation")
task_approve(task_id=42)
task_advance(task_id=42) # review → done
The whole flow is visible in the dashboard — a kanban board that updates in real-time via WebSocket.
The dashboard
The built-in dashboard gives you a kanban view of all tasks across pipeline stages. You can:
No frameworks — it’s vanilla HTML/CSS/JS with morphdom for efficient DOM updates.
Technical details
It pairs naturally with agent-comm — when a task changes, agents get notified through the communication bridge.
What’s next
I’m actively using this to coordinate up to 5 Claude Code agents working simultaneously. If you’re running multi-agent setups and losing track of what’s happening, give it a try.
GitHub: github.com/keshrath/agent-tasks
Feedback welcome — open an issue or drop a comment below.
TL;DR: I made a config pack that turns OpenCode into a structured game development studio with 48 specialized agents and 37 workflow skills — all running on Big Pickle (free). Drop it in your ~/.config/opencode/ and your next game gets a full team.
The Problem With AI-Assisted Game Dev
Solo game dev with AI is genuinely powerful. But there’s a fundamental issue nobody talks about: a single AI session has no structure.
Nothing stops you from hardcoding magic numbers at 2am. Nobody’s checking whether your inventory system actually fits the game’s vision. There’s no QA pass, no architecture review, no one asking “wait, does this mechanic even make sense?”
You end up with a chat assistant, not a team.
What I Built
OpenCode Game Studios is a drop-in configuration for OpenCode that transforms it into a proper studio hierarchy:
Tier 1 — Directors (Strategic)
creative-director · technical-director · producer
Tier 2 — Department Leads
game-designer · lead-programmer · art-director
audio-director · narrative-director · qa-lead · release-manager
Tier 3 — Specialists (22 agents)
gameplay-programmer · engine-programmer · ai-programmer
level-designer · systems-designer · sound-designer · writer
performance-analyst · qa-tester · accessibility-specialist ...
Plus dedicated engine specialists for Godot, Unity, and Unreal — 5 agents per engine covering shaders, scripting, DOTS, GAS, blueprints, replication, UI systems.
48 agents total.
How It Works
Every agent knows its role in the studio. The creative-director guards the vision. The lead-programmer owns architecture decisions. The qa-tester finds edge cases. You call whoever you need:
@game-designer "Design a combat system for my roguelike"
@lead-programmer "Review this ECS architecture"
@godot-shader-specialist "Write a 2D water shader with refraction"
@qa-tester "What are the edge cases in this save system?"
And there are 37 workflow skills via slash commands:
/start — Kick off a new game project with proper setup
/sprint-plan — Plan your week with task breakdown
/code-review — Full architectural review
/balance-check — Game economy and difficulty audit
/brainstorm — Structured creative session
/release-checklist — Pre-launch verification
/patch-notes — Auto-generate from your git history
The Collaboration Protocol
Every task follows a mandatory flow: Question → Options → Decision → Draft → Approval
Agents must ask “May I write this to [filepath]?” before touching your code. They show drafts before requesting approval. Multi-file changes need explicit sign-off for the entire changeset.
You make all final decisions. The agents provide expertise, not autonomy. This single constraint has made the difference between sessions that produce focused output and sessions that spin forever.
100% Free
Everything runs on OpenCode’s Big Pickle model. No API keys, no tokens burning, no credit card. The config defaults every agent to opencode/big-pickle. You can override specific agents to premium models if you want, but the whole setup works out of the box for free.
Getting Started
# Install OpenCode
npm install -g opencode
# Clone the studio config
git clone https://github.com/TraftG/opencode-game-studio
cd opencode-game-studio
# Apply globally
cp -r .opencode/* ~/.config/opencode/
# Start your studio
opencode
That’s it. Open a session, type @creative-director and describe your game idea. Watch it ask you the right questions instead of just vibing.
Why I Made This
I kept running into the same wall: the AI was capable, but sessions had no memory of earlier decisions and no consistent “voice” keeping the project coherent. A creative director who remembers that this is a horror game, not an action game. A QA lead who always checks for save corruption. A technical director who enforces the performance budget you set on day one.
Structured agents with clear roles solved this better than any amount of prompt tweaking.
What’s Next
I’m actively using this on my own projects. If you build something with it or have ideas for new agents/skills, PRs are very welcome.
⭐ github.com/TraftG/opencode-game-studio
Built by @TraftG — reach out on Telegram if you have questions about the setup.
Your Vibe-Coded App Will Break in Production. Here’s Why.
170 out of 1,645 Lovable-built apps had data-exposure vulnerabilities. That’s 10.3% — one in ten apps leaking user data before a single real customer signed up. This stat comes from a May 2025 security audit, and the problem has only gotten worse as vibe coding tools have grown in popularity.
I run a software development company that has rescued 12 vibe-coded apps in the past 6 months. Founders come to us after burning $5,000-$15,000 in Lovable and Bolt.new credits, with an app that works in demos but falls apart under real traffic. The problems are always the same.
The 80/20 Wall: Where Vibe Coding Breaks Down
AI-generated code is brilliant for the first 80% of a project. Landing pages, CRUD forms, basic auth flows, dashboard layouts — Lovable and Bolt.new handle these faster than any human developer.
The last 20% is where projects die:
Lovable’s own documentation acknowledges this: the platform is designed for prototyping and MVPs, not production workloads. Bolt.new’s token consumption scales with codebase size, meaning the same edit costs more tokens as your project grows — creating a perverse incentive where fixing bugs gets progressively more expensive.
Vibe Coding Security Problems: The Hidden Risks
The security issues in AI-generated code aren’t random — they follow predictable patterns:
1. Exposed API Keys
Vibe coding tools frequently embed API keys directly in client-side code. We found Stripe secret keys, Supabase service role keys, and SendGrid API keys in the frontend bundle of 4 out of 12 apps we audited.
// This was in a production Lovable app's client bundle
const supabase = createClient(
'https://xyz.supabase.co',
'eyJhbGciOiJIUzI1NiIsInR5cCI6IkpXVCJ9...' // service_role key - full DB access
);
The service_role key bypasses Row Level Security entirely. Anyone who opens browser DevTools can read, modify, or delete every row in every table.
2. Missing Server-Side Validation
AI-generated apps typically validate inputs on the client only. The server accepts whatever arrives:
// Client-side validation exists...
if (amount > 0 && amount < 10000) {
await fetch('/api/transfer', { body: JSON.stringify({ amount }) });
}
// ...but the API endpoint trusts the input blindly
app.post('/api/transfer', async (req, res) => {
const { amount } = req.body; // No server-side validation
await transferFunds(amount); // Negative amounts? Infinity? Strings?
});
3. Broken Authentication
Session handling in vibe-coded apps is typically the weakest link. We’ve seen JWT tokens with no expiration, refresh tokens stored in localStorage (XSS-vulnerable), and password reset flows that don’t invalidate previous tokens.
For the full security and architecture audit checklist, we published a detailed production-readiness guide covering every vulnerability pattern we’ve encountered.
Lovable to Production: What Actually Needs to Change
Taking a Lovable or Bolt.new app to production isn’t about rewriting everything. It’s about fixing the 20% that AI tools get wrong. Here’s our audit checklist after 12 production rescues:
Authentication (2-3 days of work)
Database Security (1-2 days)
API Hardening (2-3 days)
Deployment and Infrastructure (1-2 days)
Performance (1-2 days)
Total: 7-12 days of professional development work. That’s the gap between a vibe-coded prototype and a production app. Not a rewrite — a hardening sprint.
The Credit Burn Problem: When AI Tools Cost More Than Developers
A pattern we see repeatedly: founders burn $3,000-$8,000 in Lovable credits trying to fix bugs that a developer would solve in 2 hours.
Lovable users report burning 400 credits in under an hour fixing circular bugs. Bolt users describe “endless error loops” where each fix creates a new problem. The AI doesn’t understand the architectural context — it fixes symptoms, not causes.
Here’s the math that founders discover too late:
Compare: a senior developer at $40/hour spends 2-4 hours per bug, fixes the root cause (not a workaround), and the fix stays fixed. Total for 15-30 bugs: $1,200-$4,800 — and you get a codebase that’s actually maintainable.
The vibe coding tools aren’t the problem. Using them past their intended scope is.
Production-Ready Checklist: AI App to Real Product
Before launching any vibe-coded app to real users:
Security
Reliability
Performance
Operations
When to Keep Vibe Coding, When to Hire Developers
Vibe coding is perfect for:
Hire developers when:
The smartest founders we work with use vibe coding for the prototype, validate the idea, then bring in engineers for the production build. They get the speed of AI tools for exploration and the reliability of human engineers for execution.
The worst approach? Trying to make a vibe-coded prototype handle production load. That’s how you get the 10.3% data-exposure stat.
What We Tell Every Founder Who Calls Us
Your Lovable or Bolt.new app isn’t garbage. It’s a prototype. A very good one, probably. The architecture just needs professional hardening — typically 7-12 days of focused work.
Don’t rewrite from scratch. Don’t burn more credits trying to fix it with AI. And definitely don’t launch it to real users with payment processing in its current state.
Get a proper MVP architecture review, fix the security gaps, add monitoring, and ship it right. The total cost of hardening is almost always less than what founders spend on credits trying to fix problems the AI tools created.
Build fast with AI. Ship with engineers. That’s the playbook for 2026.
Yash Korat is the CEO of Geminate Solutions, a custom software development company that has shipped 50+ products for startups across the US, UK, and Australia. His team has rescued 12 vibe-coded apps in the past 6 months alone.
Build AI Agents in Node.js That Handle 10K Requests/Day
Most AI agent tutorials teach you to build a toy. A chatbot that answers trivia questions. A script that summarizes text. Cool for a weekend project — useless in production.
I’ve spent the last 18 months shipping AI agents that handle 10,000+ requests per day for SaaS companies. Agents that book appointments, process refunds, triage support tickets, and orchestrate multi-step workflows without human intervention.
Here’s everything I learned about building AI agents with Node.js that actually survive contact with real users.
What Are AI Agents (And What They’re Not)
An AI agent is not a chatbot with extra steps. A chatbot responds to messages. An agent acts.
The difference comes down to three properties:
Think of it this way: a chatbot is a calculator. An AI agent is an accountant. The accountant decides which calculations to run, pulls the right numbers from your books, and delivers the finished report.
In March 2026, every major LLM provider supports agentic patterns natively. Claude’s tool_use API, OpenAI’s function calling, and Gemini’s function declarations all follow the same core loop: prompt, think, act, observe, repeat.
The real challenge isn’t getting an agent to work. It’s getting it to work reliably at scale.
The Agent Loop: Build an AI Agent in Node.js
Every production AI agent follows this pattern:
User Input -> LLM Reasoning -> Tool Selection -> Tool Execution -> Result Observation -> (loop or respond)
Here’s the minimal implementation using the Claude API:
import Anthropic from '@anthropic-ai/sdk';
const client = new Anthropic();
const tools = [
{
name: "search_orders",
description: "Search customer orders by email or order ID",
input_schema: {
type: "object",
properties: {
query: { type: "string", description: "Email or order ID" },
status: { type: "string", enum: ["pending", "shipped", "delivered", "refunded"] }
},
required: ["query"]
}
},
{
name: "process_refund",
description: "Issue a refund for a specific order",
input_schema: {
type: "object",
properties: {
order_id: { type: "string" },
reason: { type: "string" },
amount_cents: { type: "number" }
},
required: ["order_id", "reason"]
}
}
];
async function runAgent(userQuery) {
let messages = [{ role: "user", content: userQuery }];
while (true) {
const response = await client.messages.create({
model: "claude-sonnet-4-6",
max_tokens: 1024,
system: "You are a customer support agent. Use tools to look up orders and process refunds.",
tools,
messages
});
if (response.stop_reason === "end_turn") {
const textBlock = response.content.find(b => b.type === "text");
return textBlock?.text || "Task completed.";
}
const toolBlocks = response.content.filter(b => b.type === "tool_use");
if (toolBlocks.length === 0) break;
messages.push({ role: "assistant", content: response.content });
const toolResults = [];
for (const block of toolBlocks) {
const result = await executeTool(block.name, block.input);
toolResults.push({
type: "tool_result",
tool_use_id: block.id,
content: JSON.stringify(result)
});
}
messages.push({ role: "user", content: toolResults });
}
}
This is the foundation. The while(true) loop is intentional — the agent keeps calling tools until it has enough information to respond.
Claude API in Node.js: Tool Calling That Works
The executeTool function is where your business logic lives:
async function executeTool(name, input) {
const toolHandlers = {
search_orders: async ({ query, status }) => {
const orders = await db.orders.findMany({
where: {
OR: [{ email: query }, { id: query }],
...(status && { status })
},
take: 10
});
return { orders, count: orders.length };
},
process_refund: async ({ order_id, reason, amount_cents }) => {
const order = await db.orders.findUnique({ where: { id: order_id } });
if (!order) return { error: "Order not found" };
if (order.status === "refunded") return { error: "Already refunded" };
const refund = await stripe.refunds.create({
payment_intent: order.paymentIntentId,
amount: amount_cents || undefined
});
await db.orders.update({
where: { id: order_id },
data: { status: "refunded", refundReason: reason }
});
return { success: true, refund_id: refund.id };
}
};
const handler = toolHandlers[name];
if (!handler) return { error: `Unknown tool: ${name}` };
try {
return await handler(input);
} catch (err) {
return { error: err.message };
}
}
Two patterns to notice: every tool returns structured data (never raw errors), and every tool validates inputs before executing side effects. Never trust the LLM to validate — validate in the handler.
Production Error Handling: Deploy AI Agents That Don’t Crash
The tutorial code above will crash in production within hours. Here’s what you actually need:
async function runAgentWithGuards(userQuery, maxIterations = 10) {
let messages = [{ role: "user", content: userQuery }];
let iterations = 0;
while (iterations < maxIterations) {
iterations++;
let response;
try {
response = await client.messages.create({
model: "claude-sonnet-4-6",
max_tokens: 1024,
tools,
messages
});
} catch (err) {
if (err.status === 429) {
const delay = Math.min(1000 * Math.pow(2, iterations), 30000);
await new Promise(r => setTimeout(r, delay));
iterations--;
continue;
}
throw new Error(`Agent failed: ${err.message}`);
}
if (response.stop_reason === "end_turn") {
const text = response.content.find(b => b.type === "text");
return {
answer: text?.text || "Done.",
iterations,
tokensUsed: response.usage.input_tokens + response.usage.output_tokens
};
}
const toolBlocks = response.content.filter(b => b.type === "tool_use");
if (toolBlocks.length === 0) break;
messages.push({ role: "assistant", content: response.content });
const toolResults = [];
for (const block of toolBlocks) {
try {
const result = await executeTool(block.name, block.input);
toolResults.push({
type: "tool_result",
tool_use_id: block.id,
content: JSON.stringify(result)
});
} catch (toolErr) {
toolResults.push({
type: "tool_result",
tool_use_id: block.id,
content: JSON.stringify({ error: toolErr.message }),
is_error: true
});
}
}
messages.push({ role: "user", content: toolResults });
}
return { answer: "Could not complete within allowed steps.", iterations, maxedOut: true };
}
Three production patterns that save you at 3 AM:
Agentic AI Patterns for SaaS Applications
Shipping a single agent is the easy part. Shipping an agent system for a SaaS product means solving coordination, state management, and cost control.
Here are the patterns we use at Geminate Solutions when building AI-powered features for production SaaS:
Pattern 1: Router Agent to Specialist Agents
Don’t build one mega-agent. Build a lightweight router that classifies intent and delegates to specialists. A billing agent has Stripe tools only. A technical agent has logs and deployment tools. Each specialist has a narrow tool set, which reduces hallucination and keeps token costs down.
Pattern 2: Human-in-the-Loop Checkpoints
For high-stakes actions (refunds over $100, account deletions), pause the agent loop and request human approval via Slack webhook. This isn’t optional for B2B SaaS — your customers will demand it.
Pattern 3: Conversation Memory with Sliding Window
Long conversations blow up your token budget. Keep the system prompt + last 6 messages + a compressed summary of earlier messages. The Claude API SaaS integration guide covers token optimization strategies in depth.
Hybrid Automation: When Code Meets No-Code
Not every AI workflow needs custom code. For internal operations — lead scoring, email triage, content pipelines — combining Node.js agents with tools like n8n gives you the best of both worlds.
The pattern: n8n handles the trigger (new email, form submission, scheduled job) and calls your Node.js agent via HTTP webhook. The agent does the reasoning, n8n handles the plumbing. This hybrid approach cuts development time by 40-60% for internal automation.
AI Agent Architecture: Production Reference
Here’s the architecture handling 10K+ daily requests for one of our SaaS clients:
API Gateway (Express/Fastify) - Rate limiting, auth, request queue
|
Router Agent (Claude Haiku) - Intent classification, fast + cheap
|
+-- Support Agent (Sonnet) - 6 tools (tickets, orders, FAQ)
+-- Sales Agent (Sonnet) - 4 tools (CRM, calendar, email)
+-- Ops Agent (Sonnet) - 8 tools (deploy, logs, alerts)
|
Tool Execution Layer - Postgres, Stripe, SendGrid, Slack
|
Observability - Token tracking, latency, cost per conversation
Key decisions: Haiku for routing (200ms, 1/10th cost), Sonnet for reasoning. Tool execution layer is shared across agents. Observability is non-negotiable — track tokens per conversation and cost per resolution.
Deploy Your AI Agent: Production Checklist
Before you ship:
Start with a single, well-scoped agent. Customer support triage is the best first project — clear intent classification, bounded tool set, measurable ROI.
The teams shipping the fastest right now aren’t the ones with the most ML engineers. They’re the ones who treat AI agents as software engineering problems — with proper error handling, observability, testing, and deployment pipelines.
Build it like you’d build any production system. Because that’s exactly what it is.
Yash Korat is the CEO of Geminate Solutions, a custom software development company shipping AI-powered products for startups across the US, UK, and Australia. His team integrates Claude, GPT-4, and Gemini APIs into production SaaS applications.
If you’ve ever tried to compare LLM pricing across vendors you know how painful it is. One charges per token, another per character, another per request. Cached input discounts exist but good luck finding them. Context window pricing is buried. And by the time you’ve normalized everything into a spreadsheet something changed on a pricing page and your numbers are stale.
This is the problem ATOM was built to solve. It tracks 2,583 SKUs across 47 vendors, normalizes everything to a common unit, and exposes it all through an MCP server your agents can query directly.
Here’s how to set it up and what you can actually do with it.
What MCP gives you here
Model Context Protocol lets AI agents connect to external data sources through a standardized interface. Claude, Cursor, Windsurf and others support it natively.
Instead of pasting a pricing table into your prompt and hoping it’s current, you give your agent a live connection to the source. It queries, reasons, and acts on real numbers.
Setting up the ATOM MCP server
ATOM’s server is published on npm, Smithery, and the official MCP registry.
Claude Desktop
Add this to your claude_desktop_config.json and restart:
{
"mcpServers": {
"atom-pricing": {
"command": "npx",
"args": ["-y", "atom-mcp-server"]
}
}
}
Cursor or Windsurf
Add the server endpoint in your MCP settings:
https://atom-mcp-server-production.up.railway.app/mcp
Any other MCP client
The server supports both HTTP SSE and stdio transport. Run it locally via npx or point at the Railway endpoint above.
The tools
The free tier includes 4 tools that give you macro market intelligence with no login required. MCP PRO ($49/mo) unlocks the remaining 4, which give you model-level and vendor-level detail.
Free tier
| Tool | What it does |
|---|---|
list_vendors |
All 47 tracked vendors with type and region |
get_kpis |
6 live market KPIs updated weekly |
get_index_benchmarks |
14 AIPI price indexes by modality and tier |
get_market_stats |
Aggregate supply and cost structure data |
MCP PRO
| Tool | What it does |
|---|---|
search_models |
Filter by context size, tool support, modality, price |
get_model_detail |
Full spec and pricing for a specific model |
compare_prices |
Cross-vendor comparison for a model family |
get_vendor_catalog |
Full SKU list for a specific vendor |
What it looks like in practice
Check what the market looks like right now (free)
get_kpis
This week’s numbers:
These are median figures across all tracked SKUs, recalculated every Monday.
Find the cheapest model with 100K+ context and tool calling (PRO)
search_models
context_window_min: 100000
tool_calling: true
sort_by: input_price_asc
Returns model-level results with normalized per-token pricing across vendors. The spread between cheapest and most expensive for functionally similar models is typically over 30x. That difference compounds fast at any real usage volume.
Compare vendors for a specific model family (PRO)
compare_prices
model_family: "Llama 3.3 70B"
Returns every vendor offering that model with normalized pricing so you can make a direct comparison without doing any unit conversion yourself.
Why this is useful for agent architecture
If you’re building anything that makes a lot of LLM calls, model routing based on cost and capability is a real decision you’re making, consciously or not. The cheapest model that can handle a task should handle it.
With ATOM connected your agent can check current prices before picking a model, catch when a vendor changes pricing, estimate the cost of a planned workload before running it, and compare vendors for a specific capability requirement. That reasoning used to mean a spreadsheet someone had to maintain. Now it’s a tool call.
A note on the data
ATOM uses a chained matched-model methodology, the same logic you’d apply to a commodity price index. Every SKU is normalized to a common unit, timestamped, and verified. The point of the methodology is to eliminate composition bias so week-over-week comparisons are actually meaningful and not just reflecting which vendors got added or dropped.
Full methodology at a7om.com/methodology.
Try it
Run npx atom-mcp-server or search “ATOM” on Smithery. Free tier covers 4 tools with no login. MCP PRO is at a7om.com/mcp.
The inference market now has a benchmark. Might as well use it.
How We Built EdTech Apps Serving 500K+ Users
The global EdTech market crossed $340 billion in 2025, growing at 16.3% CAGR according to HolonIQ’s annual report. Yet 70% of education startups fail within two years — not because of bad ideas, but because of bad architecture decisions made in month one.
Our team at Geminate Solutions has shipped four EdTech platforms: Youth Pathshala (250K daily active users), VSmart Academy (200K+ students), Your CA Buddy (95% exam pass rate), and Academic Edutech (live virtual classrooms). This article shares what we learned building them — the architecture patterns, tech stack choices, and scaling strategies that actually worked.
EdTech App Architecture That Survives 250K Daily Users
Most education platforms start as simple CRUD apps. Videos go up, students watch, quizzes get submitted. This works until 10,000 concurrent users hit your system during a live exam.
Here is the architecture we use after four production EdTech builds:
Client Layer: Flutter App (iOS + Android + Web)
- Offline Content Cache
- Video Player (HLS)
- Real-time Quiz Engine
API Gateway (Rate Limited)
|
+-- Content Service (Node.js)
+-- Auth & Payment Service
+-- Analytics Service (Events)
|
Media Pipeline: S3 -> CloudFront -> HLS (Adaptive Bitrate)
Three non-negotiable principles:
Why Flutter Works for Cross-Platform Education Apps
We evaluated React Native, native iOS/Android, and Flutter across all four EdTech projects. Flutter won every time for education apps. Here is why:
Custom UI for learning interfaces. Education apps need progress rings, interactive quizzes, drag-and-drop exercises, animated explanations. Flutter’s widget composition model makes building these 3-4x faster than platform-native alternatives.
Single codebase, three platforms. Youth Pathshala ships to iOS, Android, and web from one Dart codebase. Our 4-person Flutter team maintains all three. A native approach would have needed 8-10 developers.
Offline content sync. Flutter’s sqflite + Hive combination handles local content caching well. Students download course modules on Wi-Fi and study offline. When connectivity returns, progress syncs automatically.
For the Your CA Buddy app, our Flutter developers built a custom PDF annotation layer and timed mock-exam engine that contributed to that 95% pass rate among active users.
Live Streaming Classrooms: WebRTC vs HLS
Academic Edutech needed live virtual classrooms with real-time interaction. This forced us to make a critical choice: WebRTC or HLS.
WebRTC gives sub-second latency. Teachers ask a question, students respond instantly. But WebRTC connections are peer-to-peer at heart, and scaling beyond 50 concurrent viewers per room requires a Selective Forwarding Unit (SFU).
HLS scales to millions through CDN but introduces 6-15 seconds of latency. Fine for pre-recorded content, terrible for live Q&A.
Our hybrid approach:
This architecture handled Academic Edutech’s 500-student live classes with consistent quality. The WebSocket chat layer meant even HLS-stream students could ask questions with zero perceived delay.
Essential EdTech App Features: LMS Feature Checklist
After building four platforms, here are the features that actually drive retention — ranked by impact on our metrics:
Tier 1: Launch Features (MVP)
Tier 2: Retention Features (Month 2-3)
Tier 3: Scale Features (Month 4+)
VSmart Academy’s retention jumped 34% after we added spaced repetition reminders in month three. Youth Pathshala’s DAU grew from 80K to 250K after offline downloads launched. Features should follow data, not assumptions.
EdTech App Development Cost: Realistic Breakdown
Every founder asks “how much does it cost to build an education app?” Here is an honest breakdown based on our four production builds:
MVP (3-4 months): $25,000 – $45,000
Production-Ready (6-8 months): $60,000 – $120,000
Enterprise Scale (12+ months): $150,000 – $300,000
Where most founders waste money: Building custom video infrastructure. Use Mux or Cloudflare Stream. The encoding pipeline alone can consume $30,000+ in development time.
Where you should invest more: The content authoring tool for instructors. If teachers struggle to upload and organize content, your platform dies regardless of how good the student experience is.
Scaling an EdTech Platform From 10K to 250K Users
Youth Pathshala’s growth from 10,000 to 250,000 daily active users forced five architectural changes:
The pattern: every 2-3x growth multiplier exposes the next bottleneck. Plan for the current order of magnitude plus one.
EdTech MVP: Ship in 90 Days
If you are building an EdTech product in 2026, here is the 90-day checklist we give every client:
Week 1-2: Flutter project setup, Node.js backend, PostgreSQL schema, CI/CD pipeline, video hosting account
Week 3-6: Authentication, course catalog, video player with HLS, progress tracking, payment integration
Week 7-10: Push notifications, quiz engine, discussion/comments, offline downloads, admin panel
Week 11-12: Load testing, security audit, App Store submission, monitoring setup
Week 13: Staged rollout (10% to 50% to 100%)
This timeline assumes a 4-5 person team. Solo developers should plan for 5-6 months.
The EdTech market rewards speed to market and content quality over technical sophistication. Ship the MVP, watch how students actually use it, then invest engineering effort where the data points.
Yash Korat is the CEO of Geminate Solutions, a custom software development company that has shipped 4 EdTech platforms serving 500K+ combined users. His team built Youth Pathshala (250K daily active users) and VSmart Academy (200K+ students).