Azure Functions for .NET Developers: Series
Introduction: from local to production
Local tooling hides four things you have to own in production: packaging, authentication, configuration injection, and rollback. func start handles all of them silently; a CI/CD pipeline does not, and the decisions you make about each one compound quickly.
The gap is easy to miss. Your local environment reads from local.settings.json, authenticates with your personal identity, and recovers from bad deploys by letting you just restart. Azure does none of that for you. You need a packaging step, a way to authenticate from a pipeline without storing secrets, a strategy for injecting environment-specific configuration, and some mechanism for rolling back when a deploy breaks something.
This article covers two stages of that journey. First, manual deployment using the Azure CLI and the Functions Core Tools: useful for quick validation and understanding what the automated pipeline will do under the hood. Then a GitHub Actions workflow with two jobs, OIDC authentication (no stored credentials in your repository), deployment slots for zero-downtime releases, and configuration management that keeps secrets out of your pipeline definition entirely.
Manual deployment options
Before wiring up a full CI/CD pipeline, understand what actually happens when code reaches Azure. Manual deployment gives you that visibility, and it remains useful long after you’ve automated everything: for one-off hotfixes, for validating a packaging issue, or for deploying to a scratch environment without spinning up a workflow run.
func azure functionapp publish
The Core Tools command is the closest thing to a one-stop deploy:
func azure functionapp publish <APP_NAME>
Under the hood, it runs dotnet build --output bin/publish, creates a .zip archive (filtered by your .funcignore), uploads the archive via the Kudu ZipDeploy API (or One Deploy for Flex Consumption plans), and then syncs triggers and restarts the host. By default it also sets WEBSITE_RUN_FROM_PACKAGE=1 on the app, covered in the next subsection.
Flags you’ll reach for regularly:
# Skip the local build — useful when you've already built in CI
func azure functionapp publish <APP_NAME> --no-build

# Deploy to a staging slot instead of production
func azure functionapp publish <APP_NAME> --slot staging

# Push local.settings.json values to app settings (prompts for confirmation)
func azure functionapp publish <APP_NAME> --publish-local-settings -i

# Verify what files will be included before committing to a deploy
func azure functionapp publish <APP_NAME> --list-included-files
Run --list-included-files at least once per project. If your archive includes bin/ debug artifacts, test assemblies, or secrets you meant to .funcignore, you want to catch that before it’s sitting on a production host.
A minimal .funcignore for a .NET project:
*.csproj
*.sln
.git/
.vscode/
local.settings.json
test/
local.settings.json is the most important exclusion: it often contains connection strings and keys meant for local development only.
Azure CLI: two commands, two APIs
The Azure CLI gives you two distinct options, and picking the wrong one for your plan type will fail silently or throw a confusing error.
# Kudu ZipDeploy — works for Consumption, Premium, and Dedicated plans
az functionapp deployment source config-zip
  -g <RESOURCE_GROUP> -n <APP_NAME> --src ./publish.zip

# One Deploy API — required for Flex Consumption, also valid elsewhere
az functionapp deploy
  -g <RESOURCE_GROUP> -n <APP_NAME> --src-path ./publish.zip --type zip
The older config-zip command talks directly to Kudu and does no building; you’re responsible for providing a publish-ready zip. It does not support Flex Consumption, the newer serverless plan that bypasses Kudu entirely. If you’re on Flex Consumption, az functionapp deploy is the only CLI path that works. It also gives you --clean to remove files not in the archive and --async to return immediately without polling for completion.
A rule of thumb: if you’re writing a deploy script that needs to work across plan types, use az functionapp deploy. If you’re on a legacy plan and config-zip already exists in your runbooks, it’s fine to leave it.
Run-From-Package and why it matters
When WEBSITE_RUN_FROM_PACKAGE=1 is set, Azure mounts your zip archive as a read-only filesystem at wwwroot rather than extracting files into it. This is the default behavior when you publish with Core Tools, and it has real production benefits: deployment is atomic (the old package stays mounted until the new one is ready), file-copy locking errors disappear, and cold start times improve because the runtime reads directly from the zip.
The constraints: wwwroot becomes read-only (portal-based editing no longer works), the archive has a 1 GB limit, and you should not set this value on Flex Consumption plans, which manage packages differently.
Which method to use

For anything beyond a one-off fix or an afternoon prototype, these manual commands are the foundation you’ll extract into a pipeline. Knowing what each one does makes the GitHub Actions steps in the next section easier to reason about when something goes wrong.
GitHub Actions workflow setup
The pieces fit together like this:

The build job produces a single artifact. The deploy job authenticates via OIDC, pushes to a staging slot, and swaps it into production.
The complete workflow is below. Read through it first; the walkthrough after explains the decisions behind each piece.
name: Deploy Azure Functions (.NET 10)

on:
  push:
    branches: [main]

jobs:
  build:
    runs-on: ubuntu-latest
    permissions:
      contents: read
    steps:
      - uses: actions/checkout@v4

      - uses: actions/setup-dotnet@v4
        with:
          dotnet-version: '10.0.x'
          cache: true

      - run: dotnet restore --locked-mode

      - run: >
          dotnet publish src/MyFunctionApp
          --configuration Release
          --output ./output
          --runtime linux-x64
          --self-contained true

      - uses: actions/upload-artifact@v4
        with:
          name: function-app
          path: ./output
          retention-days: 3

  deploy:
    runs-on: ubuntu-latest
    needs: build
    environment: production
    permissions:
      id-token: write
      contents: read
    steps:
      - uses: actions/download-artifact@v4
        with:
          name: function-app
          path: ./output

      - uses: azure/login@v2
        with:
          client-id: ${{ secrets.AZURE_CLIENT_ID }}
          tenant-id: ${{ secrets.AZURE_TENANT_ID }}
          subscription-id: ${{ secrets.AZURE_SUBSCRIPTION_ID }}

      - uses: Azure/functions-action@v1
        with:
          app-name: ${{ vars.FUNCTION_APP_NAME }}
          slot-name: staging
          package: ./output

      - name: Swap staging to production
        uses: azure/cli@v2
        with:
          inlineScript: |
            az functionapp deployment slot swap
              --name ${{ vars.FUNCTION_APP_NAME }}
              --resource-group ${{ vars.RESOURCE_GROUP }}
              --slot staging
              --target-slot production
This is the same function app from Parts 1 through 7. The complete source is in the azure-functions-samples repository. Every push to main builds it, deploys to a staging slot, and swaps to production. No secrets stored, no manual steps, and a rollback is one swap away.
If your plan doesn’t support slots (Consumption with only one slot available, or Flex Consumption), remove the slot-name parameter and the swap step. The functions-action will deploy directly to production.
Why two jobs instead of one
The split between build and deploy exists for two reasons.
First, the artifact produced by build is reusable. If you add a staging environment later, the deploy job can run twice against the same artifact without rebuilding. Build once, deploy to as many environments as you need.
Second, the id-token: write permission required for OIDC authentication (covered in the next section) is scoped to the deploy job only. If you set it at the workflow level, every job gets that elevated permission. Keeping it on the deploy job limits the blast radius if something goes wrong.
The build job
actions/checkout@v4 pulls your code. actions/setup-dotnet@v4 installs the SDK, and the cache: true option tells it to cache the NuGet package cache between runs.
That cache only works if your project has a lock file. Add this to your .csproj:
<RestorePackagesWithLockFile>true</RestorePackagesWithLockFile>
Then commit the generated packages.lock.json. Without it, cache: true has nothing to hash (so every run misses the cache), and --locked-mode silently regenerates a new lock file instead of validating against a committed one. With both in place, clean builds skip the network entirely for packages that haven’t changed.
The publish step is where .NET 10 requires extra care:
dotnet publish src/MyFunctionApp
  --configuration Release
  --output ./output
  --runtime linux-x64
  --self-contained true
--self-contained true is required for .NET 10. The Azure Functions v4 host runs on .NET 8. If you publish a framework-dependent app targeting .NET 10, the host cannot find the .NET 10 runtime and the deployment fails with exit code 150 (0x96). A self-contained publish bundles the runtime with your app, so the host’s .NET version becomes irrelevant.
actions/upload-artifact@v4 takes the ./output folder and makes it available to downstream jobs. The name value (function-app) is how the deploy job will refer to it.
The deploy job
needs: build means this job waits for the build to succeed before starting. environment: production ties the job to a GitHub environment, which lets you add required reviewers or protection rules before any deployment proceeds.
actions/download-artifact@v4 retrieves the artifact by the same name used during upload and places it in ./output.
azure/login@v2 handles authentication using OIDC; the specifics of how to configure this are in the next section. This step must come before functions-action, and the three secrets (AZURE_CLIENT_ID, AZURE_TENANT_ID, AZURE_SUBSCRIPTION_ID) must be set in your repository or environment settings.
Azure/functions-action@v1 does the actual deployment. Two parameters are required: app-name (the name of your Function App in Azure) and package (the path to your artifact). An optional slot-name parameter targets a deployment slot if you are using them.
The deployment method the action uses depends on your hosting plan. Flex Consumption plans use One Deploy; all other plans use Zip Deploy. The action picks this automatically based on your app’s plan type, so you do not need to configure it explicitly.
OIDC authentication (no stored secrets)
The workflow above uses three secrets: AZURE_CLIENT_ID, AZURE_TENANT_ID, and AZURE_SUBSCRIPTION_ID. None of them are actual credentials. That’s the point of OIDC.
Why not publish profiles or service principal secrets?
Publish profiles are XML files containing deployment credentials baked into the Function App. They work, but they create problems at scale: they can’t be scoped to a branch or environment, they don’t expire on a schedule, and if one leaks, anyone with the file can deploy to your app until you manually reset it.
Service principal secrets are better (they support expiration and RBAC scoping), but you still have a secret stored in GitHub that needs rotating every 6-24 months. Miss a rotation and your pipeline breaks silently on the next deploy.
OIDC eliminates stored credentials entirely. GitHub mints a short-lived token for each workflow run, Azure validates that token against a federated credential you configure once, and nothing secret ever sits in your repository settings.
How it works
- Your workflow requests an OIDC token from GitHub’s token service
- The
azure/login action sends that token to Microsoft Entra ID
- Entra validates the token’s issuer (
token.actions.githubusercontent.com), audience, and subject claim (which encodes the repo, branch, and environment)
- If the claims match your federated credential configuration, Entra issues an Azure access token
- The access token is used for the deployment, then expires
The subject claim is what makes this granular. You can restrict a credential to only work from a specific environment (repo:your-org/your-repo:environment:production), a specific branch, or even pull requests. A token minted from a feature branch won’t match a credential scoped to the production environment.
Setup steps
1. Create an Entra app registration with a service principal:
az ad app create --display-name "github-deploy-my-func-app"
az ad sp create --id <APP_ID>
2. Assign the Website Contributor role scoped to the resource group containing your Function App:
az role assignment create
  --assignee <APP_ID>
  --role "Website Contributor"
  --scope /subscriptions/<SUB_ID>/resourceGroups/<RG_NAME>
Website Contributor is enough for deploying code. Contributor works too but grants more access than the pipeline needs.
3. Configure a federated identity credential:
{
  "name": "github-actions-production",
  "issuer": "https://token.actions.githubusercontent.com",
  "subject": "repo:your-org/your-repo:environment:production",
  "audiences": ["api://AzureADTokenExchange"]
}
az ad app federated-credential create
  --id <APP_ID>
  --parameters @credential.json
The subject field must match exactly. If your deploy job uses environment: production, the subject must end with :environment:production. If you deploy from a branch without an environment, use :ref:refs/heads/main instead.
4. Store the IDs as GitHub environment secrets:
Go to your repository Settings > Environments > production > Environment secrets, and add:
-
AZURE_CLIENT_ID: the Application (client) ID from your app registration
-
AZURE_TENANT_ID: your Entra tenant ID
-
AZURE_SUBSCRIPTION_ID: the subscription containing your Function App
These are identifiers, not credentials. Even if someone reads them, they can’t authenticate without a valid OIDC token from your specific repository and environment.
Workflow permissions
The deploy job needs id-token: write to mint the OIDC token:
deploy:
  permissions:
    id-token: write
    contents: read
Set this on the deploy job only, not at the workflow level. The build job doesn’t need token-minting permissions.
One gotcha
The Azure/functions-action supports two authentication methods: publish-profile and the azure/login action. They are mutually exclusive. If you pass a publish-profile parameter while also using azure/login, the action uses the publish profile and ignores your OIDC session. Remove the publish-profile parameter entirely when switching to OIDC.
Deployment slots and zero-downtime releases
Deploying directly to production means every release has a moment where either the old code or the new code is partially running. Deployment slots give you a staging URL to validate before any production traffic sees the new version, and an instant rollback if something goes wrong.
What each plan supports

If you’re on Flex Consumption, skip to the rolling updates section below.
The blue-green pattern
Deploy to a staging slot, verify it works, then swap staging into production.
-
Deploy to staging: your CI/CD pipeline targets the
staging slot instead of production
-
Validate: hit the staging URL (
your-func-app-staging.azurewebsites.net) with smoke tests or manual checks
-
Swap: Azure switches the routing so staging serves production traffic
-
Rollback if needed: swap again to revert (the old production code is now in the staging slot)
The swap itself takes seconds. Your users see either the old version or the new version, never a half-deployed state.
What swaps and what stays
This trips people up. During a swap, code and most settings travel together from staging to production. But some things are pinned to the slot:
Travels with code (gets swapped): general app settings (unless marked sticky), connection strings (unless marked sticky), handler mappings, public certificates.
Stays with the slot: publishing endpoints, custom domains, TLS/SSL certificates, scale settings, IP restrictions, Always On, FUNCTIONS_EXTENSION_VERSION (sticky by default).
Sticky settings that cause problems
Two settings deserve special attention:
FUNCTIONS_EXTENSION_VERSION is sticky by default. If your staging slot runs ~4 and production also runs ~4, this is invisible. But if you ever need to change the version, the stickiness means the setting won’t swap with the code. To make it travel with the swap, set WEBSITE_OVERRIDE_STICKY_EXTENSION_VERSIONS=0 on all slots.
WEBSITE_CONTENTSHARE is auto-generated per slot and should never be set manually. Each slot needs its own content share to avoid file locking conflicts. If you see deployment failures mentioning “cannot access file,” check whether slots are sharing this value.
Deploy-to-slot and swap in GitHub Actions
Add slot-name to the deploy step, then swap using the Azure CLI:
- uses: Azure/functions-action@v1
  with:
    app-name: 'my-func-app'
    slot-name: staging
    package: ./output

- name: Swap staging to production
  uses: azure/cli@v2
  with:
    inlineScript: |
      az functionapp deployment slot swap
        --name my-func-app
        --resource-group my-rg
        --slot staging
        --target-slot production
Swap gotchas
Watch for these:
-
Running functions are terminated during a swap. There is no graceful drain. If you have long-running executions, they will be killed. For timer or queue triggers, the runtime will pick up incomplete work after the swap, but HTTP requests in flight will fail.
-
Warm-up matters. After a swap, the new production instances need to initialize. Set
WEBSITE_SWAP_WARMUP_PING_PATH to an endpoint (like a health check) that forces initialization before traffic arrives.
-
Keep app names under 32 characters. Longer names can cause host ID collisions between slots, leading to unexpected behavior.
Flex Consumption alternative: rolling updates
Flex Consumption doesn’t support slots, but it offers rolling updates as an alternative. With siteUpdateStrategy.type set to RollingUpdate, Azure replaces instances in batches rather than all at once, giving in-progress executions a 60-minute grace period to complete.
The trade-off: there’s no separate staging URL for validation, no way to split traffic between versions, and rollback means redeploying the previous version rather than an instant swap.
Environment configuration in pipelines
A deployment pipeline needs to put the right configuration in the right environment without leaking secrets into workflow files. GitHub Environments, the secrets hierarchy, and Key Vault references each handle a piece of this.
GitHub Environments
Environments are configured under your repository’s Settings > Environments. Each environment can have:
-
Required reviewers (up to 6 people who must approve before the deploy job runs)
-
Wait timers (a delay before deployment proceeds, useful for change windows)
-
Deployment branches (restrict which branches can target this environment)
In the workflow, environment: production on a job ties it to that environment’s rules. The job will pause and wait for approval if reviewers are configured.
Secrets hierarchy
GitHub secrets exist at three levels:

When the same secret name exists at multiple levels, environment wins over repository, which wins over organization. This means you can set AZURE_CLIENT_ID at the environment level with different values for development, staging, and production, each pointing to a different service principal scoped to its own resource group.
Setting app configuration during deployment
Your Function App needs configuration values beyond what’s in the code. The most direct approach is the Azure CLI:
- name: Configure app settings
  uses: azure/cli@v2
  with:
    inlineScript: |
      az functionapp config appsettings set
        --name ${{ vars.FUNCTION_APP_NAME }}
        --resource-group ${{ vars.RESOURCE_GROUP }}
        --settings
          "ServiceBus__Connection=${{ secrets.SERVICEBUS_CONNECTION }}"
          "FeatureFlags__NewCheckout=true"
Use vars (GitHub Variables) for non-sensitive configuration and secrets for anything you wouldn’t put in a log file.
One warning if you manage settings through Bicep or ARM templates instead: the ARM API replaces all app settings on each deployment. If your template omits a setting that exists on the app, that setting gets deleted. The CLI’s appsettings set command merges instead, which is safer for incremental updates.
Multi-environment workflow
The build-once-deploy-many pattern chains environments with approval gates:
jobs:
  build:
    runs-on: ubuntu-latest
    # ... build steps from earlier ...

  deploy-dev:
    needs: build
    environment: development
    runs-on: ubuntu-latest
    steps:
      # download artifact, azure/login, functions-action
      # (same structure, different secrets per environment)

  deploy-staging:
    needs: deploy-dev
    environment: staging
    runs-on: ubuntu-latest
    steps:
      # deploy to staging slot, run smoke tests

  deploy-production:
    needs: deploy-staging
    environment: production  # approval gate triggers here
    runs-on: ubuntu-latest
    steps:
      # swap staging to production
The same artifact flows through all three environments. The only things that change are the secrets (different AZURE_CLIENT_ID per environment, each scoped to its own resource group) and the deployment target.
Key Vault integration
This ties back to Part 6 (Configuration Done Right). Instead of passing secret values through your pipeline, store them in Key Vault and reference them in app settings:
ServiceBus__Connection=@Microsoft.KeyVault(VaultName=my-kv;SecretName=servicebus-conn)
Your pipeline sets the reference, not the secret value. The Function App’s managed identity resolves the actual value at runtime using the Key Vault Secrets User role. The pipeline never sees the secret, and rotating it in Key Vault takes effect without redeployment.
If you use deployment slots, mark Key Vault references as slot settings when different environments need different secrets (e.g., staging points to a staging Key Vault, production to a production Key Vault).
What goes where

Closing
Eight articles, one function app, and a pipeline that deploys itself. If something in your own setup doesn’t match what’s here, the series navigation links every piece: from the first HTTP trigger through testing to this deployment workflow.
Do you deploy straight to production or use a staging slot? What made you choose one over the other?
Azure Functions for .NET Developers: Series



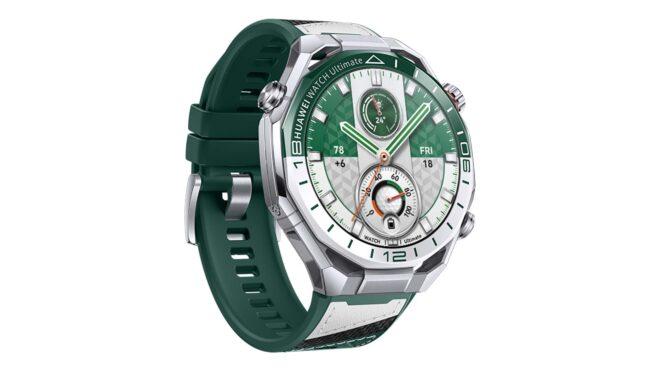
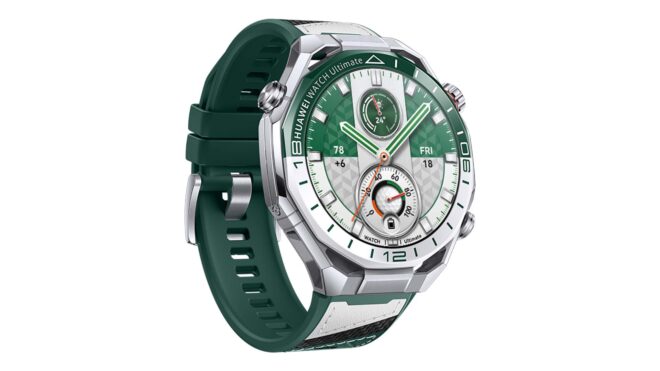 Gelişmiş özelliklere sahip akıllı saat modeli Huawei Watch Ultimate 2 için hazırlanan “e-SIM” versiyonu da Türkiye’de resmi olarak satışa sunuldu. Bluetooth versiyonu 40 bin TL, Bluetooth + e-SİM versiyonu ise 64 bin TL olan saat için Huawei Türkiye şunları aktardı: “Ultimate 2 eSIM versiyonu, akıllı saat endüstrisindeki en büyük batarya sorunlarından birini çözüyor. Cihaz, sektörde ilk kez “Pil Tasarrufu Modu”ndayken bile eSIM aramalarını destekliyor. Yapay zeka (AI) destekli gürültü engelleme teknolojisi ve rüzgar hızı direncine sahip mikrofonu sayesinde, kullanıcılar fırtınalı bir dağ zirvesinde veya dalgalı bir denizde telefonlarına ihtiyaç duymadan kristal netliğinde görüşmeler yapabiliyor. Ultimate 2, sektör standardı olan 10ATM’yi (100 metre) aşarak 20ATM ve 150 metre dalış kapasitesi sunuyor. Rakiplerinden farklı olarak, hava tankına takılan ek bir sensöre veya aksesuara ihtiyaç duymadan, doğrudan saat üzerinden çalışan Sonar Tabanlı Sualtı İletişimi ile geliyor. Dalgıçlar, 30 metreye kadar olan mesafelerde dalış arkadaşlarına sessizce önceden ayarlanmış mesajlar gönderebiliyor ve acil durumlarda 60 […]


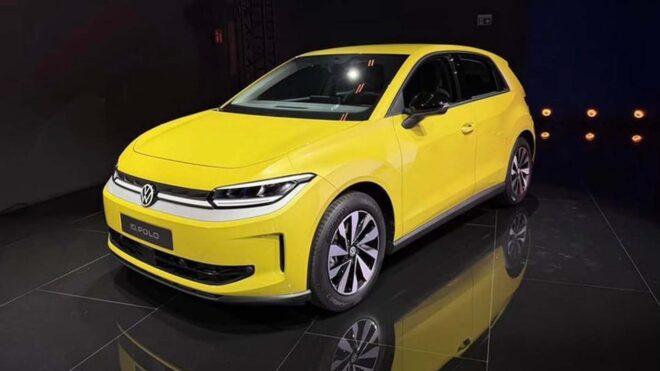
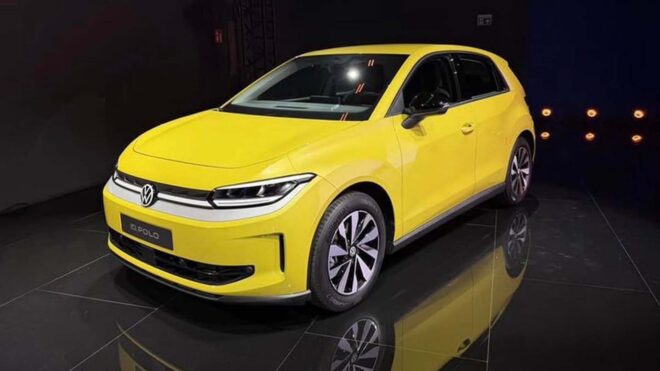 Tamamen elektrikli Volkswagen ID. Polo ve ID. Polo GTI için yeni fotoğraflar sızdırıldı. Araçların çok da sürpriz olmayan tasarımlarını net olarak gözler önüne seren fotoğraflarda en çok ID. Polo GTI dikkat çekiyor; sportif elektriklinin önümüzdeki yıl 223 beygir güçle yollara çıkarılacağı aktarılıyor. Önden çekişli olarak tasarlanan modelin 52 kWh NMC batarya üzerine kurulacağı ve 450 km civarında menzil sunacağı belirtiliyor. 130 kW DC şarj desteğiyle yolda bulunan araçta, bir GTI olarak daha sportif jantlar ve tamponlara yer veriliyor. Bu yıl yollara çıkarılacak standart ID. Polo ise 114 beygir, 133 beygir ve 208 beygir güç sunan üç farklı versiyona sahip olacak. 37 kWh ve 52 kWh batarya paketleriyle donatılacak elektrikli Polo, en üstte 450 km menzil sunacak. Daha sportif “R-Line” paketinin de hazırlandığı ID. Polo, Türkiye dahil çok sayıda pazarda satışa sunulacak.