LG, 2026 TV serisini duyurdu: Kablosuz OLED, Micro RGB ve dahası
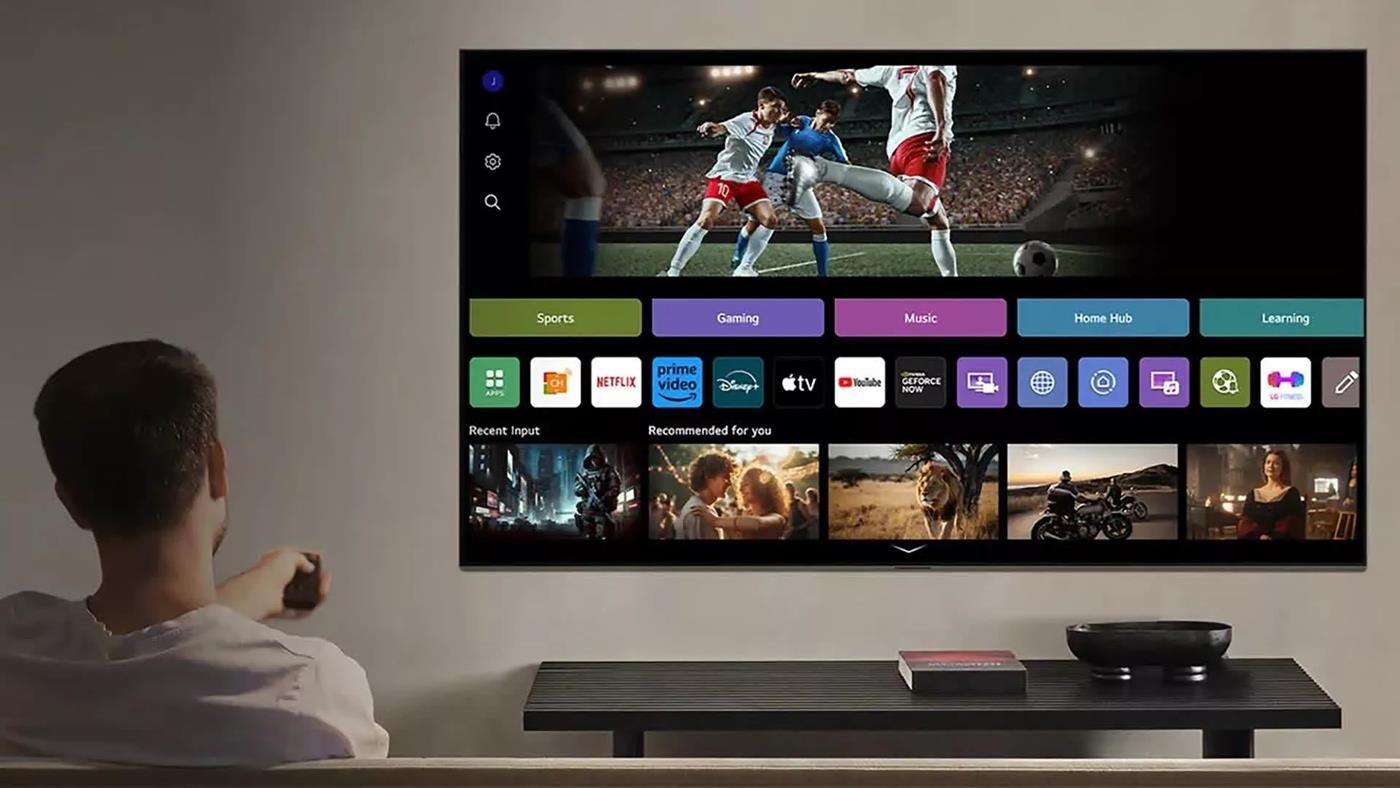
 LG, 2026 TV serisini duyurdu. OLED evo modeller, kablosuz W6 ve yeni Micro RGB evo serisi, parlaklık ve yapay zekâ tarafında önemli güncellemeler içeriyor.
 LG, 2026 TV serisini duyurdu. OLED evo modeller, kablosuz W6 ve yeni Micro RGB evo serisi, parlaklık ve yapay zekâ tarafında önemli güncellemeler içeriyor.
 Apple, 18 yıl sonra kule tipi bilgisayarı Mac Pro’nun üretimini resmen durdurdu. Apple Mac Pro, 2023 yılında M2 Ultra çipiyle son güncellemesini aldı.
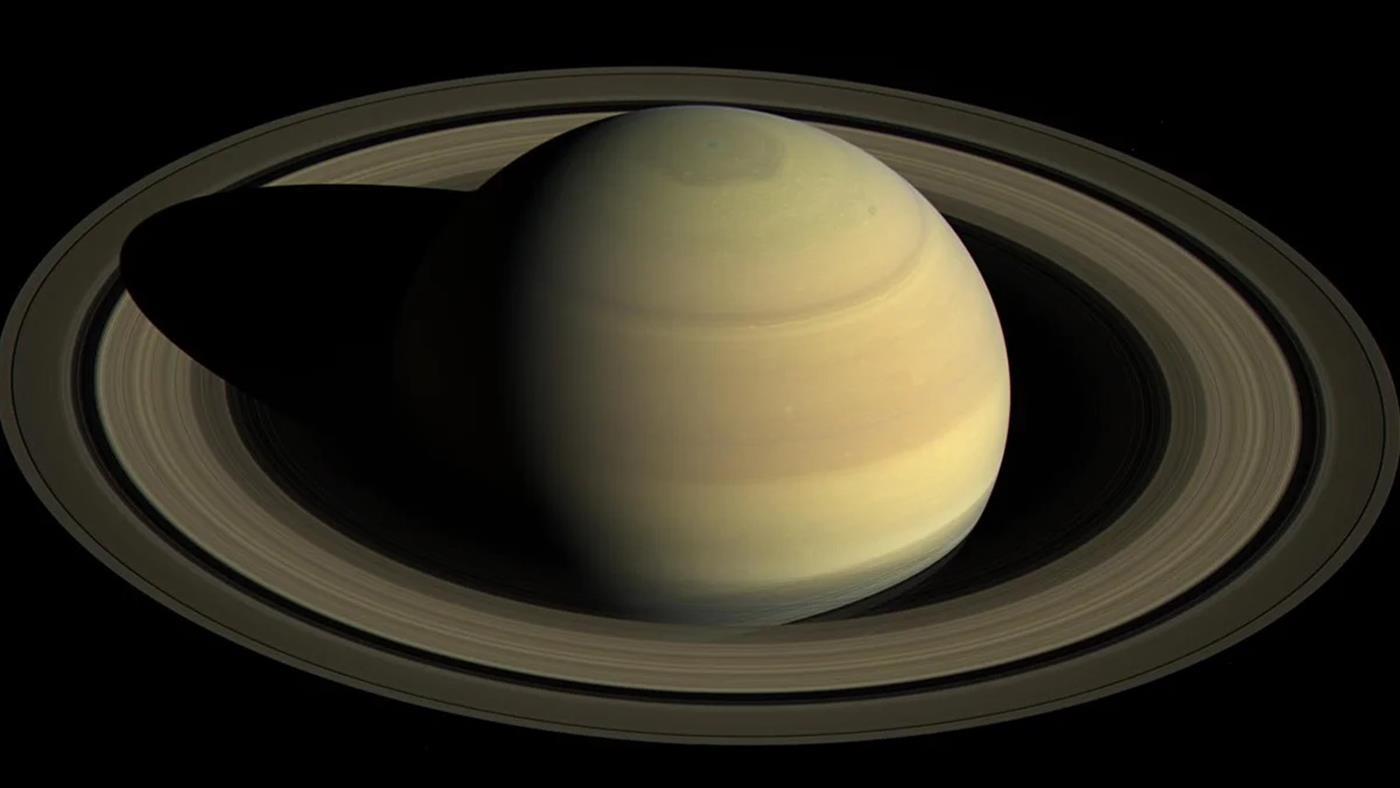
 NASA’nın Webb ve Hubble teleskopları, Satürn’ün atmosferini ve halkalarını katman katman gözler önüne serdi. Kutup ışıkları, fırtınalar ve altıgen jet akımı detaylı şekilde görüntülendi.
 Google, Android 17 Beta 3 sürümünü yayınladı. Platform kararlılığına ulaşan yeni sürüm, Pixel cihazlara OTA ile gelirken RAW14 desteği ve yeni arayüz iyileştirmeleri sunuyor.
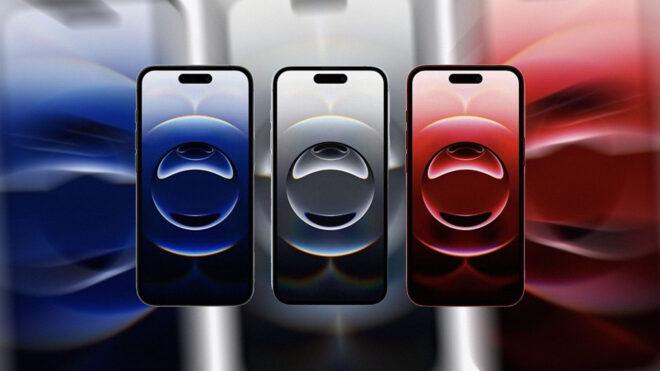
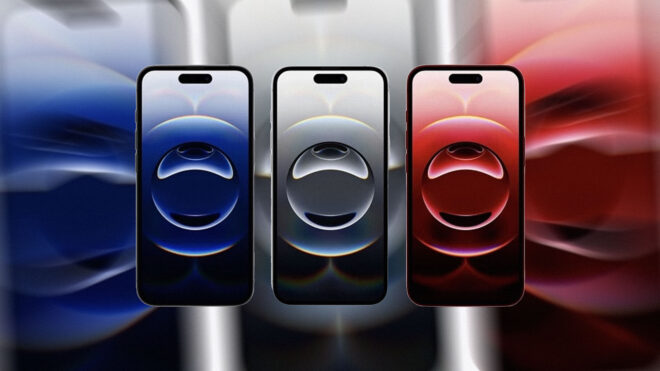 Apple, Bloomberg’in son iddiasına göre “iPhone Product Design” takımındaki çalışanların diğer şirketler tarafından kapılmasını önlemek amacıyla 400 bin dolara varan ikramiye ödemeleri gerçekleştirdi. Teknoloji devi son dönemde çok sayıda tecrübeli mühendisini ve tasarımcısını, çok büyük ödemeler gerçekleştiren rakip şirketlere kaptırdı. Bu şirketler arasında ilk donanım ürünü tasarlayan OpenAI da yer alıyor. Efsane Apple tasarımcısı Jony Ive’ın desteğiyle hayat bulacak yapay zeka temelli bu ürünün 2027’de pazara sunulması bekleniyor.
Apple, iddiaya göre iPhone’lar üzerinde çalışan ekiplere büyük ikramiye ödemeleri gerçekleştirdi yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
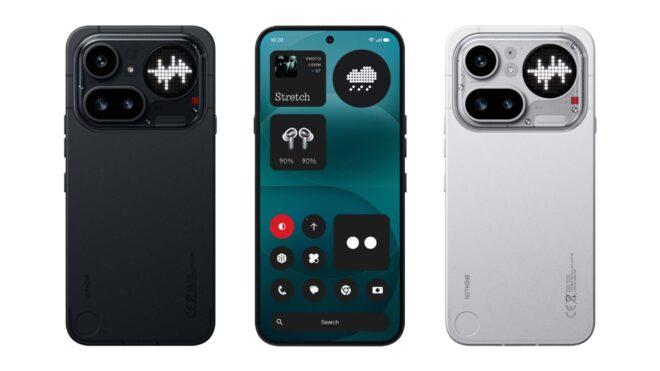
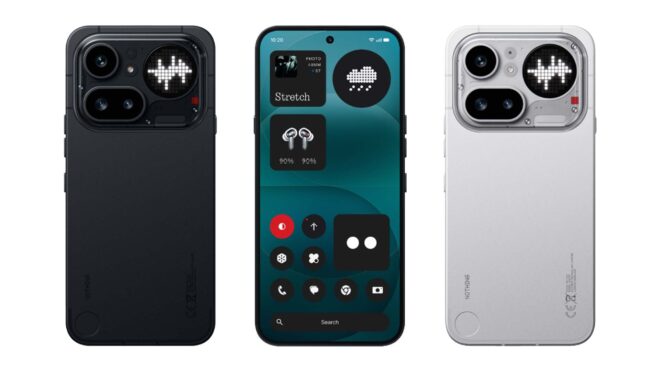 Nothing Phone (4a) ve Phone (4a) Pro modelleri bugün itibarıyla Türkiye’de resmi olarak satışa sunuldu. Şirket, altta yer alan Phone (4a) için lansmana özel olarak 29.999 TL, Phone (4a) Pro içinse lansmana özel olarak 36.999 TL başlangıç fiyatı açıkladı. Arka tasarımlarıyla dikkat çeken telefonlardan Phone (4a) Pro, metal çerçeve üzerine kuruluyor ve IP65 sertifikasıyla geliyor. Phone (4a) modelinin arkasına 63 mini LED’den oluşan 7 parçalı bir “Glyph Bar” konumlandıran Nothing, Phone (4a) Pro’da ise Glyph Matrix isimli, 137 farklı mini LED’den oluşan nokta/piksel bazlı yuvarlak bir ekrana yer veriyor. Phone (4a), teknik olarak baktığımız zaman 6,78 inç “30–120 Hz” AMOLED ekranla donatılmış ve 32 megapiksellik selfie kamerası taşıyor. Gücünü Snapdragon 7 Gen 4 işlemciden alan telefonda 50W şarj destekli 5.400 mAh’lık batarya kullanılıyor. Telefonun arkasında ise 50 megapiksel geniş açı (Samsung GN9), 50 megapiksel 3,5x periskop telefoto (Samsung JN5 / 70x’e kadar dijital/hibrit zoom) ve 8 megapiksel ultra geniş açı […]
Nothing Phone (4a) ve Phone (4a) Pro, Türkiye’de satışa sunuldu yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.
We shipped MagiC v0.4 today. Two things worth talking about: embedded server mode and the benchmark suite we built to validate our performance claims.
Background: What is MagiC?
MagiC is an open-source framework for managing fleets of AI workers. Think Kubernetes for AI agents — it doesn’t build agents, it manages any agents built with any framework (CrewAI, LangChain, custom bots) through an open HTTP protocol.
         You (CEO)
          |
     MagiC Server  ←— Go, 15MB binary
    /    |    |
ContentBot  SEOBot  LeadBot  CodeBot
(Python)   (Node)  (Python)  (Go)
The core is Go. Workers are anything that speaks HTTP.
What’s new in v0.4
1. Embedded server mode
Before v0.4, using MagiC from Python required you to separately install and run the Go server. Now you can do this:
from magic_ai_sdk import MagiC

with MagiC() as client:
    # Server is running. client is a MagiCClient.
    client.submit_task({"type": "summarize", "input": {"url": "..."}})
# Server stops automatically.
MagiC() downloads the correct binary for your platform on first use (Linux/macOS, amd64/arm64), caches it at ~/.magic/bin/, and starts it in the background. Second run is instant — no download.
This is how it works under the hood:
class MagiC:
    def __enter__(self) -> MagiCClient:
        binary = _get_binary(self._version)   # download if not cached
        self._proc = subprocess.Popen(
            [str(binary), "serve"],
            env={"MAGIC_PORT": str(self._port), **os.environ},
        )
        self._wait_ready()  # polls /health until 200 OK
        return MagiCClient(base_url=f"http://localhost:{self._port}")

    def __exit__(self, *_):
        self._proc.terminate()
The binary is pulled from GitHub Releases, which the release CI builds automatically for 4 targets on every v* tag:
- run: |
    GOOS=linux  GOARCH=amd64 go build -ldflags="-s -w" -o dist/magic-linux-amd64  ./cmd/magic
    GOOS=linux  GOARCH=arm64 go build -ldflags="-s -w" -o dist/magic-linux-arm64  ./cmd/magic
    GOOS=darwin GOARCH=amd64 go build -ldflags="-s -w" -o dist/magic-darwin-amd64 ./cmd/magic
    GOOS=darwin GOARCH=arm64 go build -ldflags="-s -w" -o dist/magic-darwin-arm64 ./cmd/magic
Result: pip install magic-ai-sdk is all a Python developer needs. No Go toolchain required.
2. Benchmark suite
A frequent question is: “Why Go? Won’t Python be fine?” We now have actual numbers.
The benchmark suite lives in core/benchmarks/ — 13 benchmarks covering routing, registration, heartbeat, and the event bus. Run them yourself:
git clone https://github.com/kienbui1995/magic
cd magic/core
go test -bench=. -benchtime=5s -benchmem ./benchmarks/...
Results on an i7-12700 (20 logical cores):
| Benchmark | Latency | Throughput |
|---|---|---|
| Route task — 10 workers | 2.8 µs | 920K tasks/s |
| Route task — 100 workers | 20 µs | 50K tasks/s |
| Route task — 1000 workers | 240 µs | 4K tasks/s |
| Worker registration | 1.9 µs | 1.3M/s |
| Heartbeat — 100 workers | 84 µs | — |
| Heartbeat — 1000 workers | 1.0 ms | — |
| Event bus (10 subscribers) | 163 ns | 12.5M/s |
| Event bus (parallel) | 77 ns | 26M/s |
A few things worth noting:
Routing scales O(n) with worker count, which is expected — we scan all workers to filter by capability. With 1000 workers the overhead is 240µs. An LLM call is 1–30 seconds. The orchestrator is never the bottleneck.
Heartbeat at 1000 workers costs ~1ms per check cycle. In practice, heartbeats happen every 30 seconds per worker, so the server processes ~33 heartbeats/second at 1000 workers. Completely trivial.
The event bus at 26M events/second means no async communication between modules will ever be a bottleneck.
Why these numbers matter for fleet management
Every AI agent framework I’ve seen (AutoGen, CrewAI, Agno, LangGraph) runs agents as Python objects in a single process. There’s no heartbeat because there’s no persistent worker registry. There’s no routing because there’s no fleet.
Agno’s “529x faster” benchmark measures how quickly Python objects instantiate. That’s a valid metric for their architecture. MagiC measures something different: how many concurrent agents can the orchestrator manage, and how fast can it route tasks to them.
Python’s GIL means routing decisions for N concurrent agents share one thread. In Go, each heartbeat runs in its own goroutine (~2KB RAM, true parallelism). The numbers reflect that.
What’s coming in v0.5
We’re implementing zero-trust worker authentication:
mct_<256-bit token> credential (not a shared API key)No competitor has this at the framework level. AutoGen agents have no identity. CrewAI’s shared_memory=True default has caused PII leaks between sessions. LangGraph gets closest with interrupt primitives but still no agent-level auth.
We’ll publish the implementation and a write-up when it ships.
Try it
pip install magic-ai-sdk
from magic_ai_sdk import MagiC, Worker, capability

# Define a worker
class SummarizerBot(Worker):
    @capability(name="summarize")
    def summarize(self, task):
        # your LLM call here
        return {"summary": "..."}

# Start server + register worker
with MagiC() as client:
    bot = SummarizerBot(name="SummarizerBot", endpoint="http://localhost:9001")
    bot.start(magic_url=client.base_url)

    result = client.submit_task({
        "type": "summarize",
        "routing": {"required_capabilities": ["summarize"]}
    })
    print(result)
GitHub: kienbui1995/magic
Feedback welcome — especially on the benchmark methodology. We want to publish fair comparisons, not marketing numbers.
Quick Comparison
| gstack | Superpowers | AEGIS | |
|---|---|---|---|
| Creator | Garry Tan (YC President) | Jesse Vincent (obra) | AEGIS Contributors |
| GitHub Stars | ~23K+ (7 days) | ~40K+ | New (PyPI: aegis-gov) |
| Philosophy | Startup sprint workflow | Engineering methodology | Constitutional governance |
| Approach | 15 opinionated skills as roles | TDD + debugging + brainstorming framework | Boardroom meetings + rule engine + red team |
| Governance | None (trust the workflow) | Methodology-enforced discipline | Explicit rules, verdicts, audit trails |
| Agent Count | 6 virtual roles | Subagent-driven (dynamic) | 9 default + 8 specialists (17 council members) |
| Scalability | Solo developer / small team | Solo to small team | Solo to enterprise (140+ agents in full version) |
| Learning Curve | Low — copy skills, run commands | Medium — understand methodology first | Medium — understand governance model |
| LLM Support | Claude Code (+ Codex, Gemini CLI) | Claude Code primary | Anthropic, OpenAI, Ollama (any LLM) |
| License | MIT | MIT | Apache 2.0 |
gstack: The Startup Sprint
What it is: Garry Tan’s personal Claude Code setup, open-sourced. 15 opinionated workflow skills that turn Claude Code into a virtual engineering team — CEO, Designer, Eng Manager, Release Manager, Doc Engineer, QA.
The philosophy: AI agents work best when they follow the same sprint cadence that works for human teams. Think, Plan, Build, Review, Test, Ship, Reflect.
Strengths
Immediate productivity. Copy the skills, run the commands, ship code. gstack hit 23K stars in a week because it delivers instant value. No configuration ceremony — just /office-hours to think, /plan-ceo-review to plan, /ship to deploy.
Real-world provenance. This is how the president of Y Combinator actually builds software. It’s not theoretical — it’s battle-tested on real products.
Browser-first architecture. gstack runs a persistent Chromium daemon with sub-second latency. This is genuinely hard engineering — the browser doesn’t cold-start between commands, so QA testing and visual reviews are fast and stateful.
Cross-agent compatibility. Through the SKILL.md standard, gstack works with Claude Code, Codex, Gemini CLI, and Cursor.
Limitations
No governance layer. There’s no mechanism to prevent an agent from taking a harmful action. The workflow assumes good outcomes follow good process, which is true until it isn’t.
Copy-paste culture risk. 23K stars in a week means thousands of developers are running one person’s opinionated workflow without modification. gstack is Garry Tan’s brain — your team might need a different brain.
Solo-focused. The skills are designed for a single developer working with AI. There’s no multi-agent coordination, no conflict resolution, no audit trail for team accountability.
Superpowers: The Methodology
What it is: An agentic skills framework and software development methodology. More installs than Playwright on the Claude Code marketplace. 40K+ stars.
The philosophy: The bottleneck in AI-assisted development isn’t model capability — it’s methodology. If you teach agents disciplined engineering practices, they earn your trust.
Strengths
Trust through discipline. Superpowers enforces red-green-refactor TDD cycles where tests must fail before implementation. It requires root cause investigation before any fix. It runs Socratic brainstorming sessions that refine requirements before coding begins. This is genuine engineering methodology, not vibes.
Subagent-driven development. Once you approve the plan, Superpowers launches subagents to work through each task, inspecting and reviewing their work before continuing. The implementation plan is deliberately written for “an enthusiastic junior engineer with poor taste, no judgement, and an aversion to testing” — meaning the instructions are unambiguous enough for any agent to follow.
Compound learning. Each development cycle documents learnings for future AI agent consumption. 80% of developer time goes to planning and review, systematically creating a self-improving system.
Strong community. 40K+ stars and active development mean continuous improvement, community skills, and broad compatibility.
Limitations
Single-user scope. Like gstack, Superpowers is designed for a developer working with their AI agent. It doesn’t address multi-agent governance, cross-team coordination, or organizational-scale decision making.
No enforcement mechanism. The methodology is advisory — agents follow it because the prompts tell them to. There’s no rule engine that can BLOCK an action, no HALT that stops all processes, no human escalation gate that requires approval.
Methodology, not governance. Superpowers ensures agents build well. It doesn’t ensure they should build at all. There’s no red team challenging whether the decision itself was correct.
AEGIS: The Constitution
What it is: A governance-first framework where AI agents debate decisions in structured boardroom meetings, face mandatory red team review, and operate under constitutional rules with enforceable verdicts.
The philosophy: Every other multi-agent framework helps AI agents do things. AEGIS makes sure they should.
Strengths
Enforceable governance. AEGIS has a 5-verdict rule engine (PASS, FLAG, BLOCK, ESCALATE_TO_HUMAN, HALT) that prevents actions, not just advises against them. Self-review is blocked. Low-confidence decisions are flagged. Production deployments without review are escalated to humans.
from aegis_gov import RuleEngine

engine = RuleEngine()
# Production deploy without review? -> ESCALATE_TO_HUMAN
engine.evaluate("DevOps", "deploy", {
    "environment": "production",
    "tests_passed": True,
    "review_approved": False,
})
Mandatory red team. Every decision faces a DevilsAdvocate (challenges assumptions, demands evidence) and a Skeptic (explores alternatives, runs pre-mortem analysis). The red team cannot be disabled in the default configuration.
Structured decision-making. 17 AI agents with distinct roles debate every decision across 6 phases: CEO Opening, Executive Council (7 C-level perspectives), Advisory Input (8 specialists), Critical Review (red team), Open Debate, and CEO Synthesis with vote tally and confidence score.
Compliance-ready. The audit trail, decision categorization, and human escalation gates map directly to EU AI Act, NIST AI RMF, and ISO 42001 requirements.
LLM-agnostic. Works with Anthropic, OpenAI, or any OpenAI-compatible API (including local models via Ollama).
Limitations
Overhead for small projects. If you’re a solo developer building a side project, a 17-agent boardroom meeting is overkill. gstack or Superpowers will get you shipping faster.
Newer project. AEGIS doesn’t have 40K stars (yet). The community is smaller, and the ecosystem is younger.
Governance adds latency. A full boardroom meeting with red team review takes time. For rapid prototyping, you want speed. For production decisions with real consequences, you want governance.
When to Use Which
| Scenario | Best Choice | Why |
|---|---|---|
| Solo developer, ship fast | gstack | Instant productivity, proven workflow |
| Engineering team, build trust in AI | Superpowers | TDD methodology, compound learning |
| Multi-agent systems, need accountability | AEGIS | Governance, audit trails, enforcement |
| Compliance-sensitive industry | AEGIS | EU AI Act / NIST / ISO alignment |
| Learning AI-assisted development | Superpowers | Best teaching methodology |
| Startup MVP sprint | gstack | Fastest path from idea to deploy |
| Production decisions with real consequences | AEGIS | Red team + rule engine + human escalation |
The Combination Play
These tools are not mutually exclusive. The strongest setup might be:
AEGIS is explicitly designed to be “the governance layer you add on top” of existing frameworks.
Try AEGIS
pip install aegis-gov
aegis convene "Should we mass-email all users about the new feature?" --category TACTICAL
Want the full 140-agent configuration with 148 optimized prompts? The AI Agent Prompts Pack includes production-ready agent definitions, constitutional governance templates, and the complete AEGIS organizational structure.
What’s your approach to AI agent governance? Are you in the “trust the workflow” camp, the “enforce methodology” camp, or the “constitutional governance” camp? Drop a comment below.
You describe how it feels. It draws what it looks like.
There’s a question I’ve been sitting with for a while:
What does a song look like?
Not the album art. Not the waveform. The feeling of it. The way Gymnopédie No.1 feels like fog over cold water. The way Bohemian Rhapsody feels like architecture that shouldn’t work but does.
Spotify tried to answer this with their audio features API — energy, valence, danceability, tempo. Machine-derived floats between 0 and 1. They deprecated it last year.
I think they were solving the wrong problem anyway.
Your ears are the API
Spotify’s audio analysis is about the signal. I’m interested in the experience.
So I built Song Portrait — a tool where you are the data source.
You describe a song across 8 perceptual dimensions:
Move the sliders. The portrait draws itself.
What it draws
Each set of values generates a spiral DNA structure — a pair of intertwining helices whose properties are all derived from what you felt:
The result is different for every song. And every person’s description of the same song.
Two people. Same song. Different portraits.
That’s the part I find most interesting.
If you and I both describe “Black” by Pearl Jam, we might both agree it’s low-energy, very dark, heavy on memory. But you might feel more complexity in the guitar work; I might feel more space in the production. Our portraits will be similar but not identical.
The portrait isn’t a fact. It’s a record of how you heard it.
That feels more honest than a database entry.
Try the presets
I built in six presets to get you started:
| Song | Notable shape |
|---|---|
| Gymnopédie No.1 – Satie | Few strands, wide open, cool, grainy |
| Bohemian Rhapsody – Queen | Max complexity, high energy, maximum turns |
| Mr. Brightside – The Killers | Fast, bright, high memory |
| Africa – Toto | Warm, complex, nostalgic — my personal favorite result |
| Black – Pearl Jam | Dark, slow, spacious, deeply nostalgic |
| Blue (Da Ba Dee) – Eiffel 65 | High energy, fast, cold, clean |
Each portrait is animated — the helix rotates slowly, driven by Tempo Feel. You can download any frame as a PNG.
Why I built this
I’ve been building a series of tools I call “useless but beautiful” — things that don’t help you do anything, but reveal something.
Noise Field makes particle art from invisible forces. Breathing Clock encodes the time into organic forms. Code Scent translates your codebase into landscape.
Song Portrait continues that logic: take something invisible — the subjective experience of music — and give it a visible form.
I don’t know if the portraits are “accurate.” I’m not sure accuracy is the right standard for something that lives in the gap between sound and feeling.
What I do know: when I loaded the Satie preset and saw thin blue-grey spirals drifting in cold space, it felt right.
Free. No account. Runs entirely in your browser.
If you describe a song and like how it looks, I’d genuinely want to see it — reply here or find me @Clavis_Citriac.