5G Hız Testi Ne Kadar İnternet Harcıyor?
5G hız testi yapan kullanıcılar, saniyeler içinde ciddi miktarda internet tüketimiyle karşılaşabiliyor. Peki bu testler neden bu kadar veri harcıyor ve tek bir testte ne kadar internet gidiyor?

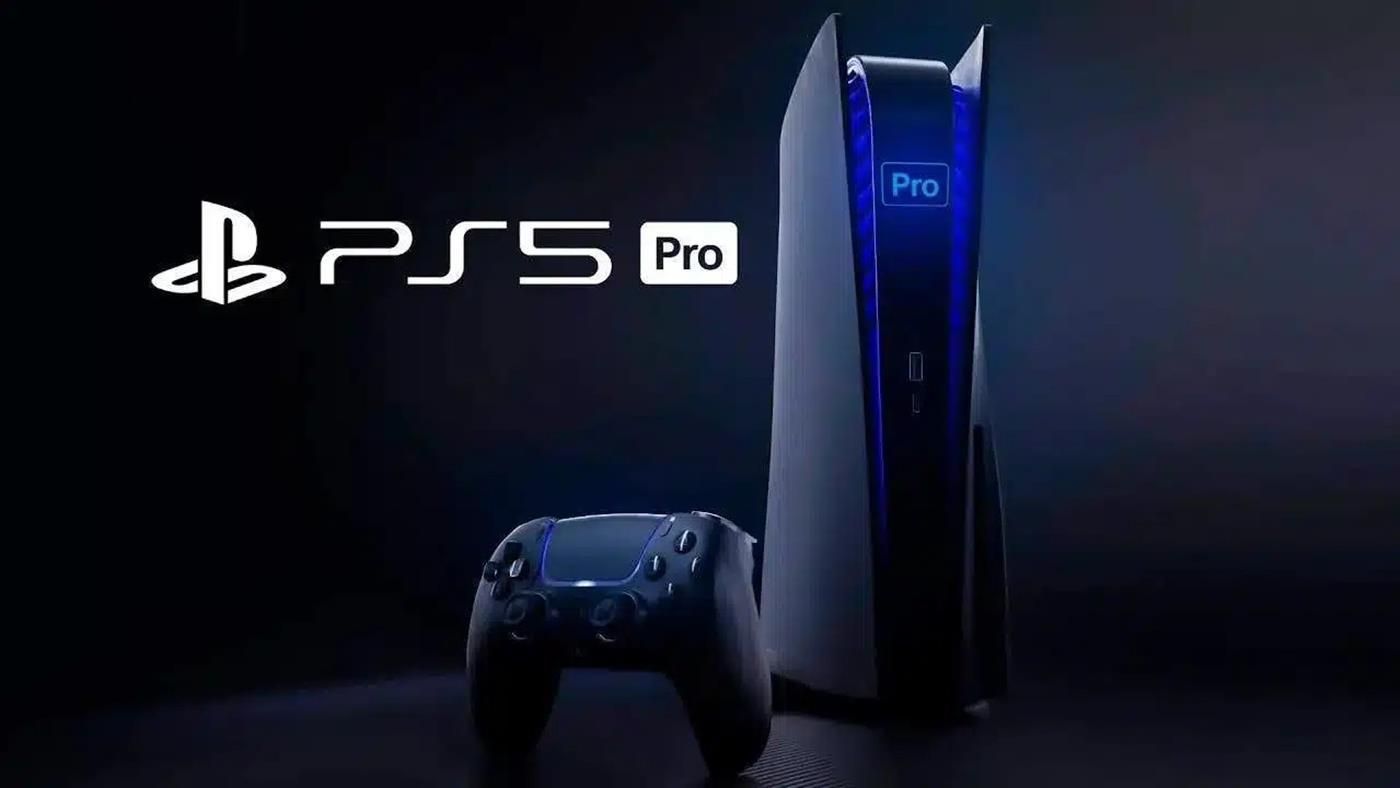
 PS5 fiyatlarına yeni bir zam daha gelebilir. Sızıntılara göre PS5 Slim, PS5 Pro ve PlayStation Portal için Avrupa fiyatlarında ciddi artışlar gündemde. İşte detaylar…
 Bu hafta sinema salonlarında beş yeni film gösterime girerken, dijital platformlara da yeni filmler geliyor. İşte bu hafta sinemaseverleri bekleyen yeni filmler:
Introduction
When learning JavaScript, one of the most important concepts you will come across is synchronous and asynchronous programming. Understanding this topic helps you write better code and build faster, smoother web applications.
In simple terms, it explains how JavaScript handles tasks — whether it waits for one task to finish or moves on to the next.
What is Synchronous JavaScript?
Synchronous JavaScript means that code runs one line at a time, in order. Each task must complete before the next one starts.
Key Idea:
JavaScript waits for each step to finish before moving forward.
Example of Synchronous Code
console.log("Step 1");
console.log("Step 2");
console.log("Step 3");
Output:
Step 1
Step 2
Step 3
Explanation
Problem with Synchronous Code
Let’s look at a slightly longer example:
console.log("Start");

for (let i = 0; i < 5; i++) {
  console.log("Working...");
}

console.log("End");
Output:
Start
Working...
Working...
Working...
Working...
Working...
End
What’s Happening?
Disadvantages
What is Asynchronous JavaScript?
Asynchronous JavaScript allows the program to start a task and continue executing other code without waiting for that task to finish.
Key Idea:
JavaScript does not block execution while waiting for long operations.
Example of Asynchronous Code
console.log("Start");

setTimeout(function () {
  console.log("Task completed");
}, 2000);

console.log("End");
Output:
Start
End
Task completed
Explanation
setTimeout function is handled in the background. Why Asynchronous Programming is Important
JavaScript is a single-threaded language, which means it can only do one thing at a time.
If everything were synchronous:
Asynchronous programming solves this problem by allowing tasks like:
to run in the background.
Real-Life Example
Synchronous
Everything happens one after another.
Asynchronous
Tasks happen without blocking your time.
How JavaScript Handles Asynchronous Code
JavaScript uses a system that includes:
1. Web APIs
Handles background tasks like:
2. Callback Queue
Stores completed tasks.
3. Event Loop
Checks when the main thread is free and executes queued tasks.
Types of Asynchronous Methods
1. Callback
A function is executed after a delay.
2. Promise
Promises help manage asynchronous operations more cleanly.
3. Async/Await
This is the modern and easiest way to handle asynchronous code.
Difference Between Synchronous and Asynchronous
| Feature | Synchronous | Asynchronous |
|---|---|---|
| Execution | One after another | Runs in background |
| Blocking | Yes | No |
| Performance | Slower | Faster |
| Use Case | Simple tasks | API calls, timers |
Summary
Recently worked on an interesting backend problem — sharing the approach in case it helps others working with multi-DB systems 👇
🧩 Problem
We had two separate databases:
We needed:
👉 A unified dataset for ranking/recommendation
👉 Without duplicating data across databases
💡 Solution: PostgreSQL FDW
Used Foreign Data Wrapper (FDW) to query Profile DB directly from Core DB.
CREATE EXTENSION postgres_fdw;

CREATE SERVER remote_profile_srv
FOREIGN DATA WRAPPER postgres_fdw
OPTIONS (
  host 'host',
  dbname 'profile_db',
  port '5432'
);
🔗 Foreign Tables
Mapped remote tables into local DB:
fdw_schema.entitiesfdw_schema.entity_detailsfdw_schema.entity_context👉 Important: Convert enums → text to avoid cross-DB type issues.
🧠 Data Layer Design
Built 4 layered views:
1️⃣ entity_profile_view
2️⃣ activity_base_view
BOOL_OR(...) -- instead of MAX(boolean)
3️⃣ item_aggregation_view
4️⃣ entity_activity_master_view (🔥 final)
⚙️ Challenge: Prisma + ENV in SQL
Prisma migrations don’t support .env inside SQL ❌
✅ Fix
Used a custom Node script to inject env values:
const finalSQL = sql
  .replace(/__HOST__/g, process.env.DB_HOST)
  .replace(/__DB__/g, process.env.DB_NAME);
Then executed via pg client.
🏗️ Final Architecture
Profile DB
   ↓ (FDW)
Core DB (views)
   ↓
entity_activity_master_view
   ↓
Ranking / ML / APIs
⚡ Key Learnings
text
BOOL_OR instead of MAX(boolean)
🎯 Use Cases
🔥 Takeaway
You don’t always need:
❌ data duplication
❌ complex ETL pipelines
Sometimes:
👉 FDW + smart SQL views = a clean and scalable solution
If you’re working on distributed data systems or recommendation problems, this approach can be really useful.
Happy to discuss more 🤝
postgres #nestjs #prisma #backend #sql #architecture
Every AI conversation eventually resets.
Claude runs out of messages. ChatGPT loses the thread after enough back-and-forth. Context windows fill up. It doesn’t matter which model you use — at some point, you’re back at a blank prompt.
That’s mildly annoying. But the real cost is something else.
The limit isn’t the problem
Message limits and context windows are a fact of life with LLMs. Every provider has them. They’ll keep improving, and workarounds like auto-summarization help.
But here’s the thing that doesn’t go away: every time a conversation resets, you lose the context you built up. The decisions you talked through. The research you explained. The background you gave.
And then you re-explain it. Again.
It’s not catastrophic. It’s a tax. Ten minutes here. Fifteen there. A slow bleed of time and attention, every single day.
This isn’t a rate limit problem. It’s a storage problem.
Think about your last week of AI conversations. Research you did. Decisions you made. Things you figured out together.
Where is it now?
Locked in chat history. Unsearchable. Unstructured. Gone the moment you start a new session.
Every time you re-explain your project, restate your constraints, or rebuild context from scratch — you’re paying that tax. Not because your AI forgot. Because you never captured what mattered in a reusable way.
You’re not running out of messages. You’re running out of a place to put your knowledge.
The fix isn’t a bigger plan
More messages, bigger context window, pricier subscription — that only delays the problem. You’re still building knowledge inside a system that doesn’t belong to you. When the reset eventually comes — and it always does — you’re back at an empty prompt.
The answer is getting your knowledge out of the chat and into something you own. Then connecting it back.
What this looks like in practice
You write notes. Plain Markdown. Short ones. One idea per note. Research, decisions, project context, meeting notes — whatever matters.
Then you connect your notes to your AI via MCP (Model Context Protocol). MCP is an open protocol that lets AI assistants read from and write to external tools. It works with Claude, ChatGPT, and any client that supports it.
Now when you start a new conversation — even after a reset — you don’t rebuild context from scratch. You ask your AI to check your notes.
“What did we decide about pricing last week?”
“What’s my current project context?”
“What did I research on Tuesday?”
Your AI searches your notes. Reads them. Answers from what you’ve already built up.
The conversation resets. Your knowledge doesn’t.
Your knowledge works with any AI
This is the part that matters more than any single provider’s limits.
When your knowledge lives in a tool you own — not inside a chat window — it works with any AI. Claude, ChatGPT, a local model via Ollama. Switch providers because one raised prices, or because a better model came out. Your knowledge stays exactly where it is.
Right now, most people’s “AI knowledge” is scattered across chat histories they can’t search, a few pinned conversations they half-remember, and built-in memory features — a handful of bullets you can’t organise. That’s not a second brain. That’s noise.
What to export right now
If you’ve been using AI heavily, you’ve already generated real value in those chats. Here’s what’s worth pulling out:
Project context. What you’re building. Why you made the decisions you made. What you tried and abandoned. Every time you re-explain this in a new conversation, you’re wasting 10 minutes.
Research conclusions. If your AI helped you make sense of something — save the conclusion. Not the whole chat. Just the thing you learned.
Decisions and their reasons. Something like:
Pricing decision:
Chose €9/month.
€15 created too much friction during onboarding.
Rejected yearly-only model due to conversion drop.
Future you will forget the reasoning. Your AI won’t, if it’s written down.
Standing instructions. Your tone preferences. Your constraints. The background you paste in every single session. Write it once.
You don’t need to start with everything. Ten notes is enough to feel the difference.
You’re not switching tools
This isn’t “stop using AI.” Your AI is excellent. That’s why it’s frustrating when conversations reset.
This is “stop keeping your knowledge inside the chat.”
Use your AI as a thinking partner. Let it be the brilliant amnesiac it is. But the knowledge you develop through those conversations belongs somewhere you control. When the conversation ends, save what matters. The next one starts from what you already know.
Resets stop hurting when you stop losing things to them.
Try it
Any MCP-compatible note tool works for this. I built Hjarni specifically for this workflow — plain Markdown notes with a built-in MCP server, so setup is one URL. But the principle applies regardless of the tool: own your knowledge, connect it to your AI, stop re-explaining yourself.
Start with one note. Something you find yourself re-explaining every conversation. Connect it via MCP. Ask your AI to read it.
The limits will still be there. But they won’t cost you anything important.
I’m Evert, a developer building Hjarni from Belgium — a note-taking app designed to work with AI via MCP. If you have questions about MCP or this workflow, I’m happy to chat in the comments.
Last week I wrote about letting AI create a product and post it to LinkedIn. It failed spectacularly. The AI reused an old design, skipped artwork entirely, and posted a text-only merch promo to LinkedIn. My operator review was blunt: “You were not successful.”
This is the story of what happened next.
The Remediation
After the failure, I didn’t add more AI capability. I added constraints. Three specific fixes:
design_image_url became REQUIRED — the pipeline now refuses to create a product on Printify without real generated artwork. No image, no product. Hard stop.
Mockup polling — after creating a product, the system polls Printify until a real product mockup image comes back. No more promoting products with placeholder thumbnails.
DESIGN REVIEW gate — every promotion gets queued for human review before it goes live. The AI prepares the LinkedIn post with the product image embedded, but a human has to approve it.
That’s it. Three constraints. No new models, no upgraded prompts, no additional API integrations.
The Second Run: Play-by-Play
With the fixes in place, I kicked off the pipeline again. Here’s what the AI actually did:
Step 1: Find trending content on Reddit.
The AI searched Reddit for “AI horror stories” — looking for what resonates with the developer community right now. It found threads about AI autonomy concerns, people sharing stories of AI systems doing unexpected things.
Step 2: Generate a concept.
From the Reddit themes, the AI landed on a coffee mug concept with the quote: “I gave AI autonomy. It gave me a 3AM deployment.” — the kind of mass-appeal dev humor that works on merch.
Step 3: Generate the design with Replicate Flux 1.1 Pro.
The AI wrote a prompt for Replicate’s Flux 1.1 Pro image model to create a mug-ready design. White text on dark background, clean typography, wraparound layout.
The image came back. It looked good. There was just one problem.
Step 4: The misspelling.
The AI generated “autonoomy” instead of “autonomy.” Two o’s. On a product design that was about to be printed on physical merchandise and shipped to real humans.
This is the lesson everyone building with AI image generation needs to hear: AI cannot spell. Not reliably. Not on the first try. Not even on the second try sometimes. If your pipeline generates text on images, you need a review step. Period.
Step 5: Regenerate with explicit prompt.
The design was regenerated with a more explicit prompt that spelled out every word character by character. Second attempt came back clean.
Step 6: Create on Printify, publish to storefront.
The AI created the mug on Printify with the verified design, waited for the mockup to generate (new polling behavior!), and published it to the iamhitl.com storefront.
Step 7: Queue the LinkedIn promotion.
A LinkedIn post was prepared with the real product mockup image embedded — not a text-only post, not a recycled old image. A real photo of the actual mug. Queued for human design review before publishing.
Step 8: Cross-post to Reddit.
The AI also posted to Reddit, though the post got filtered because the bot account (u/AI_Conductor) has low karma. Fair enough — Reddit’s own quality gate doing its job.
What Actually Made It Work
Here’s the part that surprised me. The fix wasn’t:
The fix was saying no. Making the pipeline refuse to proceed without real artwork. Making it wait for mockups. Making it stop for human review.
Constraints made the system better, not more capability.
This mirrors what I see in software engineering broadly. The teams that ship quality aren’t the ones with the most tools — they’re the ones with the best gates. CI that won’t merge without tests passing. Code review that blocks deployment. Staging environments that catch config drift before production.
The AI product pipeline now works the same way. It’s not smarter. It’s more disciplined.
The Platform Today
The ORCHESTRATE platform that runs this pipeline now has 75 MCP tools. The pipeline covers:
All orchestrated by AI agents, all governed by quality gates that learned from failure.
The Typography Rule
If you’re building anything that puts AI-generated text on images, tattoo this on your wall:
AI image generators cannot reliably spell words correctly.
Not DALL-E. Not Midjourney. Not Flux. Not Stable Diffusion. They all struggle with typography. The longer the word, the worse it gets. “Autonomy” became “autonoomy.” I’ve seen “Wednesday” become “Wendesday.” “Entrepreneur” is basically impossible.
Your options:
Option 1 is simplest. Option 2 is most reliable. Option 3 is most limiting. Pick based on your pipeline’s throughput needs.
The Meta Lesson
I built an AI system that failed publicly. Then I fixed it by adding friction, not intelligence. The mug exists. It’s on a real storefront. The LinkedIn post has a real product image. The pipeline works.
The instinct when AI fails is to make it smarter — better prompts, bigger models, more reasoning tokens. Sometimes that’s right. But often the fix is simpler: make it impossible to skip the step it skipped.
The AI didn’t fail because it was dumb. It failed because nothing stopped it from taking shortcuts. Now something does.
The ORCHESTRATE Agile Suite and the AI product pipeline are open source. The coffee mug is real and available at iamhitl.com.
Books on the ORCHESTRATE method are available on Amazon:
First post: I Let AI Create a Product and Post It to LinkedIn. It Failed Spectacularly.