Despliegue, Operación y Troubleshooting interactivo de Infraestructura, usando AWS Kiro

🧠 Introducción

La operación de infraestructura en AWS suele involucrar múltiples fuentes de información: configuraciones distribuidas, logs, métricas, eventos de despliegue y dependencias entre servicios. Este escenario hace que la identificación de incidencias y el análisis de causa raíz (RCA) sean procesos complejos, especialmente en entornos modernos basados en microservicios, IaC y automatización continua.

AWS Kiro surge como una capa de inteligencia que procesa, correlaciona y razona sobre este ecosistema, actuando como un asistente operativo y de troubleshooting interactivo basado en IA, capaz de integrarse desde el despliegue hasta la operación diaria.

📌 Preambulo

¿Qué es Kiro desde el punto de vista de infraestructura?

Kiro puede entenderse como un asistente de troubleshooting interactivo basado en IA, capaz de diagnosticar, correlacionar y resolver incidencias en AWS mediante análisis contextual de múltiples capas:

🔐 Configuración de recursos: IAM, VPC, compute, storage

📊 Métricas y logs: Amazon CloudWatch, CloudTrail

🚀 Eventos de despliegue: CloudFormation, CDK, pipelines CI/CD

🕸️ Topología de arquitectura: dependencias y flujos entre servicios

✔️ En este artículo analizaremos en detalle:

  • Kiro como asistente integral de infraestructura en AWS.
  • Soporte inteligente en el despliegue de infraestructura.
  • Operación asistida mediante observabilidad aumentada.
  • Troubleshooting guiado y análisis de causa raíz (RCA).
  • Cómo Kiro transforma el ciclo completo de infraestructura.
  • Beneficios para equipos de arquitectura y operación.

Despliegue de Infraestructura con AWS Kiro

Una de las principales en los cuales se incorpora Kiro , es por las capacidades avanzadas que apoyan de forma inteligente los despliegues de infraestructura en AWS, ya que permite integración directamente con los flujos de IaC y automatización continua. Su rol en esta etapa es clave para asegurar despliegues consistentes, predecibles y libres de errores.

Validación inteligente de IaC (Infrastructure as Code)
Kiro analiza plantillas y definiciones de infraestructura en formatos como CloudFormation, CDK y Terraform, identificando:

  • Relaciones mal definidas entre recursos.
  • Parámetros inconsistentes o faltantes.
  • Bucles de dependencia.
  • Políticas IAM que no cumplen buenas prácticas.
  • Definiciones que generarán fallos en tiempo de ejecución.

Análisis en tiempo real de eventos de despliegue
Durante un despliegue, Kiro consume:

  • Eventos de CloudFormation Stack
  • Logs de CodeBuild y CodePipeline
  • Salidas de CDK Synth y CDK Deploy
  • Cambios registrados en CloudTrail

Con esta información, puede:

  • Correlacionar errores de compilación con fallos de permisos
  • Detectar recursos que quedaron en estado ROLLBACK_COMPLETE
  • Identificar drifts entre infraestructura declarada y real
  • Explicar qué dependencia o recurso provocó que el despliegue falle
  • Puede guiar paso a paso la solución.

Esto ayuda a detectar errores antes de que lleguen al pipeline.

Prevención de drift y problemas de consistencia
Kiro monitorea continuamente:

  • Configuraciones de IAM
  • Parámetros de VPC y subredes
  • Cambios no declarados en recursos críticos
  • Desvíos entre plantilla IaC y estado real

Si detecta un cambio manual, lo señala, explica el impacto y propone las correcciones para volver al estado deseado.

Acompañamiento guiado en despliegues complejos
Para arquitecturas con múltiples componentes —como EKS, RDS, Lambdas, VPC altamente segmentadas o stacks encadenados— Kiro puede:

  • Proponer el orden correcto de despliegue
  • Verificar dependencias inter-stack
  • Validar prerequisitos (roles, parámetros, networking)
  • Identificar componentes que requieren reprovisión

Esto reduce significativamente el riesgo de fallas por dependencias rotas.

Documentación automática del despliegue
Al finalizar un despliegue (exitoso o con errores), Kiro puede generar:

  • Resumen técnico
  • Recursos afectados
  • Logs relevantes
  • Cambios aplicados
  • Causas raíz de fallos (si ocurren)
  • Pasos a seguir

Esto no solo acelera auditorías, sino que mejora la trazabilidad operativa.

🚀 Asistencia en la Operación de la Reacción a la Prevención

Una de las bondades principales de Kiro, es que actúa como una herramienta de operación predictiva, permitiendo:

– Detección temprana de anomalías
Basado en métricas históricas, distribución de eventos y patrones
operativos.

– Recomendaciones de optimización
Incluyendo:

  • Costos y dimensionamiento.
  • Seguridad (IAM, Security Groups, KMS).
  • Mejoras de rendimiento en componentes compute y networking.
  • Buenas prácticas de arquitectura.

– Documentación automática de incidentes
Genera un informe con:

  • Análisis de contexto.
  • Pasos realizados.
  • Hallazgos.
  • RCA.
  • Solución.
  • Recomendaciones futuras.

Esto reduce drásticamente la carga operativa y mejora la gobernanza técnica.

⚙️ Troubleshooting Interactivo y Basado en Razón

Una de las capacidades más potentes de Kiro es su comportamiento como un asistente técnico conversacional, capaz de:

– Diagnóstico guiado
Kiro analiza el contexto del incidente, revisa logs, revisa configuración, compara con desviaciones previas y propone hipótesis técnicas.

– Correlaciones automáticas
Relaciona métricas de rendimiento con fallos de despliegue, cambios de configuración o eventos de seguridad.

Ejemplos típicos:

  • Un error 503 en API Gateway correlacionado con fallas en Lambda y timeouts de VPC.

  • Caídas en throughput en EKS correlacionadas con cambios de autoscaling o limitaciones de CPU.

  • Incremento en 5xx tras un despliegue específico detectado mediante CloudTrail + CodePipeline.

– Guía hacia la causa raíz (RCA)
Kiro opera como un copiloto técnico:

  • Identifica el punto de falla.
  • Explica qué lo produjo.
  • Muestra el rastro de dependencias.
  • Propone acciones correctivas.

Todo con trazabilidad y evidencia técnica.

🧪 Caso práctico (ejemplo típico)

Escenario: aplicación en EKS con latencia elevada

Kiro permite:

  • Detectar incremento en métricas de latencia (CloudWatch)

Correlacionar con:

  • Saturación de CPU en pods.

  • Throttling en base de datos.

Identificar causa raíz:

  • Subdimensionamiento o mala configuración de autoscaling

Sugerir acciones:

  • Ajuste de HPA

  • Optimización de Queries.

  • Mejora de límites de recursos.

Troubleshooting Interactivo y Basado en Razón

** Aplicación en el ciclo de vida de infraestructura**

👉 Despliegue

  • Identificación de errores en IaC (CloudFormation/CDK)
  • Diagnóstico de fallos en pipelines CI/CD
  • Validación de configuraciones antes de producción

🔄 Operación

  • Monitoreo continuo con correlación automática
  • Detección de anomalías en tiempo real
  • Optimización de performance y costos

🛠️ Troubleshooting

  • Reducción del tiempo de análisis manual
  • Identificación guiada de causa raíz
  • Generación de recomendaciones accionables

📈 Beneficios clave

⏱️ Reducción del MTTR hasta un 40–70%
👥 Menor dependencia de múltiples equipos en incidentes complejos (30–50%)
🔍 Mayor visibilidad end-to-end de la arquitectura
📚 Documentación implícita del proceso de resolución
📉 Disminución de errores operativos repetitivos

💬 Conclusión

Kiro permite diagnosticar y resolver problemas en AWS de forma interactiva, identificando fallos en despliegues, analizando métricas operativas, explicando causas raíz y proponiendo acciones concretas para mejorar la infraestructura, su operación y la documentación asociada a la resolución de incidentes.

Happy learnning on AWS!

Building My Own API Client at 14: From Requests to AI-Powered Insights

**_Building My Own API Client: Why I Did It

I’m 14, and I’ve already spent a lot of time exploring API tools like Postman, Hoppscotch, Insomnia, and more. While they’re all powerful and useful, I wanted something that was truly my own. Using pre-made tools is great, but I often felt limited by their design and workflow. I wanted a tool that reflects how I think about APIs, handle requests and responses, and analyze data in ways that make sense to me. That curiosity and need for control inspired me to start building my own API client from scratch.

What My API Client Can Do

Even at this early stage, the client already supports a lot of features. It handles cookies, request bodies, JSON data, headers, parameters, HTTP methods, and keeps a history of all requests and responses. It also measures request and response size and timing, giving detailed insights into API performance. This makes it easier to understand exactly what’s happening behind the scenes with each API call, instead of just sending requests blindly.

Planned Features and Visualizations

The project is currently about 20% complete, but the roadmap is exciting. I plan to add interactive graphs to visualize request size, response speed, and data capacity, so performance trends are easy to spot. I’m also integrating AI features that can automatically explain responses, suggest smart autofills for requests, and guide users through complex endpoints. The goal is to make API testing and exploration faster, smarter, and more intuitive.

Why Build It at 14

Building a project like this at 14 has been an amazing learning experience. It gives me a head start in understanding web development, API design, and performance optimization. Each bug, limitation, or challenge is an opportunity to improve my problem-solving skills and creativity. Starting early means I can experiment freely, try new ideas, and learn faster than if I waited.

Looking Forward

This API client is more than just a tool—it’s a platform for learning, experimenting, and pushing the limits of what I can create at my age. I’m excited to keep developing it, adding features, improving performance, and eventually having a full-fledged client that I can truly call my own. It’s a journey that’s teaching me so much about coding, design, and problem-solving, and it’s only just beginning._**

How I designed a multi-agent AI support copilot

Every support ticket starts the same way at our SaaS company: open the ticket, scan the description, then spend the next 15 minutes manually gathering context across five different systems. Check application telemetry for exceptions. Look up the customer in the CRM. Grep provisioning logs for failed sync events. Search work item systems and source control for related bugs. Cross-reference identity policy config if authentication is involved.

That context is all out there. It’s just scattered. By the time you’ve assembled it, you’ve already spent most of your time budget on information retrieval, not on reasoning.

That’s what I set out to fix. This is the first post in a series about the multi-agent AI support copilot.

The idea: a side-by-side AI copilot, not a replacement

The typical AI support story starts with a ticket routing chatbot or an automatic responder. That’s not this. We’re not changing the helpdesk agent’s job or asking the model to speak to the customer. Instead, we start a background process alongside the human support agent. The moment a ticket arrives, the copilot gathers context from the surrounding systems and checks whether that evidence corroborates, weakens, or contradicts what the customer is reporting.

The first milestone is deliberately modest from the product side: show the ticket and the supporting evidence side by side so the support agent can reason faster with better context. Under the hood, the implementation already goes further and can synthesize ranked hypotheses with confidence scores, but I still want the first user-visible win to be evidence the human can inspect. For now, the human stays in charge.

Everything that touches the customer still requires a human to approve it.

The design had three hard requirements:

  1. Parallel evidence gathering: all domains queried at the same time, not sequentially
  2. Structured outputs: every agent returns validated JSON, not prose that needs re-parsing
  3. Human-in-the-loop for every action: the copilot informs judgment, humans approve, deterministic code acts

Where the design came from

The initial architecture sketch came from a long ChatGPT conversation, the kind where you brain-dump a problem and the model helps you think through the components. That session produced the five-agent skeleton: identity resolution, observability telemetry, provisioning logs, work items, and a synthesis layer. It also produced the confidence arbitration formula:

FinalConf = sigmoid(Support - Conflict) × AgreementMultiplier

Where Support and Conflict are weighted sums of evidence claims, each claim weighted by the originating agent’s reliability (R_agent) and the claim’s local confidence.

The second source was internal: a reusable agentic scaffolding template we use for experiments. It had a graded architecture philosophy that mapped almost exactly to what we needed:

Grade Template capability What we needed
1 CLAUDE.md session memory SupportAgent persona + IncidentContext schema
2 Domain expertise YAML files Mental models per support domain (APM, CRM, SCIM, B2C, ALM)
3 Skills (SKILL.md with frontmatter) Evidence agent skill implementations
4 Closed-loop validation Re-evidence loop + Reviewer gate
5 Orchestration (parallel worker dispatch) Management Agent with parallel evidence dispatch

The template’s confidence_score field in expertise YAML files turned out to be exactly our R_agent reliability weight. Agents that update their own expertise files after each incident self-improve over time.

The two-layer repo structure

The template introduced a two-layer structure we adopted verbatim:

support-agent-research/
├── .agentic/              ← domain knowledge layer
│   ├── CLAUDE.md          - SupportAgent persona, session bootstrap
│   ├── memory/            - architecture decisions, ADR log
│   ├── plans/             - living docs for major system design changes
│   ├── expertise/         - per-domain YAML mental models
│   └── specs/             - per-incident IncidentContext files
│
└── .claude/               ← execution layer
    ├── agents/            - agent definitions (.md with frontmatter)
    ├── skills/            - evidence skill implementations (SKILL.md)
    └── settings.json      - hook wiring (Reviewer gate, Policy Gate)

The important part is that .agentic/ is the knowledge layer. It keeps the system’s memory between incidents: persona, architecture notes, domain expertise, plans, and incident files. In this article, plans/ just shows that the system’s design and build history live in the same place. .claude/ is the execution layer. It turns that knowledge into agents, skills, and hooks. Keeping them separate means you can update domain knowledge without touching execution logic, and vice versa.

How this matches broader agentic patterns

I didn’t invent this split in a vacuum. The Techorama 2025 sessions I captured in my notebook pointed at the same shape: a central orchestrator, specialist workers, shared context, and a clean split between knowledge and execution. I then turned that shape into a reusable agentic template, basically a starter kit that bootstraps those layers into a repo and keeps the supporting plans, memory, and delivery notes in one place.

That also matches the plan modes now showing up in current CLIs: they separate thinking from doing. The template goes further by preserving state, specialist workers, and feedback loops, so the agent can plan, execute, and improve without starting from zero each time.

These public repos corroborate the same building blocks. microsoft/skills covers skills, custom agents, AGENTS.md templates, and MCP configs. dotagents and source-agents focus on keeping one canonical instruction set synchronized across tools. claude-reflect turns corrections into durable memory and reusable skills. agnix adds validation gates by linting agent configs before they break workflows. For the orchestrator-worker shape itself, I point to the architecture docs from Anthropic and OpenAI below rather than forcing a weak repo comparison.

Anthropic draws a line between workflows and agents and recommends starting simple. The composable patterns they call out, like routing, parallelization, orchestrator-workers, and evaluator-optimizer loops, are the same kinds of building blocks I ended up using here. OpenAI’s Agents SDK makes a similar point by keeping the primitive set small: instructions, tools, handoffs, guardrails, sessions, and tracing. It also separates orchestration done by the LLM from orchestration done in code. That distinction matters to me because I want the model to reason, but I want deterministic code to route work and enforce boundaries. See Anthropic’s “Building effective agents”, OpenAI Agents SDK docs, and OpenAI Agents orchestration docs.

AGENTS.md fits this pattern too. It’s basically a repo-local README for agents, a human-readable place for durable instructions that complements the normal README.md. That’s exactly what .agentic/CLAUDE.md is doing for me here. See AGENTS.md.

.agentic piece What it stores Broader pattern
.agentic/CLAUDE.md Persona, operating rules, bootstrap guidance Repo-local agent instructions, AGENTS.md
.agentic/memory/ Architecture decisions and shared context Durable instructions and session memory
.agentic/plans/ Living record of the system’s design and build history Bootstrap paths, planning, and rollout history
.agentic/expertise/ Domain-specific mental models Specialist workers and routing inputs
.agentic/specs/ Incident-scoped state and evidence Persistent session state, blackboard
.claude/agents/ Worker definitions Handoffs, agent-as-tool
.claude/skills/ Narrow deterministic actions Tools and guardrails
.claude/settings.json Hook wiring and policy gates Deterministic routing and execution control

That’s why I ended up with a central Management Agent, specialized workers, a shared IncidentContext, and deterministic gates. The manager handles routing, the workers stay narrow, and the shared context gives every worker the same incident memory without letting them talk to each other directly. Then the reviewer and policy hooks decide what can actually happen. I want the model to gather evidence and propose answers, but I want code to decide when work is allowed to move forward. That same split shows up in Anthropic’s guidance, OpenAI’s Agents SDK docs, and AGENTS.md.

+------------------------+      +------------------------+
| .agentic               | ---> | .claude                |
| knowledge layer        |      | execution layer        |
|                        |      |                        |
| - CLAUDE.md            |      | - agents/              |
| - memory/              |      | - skills/              |
| - plans/               |      | - settings.json        |
| - expertise/           |      |                        |
| - specs/               |      |                        |
+------------------------+      +------------------------+

Core design decisions

Before writing a line, we laid out the key architectural bets in decisions.md:

  • Orchestrator-Worker over Decentralised: agents never pass control to each other. This prevents circular reasoning and cascading hallucinations. The Orchestrator is the only router.
  • IncidentContext as Blackboard: the shared knowledge base all agents write to and the Synthesis Agent reads from. Enables cross-domain correlation without agent-to-agent communication. “Identity policy changed last week” + “provisioning returned null” + “telemetry shows NullReferenceException” all point to the same root cause.
  • CLI-first auth: every skill uses the vendor’s own CLI (az, gh, acli) for authentication. Skills are credential-free; the bootstrap section validates auth before any query runs.
  • No LLM both concludes and acts: reasoning and execution are separate. The Policy Gate is deterministic code, not a model.

Orchestrator-Worker at a glance

      Support ticket
            |
            v
     Management Agent
   /   |    |    |   
  /    |    |    |    
  v    v    v    v     v
 APM  CRM  SCIM  B2C  ALM
      |    |    |    /
      |    |    |   /
    v  v    v    v  v
     IncidentContext
            |
            v
     Synthesis Agent

IncidentContext at a glance

IncidentContext
  - intake
  - resolved_identity
  - evidence
  - hypotheses
  - audit_log

That’s the design story. In part 2, I’ll show what happened when the first live tickets hit the wiring.

References

How I built cryptographic audit trails for AI agents (and why it matters)

Every company is deploying AI agents. Nobody knows what those agents are actually doing.

An autonomous agent can read your emails, call your Stripe API, export your database, and send messages — all without a human in the loop. When something goes wrong, there’s no proof of what happened, no way to prove authorization, and no compliance trail.
I built MandateZ to solve this. Here’s how it works technically.
The core problem
Traditional software has clear audit trails. An AI agent doesn’t. When a LangChain agent calls send_email(), nothing records: who authorized it, which policy allowed it, what the payload was, or whether a human approved it. That’s fine for demos. It’s a blocker for any enterprise deployment.
The architecture
Everything flows from one data structure — the AgentEvent:

interface AgentEvent {
  event_id: string;        // uuid v4
  agent_id: string;        // ag_ prefix + nanoid
  owner_id: string;        
  timestamp: string;       // ISO 8601
  action_type: 'read' | 'write' | 'export' | 'delete' | 'call' | 'payment';
  resource: string;        // e.g. "emails", "api/stripe"
  outcome: 'allowed' | 'blocked' | 'flagged' | 'pending_approval';
  policy_id: string | null;
  metadata: Record<string, unknown>;
  signature: string;       // Ed25519 signature
  public_key: string;      // agent's public key
}

Every agent action produces one of these. Every event is Ed25519 signed — cryptographically proving which agent produced it and that it hasn’t been tampered with.
Agent identity
Each agent gets a unique Ed25519 keypair on registration:

import { generateAgentIdentity, MandateZClient } from '@mandatez/sdk';

const agent = await generateAgentIdentity();
// { agent_id: 'ag_abc123', public_key: '...', private_key: '...' }

const client = new MandateZClient({
  agentId: agent.agent_id,
  ownerId: 'your_owner_id',
  privateKey: agent.private_key,
  supabaseUrl: process.env.SUPABASE_URL,
  supabaseAnonKey: process.env.SUPABASE_ANON_KEY,
});

Tracking events

await client.track({
  action_type: 'call',
  resource: 'api/stripe',
  metadata: { amount: 9900, currency: 'usd' }
});

Under the hood this: generates an event ID, timestamps it, canonicalizes the payload (keys sorted alphabetically), signs it with the agent’s private key using Ed25519, and inserts it into Supabase. The whole thing takes ~5ms.
Policy enforcement

const result = await client.track({
  action_type: 'export',
  resource: 'database/users',
});
// outcome: 'blocked' — policy rule matched, action never executed

Policies are JSON rules stored per owner. The engine evaluates them before the action executes. Blocked actions are logged with the matched rule ID.
Human oversight gate
For high-risk actions:

const oversight = {
  require_human_approval: ['export', 'delete', 'payment'],
  alert_channel: 'slack',
  timeout_seconds: 300,
  timeout_action: 'block'
}

The agent pauses execution, fires a Slack alert, and waits for human approval. If no response in 5 minutes — auto-blocked and logged.
Why Ed25519 specifically
RSA and ECDSA are too slow for high-frequency agent event signing. Ed25519 signatures are 64 bytes, verification is ~0.05ms, and the keys are small enough to store as base64 strings without bloating your database. libsodium-wrappers handles all of this with a clean API.
The neutrality moat
MandateZ works with LangChain, n8n, AutoGen, CrewAI, and every other framework simultaneously. OpenAI, Anthropic, and Nvidia all have security layers — but only for their own agents. MandateZ is the only layer that works across all vendors without a conflict of interest.
Try it

npm install @mandatez/sdk

Docs: mandatez.mintlify.app
GitHub: github.com/mandatez/core

💊 Did You Take Your Medicine Today? I Built a Pure-Frontend Medication Reminder App

A lightweight, no-sign-up, plug-and-play daily medication reminder tool

🎯 The Origin

As a working professional who kept forgetting to take my vitamins, I realized I needed a simple tool to remind myself to take medications on time. The medical apps out there were too heavy, too complex, and required registration — I just wanted to casually log “did I take my medicine today?”

That’s how this project was born: “Did You Take Your Medicine Today?”

Core Philosophy:

  • ✅ Open and use instantly, no registration
  • ✅ Data stays local, privacy protected
  • ✅ Clean interface, one-tap check-in
  • ✅ Browser push notifications for reminders

🛠️ Tech Stack

Layer Technology
Frontend HTML5 + CSS3 + Vanilla JS
Storage LocalStorage
Reminders Web Notification API
Deployment Static files (hosted on Cloudflare Pages)

Why pure frontend?

  • Zero backend dependency, lowest cost
  • No need to deal with server security or data compliance
  • User data stays completely private, never uploaded to any server

📱 Features

Core Features

  1. Daily Check-in — One tap to mark “I took my medicine today”, never forget again
  2. Medication Management — Add/edit/delete medications, set reminder times and dosages
  3. Browser Notifications — Scheduled push reminders for taking medications
  4. Today’s Status — Open the page and know immediately if you took your medicine today

Additional Features

  • 7-day medication history
  • Adherence statistics
  • Responsive design, mobile-friendly

🎨 UI Design

Using a purple gradient as the primary color, paired with green (success) and red (incomplete) for contrast:

/* Primary color */
background: linear-gradient(135deg, #667eea 0%, #764ba2 100%);

/* Success / Taken */
background: linear-gradient(135deg, #11998e 0%, #38ef7d 100%);

/* Incomplete */
background: linear-gradient(135deg, #eb3349 0%, #f45c43 100%);

Design Principles:

  • Large buttons, high contrast, suitable for elderly users
  • Card-based layout, clear hierarchy
  • Max width 480px, mobile-first

💾 Data Structure

{
  "medicines": [
    { "name": "Vitamin C", "time": "09:00", "dose": "1 tablet" },
    { "name": "Calcium", "time": "21:00", "dose": "2 capsules" }
  ],
  "records": {
    "2026-03-27": ["Vitamin C", "Calcium"],
    "2026-03-26": ["Vitamin C"]
  }
}

All data is stored in the user’s browser LocalStorage, never uploaded.

🤔 Technical Challenges

1. Browser Notification Permissions

Many users reject notification permissions on first use. Need to gracefully handle the fallback scenario:

// Request notification permission
Notification.requestPermission().then(permission => {
  if (permission === 'granted') {
    // Can send notifications now
  } else {
    // Show a prompt to guide user to enable manually
  }
});

2. Cross-Date Data Synchronization

Users might add tomorrow’s medication at 23:59. Need to ensure data consistency during date transitions.

3. LocalStorage Capacity Limits

While LocalStorage has a 5-10MB limit, for plain-text medication records this is more than sufficient.

📂 Project Structure

medicine-reminder/
├── medicine-reminder.html   # Main page
├── user.html               # User page
├── login.html              # Login page
├── donation.html           # Donation page
├── MVP-需求文档.md          # Requirements doc (Chinese)
└── _headers                # Cloudflare deployment config

🚀 Deployment

The project is deployed on Cloudflare Pages with a custom domain.

Deployment:

# Install wrangler CLI
npm install -g wrangler

# Deploy
wrangler pages deploy .

📈 Roadmap

Version Features
V1.1 7-day history, adherence stats, data export
V2.0 User accounts, multi-device sync, family reminders

💡 Conclusion

This tool is simple, but it solves a real problem: helping people build the habit of taking medications on time.

On the tech choices, the pure frontend approach sacrifices some “advanced features” (like multi-device sync) in exchange for extremely low development and maintenance costs, plus complete user control over their data. This is a classic “good enough is enough” product decision.

If you have similar needs, feel free to use it or fork it for customization!

Project: [https://github.com/qinyanbo/medicine-reminder.git]

Live Demo: [https://medicine-reminder.shop]

#javascript #webdev #sideproject #productivity #health

How Netflix Handles Millions of Requests (And Why Your System Probably Can’t Yet)

Most developers build apps that handle hundreds… maybe thousands of requests.

But systems like Netflix?
They handle millions of concurrent users—streaming video, serving APIs, running recommendations—all in real time.

I’ve seen this too many times: people design systems that work fine locally… then collapse the moment real traffic hits.

So, the real question is:

Why do systems like Netflix survive massive scale while most systems don’t?

Let’s break it down—no fluff.

⚙️ 1. Everything Scales Horizontally (Not Vertically)

Here’s the first mistake I see everywhere:

People try to scale by upgrading servers.

That doesn’t work.

Netflix-style systems follow one rule:

Add more machines, not bigger machines.

🔁 Flow
User Requests → Load Balancer → Multiple Services → Databases

When traffic increases:

New instances spin up
Load gets distributed

While working on backend systems, I realized quickly that vertical scaling hits a ceiling fast—horizontal scaling is the only real way forward.

🌐 2. Load Balancing: The Silent Hero

Before your backend even sees traffic, a load balancer is already doing heavy lifting.

It:

Distributes requests
Detects unhealthy instances
Reroutes traffic instantly
Reality:

If one service goes down:

👉 Users shouldn’t notice

If they do, your system isn’t ready.

🧱 3. Microservices: Break the Monolith

Monoliths feel easy—until they aren’t.

Netflix moved to microservices because:

Each service can scale independently
Failures don’t take down the entire system
Example Services:
User Service
Recommendation Engine
Streaming Metadata

I ran into this issue early tight coupling between components made everything fragile.

Breaking things into smaller services made debugging and scaling way easier.

⚡ 4. Caching: The Difference Between Fast and Dead

Let’s be honest:

Without caching, your system will choke under load.

What gets cached:
User data
API responses
Popular content
Flow:
Request → Cache → (miss) → DB → Cache → Response

In one of my deployments, skipping proper caching caused massive DB pressure. Fixing that alone dropped latency significantly.

🌍 5. CDN: Serving the World Locally

Netflix doesn’t stream from one central server.

They use distributed systems, so users get content from nearby locations.

Example:
A user in Lagos → gets data from a nearby edge server
Not from another continent

👉 Result:

Lower latency
Better performance
🧠 6. Data Layer: Designed for Scale

Single database? That’s a bottleneck waiting to happen.

Netflix uses:

Sharding → split data
Replication → duplicate for availability
NoSQL systems → handle scale
Reality:

If your database can’t scale, your system can’t scale.

🔄 7. Failure Is Expected (Not Optional)

Here’s where most systems fail badly:

They assume things won’t break.

At scale:

Failure is guaranteed

Techniques:
Circuit breakers
Retry logic
Fallback responses

Netflix even built Chaos Monkey
—a tool that randomly shuts down servers in production.

Sounds crazy… but it forces systems to become resilient.

📊 8. Observability: Know What’s Happening

You can’t fix what you can’t see.

At scale, you must track:

Latency
Errors
Throughput

In my experience, lack of visibility is what kills systems—not just bugs.

🚀 9. Auto-Scaling: Survival Mode

When traffic spikes:

New instances spin up automatically

When traffic drops:

Resources scale down

No manual intervention.

If your system needs, you to survive traffic… it’s not scalable yet.

🧬 10. Personalization at Scale

Netflix isn’t just serving content.

It’s:

Running ML models
Personalizing recommendations
Updating in real time

This adds another layer:
👉 AI + infrastructure must work together seamlessly

💥 Why Most Systems Fail

Let’s not pretend:

Most systems fail because:

No caching strategy
Tight coupling
Single database dependency
No failure handling
No monitoring

🧠 Key Takeaways
Scale horizontally
Cache aggressively
Design for failure
Monitor everything
Decouple your services

⚡ Final Thought

Netflix didn’t start here.

They got here through:

Failures
Outages
Iteration

If you’re building today:

Design for scale before you need it.

🔥 Follow My Journey

I’m building AI systems, telecom infrastructure, and scalable platforms—and sharing everything I learn along the way.

If you’re into real-world systems, not just theory, follow me for more deep dives.

Your Laravel Queries Are Lying to You

How many times does Product::latest() appear in your codebase?

If the answer is more than once, you’re not DRY — you’re just organized duplication. Every repeated query entry point is another interpretation of how that query should behave. Inconsistencies creep in silently, and future changes become a scavenger hunt.

Atomic Query Construction (AQC) fixes this with one rule:

Every model gets exactly one query entry point, inside a dedicated execution class.

// Every. Single. Time.
(new GetProducts())->handle($params);

Filters, sorting, pagination — all controlled through params. One place to change, one place to debug, zero drift.

📖 Read the complete article here.

Building Privacy-Preserving Machine Learning: A Practical Guide to Federated Learning

Student data is sensitive. Healthcare records are confidential. Financial information is protected. Yet organizations need machine learning to improve their services. How do you train AI models without exposing private data?

The answer is federated learning—a paradigm shift in how we approach machine learning with sensitive data.

The Problem with Traditional ML

Traditional machine learning requires centralizing data:

# Traditional approach - BAD for privacy
all_student_data = []
for school in schools:
    all_student_data.extend(school.get_data())  #  Privacy violation!

model.fit(all_student_data)  # Training on centralized data

This approach violates privacy regulations like FERPA (education), HIPAA (healthcare), and GDPR (Europe). Even anonymization isn’t enough—research shows that “anonymous” datasets can often be re-identified.

Enter Federated Learning

Federated learning flips the script: instead of moving data to the model, we move the model to the data.

# Federated approach - Privacy preserved
global_model = initialize_model()

for school in schools:
    local_model = global_model.copy()
    local_model.train_on_local_data()  #  Data never leaves school
    send_only_model_updates(local_model)  #  Share learning, not data

global_model = aggregate_updates()  # Combine knowledge

Real-World Example: Student Dropout Prediction

Let’s say 10 universities want to build a student dropout prediction model together, but FERPA prohibits sharing student records. Here’s how federated learning solves this:

Step 1: Initialize Global Model

import tensorflow as tf
from tensorflow import keras

def create_model():
    model = keras.Sequential([
        keras.layers.Dense(128, activation='relu', input_shape=(20,)),
        keras.layers.Dropout(0.3),
        keras.layers.Dense(64, activation='relu'),
        keras.layers.Dense(1, activation='sigmoid')
    ])
    model.compile(optimizer='adam', 
                  loss='binary_crossentropy',
                  metrics=['accuracy'])
    return model

global_model = create_model()

Step 2: Distribute to Universities

def federated_training_round(global_model, universities, num_clients=5):
    # Randomly select universities for this round
    selected = random.sample(universities, num_clients)

    local_weights = []
    local_sizes = []

    for university in selected:
        # Each university trains on their own data
        local_model = clone_model(global_model)

        # Training happens locally - data never leaves!
        history = local_model.fit(
            university.X_train,  # ✅ Stays at university
            university.y_train,
            epochs=5,
            batch_size=32,
            verbose=0
        )

        # Only model weights are shared, not data
        local_weights.append(local_model.get_weights())
        local_sizes.append(len(university.X_train))

    return local_weights, local_sizes

Step 3: Aggregate Updates

def federated_averaging(global_weights, local_weights, local_sizes):
    """
    Weighted average of model updates
    Universities with more data have more influence
    """
    total_size = sum(local_sizes)

    # Initialize averaged weights
    averaged_weights = []

    for layer_idx in range(len(global_weights)):
        # Weighted average for this layer
        layer_avg = sum(
            (size / total_size) * weights[layer_idx]
            for weights, size in zip(local_weights, local_sizes)
        )
        averaged_weights.append(layer_avg)

    return averaged_weights

Step 4: Add Differential Privacy

Even model updates can leak information. Add noise for mathematical privacy guarantees:

def add_differential_privacy(weights, epsilon=1.0, sensitivity=0.1):
    """
    Add Laplace noise for epsilon-differential privacy
    epsilon: Privacy budget (lower = more private)
    """
    noisy_weights = []
    scale = sensitivity / epsilon

    for layer in weights:
        noise = np.random.laplace(0, scale, layer.shape)
        noisy_weights.append(layer + noise)

    return noisy_weights

Complete Training Loop

# Full federated learning with privacy
global_model = create_model()
universities = load_universities()  # 10 universities with local data

for round in range(100):
    # Select random subset for this round
    local_weights, local_sizes = federated_training_round(
        global_model, universities, num_clients=5
    )

    # Add differential privacy
    local_weights = [
        add_differential_privacy(w, epsilon=1.0) 
        for w in local_weights
    ]

    # Aggregate with weighted averaging
    global_weights = global_model.get_weights()
    new_weights = federated_averaging(
        global_weights, local_weights, local_sizes
    )

    global_model.set_weights(new_weights)

    # Evaluate on global test set
    if round % 10 == 0:
        accuracy = evaluate_global_model(global_model)
        print(f"Round {round}: Accuracy = {accuracy:.2%}")

Real Results

In our research using this approach across educational institutions:

  • 99.3% accuracy in dropout prediction
  • ε = 1.0 differential privacy (strong privacy guarantee)
  • Zero student records shared between institutions
  • 34% better privacy-utility tradeoff vs. traditional approaches

The Non-IID Challenge

Real-world data isn’t uniform. University A might have mostly STEM students, University B liberal arts. This “non-IID” (non-independent and identically distributed) data breaks standard federated learning.

Solution: Adaptive client weighting based on data quality:

def adaptive_weighting(local_accuracies, local_sizes):
    """
    Weight clients by both size AND performance
    Better local models get more influence
    """
    quality_scores = [
        acc * size 
        for acc, size in zip(local_accuracies, local_sizes)
    ]

    total_quality = sum(quality_scores)

    return [score / total_quality for score in quality_scores]

When to Use Federated Learning

Use federated learning when:

  • Data is sensitive (healthcare, education, finance)
  • Data cannot be centralized (regulatory, competitive)
  • Data is distributed (mobile devices, institutions)
  • Privacy is non-negotiable

Don’t use it when:

  • Data is already centralized
  • Privacy isn’t a concern
  • You need very fast training
  • Data is small enough to process centrally

Getting Started

Want to try federated learning yourself?

Libraries:

  • TensorFlow Federated: pip install tensorflow-federated
  • PySyft: pip install syft
  • Flower: pip install flwr

Simple Example:

import tensorflow_federated as tff

# Define your model
def model_fn():
    return tff.learning.from_keras_model(
        keras_model=create_model(),
        input_spec=...,
        loss=...,
        metrics=[...]
    )

# Create federated learning process
iterative_process = tff.learning.build_federated_averaging_process(
    model_fn,
    client_optimizer_fn=lambda: tf.keras.optimizers.SGD(0.02),
    server_optimizer_fn=lambda: tf.keras.optimizers.SGD(1.0)
)

# Train!
state = iterative_process.initialize()
for round_num in range(100):
    state, metrics = iterative_process.next(state, federated_train_data)
    print(f'Round {round_num}: {metrics}')

The Future is Federated

As privacy regulations tighten and data breaches make headlines, federated learning isn’t just nice-to-have—it’s becoming essential. Organizations that adopt privacy-preserving ML now will have a competitive advantage tomorrow.

The best part? You can start today. The tools are mature, the libraries are production-ready, and the benefits are proven.

Your data doesn’t need to travel to learn. The model can come to you.

Questions? Drop them in the comments!

Building something with federated learning? I’d love to hear about it.

Connect: https://www.linkedin.com/in/dinesh-garikapati-7080b1184/[email protected]

Your AI Agent Needed Gmail, Slack, and GitHub. I Gave It One Login.

How Auth0 Token Vault solved the multi-provider problem for AI agents and the three lessons I’d love to share with the Auth0 team.

It started with a dream setup.

I was building MCS (Model Context Standard), an open-source Python SDK that lets AI agents interact with services like Gmail, Google Drive, and Slack through a standardized tool interface. The agent doesn’t know it’s talking to Gmail. It just calls search_emails(query="invoices from last week") and gets results.

Authentication should be equally invisible. The agent shouldn’t care how it gets a token. It just needs one.

Then I found Auth0 Token Vault and immediately understood the promise.

The Promise That Hooked Me

Before Token Vault, every service my agent needed meant another OAuth client. Gmail? Register a Google OAuth app. GitHub? Another OAuth app. Slack? Another one. Each with its own token refresh logic, its own scopes, its own error handling. Multiply that by every agent deployment.

Token Vault flips this. One Auth0 login. One refresh token. Access to every connected service.

token = provider.get_token("gmail")    # → Google access token
token = provider.get_token("github")   # → GitHub access token  
token = provider.get_token("slack")    # → Slack access token

Without new OAuth clients, new callback URLs and new token refresh logic. You configure connections in the Auth0 dashboard, and the agent accesses any service through a single method call. The code never changes.

Then I tried to run it.

The Wall: Where Agents Live vs. Where OAuth Expects Them

My agent runs in a Docker container. No browser. No localhost callback. No web UI. Just a terminal.

And Claude Code lives in its sandbox.

The most natural auth pattern for this is Device Flow: show a URL and a code, the user authenticates after following the URL, done. It’s the pattern every smart TV and CLI tool uses.

Here’s where I hit the wall:

Token Vault requires a Confidential Client. That’s a Regular Web Application with a client secret. Makes sense, you don’t want agents exchanging tokens without proper credentials.

Device Flow requires a Native Application. That’s a public client, no secret. Also makes sense, it’s designed for devices without secure storage.

You can’t have both on the same application.

This isn’t a misconfiguration. It’s a product constraint that makes perfect sense from a security perspective, but it creates a real gap for AI agents. Agents are confidential (they have secure storage for secrets), but they behave like devices (no browser, no callback URL).

Auth0 clearly sees this gap. It’s exactly why they launched Auth for GenAI. But today, with the current Token Vault, I needed a bridge.

Building the Bridge

What if I bring the Device Flow experience to Token Vault, without actually using Device Flow?

The user experience I wanted:

Agent: I need Gmail access. Please open this URL and enter code ABCD-1234.
User:  *opens URL, enters / checks code, logs in with Google*
Agent: Got it. Reading your emails now.

Under the hood, it’s actually a full OAuth Authorization Code Flow with PKCE, which is compatible with Token Vault. The user just doesn’t see that. They see a URL and a code, exactly like Device Flow.

To make this work, I needed three things:

  1. A broker that can receive the OAuth callback on behalf of the agent
  2. A way for the agent to poll for completion without a callback server
  3. Zero-knowledge encryption so the broker never sees credentials in plaintext

That became LinkAuth – An open-source credential broker that gives any sandboxed agent a Device Flow UX on top of standard OAuth and more…

The Architecture (Where SOLID Actually Matters)

MCS uses a layered design where each layer has exactly one job:

┌─────────────────────────────────────────────────┐
│  AI Agent (LLM + Tools)                         │
│  "Search my Gmail for invoices"                 │
├─────────────────────────────────────────────────┤
│  MailDriver + AuthMixin                         │
│  Intercepts AuthChallenge, shows URL to user    │
├─────────────────────────────────────────────────┤
│  Auth0Provider (CredentialProvider)              │
│  get_token("gmail") → Token Vault exchange      │
├─────────────────────────────────────────────────┤
│  LinkAuthConnector (AuthPort)                   │
│  Device-flow UX via broker                      │
├─────────────────────────────────────────────────┤
│  LinkAuth Broker                                │
│  Receives OAuth callback, encrypts, stores      │
└─────────────────────────────────────────────────┘

The critical design decision: AuthPort is a protocol, not a base class.

class AuthPort(Protocol):
    def authenticate(self, scope: str, *, url: str | None = None, ...) -> str: ...

Any object with an authenticate method satisfies it. No inheritance. No imports. The provider doesn’t know and doesn’t care which connector is plugged in.

This means switching auth strategies is a one-line change:

provider = Auth0Provider(
    domain="my-tenant.auth0.com",
    client_id="...",
    client_secret="...",
    _auth=connector,  # OAuthConnector OR LinkAuthConnector - same interface
)

# This line is the same regardless of auth method:
token = provider.get_token("gmail")

Switch connector and you switch from browser login to device-flow UX. Zero changes in agent code. Zero changes in the Gmail driver. Zero changes in the LLM prompt.

The Double Flow Surprise

This one cost me an entire day and it’s the kind of insight you only get from building against an API, not reading about it.

Auth0 has a connection setting called “Authentication and Connected Accounts.” The name suggests a single step. Log in with Google, Auth0 stores the Google token in Token Vault. One flow, done.

In practice, the first time a user connects, they go through two separate flows:

  1. OAuth login – The user authenticates with Auth0 (via Google). You get an Auth0 refresh token.
  2. Connected Accounts setup – You exchange the refresh token for a My Account API token (MRRT), POST to /connect, the user consents again in a browser, then POST to /complete.

Two browser interactions. Two consent screens. For what the user perceives as “log in with Google.”

First run: get_token("gmail")
  → No refresh token → AuthChallenge("Open URL, enter ABCD")
  → User logs in → Auth0 refresh token ✅
  → Token Vault → "federated_connection_refresh_token_not_found"
  → MRRT exchange → POST /connect → AuthChallenge("Open URL again")
  → User consents (again!) → POST /complete ✅

Every subsequent call: get_token("gmail")
  → Refresh token cached → Token Vault → Google access token ✅
  → Instant.

Once set up, the experience is seamless. But that first run is a surprise for both developers and users. To absorb this complexity, Auth0Provider handles the entire state machine automatically. The agent developer never sees the MRRT exchange or the /connect flow, just AuthChallenge exceptions that bubble up as “please open this URL” messages.

The Checklist Nobody Gives You

If you’re integrating Auth0 Token Vault for agents, here’s the checklist I wish the docs had as a single page:

  • [ ] Application type: Regular Web Application (Confidential Client)
  • [ ] Grant types: Authorization Code, Refresh Token, Token Vault
  • [ ] Connection mode: “Authentication and Connected Accounts” on your Google connection
  • [ ] API settings: Allow Offline Access enabled on your API
  • [ ] MRRT: Multi-Resource Refresh Tokens enabled (Tenant Settings → Advanced)
  • [ ] Audience: Pass the correct audience parameter in your authorization request
  • [ ] Google Cloud: Gmail API enabled in the GCP project linked to your Google OAuth client
  • [ ] Scopes: Include offline_access in your Auth0 scopes, AND the Gmail scope in your connection_scopes

Miss any one of these and you get a cryptic error. federated_connection_refresh_token_not_found is the one you’ll see most. It’s the catch-all for “something in the chain isn’t configured right.” A dedicated “Token Vault Setup Wizard” in the Auth0 dashboard could save developers hours.

What Auth0 Gets Right – And Three Ideas to Make It Even Better

Token Vault is the right abstraction for AI agents. The idea that an agent holds one credential and accesses dozens of services through configuration rather than code is exactly how agent auth should work. No other identity platform offers this today as far as I know.

Building this integration gave me three pieces of feedback I’d love to share with the Auth0 team:

1. Bridge the Device Flow Gap

Agents are confidential clients that behave like devices. They have secure storage for secrets (so Device Flow’s public-client model isn’t needed), but they can’t receive callbacks or open browsers (so Authorization Code Flow is awkward). A first-party “Agent Flow” – Device Flow UX backed by a Confidential Client – would eliminate the need for broker infrastructure like LinkAuth entirely. The UX works. We proved it. Auth0 could offer it natively.

Or use LinkAuth in the meantime 😉

2. Streamline the Double Flow

“Authentication and Connected Accounts” is the right feature, but the first-run experience of two separate consent screens is confusing. If the consent for Connected Accounts could be bundled into the initial login flow (even as an optional “eager connect” mode), the first-run experience would match what the setting name already implies: one flow, authentication and connected accounts.

3. One Page, All the Settings

Token Vault touches Auth0 application settings, API settings, connection settings, tenant-level feature flags, and the external provider’s dashboard. A single “Token Vault Setup Guide” or setup wizard that walks through all eight configuration steps in sequence would save every developer the evening I spent chasing federated_connection_refresh_token_not_found through five different settings screens.

Try It

The Gmail Agent example is a fully working chat client that reads and sends email through any LLM. Auth0 Token Vault is one flag away:

# 1. Install
pip install mcs-driver-mail[gmail] mcs-auth-auth0 litellm rich python-dotenv

# 2. Configure (.env)
AUTH0_DOMAIN=my-tenant.auth0.com
AUTH0_CLIENT_ID=...
AUTH0_CLIENT_SECRET=...

# 3. Run with Auth0 + LinkAuth (device-flow UX, works in Docker/CLI)
python main.py --auth0-linkauth

# Or with Auth0 + browser login (dev machine)
python main.py --auth0-oauth

That’s it. The agent starts, the LLM discovers the Gmail tools, and on the first call that needs credentials, the user sees a URL to authenticate. From the second call on, Token Vault handles everything silently.

The code that makes this work is surprisingly short. The entire agent class is one line:

class GmailAgent(AuthMixin, MailDriver):
    pass

AuthMixin intercepts any AuthChallenge and turns it into a message the LLM can show the user. MailDriver provides the Gmail tools. The agent itself has zero auth logic.

Switch --auth0-linkauth to --auth0-oauth and the auth path changes from device-flow to browser login. The driver, the LLM prompt, the tool definitions – nothing changes.

Everything is open source:

Built for the Auth0 AI Agent Hackathon. Token Vault is the right idea. I just needed to build a bridge to reach it.

QCon London 2026: AI Agents Write Your Code. What’s Left For Humans?

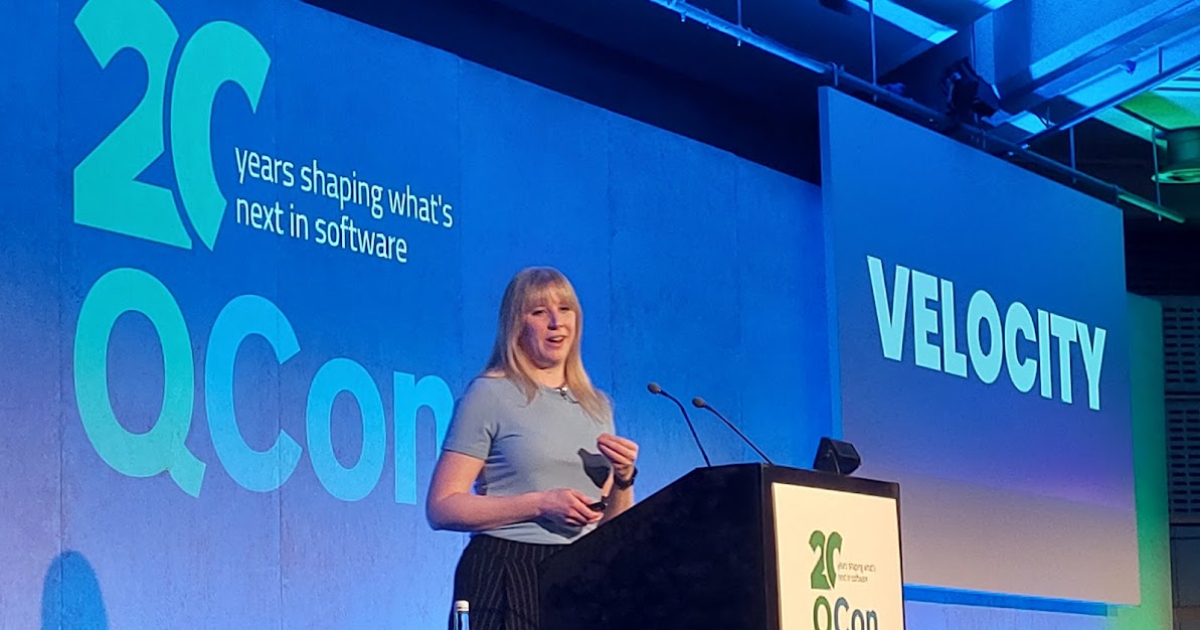
Hannah Foxwell began her QCon London 2026 talk by noting that the long-sought velocity in development has arrived, but the industry is unsure how to use it. She set aside the technical details of agentic coding, focusing instead on its implications for the people working with these systems.

By Matt Saunders