Bakan Göktaş: İnsan, dünyayı önce aile içinde tanır
AİLE ve Sosyal Hizmetler Bakanı Mahinur Özdemir Göktaş, “Bugün dünya nüfusu 8 milyarı aşmış durumda.

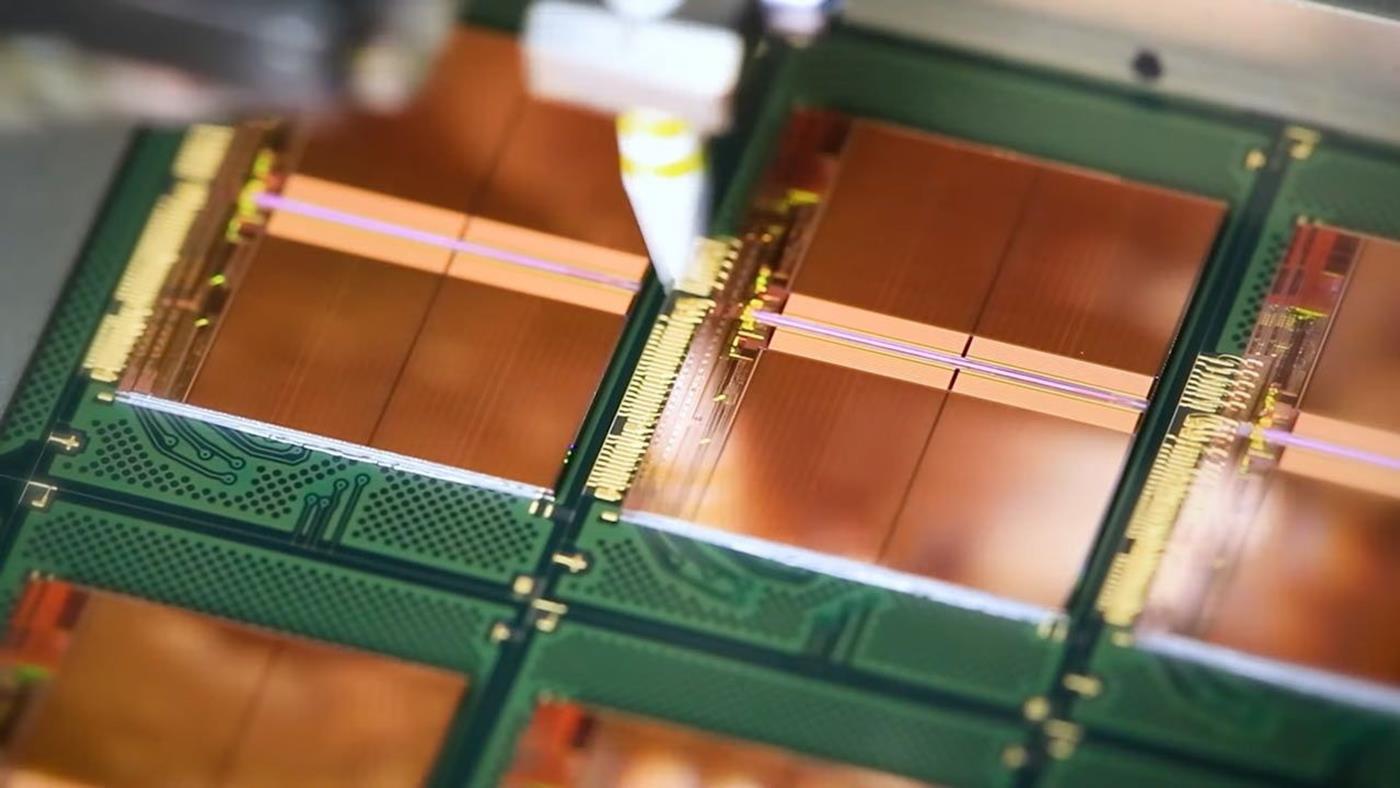
 Yapay zekâ veri merkezleri, bellek ve depolama krizinin ardından CPU pazarına yönelmeye başladı. Intel ve AMD’nin yetişemediği talep, PC ve sunucu fiyatlarını yukarı çekiyor.
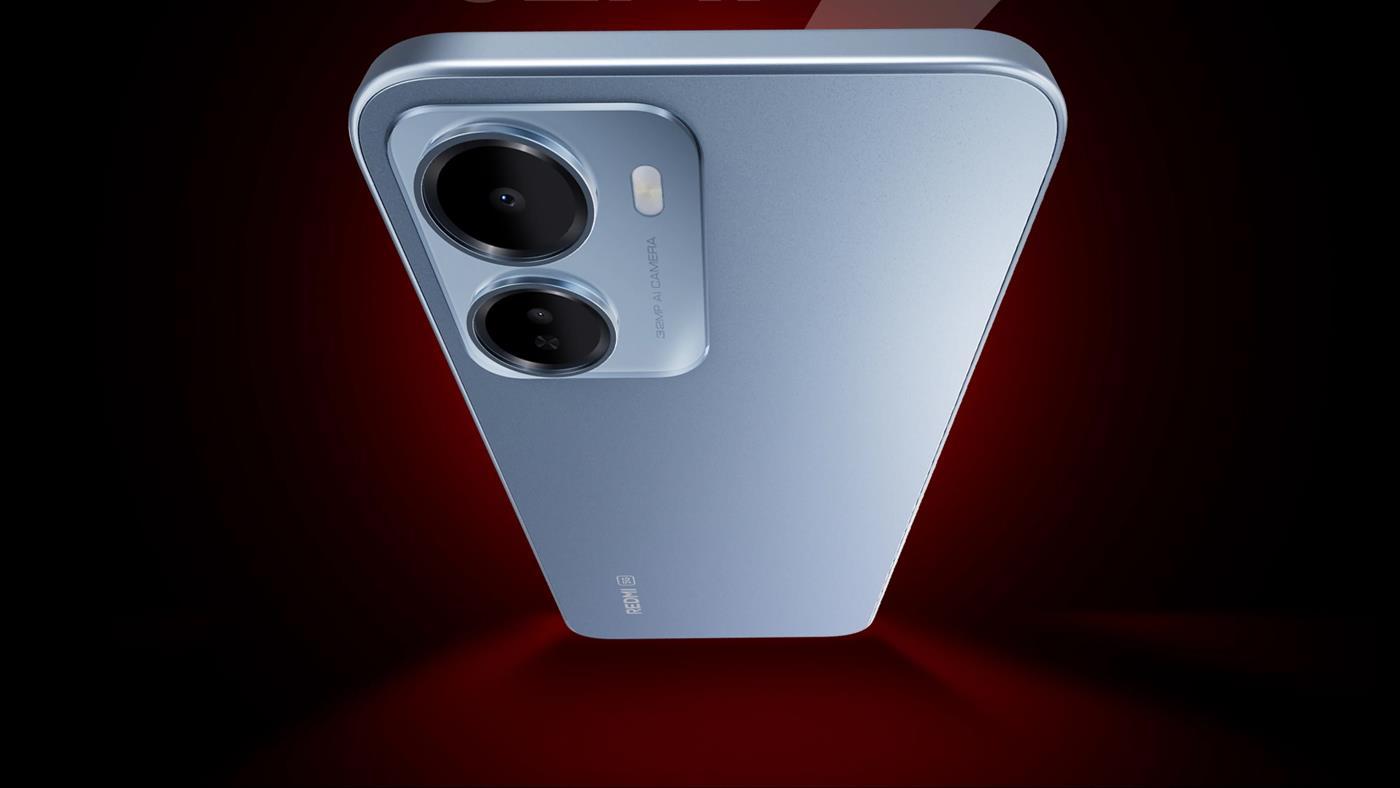
 Xiaomi, uygun fiyatlı 5G telefonunu tanıttı. Redmi 15A olarak adlandırılan cihaz, microSD kartla hafıza genişletme, 3.5mm kulaklık girişiyle kablolu kulaklıkları kullanma ve fazlasını sunuyor.
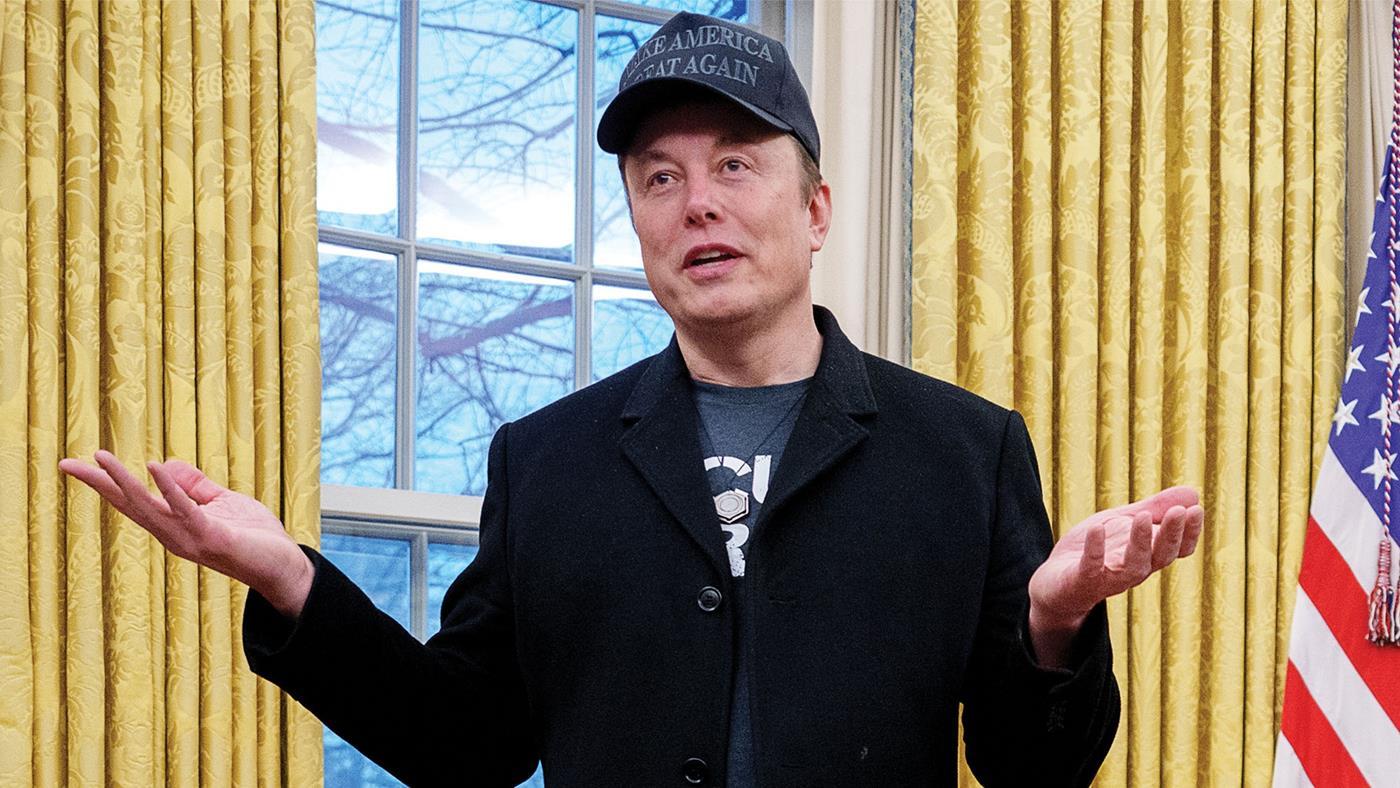
 X, çok sütunlu arayüzü X Pro’yu sessizce Premium+ aboneliğe taşıdı. Değişim, bildirim yapılmadan uygulanınca kullanıcılar tepki gösterirken daha güçlü araçların geleceği açıklandı.

Learn how to build reliable web data pipelines in Python using API-based extraction instead of scraping scripts. This guide walks through single-page scrapes, batch processing, structured JSON output, and handling errors in production.
If you have ever written a Python scraping script that worked perfectly on Tuesday and broke by Thursday, you already understand the core problem. Websites change their HTML structure, deploy anti-bot protections, and render content with JavaScript that a simple requests.get() call never sees. Maintaining these scripts becomes a job in itself.
Web Data APIs take a different approach. Instead of managing headless browsers, proxy pools, and CSS selectors yourself, you send an HTTP request with a URL and get back clean, structured content. The infrastructure that handles JavaScript rendering, IP rotation, and retry logic lives on someone else’s servers.
This guide uses Olostep as the API provider to walk through practical Python examples. By the end, you will have tested, working code that runs against a real API.
All code examples in this article are available in the companion GitHub repository: olostep-python-guide.

Web data API request flow. Image by Author.
What Is a Web Data API?
The term “Web Data API” describes a category of services that handle the scraping infrastructure for you and return structured page content through a standard HTTP interface. Before I get into how these APIs work, let me start with what they replace and why.
The problem with traditional scraping
Traditional web scraping means writing code that downloads a page’s HTML, parses it with a library like BeautifulSoup or Scrapy, and extracts the data you need by targeting specific CSS selectors or XPath expressions. This works fine for small, stable projects. It starts to fall apart when any of the following happens:
Each of these problems has a solution, but the solutions stack up. You end up maintaining a headless browser, a proxy pool, a retry queue, and a CAPTCHA solver alongside the actual data extraction logic. At that point, the scraping infrastructure often takes more engineering effort than the analysis you built it for.
What web data APIs solve
A web data API handles all of that infrastructure behind a single HTTP endpoint. You send a POST request with the URL you want to scrape and the format you need (Markdown, HTML, JSON), and the API returns the extracted content. JavaScript rendering, residential IP rotation, and anti-bot handling happen on the provider’s side.
The real difference is who owns the maintenance. With traditional scraping, that is you: the browser, the proxies, the retry logic. With a web data API, the provider handles that stack, and you pay per request. Your code deals with the data, not with how to get it.
Who uses web data APIs?
AI companies building RAG pipelines need clean text from thousands of documentation pages. So do product teams running research agents and data engineers who need extraction that does not break every time a target site updates its frontend.
Getting Started with Olostep
With that background covered, let me walk through a practical setup using Olostep.
Creating an account and getting your API key
Head to olostep.com and create an account. The free tier gives you 500 successful requests per month, which is enough to follow along with this guide.
Once you are logged in, find your API key in the dashboard. You will need it for every request.

Dashboard API key retrieval section. Image by Author.
Store it as an environment variable rather than hardcoding it in your scripts:
export OLOSTEP_API_KEY="your_api_key_here"
On the Python side, you only need the requests library:
pip install requests
Your first API scrape
Here is a minimal example that scrapes a single URL and returns the content as Markdown and HTML. I will break down each part after the code.
import os
import requests

api_key = os.environ.get("OLOSTEP_API_KEY")
endpoint = "https://api.olostep.com/v1/scrapes"

headers = {
    "Authorization": f"Bearer {api_key}",
    "Content-Type": "application/json"
}

payload = {
    "url_to_scrape": "https://books.toscrape.com/",
    "formats": ["markdown", "html"]
}

response = requests.post(endpoint, json=payload, headers=headers)
response.raise_for_status()

data = response.json()
print(data["result"]["markdown_content"][:500])
Note that formats takes an array, so you can request multiple output formats in one call. The response.raise_for_status() call ensures your code fails loudly on HTTP errors rather than silently processing a bad response.
Understanding the API response
The response from /v1/scrapes is a JSON object. Two parts are worth paying attention to. At the top level you get metadata, including a retrieve_id you can use later to fetch the same content without re-scraping:
retrieve_id = data["retrieve_id"] # Top-level field
The actual extracted content lives inside the result object:
markdown = data["result"]["markdown_content"]
html = data["result"]["html_content"]
Core Endpoints and When to Use Them
Olostep provides several endpoints, but three cover most of the extraction jobs you will run. Each one suits a different scenario, so picking the right one matters.

Choosing the right API endpoint. Image by Author.
/v1/scrapes: single-page extraction
This is the endpoint I used in the previous section. It works synchronously: you send a URL, and you get back the content in the same HTTP response. Use it when you need to extract data from a single page or a small number of pages (under 50) where you can run requests in parallel from your own code.
The key optional parameters are:
wait_before_scraping (integer, milliseconds): Tells the API to pause before extracting, giving JavaScript time to render. This replaces any selector-based waiting you might expect from browser automation tools.country: Routes the request through a residential IP in a specific country. Useful when the page serves different content based on location. Supported values include US, GB, JP, IN, and others.actions: An array of browser interactions (click, scroll, fill input, wait) that the API executes before extraction. This covers scenarios where content is behind a button click or requires scrolling to load.Each scrape costs 1 credit on the base plan.
/v1/batches: bulk URL processing
When you have a list of URLs, say 100 to 10,000, submitting them one by one through /v1/scrapes is inefficient. The /v1/batches endpoint accepts a single POST request containing all your URLs and processes them in parallel on Olostep’s infrastructure.
batch_payload = {
    "items": [
        {"custom_id": "page_1", "url": "https://example.com/page-1"},
        {"custom_id": "page_2", "url": "https://example.com/page-2"},
        {"custom_id": "page_3", "url": "https://example.com/page-3"}
    ]
}

response = requests.post(
    "https://api.olostep.com/v1/batches",
    json=batch_payload,
    headers=headers
)
response.raise_for_status()
batch_id = response.json()["id"]
Each item needs a custom_id (a unique string you define) and a url. The batch processes in parallel and typically completes in 5 to 8 minutes regardless of size. You check the status by polling, which I will cover in the pipeline section.
One thing to know: new accounts may start with a lower batch limit than the 10,000 maximum. Contact Olostep’s support team to confirm your account’s current limit and request an increase if needed.
/v1/answers: natural language web queries
This endpoint works differently from the other two. Instead of providing a URL, you provide a natural language question. The API searches the web, cross-references sources, and returns an answer with citations.
answer_payload = {
    "task": "What is the current market cap of NVIDIA?",
    "json": {
        "company": "",
        "market_cap": "",
        "currency": "",
        "source": ""
    }
}

response = requests.post(
    "https://api.olostep.com/v1/answers",
    json=answer_payload,
    headers=headers
)
The json parameter lets you define the structure of the response. Pass an object with empty string values as a schema template, and the API returns data that matches those fields. If the API cannot find a reliable answer for a field, it returns "NOT_FOUND" instead of guessing, which is useful for data validation pipelines.
This endpoint costs 20 credits per request, so it is best suited for research automation and enrichment tasks rather than high-volume extraction.
Building a Web Data Pipeline in Python
With the individual endpoints covered, let me put them together into a working pipeline.

End-to-end batch data pipeline flow. Image by Author.
Defining your target URLs
Start with a list of URLs you want to process. In a real project, these might come from a database, a sitemap, or a prior discovery step. For this example, I will use a static list:
target_urls = [
    "https://books.toscrape.com/catalogue/a-light-in-the-attic_1000/index.html",
    "https://books.toscrape.com/catalogue/tipping-the-velvet_999/index.html",
    "https://books.toscrape.com/catalogue/soumission_998/index.html",
]
If you need to discover URLs programmatically, Olostep also offers a /v1/searches endpoint for web search and a /v1/maps endpoint for listing all URLs on a domain. Both can feed into a batch job, though they are outside the scope of this guide.
Submitting a batch job
Build the items array from your URL list and submit it. I am using a simple hash of the URL as the custom_id to keep each item unique:
import hashlib

items = [
    {
        "custom_id": hashlib.sha256(url.encode()).hexdigest()[:12],
        "url": url
    }
    for url in target_urls
]

batch_payload = {"items": items}
response = requests.post(
    "https://api.olostep.com/v1/batches",
    json=batch_payload,
    headers=headers
)
response.raise_for_status()
batch_id = response.json()["id"]
print(f"Batch submitted: {batch_id}")
Polling for completion
Batch jobs are asynchronous, so you need to poll the status endpoint until the job finishes. One thing to watch: add a timeout so your script does not hang if something goes wrong:
import time

def wait_for_batch(batch_id: str, timeout: int = 600) -> None:
    """Poll batch status with a timeout guard."""
    deadline = time.time() + timeout
    while time.time() < deadline:
        status_response = requests.get(
            f"https://api.olostep.com/v1/batches/{batch_id}",
            headers=headers
        )
        status_response.raise_for_status()
        status = status_response.json()["status"]

        if status == "completed":
            print("Batch completed.")
            return
        elif status != "in_progress":
            raise RuntimeError(f"Unexpected batch status: {status}")

        time.sleep(30)

    raise TimeoutError(f"Batch {batch_id} did not complete within {timeout}s")

wait_for_batch(batch_id)
I set the default timeout to 600 seconds since that gives enough headroom over the typical completion time I mentioned earlier.
Retrieving and structuring the results
Once the batch is complete, fetch the results. Each item includes a retrieve_id that you pass to the /v1/retrieve endpoint to get the actual content:
import json
import pandas as pd

# Get batch items
items_response = requests.get(
    f"https://api.olostep.com/v1/batches/{batch_id}/items",
    headers=headers
)
items_response.raise_for_status()
batch_items = items_response.json()["items"]

# Retrieve content for each item
results = []
for item in batch_items:
    if not item.get("retrieve_id"):
        print(f"Skipping item with no retrieve_id: {item['custom_id']}")
        continue

    retrieve_response = requests.get(
        "https://api.olostep.com/v1/retrieve",
        params={
            "retrieve_id": item["retrieve_id"],
            "formats": ["markdown"]
        },
        headers=headers
    )
    retrieve_response.raise_for_status()
    content = retrieve_response.json()

    results.append({
        "custom_id": item["custom_id"],
        "url": item["url"],
        "markdown": content.get("markdown_content", "")
    })

# Load into DataFrame and export
df = pd.DataFrame(results)
df.to_csv("scraped_results.csv", index=False)
print(f"Saved {len(df)} results to scraped_results.csv")
Items without a retrieve_id have failed. Olostep does not charge for failed requests, but you still want to log them for review.
Note: For larger batches, the items endpoint returns paginated results. Loop through pages using the
cursorandlimitquery parameters until nocursoris returned. See the Olostep batch documentation for details.
Scheduling and automation
For recurring pipelines, you can schedule this script using standard Python tools. cron is the simplest option for Unix systems. For more control, Apache Airflow or Prefect let you define the pipeline as a DAG with dependency management and monitoring. Olostep also has a /v1/schedules endpoint for recurring scrapes, which means you do not need a separate scheduler.
Working with Structured JSON Output
Extracting raw Markdown or HTML is useful, but many pipelines need structured data: product names, prices, ratings, dates. Olostep’s llm_extract parameter lets you define a JSON schema and get back structured output instead of raw text.
Defining a custom extraction schema
To use structured extraction, add an llm_extract object to your /v1/scrapes request with a schema key. You also need to include "json" in the formats array:
payload = {
    "url_to_scrape": "https://books.toscrape.com/catalogue/a-light-in-the-attic_1000/index.html",
    "formats": ["json"],
    "llm_extract": {
        "schema": {
            "title": {"type": "string"},
            "price": {"type": "string"},
            "availability": {"type": "string"},
            "rating": {"type": "string"}
        }
    }
}

response = requests.post(endpoint, json=payload, headers=headers)
response.raise_for_status()
data = response.json()
The schema is a JSON Schema object where each key defines a field you want extracted, with no CSS selectors or XPath required.
Note: As of this writing, schema-based
llm_extractrequests may return a500 extraction_errordue to a known bug on Olostep’s end. The Olostep team has confirmed the fix will be deployed within 24–36 hours and officially recommends omitting theschemakey in the meantime:"llm_extract": {}. With this workaround, the API auto-extracts the fields it determines are most relevant. The companion GitHub repository uses this approach so the code runs without errors right now. Once the fix is live, you can add theschemakey back to control exactly which fields are returned.
One cost consideration: llm_extract uses 20 credits per request compared to 1 credit for a standard scrape. If you are extracting the same type of data from the same site structure repeatedly, Olostep’s pre-built parsers (available in their Parsers Store) cost only 1 to 5 credits and auto-update when the site changes its layout.
Use case: scraping structured e-commerce data
Here is a practical example that extracts product details and handles the response correctly:
import json
import pandas as pd

response = requests.post(endpoint, json=payload, headers=headers)
response.raise_for_status()
data = response.json()

# json_content is a stringified JSON string, not a dict
raw_json = data["result"]["json_content"]
parsed = json.loads(raw_json)

print(parsed)
# {"title": "A Light in the Attic", "price": "£51.77", ...}

Structured JSON extraction from e-commerce. Image by Author.
The json.loads() step is not optional. If you try to pass raw_json directly to a DataFrame constructor, you will get a TypeError because it is a string, not a dictionary. This trips up many developers the first time they work with this endpoint.
Loading structured output into pandas
Once parsed, the data loads directly into a DataFrame. The simple form works when all fields are flat:
df = pd.DataFrame([parsed])
print(df)
If llm_extract returns nested fields, switch to pd.json_normalize(), which flattens the structure into columns automatically:
df = pd.json_normalize([parsed])
df.to_csv("products.csv", index=False)
When to Still Use Traditional Scraping
Web data APIs are not the right tool for every situation. I want to be honest about the cases where writing your own scraping script makes more sense.
If you are doing a one-time extraction from a simple, static HTML page, a five-line BeautifulSoup script costs nothing and runs in seconds. And if you are working at very low volume against sites with no anti-bot protection, the overhead of setting up API authentication is harder to justify.
Here is a quick comparison to help you decide:
| Scenario | Traditional scraping | Web data API |
|---|---|---|
| One-time, static page | Quick and free | Overkill |
| Recurring production pipeline | Fragile; maintenance-heavy | Fits well |
| JavaScript-heavy pages | Requires headless browser setup | Handled automatically |
| Anti-bot protected sites | Requires proxy management | Handled automatically |
| Over 100 URLs at once | Complex concurrency logic | Single batch request |
| Proof of concept | Good starting point | Free tier covers it |
The decision usually comes down to whether you are building something that runs once or something that runs repeatedly. For one-off jobs, traditional scraping is simpler. For anything you need to maintain, the API approach is easier to keep running.
Best Practices and Common Pitfalls
A few things make the difference between a script that works locally and one that holds up in production. These come from patterns I have seen across scraping and API-based projects.
Respect robots.txt and terms of service. Olostep’s terms put the responsibility for compliance on you. Before scraping any site, check its robots.txt and terms of service. The file is not legally binding everywhere, but ignoring it can lead to IP blocks. GDPR and CCPA requirements apply regardless of how you collect the data.
Store retrieve_id values for content reuse. As I mentioned earlier, every response includes a retrieve_id. If you need the same content in a different format later, call /v1/retrieve with that ID instead of re-scraping. As of this writing, retrieved content is stored for 7 days. Contact Olostep support to verify the current retention policy before relying on long-term availability.
Use country targeting when content varies by location. As I covered earlier, the country parameter routes the request through a residential IP in the region you specify. This matters when the page serves different prices, languages, or product availability depending on geography.
Add retry logic for production pipelines. Network errors and rate limits are inevitable at scale. Instead of wrapping every call in a manual try/except loop, use the tenacity library to add exponential backoff with a decorator:
from tenacity import retry, stop_after_attempt, wait_exponential, retry_if_exception_type
import requests

@retry(
    stop=stop_after_attempt(3),
    wait=wait_exponential(multiplier=1, min=2, max=30),
    retry=retry_if_exception_type(requests.exceptions.RequestException)
)
def scrape_url(url: str) -> dict:
    """Scrape a URL with automatic retry on failure."""
    api_key = os.environ.get("OLOSTEP_API_KEY")
    headers = {"Authorization": f"Bearer {api_key}"}
    payload = {"url_to_scrape": url, "formats": ["markdown"]}
    response = requests.post(
        "https://api.olostep.com/v1/scrapes",
        json=payload,
        headers=headers
    )
    response.raise_for_status()
    return response.json()
This retries up to 3 times with increasing delays (2, 4, 8 seconds) on RequestException subclasses, covering network failures and HTTP 429/5xx errors.
Start with single-page scrapes, then scale to batches. Test your extraction logic on a few URLs through /v1/scrapes before submitting a batch of thousands. This saves credits and helps you catch schema issues early. The Olostep documentation recommends using /v1/scrapes in parallel for fewer than 50 URLs and switching to /v1/batches for anything larger.
Conclusion
Traditional scraping still works for small, one-off tasks, and I do not think it is going away. But for production pipelines, recurring extraction jobs, and anything that needs to handle JavaScript rendering or anti-bot protections at scale, the API approach cuts down on a lot of the infrastructure you would otherwise need to manage.
In this guide, I covered single-page extraction with /v1/scrapes, batch processing with /v1/batches, question-based web queries with /v1/answers, structured JSON extraction with llm_extract, and production patterns for polling, retries, and error handling.
If you want to go further, Olostep’s /v1/crawls endpoint handles full-site crawling with depth and page limits, and works well for ingesting entire documentation sites into RAG knowledge bases.
I am Amit Shekhar, Founder @ Outcome School, I have taught and mentored many developers, and their efforts landed them high-paying tech jobs, helped many tech companies in solving their unique problems, and created many open-source libraries being used by top companies. I am passionate about sharing knowledge through open-source, blogs, and videos.
I teach AI and Machine Learning, and Android at Outcome School.
Join Outcome School and get high paying tech job:
In this blog, we will learn about KV Cache – where K stands for Key and V stands for Value – and why it is used in Large Language Models (LLMs) to speed up text generation.
We will start with how LLMs generate text one token at a time, understand the role of Key, Value, and Query inside the model, see the problem of repeated computation through an example, and then walk through how KV Cache solves this problem by storing and reusing past results.
Let’s get started.
How LLMs Generate Text
Before we understand KV Cache, we first need to understand how LLMs generate text.
An LLM – Large Language Model – is a model that has been trained on a massive amount of text data. It can understand and generate human language. When we give it a sentence, it predicts what comes next.
LLMs generate text one token at a time. A token is a small piece of text – it can be a word, part of a word, or even a single character. For simplicity, let’s treat each word as one token.
Let’s say we give the model this input:
"I love"
The model looks at “I” and “love”, and predicts the next token: “teaching”.
Now the full sequence becomes:
"I love teaching"
The model looks at “I”, “love”, and “teaching”, and predicts the next token: “AI”.
Now the full sequence becomes:
"I love teaching AI"
This process continues, one token at a time, until the model decides to stop.
The important thing to notice here is: every time the model predicts a new token, it needs to look at all the previous tokens to decide what comes next.
What Happens Inside the Model
Now, let’s understand what happens inside the model when it generates each token.
The model has a component called the attention layer. The job of the attention layer is to help the model figure out which previous tokens are important for predicting the next token. Not all previous tokens are equally useful. Some matter more than others.
Inside the attention layer, every token is converted into three things. Let’s understand each of them with a simple analogy.
Imagine a classroom where a new student joins and wants to find out who can help with a specific topic:
So, the current token uses its Query to compare against the Keys of all previous tokens. This comparison produces attention scores – numbers that tell the model how much focus to give to each previous token. A higher score means that token is more relevant. A lower score means it is less relevant. The model then uses these scores to collect the Values from the relevant tokens.
This is how the attention layer works.
Now, let’s see the problem.
The Problem: Repeated Computation
Every time the model predicts the next token, it computes the Key, Value, and Query for all tokens in the sequence – not just the new one.
Let’s see what happens step by step with our example:
Step 1: Input is “I love”
The model computes Key, Value, and Query for:
It uses these to predict the next token: “teaching”.
Step 2: Input is “I love teaching”
The model computes Key, Value, and Query for:
It uses these to predict the next token: “AI”.
Step 3: Input is “I love teaching AI”
The model computes Key, Value, and Query for:
Do you see the problem?
The Key and Value for “I” were computed in Step 1. But the model computes them again in Step 2, and again in Step 3. The same goes for “love” and “teaching”.
The model is repeating the same work for tokens it has already seen. This is wasted computation.
As the sequence grows longer, this problem gets worse. If the model has already generated 100 tokens, then at the next step, it would recompute the Key and Value for all 100 previous tokens just to predict one new token. This makes text generation very slow.
The Solution: KV Cache
The idea behind KV Cache is simple: compute the Key and Value for each token once, store them, and reuse them in every future step.
Think of it like taking notes. Imagine you are in a meeting. Every time someone new speaks, instead of asking all the previous speakers to repeat what they said, you simply read from your notes and only listen to the new speaker. The notes are your cache.
Similarly, KV Cache is a memory where we save the Key and Value of every token that has already been processed. This way, the model does not have to compute them again.
Let’s see how the same example works with KV Cache:
Step 1: Input is “I love”
The model computes Key, Value, and Query for:
It saves the Key and Value of “I” and “love” in the KV Cache.
It uses these to predict the next token: “teaching”.
KV Cache now contains: Key and Value for “I”, “love”
Step 2: Input is only “teaching” (only the new token)
The model retrieves the Key and Value of “I” and “love” from the KV Cache. No recomputation needed.
It computes Key, Value, and Query only for the new token: “teaching”.
It saves the Key and Value of “teaching” in the KV Cache.
It uses all of these together to predict the next token: “AI”.
KV Cache now contains: Key and Value for “I”, “love”, “teaching”
Step 3: Input is only “AI” (only the new token)
The model retrieves the Key and Value of “I”, “love”, and “teaching” from the KV Cache. No recomputation needed.
It computes Key, Value, and Query only for the new token: “AI”.
It saves the Key and Value of “AI” in the KV Cache.
KV Cache now contains: Key and Value for “I”, “love”, “teaching”, “AI”
So, instead of recomputing the Key and Value for every token at every step, the model computes them only for the new token and reuses the cached values for all previous tokens.
This is how KV Cache avoids repeated computation.
Why Only Key and Value Are Cached, Not Query
You would naturally ask: why do we cache only the Key and Value, and not the Query?
The Query is only needed for the current token – the one being generated right now. The current token uses its Query to compare against the Keys of all previous tokens to find which ones are relevant. Once the prediction is done, that Query is no longer needed.
But the Key and Value of every past token are needed at every future step, because every new token must look at all the previous tokens to make its prediction.
So, we only need to store the Keys and Values. This is why it is called KV Cache – it caches the Keys and Values.
How Much Faster Does It Get
Let’s compare the two approaches side by side:
Without KV Cache:
Step 1: Compute K, V, Q for 2 tokens
Step 2: Compute K, V, Q for 3 tokens  (2 recomputed)
Step 3: Compute K, V, Q for 4 tokens  (3 recomputed)
Step 4: Compute K, V, Q for 5 tokens  (4 recomputed)
...
Step N: Compute K, V, Q for (N+1) tokens  (N recomputed)
The amount of computation keeps growing at every step.
With KV Cache:
Step 1: Compute K, V, Q for 2 tokens → Save K, V for 2 tokens in cache
Step 2: Compute K, V, Q for 1 token  → Reuse K, V for 2 tokens from cache
Step 3: Compute K, V, Q for 1 token  → Reuse K, V for 3 tokens from cache
Step 4: Compute K, V, Q for 1 token  → Reuse K, V for 4 tokens from cache
...
Step N: Compute K, V, Q for 1 token  → Reuse K, V for N tokens from cache
After the first step, the model computes only for one new token at each step instead of the entire sequence.
To put this into perspective: if the model is generating a sequence of 100 tokens, without KV Cache, the total number of Key and Value computations across all steps would be 2 + 3 + 4 + … + 100 = 5,049 computations. With KV Cache, it would be 2 + 1 + 1 + … + 1 = 101 computations. That is roughly 50 times fewer computations. The longer the sequence, the bigger the savings.
This is what makes KV Cache so effective at speeding up text generation.
The Trade-Off: Speed vs Memory
KV Cache makes generation faster, but it comes with a trade-off: it uses extra memory to store all the Key and Value information for every token that has been generated so far.
As the sequence gets longer, the cache grows larger. For very long sequences with thousands of tokens, the cache can consume a significant amount of memory.
So, KV Cache is a trade-off: we use more memory to save computation time. For most use cases, this trade-off is well worth it, as the speed improvement is significant.
Now, we have understood the KV Cache in LLMs.
In the next blog, we will learn about Paged Attention that solves the memory issue of KV Cache.
Prepare yourself for AI Engineering Interview: AI Engineering Interview Questions
That’s it for now.
Thanks
Amit Shekhar
Founder @ Outcome School
You can connect with me on:
Follow Outcome School on:
A lot of system design content looks impressive… until you actually try to build it.
I’ve seen architectures that look clean on paper but fall apart the moment real traffic hits.
So instead of theory, I decided to break things down from a builder’s perspective:
What does it actually take to build a scalable, Netflix-style system on AWS?
Let’s get into it—no fluff.
🧱 1. The Real Architecture (Not Just Diagrams)
At a high level, your system should look like this:
Users → CloudFront → API Gateway → Load Balancer → Microservices (EKS/ECS)
→ Cache (Redis) → Databases (RDS/DynamoDB)
→ Monitoring (CloudWatch + Prometheus)
When I first started designing systems like this, I underestimated how important each layer is. Skip one, and everything downstream suffers.
🌐 2. CDN + API Gateway: Your First Line of Defense
Before your backend even sees traffic:
CloudFront handles global content delivery
API Gateway manages routing, throttling, and security
Why this matters:
If you don’t control traffic at the edge:
👉 Your backend gets overwhelmed fast
Real talk—I’ve seen setups where skipping proper API management led to unnecessary load and higher costs.
⚖️ 3. Load Balancer: Keep Things Even
Use:
Application Load Balancer (ALB)
Incoming Traffic → ALB → Multiple Service Instances
This is what prevents:
One server from getting slammed
Others sitting idle
If your traffic distribution isn’t balanced, scaling won’t save you.
🧩 4. Microservices (This Is Where Complexity Starts)
Breaking a system into services sounds nice… until you manage them.
Example services:
User Service
Recommendation Service
Content Metadata Service
Deployment example:
apiVersion: apps/v1
kind: Deployment
metadata:
name: recommendation-service
spec:
replicas: 3
selector:
matchLabels:
app: recommendation
template:
metadata:
labels:
app: recommendation
spec:
containers:
– name: app
image: your-docker-image
ports:
– containerPort: 80
In one of my deployments, increasing replicas alone handled a traffic spike without touching the core logic.
That’s the power of proper separation.
⚡ 5. Caching (This Will Save You)
Let me be blunt:
If you skip caching, your database becomes your bottleneck.
Use:
Amazon ElastiCache (Redis)
Flow:
Request → Cache → (miss) → DB → Cache → Response
I ran into this early—DB latency started creeping up under load.
Adding Redis reduced response times instantly.
🧠 6. Database Strategy: One Size Doesn’t Work
Don’t rely on a single database.
Use a mix:
Use Case Service
User data RDS (PostgreSQL)
High scale reads DynamoDB
Logs/events S3
👉 SQL for consistency
👉 NoSQL for scale
If your DB can’t scale independently, your entire system is fragile.
🔄 7. Auto Scaling: Handle Traffic Without Panic
Set scaling rules based on:
CPU usage
Request count
Latency
Example:
CPU > 70% → Scale up
CPU < 30% → Scale down
This is what keeps your system alive during spikes.
Without it, you’re just hoping traffic stays low.
📊 8. Observability: Don’t Fly Blind
Use:
CloudWatch → logs & metrics
Prometheus + Grafana → deeper insights
Track:
Response time
Error rates
Throughput
From experience, debugging without proper monitoring is chaos.
You’ll waste time guessing instead of fixing.
🧬 9. Resilience: Design for Failure
At scale:
Things WILL break.
So, prepare:
Retry logic
Circuit breakers
Fallback responses
If one service fails:
👉 Your system should degrade gracefully—not crash.
🔥 Real Scenario
Let’s say:
A new feature drop
Traffic spikes 10x
Here’s what happens in a well-built system:
CloudFront absorbs global traffic
API Gateway controls request flow
ALB distributes load
Auto-scaling spins up more instances
Redis serves cached data
Databases stay stable
👉 No downtime
👉 No panic
💥 Where Most People Get It Wrong
Let’s be honest:
Overcomplicating too early
Ignoring caching
Relying on one database
No monitoring
No scaling strategy
I’ve seen systems that looked “advanced” but failed under basic load.
Complex ≠ scalable.
🧠 Key Takeaways
Control traffic at the edge
Scale horizontally
Cache aggressively
Use the right database for the job
Monitor everything
Expect failure
⚡ Final Thought
You don’t need Netflix-scale systems on day one.
But if you build without thinking about scale:
You’ll rebuild everything later.
🔥 Follow My Journey
I’m building AI systems, telecom infrastructure, and scalable platforms—and sharing what actually works (and what doesn’t).
If you’re into real-world engineering, not just theory, follow me for more.
zeed_xo.