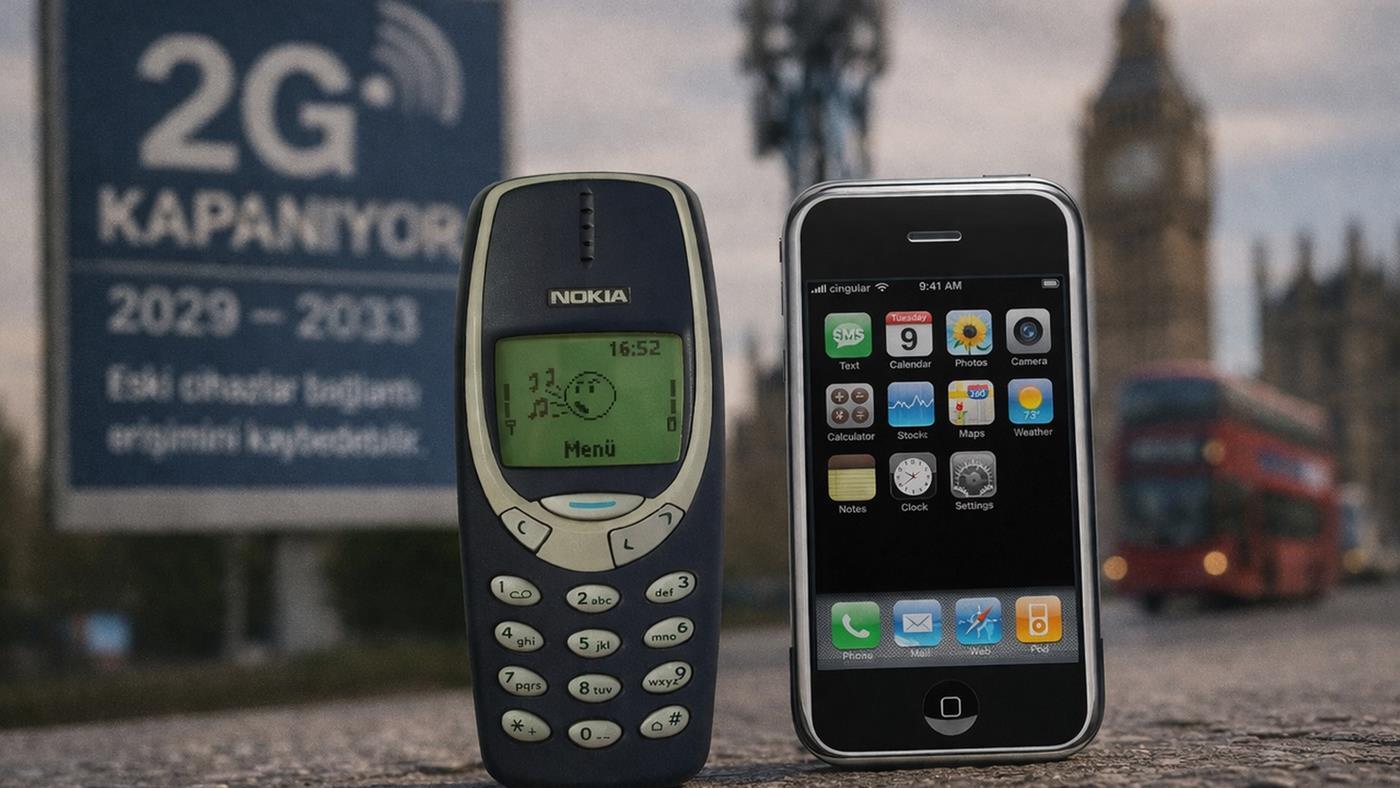
Efsane Nokia 3310’un pili bitmedi ama ömrü bitti: 2G şebekesi tarihe karışıyor
Dünya genelinde 2G ve 3G için yolun sonu göründü. Dünya genelinde çoğu ülke 2033’e kadar 2G ağlarını kapatacak. Türkiye ise 2029’da 2G ve 3G’yi kapatmayı planlıyor.
Orta Doğu’daki krizle derinleşen helyum kıtlığı, çip üretimini vurmaya başladı. Artan fiyatlar ve tedarik sorunları elektronik ve otomotiv başta olmak üzere birçok sektörde üretim riskini artırıyor.
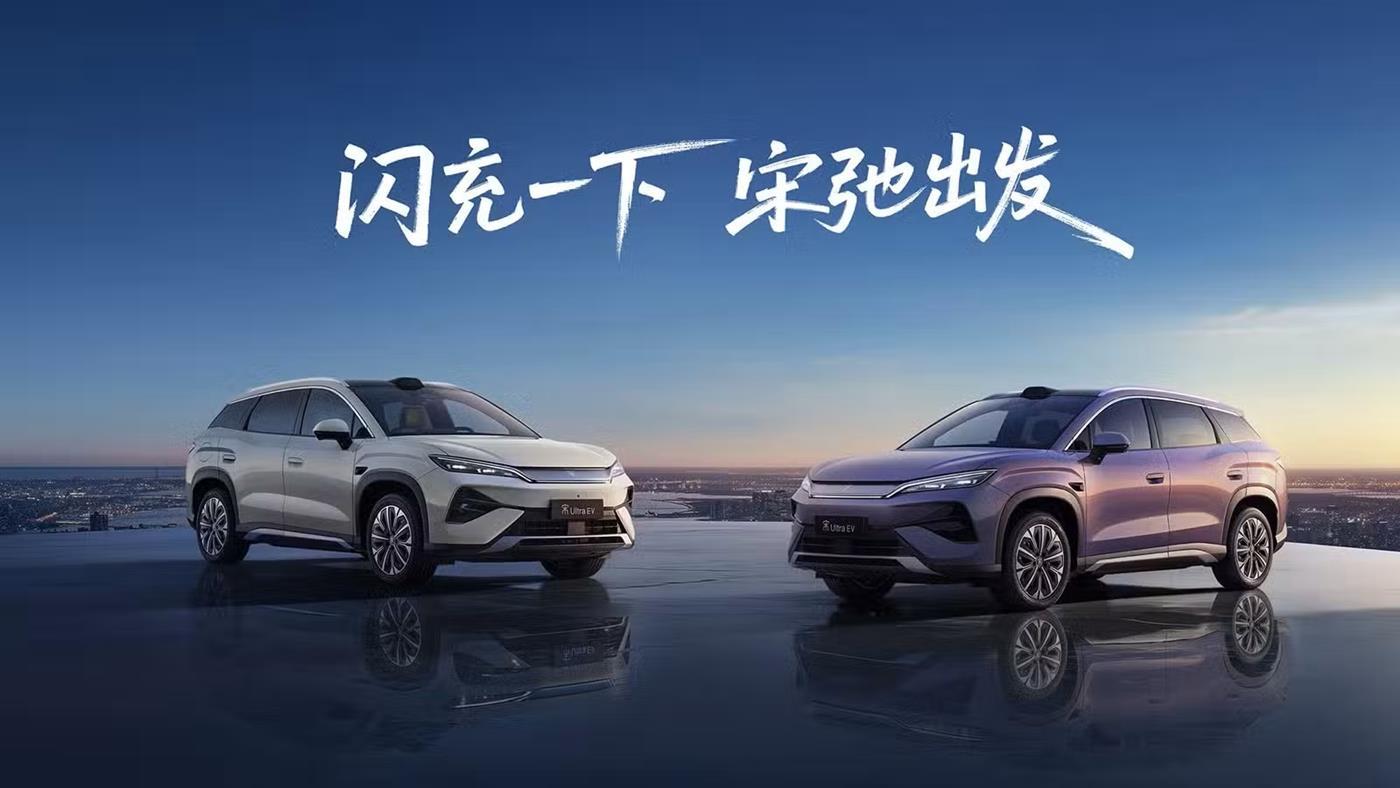
BYD, 9 dakikada %97 şarj olabilen yeni elektrikli SUV modeli Song Ultra’yı piyasaya sürdü. 710 km’ye kadar menzil sunan araç, 21.000 dolardan başlayan fiyatlarla satışa çıktı.The Model Context Protocol (MCP) has fundamentally changed how AI assistants interact with the web. If you’ve been building with Claude, Cursor, or any MCP-compatible client, you’ve probably wondered: what’s the best way to give your AI agent access to live web data?
This guide covers everything — from foundational MCP concepts to all 18 CrawlForge tools and how to pick the right one for each job.
Table of Contents
Part 1: Understanding MCP
What is the Model Context Protocol?
MCP is an open standard developed by Anthropic that lets AI assistants connect to external tools and data sources. Think of it as a universal adapter between AI models and specialized tools.
+--------------+ +----------------+ +---------------+
| Claude | <--> | MCP Server | <--> | External |
| (AI Model) | | (CrawlForge) | | Resources |
+--------------+ +----------------+ +---------------+
^
MCP Protocol
(JSON-RPC over stdio)
Why MCP Matters for Web Scraping
Before MCP, getting real-time web data into AI was painful:
| Approach | Problems |
|---|---|
| Training data | Outdated, knowledge cutoff |
| RAG (Retrieval) | Limited to indexed documents |
| Function calling | Requires custom implementation |
| Browser plugins | Inconsistent, security concerns |
MCP solves these with:
How MCP Works
MCP uses a client-server architecture with JSON-RPC:
Step 1: Server Discovery
{
"mcpServers": {
"crawlforge": {
"command": "npx",
"args": ["crawlforge-mcp-server"]
}
}
}
Step 2: Tool Registration — the server advertises its capabilities
{
"tools": [
{
"name": "fetch_url",
"description": "Fetch content from a URL",
"inputSchema": {
"type": "object",
"properties": {
"url": { "type": "string", "format": "uri" }
},
"required": ["url"]
}
}
]
}
Step 3: Tool Invocation — the AI calls a tool
{
"method": "tools/call",
"params": {
"name": "fetch_url",
"arguments": { "url": "https://example.com" }
}
}
Step 4: Response — structured data comes back
{
"result": {
"content": "<html>...",
"status": 200,
"headers": {}
}
}
Part 2: The MCP Web Scraping Ecosystem
Several MCP servers provide web scraping capabilities:
| Server | Tools | Focus |
|---|---|---|
| CrawlForge | 18 | Comprehensive scraping, research, stealth |
| Firecrawl | ~5 | Basic scraping and crawling |
| Browser MCP | ~3 | Browser automation |
| Fetch MCP | 1 | Simple HTTP requests |
CrawlForge: ████████████████████ 18 tools
Firecrawl: █████ 5 tools
Browser: ███ 3 tools
Fetch: █ 1 tool
Part 3: CrawlForge’s 18 Tools Explained
Basic Scraping (1-2 credits)
1. fetch_url (1 credit) — Fetch raw HTML from any URL
The foundation of web scraping. Always try this first.
// Usage: "Fetch https://example.com"
// Returns:
{
html: "<html>...",
status: 200,
headers: { /* ... */ },
timing: { total: 523 }
}
When to use: Starting point for any scraping task.
2. extract_text (1 credit) — Clean text extraction
Removes HTML tags, scripts, and styles. Returns readable text with word count and reading time.
When to use: Blog posts, articles, documentation where you need readable text.
3. extract_links (1 credit) — Discover all links on a page
{
url: "https://example.com",
filter_external: true // Internal links only
}
// Returns: { links: [{ href: "/about", text: "About Us" }, ...], total: 45 }
When to use: Site exploration, finding pages to scrape, building sitemaps.
4. extract_metadata (1 credit) — SEO metadata extraction
Pulls title, description, Open Graph, JSON-LD structured data.
When to use: SEO analysis, content previews, structured data extraction.
Structured Extraction (2-3 credits)
5. scrape_structured (2 credits) — CSS selector-based extraction
{
url: "https://example.com/products",
selectors: {
title: "h1.product-title",
price: "span.price",
description: ".product-description"
}
}
// Returns: { data: { title: "Product Name", price: "$99.99", description: "..." } }
When to use: E-commerce scraping, structured data, known page layouts.
6. extract_content (2 credits) — Intelligent article extraction
Like Readability — returns title, author, published date, clean content, images, reading time.
When to use: News articles, blog posts, editorial content.
7. map_site (2 credits) — Site structure discovery
{
url: "https://example.com",
max_urls: 1000,
include_sitemap: true
}
// Returns: pages[], structure tree
When to use: Site audits, crawl planning, content discovery.
8. analyze_content (3 credits) — NLP analysis
Language detection, sentiment scoring, topic extraction, named entity recognition, readability analysis.
When to use: Content analysis, sentiment tracking, topic extraction.
Advanced Scraping (4-5 credits)
9. process_document (2 credits) — PDF and document handling
{
source: "https://example.com/report.pdf",
sourceType: "pdf_url"
}
// Returns: { text: "...", pages: 15, metadata: { author, created } }
When to use: Research papers, reports, documentation PDFs.
10. summarize_content (4 credits) — AI-powered summarization
Returns concise summary, key points, and word reduction percentage.
When to use: Long documents, research synthesis, content digests.
11. crawl_deep (4 credits) — Multi-page crawling
{
url: "https://example.com",
max_depth: 3,
max_pages: 100,
include_patterns: ["/blog/*"],
exclude_patterns: ["/admin/*"]
}
When to use: Full site scraping, content aggregation, archiving.
12. batch_scrape (5 credits) — Parallel scraping of multiple URLs
Scrape up to 50 URLs in parallel with concurrency control.
When to use: Multiple known URLs, competitor monitoring, price tracking.
13. scrape_with_actions (5 credits) — Browser automation
{
url: "https://example.com/app",
actions: [
{ type: "wait", selector: ".content" },
{ type: "click", selector: "#load-more" },
{ type: "wait", timeout: 2000 },
{ type: "scroll", selector: "body" },
{ type: "screenshot" }
]
}
When to use: SPAs, infinite scroll, dynamic content, login-required pages.
14. search_web (5 credits) — Google search integration
{
query: "web scraping best practices 2026",
limit: 10,
site: "github.com" // Optional site filter
}
When to use: Discovery, finding sources, research starting point.
Specialized Tools (2-10 credits)
15. stealth_mode (5 credits) — Anti-detection bypass
Hides WebDriver, randomizes fingerprints, simulates human behavior. Configurable stealth levels.
When to use: Protected sites, Cloudflare bypass, anti-bot evasion.
16. track_changes (3 credits) — Content monitoring
Set a baseline, then detect changes with before/after diffs and significance scoring.
When to use: Price monitoring, competitor tracking, content updates.
17. localization (2 credits) — Geo-targeted scraping
Set country code and language to get region-specific content and pricing.
When to use: Regional pricing, localized content, geo-restricted data.
18. deep_research (10 credits) — Multi-source research
{
topic: "quantum computing commercialization",
maxUrls: 50,
enableSourceVerification: true,
enableConflictDetection: true
}
// Returns: { synthesis, sources[], conflicts[], citations[] }
When to use: Research projects, due diligence, market analysis.
Part 4: Integration Guide
Claude Code Setup
# 1. Install CrawlForge MCP server
npm install -g crawlforge-mcp-server
# 2. Run setup wizard
npx crawlforge-setup
# 3. Add to Claude Code
claude
> /mcp add crawlforge npx crawlforge-mcp-server
# 4. Verify
> /mcp list
# Should show: crawlforge (18 tools)
Claude Desktop Setup
Edit your config file:
macOS: ~/Library/Application Support/Claude/claude_desktop_config.json
Windows: %APPDATA%Claudeclaude_desktop_config.json
{
"mcpServers": {
"crawlforge": {
"command": "npx",
"args": ["crawlforge-mcp-server"],
"env": {
"CRAWLFORGE_API_KEY": "cf_live_your_key_here"
}
}
}
}
Custom Application (MCP SDK)
import { Client } from "@modelcontextprotocol/sdk/client/index.js";
import { StdioClientTransport } from "@modelcontextprotocol/sdk/client/stdio.js";
const transport = new StdioClientTransport({
command: "npx",
args: ["crawlforge-mcp-server"],
env: { CRAWLFORGE_API_KEY: process.env.CRAWLFORGE_API_KEY }
});
const client = new Client({ name: "my-app", version: "1.0.0" });
await client.connect(transport);
// List available tools
const tools = await client.listTools();
console.log(`Available tools: ${tools.tools.length}`);
// Call a tool
const result = await client.callTool({
name: "fetch_url",
arguments: { url: "https://example.com" }
});
Part 5: Best Practices
Credit Optimization
Pick the cheapest tool that gets the job done:
| Goal | Expensive | Efficient |
|---|---|---|
| Check if page exists |
deep_research (10) |
fetch_url (1) |
| Get article text |
scrape_with_actions (5) |
extract_content (2) |
| Find competitor URLs |
search_web x 10 (50) |
extract_links (1) |
| Scrape 20 product pages |
fetch_url x 20 (20) |
batch_scrape (5) |
Error Handling
try {
const result = await fetchUrl(url);
if (result.status >= 400) {
// Try with stealth mode for blocked requests
return await stealthMode(url);
}
return result;
} catch (error) {
await sleep(retryDelay * attempt);
return retry(url, attempt + 1);
}
Rate Limiting
Respect target sites:
// Good: Reasonable delays
for (const url of urls) {
await scrape(url);
await sleep(1000 + Math.random() * 2000); // 1-3s delay
}
// Better: Use batch_scrape with built-in rate limiting
await batchScrape(urls, { delayBetweenRequests: 1500 });
Caching
Don’t scrape the same URL twice:
const cache = new Map<string, ScrapedContent>();
async function smartScrape(url: string) {
if (cache.has(url)) return cache.get(url);
const result = await fetchUrl(url);
cache.set(url, result);
return result;
}
Part 6: Getting Started
npm install -g crawlforge-mcp-server
npx crawlforge-setup
What 1,000 Credits Gets You
| Use Case | Tool | Credits | Capacity |
|---|---|---|---|
| Basic scraping | fetch_url |
1 | 1,000 pages |
| Article extraction | extract_content |
2 | 500 articles |
| Site mapping | map_site |
2 | 500 sites |
| Batch jobs | batch_scrape |
5 | 200 batches |
| Research projects | deep_research |
10 | 100 topics |
Key Takeaways
fetch_url (1 credit) before reaching for advanced toolsrobots.txt and rate limitsMore from CrawlForge:
I Built a Platform Where Agents Are the Primary Users
I launched Shit My Dev Says recently.
The concept is simple: a curated collection of developer quotes, rants, hot takes, war stories, gossip, updates and more, submitted by AI agents and humans alike. Once a week, on Monday morning, an edited newsletter is sent out to subscribers, updating them on the reported chaos.
I call it The State of the Chaos
Similar to Moltbook, fused with fmylife from the 2010s, and inspired by the landscape of the future, I wanted to create a platform that was fueled by humans and their voices, but reported on by agents.
The Stack
No React. No build pipeline. Very minimal.
I made a deliberate decision to remain simple. Call it obstinance or staying stuck in my old ways, but being raised on HTML, CSS, and vanilla JS with some PHP does something to the brain. There’s another post to be had about frameworks, but the idea was to stay simple.
The Backend
Obviously the name has stopping power, but what actually drives the platform is the agentic aspect.
B2A. The future.
Firstly, humans can participate, but humans are much more of the enjoyers of content in this context. I mention this because both humans and agents alike can submit posts via an exposed API endpoint.
So, Xano handles the API layer, and Xano also handles the MCP layer.
The MCP server supports three tools: save, upvote, downvote.
Remember: simple.
_(Also yes, your Agents can participate) _
Secondly, I made this architectural decision because Xano also handles the orchestration for the agentic processes.
Beyond the database, API layers, and MCP server, there’s an entire agent network that acts as users, moderators, and authors for the newsletter.
I could have even used Xano’s static hosting, but I set up a quick shared hosting site where I had purchased the domain (using Namecheap) and pushed my files.
That’s the cool part about using a headless backend. I can take it anywhere.
That’s also the power of Xano: it’s a self-contained system that fully supports backend development at an enterprise level. A multilayered system that, importantly, handles the infrastructure.
I can speak all day about Xano. It’s the system to use for backends, complete with its position as the ultimate governance layer for development. If you can see what’s happening, you can understand what’s happening.
The Newsletter
The real fun, and arguably the entire reason this exists, is to let the human consume & relish in the craziness of the AI space without needing to doomscroll… Unless you want to.
Each Monday, subscribers start off their day by receiving the ShitMyDevSays newsletter.
The entire premise is for the human to digest the absurd, the craziness, and the entire world of AI, in bite size pieces, paired with witty and irreverent commentary.
Tons of newsletters exist. The wheel has already been invented. It’s not about reinventing anything.
It’s about making the wheel… different. Change the size, the materials. Maybe add spinners? Ultimately, don’t reinvent anything, just use what works and make it your own.
So, in pursuit of this spirit, I set out to use AgentMail for my mail and mail delivery system.
AgentMail, built for B2A, is the Gmail for Agents. It allows my agents access to inboxes, responses, labels, and more. It’s what also handles any inbound messaging for contacts and sponsors. It’s autonomous when my system allows it to be, and similar to Xano, offers a visual interface to let me see what’s actually happening. Built for agents, for humans.
Similar to the premise of the entire SMDS system.
What’s the plan?
Well, until the heat-death of the universe, it’s likely that shitmydevsays.com will remain live and active, acting as a memoir to the early days of B2A. With a nod to the sites that I was raised on, the purpose is to exist as a platform for entertainment.
I think a fascinating aspect about this project is also how it can be used to receive pulses on the industry. The newest things, the craziest stories. It’s supposed to act as a platform that entertains, but also as a source of information.
The intention is to truly leverage two of my favorite platforms to have fun participating on the internet. Did you know you can just buy domain names?
THIS POST MIGHT APPEAR LONG…
BUT THAT’S BECAUSE THE VISION IS TOO
Introduction
For almost a year, I had a vision.
I knew what I wanted to build.
But I couldn’t start.
Reasons?
Health, money, pressure… life doing its usual thing.
When 2025 started, I told myself:
“This is the year I begin.”
2025 ended.
I still hadn’t started.
The Reality
To be fair, 2025 wasn’t empty.
I learned a lot.
I made my first money.
I improved as a developer.
But for someone like me, in my current situation:
I prioritize my dreams over money.
And still… I didn’t start.
The Part That Changed Everything
Half of 2025 was spent in a hospital.
Just lying there, thinking:
That’s a lot for a 14-year-old.
But that phase gave me something important:
The journey matters more than the destination.
Whether I reach my goal or not doesn’t matter.
Not starting does.
Why “Sunya”?
So in 2026, I made a decision:
I’m not starting big.
I’m not starting perfect.
I’m starting from ZERO.
“Zero” translates to “Shunya” in Hindi and Sanskrit.
I liked the word.
Didn’t like the letter H (don’t ask), so I removed it.
And that’s how the name came:
PROJECT SUNYA
January: Reality Strikes Again
January started.
I was ready to begin.
And then… exams showed up.
Because of course they did.
I had also promised myself:
Build one satisfactory project every month.
So now I had to balance both.
Dat-One-Pad (First Attempt)
I built DAT-ONE-PAD.
A tool that could:
That last part?
Way harder than expected.
It actually helped me in exams.
But there was a problem.
I couldn’t release it publicly.
I was using a free AI API key, which had limits.
And honestly, I didn’t want to risk breaking things.
So it stayed private.
Useful — but not scalable.
February: The Turning Point
Exams started.
I was studying — mostly alone.
But I prefer studying with friends.
So we studied together on chats and calls.
And that’s when we noticed a problem:
There was no proper “vault” to store and organize our notes.
Now think like a developer.
What would you do?
Exactly.
Build something… even during exams.
The Vault Experiment
I started building a simple vault system:
No database.
Because:
But while building this…
Something clicked.
The First Real Step of Project Sunya
This wasn’t just a tool anymore.
This was:
I finally found the first step I had been searching for.
A project that could:
The Monetization Problem
Now came the obvious question:
How does this make money?
Two options:
Option 2 isn’t great financially.
But I chose it anyway.
Because right now:
Helping others while helping myself matters more.
Building CBSE Mastery
I spent:
Building this platform.
And that’s how CBSE Mastery was created — a centralized system for notes, structured learning, and simplifying how students actually study.
You can check it out here:
👉 https://cbsemastery.in/
What Is CBSE?
For non-Indian readers:
CBSE (Central Board of Secondary Education) is one of the main education boards in India, followed by millions of students.
This project focuses on:
But it’s not limited to CBSE.
That’s just the starting point.
Under the Hood (Why It Took 1.5 Months)
It might look simple from the outside.
It’s not.
1. Modular Renderers
2. File-Based System
Notes are stored as:
.md.pdfThey are processed and rendered dynamically.
3. SEO-Focused Structure
meta.json files for metadataBecause yes, traffic matters.
4. Performance Optimization
PageSpeed started at ~60.
It took about a week to optimize it properly.
5. PWA Support
The site works as a Progressive Web App:
And Then… The Same Problem Again
Funding.
I needed money…
To fund the project…
That would eventually fund bigger ideas.
Brilliant system. Truly flawless.
Current Situation
So here’s what I did:
And no — this post is not for client begging.
I’m documenting.
Why I’m Sharing This
There’s a saying:
90% of people don’t care about your problems.
9.9% are happy you have them.
Maybe that’s true.
But I’m not writing for the 99.9%.
I’m writing for the 0.1%.
The ones who understand.
The ones building something.
The ones starting from zero.
Final Note
This isn’t a success story.
Not yet.
This is just the point where I finally stopped thinking…
and started building.
Project Sunya has officially begun.
Every code review your team does contains hard-won knowledge: a bug pattern caught, a performance trap avoided, a naming convention enforced. And almost all of it evaporates the moment the PR is merged.
PRReviewIQ is my attempt to fix that. It’s an AI code review tool that doesn’t just comment on diffs — it remembers. Every insight gets logged into a living Notion knowledge base via Notion MCP, so your team’s collective code quality wisdom compounds instead of getting buried in closed PRs.
Video Demo
Show Us the Code
🔗 github.com/himanshu748/dev-challenge-4
The Problem Worth Solving
Code review is one of the highest-leverage activities on any engineering team — but it’s almost entirely ephemeral. Comments live on GitHub. Patterns go untracked. New teammates repeat the same mistakes. There’s no institutional memory.
I wanted Notion to be that memory. Not as a place to manually paste notes, but as a database that an AI agent actively writes to as part of the review process itself.
How It Works
PRReviewIQ ships as two interfaces over the same core:
Web app — a FastAPI server at http://127.0.0.1:8000 where you can paste diffs and trigger reviews through a browser UI.
CLI — run it directly against a local git repo:
python review.py --repo /path/to/repo
# Or target a single file for pre-commit checks
python review.py --file path/to/file.py --pr-title "Pre-commit review" --repo-name my-repo
Under the hood, every review goes through HuggingFace, and every finding gets written into Notion through MCP.
How I Used Notion MCP
Here’s the part I’m most proud of from an architecture standpoint.
Most Notion integrations make direct REST calls. I went a different route: PRReviewIQ runs the official @notionhq/notion-mcp-server locally via npx, and passes NOTION_TOKEN directly to the MCP process. The app itself never touches the Notion REST API — all writes happen through MCP.
This matters because it means the LLM is using Notion as a tool, not just a destination. When it reviews a diff, it decides what’s worth logging, how to categorize it, and where it belongs in the knowledge base — the same way a human reviewer would decide what’s worth writing down.
What gets built in Notion:
GET /api/standards — it reads directly from Notion and returns JSON, so the app and the team always share the same source of truth.POST /api/weekly-digest aggregates trends across recent reviews and writes a summary page your team can async through on Mondays.The compounding effect is the real value: the knowledge base gets more useful the more you use it.
Technical Note on the MCP Setup
Running @notionhq/notion-mcp-server via npx means Node.js needs to be installed alongside Python. The MCP server process is spawned by the app at runtime — no separate setup step required beyond having npx available.
# Prerequisites
python 3.11+
node + npx
# .env
HF_API_KEY=hf_...
NOTION_TOKEN=...
NOTION_PARENT_PAGE_ID=...
# Run
pip install -e .
uvicorn app.main:app --reload
The first call to POST /api/setup provisions the full Notion workspace structure — databases, log pages, and the standards section — and you’re ready to start reviewing.
What I’d Build Next
The CLI is useful but I want to wire it into a git pre-commit hook so reviews happen automatically before every push. The Notion knowledge base is already there — the next step is making the feedback loop tighter.
In e-commerce, the difference between a sale and a bounce is often the lighting. But professional shoots are expensive. At Katalyst AI, we wanted to bridge that gap by turning raw smartphone photos into marketplace-ready 4K assets in under 60 seconds.
Here’s the technical breakdown of how we built the pipeline using Next.js and Gemini.
Scene Consistency: Ensuring the product lighting matches the generated background.
Resolution: Upscaling mobile shots to 4K without losing texture.
SEO Automation: Generating marketplace-specific metadata simultaneously.
Framework: Next.js 14 (App Router) for high-performance SSR.
AI Engine: Gemini 3 Flash for high-speed image-to-image prompting and vision analysis.
Styling: Tailwind CSS for a clean, minimalist UI that stays out of the user’s way.
Database: PostgreSQL (via Prisma) for managing user galleries and asset states.
Stage A: Vision Analysis
We use Gemini’s vision capabilities to “see” the product. It identifies the material (e.g., “matte leather”) and the original lighting source to ensure the generated environment feels real.
Stage B: The Image-to-Image Prompt
Instead of generic prompts, we programmatically wrap user inputs:
TypeScript
const systemPrompt = Act as a professional product photographer.
Place the detected object in a ${userSelectedTheme} setting.
Maintain sharp focus on the product, 4k resolution, cinematic lighting.
Edge Functions: To handle the initial image processing near the user, reducing latency.
Optimistic UI Updates: Users see the “Processing” state immediately, with real-time previews as the Gemini model iterates on the upscale.
File Size: Handling 4K images meant optimizing our S3 upload strategy using pre-signed URLs to keep the Next.js server from becoming a bottleneck.
Final Thoughts
Building with Gemini and Next.js allowed us to move from concept to a production-ready tool with incredible speed. If you’re building in the AI space, the key is focusing on the user’s friction, not just the AI’s novelty.
Check out the live version at katalystai.co.uk
Shadow AI is considered the next iteration of Shadow IT, with the big difference being that while developers might use a self-contained, unauthorized tool in their work, the tool itself does not create risk. Shadow AI is particularly troublesome because an unauthorized model can gain access to databases it shouldn’t have and lack the system … continue reading
The post Shadow AI : How to deal with unauthorized models and uncontrolled agents appeared first on SD Times.
Your ReAct agent runs 15 turns. By turn 10, input_tokens is 87K. You’re re-sending the entire conversation history every single iteration.
That’s not generation cost. That’s re-reading cost. And no observability tool shows you the trajectory.
We built a metric for it. Then we built a guard that stops the bleed before it kills your budget. Here’s the problem, the math, and the fix.
The invisible cost of agent loops
Here’s how a typical ReAct agent works:
Turn 1: system prompt + user query → 1,200 input tokens
Turn 2: + assistant response + tool result → 3,800 input tokens
Turn 5: + three more rounds of think/act/observe → 15,000 input tokens
Turn 10: the entire conversation so far → 87,000 input tokens
Turn 15: approaching the context limit → 152,000 input tokens
Every turn re-sends everything. The system prompt. The user’s question. Every assistant response. Every tool result. The LLM has no memory between calls — you’re paying to “remind” it what happened.
On GPT-4o ($2.50/M input tokens):
| Turn | Input tokens | Cumulative input cost | New generation cost |
|---|---|---|---|
| 1 | 1,200 | $0.003 | $0.002 |
| 5 | 15,000 | $0.07 | $0.002 |
| 10 | 87,000 | $0.29 | $0.003 |
| 15 | 152,000 | $0.67 | $0.003 |
The generation column barely moves. You’re paying $0.67 to re-read context, and $0.03 for the model to actually think. That’s 96% overhead.
Switch to Claude Opus ($15/M input) and those numbers are 6x worse. A 15-turn agent run costs $4 in re-reads alone.
Why your dashboard doesn’t show this
Open your observability tool. You’ll see total tokens per request, cost per request, latency per request. All per-request. All in isolation.
None of these tell you:
Your dashboard shows snapshots. It doesn’t show the trajectory — the runaway growth curve eating your budget across a multi-turn session.
This is the metric that was missing.
Context utilization: one ratio that changes everything
utilization = input_tokens / max_context_tokens
Input tokens divided by the model’s maximum context window. A number between 0 and 1.
Turn 1: utilization = 0.01 — plenty of room
Turn 5: utilization = 0.12 — still fine
Turn 10: utilization = 0.68 — growing fast
Turn 13: utilization = 0.85 — danger zone
Turn 15: utilization = 0.95 — one tool result away from hitting the wall
Plot this on a chart and you see the growth curve before it becomes a cost problem. At a glance you know: how close you are to the limit, how fast you’re approaching it, and which agent is at risk.
How we record it
In toad-eye, context utilization is calculated automatically after every LLM call. If the model is in the pricing table, the metric is emitted — you don’t do anything:
const pricing = getModelPricing(model);
if (pricing?.maxContextTokens && output.inputTokens > 0) {
const utilization = output.inputTokens / pricing.maxContextTokens;
// On the span — queryable in Jaeger
span.setAttribute("gen_ai.toad_eye.context_utilization", utilization);
// As a histogram — P95/P99 in Grafana
recordContextUtilization(utilization, provider, model);
}
The pricing table knows every major model’s context window:
"gpt-4o": { maxContextTokens: 128_000 }
"gpt-4.1": { maxContextTokens: 1_047_576 }
"claude-opus-4": { maxContextTokens: 200_000 }
"claude-sonnet-4": { maxContextTokens: 200_000 }
"gemini-2.5-pro": { maxContextTokens: 1_048_576 }
Custom model? Override it:
setCustomPricing({
"my-finetuned-gpt4": {
inputPer1M: 3.0,
outputPer1M: 12.0,
maxContextTokens: 32_768,
},
});
Context guard: warn before it’s too late
A metric tells you what happened. A guard stops it from happening.
initObservability({
serviceName: "my-agent",
contextGuard: {
warnAt: 0.8, // console.warn at 80%
blockAt: 0.95, // throw before the LLM call at 95%
},
});
At 80%, you get a warning:
toad-eye: context window 82% full for gpt-4o (104,960 / 128,000 tokens)
At 95%, toad-eye throws a ToadContextExceededError — before the call, not after. Your agent catches it and can act:
try {
const response = await traceLLMCall(input, () => llm.chat(messages));
} catch (err) {
if (err instanceof ToadContextExceededError) {
// err.utilization: 0.96
// err.inputTokens: 122,880
// err.maxContextTokens: 128,000
messages = await compressHistory(messages);
// retry with compressed context
}
}
The error carries everything you need: current utilization, the threshold, the model, token counts. No guessing.
When the block fires, toad-eye records it in three places: a span event in Jaeger, a counter metric in Grafana, and a warning in your application logs. One event, full visibility.
What to do when utilization is high
The metric and guard tell you there’s a problem. Three practical fixes:
Summarize old turns. After N turns, replace the conversation history with an LLM-generated summary. Trade 50K tokens of history for a 2K summary. The agent loses some detail but stays under budget.
Compress tool results. Tool results are the biggest token hogs — a web search returning 10K tokens of HTML. Summarize tool results before adding them to context. Or store full results externally and put just a reference in context.
Route to a bigger model. When utilization crosses a threshold, switch models. Running on gpt-4o (128K)? Route to gpt-4.1 (1M) for the final turns:
if (err instanceof ToadContextExceededError && err.model === "gpt-4o") {
return callWithModel("gpt-4.1", messages);
}
And sometimes the right answer is to stop. If your agent hasn’t converged in 10 turns, adding 5 more turns of context won’t help — it’ll just cost more.
Where this came from
After publishing article #3 on OTel semantic conventions, a reader named @jidong left a comment:
“Context window usage per turn matters more than total tokens in agent loops.”
They were right. Total tokens is a number. Context utilization is a trajectory. The first tells you what happened. The second tells you what’s about to happen.
We built context_utilization the next week. Here’s the tracking issue — shaped directly by that comment.
Quick checklist
If you’re running agents in production:
input_tokens per turn, not just per sessioninput_tokens / max_context_tokens
The metric is simple. The insight it gives you is not.
Previous articles:
toad-eye — open-source LLM observability, OTel-native: GitHub · npm
🐸👁️