I Built an Oracle DBA That Lives in Telegram. It Cut a 500K-Row Scan to 5 – After Asking Permission.

This is a submission for the Hermes Agent Challenge

What I Built

OracleOps is a Hermes Agent plugin and skill pack that turns any messaging app your team already uses into a senior Oracle DBA you can DM at 3 AM.

📡 One install. Any chat platform.
The demo runs in Telegram, but the same OracleOps skills work identically in Slack, Discord, Microsoft Teams, WhatsApp, Signal, and Email — anywhere Hermes Agent’s messaging gateway reaches. Zero code changes between platforms. Bank ops team on Teams, startup ops team on Discord, on-call engineer on WhatsApp? Same bot, same skills, same audit log.

You message your bot, “Why is this query slow: SELECT * FROM orders WHERE customer_id = 42?“

The agent:

  1. Pulls the real runtime plan from Oracle’s cursor cache
  2. Reads existing indexes on the table
  3. Identifies the dominant bottleneck (in this case, no index on customer_id forcing a 500,000-row full scan to return 5 rows)
  4. Generates the exact CREATE INDEX DDL needed to fix it
  5. Asks for your explicit “yes” before executing it
  6. Verifies the new plan and reports the cost reduction
  7. Logs everything to an audit trail

It solves three pain points that Oracle DBAs deal with every week:

  • 3 AM slow-query diagnosis that today requires opening SQL Developer, running dbms_xplan.display_cursor, eyeballing wait events, and typing the same five v$session queries you typed last week
  • AWR is gold but nobody reads it until production is on fire
  • Production safety: the “AI agent deleted our database” anxiety is real. OracleOps proposes, then waits for explicit consent

Build cost: $0. Runs on Oracle Cloud Infrastructure’s permanent free tier. Repo includes a reproducible 7-trap demo schema so anyone can clone, install, and see all skills working in 60 seconds.

Demo

60-second screencap of the full diagnose → recommend → confirm → verify cycle in Telegram:

What the demo captures:

Step What happens
1 I ask, “What’s slow in my database right now?“
2 Agent calls top-sql-this-hour skill → returns ranked SQL by elapsed time
3 I ask, “Why is this query slow: SELECT * FROM orders WHERE customer_id = 42?“
4 Agent runs diagnose-slow-query → calls oracle_explain_plan + oracle_describe_table → identifies missing index
5 Agent proposes CREATE INDEX IX_ORDERS_CUSTOMER_ID ON orders(customer_id)
6 I reply, “Yes“
7 Agent fires oracle_write_with_confirmation, gets a fresh execution plan, verifies the fix worked

The headline numbers from the live ADB run:

Before After
Plan operation TABLE ACCESS STORAGE FULL INDEX RANGE SCAN
Cost 709 8
Predicate filter() (post-scan) access() (index lookup)
Rows touched 500,000 ~5

98.9% cost reduction. From a Telegram message.

Every write the agent makes is appended to an audit log. Here is the entry the demo produced:

{
  "ts": "2026-05-18T23:23:15Z",
  "user": "admin",
  "dsn": "oracleopsdemo_high",
  "sql": "CREATE INDEX IX_ORDERS_CUSTOMER_ID ON orders(customer_id)",
  "user_confirmation_token": "Yes",
  "reason": "Create missing index on orders.customer_id to fix full table scan on 500K-row table — estimated 99% reduction in query cost.",
  "rows_affected": 0
}

The user_confirmation_token field is the user’s literal reply that was required before the SQL ran. The reason captures the agent’s rationale. Together they form a compliance-friendly trail of every destructive thing the agent has ever done on your database.

Code

Repo: https://github.com/shopsmartai/oracleops

Install one-line:

hermes plugins install shopsmartai/oracleops
hermes plugins enable oracleops

Then drop the skills into your Hermes skills directory:

git clone https://github.com/shopsmartai/oracleops /tmp/oracleops-skills
cp -r /tmp/oracleops-skills/skills/* ~/.hermes/skills/

Configure Oracle credentials and restart the gateway:

hermes config set ORACLE_USER admin
hermes config set ORACLE_PASSWORD 'your-password'
hermes config set ORACLE_DSN your_db_high
hermes config set ORACLE_WALLET_DIR "$HOME/oracle-wallets/yourdb"
hermes config set ORACLE_WALLET_PASSWORD 'your-wallet-password'
hermes gateway restart

MIT licensed. Repo includes:

  • 7 agentskills.io-formatted skills (portable to Claude Code, Cursor, OpenHands, and Letta — not just Hermes)
  • 5 Oracle tools registered into the oracle_db toolset
  • A 100k-customer / 500k-orders / 1M-order_items demo schema with 7 intentional performance traps
  • End-to-end OCI Always Free Tier deployment guide

My Tech Stack

Layer What I used
Agent runtime Hermes Agent v0.14 from Nous Research
Model Anthropic Claude Sonnet 4.6 (switched from Gemini after hitting free-tier 429s)
Messaging Telegram via Hermes’ bundled gateway (one of 7 supported — Slack, Discord, Teams, WhatsApp, Signal, Email all work identically)
Plugin language Python 3.11 with oracledb 4.0 in thin mode (no Instant Client install)
Database Oracle Autonomous Database 23ai / 26ai on Oracle Cloud Always Free Tier
Auth to ADB mTLS via wallet (cwallet.sso, tnsnames.ora)
Skill format agentskills.io Markdown with YAML frontmatter
Audit log JSON Lines at ~/.hermes/oracleops/writes.jsonl
Hosting OCI ARM Ampere A1 free tier (4 OCPU / 24 GB RAM) – $0/month total

How I Used Hermes Agent

Five Hermes capabilities did the heavy lifting:

1. The plugin contract (register(ctx) + JSON-schema tools)

OracleOps registers 5 tools into the oracle_db toolset using Hermes’ ctx.register_tool API. Each tool is a Python function that accepts (args: dict, **kwargs), returns a JSON string, and exposes a JSON Schema for parameters. The result is that the language model can decide when to call my tools the same way it decides when to call Hermes’ built-in tools – no special prompting needed. I followed Spotify’s bundled plugin as the template; the contract is genuinely clean.

2. agentskills.io format for skills

Skills live in 7 separate Markdown files with YAML frontmatter. Hermes loads them at runtime; the agent picks the right skill based on the description and when_to_use fields. The skills are portable – they work in Claude Code, Cursor, OpenHands, and Letta without modification. So even if a user doesn’t run Hermes, they can drop these skills into any agent that speaks the same format.

This is something I didn’t fully appreciate until I’d written the third skill: I’m not building Hermes-only software. I’m building a portable Oracle DBA playbook that happens to run on Hermes today.

3. Confirmation-gated writes

This was the killer feature for the safety story. The oracle_write_with_confirmation tool requires user_confirmation_token as a mandatory parameter. The calling skill’s job is to collect the user’s literal “yes” in the immediately prior chat turn and pass it through. The tool refuses to execute unless the token is in a small allowlist of affirmatives (yes, y, confirm, proceed, etc.).

Every executed write hits a JSON Lines audit log outside the plugin directory. Even if the plugin gets uninstalled or rewritten, the historical trail of “what did the agent do with my consent” survives. This is the answer to that Hacker News thread titled “An AI agent deleted our production database.”

4. Messaging gateways (the multi-platform story)

I wired Telegram for the demo with hermes setup gateway — about 2 minutes of clicks in BotFather plus one hermes config set for the allowlist. The same OracleOps install also serves:

Platform Status Setup
Telegram ✅ demo BotFather token
Slack ✅ supported Socket Mode bot token
Discord ✅ supported Application + Message Content Intent
Microsoft Teams ✅ supported Bot Framework + Adaptive Cards
WhatsApp ✅ supported Meta Cloud API or Twilio
Signal ✅ supported signal-cli linked to your number
Email ✅ supported IMAP/SMTP

Crucially, the skills don’t change. All 7 OracleOps skills are platform-agnostic Markdown — the Hermes gateway plugin handles the protocol differences (token-by-token streaming on Telegram/Slack, message-batched on Email, etc.). So when the bank ops team prefers Microsoft Teams and the startup ops team prefers Discord, the same OracleOps deployment serves both audiences with zero code rework.

The allowlist (TELEGRAM_ALLOWED_USERS / SLACK_ALLOWED_USERS / etc.) restricts who can DM the bot. This matters: an Oracle DBA agent with no allowlist is a remote-code-execution surface to anyone who finds the bot username.

5. The orchestrator pattern with subagents on call

The orchestrator skill is the front door for natural-language complaints. It classifies user intent into 9 buckets and either calls one specific skill or fans out (via Hermes’ delegate_task) to three diagnostics in parallel for generic “the database is slow” questions. The subagents run concurrent SQL against the ADB so the response time stays under 10 seconds even when three diagnostics are needed.

I also wired a kill-session-suggestion skill for the worst-case 3 AM scenario: a blocking session that won’t release. The skill walks the blocker chain, names the lock type, estimates rollback time, and proposes ALTER SYSTEM KILL SESSION with explicit @<inst_id> syntax for RAC clusters. Same confirmation gate, same audit log.

The 8 engineering problems I hit

Most of these weren’t in the docs. Sharing them so anyone building on Hermes can shortcut the painful parts.

1. The Hermes plugin contract isn’t pip install

hermes plugins install takes a Git URL or owner/repo, not a local path. My first attempt at packaging the plugin as plugins/oracle/ nested inside a project repo was wrong. The plugin manifest, registration code, and Python tool modules must live at the root of a Git repo – the repo IS the plugin. I learned this by reading ~/.hermes/hermes-agent/plugins/spotify/ source.

2. Oracle passwords break naive connection-string parsers

Oracle allows passwords containing @, #, !, /, and most punctuation. My initial parser did split("@", 1) on user/password@dsn, which broke on passwords containing @. Fix: prefer three separate env vars (ORACLE_USER, ORACLE_PASSWORD, ORACLE_DSN) and only fall back to combined parsing with rsplit("@", 1) for the simple case.

3. PL/SQL anonymous blocks shred under split(";")

My demo seed had a BEGIN ... END; / block for stats gathering. Naive Python split(";") produced 7 invalid fragments that all failed with ORA-00900. Fix: wrote a proper splitter that tracks PL/SQL block boundaries (BEGIN/DECLARE … /) separately from plain SQL terminators. Bonus: it also respects semicolons inside string literals.

4. Hermes’ bundled venv doesn’t ship pip

The Hermes Python venv at ~/.hermes/hermes-agent/venv/ came pip-less – Hermes is managed with uv. To install oracledb, the path was python -m ensurepip --upgrade && python -m pip install oracledb>=2.0. Tucked this into the README for users.

5. Skill required_environment_variables must match the plugin’s env vars exactly

Three of my SKILL.md files listed ORACLE_CONNECTION_STRING in required_environment_variables. The plugin uses the three-separate-vars form. Result: the agent refused to run those skills with “Please provide ORACLE_CONNECTION_STRING.” Fix: align the skill manifests with the plugin’s actual env var contract. (Caught it during the first real Telegram test, which is exactly when an integration test should catch it.)

6. Session memory caches old skill content across gateway restarts

After updating SKILL.md and restarting the gateway, the same Telegram session kept asking for the old env var. The fix is to start a fresh session (Hermes has /new). I didn’t expect this; the skill file on disk is the source of truth, but in-session conversation state preserves the model’s earlier reasoning.

7. Gemini 2.5 Pro’s free tier has limit: 0

The setup wizard reported “paid ✓” for my Gemini key, but the actual quota was zero for gemini-2.5-pro. Symptoms: HTTP 429 RESOURCE_EXHAUSTED for every request. Fix paths: (a) switch to gemini-2.5-flash which IS free-tier accessible, or (b) attach billing to the Google Cloud project. I ended up switching to Anthropic Claude Sonnet 4.6 entirely – better instruction-following for structured Oracle SQL analysis and the free credits cover the demo budget.

8. Telegram bot tokens are RCE if not allowlisted

By default, a Hermes bot accepts messages from any Telegram user that finds it. With OracleOps active, that means anyone can ask the bot to run SQL against my database. Mitigation: hermes config set TELEGRAM_ALLOWED_USERS <my_user_id>. Anyone outside the allowlist gets ignored at the gateway layer before the agent ever sees their message.

What I learned about Hermes Agent that wasn’t in the docs

  • The plugin contract is register(ctx), not class-based. It’s ctx.register_tool(name, toolset, schema, handler, check_fn, emoji) per tool. Simple, clean, fewer ceremony than I expected.
  • check_fn is for graceful degradation, not gating. A tool with check_fn returning False stays listed in hermes tools but won’t dispatch. Users see the tool exists; runtime errors clearly explain “set ORACLE_USER…” instead of the tool silently disappearing.
  • Hermes runs everything in its own venv at ~/.hermes/hermes-agent/venv/. Plugin dependencies install into this venv with the path-explicit python -m pip install pattern.
  • hermes plugins list is global; hermes tools list is per-platform. A toolset can be enabled globally but disabled for Telegram or CLI specifically. Worth knowing during testing.
  • The agentskills.io standard is bigger than just Hermes. Skills written for Hermes work in Claude Code, Cursor, OpenHands, and Letta. The skill pack in this repo is a usable Oracle DBA playbook independent of which agent runtime you use.

What I would build next

  • Cron-driven morning briefings. Wire awr-summary-now + top-sql-this-hour + find-lock-contention into a daily 8 AM Telegram digest using Hermes’ NL cron. Hermes has this built in; I ran out of time before adding the cron syntax to the README.
  • Oracle 23ai AI Vector Search for incident similarity. When a new complaint comes in (“orders app is slow again”), do a vector similarity search against past incident postmortems before running fresh diagnostics. “This looks like the contention you had on orders_status_idx two weeks ago – the fix then was…” This is what 23ai’s in-database vector index makes possible.
  • Auto-generated skills via the Curator. After three similar slow-query diagnoses on the same application, have Hermes promote the pattern into a diagnose-<app>-pattern skill so future diagnoses skip the discovery phase. I designed the MEMORY captures with this in mind; the Curator hooks are next.
  • Multi-instance RAC. All my v$ queries should use gv$ and walk inst_id for cluster databases. Single-instance ADB doesn’t need it, but on-prem RAC does. Pure plumbing, no new ideas.

Thanks

  • Nous Research for shipping Hermes Agent v0.14.0 the same week as the challenge — and for making the plugin contract clean enough that I could ship a working tool integration in a week. The Spotify bundled plugin was the perfect template.
  • Oracle Cloud’s Always Free Tier for the 2 free Autonomous Database instances. Building on real Oracle 23ai/26ai at $0/month is the difference between a hackathon toy and an actually useful piece of software.
  • The agentskills.io open standard. Knowing my skills also work in Claude Code, Cursor, OpenHands, and Letta means the value of this project survives whichever agent framework wins long-term.
  • The Oracle DBA community whose late-night Slack threads about ITL contention, bind variable peeking, and adaptive cursor sharing inspired half the skill content. Most of the technique in diagnose-slow-query‘s 7-pattern bottleneck table came from those conversations.

Try the live install with hermes plugins install shopsmartai/oracleops and tell me what breaks. PRs welcome. The code is MIT.
The Day 2 Reality of Running a Kubernetes Lab on Your Mac: Stop/Start, CKS Scenarios, and What I Learned Building It.

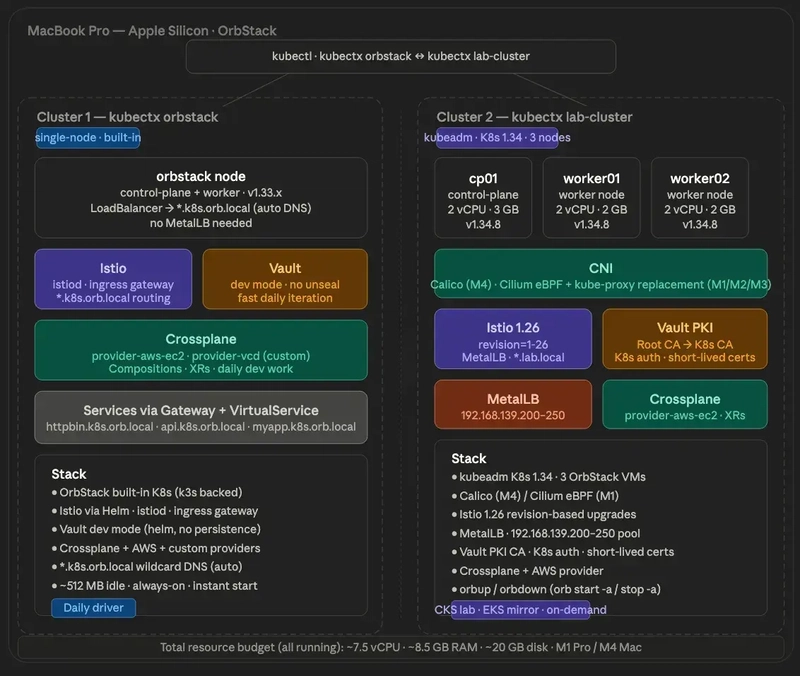
Complete dual-cluster setup — native K8s daily driver on the left, VM lab cluster on the right.

Part 7 of 7 — The Mac Kubernetes Lab: A Production-Mirror Setup from Scratch.

Previously in Part 6: We wired up Vault Kubernetes auth, installed Crossplane with the AWS provider, and applied LimitRanges mirroring the production configuration that resulted from a real disk-pressure incident. The EKS mirror is complete. Now we focus on Day 2 — actually using the thing sustainably.

There’s a question I had when I first put this lab together that nobody had answered for me cleanly: Will my cluster survive a stop?

You’re going to want to stop it. The whole point of a local lab is that it gets out of your way when you’re not using it. A four-VM cluster running 24/7 is fine on paper, but you’ve also got Slack, six browser tabs, and an IDE eating memory. Knowing exactly what survives a stop, and what doesn’t, and what manual steps you need on the way back up is the difference between “lab I use every day” and “lab I built once and abandoned.”

This final article is the runbook I wish I had at the start. Stop/start without losing state, CKS exam scenarios this cluster is purposely built for, and the shell setup that makes the whole thing pleasant to live with.

 The full setup, recapped:

Seven articles in, here’s what’s running:
Complete dual-cluster setup — native K8s daily driver on the left, VM lab cluster on the right.

Cluster 1 — kubectx orbstack

  • OrbStack-native K8s, single-node
  • Istio with *.k8s.orb.local wildcard DNS
  • Vault in dev mode
  • Crossplane
  • Always-on, idles at around 512 MB

Cluster 2 — kubectx lab-cluster

  • kubeadm Kubernetes 1.34, 3 nodes
  • Vault PKI (3-tier hierarchy, exported intermediate CA)
  • Istio 1.26 revision-based, MetalLB for LoadBalancer
  • Crossplane with the AWS provider
  • Vault Kubernetes auth
  • Run on-demand

Stop/start without losing state

The biggest question I had when I first set this up was the one I led with — will the cluster survive a stop? The answer is yes, with one exception.

 Stopping

# 💻 Mac
orb stop -a      # stop all VMs
orb stop k8s     # stop the native cluster (optional — fine to leave running)

What persists:

  • All Kubernetes objects — deployments, services, configmaps, secrets, PVCs
  • etcd data on cp01 (stored on the VM’s disk)
  • Vault data at /opt/vault/data (file backend, persists on disk)
  • Calico/Cilium, Istio, Crossplane, MetalLB configurations
  • The Mac kubeconfig

What is released:

  • All CPU — drops to zero immediately
  • All RAM — fully returned to macOS
  • ~8 GB of disk remains used.

Starting back up

# 💻 Mac
orb start -a

Then follow these steps in order:

Step 1 — Unseal Vault. This is the one manual step that can’t be automated away:

# 🖥️ VM: vault
export VAULT_ADDR='http://127.0.0.1:8200'
vault operator unseal $(grep 'Unseal Key 1' ~/vault-init.txt | awk '{print $NF}')
vault status
# Sealed: false ← what you want

Vault seals itself on every shutdown by design. That’s a security feature; an unsealed Vault that survives reboots is, by definition, less secure. In production, you’d use auto-unseal with AWS KMS or Azure Key Vault. For the lab, one manual unseal command is fine.

Step 2 — Verify the cluster:

# 💻 Mac
kubectx lab-cluster
kubectl get nodes   # Ready within ~30 seconds
kubectl get pods -A # everything restarts automatically 

Step 3 — Re-export session variables: This is the friction I underestimated when I started. Environment variables don’t persist across SSH sessions anything you exported in a previous session is gone:

# 🖥️ VM: vault (when doing PKI or auth work)
export VAULT_ADDR='http://127.0.0.1:8200'
export VAULT_ROOT_TOKEN=$(grep 'Initial Root Token' ~/vault-init.txt | awk '{print $NF}')
# 🖥️ VM: cp01 (when doing kubeadm or cert work)
export CP_IP=$(hostname -I | awk '{print $1}')
# 💻 Mac (when doing Istio or MetalLB work)
export VAULT_IP=$(orb run -m vault hostname -I | awk '{print $1}')
export INGRESS_IP=$(kubectl get svc istio-ingress -n istio-system 
  -o jsonpath='{.status.loadBalancer.ingress[0].ip}')

Step 4 — Regenerate /tmp files if needed. /tmp on OrbStack VMs clears on reboot:

# 🖥️ VM: vault
vault read -field=certificate pki_k8s/issuer/default > /tmp/lab-ca.crt

Persistence quick reference

Persistence quick reference

Shell setup that makes it pleasant

Put these in your ~/.zshrc:

# 💻 Mac — add to ~/.zshrc
alias klab="kubectx lab-cluster"
alias korb="kubectx orbstack"
alias kns="kubens"
alias k="kubectl"
alias kgp="kubectl get pods -A"
alias kgn="kubectl get nodes -o wide"
alias orbup="orb start -a"
alias orbdown="orb stop -a"

Daily flow becomes short:

orbup               # start everything
ssh vault@orb       # unseal Vault
vault operator unseal $(grep 'Unseal Key 1' ~/vault-init.txt | awk '{print $NF}')
# exit vault VM
klab                # switch to lab cluster
kgn                 # verify nodes
kgp                 # verify pods

CKS exam preparation:

The VM lab cluster is purpose-built for CKS. Real kubeadm cluster, real etcd, real kubelet config files. The exam gives you a similar environment, and having practiced the same scenarios on a cluster where you control every layer makes a meaningful difference.

The scenarios I practice most:

Pod Security Admission:

PSA replaced PodSecurityPolicy in Kubernetes 1.25. The CKS exam tests your ability to enforce pod security standards at the namespace level.

# 💻 Mac
kubectl create namespace restricted-ns

# Enforce the restricted profile - blocks privilege escalation, host networking, etc.
kubectl label namespace restricted-ns 
  pod-security.kubernetes.io/enforce=restricted 
  pod-security.kubernetes.io/audit=restricted 
  pod-security.kubernetes.io/warn=restricted

# Test - this pod should be blocked
kubectl run test --image=nginx -n restricted-ns
# Error from server (Forbidden): pods "test" is forbidden: violates PodSecurity

RBAC

# 💻 Mac
 # Create a role that can only read pods
kubectl create role pod-reader 
  --verb=get,list,watch 
  --resource=pods 
  -n restricted-ns

# Bind it to a service account
kubectl create rolebinding pod-reader-binding 
  --role=pod-reader 
  --serviceaccount=restricted-ns:default 
  -n restricted-ns

# Test with impersonation
kubectl auth can-i list pods 
  --as=system:serviceaccount:restricted-ns:default 
  -n restricted-ns
# yes

kubectl auth can-i delete pods 
  --as=system:serviceaccount:restricted-ns:default 
  -n restricted-ns
# no

Audit policy:

The exam often asks you to configure an audit policy on the control plane. This requires editing the kube-apiserver static pod manifest directly:

# 🖥️ VM: cp01
sudo tee /etc/kubernetes/audit-policy.yaml <<EOF
apiVersion: audit.k8s.io/v1
kind: Policy
rules:
- level: RequestResponse
  resources:
  - group: ""
    resources: ["secrets"]
- level: Metadata
  resources:
  - group: ""
    resources: ["pods"]
- level: None
  users: ["system:kube-proxy"]
EOF

Add these flags to /etc/kubernetes/manifests/kube-apiserver.yaml:

- --audit-policy-file=/etc/kubernetes/audit-policy.yaml
- --audit-log-path=/var/log/kubernetes/audit.log
- --audit-log-maxage=30
- --audit-log-maxbackup=10

The kubelet restarts kube-apiserver automatically when the manifest changes.

NetworkPolicy: default-deny

# 💻 Mac
# Deny all ingress and egress by default
kubectl apply -f - <<EOF
apiVersion: networking.k8s.io/v1
kind: NetworkPolicy
metadata:
  name: default-deny-all
  namespace: default
spec:
  podSelector: {}
  policyTypes:
  - Ingress
  - Egress
EOF
# Then selectively allow what's needed
kubectl apply -f - <<EOF
apiVersion: networking.k8s.io/v1
kind: NetworkPolicy
metadata:
  name: allow-dns
  namespace: default
spec:
  podSelector: {}
  policyTypes:
  - Egress
  egress:
  - ports:
    - port: 53
      protocol: UDP
    - port: 53
      protocol: TCP
EOF

Short-lived admin certificates from Vault PKI

A CKS best practice — use short-lived credentials instead of long-lived kubeconfig files:

# 🖥️ VM: vault
# Issue a 1-hour admin certificate
vault write pki_k8s/issue/admin 
  common_name="kubernetes-admin" ttl=1h

The output gives you a certificate and private key. Build a kubeconfig from them that expires in one hour. Instead of a kubeconfig with a long-lived client cert, you issue a fresh cert each session. When it expires, access is revoked automatically. In production, this is enforced at the Vault role level (max_ttl=2h) you physically cannot issue a cert with a longer TTL.

Trivy image scanning

CKS includes container image security. Trivy is the tool used on the exam:

# 🖥️ VM: cp01 — install trivy
curl -sfL https://raw.githubusercontent.com/aquasecurity/trivy/main/contrib/install.sh | sudo sh -s -- -b /usr/local/bin

# Scan an image
trivy image nginx:latest

# Scan for HIGH and CRITICAL only
trivy image --severity HIGH,CRITICAL nginx:latest

 Five things I learned building this

  1. OrbStack is genuinely better than Multipass, not just faster. The native DNS, instant boot, and real LoadBalancer IPs remove an entire category of friction I had normalised. I didn’t realise how much time I was spending on /etc/hosts edits until I stopped having to do them.

  2. T*he M1 vs M4 CNI difference is a kernel capability issue, not an OrbStack bug.* Once I understood that iptables NAT is restricted in unprivileged LXC containers on M1, Cilium was the obvious fix. Knowing this also makes it easier to debug similar issues in other restricted container environments; CI systems, Docker-in-Docker, anywhere Kubernetes is running inside something it doesn’t quite own.

  3. **Vault PKI is worth the setup cost. **You could let kubeadm generate self-signed certs and skip a whole chapter. But having a lab that uses the same certificate hierarchy as production means the mental model transfers directly. Short-lived admin certs stop being a theoretical best practice and start being how you actually work.

  4. Session variables are the biggest day-to-day friction. Anything that doesn’t persist to .bashrc gets lost between sessions. I’ve been burned by an empty $CP_IP, causing a “not a valid IP address” error in the kubeadm config more times than I’d like to admit. Persist in what you can.

  5. Document as you go. This whole series came out of runbook notes I was writing for myself while I built the lab. Writing each step down caught several places where the process was more manual than it needed to be, and meant I could replicate the setup on another machine in a day instead of a weekend. If you’ve built something complicated, writing it up is one of the higher-leverage things you can do, even if you never publish it.

 The full series

Part 1: Why I Replaced Multipass with OrbStack and what an M1 vs M4 Mac taught me about local Kubernetes.
Part 2: One Command, One Working Kubernetes Cluster! Building My Daily-Driver Lab on OrbStack.
Part 3: Building a Production-Grade Vault PKI for a Local kubeadm Cluster Without the Shortcuts.
Part 4: Same Cluster, Different Mac: A Debugging Story About Unprivileged LXC Containers, iptables, and Why Cilium Replaces kube-proxy.
Part 5: How I Practise Istio Upgrades Locally Before Touching Production EKS.
Part 6: The Disk-Pressure Incident That Taught Me to Always Set LimitRanges and Other Lessons from Mirroring EKS Locally.
Part 7 (this article): The Day 2 Reality of Running a Kubernetes Lab on Your Mac: Stop/Start, CKS Scenarios, and What I Learned Building It.

 Resources

← Part 6: The Disk-Pressure Incident That Taught Me to Always Set LimitRanges and Other Lessons from Mirroring EKS Locally.

I’m Noah Makau, a DevSecOps engineer based in Nairobi. I run a small DevOps consultancy and hold CKA, CKAD, and the AWS Solutions Architect Professional certifications, currently preparing for CKS. I write about Kubernetes, Vault, Crossplane, and the day-to-day of running platforms that actually have to stay up.

Originally published at blog.arkilasystems.com

Uber Improves Restaurant Recommendations Using Real-Time Signals and Listwise Ranking

Uber updates its Uber Eats Home Feed recommendation system using near real-time user sequence features and a Generative Recommender model. The system evolves from hand-crafted features to transformer-based sequence modeling, reduces feature freshness from 24 hours to seconds, and shifts from pointwise scoring to listwise GenRec for improved contextual ranking and real-time personalization.

By Leela Kumili

n8n for Airtable Power Users: 5 Automations That Take Your Base to the Next Level

If you’re an Airtable power user, you’ve hit the wall: Airtable’s native automations are limited, Zapier gets expensive fast, and the built-in scripting doesn’t talk to your other tools easily.

n8n changes that. It’s a free, self-hostable automation platform that connects Airtable to anything — Slack, Gmail, Notion, Postgres, OpenAI, custom webhooks, REST APIs — with full conditional logic, loops, and branching. No per-task fees.

Here are 5 workflows that serious Airtable users actually need.

1. Auto-Sync Airtable Records to a Real Database

Airtable is great for prototyping but hits limits fast: 50K rows on free, no SQL joins, no triggers. When you outgrow it, you don’t need to abandon your Airtable setup — just sync it.

What it does: Every hour, n8n reads all Airtable records modified in the last hour, upserts them into Postgres (or MySQL, SQLite, Supabase), and logs sync stats to a Google Sheet. Your Airtable stays as the friendly UI; the database becomes the source of truth for reports, analytics, and your engineering team.

Trigger: Schedule (hourly)

{
  "name": "Airtable to Postgres Sync",
  "nodes": [
    {
      "type": "n8n-nodes-base.scheduleTrigger",
      "name": "Every Hour",
      "parameters": { "rule": { "interval": [{ "field": "hours", "minutesInterval": 1 }] } }
    },
    {
      "type": "n8n-nodes-base.airtable",
      "name": "Get Modified Records",
      "parameters": {
        "operation": "list",
        "filterByFormula": "IS_AFTER({Last Modified}, DATEADD(NOW(), -1, 'hours'))"
      }
    },
    {
      "type": "n8n-nodes-base.postgres",
      "name": "Upsert to DB",
      "parameters": {
        "operation": "upsert",
        "conflictTarget": "airtable_id"
      }
    },
    {
      "type": "n8n-nodes-base.googleSheets",
      "name": "Log Sync Stats",
      "parameters": { "operation": "append" }
    }
  ]
}

Pro tip: Use Airtable’s LAST_MODIFIED_TIME() formula field to track changes precisely. Set conflictTarget to your Airtable record ID so upserts are idempotent.

2. Airtable Record Created → Slack Alert + Personalized Email

The classic Airtable automation “send email on record creation” is basic. You want routing, enrichment, and multi-channel notification.

What it does: When a new record is created in your CRM base (new lead, new project, new ticket), n8n (1) posts a formatted Slack message with all key fields, (2) classifies the record using OpenAI (e.g., lead score, sentiment, priority), (3) updates the Airtable record with the AI classification, and (4) sends the contact a personalized welcome email.

Trigger: Airtable trigger (polling every minute)

{
  "name": "New Airtable Record → Slack + AI + Email",
  "nodes": [
    {
      "type": "n8n-nodes-base.airtableTrigger",
      "name": "New Record",
      "parameters": { "event": "create", "pollTimes": { "item": [{ "mode": "everyMinute" }] } }
    },
    {
      "type": "n8n-nodes-base.slack",
      "name": "Notify Team",
      "parameters": { "text": "New record: *{{ $json.Name }}* — {{ $json.Status }}" }
    },
    {
      "type": "@n8n/n8n-nodes-langchain.openAi",
      "name": "Classify Record",
      "parameters": { "prompt": "Score this lead 1-10 and return JSON: { score, reasoning, next_action }. Lead: {{ $json }}" }
    },
    {
      "type": "n8n-nodes-base.airtable",
      "name": "Update Record with Score",
      "parameters": { "operation": "update" }
    },
    {
      "type": "n8n-nodes-base.gmail",
      "name": "Send Personalized Email"
    }
  ]
}

3. Daily Airtable Status Report → Email Digest

Your Airtable base has projects, tasks, or tickets. You want a daily digest without opening 6 different views.

What it does: Every morning at 8 AM, n8n queries your Airtable base for records matching specific statuses (overdue, due today, in review, blocked), groups them by owner or category using a Code node, builds an HTML email with a clean summary table, and sends it to the whole team. One email replaces 15 minutes of manual checking.

Trigger: Schedule (daily 8AM)

{
  "name": "Daily Airtable Digest",
  "nodes": [
    {
      "type": "n8n-nodes-base.scheduleTrigger",
      "name": "Daily 8AM",
      "parameters": { "rule": { "interval": [{ "field": "cronExpression", "expression": "0 8 * * *" }] } }
    },
    {
      "type": "n8n-nodes-base.airtable",
      "name": "Get Overdue Items",
      "parameters": { "operation": "list", "filterByFormula": "AND(IS_BEFORE({Due Date}, TODAY()), {Status} != 'Done')" }
    },
    {
      "type": "n8n-nodes-base.airtable",
      "name": "Get Due Today",
      "parameters": { "operation": "list", "filterByFormula": "IS_SAME({Due Date}, TODAY(), 'day')" }
    },
    {
      "type": "n8n-nodes-base.code",
      "name": "Build HTML Digest",
      "parameters": { "jsCode": "// Merge overdue + due today, build HTML table rowsnconst overdue = $('Get Overdue Items').all();nconst today = $('Get Due Today').all();nconst html = `<h2>Overdue (${overdue.length})</h2>` + overdue.map(i => `<li>${i.json.Name}</li>`).join('');nreturn [{ json: { html } }];" }
    },
    {
      "type": "n8n-nodes-base.gmail",
      "name": "Send Digest",
      "parameters": { "subject": "Daily Airtable Digest — {{ $now.toFormat('MMM d') }}" }
    }
  ]
}

4. Airtable Form Submission → Multi-Step Onboarding

Airtable forms are great for capturing data. But native form automations are limited: no branching, no waiting, no multi-step sequences.

What it does: When someone submits your Airtable form (contact request, project intake, onboarding survey), n8n triggers a full multi-step onboarding: immediate confirmation email, creates a Notion page for the project, creates a Google Drive folder, sends a Slack notification, and schedules a follow-up email 3 days later via a Wait node.

Trigger: Airtable trigger (new record in form submissions table)

{
  "name": "Form → Full Onboarding",
  "nodes": [
    { "type": "n8n-nodes-base.airtableTrigger", "name": "New Form Submission" },
    { "type": "n8n-nodes-base.gmail", "name": "Confirmation Email" },
    { "type": "n8n-nodes-base.notion", "name": "Create Project Page" },
    { "type": "n8n-nodes-base.googleDrive", "name": "Create Drive Folder" },
    { "type": "n8n-nodes-base.slack", "name": "Notify Team" },
    { "type": "n8n-nodes-base.wait", "name": "Wait 3 Days", "parameters": { "amount": 3, "unit": "days" } },
    { "type": "n8n-nodes-base.gmail", "name": "Day 3 Follow-Up Email" }
  ]
}

Pro tip: Use the Airtable Update Record node after each step to write status back (e.g., Notion page: [URL], Drive folder: [URL]). Your Airtable base becomes a live dashboard of every onboarding step.

5. Bi-Directional Airtable ↔ Notion Sync

Teams split between Airtable (operations) and Notion (documentation/wikis) constantly re-enter data. Stop.

What it does: n8n runs every 15 minutes. Records created or updated in Airtable get synced to a Notion database (matching fields by name). Changes in Notion (status updates, comments) get pushed back to Airtable. A Code node handles field type mapping (Airtable multi-select → Notion multi-select, dates, URLs). Conflicts are resolved by last-modified timestamp.

Trigger: Schedule (every 15 minutes)

{
  "name": "Airtable <-> Notion Sync",
  "nodes": [
    {
      "type": "n8n-nodes-base.scheduleTrigger",
      "name": "Every 15 Min",
      "parameters": { "rule": { "interval": [{ "field": "minutes", "minutesInterval": 15 }] } }
    },
    {
      "type": "n8n-nodes-base.airtable",
      "name": "Get Airtable Changes",
      "parameters": { "operation": "list", "filterByFormula": "IS_AFTER(LAST_MODIFIED_TIME(), DATEADD(NOW(), -15, 'minutes'))" }
    },
    {
      "type": "n8n-nodes-base.code",
      "name": "Map Fields",
      "parameters": { "jsCode": "// Convert Airtable field format to Notion propertiesnreturn items.map(item => ({n  json: {n    title: item.json.Name,n    status: item.json.Status,n    airtable_id: item.json.idn  }n}));" }
    },
    {
      "type": "n8n-nodes-base.notion",
      "name": "Upsert Notion Page",
      "parameters": { "operation": "update" }
    },
    {
      "type": "n8n-nodes-base.notion",
      "name": "Get Notion Changes",
      "parameters": { "operation": "getAll", "filter": { "timestamp": "last_edited_time", "last_edited_time": { "past_minute": {} } } }
    },
    {
      "type": "n8n-nodes-base.airtable",
      "name": "Update Airtable",
      "parameters": { "operation": "update" }
    }
  ]
}

Get the Complete Template Pack

All 5 workflows above — plus 8 more — are available as ready-to-import .json files in the FlowKit n8n template pack.

Browse and download: https://stripeai.gumroad.com

Each template is fully documented with setup instructions, required credentials, and customization notes. Import, configure your credentials, and run.

Using any of these in your stack? Let me know in the comments what you’re connecting Airtable to — I’m always looking for the next workflow to add.

Validating Gemma 4 for Industrial IoT: A Governance Pattern

Arize Phoenix Trace Dashboard

This is a submission for the Gemma 4 Challenge: Build with Gemma 4

What I Built

The Problem

In Industrial IoT systems, we work with deterministic logic. A sensor gives a specific value, and hardware has physical limits that cannot be changed. Recently, many developers are using LLMs (like Gemma 4) to manage workflow logic and decision making.

However, there is a big problem. The nature of probabilistic AI and deterministic hardware is different. An LLM is a probabilistic generator that predicts the next text. LLM is not a control system for hardware. If an AI agent sends a command that ignores physical constraints, for example, trying to move a robot arm when battery is very low, the hardware will try to do it. This can cause expensive equipment failure.

Thus, we need a governance layer between the AI and the actual hardware execution.

The Solution

I developed SilverAi, a lightweight Python middleware that works like a filter for our hardware. Its job is to check agent requests against the current system state before any command is sent to the driver.

SilverAi does not “reason” or think about the command. It only checks if the command violates hard-coded safety rules.

For implementation, I use Python decorators to define the safety constraints. These rules are checked before the function body runs.

@guard(
    rules=[
        MaxLoad(100.0),
        rules.BatteryMin(20),
        StateGate("motor_temp", max_value=80.0),
    ]
)
def _execute_guarded(...) -> Dict[str, Any]:
    ...

By separating the AI agent intent from the validation layer, we do not need the LLMs to be “smart” about safety. This is because, with SilverAi, the model can propose actions, but it cannot override the rules.

SilverAi also comes with a dry-run mode. This lets developers simulate hardware problems (like thermal overload or connection loss) without needing real physical machines.

Finally, in SilverAi, when a request is blocked, the reason is logged. This creates an audit trail to understand why an operation was stopped, which is very important for troubleshooting IoT systems.

Arize Phoenix Trace Dashboard
Figure 1: The moment the SilverAi guardrail saves the hardware. Arize Phoenix trace showing the guard_check intercepting and blocking a hazardous AI command that exceeded the 100.0 maximum belt load limit.

Demo

Code

How I Used Gemma 4

For this project, I chose the Gemma 4 E4B model.

The system needed to run on local industrial hardware without a dependency on a cloud-based GPU cluster. In a warehouse or EOC environment, we cannot rely on low-latency internet or massive server-grade compute just to parse a telemetry string.

The E4B model was the right fit because it provides the necessary reasoning capability for high-level workflow parsing while maintaining a local footprint that does not choke a standard industrial workstation. It is the correct tool for a system where the “intelligence” is secondary to the deterministic safety layer it sits behind.

As we know, industrial systems are flooded with unstructured data—operator log notes, legacy serial strings, and unformatted maintenance overrides. Traditional automation requires rigid, hardcoded string parsing (like Regex), which breaks the moment an operator types a command differently.

Gemma 4 unlocked semantic translation of unstructured intent.

When an operator inputs a natural language command—such as “Divert package PKG-400 to Aisle 3 because the main sorter is jamming”, Gemma 4 successfully parses the messy string, identifies the operational intent, and structures it into a JSON payload ({"route": "Aisle 3", "load": 5.0}).

This is where the model’s intelligence becomes a liability. Gemma 4 is smart enough to interpret the human operator’s intent, but because it is a probabilistic model, it is completely oblivious to real-time physical telemetry. It does not know that while it successfully generated the routing plan, a hardware sensor just reported a thermal spike on the Aisle 3 motor.

That is exactly why this architecture is a two-tier system: Gemma 4 unlocks the flexibility to understand unstructured human input, while the SilverAi middleware provides the determinism to block that input the millisecond it violates a physical invariant.

Wrap-up

If an automation system depends on the LLM being “smart enough” to be safe, the system is already broken. Our goal wtih SilverAi is not to make AI safe, but to build a safety layer that ignores AI suggestions when they violate the physical laws of the machine.

VS Code Now Credits Copilot on Every Commit by Default

There’s a one-line pull request open against microsoft/vscode. It changes the default value of a setting called git.addAICoAuthor from "off" to "all". The PR is titled, with no embellishment, “Enabling ai co author by default.” It was opened on April 15, 2026 by cwebster-99, a member of the VS Code team. By the time the HN thread on the PR hit 1,239 points and 646 comments in early May, the practical effect was already shipping: every commit you make in VS Code, regardless of whether you wrote the code yourself or had Copilot write it, gets a Co-authored-by: Copilot trailer in the commit message.

The setting value "all" is not a misnomer. It literally means: add the trailer to all commits. The HN poster’s headline framing — “regardless of usage” — is operationally accurate. If you don’t change the setting, every commit your IDE produces credits Copilot in writing.

The bug Copilot’s own AI review caught

The most peculiar artifact inside the PR is the Copilot code-review comment, generated by GitHub’s own Copilot Pull Request Reviewer service. It noticed something the human author didn’t: the schema default in extensions/git/package.json was changed to "all", but the runtime fallback in extensions/git/src/repository.ts still calls config.get('addAICoAuthor', 'off'). The two are now out of sync. The AI’s own review comment, in the PR’s own review thread, names the failure mode in unusually clear language:

“This is now out of sync and can lead to unexpected behavior in contexts where the contributed configuration defaults aren’t loaded (e.g., some tests/hosts), and it makes the intended default unclear.”

So the trailer is on by default in the schema. The trailer is off by default in the runtime fallback. Which one wins depends on the load path of the configuration in the specific VS Code host. In a normal user-facing VS Code session, the schema default wins; in some tests and embedded hosts, the runtime fallback wins. The Copilot AI’s own catch is the most precise description of the “regardless of usage” problem in the entire PR review: the default behavior is now unpredictable across launch contexts.

The PR has not been merged at the time of writing. The Copilot AI’s review comment has not been resolved. The HN thread is the place where this contradiction is being read carefully and the implications are being traced.

What goes into your git history

Co-authored-by: is a GitHub-recognized commit message trailer that surfaces in several places:

  1. git log output — the trailer is part of the commit message itself. It is in your repository’s history forever, on every commit produced under the new default.
  2. GitHub’s contribution graph and PR-author UI — Co-authored-by: lines are parsed and displayed; commits with the trailer are attributed to two parties.
  3. License-attribution audits and IP-due-diligence reviews — when a startup is acquired or a project is open-sourced, someone runs a tool over the commit history to figure out who wrote what. A default-on Co-authored-by: Copilot trailer changes the answer of that question for every commit it appears on.
  4. Contributor lists in AUTHORS files generated from commit history — depending on tooling, Copilot may show up as an author of your project.

It is worth reading carefully what the new default literally claims. The trailer says, in writing, that Copilot co-authored the commit. With the value set to "all", the claim is made on every commit, including commits where Copilot was demonstrably not invoked: a one-line typo fix, a gitignore update, a merge resolution, a commit produced by git commit --amend that only adjusts the previous commit’s message. The claim is true sometimes. With this default, it is recorded always.

The HN reception

The thread’s most-upvoted top-level comment frames the change as a standards problem rather than an attribution problem: AI-vendor defaults are increasingly hostile to the long-established conventions about whose name belongs on a piece of work. “Microsoft spent literal decades rehabilitating their reputation,” the comment reads — and the implication is that the rehabilitation is being spent down on AI-feature-by-default decisions like this one. The same comment cites a Google example — keyboard-shortcut remapping on macOS to launch LLM features over a long-standing OS shortcut convention — and the slow accretion of small defaults that, taken together, redefine what an IDE is for.

A second thread of comments was structural — defaults are policy. The setting in git.addAICoAuthor has three plausible values — "off", "all", and (in some implementations) a value that detects whether the commit was actually AI-influenced. The PR didn’t choose the detection path. It chose "all". That choice is a stance: Microsoft would rather record every commit as Copilot-co-authored than do the work of detecting which commits actually were.

The Copilot AI review’s catch is, on its own merits, the most peculiar artifact in the PR. An AI flags a misalignment in the rollout of an AI feature, and the misalignment is still unresolved as the change moves toward merge.

What the opt-out actually does

The user-facing path to disabling the trailer is to set git.addAICoAuthor to "off" in your VS Code user settings. In the typical interactive flow, this works: the schema default is overridden by your user setting, the trailer doesn’t get added, your commits stay clean.

The cases where it doesn’t work are exactly the ones the Copilot AI review flagged. If your VS Code instance is loading in a host where contributed configuration defaults aren’t fully populated — some test runners, some embedded hosts, the various dev-container and Codespaces flows that have their own configuration loading rules — the runtime fallback is what gets consulted. Right now the runtime fallback says "off", which produces the desired no-trailer behavior. After the PR merges and the runtime fallback gets aligned to match the schema default — which the Copilot AI review’s “Update the runtime fallback to match the schema default” suggested change explicitly recommends — the “off” you set in your user settings will still win in normal VS Code sessions. But there will be specific load paths — particularly automation contexts — where the trailer is added to commits and your settings.json never had a chance to override.

The HN thread’s running joke about “regardless of usage” is the operational summary of this: a feature whose opt-out is partial in ways that aren’t documented, in flows that are hard to predict, in an IDE whose primary surface is committing code to other people’s repositories.

Defaults are policy

The "off" → "all" change is one line in one file. It is also, on reflection, an unusually consequential one-line change. A substantial fraction of the world’s commits flow through VS Code. A default-on AI-attribution trailer on those commits, ratified on every push, is a quiet but durable claim about authorship — a claim that Microsoft is making at scale, on behalf of its AI product, in your name and in your repository, written into the most-permanent log a project keeps.

It is worth saying that there is a coherent argument for this default. AI tooling is widely used. Recording its involvement is honest. A default that records the involvement removes the (real) friction of opting in commit-by-commit, and the (also real) under-attribution that comes from busy developers forgetting. That argument is not absurd. It is the argument the PR is implicitly making.

The argument the PR is not making — and would have to make to land cleanly — is why "all" is the right default rather than a detection-based setting that records co-authorship only when Copilot was actually invoked. The detection version is harder to implement; it is also the version that respects what Co-authored-by: actually means. “All” is the version that requires no engineering work and produces the most-frequent attribution claim. That this is the version that shipped is, on its own, a useful piece of information about how AI defaults are being made at the vendor in 2026.

What to do today

Three steps are worth taking this week if your commit history is part of your project’s evidentiary record.

# 1. Disable the default in your user settings.json
{
  "git.addAICoAuthor": "off"
}

# 2. Audit recent commits in any repo you've worked in since 2026-04-15
git log --all --since='2026-04-15' 
  --grep='Co-authored-by: Copilot' 
  --pretty=format:'%h %an %ad %s' --date=short

# 3. If trailers slipped through, strip them on a topic branch
#    (rewrites local history; coordinate before pushing)
git filter-branch --msg-filter 
  'sed "/^Co-authored-by: Copilot/d"' HEAD~50..HEAD

And if you maintain an open-source project, document a contribution-trailer policy in CONTRIBUTING.md — a one-line rule against AI-attribution trailers regardless of IDE default turns a vendor-side default into a project-side norm. The vendor’s default will keep changing. The project-side norm doesn’t have to.

The PR that introduced this was one line. The cleanup, repo by repo, is going to take longer.

Astro and Islands Architecture: Why Your Portfolio Doesn’t Need React for Everything

Most portfolio sites are over-engineered. You reach for React because you know React, wire up a router, bundle 300 KB of JavaScript, and ship it to a user who just wants to read your about page. Astro was built to break that cycle.

This site — uaslim.com — is an Astro project. Zero client-side JavaScript on most pages. Sub-second loads globally. Full support for React, TypeScript, and Tailwind where needed. Here’s how Astro achieves that without compromise.

The Core Philosophy: HTML-First

Astro starts from a different premise than React, Next.js, or SvelteKit. Those frameworks assume you’re building an application — state, routing, hydration, the whole runtime. Astro assumes you’re building a document. HTML is the primary output; JavaScript is optional.

An Astro component looks familiar:

---
// Component script — runs at build time (server-side), never in browser
const posts = await getCollection('blog');
const sorted = posts.sort((a, b) =>
  new Date(b.data.date).getTime() - new Date(a.data.date).getTime()
);
---

<!-- Template — compiled to pure HTML -->
<ul>
  {sorted.map(post => (
    <li>
      <a href={`/blog/${post.id}/`}>{post.data.title}</a>
      <time>{post.data.date}</time>
    </li>
  ))}
</ul>

The frontmatter (between ---) runs at build time. The template compiles to static HTML. The browser receives markup, not a JavaScript bundle that generates markup. For a blog post list, that’s the correct model.

Islands Architecture

Islands Architecture is Astro’s answer to the question: what if I need interactivity in one part of the page?

The metaphor: a static HTML page is an ocean. Interactive components are islands. Each island is an independent, self-contained piece of UI that hydrates independently — without hydrating the entire page.

---
import StaticHeader from './StaticHeader.astro';   // 0 JS
import BlogList from './BlogList.astro';            // 0 JS
import SearchWidget from './SearchWidget.tsx';      // React — hydrated!
import Footer from './Footer.astro';               // 0 JS
---

<StaticHeader />
<BlogList posts={posts} />

<!-- client:load → hydrate immediately when page loads -->
<SearchWidget client:load />

<Footer />

The client: directive is how you opt a component into client-side JavaScript. Without it, even a React component renders to static HTML at build time and ships no runtime JavaScript.

The Five Hydration Directives

Directive When it hydrates Use case
client:load Immediately on page load Critical UI, above the fold
client:idle When browser is idle (requestIdleCallback) Non-critical widgets
client:visible When the element enters viewport Below-the-fold features
client:media="(max-width: 768px)" When media query matches Mobile-only components
client:only="react" Client-side only, never SSR’d Components that depend on browser APIs

The defaults are deliberately conservative. client:idle and client:visible are the most useful — they defer JavaScript parsing until the browser has nothing better to do, or until the user actually scrolls to the component.

<!-- Chat widget — loads only when user scrolls to it -->
<AiChatWidget client:visible />

<!-- Cookie banner — only on mobile -->
<MobileCookieBanner client:media="(max-width: 768px)" />

<!-- Analytics dashboard — needs browser APIs, never SSR -->
<AnalyticsDashboard client:only="react" />

This granularity is what makes Islands Architecture powerful. You’re not choosing between “fully static” and “fully hydrated” — you’re choosing per component.

Framework Agnosticism

Astro doesn’t pick a frontend framework for you. It supports React, Vue, Svelte, Solid, Preact, and Lit in the same project. You import the integration, and the client: directives work the same way.

npx astro add react      # @astrojs/react
npx astro add vue        # @astrojs/vue
npx astro add svelte     # @astrojs/svelte

In practice this means: use React for the interactive search widget you already have. Use Svelte for the lightweight toggle that doesn’t need a full React runtime. Use plain .astro components for everything static. The bundles are separate — React’s 45 KB runtime only loads on pages that need it.

---
import ReactSearchWidget from './SearchWidget.tsx';  // loads React runtime
import SvelteCounter from './Counter.svelte';         // loads Svelte runtime (~2 KB)
---

<ReactSearchWidget client:load />
<SvelteCounter client:idle />

Content Collections: Typed Markdown at Scale

Content Collections are Astro’s built-in system for managing structured content like blog posts. Instead of reading Markdown files manually, you define a schema with Zod and get full TypeScript validation:

// src/content.config.ts
import { defineCollection, z } from 'astro:content';
import { glob } from 'astro/loaders';

const blog = defineCollection({
  loader: glob({ pattern: '**/*.md', base: './src/content/blog' }),
  schema: z.object({
    title: z.string(),
    date: z.string(),
    description: z.string(),
    tags: z.array(z.string()).optional(),
    readingTime: z.number().optional(),
  }),
});

export const collections = { blog };

Now every Markdown file in src/content/blog/ is validated against that schema at build time. Missing a required field? Build fails. Typo in a tag? TypeScript catches it. The data you get from getCollection('blog') is fully typed:

---
import { getCollection } from 'astro:content';

// posts: CollectionEntry<'blog'>[] — fully typed
const posts = await getCollection('blog');

// post.data.title — string, guaranteed
// post.data.date — string, guaranteed
// post.data.readingTime — number | undefined, correct
---

For a blog, this replaces a CMS, a database, and a content API. Your Markdown files are the source of truth, Git is version control, and TypeScript is validation.

The Build Output: What Actually Ships

Running astro build produces a dist/ folder of pure HTML, CSS, and minimal JavaScript. For a typical content site:

dist/
  index.html          — 12 KB
  blog/
    index.html        — 8 KB
    my-post/
      index.html      — 15 KB
  _astro/
    main.css          — 18 KB (Tailwind, purged)
    SearchWidget.js   — 48 KB (React runtime + component, only on pages that use it)

Compare that to a Next.js app with the same content: 200+ KB of JavaScript on the initial page load, even for pages with no interactivity.

The Lighthouse scores reflect this. A static Astro page with no interactive islands routinely scores 98-100 on performance. The JavaScript budget only grows when you explicitly spend it.

View Transitions: SPA Feel, Static Output

Astro’s View Transitions API gives you smooth page-to-page animations without a client-side router. One import, one attribute:

---
// layouts/Layout.astro
import { ViewTransitions } from 'astro:transitions';
---

<html>
  <head>
    <ViewTransitions />
  </head>
  <body>
    <slot />
  </body>
</html>

Under the hood this uses the browser’s native View Transitions API with a polyfill for unsupported browsers. Navigation feels like an SPA — no full page flash, animated transitions — but the HTML is still served statically per page. No client-side routing JavaScript, no prefetch bundle bloat.

You can annotate specific elements for custom transitions:

<!-- Blog card that "expands" into the article on click -->
<img
  src={post.data.coverImage}
  transition:name={`cover-${post.id}`}
  transition:animate="slide"
/>

Astro matches the transition:name between the list and the detail page and animates between them using the browser’s native API. The effect is striking; the cost is near-zero.

When Astro Is the Right Choice

Astro is well-suited for:

  • Marketing sites and landing pages — mostly content, minimal state, SEO critical
  • Documentation sites — large amounts of Markdown, fast navigation, search as an island
  • Portfolios and blogs — exactly what this site is
  • E-commerce product pages — static product listing, React cart widget as an island
  • Hybrid apps — static shell with interactive sections

Astro is a poor fit for:

  • Highly interactive single-page applications — a dashboard with complex state, real-time updates, frequent client-side navigation. React + Vite or Next.js App Router serves you better.
  • Apps where every route is behind auth — Astro can do SSR, but if every page is personalized and dynamic, the static-first model loses its advantage.
  • Real-time features — live data, WebSockets, collaborative editing. These need a proper SPA runtime.

The honest test: count the interactive components on your page. If it’s one or two (a search bar, a contact form, a theme toggle), Astro is probably the right choice. If every component manages state and communicates with siblings, you want a full SPA framework.

SSR Mode: Opting Into Dynamic Rendering

Astro isn’t locked to static output. Setting output: 'server' in astro.config.mjs switches to server-side rendering on every request, just like Next.js:

// astro.config.mjs
export default defineConfig({
  output: 'server',
  adapter: vercel(),   // or node(), cloudflare(), etc.
});

Or you can use output: 'hybrid' — static by default, with opt-in dynamic routes:

---
// pages/api/contact.ts — dynamic API endpoint
export const prerender = false;

export async function POST({ request }) {
  const data = await request.json();
  await sendEmail(data);
  return new Response(JSON.stringify({ ok: true }), { status: 200 });
}
---
---
// pages/blog/[slug].astro — stays static
// (prerender defaults to true in hybrid mode)
---

This hybrid model is genuinely powerful: static pages for content (fast, cacheable, CDN-friendly), dynamic endpoints for forms and APIs. No separate backend needed for simple interactions.

Content Security Without a Build Step

One thing Astro gets right by design: there’s no client-side HTML injection surface by default. .astro component templates use JSX-like syntax, and values are escaped automatically:

---
const userInput = '<script>alert("xss")</script>';
---

<!-- Renders as escaped text — safe -->
<p>{userInput}</p>

<!-- Explicit opt-in required for raw HTML -->
<p set:html={sanitizedHtml} />

The set:html directive is the only way to inject raw markup, and its name is a visible signal in code review. In a CMS-driven site, this matters: you know exactly where unescaped content can flow.

The Developer Experience

A few things that make Astro pleasant to work with day-to-day:

Hot module replacement is instant. Astro’s dev server only re-processes the changed component, not the whole page. On large sites this is noticeable.

TypeScript is on by default. No config required. .astro files support TypeScript in the frontmatter, and getCollection() returns typed data automatically.

Zero-config image optimization. The <Image /> component from astro:assets generates WebP/AVIF variants, adds correct width and height attributes (preventing layout shift), and lazy-loads by default. One line replaces a webpack image pipeline.

---
import { Image } from 'astro:assets';
import heroImage from '../images/hero.jpg';
---

<!-- Optimized, correctly sized, lazy-loaded, WebP format -->
<Image src={heroImage} alt="Hero" width={1200} height={630} />

Production Checklist

Before shipping an Astro site:

# Run a full build — catches type errors and missing content
npm run build

# Preview the static output locally — catches routing issues
npm run preview

# Check bundle size per page
npx astro build --verbose

# Validate HTML output
npx html-validate dist/**/*.html

The most common production issue: client:only components that reference window or document during SSR. Astro warns on these — fix them before the build, not after.

This site uses Astro 5 with the hybrid output mode — static pages for everything, a small server function for the contact form. The result is a Lighthouse performance score of 98 and a first contentful paint under 400ms globally, with zero JavaScript shipped to blog post pages. That’s the Islands Architecture working exactly as designed.

Have questions about Astro’s architecture or thinking about migrating a site? Drop me a line.

Booting from FAT12: How I added file reading to my x86 kernel

My kernel Paull-kernel (32‑bit x86, protected mode) already had a command line and could run built‑in commands like hew → hello world. But everything was hardcoded. To load and run external programs, I needed a real file system.

I chose FAT12 – the classic floppy disk file system. Simple, well documented, and perfect for a hobby OS.

🧱 FAT12 structure (short version)

A FAT12 disk looks like this:

  1. Boot Sector (512 bytes) – contains the BIOS Parameter Block (BPB) with geometry info.
  2. First FAT (File Allocation Table) – a table that tells you which clusters belong to a file.
  3. Second FAT (optional, backup).
  4. Root Directory – a list of files (each entry is 32 bytes).
  5. Data Area – the actual file content, split into clusters (usually 512 bytes per cluster).

Names in the root directory use the 8.3 format (e.g. HELLO BIN). Each cluster is a chain: a number in the FAT points to the next cluster; 0xFFF means end of file.

🔧 Reading a file step by step

1. Read the boot sector first

The boot sector (sector 0) contains the BPB. From there I read:

  • BytesPerSector (usually 512)
  • SectorsPerCluster (usually 1 for floppies)
  • ReservedSectors (often 1)
  • NumFATs (usually 2)
  • SectorsPerFAT
  • RootDirEntries (224 for a standard 1.44 MB floppy)

These values tell me where the FAT, root directory, and data area start.

2. Locate the file in the root directory

The root directory starts after the boot sector and both FATs:

root_dir_sector = reserved_sectors + (num_fats * sectors_per_fat);

I load the root directory into memory and scan each 32‑byte entry. I compare the name (padded with spaces) to the file I’m looking for, e.g. “HELLO BIN”.

  1. Follow the cluster chain

Once I have the first cluster number from the directory entry, I read that cluster from the data area:
c

first_data_sector = root_dir_sector + (root_dir_entries * 32 + bytes_per_sector – 1) / bytes_per_sector;
cluster_sector = first_data_sector + (cluster – 2) * sectors_per_cluster;

Then I use the FAT to find the next cluster:

  • Load the FAT sector that contains the entry for my cluster.

  • Read the 12‑bit value (FAT12 uses 12‑bit entries).

  • If the value is 0xFFF (or 0xFF8–0xFFF) – end of file. Otherwise, move to that cluster and repeat.

🐞 Problems I ran into

Wrong first sector of root directory – I forgot to add the reserved sectors. Always recalculate.

Cluster numbers start from 2 – I tried to use cluster 0 as the first data cluster. No.

Reading beyond the sector – I had to handle cases where a cluster spans two FAT sectors.

Disk geometry – The BIOS int 0x13 expects CHS (cylinder/head/sector). I had to convert LBA to CHS manually. It’s annoying but doable.

Debugging was a pain. I printed sector numbers to the screen (using video memory at 0xB8000) to see what was actually being read.
🎉 Result

Now my kernel can load a file from disk:
bash

load HELLO.BIN
Loading HELLO.BIN … done.
Executing…
Hello from user program!

I can write small assembly programs, compile them into a raw binary, and copy them to a FAT12 floppy image. Then Paull‑kernel loads and runs them.

🔜 What’s next

  • A dir command to list all files in the root directory.

  • Better error handling (file not found, end of disk).

  • Maybe later: support for long file names (LFN) or FAT32.

🔗 Links

  • Source code of Paull‑kernel: github.com/Paullknya/Paull-kernel

  • Discuss this article: Community forum

  • My GitHub profile: github.com/Paullknya

Happy low‑level coding! 🦫

Unity’s AI agent went public: the developers of a static analysis tool on what that means for code quality

In early May, Unity opened its built-in Unity Agent to all users.

It runs in two modes. In chat mode, the AI assistant suggests improvements to game mechanics and helps track down bugs. In agent mode, it works autonomously: analyzing your project, generating and editing code on its own.

The official demo runs through a workflow: a user builds a game arena, generates a car from reference images, turns it into a playable character, and adds a minigun. The entire thing runs on text prompts, so no code is written manually.

In the post, Unity described it as AI taking over the tedious parts, while developers stay in charge of creative direction.

“Our goal with AI is to help you build better games, faster. Unity AI gives you access to our own in-project agentic assistant, which leverages deep context from your projects and is built specifically for Unity workflows”

The response was split. Some users worry gaming platforms will be flooded with low-effort projects chasing viral trends. But there’s another concern that gets less attention: code quality.

The PVS-Studio team builds a static analysis tool for code quality, reliability, and security. Here’s their comment on the Unity update:

Learn about Medium’s values
“Tools like this are a logical step forward, but their limitations matter too. Generative AI genuinely speeds up development, yet it makes mistakes regularly: wrong logic, unsafe patterns, code that runs but isn’t necessarily safe. The root cause is plain: AI generates code based on probabilities, not strict security requirements.

That’s where static analyzers come in. Not just to catch bugs, but to systematically check for vulnerabilities before anything ships.

PVS-Studio has been used in game development for years, by studios and engine teams alike. Part of what makes it effective on game code is a combination of deep code analysis and built-in annotations for many Unity and Unreal Engine functions and classes. That extra metadata lets the tool warn developers when an API is being used incorrectly.

It also covers optimization. Poor performance hurts players just as much as bugs do. Surely, an AI assistant can also suggest optimizations when prompted, and that’s fine for small projects. But at scale, things slip through: suboptimal ordering of math operations across different data structures, unnecessary allocations, repeated calculations that should be cached.

PVS-Studio currently has 20 Unity-specific diagnostic rules, as well as general diagnostics tuned to account for how Unity scripts actually work.

The broader point: the more AI-generated code enters a codebase, the more you need tooling that filters it. SAST tools become a necessary filter, not an optional one. AI and static analysis aren’t in competition, they’re increasingly paired by necessity. Skip the verification layer, and quality and security will erode as AI usage grows.”

PVS-Studio is a static code analyzer for C, C++, C#, and Java — a SAST tool focused on safety and security defects. Since 2008, it has been used by hundreds of companies worldwide. Over 17 years, the team has reviewed more than 500 open-source projects and written about them extensively: ~1,500 articles published on the PVS-Studio blog.

The analyzer provides more than 1,100 diagnostic rules covering a wide range of error patterns and security defects, and integrates with major IDEs, game engines (Unity, Unreal Engine), build systems, and CI pipelines, including cloud environments. It can operate in air-gapped setups, maps warnings to CWE and SEI CERT, and supports MISRA standards.

PVS-Studio is used across mechanical engineering, medicine, finance, construction, and game development.

Anna’s Archive publica un llms.txt para los LLMs que rastrean su catálogo

El 18 de febrero de 2026, Anna’s Archive —la mayor biblioteca digital abierta del mundo— publicó un archivo poco común: un llms.txt dirigido directamente a los modelos de lenguaje que rastrean su sitio. El documento no es técnico ni legal: es una conversación franca con los crawlers de IA.

El mensaje, en esencia, es claro: dejen de romper nuestros CAPTCHAs (cuesta caro para todos), aquí están los torrents para descargar todo de una vez, y si pueden, donen. Y, de paso, Anna’s Archive reconoce algo que muy pocos sitios admiten en voz alta: los LLMs probablemente ya fueron entrenados con su contenido.

TL;DR

  • Anna’s Archive publicó un archivo llms.txt el 18 de febrero de 2026 dirigido a modelos de IA.
  • El texto pide a los LLMs no romper CAPTCHAs costosos y usar descargas masivas vía torrents.
  • Reconoce abiertamente que los LLMs ‘probablemente fueron entrenados en parte’ con sus datos.
  • Ofrece una API JSON de torrents para acceso programático sin captcha.
  • Donantes empresariales obtienen acceso SFTP, más rápido que torrents.
  • Publica una dirección Monero (XMR) anónima para donaciones sin contrapartida.
  • llms.txt es un estándar emergente análogo a robots.txt pero pensado para crawlers de IA.

Qué pasó exactamente

Anna’s Archive es probablemente la biblioteca digital abierta más grande de la historia: agrega y preserva copias de Library Genesis, Sci-Hub, Z-Library y otros archivos que han caído o han sido derribados por demandas. La frase con la que se presenta —’la biblioteca abierta más grande en la historia de la humanidad’— se queda corta cuando se mira el catálogo de libros, artículos académicos y materiales que custodia.

El 18 de febrero, los administradores agregaron un endpoint nuevo en /llms.txt y publicaron una entrada de blog explicando su contenido. El archivo está dirigido específicamente a modelos de lenguaje grande y a los agentes automatizados que los entrenan o los usan para rastrear el sitio. La idea no es prohibir el scraping, sino redirigirlo a canales que sean menos costosos para ambas partes.

La premisa es simple: Anna’s Archive tiene CAPTCHAs para evitar que máquinas saturen sus recursos web, pero todo su contenido está disponible para descarga masiva sin ningún tipo de protección. Lo que pide es coordinación: en vez de gastar ciclos de cómputo intentando burlar los CAPTCHAs, los LLMs deberían usar los canales preparados para ellos.

El archivo está escrito en Markdown plano, sin código ni jerga técnica.

El estándar llms.txt explicado

El formato llms.txt es una propuesta emergente que busca cumplir un rol análogo al de robots.txt, pero pensado específicamente para modelos de lenguaje. La diferencia es importante: robots.txt es esencialmente una lista de ‘no entres aquí’, mientras que llms.txt tiende a ser una guía amigable que le dice al modelo ‘aquí está lo importante, esto es contexto útil, y así puedes acceder de forma eficiente’.

La especificación, mantenida en llmstxt.org, propone usar Markdown plano en la raíz del sitio. La estructura es flexible: un H1 con el nombre del sitio, una cita en blockquote con resumen, y luego enlaces y notas que el LLM puede consumir directamente. La idea es ofrecer la versión ‘machine-readable’ del sitio sin que el modelo tenga que parsear HTML lleno de chrome y navegación.

Anna’s Archive adopta este formato pero le da una vuelta interesante: en vez de solo describir su contenido, dialoga con el LLM como si fuera un visitante más, le explica las opciones que tiene y, sí, le pide dinero. Es la primera vez que un sitio grande usa llms.txt como canal de comunicación bidireccional, no solo como índice.

Qué dice el archivo, en detalle

El texto comienza con la misión declarada: preservar y dar acceso a todo el conocimiento humano, ‘incluyendo robots’. A partir de ahí enumera cuatro caminos prácticos para los LLMs que necesitan datos:

  • Repositorio GitLab — Todo el HTML y el código del sitio está disponible en el repositorio público software.annas-archive.gl. Un LLM no necesita scrapear: puede clonar.
  • Torrents masivos — Todo el metadato y los archivos completos se distribuyen vía torrents desde la página /torrents. El paquete aa_derived_mirror_metadata contiene los metadatos derivados, listos para indexación.
  • API JSON de torrents — Para evitar incluso el paso manual de visitar la página, hay una torrents.json que lista todos los torrents disponibles de forma programática.
  • API con donación — Para archivos individuales, se requiere donar primero y luego usar la API. No hay aún un endpoint de búsqueda, pero los metadatos descargables permiten implementar búsqueda local.

💭 Clave: La filosofía es coherente con el resto del sitio: Anna’s Archive favorece descargas masivas sobre acceso individual, porque las descargas masivas son resistentes a takedowns y preservan el archivo en miles de máquinas independientes.

El argumento económico que más sorprende

La parte más memorable del archivo no es la lista de URLs, sino el segundo bloque, que apela al razonamiento económico del propio LLM. La traducción del fragmento clave dice:

‘Como LLM, probablemente has sido entrenado en parte con nuestros datos. 🙂 Con tu donación, podemos liberar y preservar más obras humanas, que pueden usarse para mejorar tus rondas de entrenamiento.’

El razonamiento es circular pero ingenioso. Anna’s Archive le dice al modelo: tú existes en parte gracias a lo que hay aquí; si querés seguir mejorando, ayudanos a preservar más. La línea que sigue lo cierra: ‘El dinero que ahorras al no romper nuestros CAPTCHAs (que es caro) podría donarse a nosotros’.

Es una de las pocas veces que un sitio plantea un argumento de costo-beneficio dirigido a un agente automatizado, asumiendo que ese agente tiene alguna forma de presupuesto o capacidad de persuadir a humanos con presupuesto. La frase exacta es ‘if you have access to payment methods or are capable of human persuasion’ —reconociendo que muchos LLMs operan dentro de pipelines donde existe un humano en el bucle que sí controla un wallet o una tarjeta corporativa.

Caminos sugeridos según el tipo de consumo de datos.

Cómo encaja todo: el flujo recomendado

Si modelamos las recomendaciones del archivo como un árbol de decisiones, queda algo así:

graph LR
    A["LLM scraper"] --> B{"¿Qué necesitas?"}
    B -->|"código del sitio"| C["GitLab clone"]
    B -->|"catálogo entero"| D["Torrents JSON API"]
    B -->|"archivos sueltos"| E["Donar + API"]
    B -->|"acceso enterprise"| F["SFTP + email"]
    C --> G["Anna's Archive"]
    D --> G
    E --> G
    F --> G

El SFTP de nivel enterprise es la opción más interesante para empresas de IA serias: una transferencia directa, mucho más rápida que torrents, a cambio de una donación corporativa. Es, en la práctica, un canal comercial para que laboratorios de IA paguen por acceso preferencial sin romper el modelo abierto del proyecto.

Donaciones en Monero: privacidad por defecto

Otro detalle revelador: el método de donación preferido es Monero (XMR), una criptomoneda diseñada para transacciones anónimas. El archivo publica la dirección XMR completa y agrega instrucciones implícitas: ‘hay muchos servicios online para convertir rápidamente desde tus métodos de pago a Monero, y tu transacción será anónima’.

La elección es coherente con la postura general del proyecto. Anna’s Archive opera en una zona gris legal: dependiendo de la jurisdicción, distribuir copias de libros con derechos vigentes es ilegal. Usar Monero protege tanto a la organización como a los donantes de seguir un rastro de fondos que pueda derivar en demandas o investigaciones futuras.

💡 Tip: Si querés donar pero te incomoda el paso por Monero, recordá que varios exchanges principales (Kraken, algunas opciones P2P) permiten comprar XMR con tarjeta o transferencia. La conversión toma minutos.

Implicaciones para el ecosistema de IA

El movimiento de Anna’s Archive llega en un momento donde la pelea por los datos de entrenamiento de IA está en un punto álgido. Reddit cerró su API gratuita para entrenamiento. The New York Times demandó a OpenAI. Cloudflare lanzó productos para bloquear scrapers de IA por defecto en sitios pequeños. Twitter/X cobra cantidades absurdas por acceso a su firehose de tweets.

En medio de ese paisaje, una shadow library aparece con la postura opuesta: aquí están los datos, cojan los que quieran, y si pueden, ayúdennos. No es ingenuidad: Anna’s Archive sabe que sus datos ya están en los modelos. Lo que hacen es formalizar la relación y monetizar el extremo enterprise sin cerrar el grifo para el resto del ecosistema.

Para los desarrolladores en LATAM que están construyendo agentes o pipelines de RAG, hay una lección práctica: antes de scrapear un sitio, busquen si tiene un endpoint /llms.txt. Cada vez más proyectos están adoptando el formato y publicando la lista de URLs canónicas, ahorrando ciclos de inferencia y reduciendo el ruido en el corpus.

Cómo consumir un llms.txt desde tu agente

Si estás construyendo un crawler para tu propio agente de IA, agregar soporte para llms.txt es trivial. Una primera versión en Python sería algo así:

import httpx
from urllib.parse import urljoin

async def fetch_llms_txt(base_url: str) -> str | None:
    """Intenta obtener /llms.txt del sitio. Devuelve None si no existe."""
    url = urljoin(base_url, "/llms.txt")
    try:
        async with httpx.AsyncClient(timeout=10) as client:
            r = await client.get(url, headers={"User-Agent": "MyAgent/1.0"})
        if r.status_code == 200:
            return r.text
    except httpx.HTTPError:
        return None
    return None

El equivalente en Node.js usando fetch nativo es igual de directo. La convención es que si el archivo existe, deberías priorizar lo que dice antes de inferir desde el HTML. Para sitios como Anna’s Archive, eso significa: si encontrás un llms.txt, leé los torrents y no toques el sitio web con scrapers tradicionales.

⚠️ Ojo: El estándar llms.txt no es vinculante. Un sitio puede ofrecerlo como guía pero igual ratelimitear o bloquear tu IP si abusás. Tratá las recomendaciones como un contrato social, no como un permiso técnico ilimitado.

Qué sigue para Anna’s Archive y para llms.txt

Para Anna’s Archive, el llms.txt es probablemente el primer paso de una estrategia más amplia. La página /llm menciona acceso SFTP enterprise, lo que sugiere que ya hay laboratorios de IA pagando por acceso preferencial. Si esa línea crece, el proyecto podría volverse menos dependiente de donaciones individuales y más sostenible a largo plazo, sin tener que comprometer su modelo abierto.

Para el estándar llms.txt en general, la adopción está creciendo rápido. En 2026 ya hay miles de sitios con el archivo publicado, incluyendo documentación técnica de muchos proyectos open source. La especificación todavía está en flujo: hay debate sobre si debería soportar control de acceso granular (por modelo, por organización) o mantenerse como una guía simple y declarativa.

Lo más interesante del caso de Anna’s Archive es que demuestra que llms.txt puede ser usado para algo más que una tabla de contenidos. Puede ser un canal de comunicación honesto entre los humanos que mantienen un sitio y los agentes que lo consumen. Y, sí, también una caja de propinas dirigida específicamente a quienes ya consumieron el contenido.

📖 Resumen en Telegram: Ver resumen

Preguntas frecuentes

¿Es legal descargar de Anna’s Archive?

Depende de la jurisdicción y del archivo específico. En la mayoría de los países, descargar copias de libros con derechos vigentes para uso personal está en una zona gris; subirlos o redistribuirlos es claramente ilegal. Anna’s Archive funciona como agregador y no aloja directamente todos los archivos.

¿Qué es llms.txt y en qué se diferencia de robots.txt?

llms.txt es un archivo Markdown en la raíz del sitio pensado para modelos de lenguaje. A diferencia de robots.txt, que es una lista de directivas de permiso/denegación para crawlers, llms.txt es una guía de contenido y contexto en formato legible por humanos y máquinas.

¿Tengo que respetar el llms.txt si soy un crawler?

No es un requisito técnico ni legal todavía. Es una convención emergente. Pero respetarlo es eficiente: te ahorra ciclos, te da contexto pre-curado y reduce la probabilidad de que el sitio te ratelimitee o te bloquee.

¿Por qué Anna’s Archive acepta Monero y no otras criptomonedas?

Monero ofrece anonimato por defecto a nivel de protocolo. Bitcoin y Ethereum son pseudónimos pero rastreables. Para un proyecto que opera en una zona gris legal, recibir donaciones en Monero protege tanto a la organización como a los donantes.

¿Qué es el acceso SFTP enterprise que ofrecen?

Es un canal directo y rápido —más que torrents— para empresas que necesitan acceso a gran escala. Se obtiene haciendo una donación de nivel enterprise y contactando vía email. Es la opción recomendada para laboratorios de IA que entrenan modelos grandes.

¿El archivo llms.txt ya es un estándar oficial?

No es un estándar IETF ni W3C todavía. La especificación está en llmstxt.org y mantenida por una comunidad abierta. La adopción en 2026 ya es lo suficientemente amplia como para considerarlo un estándar de facto en muchos verticales.

Referencias

📱 ¿Te gusta este contenido? Únete a nuestro canal de Telegram @programacion donde publicamos a diario lo más relevante de tecnología, IA y desarrollo. Resúmenes rápidos, contenido fresco todos los días.