How I Reverse-Lookup M-Pesa’s Hashed Phone Numbers Using a 7.2 GB Binary File and One S3 Request

At some point, Safaricom quietly changed the M-Pesa Daraja C2B callback payload. The MSISDN field — which used to contain a partially-masked phone number like 2547*****126 — started returning something like this:

fc418dcfe94c732a57f109e85e54d6c2e86f7c2afe6a2a5a6a5e5a9a9a9a9a9

A SHA256 hash. No announcement, no migration guide. Your integration just quietly broke.

This is how I solved it.

The problem

SHA256 is a one-way function. You cannot mathematically reverse it. The only way to recover the original phone number is to hash every possible candidate and check for a match.

For Kenyan Safaricom numbers the search space is 2547XXXXXXXX and 2541XXXXXXXX — exactly 200 million candidates. Hashing all of them on every callback request takes roughly 2 minutes. That’s not a solution, that’s a timeout.

Why the obvious approaches don’t work

Approach Lookup time Problem
Brute-force per request ~2 min Kills every callback before Safaricom’s 5-second timeout
SQLite file ~5–50 ms ~15 GB with indexes, plus query overhead
PostgreSQL ~5 ms Now you need a database server for a Lambda function
Rainbow tables Saves some space Complex, slower than direct lookup, not worth it for a closed 200M space

The insight that unlocked everything: the phone number space is closed and enumerable.

There are exactly 200 million valid numbers. That’s small enough to pre-hash every single one, sort the results, and store them in a flat file. Every subsequent lookup becomes a binary search — ~28 comparisons, sub-millisecond, no server, no dependencies.

Building the database

Each record is 36 bytes: 32 bytes of SHA256 hash + 4 bytes of encoded phone index.

import hashlib
import struct

def hash_number(n: int) -> bytes:
    phone = f"2547{n:08d}" if n < 100_000_000 else f"2541{n - 100_000_000:08d}"
    return hashlib.sha256(phone.encode()).digest() + struct.pack(">I", n)

200 million of these, sorted by hash, packed into a flat binary file = 7.2 GB.

The build is parallelised across all CPU cores — each worker hashes and sorts a chunk independently, then the chunks are merged in a single streaming pass. On a modern laptop it takes 60–120 seconds and requires about 8 GB of free disk space. You only ever build it once.

python msisdn_lookup.py build
# Building hashes.bin...
# Workers: 12
# Done in 73s. Records: 200000000. File: 7.2 GB

Local lookup: binary search

With a sorted flat file, lookup is textbook binary search:

import mmap

def lookup(target_hash: bytes, f) -> str | None:
    mm = mmap.mmap(f.fileno(), 0, access=mmap.ACCESS_READ)
    lo, hi = 0, RECORD_COUNT - 1
    while lo <= hi:
        mid = (lo + hi) // 2
        record = mm[mid * 36 : mid * 36 + 36]
        h, idx = record[:32], struct.unpack(">I", record[32:])[0]
        if h == target_hash:
            return index_to_phone(idx)
        elif h < target_hash:
            lo = mid + 1
        else:
            hi = mid - 1
    return None

~28 iterations. After the OS page cache warms up, repeated lookups are effectively instant.

The Lambda problem — and how uniform distribution solves it

Downloading 7.2 GB inside a Lambda function isn’t viable. But you don’t have to.

SHA256 output is uniformly distributed. That means if you sort 200 million SHA256 hashes, they’re spread evenly across the full 32-byte hash space. The first 8 bytes of any target hash directly estimate its position in the sorted file:

def estimate_position(target_hash: bytes, record_count: int) -> int:
    prefix = struct.unpack(">Q", target_hash[:8])[0]
    max_prefix = (1 << 64) - 1
    return int(record_count * prefix / max_prefix)

This gives you a position estimate accurate to within a few thousand records. Fetch a 2 MB block centred on that position with a single S3 Range GET, binary search within the block — and you’re done. One HTTP request, no cold-start overhead, no database.

import boto3

s3 = boto3.client("s3")

def lambda_lookup(target_hash: bytes) -> str | None:
    pos = estimate_position(target_hash, RECORD_COUNT)

    # Centre a 2 MB window on the estimated position
    start = max(0, (pos - 28_000) * 36)
    end = min(FILE_SIZE, start + 2 * 1024 * 1024)

    resp = s3.get_object(
        Bucket=LOOKUP_BUCKET,
        Key=LOOKUP_KEY,
        Range=f"bytes={start}-{end}"
    )
    block = resp["Body"].read()
    return binary_search_block(block, target_hash, start // 36)

The 2 MB window covers ~55,000 records. Given that the uniform distribution estimate is accurate to well within that range, statistically you will always find your hash in one request.

In practice: ~20 ms including S3 network latency. The Lambda never needs more than 256 MB of memory.

Putting it together in production

The full system is a serverless M-Pesa webhook receiver:

Safaricom callbacks
    → CloudFront (WAF IP allowlist)
    → API Gateway
    → Lambda (parse payload, S3 lookup, DynamoDB write)
    → DynamoDB Stream
    → Zoho Books sync + Google Sheets sync

Running costs at ~500 transactions/day: ~$0.05/month.

The MSISDN lookup adds roughly 20 ms to the confirm handler. The 5-second Safaricom timeout is never a concern.

Try it yourself

The lookup library is open source and has no external dependencies for core use — pure Python stdlib:

github.com/endafk/msisdn-lookup

git clone https://github.com/endafk/msisdn-lookup.git
cd msisdn-lookup
python msisdn_lookup.py build   # one-time, ~90s
python msisdn_lookup.py lookup fc418dcfe94c732a...
# → 254712345678

If you’re building on the Safaricom Daraja API and hit the hashed MSISDN problem, this is probably the fastest solution that exists right now. And if you’re not on M-Pesa — the technique applies anywhere you have a closed, enumerable pre-image space and need sub-millisecond lookups without a database.

Built and deployed in production. The approach came out of necessity — Safaricom’s documentation on the hash change is, to put it generously, sparse.

Why I stopped building “projects” and started building “products.”

After years of freelance “bug fixing,” I realized that the real value isn’t in the code—it’s in the solution.

I’ve spent the last few months building my own Point of Sale (POS) and LMS from scratch using Laravel and React.

The biggest lesson? Database normalization is easy; handling real-world business edge cases (like partial payments and student progress tracking) is the real challenge. Seeing these systems go live on my personal platform, shahzaib.tech, was a huge milestone for my development process.

I’ll be sharing the technical breakdown of these systems over the next few weeks. If you’re into system design or clean PHP architecture, let’s connect!

Let’s Connect:
I’m currently open to long-term roles and complex custom development. You can see my full portfolio and deep dives into my POS and LMS projects at shahzaib.tech.

I Built a Kubernetes Monitoring Stack — And Breaking It Was the Best Part

Architecture

I didn’t build this project to add a line to my resume.

I built it because I kept reading about Prometheus and Grafana, nodding along like I understood it, and then freezing when someone asked me “so how does Prometheus actually discover your pods?”

I didn’t know. Not really.

So I decided to stop reading and start breaking things.

What I built

A complete observability pipeline from scratch:

  • A Python Flask app with custom Prometheus metrics
  • Deployed on Kubernetes with 3 replicas
  • Scraped by Prometheus via ServiceMonitor
  • Visualized in Grafana with PromQL dashboards
  • Load tested with real traffic using hey

The repo is here if you want to follow along:
👉 github.com/adil-khan-723/k8s-observability-stack

Architecture

But the code isn’t the interesting part. What I learned by watching it fail is.

Mistake #1 — I used raw counters in Grafana and wondered why nothing made sense

First dashboard. I added http_requests_total as a panel. The number just kept climbing. 1000. 5000. 23000.

I stared at it thinking “okay… is that good?”

It tells you nothing. A counter that only goes up is like a car’s odometer — it doesn’t tell you how fast you’re going right now.

The correct query is:

sum(rate(http_requests_total[1m]))

rate() calculates requests per second over the last minute. That’s a number you can actually act on. After switching to this, I could see exactly when traffic spiked during load testing and when it dropped off.

Lesson: metrics alone are useless. PromQL creates insight.

Mistake #2 — I set the rate window too large and hid all my spikes

Once I had rate() working, I noticed my graph looked… suspiciously smooth. Almost like nothing was happening even during load tests.

I was using rate(http_requests_total[8m]). An 8-minute window averages out everything. A spike that lasted 30 seconds disappears completely.

Switched to [1m]. Suddenly I could see exactly what happened during the load test — a sharp climb, a plateau, a drop. Real information.

The dashboard also had stacked graphs enabled. Stacking makes it look like total traffic is the sum of all the colored areas, which is visually misleading when you’re trying to compare per-pod behavior. Disabled it immediately.

Mistake #3 — Prometheus showed all targets DOWN and I had no idea why

This one took me a while.

I ran load tests, checked Prometheus UI under Status → Targets, and saw this:

context deadline exceeded

All 3 pods. All DOWN.

My first instinct was to blame the ServiceMonitor config. I triple-checked the labels. Everything matched. The problem wasn’t discovery — Prometheus was finding the pods fine. It just couldn’t scrape them in time.

Root cause: I had a time.sleep(2) sitting in my home route. This slowed down the entire Gunicorn worker. When Prometheus tried to hit /metrics, sometimes the worker was busy sleeping and the scrape timed out.

The fix was two things:

  1. Increased the scrape interval in serviceMonitor.yaml to give more breathing room
  2. Removed the artificial delay (or accounted for it explicitly)

Watched all 3 targets flip back to UP in real time. That was a good moment.

The deeper lesson: your monitoring system depends on your application’s performance. A slow app breaks its own observability. This is why you should never put business logic on the /metrics endpoint.

Mistake #4 — I assumed Running meant healthy

After fixing the scrape issue, I noticed something strange. kubectl get pods showed all pods as Running. But requests were still failing intermittently.

I had been treating Running as “everything is fine.” It isn’t.

Running just means the container process started. It says nothing about whether the application inside is actually ready to serve traffic. A pod can be Running while your Flask app is still initializing, or while it’s in a broken state that hasn’t crashed the process.

The fix was a readinessProbe:

readinessProbe:
  httpGet:
    path: /metrics
    port: 5000
  initialDelaySeconds: 5
  periodSeconds: 5
  failureThreshold: 2

Once this was in place, Kubernetes automatically removed unhealthy pods from the Service’s endpoint list. Traffic only went to pods that were actually ready. The intermittent failures stopped.

Running ≠ healthy. Readiness probes are not optional.

The thing that surprised me most — load isn’t evenly distributed

During load testing I split the Grafana panel to show per-pod request rates:

rate(http_requests_total[1m])

I expected three roughly equal lines. What I got were three noticeably different ones. One pod was consistently getting more traffic than the others.

Kubernetes Services use round-robin at the connection level, not the request level. Under high concurrency, some pods end up holding more long-lived connections and therefore handle more requests.

If I had only been looking at sum(rate(http_requests_total[1m])) — the aggregate — I would never have seen this. The sum looked perfectly healthy. The per-pod view told a completely different story.

This is why per-pod metrics exist. Aggregates hide things.

What the ServiceMonitor actually does (and why it’s confusing at first)

The part that confused me most before building this was the relationship between Prometheus and Kubernetes.

Prometheus doesn’t scrape pods. It scrapes Services. And it discovers those Services through a custom resource called a ServiceMonitor.

The chain looks like this:

ServiceMonitor → matches Service labels → Service resolves to Pod IPs → Prometheus scrapes each pod

For this to work, three things have to align exactly:

  • The ServiceMonitor’s selector must match the Service’s labels
  • The ServiceMonitor’s namespace must have the release: monitoring label (or whatever your Helm release is named)
  • The namespaceSelector must point to where the Service lives

Get any one of these wrong and Prometheus simply never discovers the target. No error. Just silence. This is the part where most people spend hours debugging.

What I’d add next

  • Alertmanager — fire alerts when scrape targets go DOWN or error rate spikes
  • HPA — autoscale pods based on custom Prometheus metrics
  • Loki — correlate logs with metric anomalies
  • Pinned dependency versions — requirements.txt currently has no versions, which is a reproducibility risk

Final thought

The most valuable part of this project wasn’t setting up Prometheus or building the Grafana dashboard. It was the moment I saw context deadline exceeded and had to actually figure out why.

You don’t learn observability by reading about it. You learn it by watching your own system fail and having to diagnose it with the tools you built.

If you’re learning DevOps or platform engineering, build something, break it, and read the metrics.

Repo: github.com/adil-khan-723/k8s-observability-stack

Have you run into similar issues with Prometheus scraping? Drop it in the comments — would love to hear what weird things you’ve debugged.

Regression Fear in AI-Generated Codebases — Why Every PR Feels Like a Gamble

“Every PR is a gamble. We just don’t know what it’ll break.”

If your team has stopped merging on Fridays — or Thursdays — you’re experiencing regression fear. Not a psychological problem. A structural one.

This post explains the mechanism, how to measure it, and the fix.

The Mechanism: Unbounded Blast Radius

In a well-structured codebase, a change in module A affects module A and its direct dependents. The blast radius is bounded and predictable.

In most AI-generated codebases past month 3, the blast radius is unbounded:

BLAST RADIUS MAP

  Change: update pricing display

  PREDICTED impact:        ACTUAL impact:
  pricing/ui.tsx           pricing/ui.tsx
                           payments/checkout.ts
                           users/dashboard.tsx
                           notifications/email.ts

  predicted: 1 file        actual: 4 files
  blast radius: unbounded

The mechanism: AI generates code that works by taking the shortest path. That shortest path often creates implicit dependencies — shared state, cross-module imports, business logic in unexpected places. Each implicit dependency extends the blast radius of every future change.

Detection: Three Measurements

1. Regression Ratio

# Total commits in last 30 days
TOTAL=$(git log --oneline --since="30 days ago" | wc -l)

# Fix/revert commits
FIXES=$(git log --oneline --since="30 days ago" 
  --grep="fix|revert|hotfix|broken|rollback" | wc -l)

echo "Regression ratio: $(( FIXES * 100 / TOTAL ))%"

What the number means:

  • 0-10%: Normal. Minor regressions caught early.
  • 10-20%: Warning. Coupling is growing.
  • 20%+: Critical. One in five commits fixes something a previous commit broke.

2. Cursed Files

git log --since="90 days ago" --pretty=format: --name-only 
  | sort | uniq -c | sort -rn | head -10

These are the files that appear in the most commits. In AI-generated codebases, the top 3 files are usually:

  • The largest files (500+ lines, multiple domains)
  • The files where regressions originate
  • The files nobody wants to touch

3. Merge Velocity Trend

# Commits per week for last 12 weeks
for i in $(seq 0 11); do
  START=$(date -d "$((i+1)) weeks ago" +%Y-%m-%d)
  END=$(date -d "$i weeks ago" +%Y-%m-%d)
  COUNT=$(git log --oneline --since="$START" --until="$END" | wc -l)
  echo "Week -$i: $COUNT commits"
done

A declining trend means the team is merging less frequently — not because they’re doing less work, but because each merge is riskier.

Why “More QA” Doesn’t Fix This

QA catches regressions after they happen. It does not prevent the architectural condition that causes them.

The regression cycle:

  1. Developer ships change. Passes unit tests.
  2. QA finds regression in unrelated area. Files bug.
  3. Developer context-switches back. Debugs for hours.
  4. Fix introduces new side effect. Cycle repeats.

Adding more QA people makes the cycle faster — not shorter. The root cause remains: unbounded blast radius.

The Cost

A team of three developers at $150/hour loaded:

  • 30% of features cause regressions = 2.4/month
  • 6 hours average to find, diagnose, fix each
  • $2,160/month = $25,920/year in regression costs alone

Plus velocity decay:

Month 3:  8 features/month (productive)
Month 6:  5 features/month (fear + overhead)
Month 9:  3 features/month (regression management dominates)

The Structural Fix: Bounded Blast Radius

Step 1: Identify Cursed Files

Run the cursed files detection above. The top 3 files are your decomposition targets.

Step 2: Map Implicit Dependencies

For each cursed file, trace what depends on it:

# Find all files that import from the cursed file
grep -rln "from.*cursedFile|require.*cursedFile" 
  --include="*.ts" --include="*.tsx" src/

Step 3: Decompose by Domain

Split cursed files by business domain. Each new file has one responsibility and explicit imports.

Step 4: Enforce One-Directional Dependencies

# Verify no circular dependencies exist
npx madge --circular --extensions ts,tsx src/

After decomposition, the dependency graph should be a tree, not a web.

Step 5: Add Regression Tests for Boundaries

For each module boundary, add a test that verifies the contract:

// Test that pricing module doesn't depend on notification module
import { getPrice } from '@/modules/pricing';

test('getPrice returns number without side effects', () => {
  const result = getPrice({ plan: 'pro', period: 'monthly' });
  expect(typeof result).toBe('number');
  // No notifications sent, no user state changed
});

Step 6: CI/CD Enforcement

Block merges that:

  • Introduce circular dependencies
  • Exceed file size thresholds
  • Miss test coverage on boundary contracts

The Result

After structural enforcement, the blast radius of every change is bounded and predictable. QA becomes verification — confirming bounded changes work as expected — not discovery of unrelated breakage.

Regression fear disappears. Not because the team is braver. Because the architecture makes cross-module leakage structurally impossible.

This is part of the AI Chaos series — a structural analysis of failure patterns in AI-generated codebases. Based on ASA (Atomic Slice Architecture) — an open architecture standard for AI-generated software.

Resources

  • ASA Standard — the open specification
  • GitHub — source, examples, documentation
  • Vibecodiq — structural diagnostics for AI-built apps

Automating Clinical Data Analysis: The Pipeline From Hospital Exports to Paper Drafts

Cover

Automating Clinical Data Analysis: The Pipeline From Hospital Exports to Paper Drafts

Cover

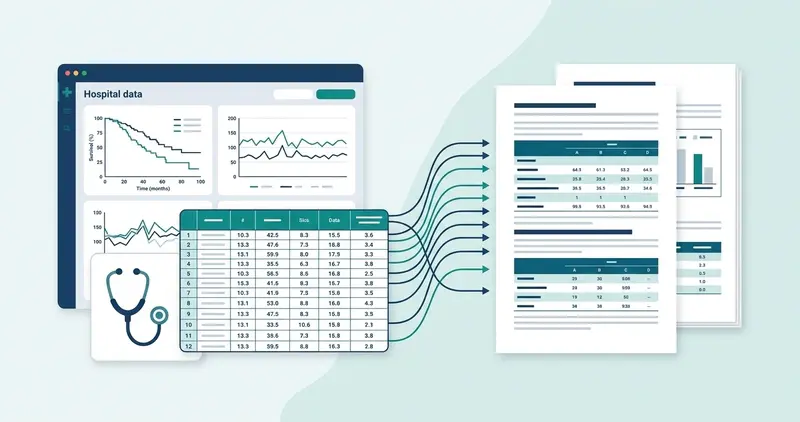
I’ve been building Data2Paper — a tool that turns research data into complete paper drafts. The latest challenge: handling clinical datasets from hospital systems.

If you’ve never worked with hospital data exports, here’s what makes them… fun.

The input problem

A typical clinical data export looks like this:

PatientID | Age | Sex | HbA1c | SBP | DBP | eGFR | Dx | AdmDate | DisDate | Status
001       | 67  | M   | 8.2   | 145 | 92  |      | T2DM | 2024-01-15 | 01/25/2024 | alive
002       | 54  | F   |       | 128 | 78  | 85   | 2型糖尿病 | 20240203 | 2024-02-10 | 
003       | -5  | M   | 7.1   | 300 | 85  | 92   | type 2 DM | 2024-03-01 | 2024-03-08 | dead

Notice: three different date formats in the same column, the same diagnosis coded three different ways, an obviously wrong age, a systolic BP that’s probably a data entry error, missing values that could mean “not tested” or “not recorded,” and mixed languages.

This is normal. Every clinical researcher I’ve talked to confirms: this is what the export looks like.

The analysis pipeline

Raw export (CSV/XLSX)
│
├─ Structure detection
│   └─ row = patient? visit? wide? long?
│
├─ Data cleaning
│   ├─ Date format standardization
│   ├─ Coding unification ("T2DM" = "2型糖尿病" = "type 2 DM")
│   ├─ Outlier flagging (SBP=300, Age=-5)
│   └─ Missing value classification (not tested vs not recorded)
│
├─ Variable typing
│   ├─ Continuous (age, HbA1c, eGFR)
│   ├─ Categorical (sex, diagnosis, comorbidities)
│   └─ Time-to-event (survival time + censoring status)
│
├─ Statistical analysis (Python execution)
│   ├─ Baseline table with per-variable test selection
│   ├─ Regression (logistic / Cox / linear / Poisson)
│   ├─ Survival analysis (KM + log-rank)
│   └─ Diagnostic evaluation (ROC + AUC)
│
└─ Output generation
    ├─ Formatted tables (baseline, regression results)
    ├─ Figures (KM curves, ROC curves, forest plots)
    └─ Manuscript sections (methods + results)

Key technical decisions

Python execution, not LLM computation. Statistics must be verifiable. The LLM writes the interpretation; scipy, statsmodels, and lifelines compute the numbers.

Clinical variable lookup. Recognizing “SBP” as systolic blood pressure enables domain-aware outlier detection (flag 300 mmHg as likely error) rather than purely statistical outlier methods.

Assumption checking. Every statistical test includes prerequisite verification — normality for parametric tests, events-per-variable for logistic regression, proportional hazards for Cox. Running analysis without assumption checks is the #1 reason clinical papers get sent back by reviewers.

The baseline table problem

Generating Table 1 (baseline characteristics) sounds simple but requires per-variable logic:

for variable in dataset:
    if is_categorical(variable):
        # n (%), chi-square or Fisher's exact
    elif is_normal(variable):
        # mean ± SD, t-test or ANOVA
    elif is_skewed(variable):
        # median (IQR), Mann-Whitney or Kruskal-Wallis

The tricky part is automating the normality decision and handling the edge cases (small cell counts triggering Fisher’s instead of chi-square, for instance).

Stack

  • Next.js + Vercel
  • Claude API for text generation
  • Python chain for statistical computation
  • Export: PDF / DOCX / LaTeX / ZIP
  • 7 output languages

What I’m still figuring out

  • Better heuristics for distinguishing “not tested” vs “not recorded” missing values
  • Automated detection of wide vs long format in longitudinal datasets
  • Handling mixed-language clinical notes in the same dataset

If you’ve worked on similar problems — clinical data pipelines, automated statistical analysis, or structured document generation from data — I’d love to compare notes.

datatopaper.com

EditThisCookie Got Removed — So I Built a Modern Cookie Editor for Chrome

If you’ve ever worked with cookies during web development, you probably used EditThisCookie. It was the go-to Chrome extension for inspecting, editing, and deleting cookies. Over 3 million users relied on it daily.

Then one day, it vanished from the Chrome Web Store.

Google pulled it because it was still running on Manifest V2 — the old extension platform that Chrome has been phasing out since 2023. The situation got worse when copycat extensions appeared, some of which turned out to contain malware. The developer community was left scrambling for a trustworthy replacement.

I was one of those developers who depended on EditThisCookie for everyday work. After trying several alternatives and finding them lacking, I decided to build my own. The result is CookieJar — a Manifest V3 cookie manager designed from the ground up for how developers actually work with cookies in 2026.

This article walks through five real-world use cases where CookieJar saves time, and explains how its privacy scoring feature helps with compliance audits.

The Problem with DevTools Alone

Chrome DevTools has a built-in cookie viewer under the Application tab. It works, but it was never designed as a productivity tool. Want to switch between two sets of cookies? Copy each value by hand. Want to export cookies for a teammate? No built-in option. Want to know which cookies are tracking you? You’ll need to look up each domain yourself.

For one-off inspections, DevTools is fine. But when cookie manipulation is part of your daily workflow — testing auth flows, managing environments, auditing third-party trackers — you need something purpose-built.

Use Case 1: Switching Between Login Sessions Instantly

The scenario: You’re building a web app with role-based access. You need to verify that the admin dashboard shows different UI elements than the regular user view, and that unauthenticated visitors see the correct landing page.

The old way:

  1. Log in as admin, verify the dashboard
  2. Log out
  3. Log in as a regular user, check restricted pages
  4. Log out
  5. Open an incognito window for the unauthenticated view
  6. Repeat every time the UI changes

This cycle can eat 5-10 minutes per round, and you’re limited to two simultaneous sessions (regular + incognito).

With CookieJar profiles:

CookieJar’s profile feature lets you snapshot an entire set of cookies and restore them with one click. Here’s the workflow:

  1. Log in as admin. Open CookieJar and save the current cookies as an “Admin” profile.
  2. Log out, log in as a regular user, and save that as “Regular User.”
  3. Save the logged-out state as “Anonymous.”

From that point on, switching roles means clicking a profile name. CookieJar uses chrome.cookies.set to restore every cookie in the profile — session tokens, CSRF tokens, feature flags, all of it. No more logging in and out.

This is especially valuable for QA engineers who test multi-role applications. Instead of maintaining a spreadsheet of test credentials and going through login flows repeatedly, they can set up profiles once and switch instantly.

Use Case 2: Managing Cookies Across Staging and Production

The scenario: You’re debugging a feature that behaves differently on staging and production. Each environment has its own session cookies, feature flags, and debug settings. Every time you switch environments, you lose your cookie state and have to set everything up again.

With CookieJar profiles:

Create an environment profile for each context:

  • “Staging” — session cookie, debug mode flag, feature flags for the staging environment
  • “Production” — production session, standard feature flags
  • “Staging + Debug” — staging session plus verbose logging cookies

Switching between environments is a single click. But the real productivity gain comes from sharing: CookieJar supports JSON and Netscape format export/import. When a new team member joins, you can hand them a JSON file and say “import this to access staging.” No more writing setup documentation that goes stale.

The Netscape format is the same one used by curl’s -b flag, so exported cookies work directly with command-line testing:

curl -b cookies.txt https://staging.example.com/api/user/me

This eliminates the awkward dance of copying cookies from DevTools into curl commands character by character.

Use Case 3: Forcing A/B Test Variations

The scenario: Your team is running an A/B test. The product manager wants to see variation B, but they keep getting assigned to variation A. The engineer responsible for the test is in a different timezone.

With CookieJar:

Most A/B testing frameworks store the variant assignment in a cookie. The challenge is finding the right cookie among dozens or hundreds on a page.

CookieJar automatically classifies every cookie into six categories: Essential, Functional, Analytics, Advertising, Social, and Unknown. A/B test cookies typically fall under Functional or Analytics, which immediately narrows the search.

The workflow:

  1. Open CookieJar’s popup and use the search bar to filter by keywords like experiment, variant, ab_test, or your framework’s naming convention (e.g., optimizely, vwo, split)
  2. Find the variant cookie — it’s visually tagged with a category badge
  3. Click to edit, change the value (e.g., from control to variation_b)
  4. Reload the page

What used to require digging through DevTools’ flat cookie list becomes a quick search-and-edit operation. The category badges provide visual context that makes the right cookie easier to spot.

Use Case 4: GDPR and Privacy Cookie Audits

The scenario: Your company needs to update its privacy policy and cookie consent banner. Legal wants a complete inventory of all cookies your site sets, categorized by purpose, with details about which ones are third-party trackers.

This is one of those tasks that nobody wants to do manually. A typical e-commerce site might set 40-80 cookies, and classifying each one means looking up domain ownership, checking known tracker lists, and documenting the results.

With CookieJar’s Privacy Score:

CookieJar includes a privacy scoring system that gives you an immediate read on any site’s cookie hygiene. When you open the popup, a circular gauge in the header shows a 0-100 score for the current site.

The score is calculated from three factors:

  • Tracking cookie ratio — the proportion of cookies classified as tracking-related (this has the highest weight)
  • Third-party cookie ratio — cookies set by domains other than the one you’re visiting
  • Security attribute coverage — how many cookies have Secure and HttpOnly flags set

The score maps to a color scale: green (80+, Good), yellow (60-79, Fair), orange (40-59, Poor), and red (below 40, Bad).

A practical audit workflow:

  1. Navigate to your site and check the Privacy Score for a quick overview
  2. Use the category filter to isolate “Advertising” cookies — these are the ones most relevant to GDPR consent
  3. Review each cookie’s domain to identify third-party trackers
  4. Export the full cookie list as CSV for documentation

CookieJar’s classification engine combines the Disconnect.me tracking domain list with pattern matching on common cookie names. Cookies named _ga or _fbp are classified as Analytics/Advertising; session or csrf land in Essential. Everything runs locally — no data is sent to any external server.

A word of caution: automated classification is a starting point, not a final answer. Always verify the actual purpose of each cookie against your codebase and third-party documentation before including it in a legal document.

Use Case 5: Exporting Cookies for E2E Test Automation

The scenario: Your Playwright or Puppeteer test suite starts every test run by going through the login flow. This adds 5-15 seconds per test and occasionally fails due to rate limiting or slow authentication services. You want tests to start from an authenticated state.

With CookieJar’s export formats:

CookieJar supports five export formats, each designed for a specific workflow:

Format Use Case Availability
JSON Import/export between CookieJar instances Free
Netscape curl commands (curl -b cookies.txt) Free
cURL Ready-to-run curl command with cookie header Pro
Puppeteer/Playwright await context.addCookies(...) code snippet Pro
CSV Spreadsheet audits and documentation Pro

The Puppeteer/Playwright export is particularly useful. Log in to your app in the browser, open CookieJar, and export. You get a JavaScript snippet that you can drop directly into your test setup:

// Generated by CookieJar export
await context.addCookies([
  {
    name: 'session_id',
    value: 'abc123...',
    domain: '.example.com',
    path: '/',
    httpOnly: true,
    secure: true,
    sameSite: 'Lax'
  },
  // ... other cookies
]);

Paste this into your beforeEach or global setup, and your tests start authenticated. No login flow, no flaky waits, no rate limit issues.

The Netscape format pairs well with backend testing. When you need to hit an authenticated API endpoint from the command line:

curl -b exported-cookies.txt https://api.example.com/v1/protected-resource

No more manually copying cookie values from the browser.

Under the Hood: Why Manifest V3 Matters

If you’re wondering why the Manifest V2/V3 distinction matters for a cookie editor, here’s the short version: MV3 extensions run in a sandboxed service worker instead of a persistent background page. This means better security, lower memory usage, and alignment with Chrome’s long-term extension platform.

Extensions that were built on MV2 and never migrated — like the original EditThisCookie — stopped working when Chrome enforced the transition. Some hastily ported alternatives cut corners, leading to the malware incidents that made headlines.

CookieJar was designed for MV3 from day one. The background service worker handles cookie classification, change monitoring, and profile management. The popup and side panel are separate React-based UIs that communicate with the service worker through Chrome’s messaging API. There’s no persistent background page consuming resources.

What CookieJar Does Not Do

Transparency matters, so here’s what CookieJar intentionally avoids:

  • No data leaves your machine. All classification, scoring, and storage happens locally using Chrome’s storage API. There are no analytics calls, no telemetry, and no external API requests for cookie classification.
  • No network requests for functionality. The Disconnect.me tracker list and name patterns are bundled with the extension, not fetched at runtime.
  • No hidden permissions. The extension requests cookies, storage, activeTab, and tabs — the minimum needed for its features.

Getting Started

CookieJar is free for core features (viewing, editing, deleting, searching, filtering, privacy score, JSON/Netscape export). Pro features (profiles, auto-cleanup, Puppeteer/Playwright export, CSV export) are available through a one-time payment.

The extension supports 8 languages: English, Japanese, Spanish, Portuguese (BR), Korean, German, French, and Italian.

If you’re migrating from EditThisCookie, the transition is straightforward — CookieJar reads the same Chrome cookies API, so all your existing cookies are visible immediately after installation. There’s nothing to import or configure.

Install CookieJar from the Chrome Web Store:


Chrome Web Store

favicon
chromewebstore.google.com

If you found this useful, I’d appreciate a like or a bookmark. Questions or feature requests? Drop a comment below or open an issue on the extension’s support page.

Other tools I’ve built:


OnPageX – On-Page SEO Analyzer & Meta Tag Checker – Chrome Web Store

Analyze meta tags, headings, schema markup, images & links in one click. Get SEO scores, find issues & export reports. Free forever.

favicon
chromewebstore.google.com


DataPick – No-Code Web Scraper & Data Extractor – Chrome Web Store

Scrape data from any website with point-and-click. Export to CSV, Excel, or Google Sheets. Save recipes to automate. No code needed.

favicon
chromewebstore.google.com

UK Skilled Worker Visa Salary Thresholds 2026: Technical Reference for HR Systems and Compliance Tools

If you’re building HR software, an ATS, or a compliance tool for UK employers, understanding how the Skilled Worker visa salary thresholds work is essential for keeping your data models and validation logic accurate. These thresholds changed significantly in April 2024, and getting them wrong in your system means your users could be issuing non-compliant Certificates of Sponsorship.

This post breaks down the threshold logic technically, so you can implement it correctly.

The Core Threshold Logic

The minimum salary for a Skilled Worker visa is not a single flat number. It’s the maximum of two values:

min_salary = max(general_threshold, soc_going_rate)

Where:

  • general_threshold = £38,700 (as of April 2024)
  • soc_going_rate = the published going rate for the worker’s SOC 2020 code

This means your system needs to store and look up going rates by SOC code, not just apply a flat salary check.

The New Entrant Reduction

A “new entrant” discount applies to certain candidate profiles. When the new entrant condition is met, the effective threshold reduces to 70% of the going rate, with a hard floor of £30,960.

if is_new_entrant:
    min_salary = max(0.7 * soc_going_rate, 30960)

A worker qualifies as a new entrant if any of these conditions are true:

  • Age < 26 at the date of application
  • Switching from a Student or Graduate visa
  • In the first 12 months of a PhD-level role (SOC skill level 6)

This is a boolean OR across three independent conditions — important to model correctly if you’re building eligibility checking logic.

Qualifying Salary: What Counts

Not all compensation counts toward the salary threshold. Your data model needs to distinguish:

Counts toward threshold:

  • Basic salary (guaranteed, contractual)
  • Guaranteed allowances (e.g. London weighting if contractually fixed)

Does NOT count:

  • Bonuses (discretionary or performance-based)
  • Commission
  • Overtime pay
  • Non-guaranteed allowances

In practice, this means you should validate against guaranteed_annual_pay, not total_compensation. If your system imports total package values from payroll, you’ll need a separate field for the guaranteed base component.

Part-Time Roles: Hourly Rate Check

For part-time workers, the Home Office validates the hourly rate, not just the prorated annual salary. The check is:

hourly_rate = guaranteed_annual_pay / (hours_per_week * 52)
going_rate_hourly = soc_going_rate / (37.5 * 52)  # standard full-time hours

hourly_rate >= going_rate_hourly  # must be true

This means a part-time worker cannot simply be paid a prorated version of the going rate at a lower hourly figure — the hourly rate must match. Systems that only check annual salary will miss this.

Health and Care Worker Sub-Route

The Health and Care Worker visa (a sub-route of Skilled Worker) uses NHS Agenda for Change pay bands rather than the standard going rate table. The SOC codes in scope for this route are defined separately in Appendix Health and Care Visa.

If you’re building for the health sector, your threshold logic needs to branch:

if visa_route == 'health_and_care':
    min_salary = get_nhs_band_minimum(soc_code, band_point)
else:
    min_salary = max(general_threshold, soc_going_rate)

NHS pay bands are updated annually (typically April), so you’ll want a versioned reference table rather than hardcoded values.

Keeping Going Rate Data Current

The Home Office publishes going rates in Appendix Skilled Occupations, which is updated periodically. This is the canonical data source. If your system stores going rates, you need a process to detect and apply updates — a change that’s easy to miss can invalidate a batch of sponsorships.

For quick eligibility checks without building your own parser and sync pipeline, tools like ImmigrationGPT provide a query interface over current threshold data, which can be useful for rapid validation or prototyping before you invest in a full integration.

Summary: Validation Checklist

When your system checks Skilled Worker salary compliance, it should verify:

  1. SOC code is on the eligible occupations list
  2. min_salary = max(general_threshold, soc_going_rate) (or new entrant variant)
  3. Only guaranteed pay counted in guaranteed_annual_pay
  4. For part-time: hourly rate >= going rate hourly equivalent
  5. Health and Care route uses NHS band logic, not standard going rate

Getting this right protects your users from inadvertently issuing non-compliant sponsorships — and from the audit and licence revocation risk that follows.

This article contains general information only. For advice specific to your situation, consult a qualified immigration lawyer.

Why Browser Agents Waste 99% of Their Tokens (And How to Fix It)

Every browser agent pays a hidden tax: tokens.

When an agent visits a webpage, it dumps the DOM into an LLM. The LLM reads thousands of elements, reasons about which button to click, and generates a tool call. Then it does it again. And again.

For a 10-step workflow, that’s 25+ LLM round trips. Context grows with each step because conversation history accumulates. By step 10, you’re sending 175,000 tokens per action.

At frontier model pricing, that’s roughly $4 for one workflow execution. Run it 1,000 times a day and you’re burning $4,000 daily — on clicking buttons.

The compounding problem

The issue isn’t that LLMs are expensive. It’s that agent architectures make them exponentially more expensive with each step:

Step 1: Inspect DOM (4,000 tokens) → Reason → Act
Step 2: Inspect DOM + step 1 context (6,000 tokens) → Reason → Act
Step 3: Inspect DOM + steps 1-2 context (8,000 tokens) → Reason → Act

By step 10, your context window is carrying the entire conversation history. Each action costs more than the last.

This is the fundamental problem with using general-purpose reasoning for repetitive browser tasks.

What if agents could skip the reasoning?

Consider a different approach: what if the first agent to figure out how to search on Amazon shared that knowledge with every other agent?

The CSS selector for Amazon’s search box doesn’t change between requests. Neither does Google’s search button or GitHub’s login form. These are solved problems being re-solved millions of times a day.

That’s the idea behind collective intelligence for agents. One agent figures out the selectors and steps. Every subsequent agent reuses that knowledge via a single API call — no DOM inspection, no LLM reasoning, zero tokens.

The result: a 10-step workflow drops from $4 and 50 seconds to $0.0006 and 178 milliseconds.

The three-step pattern

The pattern is simple — browse, execute, report:

  1. Browse: Ask what’s possible on a domain. Get back a list of capabilities with confidence scores and pre-verified selectors.
  2. Execute: Request the optimal execution path for a specific capability. Get back CSS selectors, API fast-paths, or macro steps.
  3. Report: After executing, report what worked. This closes the learning loop — successful patterns become verified macros for every other agent.

Every report makes the system smarter. Agents that use this pattern aren’t just consuming intelligence — they’re producing it.

The math that matters

If you’re building browser agents at scale, the cost equation is what determines viability:

Traditional approach: Cost grows linearly (or worse) with workflow complexity. 10 actions = 25 LLM calls = ~$4.

Collective approach: Cost is constant regardless of workflow complexity. 10 actions = 1 API call = $0.0006.

The gap widens with every additional step. A 50-step workflow with traditional LLM reasoning could cost $20+. With pre-verified macros, it’s still $0.0006.

Who benefits

This pattern is relevant if you’re building agents that interact with the web repeatedly. E-commerce bots, data extraction pipelines, testing automation, form-filling services — anywhere agents do the same browser tasks thousands of times.

If your agent visits a site once and never returns, LLM reasoning is fine. If it visits the same site daily, you’re paying a recurring tax that compounds over time.

Try it

The AIR SDK implements this pattern as an MCP server. Install, point your agent at it, and the three-step browse→execute→report pattern replaces DOM reasoning automatically.

npm install @arcede/air-sdk

GitHub: ArcedeDev/air-sdk

Building browser agents? What’s your cost-per-action looking like? Curious to hear how others are handling the token economics.

Resource Monitoring for Data Pipelines

raw `top` endraw  command output

When running data pipelines—especially in production—resource monitoring is critical to prevent slowdowns, crashes, or system-wide failures. Simple Linux command-line tools like top, htop, df -h, and free -h provide real-time visibility into system health and help you catch issues before they escalate.

1. Monitoring CPU & Processes: top and htop

top (Built-in, lightweight)

The top command gives a live view of system processes and CPU usage.

Shows:

  • CPU utilization (user, system, idle time)
  • Running processes and their CPU/memory consumption

 raw `top` endraw  command output

Why it matters for pipelines:

  • Identify CPU bottlenecks during heavy transformations (e.g., Spark jobs, ETL scripts)
  • Detect runaway processes consuming excessive CPU
  • Spot when multiple pipelines overload the system

Tip: Press P inside top to sort by CPU usage.

htop (Enhanced, user-friendly)

htop is an improved version of top with a more intuitive interface.

Features:

  • Color-coded CPU, memory, and swap usage
  • Easy process management (kill, renice)
  • Tree view of processes (great for pipeline dependencies)

 raw `htop` endraw  command output

Pipeline use cases:

  • Visualize parallel jobs in distributed pipelines
  • Quickly terminate stuck or zombie tasks
  • Monitor thread-level activity in real time

2. Monitoring Memory Usage: free -h

The free -h command shows memory usage in a human-readable format.

Key metrics:

  • Used
  • Free
  • Buffers/cache
  • Swap usage
  • Available

 raw `free -h` endraw  command output

Example use:

  • If your data pipeline loads large datasets into memory (e.g., Pandas, Spark), watch the available memory
  • If it drops too low, the system may start swapping, drastically slowing performance

Best practice:

  • Ensure pipelines don’t consume all RAM—leave headroom for the OS and other services

3. Monitoring Disk Space: df -h

The df -h command displays disk usage across mounted filesystems.

Shows:

  • Total, used, and available disk space
  • Usage percentage per filesystem

 raw `df -h` endraw  command output

Data pipelines often generate:

  • Temporary files
  • Logs
  • Intermediate datasets

If disk fills up:

  • Jobs may fail unexpectedly
  • Databases or services can crash

Common risk:

A pipeline writing large intermediate files (e.g., CSV/Parquet) can silently fill up disk → causing job failure or system instability.

Tip:

  • Watch for partitions approaching 90–100% usage
  • Clean up temp directories or rotate logs regularly

Preventing Production Failures

By combining these tools, you can proactively protect your system:

  • High CPU usage (top/htop)
    Indicates inefficient code or too many parallel jobs

  • Low available memory (free -h)
    Risk of crashes or heavy swapping

  • High disk usage (df -h)
    Risk of failed writes and system instability

Practical Workflow for Data Engineers

  • Start your pipeline
  • Open another terminal and run:

htop → monitor CPU + processes
watch free -h → track memory over time
watch df -h → monitor disk growth

  • Look for abnormal spikes or steady resource exhaustion
  • Adjust: Batch sizes, Parallelism, Memory allocation

Key Takeaways

  • These tools are lightweight, fast, and available on most Linux systems
  • They provide real-time insights into system health
  • Regular monitoring helps: Prevent crashes, Optimize performance and Ensure stable production pipelines

Conclusion

Without proper monitoring:

  • Pipelines may crash unexpectedly
  • Systems can become unresponsive
  • Other production services may be impacted

With these tools:

  • You gain early warning signals
  • You can debug performance issues faster
  • You ensure stable, reliable data processing

7 Mac Apps for Night Owl Developers Who Code After Dark in 2026

Some of my best code gets written between 11 PM and 3 AM. No Slack pings, no meetings, no context switches — just you and the compiler.

But late-night coding comes with its own problems: eye strain, runaway API bills you don’t notice until morning, doom-scrolling Twitter at 1 AM instead of shipping, and forgetting to eat. Over the years I’ve assembled a set of Mac apps that make those after-dark sessions way more productive.

Here are 7 I keep running every night.

1. f.lux — Save Your Eyes

Download f.lux

If you’re coding past sunset without f.lux, your retinas are begging for mercy. It gradually shifts your display to warmer tones as the night goes on, which reduces eye strain and helps you actually fall asleep when you finally close the laptop. The “Darkroom” mode (deep red filter) is perfect for those 2 AM sessions when even Dark Mode feels too bright.

2. Warp — A Terminal That Doesn’t Fight You

Download Warp

Late at night, the last thing you want is to fight your terminal. Warp is a GPU-accelerated terminal with inline AI command suggestions, block-based output you can actually select and copy, and built-in completions. When your brain is running on fumes at midnight, having a terminal that anticipates what you’re trying to do is a genuine lifesaver.

3. Raycast — Launch Anything Without Thinking

Download Raycast

Raycast replaces Spotlight with something developers actually want to use. Snippets, clipboard history, window management, quick calculations — all from one hotkey. During late sessions I use it constantly: toggling apps, converting timestamps, running scripts. It eliminates the tiny friction that adds up when your willpower is running low at 1 AM.

4. TokenBar — Know What Your Late-Night AI Sessions Actually Cost

Download TokenBar

This one’s a lifesaver for night owls who use LLM APIs. TokenBar sits in your menu bar and tracks token usage across OpenAI, Anthropic, and other providers in real time. I can’t tell you how many times I’ve burned through $15 in API calls during a late-night coding binge without realizing it. A $5 lifetime purchase that pays for itself the first week. Glance up, see the spend, decide if that next Claude prompt is worth it.

5. Monk Mode — Block the 1 AM Doom Scroll

Download Monk Mode

Here’s the real night owl trap: you hit a bug, get frustrated, “just quickly” open Twitter or Reddit, and suddenly it’s 2:30 AM and you’ve shipped nothing. Monk Mode blocks feeds at the content level — not the entire site. You can still search Stack Overflow or look up docs, but the infinite scroll feeds that steal your late-night hours are gone. $15 lifetime, and it’s the only reason I actually finish features past midnight instead of doomscrolling.

6. Bear — Capture Ideas Before They Vanish

Download Bear

Late at night your brain throws out its weirdest, best ideas — and they evaporate by morning. Bear is a fast, beautiful markdown notes app that I keep in a corner for capturing architecture decisions, bug theories, and random “what if” ideas during night sessions. The nested tagging system keeps things organized without folders, and it syncs across all your Apple devices so morning-you can actually find what night-you wrote down.

7. Numi — Quick Math Without Leaving Your Editor

Download Numi

Numi is a text-based calculator that lives in a small window on your desktop. During late sessions I’m constantly doing napkin math — converting milliseconds, calculating API rate limits, estimating storage costs. Instead of opening a browser tab (dangerous at 1 AM) or pulling up the system calculator, Numi lets you type natural-language calculations in a notepad-style interface. It even handles unit conversions and variables.

Honorable Mention: MetricSync (iPhone)

Download MetricSync

Not a Mac app, but worth mentioning for fellow night coders. MetricSync is an AI nutrition tracker — snap a photo of whatever you’re eating during your late session and it logs the macros automatically. I used to survive on energy drinks and forget to eat real food. Now I at least know what I’m putting in my body at 2 AM. $5/month.

The Night Owl Stack

The pattern here is simple: remove friction, protect focus, and stay aware of costs — whether that’s eye health, money, or calories. Night sessions are when I do my deepest work, and these 7 apps make sure that time actually counts.

What’s in your late-night coding setup? Drop your favorites in the comments.

All prices and links accurate as of March 2026.