The Problem No One Talks About in the Microservices Hype
It’s 2019. Your team has just finished migrating a perfectly functional ASP.NET MVC app to microservices. You now have 14 services, a Kubernetes cluster, a service mesh, distributed tracing, a message broker, and three engineers whose full-time job is keeping it all running. Feature velocity? Cut in half. Onboarding a new developer? Two weeks just to understand the infrastructure.
Sound familiar?
The architecture community spent a decade evangelizing microservices as the solution to every scalability and maintainability problem. And while microservices genuinely solve hard problems at scale, they come with an enormous operational and cognitive tax — one that most product teams can’t afford, and frankly don’t need to pay.
Enter the Modular Monolith: not a retreat to the big ball of mud, and not the complexity of distributed systems. It’s an architectural style that enforces clear internal boundaries while keeping the simplicity of a single deployable unit. For many .NET teams, it’s the most pragmatic choice they never considered.
What Is a Modular Monolith?
A modular monolith is a single deployable application composed of well-defined, loosely coupled internal modules, each owning its own domain logic, data, and public API surface.
The key distinction from a traditional monolith is intentional structure. A classic monolith tends to evolve into spaghetti — shared database tables, cross-cutting service dependencies, and no clear ownership boundaries. A modular monolith fights this entropy from day one by treating each module as if it were a microservice candidate, without actually making it one yet.
The Three-Way Comparison:
| Dimension |
Traditional Monolith |
Modular Monolith |
Microservices |
| Deployment |
Single unit |
Single unit |
Multiple units |
| Module boundaries |
Weak / absent |
Strong, enforced |
Strong, enforced |
| Data isolation |
Shared DB |
Logical isolation |
Physical isolation |
| Communication |
Direct calls |
In-process events |
Network (HTTP/gRPC/MQ) |
| Operational complexity |
Low |
Low |
High |
| Refactoring cost |
High (tightly coupled) |
Medium |
High (distributed) |
| Team autonomy |
Low |
Medium |
High |
| Latency overhead |
None |
None |
Network latency |
Think of it this way: a modular monolith is a microservices architecture collapsed into a single process. The boundaries are real — they’re just not physical.
Why Not Just Use Microservices?
Microservices are genuinely powerful when you need:
- Independent scaling of specific workloads
- Polyglot persistence and technology choices per service
- Complete team autonomy with separate CI/CD pipelines
- Fault isolation at the process boundary level
But the prerequisites are steep. You need mature DevOps culture, a platform team, distributed tracing, eventual consistency patterns, saga orchestration, and more. The distributed fallacies (network is reliable, latency is zero, bandwidth is infinite…) become your daily enemies.
The hidden costs of premature microservices decomposition:
- Distributed transactions replaced simple database transactions — now you’re managing sagas and compensating actions
- A cross-service feature requires coordinating 3 teams and 3 PRs
- Local development requires Docker Compose with 8 containers just to run the app
- Debugging requires correlating traces across 5 services
A modular monolith defers these costs until they’re actually justified. And for many applications — even those at serious scale — that day may never come.
Core Principles
1. Module Boundaries
A module is a cohesive grouping of functionality around a bounded context (to borrow DDD terminology). In an e-commerce system, natural modules might be Orders, Catalog, Users, Payments, and Notifications.
The boundary rule is simple: modules do not reference each other’s internals. If Orders needs a product name, it doesn’t call Catalog‘s internal ProductService — it goes through a defined public contract.
2. High Cohesion / Low Coupling
Everything related to the Catalog domain lives inside Catalog: its entities, repositories, domain services, use cases, and event handlers. Nothing leaks out. Other modules don’t know Catalog has an EfCore repository — they only know the public interface it exposes.
3. Independent Data Per Module
This is the most important and most violated principle. Each module should own its own data. In a modular monolith, you typically use a single database with schema-level separation (e.g., catalog.Products, orders.Orders), or separate DbContext instances that map to different schemas.
No module queries another module’s tables directly. Ever. This is the line between a modular monolith and a well-organized big ball of mud.
4. Communication Patterns
Modules communicate in two ways:
Synchronous (in-process): One module exposes an interface (e.g., ICatalogModule) and another calls it through the DI container. This is appropriate for read queries where you need an immediate result.
Asynchronous (domain events): When Orders places an order, it publishes an OrderPlacedEvent. Inventory and Notifications handle it independently. This is done in-process using a mediator or event dispatcher — no message broker required.
Implementing in .NET
Project Structure
src/
├── ECommerce.Api/                  # Host project (entry point)
│   ├── Program.cs
│   └── appsettings.json
│
├── ECommerce.Shared/               # Cross-cutting contracts
│   ├── Events/                     # Domain event interfaces
│   └── Modules/                    # IModule interface
│
├── ECommerce.Modules.Catalog/      # Catalog module (Class Library)
│   ├── CatalogModule.cs            # Module registration
│   ├── Domain/
│   │   └── Product.cs
│   ├── Application/
│   │   ├── GetProductQuery.cs
│   │   └── GetProductQueryHandler.cs
│   ├── Infrastructure/
│   │   ├── CatalogDbContext.cs
│   │   └── ProductRepository.cs
│   └── Api/
│       └── CatalogEndpoints.cs
│
├── ECommerce.Modules.Orders/       # Orders module (Class Library)
│   ├── OrdersModule.cs
│   ├── Domain/
│   │   └── Order.cs
│   ├── Application/
│   │   ├── PlaceOrderCommand.cs
│   │   └── PlaceOrderCommandHandler.cs
│   ├── Infrastructure/
│   │   └── OrdersDbContext.cs
│   └── Api/
│       └── OrdersEndpoints.cs
│
└── ECommerce.Modules.Users/        # Users module (Class Library)
Each module is a separate class library project. The Api host project references all modules, but modules reference only ECommerce.Shared — never each other directly.
The IModule Contract
Define a shared registration interface that every module implements:
// ECommerce.Shared/Modules/IModule.cs
public interface IModule
{
    string Name { get; }
    IServiceCollection RegisterServices(
        IServiceCollection services,
        IConfiguration configuration);
    WebApplication MapEndpoints(WebApplication app);
}
Module Registration in Program.cs
// ECommerce.Api/Program.cs
var builder = WebApplication.CreateBuilder(args);

// Each module self-registers
var modules = new IModule[]
{
    new CatalogModule(),
    new OrdersModule(),
    new UsersModule(),
};

foreach (var module in modules)
    module.RegisterServices(builder.Services, builder.Configuration);

builder.Services.AddMediatR(cfg =>
    cfg.RegisterServicesFromAssemblies(
        typeof(CatalogModule).Assembly,
        typeof(OrdersModule).Assembly,
        typeof(UsersModule).Assembly));

var app = builder.Build();

foreach (var module in modules)
    module.MapEndpoints(app);

app.Run();
DI Per Module
Each module’s RegisterServices method wires up its own dependencies in isolation:
// ECommerce.Modules.Catalog/CatalogModule.cs
public class CatalogModule : IModule
{
    public string Name => "Catalog";

    public IServiceCollection RegisterServices(
        IServiceCollection services,
        IConfiguration configuration)
    {
        services.AddDbContext<CatalogDbContext>(opts =>
            opts.UseSqlServer(
                configuration.GetConnectionString("Catalog"),
                sql => sql.MigrationsHistoryTable("__EFMigrationsHistory", "catalog")));

        services.AddScoped<IProductRepository, ProductRepository>();
        services.AddScoped<ICatalogModule, CatalogModuleFacade>();

        return services;
    }

    public WebApplication MapEndpoints(WebApplication app)
    {
        app.MapGroup("/catalog").MapCatalogEndpoints();
        return app;
    }
}
Real-World Example: E-Commerce Order Placement
Let’s trace an order placement flow across modules.
The Cross-Module Contract
Orders needs to verify product prices from Catalog. It does this through a public facade interface — not by importing Catalog‘s internal types:
// ECommerce.Shared/Modules/ICatalogModule.cs
public interface ICatalogModule
{
    Task<ProductDto?> GetProductAsync(Guid productId);
}

public record ProductDto(Guid Id, string Name, decimal Price, bool IsAvailable);
Placing an Order
// ECommerce.Modules.Orders/Application/PlaceOrderCommandHandler.cs
public class PlaceOrderCommandHandler
    : IRequestHandler<PlaceOrderCommand, Guid>
{
    private readonly IOrderRepository _orders;
    private readonly ICatalogModule _catalog;       // cross-module contract
    private readonly IPublisher _publisher;          // MediatR publisher

    public PlaceOrderCommandHandler(
        IOrderRepository orders,
        ICatalogModule catalog,
        IPublisher publisher)
    {
        _orders = orders;
        _catalog = catalog;
        _publisher = publisher;
    }

    public async Task<Guid> Handle(
        PlaceOrderCommand command,
        CancellationToken cancellationToken)
    {
        var product = await _catalog.GetProductAsync(command.ProductId);

        if (product is null || !product.IsAvailable)
            throw new DomainException("Product not available.");

        var order = Order.Create(command.CustomerId, product.Id, product.Price);
        await _orders.AddAsync(order, cancellationToken);

        // Publish domain event — handled by other modules in-process
        await _publisher.Publish(
            new OrderPlacedEvent(order.Id, product.Id, command.CustomerId),
            cancellationToken);

        return order.Id;
    }
}
Handling the Event in Another Module
// ECommerce.Modules.Notifications/Application/SendOrderConfirmationHandler.cs
public class SendOrderConfirmationHandler
    : INotificationHandler<OrderPlacedEvent>
{
    private readonly IEmailService _email;
    private readonly IUsersModule _users;

    public async Task Handle(
        OrderPlacedEvent notification,
        CancellationToken cancellationToken)
    {
        var user = await _users.GetUserAsync(notification.CustomerId);
        await _email.SendOrderConfirmationAsync(user.Email, notification.OrderId);
    }
}
Orders publishes an event. Notifications handles it. Neither knows the other exists. This is the power of in-process messaging with MediatR — you get the decoupling benefits of a message bus without the operational overhead.
Common Pitfalls
1. The Shared Database Anti-Pattern
The most common failure mode: all modules share a single DbContext and freely query each other’s tables. You end up with JOINs across module boundaries, and suddenly changing a column in catalog.Products breaks 4 other modules.
The fix: One DbContext per module, separate DB schemas, zero cross-schema queries. If module B needs data from module A, it calls A’s public API — not its tables.
2. Tight Coupling Through Shared Domain Models
Referencing another module’s domain entities directly creates invisible coupling. If Orders imports Catalog.Domain.Product, you’ve created a compile-time dependency that defeats the entire architecture.
The fix: Shared contracts live in ECommerce.Shared as DTOs or interfaces. Domain models are private to their module.
3. Overengineering Small Applications
If your application is a CRUD API with 5 entities and no meaningful domain complexity, a modular monolith is overkill. You’re adding project structure, DI ceremony, and module facades for no real benefit.
The fix: Apply this architecture when you have genuine domain complexity, multiple teams, or a realistic expectation of growth. Don’t architect for hypothetical futures.
When to Choose Modular Monolith vs. Microservices
Choose a Modular Monolith when:
- You’re building a new product and the domain isn’t fully understood yet
- Team size is under ~15 engineers with 2–4 feature teams
- Operational maturity for Kubernetes/service mesh isn’t there yet
- Your workloads are relatively uniform in compute/memory needs
- You value developer experience and fast local development
Choose Microservices when:
- Specific services have vastly different scaling requirements (e.g., a search service vs. a checkout service)
- You have large, autonomous teams that need independent deployment pipelines
- You need polyglot persistence (different databases per service for legitimate reasons)
- You’ve already extracted a clear, stable bounded context that rarely changes
The honest truth: Most applications should start as a modular monolith. If they grow to need microservices, the modular structure makes extraction far less painful than it would be from a traditional monolith.
Scaling and Evolution Strategy
One of the strongest arguments for this architecture is its evolutionary path. Because your modules already have clean boundaries, migrating a single module to a standalone service is a surgical operation, not a rewrite.
The extraction checklist for a module:
- ✅ The module already has its own
DbContext and schema — point it at a separate database
- ✅ All cross-module communication already goes through interfaces — swap the in-process implementation for an HTTP or message-based adapter
- ✅ MediatR domain events switch from in-process
IPublisher to publishing to a message broker (e.g., MassTransit + RabbitMQ)
- ✅ The module’s endpoints already exist — lift them into a new host project
In practice, extraction of a well-bounded module can take days, not months. Compare this to extracting from a traditional monolith where untangling shared state, circular dependencies, and cross-table queries can take quarters.
A practical evolution path looks like this:
Phase 1: Modular Monolith (single deployment, all modules)
    ↓  (Catalog service gets high read traffic)
Phase 2: Extract Catalog to a standalone service
         → Orders calls Catalog via HTTP
         → Events go through a message broker
    ↓  (Payments needs PCI compliance isolation)
Phase 3: Extract Payments to a standalone service
         → Now you have 3 deployable units
You scale surgically, not speculatively.
Key Takeaways
- A modular monolith is not a traditional monolith — it’s a disciplined architecture with enforced module boundaries, data isolation, and clean communication contracts
- The single biggest rule: no module accesses another module’s data store directly. Ever.
- In .NET, implement this with separate class libraries per module, module-scoped
DbContext instances, public facade interfaces in a shared contracts project, and MediatR for in-process event-driven communication
- Avoid the trap of premature microservices — the operational complexity is real and often unjustified at early product stages
- A well-built modular monolith is the best migration path to microservices if and when you genuinely need them
-
Start here by default. Migrate to microservices only when you have a specific, measurable reason to do so — not because it’s fashionable
The architecture world likes clean, binary choices. Microservices or monolith. Distributed or single process. But the most pragmatic choice is often in the middle: a system that’s well-structured enough to evolve, and simple enough to actually ship.
Have you migrated to or from a modular monolith? The edge cases are always where the real lessons live — reach out or drop a comment.

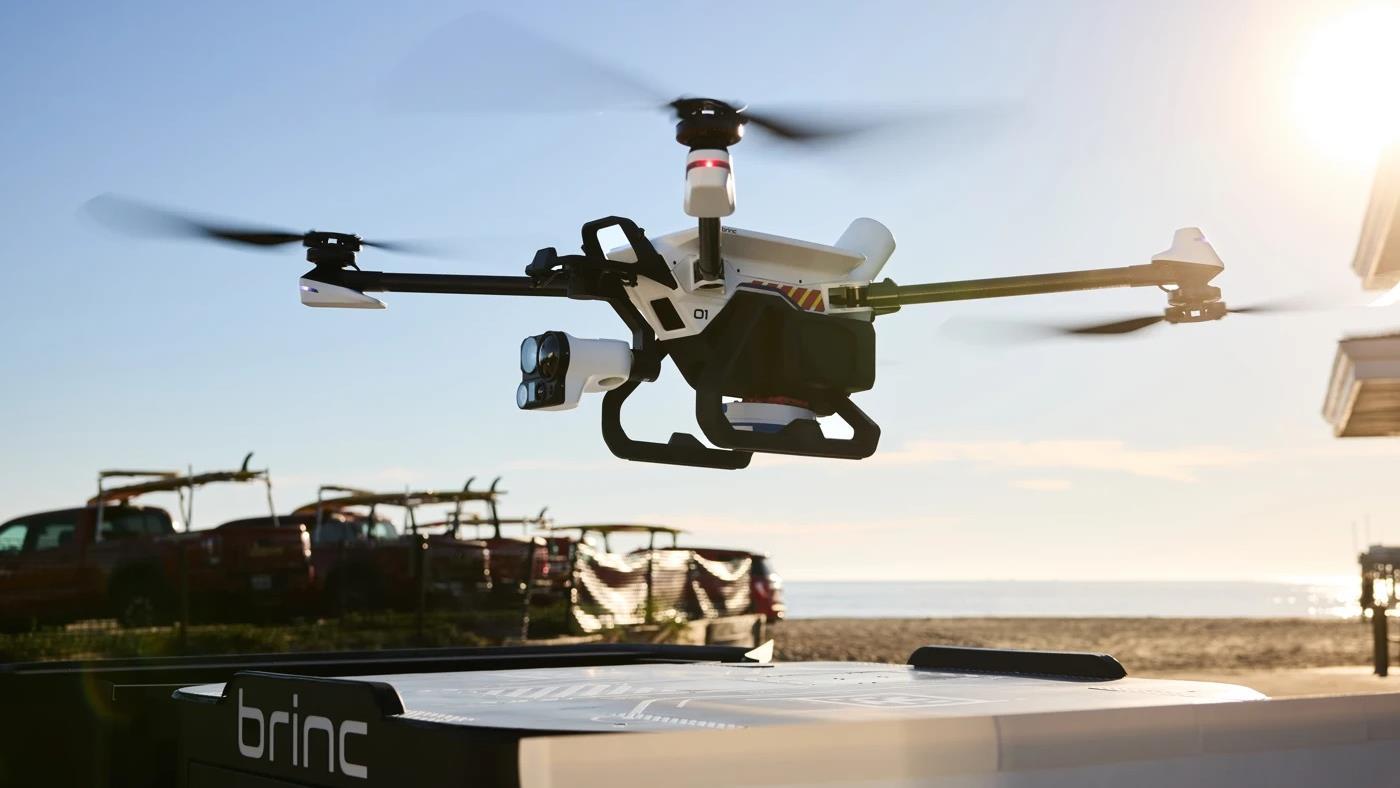
 BRINC’in Starlink destekli yeni polis dronu Guardian, saatte 100 km hızla araç takip yapabiliyor. Dron, otomatik batarya değişimi sayesinde uzun süre görev yapabiliyor.
 Avrupa Komisyonu ile ilişkili olan web platformlarına ve çalışanların veri tabanlarına sızan siber saldırganların devasa miktarlarda bir veriyi çaldıkları açıklandı.
 ABD’li yetkililer, Çin’in en büyük çip üreticisi SMIC’in İran’ın askeri sanayisine ekipman ve teknik destek sağladığını öne sürdü. Bu iddialar küresel gerilimi daha da artırabilir.