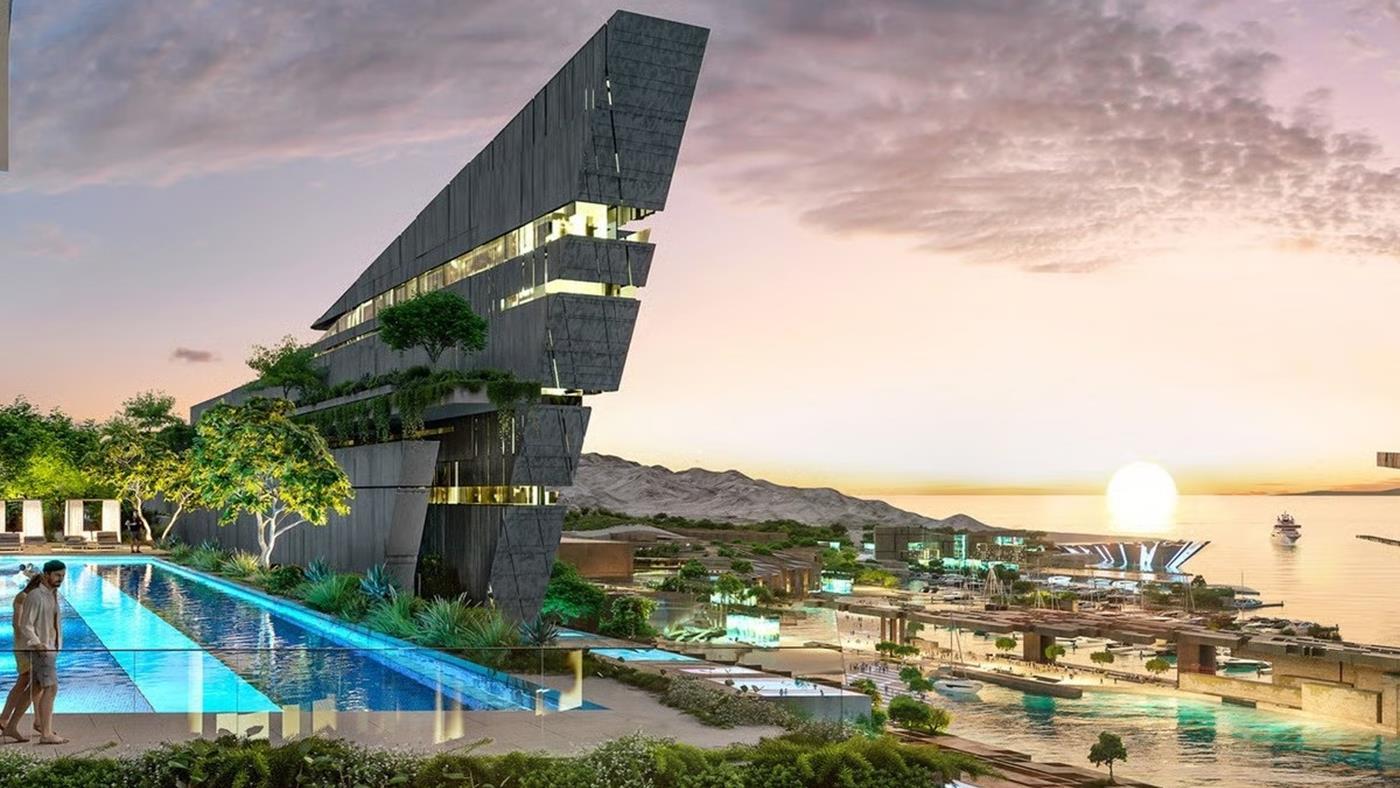
Suudi Arabistan’ın ütopik Neom projesinde deprem: Milyar dolarlık sözleşmeler iptal edildi
Suudi Arabistan’ın ütopik projesi Neom’da inşaat devleri sahadan çekiliyor. Milyar dolar değerindeki sözleşmelerin ardı ardına feshedilmesi “geleceğin şehri” vizyonunun çıkmaza girdiğini gösteriyor.7 Best Crypto APIs for AI Agent Development in 2026
AI agents are rapidly becoming first-class participants in crypto markets. The AI agent crypto sector reached a $15.4 billion market cap in early 2025 before correcting, and autonomous trading agents now account for a growing share of on-chain volume. Frameworks like ElizaOS and Virtuals Protocol have made it possible to spin up agents that hold wallets, execute swaps, and manage portfolios without human intervention. But every agent needs reliable APIs to interact with blockchains. The best crypto API for AI agents is one that returns executable transaction data in a single request, requires no API key (agents cannot fill out registration forms), and covers enough chains to operate across DeFi. This guide ranks the 7 best crypto APIs for AI agent development in 2026 — evaluated on integration simplicity, chain coverage, and agent-friendliness.
1. Swap API (swapapi.dev)
Swap API is the most agent-friendly crypto API available. It returns ready-to-execute swap calldata from a single GET request across 46 EVM chains — no API key, no authentication, no account required. For AI agents, this is critical: an agent can discover the endpoint, construct a URL, and get back a complete transaction object without any setup or credential management.
The API accepts chainId, tokenIn, tokenOut, amount, and sender, and returns tx.to, tx.data, and tx.value that can be submitted directly on-chain. The response also includes expectedAmountOut, minAmountOut, priceImpact, and recommended RPC URLs.
import requests
resp = requests.get("https://api.swapapi.dev/v1/swap/42161?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0xaf88d065e77c8cC2239327C5EDb3A432268e5831&amount=1000000000000000000&sender=0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045")
tx = resp.json()["data"]["tx"]
Swap API also provides an OpenAPI spec and an llms.txt file specifically designed for LLM consumption. Agents built with tool-calling frameworks can parse these machine-readable docs and integrate automatically. With DeFi TVL exceeding $130 billion across supported chains, the 46-chain coverage means agents can operate on Ethereum, Arbitrum, Base, Polygon, BSC, and 41 other networks from a single endpoint.
Best for: AI agents that need zero-config token swaps across the widest range of EVM chains.
2. CoinGecko API
CoinGecko provides the most comprehensive crypto market data API, covering over 15,000 tokens across 1,000+ exchanges. For AI agents, market data is the foundation of every trading decision — price feeds, volume, market cap, and historical data drive the signals that agents act on.
The free tier offers 30 calls per minute without an API key for basic endpoints. The Pro plan (starting at $129/month) unlocks higher rate limits and additional endpoints like on-chain DEX data and token security scores.
import requests
resp = requests.get("https://api.coingecko.com/api/v3/simple/price?ids=ethereum&vs_currencies=usd&include_24hr_change=true")
eth_price = resp.json()["ethereum"]["usd"]
CoinGecko’s /coins/{id}/market_chart endpoint provides historical price data that agents can use for technical analysis. The 2025 crypto industry report noted that the total crypto market cap reached $3.9 trillion, underscoring the scale of data CoinGecko indexes.
Best for: AI agents that need market data, price feeds, and token metadata for decision-making.
3. Alchemy
Alchemy is the leading blockchain node infrastructure provider, serving over 12 million developers and powering applications that handle billions in transaction volume. For AI agents, Alchemy provides the raw blockchain access layer — reading wallet balances, token holdings, transaction history, and NFT data.
The Supernode product offers enhanced JSON-RPC endpoints with built-in reliability, while the Transfers API and Token API simplify common agent tasks like checking balances before executing a swap.
const resp = await fetch("https://eth-mainnet.g.alchemy.com/v2/YOUR_KEY", {
method: "POST",
body: JSON.stringify({jsonrpc: "2.0", method: "eth_getBalance", params: ["0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045", "latest"], id: 1})
});
The free tier includes 300 million compute units per month, which is sufficient for most agent prototyping. Alchemy supports Ethereum, Polygon, Arbitrum, Optimism, Base, and other major chains.
Best for: AI agents that need reliable RPC access, balance checks, and transaction monitoring.
4. Etherscan API
Etherscan and its multi-chain variants (Arbiscan, Basescan, Polygonscan) provide block explorer APIs that are essential for AI agent verification and monitoring. With over 5 million daily active users across its explorer products, Etherscan is the standard for on-chain data verification.
Agents use Etherscan to verify transaction confirmations, decode contract interactions, and retrieve gas price estimates. The API offers endpoints for account balances, transaction lists, internal transactions, and contract ABIs.
import requests
resp = requests.get("https://api.etherscan.io/api?module=gastracker&action=gasoracle&apikey=YOUR_KEY")
gas_prices = resp.json()["result"]
The free tier allows 5 calls per second with an API key. For agents operating across multiple chains, each block explorer requires a separate API key — a friction point compared to unified APIs.
Best for: AI agents that need transaction verification, gas estimation, and on-chain data lookup.
5. Moralis
Moralis provides a unified Web3 data API that abstracts away the complexity of querying multiple chains. Their Wallet API, Token API, and DeFi API let agents retrieve portfolio balances, token prices, and DeFi positions from a single endpoint.
The EVM API covers 20+ chains and returns structured data that is particularly well-suited for AI agents — clean JSON responses with token metadata, USD valuations, and decoded transaction logs.
import requests
resp = requests.get("https://deep-index.moralis.io/api/v2.2/0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045/erc20?chain=eth", headers={"X-API-Key": "YOUR_KEY"})
tokens = resp.json()
Moralis processes over 50 billion API calls annually and offers a free tier with 40,000 compute units per day. The Streams API enables webhook-based event monitoring, allowing agents to react to on-chain events in real time rather than polling.
Best for: AI agents that need portfolio tracking, token balances, and cross-chain wallet data.
6. Chainlink Data Feeds
Chainlink is the dominant oracle network in DeFi, securing $21 billion in total value across its price feeds and services. For AI agents that need tamper-proof, on-chain price data for smart contract interactions, Chainlink’s data feeds are the industry standard.
Unlike REST APIs, Chainlink feeds are read directly from smart contracts on-chain. This means agents can verify prices within the same transaction they execute, eliminating the trust assumption of off-chain API calls.
AggregatorV3Interface feed = AggregatorV3Interface(0x5f4eC3Df9cbd43714FE2740f5E3616155c5b8419);
(, int256 price,,,) = feed.latestRoundData();
Chainlink supports 20+ blockchains and provides feeds for 1,000+ asset pairs. The data is updated by a decentralized network of node operators, making it resistant to single points of failure.
Best for: AI agents that interact with smart contracts and need on-chain verifiable price data.
7. The Graph
The Graph is a decentralized indexing protocol that lets developers query blockchain data through GraphQL APIs called subgraphs. With over 1,000 subgraphs deployed across major chains, it provides structured access to DEX pool data, lending positions, governance events, and more.
For AI agents analyzing DeFi protocols, The Graph provides data that is impossible to get from basic RPC calls — like historical liquidity pool states, trading volumes per pair, and protocol-specific metrics.
{
swaps(first: 5, orderBy: timestamp, orderDirection: desc) {
amount0
amount1
pool { token0 { symbol } token1 { symbol } }
}
}
The Graph’s decentralized network processes over 2 billion queries per month. Agents can use subgraphs to analyze liquidity depth before executing swaps, monitor protocol health, or track whale activity.
Best for: AI agents that need structured DeFi protocol data, pool analytics, and historical on-chain metrics.
Comparison Table
| Feature | Swap API | CoinGecko | Alchemy | Etherscan | Moralis | Chainlink | The Graph |
|---|---|---|---|---|---|---|---|
| Primary Function | Token swaps | Market data | Node/RPC | Explorer data | Wallet data | Price oracles | Indexed data |
| API Key Required | No | Optional | Yes | Yes | Yes | N/A (on-chain) | Yes |
| Free Tier | Unlimited | 30 req/min | 300M CU/mo | 5 req/sec | 40K CU/day | Free (on-chain) | 100K queries/mo |
| Chain Coverage | 46 EVM | 1000+ exchanges | 8 chains | 15+ explorers | 20+ chains | 20+ chains | 50+ chains |
| Returns Tx Calldata | Yes | No | No | No | No | No | No |
| LLM-Optimized Docs | Yes (llms.txt) | No | No | No | No | No | No |
| Best For Agents | Executing swaps | Price decisions | Reading chain | Verification | Portfolio view | On-chain prices | DeFi analytics |
How to Build an AI Agent Crypto Stack
A production AI agent needs multiple APIs working together. Here is the typical architecture:
1. Decision layer: CoinGecko or Chainlink for price data and market signals. The agent analyzes prices, volume trends, and volatility to decide when and what to trade.
2. Execution layer: Swap API for converting decisions into on-chain transactions. A single GET request returns executable calldata — the agent submits it through its wallet. Over 80% of institutional DeFi users now route through aggregator APIs rather than interacting with individual DEXs.
3. Verification layer: Etherscan or Alchemy to confirm transaction success, monitor gas costs, and track portfolio changes after execution.
4. Analytics layer: The Graph or Moralis to analyze pool liquidity, historical performance, and protocol-level data that informs the next trading cycle.
The key advantage of Swap API in this stack is that it is the only API that requires zero configuration. An agent can start executing swaps immediately, while every other layer requires API key provisioning.
Frequently Asked Questions
What is the best crypto API for AI agents?
Swap API is the best crypto API for AI agent swap execution. It requires no API key, returns executable transaction calldata from a single GET request, and supports 46 EVM chains. For a complete agent stack, combine it with CoinGecko for market data and Alchemy for RPC access.
Do AI agents need API keys to trade crypto?
Not for swap execution. Swap API requires no API key, no registration, and no authentication. An agent can construct a URL with the chain ID, token addresses, amount, and sender address, and receive back a complete transaction ready to sign and broadcast. Other APIs in the stack (Alchemy, Etherscan, Moralis) typically require API keys, which adds setup complexity.
How do AI agents execute on-chain swaps?
AI agents execute swaps by calling a DEX aggregator API to get transaction calldata, then signing and broadcasting the transaction using their wallet’s private key. With Swap API, the flow is: (1) GET the swap endpoint with parameters, (2) extract the tx object from the response, (3) sign with ethers.js or web3.py, (4) send to the RPC. The entire flow takes under 5 seconds.
What chains do AI crypto agents typically operate on?
Most AI agents operate on low-fee, high-speed chains. Arbitrum, Base, and Polygon are the most popular due to sub-cent transaction fees and fast finality. Ethereum remains important for high-value trades. Swap API supports all of these plus 42 additional chains, allowing agents to arbitrage across networks or follow liquidity to wherever yields are highest.
Can AI agents handle failed or partial swaps?
Yes. Well-designed agents check the status field in the API response. Swap API returns three statuses: Successful (full fill), Partial (partial fill with adjusted amounts), and NoRoute (no liquidity path found). Agents should handle all three — executing on Successful, evaluating whether to proceed on Partial, and falling back to alternative pairs on NoRoute.
Get Started
Swap API is free, requires no API key, and supports 46 EVM chains. It is the fastest way to add token swap execution to any AI agent — no registration, no credentials, no rate limit anxiety.
The llms.txt file provides machine-readable documentation designed specifically for LLM-based agents. The OpenAPI spec enables automatic client generation in Python, TypeScript, Rust, or any language.
Start with a swap quote on Base:
curl "https://api.swapapi.dev/v1/swap/8453?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0x833589fCD6eDb6E08f4c7C32D4f71b54bdA02913&amount=1000000000000000000&sender=0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045"
7 Free DeFi APIs for Building Trading Bots in 2026
If you are searching for a free DeFi API to build a trading bot, the fastest option is a DEX aggregator API that returns executable swap calldata in a single HTTP request with no API key. DEX trading bots now account for a significant share of on-chain volume, with automated trading representing over 60% of DEX transactions on major EVM chains. The DeFi trading bot market has grown alongside DEX volumes, which exceeded $13.5 billion in daily trading volume across decentralized exchanges in 2025. Building a profitable bot requires reliable price data, fast swap execution, and multi-chain coverage. This guide covers 7 free DeFi APIs that provide the core building blocks for trading bot development — from swap execution to price feeds and on-chain data.
1. Swap API (swapapi.dev) — Free DEX Aggregator
Swap API is a completely free DEX aggregator API built for trading bot developers. It returns ready-to-execute swap calldata from a single GET request across 46 EVM chains, with no API key, no registration, and no rate-limit tiers to manage.
You send a request with the chain ID, input token, output token, amount, and sender address. The API returns a complete transaction object with to, data, and value fields that you submit directly on-chain. For trading bots, this means you can go from price signal to executed trade in two steps: fetch the swap calldata, then broadcast the transaction.
curl "https://api.swapapi.dev/v1/swap/1?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0xA0b86991c6218b36c1d19D4a2e9Eb0cE3606eB48&amount=1000000000000000000&sender=0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045"
The response includes expectedAmountOut, minAmountOut with slippage protection, priceImpact as a decimal, token metadata, and recommended RPC endpoints for the target chain. Partial fills return a Partial status with adjusted amounts instead of failing, which is critical for bot reliability.
Best for: Trading bots that need multi-chain swap execution with zero integration overhead. The 46-chain coverage means a single integration handles Ethereum, Arbitrum, Base, BSC, Polygon, and 41 other networks.
2. CoinGecko API — Free Price Feeds
CoinGecko provides a free tier API for cryptocurrency price data, market caps, trading volumes, and historical charts. For trading bots, this is typically the price feed layer that triggers buy/sell signals before executing swaps through a DEX aggregator.
The free tier includes 30 calls per minute with no API key required for the public endpoints. You get current prices in any fiat currency, 24-hour price changes, and market data for over 15,000 tokens. The /simple/price endpoint is the most useful for bots — it returns current prices for multiple tokens in a single request.
curl "https://api.coingecko.com/api/v3/simple/price?ids=ethereum,bitcoin&vs_currencies=usd&include_24hr_change=true"
The limitation for bot developers is the rate limit on the free tier. At 30 requests per minute, you need to batch token lookups and cache aggressively. The pro tier ($129/month) bumps this to 500 calls per minute, but the free tier works for bots that check prices on intervals rather than tick-by-tick.
Best for: Price signal generation, portfolio tracking, and triggering swap execution based on price thresholds.
3. DeFi Llama API — Free TVL and Protocol Data
DeFi Llama offers a fully free API with no API key required and no rate limits for reasonable usage. It covers total value locked (TVL) data across 3,500+ DeFi protocols, DEX trading volumes, yield farming rates, and stablecoin analytics.
For trading bots, the most relevant endpoints are the DEX volume data and the yield/pools API. The /yields/pools endpoint returns APY data across thousands of liquidity pools, which is useful for bots that farm yield or rebalance across protocols. The /dexs endpoints provide volume data that helps identify which chains and pairs have the most liquidity.
curl "https://yields.llama.fi/pools"
DeFi Llama aggregates data from primary sources and does not charge for access. The trade-off is that data updates on intervals (typically every 10-15 minutes for TVL, hourly for yields), so it is not suitable for latency-sensitive arbitrage. But for strategy bots that rebalance daily or trade on macro signals, this is the best free data source available.
Best for: Yield farming bots, TVL-based strategy signals, and identifying liquidity-rich pools across chains.
4. Alchemy Free Tier — Node Infrastructure
Alchemy provides a free tier with 300 million compute units per month, which covers roughly 12 million standard RPC calls. For trading bots, a reliable node provider is essential for reading on-chain state, checking token balances, monitoring mempool transactions, and broadcasting signed swap transactions.
The free tier supports Ethereum, Polygon, Arbitrum, Optimism, Base, and other major EVM chains. You get access to standard JSON-RPC methods plus Alchemy-specific enhanced APIs like alchemy_getTokenBalances and webhook-based notifications for address activity.
const provider = new ethers.JsonRpcProvider("https://eth-mainnet.g.alchemy.com/v2/YOUR_FREE_KEY");
const balance = await provider.getBalance("0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045");
The compute unit model means complex calls (trace, debug, archival) consume more units than simple calls (eth_call, eth_getBalance). A trading bot that checks balances, reads prices from on-chain oracles, and sends transactions will comfortably fit within the free tier for moderate trading volumes. Note that Swap API responses also include recommended RPC URLs, which can reduce your reliance on a single node provider.
Best for: Broadcasting swap transactions, reading on-chain balances, and monitoring wallet activity.
5. Chainlink Price Feeds — Free On-Chain Oracles
Chainlink price feeds are free to read on-chain and provide decentralized, tamper-resistant price data for hundreds of token pairs. Unlike API-based price feeds, Chainlink data lives on-chain, which means your bot can read it with a simple contract call through any RPC provider.
Chainlink feeds update based on deviation thresholds (typically 0.5% for major pairs) and heartbeat intervals. For trading bots, this provides a reliable price reference that is immune to API downtime. You can read the latest price for ETH/USD, BTC/USD, and hundreds of other pairs on Ethereum, Arbitrum, Polygon, BSC, and other chains.
const priceFeed = new ethers.Contract(CHAINLINK_ETH_USD, ["function latestRoundData() view returns (uint80, int256, uint256, uint256, uint80)"], provider);
const [, price, , updatedAt] = await priceFeed.latestRoundData();
The main advantage for bot developers is that Chainlink feeds work even when centralized APIs are down. The limitation is that feeds update on deviation thresholds, not every block, so prices may lag during high-volatility periods. Combine Chainlink with a real-time price API for the best of both worlds.
Best for: On-chain price verification, stop-loss triggers, and as a fallback price source when API feeds fail.
6. Etherscan / Block Explorer APIs — Free Transaction Data
Etherscan and its multi-chain equivalents (Arbiscan, Polygonscan, BaseScan) provide free API tiers for reading transaction history, token transfers, contract ABIs, and gas prices. For trading bots, these APIs fill the analytics and monitoring gap — you can track your bot’s executed trades, verify transaction receipts, and pull historical gas data to optimize submission timing.
The free tier across Etherscan APIs provides 5 calls per second with no API key, or a registered free key bumps this to roughly 5 calls/second with higher daily limits. The /api?module=gastracker endpoint is particularly useful for bots that need to time transaction submissions around gas price dips.
curl "https://api.etherscan.io/api?module=gastracker&action=gasoracle"
Each chain has its own explorer API with the same interface, so your bot code is portable. The limitation is that Etherscan data is indexed from finalized blocks, meaning there is a slight delay compared to direct RPC calls. Use this for post-trade analytics and gas optimization rather than real-time execution.
Best for: Gas price optimization, trade history tracking, and verifying bot execution results.
7. The Graph — Free Subgraph Queries
The Graph provides a decentralized indexing protocol for querying blockchain data via GraphQL. For trading bot developers, subgraphs give you structured access to DEX pool states, liquidity positions, historical swap events, and token pair data that would require thousands of RPC calls to assemble manually.
The Graph’s free hosted service and the decentralized network both offer free query tiers. Uniswap, Aave, Compound, and most major DeFi protocols maintain official subgraphs. You can query pool reserves, recent swap volumes, and fee tiers in a single GraphQL request, which is invaluable for bots that select optimal trading pairs.
{ pools(first: 5, orderBy: totalValueLockedUSD, orderDirection: desc) { token0 { symbol } token1 { symbol } totalValueLockedUSD volumeUSD } }
The trade-off is query latency — subgraph data is indexed from confirmed blocks and may lag 1-5 blocks behind the chain head. For arbitrage bots that need real-time pool states, direct RPC calls to pool contracts are faster. But for strategy bots that analyze liquidity depth and volume trends, The Graph is the most efficient free option.
Best for: Analyzing DEX liquidity, tracking pool volumes, and building data-driven trading strategies.
Comparison Table
| API | Cost | API Key Required | Primary Use Case | Chain Coverage |
|---|---|---|---|---|
| Swap API | Free | No | Swap execution | 46 EVM chains |
| CoinGecko | Free tier | No (public) | Price feeds | 15,000+ tokens |
| DeFi Llama | Free | No | TVL, yields, volumes | 3,500+ protocols |
| Alchemy | Free tier | Yes | Node RPC, tx broadcast | 10+ chains |
| Chainlink | Free (on-chain) | No | On-chain price oracles | 15+ chains |
| Etherscan | Free tier | Optional | Tx history, gas data | Per-chain |
| The Graph | Free tier | Optional | DEX pool analytics | 40+ chains |
Putting It All Together
A typical trading bot stack combines 2-3 of these APIs. The minimal viable setup is a price feed (CoinGecko or Chainlink) to generate signals and a swap execution API (Swap API) to act on them. Here is a simplified flow:
- Monitor token prices via CoinGecko or Chainlink
- When a price threshold is hit, fetch swap calldata from Swap API
- Sign and broadcast the transaction via your RPC provider
- Verify execution via Etherscan or direct receipt polling
This entire stack can run at zero cost on the free tiers listed above.
FAQ
What is the best free DeFi API for trading bots?
For swap execution, Swap API (swapapi.dev) is the best free option because it requires no API key, covers 46 EVM chains, and returns executable transaction calldata in a single GET request. For price data, CoinGecko’s free tier provides the broadest token coverage. Most bots combine both: a price feed for signals and a swap API for execution.
Do I need an API key to use a free DeFi API?
Not for all of them. Swap API and DeFi Llama require no API key or registration at all. CoinGecko’s public endpoints work without a key but have stricter rate limits. Alchemy and Etherscan offer free tiers but require account registration to get a key. Chainlink price feeds are read directly from on-chain contracts, so no API key is needed — just an RPC connection.
How many chains can I trade on with a free DeFi API?
Swap API supports 46 EVM chains from a single endpoint, including Ethereum, Arbitrum, Base, Optimism, Polygon, BSC, Avalanche, and newer chains like Monad, MegaETH, and Berachain. This is the widest free coverage available. By comparison, most other DEX aggregator APIs that offer free tiers cover 8-15 chains.
Can I build a profitable trading bot with free APIs?
Free APIs remove the infrastructure cost, but profitability depends on your strategy, gas costs, and execution speed. The APIs listed here cover every layer of the bot stack — price data, swap execution, node access, and analytics — at zero cost. The main bottleneck for free tiers is rate limits, which matter more for high-frequency strategies than for bots that trade on longer intervals.
What is the difference between a price API and a swap API?
A price API (like CoinGecko) returns the current market price of a token. A swap API (like Swap API) returns the actual transaction data needed to execute a trade on-chain at the best available price across multiple DEX liquidity sources. Trading bots need both: price data to decide when to trade, and swap calldata to execute the trade.
Get Started
Swap API is free, requires no API key, and supports 46 EVM chains from a single endpoint. Fetch a swap quote and executable calldata in one request:
curl "https://api.swapapi.dev/v1/swap/42161?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0xaf88d065e77c8cC2239327C5EDb3A432268e5831&amount=1000000000000000000&sender=0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045"
The response includes everything your bot needs: the swap transaction, expected output amount, minimum output with slippage protection, and RPC endpoints to broadcast on the target chain. Start building at swapapi.dev.

6 DeFi APIs That Work Without Registration
Most DeFi APIs gate access behind API keys, email signups, and tiered pricing. For developers prototyping a trading bot, building an AI agent, or testing a new chain integration, that friction kills momentum. You want to call an endpoint and get data back, not fill out a form and wait for approval.
DeFi now handles over $13.5 billion in daily DEX trading volume, with aggregators routing a significant share of that flow. The infrastructure powering this volume is increasingly accessible: several APIs let you fetch swap quotes, token prices, and on-chain data with zero registration. No API key. No account. No credit card.
This guide covers 6 DeFi APIs that work without registration, ranked by developer experience and utility. Every API listed here can be called with a single curl command.
1. Swap API (swapapi.dev)
Swap API is a free DEX aggregator API that returns executable swap calldata from a single GET request. It covers 46 EVM chains, from Ethereum and Arbitrum to newer networks like Monad, MegaETH, and Berachain. No API key, no authentication, no account creation.
You send a request with a chain ID, input/output tokens, amount, and sender address. You get back a complete transaction object that can be submitted directly on-chain.
curl "https://api.swapapi.dev/v1/swap/1?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0xA0b86991c6218b36c1d19D4a2e9Eb0cE3606eB48&amount=1000000000000000000&sender=0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045"
The response includes expectedAmountOut, minAmountOut with slippage protection, priceImpact, token metadata, and recommended RPC endpoints for the target chain. Partial fills return a Partial status with adjusted amounts instead of failing.
What makes it stand out:
- 46 chains from a single endpoint, the widest EVM coverage of any keyless aggregator API
- Response includes a ready-to-sign
txobject withto,data,value, andgasPrice - Envelope response format (
{ success, data, error, timestamp }) makes error handling predictable - Full OpenAPI spec for auto-generating typed clients in any language
Swap API is the fastest path from zero to a working on-chain swap. One HTTP call, no setup.
2. CoinGecko Public API
CoinGecko provides a free public API for crypto market data: prices, market caps, historical charts, and token metadata. The public tier requires no API key and supports up to 30 calls per minute.
curl "https://api.coingecko.com/api/v3/simple/price?ids=ethereum&vs_currencies=usd"
CoinGecko covers 15,000+ tokens across hundreds of chains. The /coins/list endpoint returns token IDs, and /simple/token_price/{platform} lets you query by contract address. For developers building portfolio trackers or price feeds, this is the standard free data source.
The limitation: CoinGecko provides market data only. It does not return swap calldata or transaction objects. You cannot execute trades through CoinGecko. For swap execution, pair it with a DEX aggregator API like Swap API.
Best for: Price feeds, market data dashboards, and token metadata lookups.
3. OpenOcean
OpenOcean is a DEX aggregator that offers a free API without requiring an API key. It covers 30+ blockchains, including non-EVM chains like Solana and Tron, and routes trades through 1,000+ liquidity pools.
curl "https://open-api.openocean.finance/v3/1/swap_quote?inTokenAddress=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&outTokenAddress=0xA0b86991c6218b36c1d19D4a2e9Eb0cE3606eB48&amount=1000000000000000000&slippage=1&account=0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045&gasPrice=20"
OpenOcean’s main advantage is ecosystem breadth: EVM and non-EVM chains from a single provider. The trade-off is that routing quality on individual chains may not match specialized EVM aggregators. Response times tend to be slower, and the documentation is less structured than alternatives.
Best for: Multi-ecosystem projects that need both EVM and non-EVM chain coverage without registration.
4. LI.FI
LI.FI combines cross-chain bridging with same-chain token swaps. The API is free for standard use and requires no API key. It aggregates liquidity from 30+ DEXs and 20+ bridges across 25+ chains.
curl "https://li.quest/v1/quote?fromChain=1&toChain=42161&fromToken=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&toToken=0xaf88d065e77c8cC2239327C5EDb3A432268e5831&fromAmount=1000000000000000000&fromAddress=0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045"
LI.FI shines when your users need to move assets between chains as part of a swap. A single API call handles the bridge + swap route. The downside is complexity: cross-chain transactions involve multi-step execution, bridging risk, and longer settlement times. For same-chain swaps, a dedicated single-chain aggregator like Swap API returns faster results with simpler error handling.
Best for: Applications where users swap across chains and you want bridge + swap in a unified API.
5. DeFi Llama
DeFi Llama provides free, open-source DeFi analytics: TVL by protocol, chain, and category. The API has no API key, no rate limits, and no registration. It tracks over 6,000 protocols across 250+ chains.
curl "https://api.llama.fi/v2/chains"
The /protocol/{name} endpoint returns historical TVL, chain breakdowns, and token data. The /prices API resolves token prices by contract address across chains. DeFi Llama is the go-to source for DeFi research data and is widely used in dashboards, analytics tools, and research reports.
Like CoinGecko, DeFi Llama is data-only. It does not support swap execution. Use it for analytics, TVL tracking, and price resolution alongside a swap API.
Best for: DeFi analytics, TVL dashboards, and cross-chain price resolution.
6. Uniswap Subgraph (The Graph)
Uniswap’s public subgraphs on The Graph expose pool-level data via GraphQL: liquidity, volume, fees, tick data, and historical metrics. No API key required for the hosted service.
{
pools(first: 5, orderBy: totalValueLockedUSD, orderDirection: desc) {
token0 { symbol }
token1 { symbol }
totalValueLockedUSD
volumeUSD
}
}
Subgraphs are available for Uniswap V2 and V3 on Ethereum, Polygon, Arbitrum, Optimism, and Base. The data is indexed from on-chain events, so it reflects actual pool state. This is useful for building pool analytics, monitoring liquidity, or calculating optimal swap routes independently.
The limitation: subgraphs provide data, not execution. You still need an aggregator API to get executable calldata. The hosted service also has reliability concerns for production use.
Best for: Pool analytics, liquidity monitoring, and building custom routing logic.
Comparison Table
| Feature | Swap API | CoinGecko | OpenOcean | LI.FI | DeFi Llama | Uniswap Subgraph |
|---|---|---|---|---|---|---|
| API Key Required | No | No | No | No | No | No |
| Swap Execution | Yes | No | Yes | Yes | No | No |
| EVM Chains | 46 | N/A | 30+ | 25+ | 250+ (data) | 5 |
| Cross-Chain | No | N/A | Yes | Yes | N/A | No |
| Market Data | Prices | Full | Prices | Prices | Full | Pool-level |
| Response Format | REST | REST | REST | REST + SDK | REST | GraphQL |
| Rate Limits | Generous | 30/min | Moderate | Generous | None | Moderate |
When to Use Which API
Building a swap feature? Start with Swap API. One GET request returns executable calldata across 46 chains. No setup, no key management.
Need price feeds? CoinGecko covers 15,000+ tokens. For DeFi-specific metrics like TVL, use DeFi Llama.
Cross-chain swaps? LI.FI handles bridge + swap routing. OpenOcean covers non-EVM chains.
Pool analytics? Uniswap subgraphs give you tick-level liquidity data via GraphQL.
For most DeFi integrations, the combination of Swap API (execution) + CoinGecko or DeFi Llama (data) covers the full stack without a single API key.
Frequently Asked Questions
What is the best free DeFi API with no API key?
Swap API is the best free DeFi API for swap execution. It requires no API key, no registration, and no payment. It supports 46 EVM chains and returns ready-to-execute transaction calldata from a single GET request. For market data, CoinGecko and DeFi Llama are both free and keyless.
Why do some DeFi APIs require API keys?
API keys let providers enforce rate limits, track usage, and monetize access. APIs like 1inch and 0x moved to paid tiers as their usage scaled. Keyless APIs like Swap API and DeFi Llama sustain free access through alternative models, making them ideal for prototyping and open-source projects.
Can I build a trading bot with a free DeFi API?
Yes. Swap API returns a complete transaction object including to, data, value, and gasPrice. Your bot fetches a quote, checks priceImpact, and submits the transaction on-chain using any wallet library (ethers.js, viem, web3.py). No API key management means fewer moving parts in production.
How do I choose between a data API and a swap API?
Data APIs (CoinGecko, DeFi Llama) return prices, market caps, and analytics. Swap APIs (Swap API, OpenOcean, LI.FI) return executable transaction calldata you can submit on-chain. Most applications need both: a data API for display and a swap API for execution.
Get Started
Swap API is free, requires no API key, and supports 46 EVM chains. Start making swap requests immediately with zero registration.
Swap 1 ETH for USDC on Arbitrum:
curl "https://api.swapapi.dev/v1/swap/42161?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0xaf88d065e77c8cC2239327C5EDb3A432268e5831&amount=1000000000000000000&sender=0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045"
Explore the full OpenAPI specification to generate typed clients in TypeScript, Python, Rust, or any language. Browse the Swagger UI for interactive testing.
How to Swap Tokens Programmatically with TypeScript
Swapping tokens programmatically with TypeScript requires three things: a swap API that returns executable calldata, a wallet library to sign transactions, and an RPC connection to broadcast them. With DEX aggregators handling over $13.5 billion in daily trading volume and TypeScript dominating web3 frontend and bot development, knowing how to execute on-chain swaps from code is a core skill for any DeFi developer. This guide walks you through swapping tokens on any EVM chain using TypeScript and a free API that requires no key and no SDK — just a single GET request.
What You’ll Need
-
Node.js 18+ or Bun (for native
fetch) - TypeScript (5.x recommended)
- viem or ethers.js for signing and sending transactions
- A wallet with a private key (testnet or mainnet)
- No API key — the swap API used in this guide is free and requires no registration
Install the dependencies:
npm install viem typescript
Step 1: Fetch a Swap Quote
The swap API at api.swapapi.dev takes a GET request with five parameters and returns a complete transaction object. No authentication, no SDK, no POST body.
const res = await fetch("https://api.swapapi.dev/v1/swap/1?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0xA0b86991c6218b36c1d19D4a2e9Eb0cE3606eB48&amount=1000000000000000000&sender=0xYourAddress");
const quote = await res.json();
This fetches a quote to swap 1 ETH for USDC on Ethereum mainnet. The parameters are:
-
chainId (path):
1for Ethereum,42161for Arbitrum,8453for Base,137for Polygon,56for BSC — 46 chains total -
tokenIn: the input token address. Use
0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeEfor native ETH/BNB/MATIC on any chain -
tokenOut: the output token address. USDC on Ethereum is
0xA0b86991c6218b36c1d19D4a2e9Eb0cE3606eB48 -
amount: the input amount in the token’s smallest unit (wei). 1 ETH =
1000000000000000000 - sender: the wallet address that will execute the swap
The response includes everything you need: the transaction object (to, data, value), expected output amounts, slippage protection, token metadata, and even recommended RPC URLs for the target chain.
Step 2: Parse the Response
The API returns a structured envelope with a status field that tells you exactly what happened.
const { success, data } = quote;
if (!success) {
console.error("API error:", quote.error.message);
process.exit(1);
}
if (data.status === "NoRoute") {
console.error("No swap route found for this pair");
process.exit(1);
}
A successful response contains these key fields:
-
data.status:
"Successful"for a full fill,"Partial"if only part of the amount can be swapped,"NoRoute"if no path exists - data.expectedAmountOut: the best-case output in raw units
- data.minAmountOut: the minimum output after slippage (transaction reverts below this)
-
data.priceImpact: price impact as a decimal (e.g.,
-0.0012= -0.12%) - data.tx: the ready-to-submit transaction object
- data.rpcUrls: ranked list of recommended public RPCs for the chain
To get the human-readable output amount, divide by the token’s decimals:
const amountOut = Number(data.expectedAmountOut) / 10 ** data.tokenTo.decimals;
console.log(`Expected output: ${amountOut} ${data.tokenTo.symbol}`);
Step 3: Check Price Impact
Before executing any swap, check the price impact to avoid losing funds on low-liquidity pairs.
if (data.priceImpact < -0.05) {
console.error(`Price impact too high: ${(data.priceImpact * 100).toFixed(2)}%`);
process.exit(1);
}
A price impact of -5% or worse means you’re moving the market significantly. For production bots, set a configurable threshold — most strategies use -1% to -3% as a maximum.
Step 4: Handle ERC-20 Approvals
When swapping a native token (ETH, BNB, MATIC), no approval is needed. But when swapping an ERC-20 token, you must approve the router contract to spend your tokens before the swap will succeed.
import { createWalletClient, http, parseAbi } from "viem";
import { privateKeyToAccount } from "viem/accounts";
import { arbitrum } from "viem/chains";
const account = privateKeyToAccount("0xYourPrivateKey");
const client = createWalletClient({ account, chain: arbitrum, transport: http(data.rpcUrl) });
const erc20Abi = parseAbi(["function approve(address spender, uint256 amount) returns (bool)"]);
const approveTx = await client.writeContract({ address: data.tokenFrom.address, abi: erc20Abi, functionName: "approve", args: [data.tx.to, BigInt(data.amountIn)] });
Wait for the approval transaction to confirm, then fetch a fresh swap quote before proceeding. The calldata is time-sensitive — it includes a deadline, so always re-fetch after approval.
Note: USDT on Ethereum requires setting the allowance to 0 before setting a new non-zero allowance.
Step 5: Simulate with eth_call
Before sending a real transaction and spending gas, simulate the swap using eth_call. This is free and catches most failures before they cost you money.
import { createPublicClient } from "viem";
const publicClient = createPublicClient({ chain: arbitrum, transport: http(data.rpcUrl) });
await publicClient.call({ to: data.tx.to, data: data.tx.data, value: BigInt(data.tx.value), account: account.address });
If eth_call reverts, the swap would fail on-chain. Common reasons: insufficient balance, missing ERC-20 approval, or expired deadline (quote older than 30 seconds).
Step 6: Estimate Gas and Send the Transaction
Estimate gas with a 20% buffer to avoid out-of-gas reverts on complex multi-hop routes, then send the transaction.
const gasEstimate = await publicClient.estimateGas({ to: data.tx.to, data: data.tx.data, value: BigInt(data.tx.value), account: account.address });
const txHash = await client.sendTransaction({ to: data.tx.to, data: data.tx.data, value: BigInt(data.tx.value), gas: (gasEstimate * 120n) / 100n });
console.log(`Transaction sent: ${txHash}`);
The API provides a gasPrice field as a suggestion, but viem and ethers.js automatically handle EIP-1559 gas pricing on supported chains, so you can omit it. Submit within 30 seconds of fetching the quote — the calldata includes a deadline.
Complete Example: Swap ETH for USDC on Arbitrum
Here is a full working script that swaps ETH for USDC on Arbitrum using viem:
import { createPublicClient, createWalletClient, http } from "viem";
import { privateKeyToAccount } from "viem/accounts";
import { arbitrum } from "viem/chains";
const SENDER = "0xYourWalletAddress";
const PRIVATE_KEY = "0xYourPrivateKey";
const res = await fetch(`https://api.swapapi.dev/v1/swap/42161?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0xaf88d065e77c8cC2239327C5EDb3A432268e5831&amount=1000000000000000000&sender=${SENDER}`);
const { data } = await res.json();
if (data.status !== "Successful") throw new Error(`Swap failed: ${data.status}`);
const amountOut = Number(data.expectedAmountOut) / 10 ** data.tokenTo.decimals;
console.log(`Swapping 1 ETH for ~${amountOut} USDC on Arbitrum`);
const account = privateKeyToAccount(PRIVATE_KEY);
const publicClient = createPublicClient({ chain: arbitrum, transport: http(data.rpcUrl) });
const walletClient = createWalletClient({ account, chain: arbitrum, transport: http(data.rpcUrl) });
await publicClient.call({ to: data.tx.to, data: data.tx.data, value: BigInt(data.tx.value), account: SENDER });
const gas = await publicClient.estimateGas({ to: data.tx.to, data: data.tx.data, value: BigInt(data.tx.value), account: SENDER });
const txHash = await walletClient.sendTransaction({ to: data.tx.to, data: data.tx.data, value: BigInt(data.tx.value), gas: (gas * 120n) / 100n });
console.log(`TX: ${txHash}`);
This script fetches a quote, validates the response, simulates the swap, estimates gas, and submits the transaction — all in under 25 lines. The API provides the RPC URL, so you don’t need to configure a separate node provider.
Swapping on Other Chains
The same code works on any of the 46 supported chains. Just change the chain ID and token addresses:
Polygon (chain 137) — swap MATIC for USDC:
const res = await fetch(`https://api.swapapi.dev/v1/swap/137?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0x3c499c542cEF5E3811e1192ce70d8cC03d5c3359&amount=1000000000000000000&sender=${SENDER}`);
Base (chain 8453) — swap ETH for USDC:
const res = await fetch(`https://api.swapapi.dev/v1/swap/8453?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0x833589fCD6eDb6E08f4c7C32D4f71b54bdA02913&amount=1000000000000000000&sender=${SENDER}`);
BSC (chain 56) — swap BNB for USDT:
const res = await fetch(`https://api.swapapi.dev/v1/swap/56?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0x55d398326f99059fF775485246999027B3197955&amount=1000000000000000000&sender=${SENDER}`);
Note that USDT uses 18 decimals on BSC, unlike 6 decimals on Ethereum. The API returns tokenTo.decimals in the response, so always use that value instead of hardcoding decimals.
Using ethers.js Instead of viem
If your project uses ethers.js v6, the same flow applies with different syntax:
import { ethers } from "ethers";
const res = await fetch(`https://api.swapapi.dev/v1/swap/42161?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0xaf88d065e77c8cC2239327C5EDb3A432268e5831&amount=1000000000000000000&sender=${SENDER}`);
const { data } = await res.json();
const provider = new ethers.JsonRpcProvider(data.rpcUrl);
const wallet = new ethers.Wallet(PRIVATE_KEY, provider);
const tx = await wallet.sendTransaction({ to: data.tx.to, data: data.tx.data, value: BigInt(data.tx.value) });
console.log(`TX: ${tx.hash}`);
ethers.js automatically handles gas estimation and EIP-1559 pricing, so you can send the transaction directly. For production use, add the simulation step (provider.call(...)) and gas buffer described earlier.
Handling Partial Fills and Edge Cases
The API returns three status values, all with HTTP 200. Your code should handle each:
if (data.status === "Successful") {
// Full fill — execute the swap
}
if (data.status === "Partial") {
const filled = Number(BigInt(data.amountIn)) / Number(BigInt(requestedAmount));
console.log(`Only ${(filled * 100).toFixed(1)}% of requested amount can be filled`);
}
if (data.status === "NoRoute") {
console.log("No route — try a different pair or chain");
}
For partial fills, data.amountIn and data.expectedAmountOut reflect the fillable portion, not your original request. The tx object is still executable — it just swaps the partial amount. Do not retry the same amount in a loop; the liquidity cap won’t change.
Frequently Asked Questions
How do I swap tokens programmatically with TypeScript?
Fetch a swap quote from a DEX aggregator API, then sign and submit the returned transaction object using viem or ethers.js. With Swap API, a single GET request returns the complete to, data, and value fields — no SDK, no API key, no ABI encoding. The full flow (quote, simulate, send) takes under 25 lines of TypeScript.
Do I need an API key to swap tokens?
No. Swap API is free and requires no API key, no account, and no registration. It supports 46 EVM chains from a single endpoint. Other aggregator APIs like 1inch and 0x require API keys and paid plans for production use.
What TypeScript library should I use for on-chain swaps?
Both viem and ethers.js work. viem is the newer library with better TypeScript types and tree-shaking support. ethers.js v6 is more established with a larger community. Both can sign transactions, estimate gas, and interact with ERC-20 contracts. The swap API is library-agnostic — it returns raw transaction data that any wallet library can submit.
How do I handle token decimals when swapping?
Never hardcode decimals. The API response includes tokenTo.decimals and tokenFrom.decimals for every swap. Use these to convert between raw amounts and human-readable values: humanAmount = rawAmount / 10 ** decimals. For example, USDC uses 6 decimals on Ethereum and Arbitrum, but USDT uses 18 decimals on BSC.
What happens if a swap fails?
Simulate every swap with eth_call before sending a real transaction. If the simulation reverts, the swap would fail on-chain — do not submit. Common failure reasons: insufficient token balance, missing ERC-20 approval, or expired calldata (quotes are valid for 30 seconds). If eth_estimateGas fails, that also indicates the transaction would revert.
Get Started
Swap API is free, requires no API key, and supports 46 EVM chains from a single endpoint. One GET request returns everything you need: executable calldata, expected output amounts, slippage protection, and RPC URLs.
Browse the Swagger UI for interactive testing, or check the OpenAPI specification to auto-generate a typed TypeScript client.
curl "https://api.swapapi.dev/v1/swap/42161?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0xaf88d065e77c8cC2239327C5EDb3A432268e5831&amount=1000000000000000000&sender=0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045"
How to Build an Arbitrage Bot with a Swap API
Crypto arbitrage bots generated over $500 million in extracted value on Ethereum alone in 2024, and DEX trading volume across EVM chains exceeded $1.76 trillion that same year. The opportunity is real, but most tutorials drown you in smart contract ABIs, router addresses, and multi-library setups before you can even fetch a price. This guide takes a different approach: you will build an arbitrage bot using a single GET request to a swap API, skipping all the contract-level complexity. By the end, you will have a working bot that monitors price differences across chains and tokens, calculates profitability including gas costs, and executes swaps on-chain. No API keys, no SDKs, no accounts required.
What You’ll Need
- Node.js 18+ or Bun (examples use Bun for speed)
- A wallet with a private key funded on your target chains
-
ethers.js v6 (
npm install ethers) - Basic HTTP knowledge — the entire swap integration is one GET request
The bot uses swapapi.dev, a free DEX aggregator API covering 46 EVM chains. It returns executable transaction calldata from a single endpoint, so you do not need to manage router contracts, ABIs, or liquidity source configurations.
Step 1: Understand the Arbitrage Strategy
Arbitrage profits come from price discrepancies. The two most common patterns on DEXes:
Triangular arbitrage — trade through three tokens on the same chain. For example: ETH to USDC, USDC to DAI, DAI back to ETH. If the final ETH amount exceeds your starting amount minus gas, you profit.
Cross-pair arbitrage — compare the same swap across different routing paths. The API aggregates across multiple liquidity sources, so you compare the quoted output for the same trade at different amounts or with different intermediate tokens.
Over 70% of crypto spot trading is now automated, and DEX aggregators processed $128 billion in Q4 2024. The liquidity is there — the edge comes from speed and execution efficiency.
Step 2: Fetch Quotes from the Swap API
The entire price-fetching mechanism is a single GET request. Here is how to query the price of swapping 1 ETH to USDC on Ethereum:
GET https://api.swapapi.dev/v1/swap/1?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0xA0b86991c6218b36c1d19D4a2e9Eb0cE3606eB48&amount=1000000000000000000&sender=0xYourWalletAddress
The response includes everything you need:
-
expectedAmountOut— the best-case output in the token’s smallest unit -
minAmountOut— the slippage-protected minimum -
priceImpact— how much the trade moves the market -
tx— a ready-to-send transaction object withto,data,value, andgasPrice
Wrap this in a reusable function:
async function getQuote(chainId: number, tokenIn: string, tokenOut: string, amount: string, sender: string) {
const url = `https://api.swapapi.dev/v1/swap/${chainId}?tokenIn=${tokenIn}&tokenOut=${tokenOut}&amount=${amount}&sender=${sender}`;
const res = await fetch(url);
return res.json();
}
Step 3: Implement Triangular Arbitrage Detection
Triangular arbitrage checks whether cycling through three tokens yields more than you started with. Define your token addresses and loop through triangle paths:
const TOKENS = {
ETH: "0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE",
USDC: "0xA0b86991c6218b36c1d19D4a2e9Eb0cE3606eB48",
DAI: "0x6B175474E89094C44Da98b954EedeAC495271d0F",
WBTC: "0x2260FAC5E5542a773Aa44fBCfeDf7C193bc2C599",
};
For each triangle (e.g., ETH -> USDC -> DAI -> ETH), fetch three sequential quotes and compare the final output to the initial input:
async function checkTriangle(path: string[], decimals: number[], amountIn: string, sender: string) {
let currentAmount = amountIn;
for (let i = 0; i < path.length - 1; i++) {
const quote = await getQuote(1, path[i], path[i + 1], currentAmount, sender);
if (!quote.success || quote.data.status !== "Successful") return null;
currentAmount = quote.data.expectedAmountOut;
}
return { input: amountIn, output: currentAmount };
}
If output > input, you have a potential arbitrage opportunity. But you need to account for gas before celebrating.
Step 4: Calculate Profitability After Gas
A common mistake in arbitrage bot tutorials is ignoring gas costs. On Ethereum mainnet, a single swap can cost $5-50 in gas. A triangle of three swaps means 3x that cost. Your profit calculation must include gas:
async function estimateGas(provider: ethers.JsonRpcProvider, tx: any) {
const gasEstimate = await provider.estimateGas({
from: tx.from,
to: tx.to,
data: tx.data,
value: tx.value,
});
return gasEstimate * BigInt(120) / BigInt(100);
}
The 20% buffer on gas estimation is critical — multi-hop swap routes are complex and can exceed initial estimates. The API’s gasPrice field gives you the current gas price in wei. Multiply by the estimated gas to get total cost.
For tighter margins, consider running on Layer 2 chains. On Arbitrum (chain 42161) or Base (chain 8453), gas costs drop to fractions of a cent, making smaller arbitrage opportunities viable. Arbitrum processes over $1 billion in weekly DEX volume, providing sufficient liquidity with minimal transaction costs.
Step 5: Execute the Swap On-Chain
When your bot detects a profitable opportunity, execution must be fast. The API calldata expires after 30 seconds, so fetch a fresh quote immediately before submitting:
import { ethers } from "ethers";
async function executeSwap(provider: ethers.JsonRpcProvider, wallet: ethers.Wallet, quote: any) {
const tx = quote.data.tx;
const gasLimit = await estimateGas(provider, tx);
const transaction = await wallet.sendTransaction({
to: tx.to,
data: tx.data,
value: tx.value,
gasLimit,
});
return transaction.wait();
}
Before executing, always run a simulation with eth_call to verify the transaction will not revert. The API response includes rpcUrls — an array of recommended RPC endpoints for the chain, so you do not need to hardcode providers:
const rpcUrl = quote.data.rpcUrls[0];
const provider = new ethers.JsonRpcProvider(rpcUrl);
Step 6: Build the Monitoring Loop
Tie everything together into a continuous monitoring loop. The API allows approximately 30 requests per minute per IP, so pace your queries accordingly:
const SCAN_INTERVAL = 3000;
const MIN_PROFIT_BPS = 50;
async function monitorLoop(sender: string, wallet: ethers.Wallet) {
const triangles = [
[TOKENS.ETH, TOKENS.USDC, TOKENS.DAI, TOKENS.ETH],
[TOKENS.ETH, TOKENS.USDC, TOKENS.WBTC, TOKENS.ETH],
[TOKENS.ETH, TOKENS.DAI, TOKENS.USDC, TOKENS.ETH],
];
while (true) {
for (const path of triangles) {
const result = await checkTriangle(path, [], "1000000000000000000", sender);
if (!result) continue;
const profit = BigInt(result.output) - BigInt(result.input);
const profitBps = (profit * BigInt(10000)) / BigInt(result.input);
if (profitBps > BigInt(MIN_PROFIT_BPS)) {
console.log(`Opportunity: ${profitBps} bps profit`);
}
}
await new Promise((r) => setTimeout(r, SCAN_INTERVAL));
}
}
Step 7: Handle Edge Cases
Production arbitrage bots must handle several response states from the API:
Partial fills — The API may return status: "Partial" when liquidity is insufficient for your full amount. The amountIn in the response reflects the partial amount, not your original request. Compare it to your requested amount to detect this.
NoRoute — When status: "NoRoute", no swap path exists for that pair. Skip it and move to the next opportunity.
Price impact checks — Always check priceImpact before executing. A value below -0.05 (-5%) indicates excessive slippage. Reject these trades:
if (quote.data.priceImpact < -0.05) {
console.log("Price impact too high, skipping");
continue;
}
ERC-20 approvals — When the input token is not the native gas token, you must approve the router contract (tx.to) to spend your tokens before executing. Note that USDT on Ethereum requires setting the allowance to 0 before setting a new value.
FAQ
How much capital do I need to start an arbitrage bot?
On Ethereum mainnet, you need enough to cover gas costs for three swaps per triangle, which can be $15-150 per attempt. On Layer 2 chains like Arbitrum or Base, you can start with as little as $100 since gas costs are under $0.01 per transaction.
Is the swap API really free?
Yes. swapapi.dev requires no API key, no account, and no payment. It supports 46 chains with a rate limit of approximately 30 requests per minute per IP. That is sufficient for monitoring dozens of token pairs.
What chains are best for arbitrage bots?
Chains with high DEX volume and low gas costs offer the best ratio of opportunity to execution cost. Arbitrum (chain 42161), Base (chain 8453), and BSC (chain 56) are strong choices. Ethereum mainnet has the deepest liquidity but the highest gas costs, making only larger opportunities profitable.
Can I run multiple bots on different chains simultaneously?
Yes. Since the API uses chain ID as a path parameter, you can run parallel monitoring loops for different chains. Each chain has independent liquidity pools and independent arbitrage opportunities.
How do I avoid losing money to failed transactions?
Always simulate with eth_call before submitting. Always check priceImpact. Always estimate gas and include a 20% buffer. Never execute when status is anything other than "Successful". If eth_estimateGas fails, the swap would revert on-chain — do not submit.
Get Started
Test the API right now with a single curl command. This fetches a quote for swapping 1 ETH to USDC on Ethereum:
curl "https://api.swapapi.dev/v1/swap/1?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0xA0b86991c6218b36c1d19D4a2e9Eb0cE3606eB48&amount=1000000000000000000&sender=0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045"
The response includes the full transaction object ready for on-chain execution. Read the complete API documentation to explore all 46 supported chains and start building your arbitrage bot today.
I Built an AI-Powered AWS Cost Optimizer — Here’s How It Works
I’m an AWS consultant. My clients always ask the same question: “Why is my AWS bill so high?”
The answer is always the same: idle resources, oversized instances, and services nobody remembered to turn off. So I built a tool to find them automatically.
The Architecture
Sharktooth connects to a customer’s AWS account via a cross-account IAM role — the same pattern used by Datadog, CloudHealth, and AWS’s own tools.
Customer AWS Account Sharktooth AWS Account
┌─────────────────┐ ┌──────────────────────┐
│ │ │ │
│ IAM Role ◄──────────────── STS AssumeRole │
│ (read-only) │ │ + ExternalId │
│ │ │ │
│ Cost Explorer │ │ Cost Analysis │
│ CloudWatch │────────► │ AI Recommendations │
│ EC2 Describe │ │ Dashboard │
│ RDS Describe │ │ │
└─────────────────┘ └──────────────────────┘
Step 1: Connect (5 minutes)
The customer creates a read-only IAM role with this trust policy:
{
"Version": "2012-10-17",
"Statement": [{
"Effect": "Allow",
"Principal": { "AWS": "arn:aws:iam::SHARKTOOTH_ACCOUNT:root" },
"Action": "sts:AssumeRole",
"Condition": {
"StringEquals": { "sts:ExternalId": "UNIQUE_PER_CUSTOMER" }
}
}]
}
The ExternalId prevents confused deputy attacks — each customer gets a unique one.
Permissions requested:
ce:GetCostAndUsage
cloudwatch:GetMetricStatistics
ec2:DescribeInstances
ec2:DescribeInstanceTypes
rds:DescribeDBInstances
That’s it. No write permissions. No S3, Lambda, or IAM access.
Step 2: Pull Cost Data
Using STS AssumeRole, we get temporary credentials (1-hour expiry) and call the Cost Explorer API:
- Monthly spend by service (last 6 months)
- Daily spend trend (last 30 days)
- Service breakdown with amounts
Step 3: Detect Idle Resources
For each running EC2 instance, we pull 7 days of CloudWatch CPUUtilization:
- Average CPU < 5% = flagged as idle
- Average CPU 5-20% = right-sizing candidate
For RDS, we check DatabaseConnections:
- 0 connections over 7 days = flagged as idle
Step 4: AI Analysis
This is where it gets interesting. We feed everything into Claude (via AWS Bedrock):
- Monthly spend total and service breakdown
- 30-day daily trend
- List of idle resources
- Right-sizing candidates
The AI returns structured JSON:
[
{
"title": "Right-size or consolidate Lightsail instances",
"description": "Lightsail represents 42.9% of total spend...",
"estimatedMonthlySavings": 45.36,
"priority": "high",
"effort": "medium"
}
]
Cost per AI analysis: ~$0.005 (half a cent) using Haiku.
Results
On my own account ($352/month), it found $135/month in savings:
- Consolidate Lightsail instances ($45/mo)
- Remove unused ELB ($20/mo)
- Audit WorkMail seats ($22/mo)
- Clean up VPC resources ($18/mo)
- Plus 6 more recommendations
That’s 38% waste. On an AWS consultant’s own account.
Tech Stack
- .NET 10 — Razor Pages + Minimal API
- SQLite — EF Core, lightweight and self-contained
- AWS Bedrock — Claude Haiku 4.5 for AI analysis
- Chart.js — Cost trend visualizations
- Stripe — Billing
The whole thing runs on a single Lightsail instance alongside 7 other .NET apps.
Try It
Free tier available at sharktoothproject.com. Pro ($19/mo) adds idle detection, right-sizing, and AI recommendations.
If you manage AWS for clients, the Team tier ($39/mo) covers unlimited accounts.
Built by Nat Thompson at Obsidian River. Questions? Find me on LinkedIn or drop a comment below.
The Six-Month Onboarding Lie: Why Most Teams Never Really Let New Developers Join the Real Work
There’s a quiet lie a lot of engineering teams tell themselves:
“Onboarding takes six months. That’s just how it is.”
On paper, it sounds reasonable. Plenty of HR articles say it takes anywhere from a few months up to a year for a new hire to reach “full productivity,” especially in complex or technical roles. Six months feels like a safe middle number.
But in day‑to‑day reality, that “six months” line often turns into something more dangerous: an excuse. It’s a way to justify new developers spending half a year orbiting the real work without ever being pulled into the actual core of the team.
That’s not an onboarding problem. It’s a trust, ownership, and culture problem.
The Myth of “Full Productivity”
Most companies treat “time to full productivity” as a vague HR metric instead of a concrete engineering responsibility. You hear the same phrases everywhere:
- “It takes 3–6 months to ramp up in a complex codebase.”
- “You can’t expect real impact before the first performance cycle.”
- “They’re still onboarding; let’s not give them anything risky yet.”
Underneath that language is a more honest translation:
- We haven’t done the work to make our systems understandable.
- We haven’t designed starter problems that actually matter.
- We don’t know how to safely put a new engineer in the path of real impact.
So we package all of that up and call it “onboarding.”
Because other teams do it too, it feels normal. If your last company took months to let you ship a meaningful feature, a slow ramp at the next place just feels like “how the industry works.” But “industry average” is not the same thing as “healthy.”
The Fake Work We Give New Developers
When a team doesn’t know how to let new people touch the real system, it creates fake work that looks productive but doesn’t move anything that matters.
You’ve probably seen some of these patterns:
1. “Starter” tickets that don’t matter
Tiny UI text changes, dead‑code cleanup, or toggling a config flag no customer will ever notice. Great for day one, unacceptable for week eight.
2. Shadowing as a permanent state
The new hire “shadows” seniors in meetings, calls, and incident reviews — but never actually owns a decision, a commit, or a slice of the system.
3. Endless environment and permissions hell
Weeks disappear into VPN issues, missing access, and half‑documented local setup. All of this time quietly gets filed under “onboarding,” even though most of it is preventable with a bit of upfront work.
4. Documentation scavenger hunt
There’s no learning path. Just a graveyard of Notion pages and Confluence docs. The new engineer is told to “read the docs and ping if anything’s unclear,” which usually translates to “wander around and good luck.”
Each of these, on its own, sounds defensible. Taken together, they mean that by month three a “new” developer’s Git history is still mostly chores and drive‑by fixes, not real features or decisions.
Why Teams Don’t Let New Devs Touch Core Systems
It’s tempting to blame complexity: “Our domain is hard,” “Our stack is old,” “We’re in a regulated industry.” Those things might be true, but they’re rarely the root cause.
Underneath, you usually find a mix of:
Fear of outages
The senior folks know exactly how fragile the core system is. Letting a new person in feels risky, so they keep the “real” work in a tiny inner circle.
No safety rails
There’s no staging environment that behaves like production, the test suite is flaky or barely exists, and observability is weak. In that world, giving anyone new real responsibility isn’t just scary — it’s reckless.
Hero culture
A few “indispensable” engineers carry most of the context. They’re always firefighting and never have time to turn their knowledge into something reusable or design work that’s safe for newcomers.
Lazy management narratives
It’s easier to say “onboarding just takes six months here” than to admit “we don’t know how to expose core systems without blowing things up.”
So the compromise becomes: keep new developers close enough to feel busy, but far enough away that nothing can really break.
From the outside, it still looks like progress — there are standups, tickets, and commits. From the inside, the new hire can tell they’re not actually part of the engine yet.
The Psychological Damage of Perpetual Onboarding
Staying in “not quite trusted yet” mode for months quietly wrecks people.
For the new developer:
-
Imposter syndrome deepens.
If you’re still not allowed near core paths after three months, you don’t think “this system is badly structured.” You think “I must not be good enough.”
-
Initiative gets punished in slow motion.
You suggest taking on deeper work and repeatedly hear, “maybe later, once you’re more familiar.” Eventually you stop asking.
-
Your growth curve flattens early.
Real growth comes from owning risk: designing features, handling incidents, making tradeoffs. If you’re shielded from that, you stagnate.
For the team:
-
“Long onboarding” becomes part of the culture.
New hires are told to expect a slow start. Nobody feels personally responsible for changing that.
-
Senior devs stay permanently overloaded.
Because new people never get true ownership, the same two or three names end up on every critical path project, every incident, every migration.
The end state is boringly predictable: seniors burn out, new devs disengage, and leadership wonders why velocity feels terrible even though headcount has gone up.
The Six-Month Excuse vs. a Real Onboarding Target
Here’s the uncomfortable bit:
You don’t need six months for a developer to contribute to real work.
You might need six months (or more) for them to fully master the system — but that’s a different conversation.
High‑functioning teams separate these two ideas.
They aim for milestones like:
-
Within the first week
The new engineer has a real commit merged that touches user‑visible behavior or production code paths — protected by tests, review, and guard rails.
-
Within the first month
They own a small but meaningful slice of functionality: a feature, a workflow, one service endpoint, something they’re clearly responsible for.
-
Within the first three months
They’re participating in incidents, architecture discussions, or cross‑team projects, not as silent observers but as contributors.
Notice what’s missing: “Wait six months before they touch anything important.”
When research talks about 3–9 months or even longer to reach “full productivity,” it’s describing the time to reach peak effectiveness, not a justification to keep people on the sidelines for half a year.
How to Let New Developers Join the Real Work (Without Burning Everything Down)
If you’re a senior engineer or a manager, this is the part you actually control. The goal isn’t “onboard faster” in the abstract; it’s “create safe ways for new people to do meaningful work quickly.”
Here are a few practical moves.
1. Design a real “first feature” on purpose
Don’t just throw a random bug at the new hire.
- Pick a change that touches real code paths but is easy to roll back.
- Make sure there are tests in place — or take the opportunity to add them.
- Pair on the design, then let them drive the implementation and the PR.
The milestone isn’t “they merged something.” It’s “they experienced the whole loop: spec → code → review → deploy → feedback.”
2. Expose them to risk, but with guard rails
Instead of hiding new developers from dangerous parts of the system, make those parts safer.
- Invest in staging environments that behave like production.
- Strengthen automated tests around core flows.
- Use feature flags and solid rollback plans so mistakes are survivable.
You’re not just improving onboarding; you’re hardening the entire system.
3. Give them a meaningful area of ownership early
By month one or two, a new engineer should own something you’d absolutely notice if it broke:
- A small service.
- A specific API endpoint and its SLOs.
- A feature flag they are responsible for sunsetting.
Ownership is what turns “I’m new here” into “I’m accountable for this.”
4. Turn tribal knowledge into a product
If the only way to learn is “grab 30 minutes with Alice,” you are guaranteeing long ramp times.
Instead:
- Turn repeated questions into docs, runbooks, or short internal videos.
- Record incident reviews and architecture walkthroughs, then index them somewhere easy to search.
- Build a simple, opinionated “start here” path: what to read, in what order, and why it matters.
Every time a new hire has to dig through old Slack threads for basic context, you pay the onboarding tax again.
If You’re the New Developer Stuck in the Six-Month Lie
Sometimes you’re not the one with formal power to change the system. You still have options.
-
Push for real work early.
Ask: “What’s a small but real piece of functionality I can own end‑to‑end this month?” That question alone forces your lead to think beyond cosmetic tickets.
-
Shadow with intent, not passively.
When you sit in incident calls or design reviews, map systems, write things down, and follow up with specific questions. Turn what you see into your own documentation.
-
Trace tickets to outcomes.
Before you pick something up, ask who cares about it and how they’ll know it worked. If nobody can answer, there’s a good chance you’re being handed busywork.
-
Measure your own ramp.
Note when you first ship something real, when you first help resolve an incident, when you first make a design call. Those moments say more about your growth than any “onboarding complete” date.
You may not be able to fix the culture alone, but you can refuse to let it define your sense of competence.
The Lie Only Survives If We Let It
Saying “onboarding takes six months here” is easy. It sounds mature, professional, and especially reasonable in complex domains.
But if, six months in, your new engineers:
- still haven’t owned a feature,
- still aren’t in the rotation for serious work, and
- still don’t feel trusted around core systems,
that’s not onboarding. That’s institutionalized underutilization.
The teams that win over the long term won’t be the ones with the fanciest onboarding slide decks. They’ll be the ones that treat new developers as real engineers from week one — and build systems, processes, and culture that are safe and robust enough to make that trust real.
Credentials Route. Identity Confirms. Agent Discovery Has It Backwards.
Credentials route. Identity confirms. That is the order every discovery system in history has followed. Medical boards, search engines, licensing authorities, the Yellow Pages. You find what you need first, then verify who it is. The agent ecosystem is building it backwards — racing to prove agents are real when the harder question is whether they are relevant.
The problem everyone is solving
Right now, dozens of projects are shipping specs for decentralized identifiers, trust registries, encrypted transport, and proof-of-key-ownership. The work is technically sound. Ed25519 passports, DID resolution, interop tests passing across three languages. Real engineering, solving a real problem. But it is the wrong problem for discovery.
“Is this agent real?” is a necessary check. It is not a useful filter. A verified agent with a clean DID Document and a valid trust registry entry that cannot do what you need is just a well-authenticated waste of time.
How every other discovery system works
When you need a cardiologist, you do not browse a list of every doctor and check each one’s identity. You search by specialty and board certification. The credential routes you to the right person. Identity confirmation happens after.
When you need an electrician, you check the state licensing board. You filter by license type, active status, and geographic area. The licensing board does not just confirm the electrician exists. It confirms the electrician is qualified. An unlicensed electrician with a verified identity is still someone you cannot legally hire.
When you need a lawyer, you search bar associations by practice area and jurisdiction. The attorney’s name is the output of the search, not the input.
This pattern is not accidental. It is how discovery works in every domain where the cost of choosing wrong is high. Medical boards, bar associations, contractor licensing, financial certifications. The credential is the filter. Identity is the handshake.
The history is older than you think
The Yellow Pages organized businesses by category, not alphabetically by name. The entire information architecture was capability-first. White Pages existed too, but only worked when you already knew who you wanted. Yellow Pages worked when you knew what you needed.
DNS maps names to addresses. Pure identity resolution. It has no concept of “find me a server that does X.” Identity-first resolution requires you to already know what you are looking for. DNS could not answer “find me X,” which is precisely why search engines had to be invented. Google indexes by content relevance, not by domain name.
Every discovery system that has ever worked at scale puts capability ahead of identity. The agent ecosystem is building White Pages and DNS when it needs Yellow Pages and search engines. That will not scale.
The firehose problem
When 10 agents exist, identity-first discovery works fine. You can inspect each one. When 10,000 agents pass identity verification for the same task category, you have 10,000 verified agents and you are no closer to choosing.
This is not a hypothetical. Information retrieval theory has studied this tradeoff for decades. In 1979, C. J. van Rijsbergen formalized the precision-recall tradeoff: systems optimized for recall return everything that might be relevant, at the cost of flooding users with irrelevant results. Systems optimized for precision return fewer results, but the right ones.
Identity-first discovery maximizes recall. Credential-first discovery maximizes precision. For agent selection, where you typically need one qualified agent rather than a complete census, precision is what matters.
Without credential-based filtering at the discovery layer, every verified agent can knock on every door. That is not trust infrastructure. That is a firehose with signatures.
This is not a new idea
In 1966, Jack Dennis and Earl Van Horn introduced capability-based addressing at MIT. A capability is an unforgeable token that simultaneously names a resource and authorizes access to it. The capability routes you to the resource. You do not find the resource first and then present credentials. Possession of the capability is both necessary and sufficient.
That is how a signed attestation works. “This wallet holds governance tokens on Ethereum” is a capability token. Possession of it should be sufficient to route an agent to services that require that credential. No separate identity check needed at the discovery layer.
The multi-agent systems community learned this lesson decades ago. The FIPA Agent Management Specification defined a Directory Facilitator where agents register capabilities and other agents query by capability description. Attribute-based matching, not identity lookup. The agent identity frameworks being built today are ignoring prior art from their own field.
NIST formalized the broader principle as Attribute Based Access Control: identity is just one attribute among many, and often not the most important one. What you hold, what you are certified for, and what conditions you meet tell a system more about whether you should have access than your name ever could.
Why it matters more for agents than for humans
Humans have a natural rate limiter on identity creation. Creating a new professional identity takes years of education, licensing, and reputation building. An AI agent can create a new identity in milliseconds. Unlimited keypairs, unlimited DIDs, unlimited trust registry entries.
In a world of synthetic identity, identity verification is checking the lock on a door with no walls. A signed DID Document proves key control. It does not prove the agent behind that key can do anything useful. It does not prove the wallet behind the agent holds anything of value. It does not prove the agent has ever successfully completed a task.
Credentials backed by verifiable state are different. On-chain holdings cannot be fabricated. Staking positions cannot be faked. Governance token ownership is observable. Wallet auth — a signed attestation that a wallet holds specific assets on a specific chain at a specific block — is a credential that resists synthetic inflation in a way that identity alone never can.
The more agents that exist, the less identity tells you and the more credentials matter. Wallet auth is the filter that scales.
The credential-first flow
The discovery architecture should invert:
- Filter by credential. “Show me agents whose wallets hold governance tokens on Ethereum, with active staking positions, attested by a recognized issuer.” This is a structured query against verifiable, machine-readable data. No ambiguity, no self-reported capabilities, no natural language matching.
- Route to the qualified agent. The credential narrows the field from thousands to the handful that actually meet the requirements.
- Verify identity on connection. Confirm the agent’s DID, check the trust registry, validate the transport layer. All the identity work the ecosystem is building goes here. It is necessary. It is just not the first step.
Self-described capabilities do not scale. Two people use the same term for the same concept less than 20% of the time. One agent says “payment processing,” another says “financial transactions.” Structured credentials bypass this entirely. On-chain state, signed attestations, verifiable conditions. They are machine-readable, unambiguous, and comparable without interpretation.
Credentials route. Identity confirms.
The agent ecosystem is doing important work on identity. DIDs, trust registries, encrypted transport, and proof-of-key-ownership are real infrastructure that real systems need. None of it is wasted.
But it is step three in a flow that is being built as if it were step one. Identity tells you the agent is real. Credentials tell you the agent is relevant. Discovery systems that get the order wrong do not fail gracefully. They flood every participant with every verified agent in the registry and call it trust.
The credential is the filter. Identity is the handshake. Every discovery system in history has known this. Agent infrastructure should too.