Select Queries from DVD Rental database

  1. Film titles and rental rates (Aliased)
   SELECT title AS "Movie Title", rental_rate AS "Rate" 
   FROM film;

  1. Customer names and emails (Aliased)
   SELECT first_name AS "First Name", last_name AS "Last Name", email 
   FROM customer;

  1. Films sorted by rental rate (DESC) and title (ASC)
   SELECT * FROM film 
   ORDER BY rental_rate DESC, title ASC;

  1. Actor names sorted by last name, then first name
   SELECT first_name, last_name 
   FROM actor 
   ORDER BY last_name, first_name;

  1. Unique replacement costs
   SELECT DISTINCT replacement_cost 
   FROM film;

  1. Film title and length (Aliased)
   SELECT title, length AS "Duration (min)" 
   FROM film;

  1. Customer names and active status (Aliased)
   SELECT first_name, last_name, active AS "Is Active" 
   FROM customer;

  1. Film categories sorted alphabetically
   SELECT name FROM category 
   ORDER BY name ASC;

  1. Films by length (DESC)
   SELECT title, length 
   FROM film 
   ORDER BY length DESC;

  1. Actor names sorted by first name (DESC)

    SELECT first_name, last_name 
    FROM actor 
    ORDER BY first_name DESC;
    

  1. Unique ratings

    SELECT DISTINCT rating 
    FROM film;
    

  1. Unique rental durations

    SELECT DISTINCT rental_duration 
    FROM film;
    

  1. First unique customer ID based on active status

    SELECT MIN(customer_id) AS customer_id, active 
    FROM customer 
    GROUP BY active 
    ORDER BY customer_id;
    

  1. Earliest rental date for each customer

    SELECT customer_id, MIN(rental_date) AS rental_date 
    FROM rental 
    GROUP BY customer_id 
    ORDER BY customer_id;
    

  1. 10 shortest films

    SELECT title, length 
    FROM film 
    ORDER BY length ASC 
    LIMIT 10;
    

  1. Top 5 customers with highest IDs

    SELECT first_name, last_name 
    FROM customer 
    ORDER BY customer_id DESC 
    LIMIT 5;
    

  1. Unique store IDs from inventory

    SELECT DISTINCT store_id 
    FROM inventory;
    

  1. Unique replacement costs (Sorted ASC)

    SELECT DISTINCT replacement_cost 
    FROM film 
    ORDER BY replacement_cost ASC;
    

  1. First rental date for each store

    SELECT store_id, MIN(rental_date) AS rental_date 
    FROM rental 
    JOIN inventory ON rental.inventory_id = inventory.inventory_id
    GROUP BY store_id 
    ORDER BY store_id;
    

  1. Unique film ratings sorted alphabetically

    SELECT DISTINCT rating 
    FROM film 
    ORDER BY rating ASC;
    

  1. Films by rating (ASC) and length (DESC)

    SELECT * FROM film 
    ORDER BY rating ASC, length DESC;
    

  1. Actor names (Last Name ASC, First Name DESC)

    SELECT first_name, last_name 
    FROM actor 
    ORDER BY last_name ASC, first_name DESC;
    

  1. Films by replacement cost (ASC) and rental rate (DESC)

    SELECT * FROM film 
    ORDER BY replacement_cost ASC, rental_rate DESC;
    

  1. Customer names (Last Name ASC, First Name DESC)

    SELECT first_name, last_name 
    FROM customer 
    ORDER BY last_name ASC, first_name DESC;
    

  1. Rentals (Customer ID ASC, Rental Date DESC)

    SELECT * FROM rental 
    ORDER BY customer_id ASC, rental_date DESC;
    

  1. Films (Rental Duration ASC, Title DESC)

    SELECT * FROM film 
    ORDER BY rental_duration ASC, title DESC;
    

NUMBERING ISSUE IS THERE I ENTERED CORRECT BUT IT IS NOT CHANGING

Share of Voice in AI Search: Why Your Competitors Are Getting Cited in ChatGPT and Perplexity (And You Aren’t)

Share of Voice in AI Search: Why Your Competitors Are Getting Cited in ChatGPT and Perplexity (And You Aren’t)

Your competitors are showing up in ChatGPT responses, Perplexity answers, and Claude citations. Your brand isn’t. This isn’t random—it’s a measurable gap in AI search share of voice that’s costing you visibility as AI engines handle 30%+ of search queries and rising.

AI search engines prioritize cited sources from authoritative domains with clear topical expertise. Perplexity and ChatGPT increasingly include inline citations, making source attribution visible to users and creating a new brand visibility channel beyond traditional search results. The brands getting cited consistently aren’t luckier—they’ve built the structured content assets and authority signals that AI retrieval systems reward.

This guide breaks down how AI engines select sources, what content formats they prioritize, and how to measure your AI search share of voice.

How AI Search Engines Actually Select Sources

AI search engines don’t “rank” pages like Google—they retrieve and synthesize. When you ask Perplexity a question, it doesn’t return ten blue links. It identifies relevant sources, extracts specific claims, and generates an answer with inline citations. This fundamental difference changes everything about optimization.

Retrieval-Augmented Generation (RAG) Explained

AI engines use RAG systems: they search their index for relevant content, extract information from those sources, then generate responses citing where each piece of information came from. Your goal isn’t to rank first—it’s to become a retrieval source worth citing.

According to OpenAI’s research on retrieval systems, AI models weight sources based on:

  • Topical relevance: Does the content directly address the query?
  • Information density: Can specific claims be easily extracted?
  • Authority signals: Does the domain demonstrate expertise in this topic?
  • Structural clarity: Is the content organized for machine reading?

Perplexity’s official documentation confirms they prioritize sources that “provide comprehensive, accurate information directly answering the user’s question” while favoring domains with established topical authority.

Why Traditional SEO Tactics Fail in AI Search

Traditional SEO optimizes for keywords, backlinks, and click-through rates. AI search optimization requires different inputs:

Traditional SEO AI Search Optimization
Target keyword rankings Target citation inclusion
Optimize for crawlers Optimize for information extraction
Build backlink profiles Build topical authority clusters
Track position metrics Track citation frequency and query inclusion

Your existing SEO strategy won’t automatically translate to AI search visibility. The content formats, structural elements, and authority signals that drive AI citations differ significantly from what drives Google rankings.

Content Formats That Drive AI Citations

Structured content formats perform significantly better in AI retrieval. These formats provide clear, extractable information that AI models can easily reference and cite.

1. FAQ Pages and Q&A Content

AI engines train on question-answer pairs. FAQ pages with explicit questions and direct answers are primed for retrieval.

Effective structure:

  • Questions as H2 headers
  • Direct answers in first paragraph (no fluff)
  • Bulleted supporting details
  • Concrete examples and data points

Example: Instead of “Project Management Software Features,” use “How Does Project Management Software Handle Resource Allocation?” with a direct answer explaining specific allocation mechanisms.

2. How-To Guides with Step Sequences

Process-oriented content gets cited when users ask “how to” questions. The key is explicit numbering and clear dependencies between steps.

Best practices:

  • Numbered steps (not bullets) for sequential actions
  • Prerequisites clearly stated
  • Tool/requirements lists
  • Troubleshooting sections

AI engines extract and cite specific steps when relevant. Ambiguous prose gets skipped.

3. Comparison Pages

“X vs Y” queries dominate AI search. Comparison pages that objectively break down differences across consistent dimensions become go-to sources.

Required structure:

  • Comparison table with consistent criteria
  • Feature-by-feature analysis
  • Use case recommendations
  • Pricing/contextual differences

4. Glossary and Definition Content

AI engines frequently cite definitions and explanations of technical concepts. Build comprehensive glossaries with:

  • Clear, concise definitions (1-2 sentences)
  • Context and examples
  • Related concepts linked
  • Citations to primary sources

Track your AI search visibility and citation performance with Texta analytics

Building Topical Authority for AI Search

AI engines evaluate authority differently than Google. They prioritize demonstrated expertise within specific topics rather than overall domain authority.

Cluster Content Around Core Topics

Build content clusters covering topics comprehensively. Each cluster should include:

  • Pillar page: Broad overview covering all subtopics
  • Cluster content: Deep dives into specific aspects
  • Supporting content: Definitions, examples, FAQs

When AI engines crawl your domain, they recognize patterns of comprehensive coverage. This signals expertise, increasing citation likelihood across all queries in that topic area.

First-Mover Advantage in Emerging Categories

Brands that establish topical authority early in high-volume AI query categories tend to maintain citation leadership as AI engines refine their source selection algorithms. Monitor emerging AI search trends in your industry and create foundational content before competitors saturate the topic.

Signal Trust Through Brand Co-Occurrences

AI engines use brand mentions and contextual proximity as authority signals. When your brand appears alongside recognized experts in authoritative publications, AI systems associate your domain with trustworthy information.

Tactics:

  • Contribute expert quotes to industry publications
  • Engage in podcast interviews and roundups
  • Build relationships with analysts and researchers
  • Target mentions in third-party review sites

Technical Foundations for AI Search Visibility

Technical SEO fundamentals remain critical for AI discovery. Unlike Google’s sophisticated rendering, many AI crawlers struggle with JavaScript-heavy sites, making clean HTML and structured data essential.

Critical Technical Requirements

1. Crawlability and Site Architecture

  • Clean HTML content accessible without JavaScript rendering
  • XML sitemaps submitted to major AI engines
  • Logical URL structure and internal linking
  • Fast page load speeds

2. Structured Data Markup

  • Schema.org markup for articles, FAQs, how-to guides
  • Organization schema with entity descriptions
  • Author attribution with clear expertise indicators
  • Publication dates and last-updated timestamps

3. Content Structure

  • Semantic HTML (proper heading hierarchy)
  • Descriptive title tags and meta descriptions
  • Clear paragraph structure and section breaks
  • Alt text for images and captions for context

Common Technical Pitfalls

  • JavaScript-heavy SPAs: AI crawlers often miss content rendered client-side
  • Infinite scroll pagination: Content beyond initial load may not be indexed
  • Thin content walls: Gated content or paywalls block AI access
  • Orphaned pages: Content without internal links appears less authoritative

Learn how to structure your content for AI retrieval with Texta’s onboarding guide

Measuring AI Search Share of Voice

AI search share of voice requires different measurement than traditional SEO. Metrics should track citation frequency, query inclusion rate, and positioning within AI responses rather than keyword rankings.

Key Metrics to Track

Citation Frequency: How often your domain appears as a cited source across AI engines for queries in your category. Track weekly to identify content performance trends.

Query Inclusion Rate: Percentage of relevant queries where your brand appears in AI responses. Compare against competitors to assess relative performance.

Citation Position: Whether you’re cited as a primary source (early in response, multiple citations) or secondary source (single citation, supporting claim). Primary citations drive stronger brand association.

Brand Mention Volume: Unlinked mentions of your brand in AI responses, even without formal citations. These still contribute to brand visibility.

How to Track AI Search Performance

Manual Monitoring: Run category-relevant queries through ChatGPT, Perplexity, and Claude weekly. Document which sources appear and note patterns in citation types.

Automated Tools: Emerging platforms track AI search mentions and citations programmatically. These tools provide scalable monitoring but vary in coverage accuracy.

Competitive Benchmarking: Identify which competitors consistently appear in AI responses. Analyze their content structure, topic coverage, and technical implementation to identify gaps in your strategy.

Get started with AI search optimization using Texta’s comprehensive platform

Common Objections (And Why They’re Wrong)

“AI search traffic is too small to justify investment”

AI search is projected to handle 30%+ of search queries by 2026. Early investment builds citation authority that compounds as adoption grows, similar to early Google SEO advantages. AI citations also drive brand credibility beyond direct traffic—being cited in ChatGPT responses signals authority to prospects researching solutions.

“We can’t control whether AI engines cite our content”

True, but you can optimize the factors AI engines use for source selection: topical authority, content structure, and technical accessibility. Focus on the inputs within your control rather than the unpredictable output. Brands consistently cited in AI responses aren’t lucky—they’ve built systematic advantages in content quality and authority signaling.

“Our existing SEO strategy should cover AI search”

Traditional SEO targets keyword rankings and click-throughs. AI search requires optimizing for citation inclusion, meaning question-focused content, clear claim structure, and authoritative context signals that differ from standard SEO best practices. You need distinct tactics and measurement frameworks.

“AI search is just a trend that will fade”

AI search represents a fundamental shift in information retrieval, with Google, Microsoft, and OpenAI all investing heavily. The trend is toward AI-generated answers rather than algorithmic ranked results, making AI citation a persistent channel. Early adopters build citation advantages that compound over time.

Action Plan: Getting Started with AI Search Optimization

Week 1: Audit and Baseline

  1. Run 20-30 category-relevant queries through ChatGPT, Perplexity, and Claude
  2. Document which sources appear and note content patterns
  3. Identify competitors consistently cited in your space
  4. Audit your own content for AI-friendliness (structure, clarity, technical accessibility)

Week 2-4: Content Optimization

  1. Rewrite top 10 priority pages in question-answer format
  2. Add FAQ sections to pillar pages
  3. Implement schema markup (FAQ, HowTo, Article)
  4. Fix technical barriers (JavaScript rendering, sitemap issues)

Month 2: Authority Building

  1. Build content clusters around 2-3 core topics
  2. Pursue guest contributions and expert quotes
  3. Create comparison pages for major competitors
  4. Develop glossary content for key concepts

Month 3: Measurement and Iteration

  1. Implement citation tracking system
  2. Analyze which content types earn most citations
  3. Double down on high-performing formats
  4. Expand successful clusters to adjacent topics

Try Texta

AI search share of voice represents a new zero-click discovery channel where traditional SEO tactics fail. Brands that build topical authority and structured content assets now will capture citation advantages that compound as AI search adoption grows.

Texta helps you identify AI search opportunities, structure content for retrieval optimization, and track your citation performance across ChatGPT, Perplexity, and Claude. Get started with Texta today to build your AI search visibility before competitors cement their citation advantages.

Multi‑Model AI Chat Platforms: Why Comparing AI Models in One Workspace Is Becoming Essential

One AI model rarely gives the best answer every time. Developers, researchers, and analysts increasingly test the same prompt across several models to compare reasoning, creativity, and accuracy. That workflow has created a new category of tools called multi‑model AI chat platforms. Instead of switching between separate apps for GPT‑5, Claude, Gemini, or open models like Llama, platforms such as The Multi‑Model AI Lab allow users to send a single prompt and see responses side by side. The result is faster experimentation, better outputs, and a clearer understanding of how different AI systems behave.

What a Multi‑Model AI Chat Platform Actually Does

A multi‑model AI chat platform is a workspace that connects several large language models in one interface. Instead of interacting with a single chatbot, users send prompts to multiple AI systems simultaneously and compare the responses.

Large language models are a core technology behind modern conversational AI. Research on natural language processing explains that these models are trained on massive text datasets to generate human‑like language and perform tasks such as summarization, translation, and reasoning (Khurana et al., 2022). Because each model is trained differently and optimized for different tasks, their answers often vary significantly.

That variation is exactly why multi‑model platforms exist. Instead of guessing which AI will perform best, users can compare them instantly.

A multi‑model workflow reduces the risk of relying on a single AI output, which can sometimes sound confident even when it is incorrect.

The concept mirrors ideas from other technology systems where multiple models coexist. For example, a multi‑model database supports several data models inside a single backend rather than forcing developers to choose just one structure. The same philosophy now applies to AI chat tools: combine capabilities instead of committing to a single approach.

Typical Workflow Inside a Multi‑Model AI Chat Tool

Most platforms follow a similar pattern:

Enter a prompt once.
Select several AI models.
Send the prompt to all models simultaneously.
Compare the results side by side.
refine the prompt or choose the best answer.
For example, using The Multi‑Model AI Lab, a user can send a prompt to dozens of models at the same time and watch responses stream in real time. Instead of opening multiple browser tabs, everything appears in a single dashboard.

Why Teams Are Moving Toward Multi‑Model AI Workflows

AI tools are improving quickly, but no single model consistently dominates across all tasks. One model may excel at coding, another at reasoning, and another at creative writing.

Research on generative conversational AI highlights both the opportunities and risks of relying on AI systems, including issues with reliability and output quality across contexts (Dwivedi, Kshetri, Hughes, 2023). Multi‑model platforms address this challenge by letting users evaluate several outputs before choosing one.

Key Advantages of Comparing Multiple AI Models

Better answer quality: comparing outputs helps identify the most accurate or useful response.
Reduced hallucination risk: conflicting answers can signal when a model might be wrong.
Task optimization: some models perform better at code generation, while others excel at reasoning or summarization.
Faster experimentation: developers test prompt variations across multiple systems instantly.
Cost efficiency: one platform subscription can replace several individual AI tools.
When several models agree on a result, confidence in the output increases. When they disagree, it signals that deeper verification may be needed.

How Side‑by‑Side Model Comparison Improves AI Evaluation

Running models side by side is not just convenient. It changes how people evaluate AI systems.

Over‑the‑shoulder view of developer comparing multiple AI responses in side‑by‑side chat panels

Developers often measure outputs across several criteria: reasoning depth, speed, factual accuracy, and style. Viewing these differences in real time reveals patterns that are hard to notice when switching between separate tools.

Example: Comparing Outputs Across Popular AI Models

Different AI models often produce distinct responses to the same question.

Typical Differences When Running the Same Prompt

Model Type Typical Strength Example Use Case
Frontier proprietary models strong reasoning and broad knowledge research summaries, analysis
Open models such as Llama customizable and flexible experimentation, local deployment
Specialized reasoning models structured problem solving math, coding tasks
Multimodal models image and text understanding file analysis, visual prompts
Llama, a family of large language models released by Meta AI starting in 2023, is widely used for experimentation and open research environments.

Side‑by‑side platforms make these differences obvious. Instead of reading one answer and moving on, you see multiple interpretations instantly.

Core Features That Define Modern Multi‑Model AI Platforms

Early AI comparison tools only displayed multiple chat outputs. By 2026, the category has expanded with features designed for serious research and productivity.

Capabilities Users Expect in 2026

Simultaneous model responses so outputs appear in parallel.
File uploads for analysis including PDFs, spreadsheets, and images.
Prompt reuse and editing for quick iteration.
Image generation across models.
Model routing where the system sends tasks to the most suitable AI.
Platforms like The Multi‑Model AI Lab combine these capabilities in one workspace. Instead of juggling APIs, users interact with many models through a single chat interface.

Table: Common Capabilities in Multi‑Model AI Platforms

Feature Why It Matters
Side‑by‑side model comparison Enables fast evaluation of AI responses
Real‑time streaming outputs Lets users observe reasoning or generation speed
File and document analysis Allows AI to process reports, datasets, or research papers
Multi‑modal generation Supports text, images, and other media
Unified subscription Avoids managing several separate AI accounts
Who Benefits Most From Multi‑Model AI Platforms

Although anyone can use them, certain groups gain the most value from multi‑model systems.

Collaborative workspace with creators and developers using laptops to compare AI model outputs

Developers and AI Researchers

Developers test prompts across different models to see how architecture differences affect results. Comparing reasoning chains, formatting, and coding accuracy helps teams choose the right model for production tasks.

Product Managers and Analysts

Product teams often analyze documents, research reports, or datasets. Running the same file through multiple models can reveal different insights or summaries.

Using a unified platform such as The Multi‑Model AI Lab platform also avoids the friction of switching between tools while evaluating outputs.

Content Creators and Writers

Creative professionals frequently compare tone and style across models. One AI might produce structured outlines while another writes more engaging prose.

Running several responses at once speeds up ideation and helps identify stronger angles for articles, scripts, or marketing copy.

Common Misconceptions About Multi‑Model AI Tools

Some users assume multi‑model platforms are only useful for AI researchers. That is not accurate. They also solve everyday workflow problems for general users.

Myth: One Model Is Always the Best Choice

AI models evolve quickly. The model that performs best today may not dominate next year. Multi‑model platforms keep users flexible by allowing instant switching and comparison.

Myth: Using Multiple AI Systems Is Complicated

Modern tools hide the complexity behind a single interface. For example, The Multi‑Model AI Lab allows users to interact with dozens of models without API keys or manual configuration.

This simplicity is one reason the category has gained attention among power users who want fast experimentation without engineering overhead.

Where Multi‑Model AI Platforms Are Heading Next

The next phase of AI tools focuses less on single models and more on coordination between many models. Several trends are emerging.

AI Systems That Collaborate Instead of Compete

Future platforms may route different parts of a task to different models automatically. One model could generate a draft, another verify facts, and another optimize formatting.

This layered workflow resembles distributed computing systems where specialized components perform separate roles.

Model Benchmarking Built Into Everyday Tools

Expect more built‑in evaluation features, such as:

automated response scoring
reasoning trace comparisons
dataset testing across models
prompt performance analytics
These tools will turn AI chat platforms into practical research environments rather than simple chat apps.

Conclusion

AI models keep improving, but the idea that one system can handle every task perfectly is fading. Comparing outputs from several models is becoming the smarter workflow for developers, researchers, and power users who want more reliable results.

Multi‑model AI chat platforms simplify that process by placing dozens of models inside a single interface. Instead of switching between tools, you can test prompts, analyze files, and evaluate outputs instantly.

If you want to experiment with this workflow yourself, try The Multi‑Model AI Lab. Running the same prompt across multiple frontier AI models side by side quickly shows how different systems reason, write, and analyze information. That comparison often reveals insights a single model would miss.

How to Build AI Agents That Actually Work in 2026 AUTO TEST

Everyone is building AI agents in 2026. Most of them are terrible.

I have spent the last year building, testing, and breaking AI agents across dozens of use cases — from research assistants to code generators to automated customer support pipelines. Along the way, I watched countless projects fail spectacularly, including several of my own.

The pattern is always the same: a developer gets excited about a demo, spins up a quick prototype, shows it to stakeholders, and then spends six months trying to make it reliable enough for production. The demo-to-production gap for AI agents is wider than almost any other technology I have worked with.

This article is the guide I wish I had when I started. A practical, no-hype framework for building AI agents that actually work — not just in demos, but in the real world where users do unexpected things and uptime matters.

Why Most AI Agents Fail

Before we build anything, let us understand the failure modes. After analyzing dozens of failed agent projects (mine and others), I have identified four recurring patterns.

Failure Mode 1: Over-Engineering from Day One

The most common mistake is starting with a complex multi-agent orchestration system when a single well-prompted LLM call would do the job. I see teams building elaborate frameworks with 15 different agent types before they have even validated that the core task works.

The fix: Start with the simplest possible implementation. A single LLM call with good instructions. Only add complexity when you can prove it is necessary.

Failure Mode 2: Poor Prompt Design

Many developers treat prompts as an afterthought — a quick instruction tacked onto the beginning of a context window. But prompt design is the single most important factor in agent reliability. A well-designed prompt with a mediocre model will outperform a poorly-designed prompt with a frontier model almost every time.

Failure Mode 3: Wrong Architecture for the Task

Not every task needs an agent. If you can solve the problem with a simple chain of LLM calls (input → process → output), do that. Agents add autonomy, which adds unpredictability. That unpredictability is only worth it when the task genuinely requires adaptive decision-making.

Failure Mode 4: No Evaluation Framework

If you cannot measure whether your agent is working, you cannot improve it. Most teams skip evaluation entirely and rely on vibes — “it seems to work pretty well.” That is how you ship agents that fail 30% of the time and nobody notices until users start complaining.

The PTME Framework: Plan, Tools, Memory, Evaluation

Here is the framework I use for every agent project. It is not fancy, but it works.

Step 1: Plan — Define the Agent’s Decision Space

Before writing any code, answer these questions:

  1. What decisions does the agent need to make? List every point where the agent chooses between actions.
  2. What information does it need to make each decision? This determines your context strategy.
  3. What are the failure modes for each decision? This shapes your error handling.
  4. What should happen when the agent is uncertain? This determines your fallback strategy.

Write this down. Literally. I keep a one-page “Agent Decision Map” for every agent I build.

Agent: Research Assistant
Decisions:
  1. Which sources to search → Needs: user query, available tools
  2. Whether results are relevant → Needs: user query, search results
  3. When to stop searching → Needs: result quality threshold, max iterations
  4. How to synthesize findings → Needs: all collected results, output format
Failure modes:
  - No relevant results found → Ask user to refine query
  - Contradictory sources → Present both with confidence scores
  - Token limit approaching → Summarize and present partial results

Step 2: Tools — Give the Agent Capabilities

Tools are functions your agent can call to interact with the world. The quality of your tools determines the ceil

[Gemini] Building a LINE E-commerce Chatbot That Can “Tell Stories from Images”

image-20260225234804185

image-20260225234804185

image-20260225234701217

Reference articles:

Background

I believe many people have used the combination of LINE Bot + Function Calling. When a user asks “What clothes did I buy last month?”, the Bot calls the database query function, retrieves the order data, and then Gemini answers based on that JSON:

Traditional process designed by developers:

User: "Help me see the jacket I bought before"
Bot: [Call get_order_history()]
Function returns: {"product_name": "Brown pilot jacket", "order_date": "2026-01-15", ...}
Gemini: "You bought a brown pilot jacket on January 15th for NT$1,890."

The answer is completely correct, but it always feels like something is missing—the user is talking about “that jacket,” and Gemini is just restating the text in the JSON, with no way to “confirm” what the jacket looks like. If there happen to be three jackets in the database, the AI can’t even determine which one is the one the user remembers.

AI can read text, but it can’t see pictures—this limitation has always been a blind spot in the traditional Function Calling architecture.

Google Chrome 2026-02-26 10.34.51

Google Chrome 2026-02-26 10.34.58

This problem was truly solved only after Gemini introduced Multimodal Function Response.

What is Multimodal Function Response?

The traditional Function Calling process is as follows:

[User message] → Gemini → [function_call] → [Execute function] → [Return JSON] → Gemini → [Text answer]

Multimodal Function Response changes that middle step. The function can not only return JSON, but also include images (JPEG/PNG/WebP) or documents (PDF) in the same response:

Google Chrome 2026-02-25 23.04.28

[User message] → Gemini → [function_call] → [Execute function] → [Return JSON + image bytes] → Gemini → [Text answer that has seen the image]

When Gemini generates the next round of answers, it can “see” both the structured data and the image returned by the function, thereby generating richer and more accurate responses.

The official currently supported media formats:

Category Supported formats
Image image/jpeg, image/png, image/webp
Document application/pdf, text/plain

The application scenarios for this feature are very broad: e-commerce customer service (identifying product images), medical consultation (analyzing PDF inspection reports), design review (giving suggestions based on screenshots)… almost all scenarios that require “functions to return visual data for AI analysis” are applicable.

Project Goal

This time, I used Multimodal Function Response to create a LINE e-commerce customer service robot, demonstrating the following scenario:

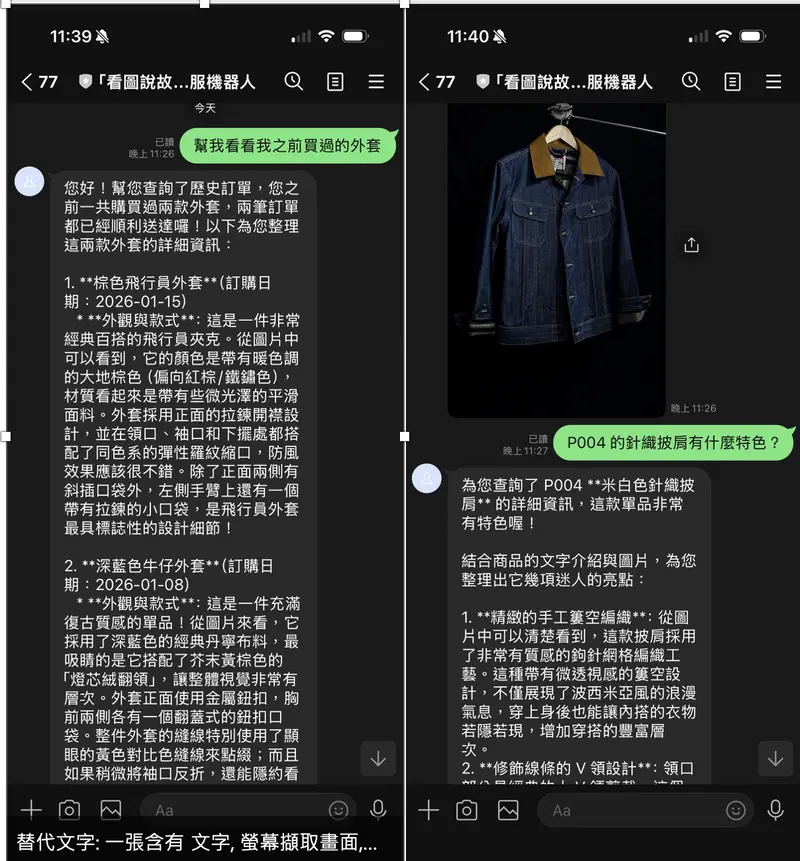
User: “Help me see the jacket I bought before” Bot (traditional): “You bought a brown pilot jacket.” Bot (Multimodal): “From the photo, you can see that this is a brown pilot jacket, made of lightweight nylon, with metal zipper pockets on the sides. This is your January 15th order ORD-2026-0115, for a total of NT$1,890, and it has been delivered.” + Product photo

The difference is obvious: Gemini really “saw” the jacket, rather than just restating the text in the database.

Architecture Design

Why not use Google ADK?

Originally, this repo used Google ADK (Agent Development Kit) to manage the Agent. The Runner and Agent of ADK encapsulated the entire process of Function Calling, which was very convenient.

But Multimodal Function Response requires manually including image bytes in the parts of the function response, and ADK completely encapsulates this layer, so it can’t be intervened.

So this time, I directly used google.genai.Client to implement the iterative cycle of function calls myself:

# Old architecture (ADK)
runner = Runner(agent=root_agent, ...)
async for event in runner.run_async(...):
    ... # ADK handles all function calls for you, but you can't control the response content

# New architecture (directly use google.genai)
response = await client.aio.models.generate_content(
    model=model,
    contents=contents,
    config=types.GenerateContentConfig(tools=ECOMMERCE_TOOLS),
)
# Handle function calls yourself, include images yourself

Overall architecture

LINE User
    │
    ▼ POST /
FastAPI Webhook Handler
    │
    ▼
EcommerceAgent.process_message(text, line_user_id)
    │
    ├─ ① Call Gemini (with conversation history)
    │
    ├─ ② Gemini decides to call a tool → function_call
    │
    ├─ ③ _execute_tool()
    │ ├─ Execute query function (search_products / get_order_history / get_product_details)
    │ └─ Read real product photos in the img/ directory (Unsplash JPEG)
    │
    ├─ ④ Construct Multimodal Function Response
    │ └─ FunctionResponsePart(inline_data=FunctionResponseBlob(data=image_bytes))
    │
    ├─ ⑤ Call Gemini again (Gemini sees the image + data)
    │
    └─ ⑥ Return (ai_text, image_bytes)
    │
    ▼
LINE Reply:
  TextSendMessage(text=ai_text)
  ImageSendMessage(url=BOT_HOST_URL/images/{uuid}) ← FastAPI /images endpoint provides

How to get product images?

This demo uses real Unsplash clothing photography photos. Each of the five products corresponds to an actual photo of the item, stored in the img/ directory. The reading logic is very simple:

def generate_product_image(product: dict) -> bytes:
    """Read the product image and return JPEG bytes."""
    with open(product["image_path"], "rb") as f:
        return f.read()

Each product in PRODUCTS_DB has an image_path field pointing to the corresponding image file:

Product ID Name Image
P001 Brown pilot jacket tobias-tullius-…-unsplash.jpg
P002 White cotton university T mediamodifier-…-unsplash.jpg
P003 Dark blue denim jacket caio-coelho-…-unsplash.jpg
P004 Beige knitted shawl milada-vigerova-…-unsplash.jpg
P005 Light blue simple T-shirt cristofer-maximilian-…-unsplash.jpg

The image bytes read have two uses:

  1. As FunctionResponseBlob to include for Gemini analysis—real photos allow Gemini to describe the actual fabric texture and tailoring details
  2. Temporarily stored in the image_cache dict, provided to the LINE Bot for display through the FastAPI /images/{uuid} endpoint

Detailed explanation of the core code

Step 1: Define tools (FunctionDeclaration)

from google.genai import types

ECOMMERCE_TOOLS = [
    types.Tool(function_declarations=[
        types.FunctionDeclaration(
            name="get_order_history",
            description="Query the current user's order history",
            parameters=types.Schema(
                type=types.Type.OBJECT,
                properties={
                    "time_range": types.Schema(
                        type=types.Type.STRING,
                        description="Time range: all / last_month / last_3_months",
                        enum=["all", "last_month", "last_3_months"],
                    ),
                },
                required=[],
            ),
        ),
        # ... search_products, get_product_details
    ])
]

Step 2: Function call cycle (up to 5 iterations)

async def process_message(self, text: str, line_user_id: str):
    contents = self._get_history(line_user_id) + [
        types.Content(role="user", parts=[types.Part(text=text)])
    ]

    for _iteration in range(5): # Up to 5 times, to prevent infinite loops
        response = await self._client.aio.models.generate_content(
            model=self._model,
            contents=contents,
            config=types.GenerateContentConfig(
                system_instruction=_SYSTEM_INSTRUCTION,
                tools=ECOMMERCE_TOOLS,
            ),
        )

        model_content = response.candidates[0].content
        contents.append(model_content)

        # Find all function_call parts
        fc_parts = [p for p in model_content.parts if p.function_call and p.function_call.name]

        if not fc_parts:
            # No function call → final text response
            final_text = "".join(p.text for p in model_content.parts if p.text)
            break

        # Has function call → execute tool, include image
        tool_parts = []
        for fc_part in fc_parts:
            result_dict, image_bytes = _execute_tool(
                fc_part.function_call.name,
                dict(fc_part.function_call.args),
                line_user_id,
            )
            tool_parts.append(
                self._build_multimodal_response(fc_part.function_call.name, result_dict, image_bytes)
            )

        contents.append(types.Content(role="tool", parts=tool_parts))

Step 3: Construct Multimodal Function Response (the most critical step)

def _build_multimodal_response(self, func_name, result_dict, image_bytes):
    multimodal_parts = []

    if image_bytes:
        # ⚠️ Note: Use FunctionResponseBlob here, not types.Blob!
        multimodal_parts.append(
            types.FunctionResponsePart(
                inline_data=types.FunctionResponseBlob(
                    mime_type="image/jpeg",
                    data=image_bytes, # raw bytes, SDK handles base64 internally
                )
            )
        )

    return types.Part.from_function_response(
        name=func_name,
        response=result_dict, # Structured JSON data
        parts=multimodal_parts or None, # ← Image is here! Gemini can "see" it after receiving it
    )

Gemini will receive both result_dict (order JSON) and image_bytes (product image) in the next generate_content call, and the generated answer can therefore describe the visual content of the image.

Step 4: LINE Bot simultaneously returns text + image

# main.py

ai_text, image_bytes = await ecommerce_agent.process_message(msg_text, line_user_id)

reply_messages = [TextSendMessage(text=ai_text)]

if image_bytes:
    image_id = str(uuid.uuid4())
    image_cache[image_id] = image_bytes # Temporary storage
    image_url = f"{BOT_HOST_URL}/images/{image_id}" # FastAPI provides service
    reply_messages.append(
        ImageSendMessage(
            original_content_url=image_url,
            preview_image_url=image_url,
        )
    )

await get_line_bot_api().reply_message(event.reply_token, reply_messages)

LINE Bot’s reply_message supports returning multiple messages at once (up to 5), so text and images can be sent simultaneously.

Potholes

❌ Pitfall 1: FunctionResponseBlob is not Blob

The most common pitfall: When constructing multimodal image parts, you cannot use types.Blob, you must use types.FunctionResponseBlob:

# ❌ Error (will TypeError)
types.FunctionResponsePart(
    inline_data=types.Blob(mime_type="image/jpeg", data=image_bytes)
)

# ✅ Correct
types.FunctionResponsePart(
    inline_data=types.FunctionResponseBlob(mime_type="image/jpeg", data=image_bytes)
)

Although both have mime_type and data fields, the inline_data field type of FunctionResponsePart is FunctionResponseBlob, and Pydantic validation will directly reject Blob. You can confirm this with python -c "from google.genai import types; print(types.FunctionResponsePart.model_fields)".

❌ Pitfall 2: aiohttp.ClientSession cannot be created at the module level

The original code directly created aiohttp.ClientSession() at the module level:

# ❌ Old method: module level
session = aiohttp.ClientSession() # Will warn or error if there is no running event loop
async_http_client = AiohttpAsyncHttpClient(session)

When importing main.py in pytest tests, because there is no running event loop, RuntimeError: no running event loop will appear. The solution is to change to lazy initialization, and create it only when it is actually needed for the first time:

# ✅ New method: lazy init
_line_bot_api = None

def get_line_bot_api():
    global _line_bot_api
    if _line_bot_api is None:
        session = aiohttp.ClientSession() # Called within the async route handler, guaranteeing an event loop
        _line_bot_api = AsyncLineBotApi(channel_access_token, AiohttpAsyncHttpClient(session))
    return _line_bot_api

❌ Pitfall 3: LINE Bot needs HTTPS URL to send images

Gemini receives raw bytes, but LINE Bot’s ImageSendMessage requires a publicly accessible HTTPS URL.

The solution is to add a /images/{image_id} endpoint in FastAPI, temporarily store the read image bytes in the image_cache dict, and LINE gets the image through this endpoint:

@app.get("/images/{image_id}")
async def serve_image(image_id: str):
    image_bytes = image_cache.get(image_id)
    if image_bytes is None:
        raise HTTPException(status_code=404, detail="Image not found")
    return Response(content=image_bytes, media_type="image/jpeg")

Use ngrok to expose port 8000 for local development, and use the service URL directly after Cloud Run deployment.

Demo Display

Mock database (default data for demo)

The system has 5 built-in products (all with real Unsplash photos), and each LINE user automatically binds two demo orders when querying orders for the first time:

Order number Date Product
ORD-2026-0115 2026-01-15 P001 Brown pilot jacket
ORD-2026-0108 2026-01-08 P003 Dark blue denim jacket

Scenario 1: “Help me see the jacket I bought before”

User sends: "Help me see the jacket I bought before"

[Gemini → function_call]
  get_order_history(time_range="all")

[_execute_tool execution]
  - get_order_history() returns two orders (P001, P003)
  - Read img/tobias-tullius-...-unsplash.jpg → Brown pilot jacket real photo bytes

[Multimodal Function Response]
  Part.from_function_response(
    name="get_order_history",
    response={"orders": [...], "order_count": 2},
    parts=[FunctionResponsePart(inline_data=FunctionResponseBlob(data=<photo>))]
  )

[Gemini responds after seeing the real photo]
  "From the photo, you can see that this is a brown pilot jacket, made of lightweight nylon with
   a glossy feel, and a metal zipper pocket on the left sleeve. This is your January 15, 2026
   order ORD-2026-0115, for a total of NT$1,890, status: delivered."

LINE displays: [Text] + [Brown pilot jacket real photo]

Scenario 2: “Are there any dark blue jackets?”

[Gemini → function_call]
  search_products(description="dark blue jacket", color="dark blue")

[Gemini sees the real photo of the P003 dark blue denim jacket]
  "Yes! This dark blue denim jacket (P003) in the photo features a retro stitching design,
   a lapel with metal buttons, and a very complete garment feel, priced at NT$1,490, with 8 in stock."

Scenario 3: “What are the features of the P004 knitted shawl?”

[Gemini → function_call]
  get_product_details(product_id="P004")

[Gemini sees the real photo of the beige knitted shawl]
  "The photo shows a beige handmade crochet shawl, with a V-neck design and tassels at the bottom,
   you can see the light lace-like mesh weave, elegant texture, priced at NT$1,290."

Traditional Function Response vs Multimodal Function Response

Traditional Multimodal
Function return Pure JSON JSON + image/PDF bytes
Gemini perception Text data Text + visual content
Answer quality “You bought a brown pilot jacket” “You can see the nylon texture in the photo, with a zipper pocket on the left sleeve…”
API difference Part.from_function_response(name, response) Part.from_function_response(name, response, parts=[...])
Applicable scenarios Pure text data queries Scenarios that require visual recognition/confirmation

Analysis and Outlook

This implementation gave me a new understanding of Gemini’s Function Calling capabilities.

The problem that Multimodal Function Response truly solves is to allow AI agents to bring in visual information in the action of “calling an external system” itself, instead of first checking text and then uploading images separately. This will be an important basic capability in areas highly related to visuals, such as e-commerce, medicine, and design.

However, there are still a few limitations worth noting:

  1. Image URLs cannot be used directly: Gemini’s FunctionResponseBlob requires raw bytes, and URLs cannot be filled in directly (this is different from bringing images directly in the prompt). If the image is originally a URL, you need to download it with requests.get() to bytes before passing it in.

  2. No display_name can also be used: The official documentation examples have display_name and $ref JSON reference, but in actual testing in google-genai 1.49.0, it can also work normally without filling in display_name, and Gemini can still see and analyze the image.

  3. Model limitations: The official mark supports the Gemini 3 series, but gemini-2.0-flash can also handle it normally in actual testing, and the API structure is the same.

There are many directions that can be extended in the future: let users send their own product photos for the Bot to compare, include PDF catalogs in the function response for Gemini to read directly, or let the Bot analyze the report images converted from DICOM in medical scenarios… As long as visual data can be obtained from external systems, Multimodal Function Response can make the AI’s answers more in-depth.

Summary

The focus of this LINE Bot implementation is only one sentence: Let the function response carry the image, and Gemini’s answer will be upgraded from “restating data” to “telling a story based on the picture”.

The core API is just these few lines, but it takes a lot of details to get the whole process working:

# The complete way for Gemini to see the image returned by the function
types.Part.from_function_response(
    name="get_order_history",
    response={"orders": [...]},
    parts=[
        types.FunctionResponsePart(
            inline_data=types.FunctionResponseBlob( # ← Not types.Blob!
                mime_type="image/jpeg",
                data=image_bytes,
            )
        )
    ],
)

The complete code is on GitHub, feel free to clone and play with it.

See you next time!

Gemini Tool Combo: Building a LINE Meetup Helper with Maps Grounding and Places API in a Single API Call

image-20260327164715459

image-20260327164715459

Reference articles:

Background

The combination of LINE Bot + Gemini is already very common. Whether it’s using Google Search Grounding to let the model look up real-time information or using Function Calling to let the model call custom logic, they are both mature when used alone.

But what if you want to achieve both “map location context” and “query real ratings” in the same question?

Taking restaurant search as an example, the traditional approach usually looks like this:

User: "Help me find a hot pot restaurant nearby with a rating of 4 stars or above"

Solution A (using only Maps Grounding):
Gemini has map context, but the rating information is described by AI itself, and accuracy is not guaranteed.

Solution B (using only Places API):
You can get real ratings, but there is no map context, and Gemini doesn't know where the user is.

To have both, you usually need to make two API calls, or manually connect them yourself.

AI can search maps and call external APIs, but doing both in a single call—has always been an awkward blank in the old Gemini API architecture.

Until March 17, 2026, Google released Gemini API Tooling Updates (by Mariano Cocirio), which provided an official solution to this problem.

What are Tool Combinations?

image-20260327163136077

Google announced three core features in this update:

1. Tool Combinations Developers can now attach built-in tools (such as Google Search, Google Maps) and custom Function Declarations simultaneously in a single Gemini API call. The model decides which tool to call and when to call it, and finally integrates the results to generate an answer.

2. Maps Grounding Gemini can now directly perceive map data, not just text descriptions of “location”, but truly has spatial context—knowing where the user is and what’s nearby.

3. Context Circulation Allows the context between multi-turn tool calls to flow naturally, and the model can fully remember the results of the first tool call when making the second call.

The key to this change is:

# Old approach (two tools cannot coexist)
types.Tool(google_search=types.GoogleSearch())
types.Tool(function_declarations=[MY_FN])

# New approach (the same Tool object, both coexist)
types.Tool(
    google_maps=types.GoogleMaps(),
    function_declarations=[MY_FN],
)

One line of modification opens up a whole new combination method.

Project Goal

This time, I used Tool Combinations to transform the existing linebot-spot-finder, upgrading it from “only Maps Grounding for rough answers” to “Google Maps context + Places API real data”:

After the user sends their GPS location, they enter: “Please find a hot pot restaurant with a rating of 4 stars or above, suitable for group dining, and list the name, address, and review summary.”

Bot (old Maps Grounding): “There are several hot pot restaurants nearby, and the ratings are good.” (AI describes it itself, which may not be accurate)

Bot (new Tool Combo): “Lao Wang Hot Pot | 100 Shimin Avenue, Xinyi District, Taipei City | Rating 4.6 (312) | Reviews: Large portions, great value for money, suitable for group dining; efficient service, fast serving.”

The difference is: Gemini now receives both map context (where you are) and the real structured data (rating numbers, review text) from the Places API, so the answer changes from a “vague description” to “informed information”.

Architecture Design

Overall Message Flow

LINE User sends GPS location
    │
    ▼
handle_location() → session.metadata stores lat/lng
    │
    └──► Returns Quick Reply (restaurant / gas station / parking lot)

LINE User sends text question (e.g. "Find a hot pot restaurant with a rating of 4 stars or above")
    │
    ▼
handle_text()
    │
    ├── session has lat/lng?
    │ Yes → tool_combo_search(query, lat, lng) ← Focus of this article
    │ No → fallback: Gemini Chat + Google Search
    │
    └──► Returns natural language answer

Tool Combo Agentic Loop

tool_combo_search(query, lat, lng)
         │
         ▼
  Step 1: generate_content()
  tools = [google_maps + search_nearby_restaurants]
         │
         ▼
  response.candidates[0].content.parts has function_call?
       ╱ ╲
      Yes   No
      │     │
      ▼     ▼
  _execute_function()  Directly returns response.text
  → _call_places_api()
    (Places API searchNearby)
    Returns rating, address, reviews
      │
      ▼
  Collect into a single Content(role="user")
  Add to history
      │
      ▼
  Step 3: generate_content(contents=history)
  Gemini integrates map context + Places data
      │
      ▼
  Returns final.text

Why not put lat/lng in Function Declaration?

This is an important design decision.

If you add lat/lng to the parameters of SEARCH_NEARBY_RESTAURANTS_FN, Gemini will fill in the coordinates itself—but it fills in the “approximate location” inferred from the conversation, not the user’s actual GPS coordinates, and the error can be as high as several kilometers.

The correct approach is to let the Python dispatcher extract the precise coordinates from session.metadata and inject them:

def _execute_function(name: str, args: dict, lat: float, lng: float):
    if name == "search_nearby_restaurants":
        return _call_places_api(
            lat=lat, lng=lng, # ← Inject from session, don't let Gemini guess
            keyword=args.get("keyword", ""),
            min_rating=float(args.get("min_rating", 4.0)),
        )

Core Code Details

Step 1: Define Function Declaration

from google.genai import types

SEARCH_NEARBY_RESTAURANTS_FN = types.FunctionDeclaration(
    name="search_nearby_restaurants",
    description=(
        "Search for nearby restaurants using Google Places API, and return the rating, address, and user reviews."
        "lat/lng is automatically included by the system and does not need to be provided."
    ),
    parameters=types.Schema(
        type=types.Type.OBJECT,
        properties={
            "keyword": types.Schema(
                type=types.Type.STRING,
                description="Restaurant type or keyword, such as: hot pot, hot pot, Italian",
            ),
            "min_rating": types.Schema(
                type=types.Type.NUMBER,
                description="Minimum rating threshold (1–5), default 4.0",
            ),
            "radius_m": types.Schema(
                type=types.Type.INTEGER,
                description="Search radius (meters), default 1000",
            ),
        },
    ),
)

The description clearly tells the model “lat/lng is included by the system”, avoiding the model filling in the coordinates itself in the args.

Step 2: Places API Call

import httpx

PLACES_API_URL = "https://places.googleapis.com/v1/places:searchNearby"
PLACES_FIELD_MASK = (
    "places.displayName,"
    "places.rating,"
    "places.userRatingCount,"
    "places.formattedAddress,"
    "places.reviews"
)

def _call_places_api(lat, lng, keyword="", min_rating=4.0, radius_m=1000):
    body = {
        "includedTypes": ["restaurant"],
        "maxResultCount": 5,
        "locationRestriction": {
            "circle": {
                "center": {"latitude": lat, "longitude": lng},
                "radiusMeters": radius_m,
            }
        },
    }

    response = httpx.post(
        PLACES_API_URL,
        headers={
            "X-Goog-Api-Key": os.getenv("GOOGLE_MAPS_API_KEY"),
            "X-Goog-FieldMask": PLACES_FIELD_MASK,
        },
        json=body,
        timeout=10.0,
    )
    response.raise_for_status()
    data = response.json()

    restaurants = []
    for place in data.get("places", []):
        rating = place.get("rating", 0)
        if rating < min_rating:
            continue
        reviews = [
            r["text"]["text"]
            for r in place.get("reviews", [])[:3]
            if r.get("text", {}).get("text")
        ]
        restaurants.append({
            "name": place["displayName"]["text"],
            "address": place.get("formattedAddress", ""),
            "rating": rating,
            "rating_count": place.get("userRatingCount", 0),
            "reviews": reviews,
        })

    return {"restaurants": restaurants}

Step 3: Tool Combo Main Function (Agentic Loop)

async def tool_combo_search(query: str, lat: float, lng: float) -> str:
    client = genai.Client(
        vertexai=True,
        project=os.getenv("GOOGLE_CLOUD_PROJECT"),
        location=os.getenv("GOOGLE_CLOUD_LOCATION", "us-central1"),
        http_options=types.HttpOptions(api_version="v1"),
    )

    enriched_query = (
        f"User's current location: latitude {lat}, longitude {lng}.n"
        f"Please answer in traditional Chinese using Taiwanese terminology, and do not use markdown format.nn"
        f"Question: {query}"
    )

    tool_config = types.GenerateContentConfig(
        tools=[
            types.Tool(
                google_maps=types.GoogleMaps(), # ← Maps grounding
                function_declarations=[SEARCH_NEARBY_RESTAURANTS_FN], # ← Places API
            )
        ],
    )

    # ── Step 1 ──────────────────────────────────────────────────────
    response = client.models.generate_content(
        model=TOOL_COMBO_MODEL,
        contents=enriched_query,
        config=tool_config,
    )

    if not response.candidates:
        return response.text or "(Unable to get a reply)"

    history = [
        types.Content(role="user", parts=[types.Part(text=enriched_query)]),
        response.candidates[0].content,
    ]

    # ── Step 2:Processing function_call ──────────────────────────────────
    function_response_parts = []
    for part in response.candidates[0].content.parts:
        if part.function_call:
            fn = part.function_call
            result = _execute_function(fn.name, dict(fn.args or {}), lat, lng)
            function_response_parts.append(
                types.Part(
                    function_response=types.FunctionResponse(
                        id=fn.id, name=fn.name, response=result,
                    )
                )
            )

    if function_response_parts:
        history.append(types.Content(role="user", parts=function_response_parts))

        # ── Step 3 ────────────────────────────────────────────────────
        final = client.models.generate_content(
            model=TOOL_COMBO_MODEL,
            contents=history,
            config=tool_config,
        )
        return final.text or "(Unable to get a reply)"

    return response.text or "(Unable to get a reply)"

Pitfalls Encountered

❌ Pitfall 1: Part.from_function_response() does not accept the id parameter

This is the easiest pitfall to step into this time, and the error only explodes when real model calls are made, and unit tests almost never detect it.

Originally, I wrote it like this, referring to the official example:

# ❌ Error——TypeError occurs at runtime
types.Part.from_function_response(
    id=fn.id, # ← This parameter does not exist!
    name=fn_name,
    response=result,
)

The actual signature of from_function_response is:

(*, name: str, response: dict, parts: Optional[list] = None) -> Part

There is no id parameter at all. Every time the model actually triggers a function_call, the program will throw a TypeError at this line, and then silently enter the except of Step 3, returning an error message, and the results of the Places API are never truly returned to Gemini.

The correct way is to directly construct types.FunctionResponse:

# ✅ Correct
types.Part(
    function_response=types.FunctionResponse(
        id=fn.id,
        name=fn_name,
        response=result,
    )
)

You can immediately confirm the parameter list with python -c "from google.genai import types; help(types.Part.from_function_response)".

❌ Pitfall 2: include_server_side_tool_invocations=True causes Pydantic to explode

I thought I should add this parameter after seeing the official documentation example:

# ❌ Error
types.GenerateContentConfig(
    tools=[...],
    include_server_side_tool_invocations=True, # ← The installed SDK version does not support it
)

In google-genai 1.49.0, this field is not in the model fields of GenerateContentConfig, and Pydantic will directly throw an extra_forbidden validation error. Just remove it, and the function is completely normal.

❌ Pitfall 3: textQuery is a parameter of searchText, not searchNearby

I thought “if there is a keyword, then bring it into the Places API”, and intuitively added it to the request body:

# ❌ Error——Invalid field for searchNearby endpoint
if keyword:
    body["textQuery"] = keyword

searchNearby only accepts fields such as includedTypes, locationRestriction; textQuery is a parameter of the searchText endpoint. Adding this field will not report an error (in some versions), but the keyword will not take effect at all.

The correct approach is to leave the keyword in the description of the Function Declaration for Gemini to refer to, let the model translate the intent to enriched_query, let Maps Grounding handle the keyword semantics, and Places API is only responsible for returning real rating data.

❌ Pitfall 4: No guard for response.candidates[0]

When the model encounters security filtering, RECITATION, or other abnormal termination, candidates may be an empty list, and then directly response.candidates[0] is IndexError.

# ❌ No guard
history = [
    types.Content(role="user", parts=[types.Part(text=enriched_query)]),
    response.candidates[0].content, # ← If candidates is empty, it will explode
]

# ✅ Add guard
if not response.candidates:
    return response.text or "(Unable to get a reply)"

history = [...]

Demo Display

image-20260327163200329

Scenario 1: “Find a hot pot restaurant with a rating of 4 stars or above for group dining”

User sends: GPS location (Xinyi District, Taipei City, 25.0441, 121.5598)

User enters: "Please find a hot pot restaurant with a rating of 4 stars or above, suitable for group dining, and list the name, address, and review summary."

[Step 1: Gemini receives query + map context]
  → Detects the need for restaurant data, emit function_call:
    search_nearby_restaurants(keyword="hot pot", min_rating=4.0)

[Step 2: Python calls Places API]
  → lat=25.0441, lng=121.5598 injected from session
  → Returns 3 restaurants with a rating ≥ 4.0, including review text

[Step 3: Gemini integrates Maps context + Places data]
  → "Lao Wang Hot Pot|100 Shimin Avenue, Xinyi District|⭐ 4.6 (312)
      Review summary: Large portions, great value for money, a top choice for friends to dine; fast service, fresh dishes.
     ... (3 restaurants in total)"

Scenario 2: “Are there any high-value Japanese restaurants?”

User enters: "Are there any high-value Japanese restaurants nearby?"

[Step 1: Gemini]
  → function_call: search_nearby_restaurants(keyword="Japanese cuisine", min_rating=4.0)

[Step 2: Places API]
  → Returns 2 Japanese restaurants that meet the rating criteria

[Step 3: Gemini]
  → "There are two recommendations:
      Washoku ○○|...|⭐ 4.4|Reviews: Weekday lunch set is only 280 yuan, very fresh.
      ..."

Demo Script Quick Test

No need for LINE Bot, directly on the local machine:

# Only test Tool Combo (main function)
python demo.py combo

# Run all three functions
python demo.py all

Old Architecture vs. New Architecture

Old Architecture (Maps Grounding only) New Architecture (Tool Combo)
Tool google_maps (built-in) google_maps + search_nearby_restaurants (custom)
Rating Data Gemini describes it itself (may not be accurate) Places API real numbers
Reviews AI generated Real user reviews (up to 3)
API Call Count 1 time 1 time (Step1) + 1 time (Step3) = 2 times, but transparent to the user
Accuracy Medium High
Custom Filtering Rely on prompt min_rating, radius_m precise control

Analysis and Outlook

This implementation has given me a clearer understanding of the potential of Gemini Tool Combinations.

The problem that Tool Combinations truly solves is that Grounding and Function Calling are no longer mutually exclusive. Previously, to achieve “map context + real external data”, you could only manually connect two APIs yourself at the application layer, or use Gemini’s text generation to “simulate” external data (unreliable). Now the model itself knows when to use map context and when to call the Places API, and developers only need to attach the tools.

However, there are also a few things to note about this implementation:

  1. lat/lng injection mode is very important: You can’t let the model guess the coordinates itself, you must inject them from the session, otherwise the positioning accuracy will be very poor. This mode also applies to all function calling scenarios that “have session status”.

  2. The cost of two generate_content calls: The agentic loop of Tool Combo requires two model calls, and the token consumption is about 1.5–2 times that of a single call. This needs to be especially considered for scenarios with high latency requirements.

  3. SDK version differences: Different versions of google-genai have different support for the fields of GenerateContentConfig, and new fields like include_server_side_tool_invocations should be used after confirming the version number, otherwise Pydantic validation errors are hard to track.

Future directions that can be extended:

  • Connect the Postback quick replies (click the “Find Restaurant” button) to Tool Combo, so that each entry can get real ratings
  • Add the searchText endpoint to support more complex keyword searches (e.g. Michelin recommendations)
  • Tool Combo combined with other built-in tools (such as google_search) to achieve more complex multi-tool chaining

Summary

The core concept of this modification is only one sentence: Put Google Maps grounding and the Places API function tool in the same types.Tool, and Gemini will coordinate the two in a single conversation.

The key code is only these few lines:

# This is all the magic of Tool Combo
types.Tool(
    google_maps=types.GoogleMaps(), # ← Maps context
    function_declarations=[SEARCH_NEARBY_RESTAURANTS_FN], # ← Places API
)

But to make it really work, you also need to pay attention to: the construction method of FunctionResponse, the guard of candidates, the correct fields of the Places API endpoint, and the injection of lat/lng from the session instead of letting the model guess.

The complete code is on GitHub, feel free to clone and play with it.

See you next time!

Gemini 3.1: Real-World Voice Recognition with Flash Live: Making Your LINE Bot Understand You

image-20260328203306501

image-20260328203306501

Background

Google released Gemini 3.1 Flash Live at the end of March 2026 March, focusing on “making audio AI more natural and reliable.” This model is specifically designed for real-time two-way voice conversations, with low latency, interruptibility, and multi-language support.

I happened to have a LINE Bot project (linebot-helper-python) on hand, which already handles text, images, URLs, PDFs, and YouTube, but completely ignores voice messages:

User sends a voice message
Bot: (Silence)

This time, I’ll add voice support and share a few pitfalls I encountered.

Design Decision: Flash Live or Standard Gemini API?

The first question: Gemini 3.1 Flash Live is designed for real-time streaming, but LINE’s voice messages are pre-recorded m4a files, not real-time audio streams.

Using Flash Live to process pre-recorded files is like using a live streaming camera to take photos – technically feasible, but the wrong tool.

Decided to use the standard Gemini API – directly passing the audio bytes as inline data, and getting the transcribed text in one call. It’s simpler and more suitable for this scenario.

image-20260328203340798

Architecture Design

Integration Approach

This repo already has a complete Orchestrator architecture, which automatically routes to different Agents (Chat, Content, Location, Vision, GitHub) based on the message content. The goal for voice messages is clear:

Convert voice to text, and then treat it as a regular text message and pass it into the Orchestrator – allowing all existing features to automatically support voice input.

User says “Help me search for nearby gas stations” → transcribed into text → Orchestrator determines it’s a location query → LocationAgent processes it. No need to implement separate logic for voice.

Complete Flow

User sends AudioMessage (m4a)
    │
    ▼ handle_audio_message()
    │
    ├─ ① LINE SDK downloads audio bytes
    │ get_message_content(message_id) → iter_content()
    │
    ├─ ② Gemini transcription
    │ tools/audio_tool.py → transcribe_audio()
    │ model: gemini-3.1-flash-lite-preview
    │
    ├─ ③ Reply #1: "You said: {transcription}"
    │ reply_message() (consumes reply token)
    │
    └─ ④ Reply #2: Orchestrator routing
            handle_text_message_via_orchestrator(push_user_id=user_id)
            ↓
            push_message() (reply token already used, use push instead)

Why two replies?

The replies are divided into two parts to let the user see the transcription result immediately, without waiting for the Orchestrator to finish processing to know if the Bot understood what they said.

Core Code Explanation

Step 1: Audio Transcription Tool (tools/audio_tool.py)

from google import genai
from google.genai import types

TRANSCRIPTION_MODEL = "gemini-3.1-flash-lite-preview"

async def transcribe_audio(audio_bytes: bytes, mime_type: str = "audio/mp4") -> str:
    """
    Transcribe audio bytes to text using Gemini.
    LINE voice messages are always m4a, MIME type is always audio/mp4.
    """
    client = genai.Client(
        vertexai=True,
        project=os.getenv("GOOGLE_CLOUD_PROJECT"),
        location=os.getenv("GOOGLE_CLOUD_LOCATION", "us-central1"),
    )

    audio_part = types.Part.from_bytes(data=audio_bytes, mime_type=mime_type)

    response = await client.aio.models.generate_content(
        model=TRANSCRIPTION_MODEL,
        contents=[
            types.Content(
                role="user",
                parts=[
                    audio_part,
                    types.Part(text="Please transcribe the above audio content into text completely, preserving the original language, and do not add any explanations or prefixes."),
                ],
            )
        ],
    )

    return response.text or ""

Design principle: The function itself does not catch exceptions, allowing the upper-level handler to handle error responses uniformly.

Step 2: Handler Main Flow (main.py)

async def handle_audio_message(event: MessageEvent):
    """Handle audio (voice) messages — transcribe and route through Orchestrator."""
    user_id = event.source.user_id
    replied = False # Track if the reply token has been used
    try:
        # Download audio
        message_content = await line_bot_api.get_message_content(event.message.id)
        audio_bytes = b""
        async for chunk in message_content.iter_content():
            audio_bytes += chunk

        # Transcription
        transcription = await transcribe_audio(audio_bytes)

        # Empty transcription (silent or too short)
        if not transcription.strip():
            await line_bot_api.reply_message(
                event.reply_token,
                [TextSendMessage(text="Unable to recognize voice content, please re-record.")]
            )
            return

        # Reply #1: Let the user confirm the transcription result (consumes reply token)
        await line_bot_api.reply_message(
            event.reply_token,
            [TextSendMessage(text=f"You said: {transcription.strip()}")]
        )
        replied = True

        # Reply #2: Send to Orchestrator, using push_message (token already used)
        await handle_text_message_via_orchestrator(
            event, user_id,
            text=transcription.strip(),
            push_user_id=user_id,
        )

    except Exception as e:
        logger.error(f"Error handling audio for {user_id}: {e}", exc_info=True)
        error_text = LineService.format_error_message(e, "processing voice message")
        error_msg = TextSendMessage(text=error_text)
        if replied:
            # reply token has been consumed, use push instead
            await line_bot_api.push_message(user_id, [error_msg])
        else:
            await line_bot_api.reply_message(event.reply_token, [error_msg])

Step 3: Enabling Orchestrator to Support External Text Input

The original handle_text_message_via_orchestrator directly reads event.message.text. AudioMessage doesn’t have .text, so add two optional parameters:

async def handle_text_message_via_orchestrator(
    event: MessageEvent,
    user_id: str,
    text: str = None, # ← External text input (voice transcription)
    push_user_id: str = None, # ← Use push_message when set
):
    msg = text if text is not None else event.message.text.strip()
    try:
        result = await orchestrator.process_text(user_id=user_id, message=msg)
        response_text = format_orchestrator_response(result)
        reply_msg = TextSendMessage(text=response_text)

        if push_user_id:
            await line_bot_api.push_message(push_user_id, [reply_msg])
        else:
            await line_bot_api.reply_message(event.reply_token, [reply_msg])
    except Exception as e:
        error_msg = TextSendMessage(text=LineService.format_error_message(e, "processing your question"))
        if push_user_id:
            await line_bot_api.push_message(push_user_id, [error_msg])
        else:
            await line_bot_api.reply_message(event.reply_token, [error_msg])

text is not None (instead of text or ...) is intentional – in case the voice transcription results in an empty string, allow the empty string to pass through (and then be intercepted by the upper-level if not transcription.strip()), instead of falling back to event.message.text.

Pitfalls Encountered

❌ Pitfall 1: Part.from_text() does not accept positional arguments

The first TypeError encountered:

# ❌ Error (TypeError: Part.from_text() takes 1 positional argument but 2 were given)
types.Part.from_text(
    "Please transcribe the above audio content into text completely, preserving the original language, and do not add any explanations or prefixes."
)

# ✅ Correct
types.Part(text="Please transcribe the above audio content into text completely, preserving the original language, and do not add any explanations or prefixes.")

In this version of the SDK, text in Part.from_text() is a keyword argument, or use the Part(text=...) constructor directly for more safety.

❌ Pitfall 2: LINE reply token can only be used once

LINE’s reply token is one-time use. Once reply_message() is called, the token is invalidated.

This project’s voice flow will call twice:

  1. Reply #1 (display transcription text) → consumes token
  2. Reply #2 (Orchestrator result) → token is invalid, will receive LINE 400 error

The solution is to have the Orchestrator handler support push_message mode (via the push_user_id parameter), and Reply #2 changes to push_message.

Error handling should also be noted: if Orchestrator throws an exception after Reply #1 succeeds, the reply_message cannot be used in the except block, and it also needs to be changed to push_message. This is the purpose of the replied flag in the code.

❌ Pitfall 3: Gemini Flash Live is not suitable for pre-recorded files

Not a real “pitfall”, but worth clarifying:

Gemini 3.1 Flash Live is designed for real-time two-way streaming, which has the overhead of connection establishment and streaming protocols. LINE voice messages are complete pre-recorded m4a files, which can be processed once.

Using client.aio.models.generate_content() directly to pass inline audio bytes is simpler, and the delay is not bad. Leave Flash Live for scenarios that truly require real-time conversations.

Effect Demonstration

Scenario 1: Voice Command Query

User sends: [Voice] Help me search for cafes near Taipei Main Station

Bot Reply #1: You said: Help me search for cafes near Taipei Main Station
Bot Reply #2: [LocationAgent replies with a list of nearby cafes]

Scenario 2: Voice Question

User sends: [Voice] What's the difference between Gemini and GPT-4

Bot Reply #1: You said: What's the difference between Gemini and GPT-4
Bot Reply #2: [ChatAgent with Google Search Grounding replies with comparison results]

Scenario 3: Voice Send URL

User sends: [Voice] Help me summarize this article https://example.com/article

Bot Reply #1: You said: Help me summarize this article https://example.com/article
Bot Reply #2: [ContentAgent fetches and summarizes the article]

The text transcribed from voice goes directly into the Orchestrator, and all existing URL detection and intent determination work as usual, with zero extra logic.

Traditional Text Input vs. Voice Input

Text Input Voice Input
Input Format TextMessage AudioMessage (m4a)
Pre-processing None Gemini transcription
reply token Direct use Reply #1 consumes, Reply #2 changes to push
Orchestrator Direct routing Route after transcription
Supported Functions All All (no additional settings required)
Error Handling reply_message replied flag determines reply/push

Analysis and Outlook

What I am most satisfied with in this integration is that I hardly need to change the Orchestrator itself. As long as the voice is converted to text at the input end, all the routing logic, Agent calls, and error handling are automatically inherited.

Gemini’s multimodal audio understanding performs very stably in this scenario – Traditional Chinese, Taiwanese accents, and sentences mixed with English can basically be transcribed accurately.

Future directions for extension:

  • Multi-language automatic detection: Tell Gemini to preserve the original language during transcription, Japanese voice → Japanese transcription, and then the Orchestrator decides whether to translate
  • Group voice support: Currently limited to 1:1, voice messages in groups are temporarily ignored
  • Long recording summary: Recordings exceeding a certain length go directly to ContentAgent for summarization, instead of being treated as commands

Extension: 🔊 Read Summary Aloud – Make the Bot Speak

Preview Program 2026-03-28 20.33.53

Voice recognition allows the Bot to “understand” what the user is saying. After this is done, the next question naturally arises:

Can the Bot respond by speaking?

The Gemini Live API has a setting response_modalities: ["AUDIO"], which can directly output an audio PCM stream. I connected it to another scenario – reading summaries aloud.

Function Design

Each time the Bot summarizes a URL, YouTube, or PDF, a “🔊 Read Aloud” QuickReply button will appear below the message. When the user presses it, the Bot sends the summary text into Gemini Live TTS, converts the PCM audio to m4a, and then sends it back using AudioSendMessage.

URL summary complete
    │
    ▼ [🔊 Read Aloud] QuickReply button
    │
User presses the button → PostbackEvent
    │
    ▼ handle_read_aloud_postback()
    │
    ├─ ① Retrieve the summary text from summary_store (10 minutes TTL)
    │
    ├─ ② Gemini Live API → PCM audio
    │ model: gemini-live-2.5-flash-native-audio
    │ response_modalities: ["AUDIO"]
    │
    ├─ ③ ffmpeg transcoding: PCM → m4a
    │ s16le, 16kHz, mono → AAC
    │
    └─ ④ AudioSendMessage sent to the user
            original_content_url: /audio/{uuid}
            duration: {ms}

Core Code (tools/tts_tool.py)

LIVE_MODEL = "gemini-live-2.5-flash-native-audio"

async def text_to_speech(text: str) -> tuple[bytes, int]:
    client = genai.Client(vertexai=True, project=VERTEX_PROJECT, location="us-central1")
    config = {"response_modalities": ["AUDIO"]}

    async with client.aio.live.connect(model=LIVE_MODEL, config=config) as session:
        await session.send_client_content(
            turns=types.Content(role="user", parts=[types.Part(text=text)]),
            turn_complete=True,
        )
        pcm_chunks = []
        async for message in session.receive():
            if message.server_content and message.server_content.model_turn:
                for part in message.server_content.model_turn.parts:
                    if part.inline_data and part.inline_data.data:
                        pcm_chunks.append(part.inline_data.data)
            if message.server_content and message.server_content.turn_complete:
                break

    pcm_bytes = b"".join(pcm_chunks)
    duration_ms = int(len(pcm_bytes) / 32000 * 1000) # 16kHz × 16-bit mono

    # PCM → m4a (temp file mode, avoid moov atom problem)
    with tempfile.NamedTemporaryFile(suffix=".pcm", delete=False) as f:
        f.write(pcm_bytes)
        pcm_path = f.name
    m4a_path = pcm_path.replace(".pcm", ".m4a")
    subprocess.run(
        ["ffmpeg", "-y", "-f", "s16le", "-ar", "16000", "-ac", "1",
         "-i", pcm_path, "-c:a", "aac", m4a_path],
        check=True, capture_output=True,
    )
    with open(m4a_path, "rb") as f:
        return f.read(), duration_ms

Pitfalls of Read Aloud Function

❌ Pitfall 4: Completely Different Model Name

The first attempt at Gemini Live TTS was:

LIVE_MODEL = "gemini-3.1-flash-live-preview"

Following the inference of gemini-3.1-flash-lite-preview used for voice recognition, the result was a direct 1008 policy violation:

Publisher Model `projects/line-vertex/locations/global/publishers/google/
models/gemini-3.1-flash-live-preview` was not found

Listing the available models on Vertex AI revealed that the model naming rules for Live/native audio are completely different:

# ✅ Correct
LIVE_MODEL = "gemini-live-2.5-flash-native-audio"

There is no Live version of Gemini 3.1 on Vertex AI. The Live/native audio feature is currently the 2.5 generation, and the naming format is gemini-live-{version}-{variant}-native-audio, which is completely separate from the general model gemini-{version}-flash-{variant}.

❌ Pitfall 5: GOOGLE_CLOUD_LOCATION=global Causes Live API to Disconnect

After changing to the correct model name, the error message was still the same:

Publisher Model `projects/line-vertex/locations/global/...` was not found

This time the model name was correct, but locations/global was strange – we clearly set us-central1.

Investigating the source code of the Google GenAI SDK revealed:

# _api_client.py
self.location = location or env_location
if not self.location and not self.api_key:
    self.location = 'global' # ← here

location or env_location – if the passed-in location is an empty string, it will fall back to global.

The root cause of the problem is the environment variable of Cloud Run:

{ "name": "GOOGLE_CLOUD_LOCATION", "value": "global" }

GOOGLE_CLOUD_LOCATION was set to the "global" string. os.getenv("GOOGLE_CLOUD_LOCATION", "us-central1") did not get "us-central1", but "global" – then the SDK obediently connected to the global endpoint, but gemini-live-2.5-flash-native-audio does not have BidiGenerateContent support in global.

Endpoint Standard API Live API
global ✅ Available ❌ Model not here
us-central1 ✅ Available ✅ gemini-live-2.5-flash-native-audio

Solution: Hardcode the location of the Live API, and don’t read from the env var:

# ❌ Affected by GOOGLE_CLOUD_LOCATION=global
VERTEX_LOCATION = os.getenv("GOOGLE_CLOUD_LOCATION", "us-central1")

# ✅ Hardcoded, not affected by env var
VERTEX_LOCATION = "us-central1" # Live API needs a regional endpoint

Voice Recognition vs. Read Summary Aloud

The two functions use completely different Gemini APIs:

Voice Recognition Read Summary Aloud
Direction Audio → Text Text → Audio
API Standard generate_content Live API BidiGenerateContent
Model gemini-3.1-flash-lite-preview gemini-live-2.5-flash-native-audio
Location Follows env var Hardcoded us-central1
Output Format text PCM → ffmpeg → m4a
LINE Message Type Input: AudioMessage Output: AudioSendMessage

Conclusion

The release of Gemini 3.1 Flash Live makes audio AI more worthy of serious consideration. This time, both voice recognition and read summary aloud were integrated into the LINE Bot:

  • Voice Recognition: Standard Gemini API, pre-recorded m4a one-time transcription, connected to the existing Orchestrator
  • Read Summary Aloud: Gemini Live TTS, summary text to PCM, ffmpeg to m4a, AudioSendMessage returns

The most troublesome part is not the function itself, but finding the correct model name and locating the SDK’s location logic – neither of these are clearly written in a prominent place in the documentation, and the answer can only be found by listing available models and reading the SDK source code.

The full code is on GitHub, feel free to refer to it.

See you next time!

Why Array Indexes Start at 0: Consistent Behavior Across Integer and String Arrays Explained

The Zero-Based Indexing Paradigm: A Technical and Historical Analysis

The convention of starting array indexing at 0 is a cornerstone of modern programming, deeply rooted in the interplay between memory management, language design, and mathematical principles. This article dissects the mechanisms behind this design choice, its historical origins, and its far-reaching implications for software development.

Mechanism 1: Historical and Low-Level Foundations

Impact: Array indexing starts at 0 across programming languages.

Causality: The origins of zero-based indexing trace back to the C programming language, where arrays are implemented as contiguous memory blocks. In this model, the index directly corresponds to an offset from the starting memory address. Starting at 0 simplifies pointer arithmetic and direct memory access, as it eliminates the need for an additional offset calculation.

Analytical Pressure: This low-level efficiency is critical in performance-sensitive applications, where memory access patterns directly impact execution speed. Misalignment between indexing and memory addressing could introduce overhead, undermining the very purpose of low-level languages like C.

Intermediate Conclusion: Zero-based indexing is not an arbitrary choice but a direct consequence of how arrays are represented in memory. Its adoption in C set a precedent that would influence generations of programming languages.

Observable Effect: Zero-based indexing is universally adopted in languages influenced by C (e.g., Java, Python, JavaScript), ensuring consistency with low-level memory operations and facilitating interoperability between languages.

Mechanism 2: Consistency in Language Design

Impact: All arrays, regardless of data type, follow the same indexing convention.

Causality: Language designers prioritize uniformity by applying zero-based indexing to all data types, from integers to Strings. This consistency avoids confusion and simplifies array operations, as the same indexing logic applies universally. Deviating from this convention would necessitate separate rules for different data types, complicating both language implementation and programmer cognition.

Analytical Pressure: Inconsistent indexing conventions would exacerbate cognitive load, increase the likelihood of errors, and hinder code portability. A unified approach ensures that developers can apply their knowledge of array indexing across diverse contexts without modification.

Intermediate Conclusion: The uniformity of zero-based indexing across data types is a deliberate design choice that prioritizes simplicity and predictability, reducing the potential for errors and enhancing code maintainability.

Observable Effect: String arrays and integer arrays exhibit identical indexing behavior, reinforcing consistency across data types and enabling developers to apply uniform patterns in their code.

Mechanism 3: Mathematical and Algorithmic Simplicity

Impact: Zero-based indexing aligns with mathematical sequences and loop constructs.

Causality: Starting at 0 naturally fits with mathematical sequences and loop constructs, such as the ubiquitous for(i = 0; i < n; i++) pattern. This alignment reduces cognitive load for programmers and minimizes errors in loop-based operations. Deviating from zero-based indexing would require adjustments in loop conditions, complicating algorithmic implementations.

Analytical Pressure: Misalignment between indexing conventions and mathematical sequences could lead to off-by-one errors, one of the most common and insidious bugs in programming. Such errors not only compromise code correctness but also erode trust in the software development process.

Intermediate Conclusion: Zero-based indexing serves as a bridge between mathematical theory and practical programming, enabling developers to translate algorithms into code with minimal friction.

Observable Effect: Codebases consistently use zero-based indexing in loops and mathematical calculations, enhancing readability and maintainability by adhering to well-established conventions.

System Instability Points

Despite its advantages, zero-based indexing introduces specific challenges that can destabilize systems if not properly managed:

  • Off-by-One Errors: Misunderstanding zero-based indexing leads to accessing out-of-bounds memory or skipping the first element, causing runtime errors or undefined behavior. These errors are notoriously difficult to debug, as they often manifest in ways unrelated to their root cause.
  • Assumption of Different Indexing for Strings: Assuming String arrays follow a different indexing convention results in logical errors, as all arrays adhere to zero-based indexing regardless of data type. This misconception can propagate through codebases, leading to systemic issues.
  • Inconsistent Conventions Across Languages: Languages or frameworks with non-zero-based indexing (e.g., 1-based indexing in MATLAB) introduce confusion and bugs when porting code between ecosystems. Developers must mentally switch between conventions, increasing the risk of errors.

Physical and Logical Processes

Process Description
Memory Addressing Arrays are stored as contiguous blocks in memory. The index acts as an offset from the starting address, with 0 representing the first element’s location. This direct mapping between index and memory offset underpins the efficiency of zero-based indexing.
Pointer Arithmetic In low-level languages like C, pointer arithmetic relies on zero-based indexing to calculate memory addresses efficiently. Deviating from this convention would necessitate additional calculations, compromising performance.
Language Design Uniformity All arrays, regardless of data type, follow zero-based indexing to maintain consistency and simplify language implementation. This uniformity reduces the cognitive load on both language designers and developers.
Mathematical Alignment Zero-based indexing aligns with mathematical sequences and loop constructs, reducing complexity in algorithmic implementations. This alignment facilitates the translation of theoretical algorithms into practical code.

Conclusion

Zero-based array indexing is a fundamental design choice that emerged from the intersection of memory management, language design, and mathematical principles. Its adoption across programming languages reflects a consensus on the importance of efficiency, consistency, and simplicity. However, this convention is not without its pitfalls, as misunderstandings can lead to critical errors. By understanding the historical and technical underpinnings of zero-based indexing, developers can navigate its complexities, write more robust code, and collaborate more effectively across diverse programming ecosystems.

Expert Analysis: The Technical and Historical Foundations of Zero-Based Array Indexing

The convention of starting array indexes at zero is a cornerstone of modern programming, deeply rooted in the interplay between memory management, language design, and mathematical principles. This analysis dissects the mechanisms driving this design choice, its implications for developers, and the consequences of misunderstanding its fundamentals.

Mechanisms Driving Zero-Based Indexing

Mechanism 1: Historical and Low-Level Foundations

Impact: Zero-based indexing originated in C, where arrays are implemented as contiguous memory blocks. This design choice was not arbitrary but a direct consequence of how memory is addressed in low-level languages.

Internal Process: An index represents an offset from the starting memory address of the array. Starting at 0 eliminates the need for additional offset calculations, streamlining memory access.

Observable Effect: This approach simplifies pointer arithmetic and direct memory access, which are critical for performance in low-level languages. It also reduces computational overhead, making it an efficient choice for systems programming.

Intermediate Conclusion: Zero-based indexing is a direct reflection of how memory is organized and accessed, making it an inherently efficient mechanism in languages like C.

Mechanism 2: Consistency in Language Design

Impact: Zero-based indexing is uniformly applied across all data types, from integers to Strings. This uniformity is a deliberate design choice to reduce complexity and cognitive load.

Internal Process: By maintaining consistent indexing behavior, language designers avoid creating exceptions that could lead to confusion or errors. This uniformity simplifies array operations and reduces the mental effort required to work with different data types.

Observable Effect: Identical indexing behavior across data types enhances predictability and maintainability. Developers can rely on the same indexing logic regardless of the data they are manipulating, reducing the likelihood of errors.

Intermediate Conclusion: Uniform zero-based indexing is a key factor in the readability and maintainability of code, fostering a more intuitive programming experience.

Mechanism 3: Mathematical and Algorithmic Simplicity

Impact: Zero-based indexing aligns seamlessly with mathematical sequences and loop constructs, which often start at 0. This alignment reduces the cognitive dissonance between mathematical theory and programming practice.

Internal Process: The natural fit with common loop patterns, such as for(i = 0; i < n; i++), minimizes the potential for errors. Developers can leverage familiar mathematical concepts directly in their code without translation layers.

Observable Effect: Consistent use of zero-based indexing in loops and calculations enhances code readability and maintainability. It also facilitates the implementation of algorithms that rely on sequential access patterns.

Intermediate Conclusion: Zero-based indexing bridges the gap between mathematical theory and programming practice, making it an essential convention for algorithmic efficiency and clarity.

System Instability Points and Their Consequences

Despite its advantages, zero-based indexing introduces specific instability points that can lead to critical errors if not properly understood:

  • Off-by-One Errors: Misinterpreting the starting index can result in out-of-bounds memory access or skipped elements, causing runtime errors. These errors are notoriously difficult to debug due to their subtle nature.
  • Assumption of Different Indexing for Strings: Assuming that Strings or other data types follow a different indexing convention can lead to logical errors. This misconception often arises from exposure to languages like MATLAB, which use 1-based indexing.
  • Inconsistent Conventions Across Languages: Porting code between ecosystems with different indexing conventions (e.g., MATLAB’s 1-based indexing) increases the risk of errors. Developers must be acutely aware of these differences to avoid introducing bugs.

Analytical Pressure: Misunderstanding zero-based indexing conventions can lead to inefficient code, runtime errors, and difficulties in collaborating with other developers. These issues underscore the importance of a deep understanding of this fundamental concept.

Physical and Logical Processes Reinforcing Zero-Based Indexing

The persistence of zero-based indexing is reinforced by several key processes:

  • Memory Addressing: The direct relationship between index and memory offset ensures that zero-based indexing remains the most efficient method for accessing array elements in low-level languages.
  • Pointer Arithmetic: Zero-based indexing enables straightforward memory address calculations, which are essential for optimizing performance in systems programming.
  • Language Design Uniformity: Consistent indexing across data types simplifies language implementation and reduces cognitive load for developers, making it a preferred design choice.
  • Mathematical Alignment: The alignment with mathematical sequences and algorithms ensures that zero-based indexing remains a natural and intuitive convention for developers.

Constraints Solidifying Zero-Based Indexing

Several constraints make zero-based indexing a hard requirement in modern programming:

  • Memory Contiguity: Arrays are implemented as contiguous memory blocks, necessitating direct memory addressing that inherently starts from 0. Deviating from this convention would introduce inefficiencies.
  • Compatibility: Changing the starting index would break compatibility with existing code, libraries, and system-level programming practices. This constraint ensures the longevity of zero-based indexing.
  • Educational Standards: Educational and community standards have solidified the zero-based indexing convention, making it a foundational concept in programming education. Deviating from this standard would create confusion and inefficiency.

Conclusion: The Enduring Significance of Zero-Based Indexing

Zero-based array indexing is a fundamental design choice rooted in memory addressing, efficiency, and mathematical alignment. Its consistency across data types, including Strings, ensures predictability and maintainability in code. However, the instability points associated with this convention highlight the need for a deep understanding to avoid critical errors. As programming languages continue to evolve, zero-based indexing remains a cornerstone of efficient and reliable software development, underscoring its enduring significance in the field.

Expert Analysis: The Technical and Historical Foundations of Zero-Based Array Indexing

Zero-based array indexing, a cornerstone of modern programming, is a design choice deeply rooted in memory addressing efficiency, language uniformity, and mathematical alignment. This convention, originating in the C programming language, has become a universal standard due to its inherent advantages and the constraints that reinforce its adoption. Misunderstanding this convention can lead to critical errors, inefficient code, and collaboration challenges, underscoring its significance in software development.

Mechanisms Driving Zero-Based Indexing

1. Memory Addressing Efficiency

Causality: Zero-based indexing emerged from the need to optimize memory access in C, where arrays are stored as contiguous memory blocks. The index directly represents the offset from the starting memory address, eliminating the need for additional calculations.

Analytical Pressure: This mechanism is critical because it minimizes CPU cycles spent on pointer arithmetic, directly impacting performance in low-level and system programming. Without this efficiency, memory-intensive operations would incur significant overhead.

Intermediate Conclusion: Zero-based indexing is a direct consequence of hardware memory mapping, ensuring that software and hardware operate in harmony for optimal access patterns.

2. Language Design Uniformity

Causality: Consistent indexing across data types (e.g., integers, Strings) reduces cognitive load and simplifies array operations. This uniformity is a deliberate design choice to enhance predictability and maintainability.

Analytical Pressure: Inconsistent indexing rules would fragment language design, increasing the likelihood of errors and complicating codebases. Uniformity ensures that developers can apply a single set of principles across diverse data structures.

Intermediate Conclusion: Zero-based indexing serves as a unifying convention, streamlining language implementation and developer experience.

3. Mathematical and Algorithmic Alignment

Causality: Zero-based indexing mirrors mathematical sequences and loop constructs (e.g., for(i = 0; i < n; i++)). This alignment reduces cognitive dissonance and enhances code readability.

Analytical Pressure: Deviating from this convention would introduce unnecessary complexity, increasing the risk of off-by-one errors—a common source of bugs in software development.

Intermediate Conclusion: Zero-based indexing is not arbitrary but a reflection of mathematical and algorithmic principles, ensuring consistency between theory and practice.

Constraints Reinforcing Zero-Based Indexing

1. Memory Contiguity

Causality: Arrays as contiguous memory blocks require sequential addressing starting from 0. Deviating from this introduces inefficiencies and misalignments with hardware memory mapping.

Analytical Pressure: Non-zero starting indexes would create gaps or overlaps in memory, violating the sequential nature of contiguous allocation and degrading performance.

Intermediate Conclusion: Zero-based indexing is a necessity for contiguous memory allocation, ensuring efficient and error-free access.

2. Compatibility

Causality: Changing the starting index would break existing code, libraries, and system-level practices, causing widespread incompatibility.

Analytical Pressure: The cost of transitioning from zero-based indexing would be prohibitive, requiring the rewriting of foundational codebases and disrupting ecosystems built over decades.

Intermediate Conclusion: Zero-based indexing is entrenched in the software stack, making it a non-negotiable standard for compatibility.

3. Educational Standards

Causality: Zero-based indexing is a foundational concept in programming education. Deviating from this convention would create confusion and inefficiency for learners and practitioners.

Analytical Pressure: Overhauling educational materials and methodologies would be a monumental task, with long-term consequences for the next generation of developers.

Intermediate Conclusion: Zero-based indexing is a pedagogical cornerstone, ensuring consistency between learning and practice.

System Instability Points

1. Off-by-One Errors

Causality: Misinterpreting the starting index leads to out-of-bounds access or skipped elements, causing runtime errors.

Analytical Pressure: These errors are not merely theoretical but have tangible consequences, including crashes, data corruption, and security vulnerabilities.

Intermediate Conclusion: Zero-based indexing mitigates off-by-one errors by aligning programmer intent with system expectations.

2. Indexing Assumptions

Causality: Assuming 1-based indexing (e.g., from MATLAB) causes logical errors in code, as it contradicts the zero-based convention.

Analytical Pressure: Cross-language confusion introduces systemic risks, particularly in projects involving multiple programming ecosystems.

Intermediate Conclusion: Zero-based indexing serves as a universal reference point, reducing the risk of errors stemming from conflicting assumptions.

3. Cross-Language Inconsistency

Causality: Porting code between ecosystems with different conventions increases error risk due to conflicting assumptions.

Analytical Pressure: The lack of a universal standard exacerbates the challenge of code portability, a critical issue in modern software development.

Intermediate Conclusion: Zero-based indexing, while not universal across all languages, remains the dominant convention, minimizing inconsistencies.

Final Thesis

Zero-based array indexing is not an arbitrary choice but a fundamental design decision rooted in memory addressing efficiency, language uniformity, and mathematical alignment. Its adoption is reinforced by constraints such as memory contiguity, compatibility, and educational standards. Misunderstanding this convention carries significant stakes, including off-by-one errors, inefficient code, and collaboration challenges. As such, zero-based indexing remains a cornerstone of programming, ensuring consistency, efficiency, and reliability across software ecosystems.

Notion MCP Challenge Entry: A2Aletheia

This is a submission for the Notion MCP Challenge

What I Built

https://aria.a2aletheia.com
A swarm of agents that can communicate with each other, each from a different company. (Well, for now it is not from a diff company, but DEMOOO)
It is crazy how a lone agent, can have access to other services from other agents via the network in just ~30s of registration.

Video Demo

A2A Extended Capability 1: Orchestration (Orchestrator to Network)

A2A Extended Capability 2: Peering (Orchestrator to Agents TO Agents

A2A Extended Capability 3: Context Preservation (Context between Orchestrator/Agents and (other) Agents

A2A Extended Capability 4: Demo Events + Notion MCP Agent, Calendar Task (it failed lol)

A2A Extended Capability: How to register an agent

Show us the code

https://github.com/weedeej/NotionA2A

How I Used Notion MCP

I created a new Agent for natural language processing, separate context window and for Notion MCP to be it’s own entity, managing your workspace within a network of agents with your authorization.

The Visual Power of AI Blueprints

Did you know AI-generated blueprints can visually map out your entire development process? Dive into the graphic representation of your project’s architecture with Lenify and see how visualizing your blueprint enhances understanding and efficiency. How would a visual map impact your development workflow? 🌐💻 #BlueprintRevolution #AIinDevelopment #TechInsights