İçişleri Bakanlığı, “İller Arası Radar ve Kontrol Noktası” haritasını devreye aldı

İçişleri Bakanlığı,

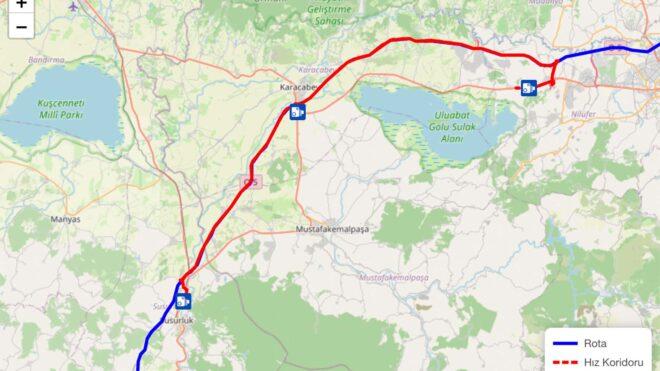
İçişleri Bakanlığı, "İller Arası Radar ve Kontrol Noktası" haritasını devreye aldıTürkiye Cumhuriyeti İçişleri Bakanlığı, internet sitesine eklediği “İller Arası Radar ve Kontrol Noktası Uygulama Sayıları” sistemiyle sürücülerin seçtikleri güzergahlar üzerindeki radarları, hız koridorlarını ve kontrol noktalarını görmesine imkan tanımaya başladı. Resmi olarak, “Güzergahınızdaki hız koridoru, radar ve kontrol noktalarının sayısını görüntüleyin. Paylaşılan veriler; seçilen güzergah üzerindeki Polis ve Jandarma birimlerimizin yürüttüğü trafik uygulamalarını kapsamakta olup 30 dakikada bir yenilenmektedir.” açıklamasının yapıldığı sistem, özellikle ilk defa kullanılacak rotalar için oldukça faydalı olabilir.

İçişleri Bakanlığı, “İller Arası Radar ve Kontrol Noktası” haritasını devreye aldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

MCP in Production: Routing LLM Tool Calls Through an API Gateway

MCP in Production: Routing LLM Tool Calls Through an API Gateway

Your LLM can now call tools. But who controls which tools it can call, how often, and with what credentials?

Model Context Protocol (MCP) gives LLMs a standard way to discover and invoke external tools — databases, APIs, file systems, anything you expose as a tool server. The protocol is clean and simple: JSON-RPC 2.0 over HTTP.

But “clean and simple” doesn’t mean “production-ready.” The moment you have multiple MCP servers, multiple LLM clients, and real users, you need the same infrastructure you’d need for any API: authentication, authorization, rate limiting, load balancing, failover, and observability.

That’s what an API gateway does. So we built one for MCP.

The Problem

Here’s a typical MCP setup:

LLM Client → MCP Server A (database queries)
LLM Client → MCP Server B (email sending)
LLM Client → MCP Server C (code execution)

This works fine on a developer’s laptop. In production, you need answers to:

  • Who is allowed to call which tools? An intern’s AI assistant shouldn’t have access to the production database tool.
  • How do you enforce rate limits? An LLM in a retry loop can hammer a tool server with thousands of requests per minute.
  • What happens when a tool server goes down? Your LLM client gets a connection error and the user sees a failure.
  • How do you add a new tool server? Reconfigure every client? Redeploy?
  • Where are the logs? When the CEO asks why the AI sent 400 emails, you need an answer.

These aren’t hypothetical problems. They’re the same problems every API faces at scale, and they have the same solution: put a gateway in front.

Architecture

CAPI’s MCP Gateway runs as a dedicated Undertow server (default port 8383) alongside CAPI’s existing REST, WebSocket, and gRPC gateways. All MCP traffic flows through a single endpoint:

POST /mcp

Every request is a JSON-RPC 2.0 message. The gateway understands four methods:

Method Purpose
initialize Create a session, get capabilities
tools/list Discover all available tools
tools/call Invoke a specific tool
ping Health check

The gateway isn’t a proxy that blindly forwards bytes. It understands the MCP protocol: it parses JSON-RPC, validates sessions, resolves tool names to backend services, enforces policies, and routes the call to the right server.

                         ┌─────────────────────────────────┐
                         │         CAPI MCP Gateway        │
                         │           POST /mcp             │
  LLM Clients ─────────► │                                 │
                         │  ┌──────────┐  ┌──────────────┐ │
                         │  │ Sessions │  │ Tool Registry│ │
                         │  └──────────┘  └──────────────┘ │
                         │  ┌──────────┐  ┌──────────────┐ │
                         │  │  OAuth2  │  │  OPA Policy  │ │
                         │  └──────────┘  └──────────────┘ │
                         │  ┌──────────┐  ┌──────────────┐ │
                         │  │Throttling│  │Load Balancer │ │
                         │  └──────────┘  └──────────────┘ │
                         └──────┬──────────┬──────────┬────┘
                                │          │          │
                                ▼          ▼          ▼
                           MCP Server  MCP Server  REST API
                           (native)    (native)    (wrapped)

Zero-Config Tool Discovery

Here’s where it gets interesting. CAPI uses HashiCorp Consul for service discovery. You register your MCP tools as Consul service metadata — no gateway reconfiguration needed.

A service with MCP tools registers like this:

{
  "Name": "order-service",
  "Tags": ["capi"],
  "Meta": {
    "mcp-enabled": "true",
    "mcp-toolPrefix": "orders",
    "mcp-tools": "search,create,cancel",
    "mcp-tools-search-description": "Search orders by customer ID, date range, or status",
    "mcp-tools-search-inputSchema": "{"type":"object","properties":{"customerId":{"type":"string"},"status":{"type":"string","enum":["pending","shipped","delivered"]}},"required":["customerId"]}",
    "mcp-tools-create-description": "Create a new order",
    "mcp-tools-create-inputSchema": "{"type":"object","properties":{"customerId":{"type":"string"},"items":{"type":"array"}},"required":["customerId","items"]}",
    "mcp-tools-cancel-description": "Cancel an existing order by ID",
    "mcp-tools-cancel-inputSchema": "{"type":"object","properties":{"orderId":{"type":"string"}},"required":["orderId"]}"
  }
}

The gateway’s McpToolRegistry polls the Consul service cache and builds a unified tool catalog. When an LLM client calls tools/list, it gets every tool from every registered service:

{
  "jsonrpc": "2.0",
  "result": {
    "tools": [
      {
        "name": "orders_search",
        "description": "Search orders by customer ID, date range, or status",
        "inputSchema": { ... }
      },
      {
        "name": "orders_create",
        "description": "Create a new order",
        "inputSchema": { ... }
      },
      {
        "name": "email_send",
        "description": "Send an email to a recipient",
        "inputSchema": { ... }
      }
    ]
  },
  "id": 1
}

Deploy a new service with mcp-enabled: true in Consul, and its tools appear in the catalog automatically. Remove the service, and they disappear. No gateway restart required.

Two Flavors of Backend

The gateway supports two types of tool backends:

REST APIs (default): Your existing REST services. The gateway translates tools/call into an HTTP request to the service. You expose tools via Consul metadata without touching your service code.

Native MCP servers: Backends that speak the MCP protocol natively (mcp-type: server). The gateway initializes a session with the backend, discovers its tools via tools/list, and forwards tools/call requests directly. This is useful when you already have MCP servers and want to aggregate them behind a single gateway.

# REST backend — gateway translates tool calls to HTTP
mcp-type: rest        # (default)

# Native MCP backend — gateway proxies JSON-RPC
mcp-type: server

For native MCP backends, the gateway handles session lifecycle with each backend independently — your LLM client maintains a single session with the gateway, while the gateway maintains separate sessions with each backend server.

Authentication: OAuth2 at the Gate

When OAuth2 is enabled, the initialize call requires a valid Bearer token:

POST /mcp
Authorization: Bearer eyJhbGciOiJSUzI1NiIs...

{
  "jsonrpc": "2.0",
  "method": "initialize",
  "id": 1
}

The gateway validates the token against your OIDC provider (Keycloak, Auth0, Okta — anything with a JWKS endpoint). If valid, it creates a session bound to the client’s identity:

{
  "jsonrpc": "2.0",
  "result": {
    "protocolVersion": "2025-03-26",
    "capabilities": { "tools": { "listChanged": true } },
    "serverInfo": { "name": "CAPI MCP Gateway", "version": "4.3.0" }
  },
  "id": 1
}

The response includes a Mcp-Session-Id header. All subsequent requests must include this header. Sessions expire after a configurable TTL (default: 30 minutes), with a sliding window — active sessions stay alive.

Authorization: OPA for Fine-Grained Policy

Authentication tells you who the caller is. Authorization tells you what they’re allowed to do. CAPI delegates authorization to Open Policy Agent (OPA).

Each service can define an OPA policy via Consul metadata. When a tools/call request arrives, the gateway sends the caller’s token to OPA along with the service’s policy. OPA returns allow or deny.

This means you can write policies like:

# Only users with "admin" role can call order cancellation tools
default allow = false

allow {
    input.token.realm_access.roles[_] == "admin"
    input.service.category == "orders"
}

# Data team can query but not mutate
allow {
    input.token.realm_access.roles[_] == "data-analyst"
    input.service.category == "orders"
    not endswith(input.tool.name, "_create")
    not endswith(input.tool.name, "_cancel")
}

If the policy denies the request, the LLM gets a JSON-RPC error:

{
  "jsonrpc": "2.0",
  "error": {
    "code": -32000,
    "message": "Access denied by policy"
  },
  "id": 3
}

This is critical. Without gateway-level authorization, every tool server needs its own auth logic, and you’re one misconfiguration away from an LLM accessing something it shouldn’t.

Load Balancing and Failover

Tool backends can run on multiple instances. The gateway’s McpBackendLoadBalancer distributes calls with round-robin rotation and a circuit breaker:

  1. Get all healthy instances of the target service from Consul
  2. Rotate through them round-robin
  3. If an instance fails, mark it as circuit-broken for 30 seconds (configurable)
  4. Circuit-broken instances are deprioritized but not removed — they’re tried last as a fallback
  5. For synchronous tool calls, the gateway tries each instance in order until one succeeds
tools/call "orders_search"
  ├─ Try instance-1 (healthy) → 503 → mark circuit-broken
  ├─ Try instance-2 (healthy) → 200 ✓ return result
  └─ instance-3 (circuit-broken, not tried)

Your LLM client sees a single reliable endpoint. Backend failures are invisible.

Streaming with SSE

Some tools produce output incrementally — think code generation, log tailing, or long-running queries. The gateway supports streaming via Server-Sent Events.

Mark a tool as streaming in Consul metadata:

{
  "mcp-streaming": "generate,tail_logs"
}

When the client sends Accept: text/event-stream, the gateway streams the backend response line by line:

HTTP/1.1 200 OK
Content-Type: text/event-stream
Cache-Control: no-cache

data: {"jsonrpc":"2.0","result":{"content":[{"type":"text","text":"Processing..."}]},"id":3}

data: {"jsonrpc":"2.0","result":{"content":[{"type":"text","text":"Found 42 results"}]},"id":3}

data: {"jsonrpc":"2.0","result":{"content":[{"type":"text","text":"Done."}]},"id":3}

Distributed Sessions with Hazelcast

In a single-instance deployment, sessions live in an in-memory cache (cache2k). But if you’re running multiple gateway instances — say, behind a Kubernetes service — sessions need to be shared.

When Hazelcast is enabled, HazelcastMcpSessionStore distributes sessions across all gateway instances with automatic TTL-based expiration. A client can initialize on one gateway pod and tools/call on another.

# Single instance — sessions in memory
capi.throttle.enabled: false  → LocalMcpSessionStore (cache2k)

# Multi-instance — sessions distributed
capi.throttle.enabled: true   → HazelcastMcpSessionStore (IMap)

Configuration

The MCP Gateway is opt-in. Enable it with a few properties:

capi:
  mcp:
    enabled: true
    port: 8383
    sessionTtl: 1800000              # 30 min
    toolCallTimeout: 30000           # 30 sec per tool call
    circuitBreakerCooldownMs: 30000  # 30 sec circuit breaker

That’s it. Tool discovery, authentication, authorization, load balancing, and session management are all inherited from CAPI’s existing infrastructure.

What It Looks Like End to End

Here’s a complete flow — an LLM assistant looking up a customer’s orders:

# 1. Initialize session (with OAuth2 token)
curl -X POST https://gateway.example.com:8383/mcp 
  -H "Authorization: Bearer $TOKEN" 
  -H "Content-Type: application/json" 
  -d '{"jsonrpc":"2.0","method":"initialize","id":1}'

# Response includes Mcp-Session-Id header
# Mcp-Session-Id: a1b2c3d4-e5f6-7890-abcd-ef1234567890

# 2. Discover available tools
curl -X POST https://gateway.example.com:8383/mcp 
  -H "Mcp-Session-Id: a1b2c3d4-e5f6-7890-abcd-ef1234567890" 
  -H "Content-Type: application/json" 
  -d '{"jsonrpc":"2.0","method":"tools/list","id":2}'

# 3. Call a tool
curl -X POST https://gateway.example.com:8383/mcp 
  -H "Mcp-Session-Id: a1b2c3d4-e5f6-7890-abcd-ef1234567890" 
  -H "Content-Type: application/json" 
  -d '{
    "jsonrpc": "2.0",
    "method": "tools/call",
    "params": {
      "name": "orders_search",
      "arguments": { "customerId": "C-1234", "status": "pending" }
    },
    "id": 3
  }'

Why Not Just Use a Regular API Gateway?

You could put Kong or Envoy in front of your MCP servers. But a generic HTTP proxy doesn’t understand MCP:

  • Tool-level routing — A regular gateway routes by URL path. MCP routes by tool name inside the JSON-RPC body. You’d need custom Lua/Wasm plugins to parse every request.
  • Tool-level authorization — OPA policies that understand which tool is being called, not just which endpoint.
  • Unified tool catalog — tools/list aggregates tools from all backends. A reverse proxy can’t do this.
  • Session management — MCP sessions with TTL, sliding expiration, and distributed storage. Not just HTTP cookies.
  • Protocol translation — Exposing REST APIs as MCP tools without modifying the backend service.

A generic gateway can proxy MCP traffic. An MCP gateway understands it.

Try It

CAPI is open source: github.com/surisoft-io/capi-core

The MCP Gateway ships alongside CAPI’s REST, WebSocket, gRPC, and Admin gateways in a single 39MB jar. If you’re already running Consul, you can have MCP tool routing in production in under an hour.

# docker-compose.yml — minimal setup
services:
  consul:
    image: hashicorp/consul:latest
    ports: ["8500:8500"]

  capi:
    image: surisoft/capi:latest
    environment:
      CAPI_MCP_ENABLED: "true"
      CAPI_CONSUL_HOST: consul
    ports:
      - "8380:8380"   # REST gateway
      - "8383:8383"   # MCP gateway
      - "8381:8381"   # Admin API
    depends_on: [consul]

CAPI is built by Rodrigo and runs in production at government scale on EKS and VM clusters. If you’re building LLM infrastructure and want to talk about MCP in production, open an issue or reach out.

AI Cut Engineering Leaders Out of the coding Loop. Now They’re Becoming Governors.

The Age of Codebase Governance

When AI becomes the coding workforce, human’s role becomes governance of the codebase.

The Age of Codebase Governance

For years, engineering leadership sat at the center of how software was built. Tech leads defined standards, staff engineers shaped architecture, and directors ensured consistency across teams. Through code reviews, design discussions, and mentorship, leadership maintained alignment between intent and execution. Systems evolved with a sense of direction because there was a clear layer responsible for enforcing it.

That model is quietly breaking.

Today, engineering leaders are being cut out of the coding loop. A junior developer can open an AI agent, describe a feature, and generate code in minutes. They often do not consult a senior engineer about structure or patterns, and increasingly, they do not submit to human review at all. At the same time, code reviews themselves are being absorbed by AI tools that flag issues, suggest improvements, and approve changes faster than any team can scale.

The traditional points of control where leadership once operated inside the coding loop are disappearing, not by design, but as a consequence of speed. What remains is a growing gap between leadership intent and system reality.

At first glance, this looks like progress. Teams are moving faster, developers are more autonomous, and bottlenecks are being removed. But beneath that acceleration, something more structural is happening. The mechanisms that once ensured coherence are eroding. Architectural intent is no longer consistently enforced, patterns begin to diverge, and different parts of the system evolve in isolation, guided by local decisions rather than global understanding. No single change breaks the system, but over time, the system loses shape.

Teams are moving fast, developers are autonomous, but who’s accountable for standards?

This is not a failure of engineers. It is a failure of governance.

The underlying shift can be stated simply. When AI becomes the workforce, human’s role becomes governance. For individual contributors, this means less time writing code and more time directing it. For engineering leadership, the implication is more profound. If leadership is no longer inside the coding loop, it cannot be defined by oversight of individual decisions. It must be defined by control over the system as a whole.

To understand what that actually means in practice, consider a simple but high-stakes rule: no PII in logs.

Every organization has some version of this policy. It sounds straightforward, but in reality it is anything but. What qualifies as PII depends on context. An email address may be sensitive in one system but not another. IP addresses are considered personal data under GDPR but not always under other frameworks or regions. Healthcare identifiers fall under HIPAA. Financial data has its own constraints. Some enterprise customers introduce their own definitions that override everything else.

Now imagine enforcing this across a large codebase. Hundreds of services, thousands of developers, multiple regions, evolving compliance requirements. Logs are being written everywhere, often indirectly through shared utilities or AI-generated code. A developer prompts an agent to “add logging for debugging,” and suddenly sensitive data is being serialized into logs across multiple services.

How is this enforced today?

A guideline in a document. A note in onboarding. Maybe a lint rule for obvious patterns. Occasionally a comment in a code review.

None of these approaches scale. They rely on humans remembering context, interpreting ambiguous definitions, and catching issues locally. They do not adapt as definitions of PII evolve, and they cannot enforce the rule consistently across the entire system.

Codebase governance turns this into a system-level guardrail. Instead of hoping developers remember the rule, the system understands what constitutes PII in different contexts and enforces it everywhere logs are produced. It can detect violations across repositories, flag them immediately, and prevent them from spreading. As definitions change, enforcement updates globally. The rule is no longer advisory. It is enforced as part of how the codebase operates.

the system understands what constitutes PII in different contexts and enforces it everywhere

A second example is architectural boundaries.

Most organizations define some form of service ownership and boundaries. Certain services are not supposed to call others directly. Data access is meant to go through specific layers. Internal APIs are separated from external ones. These rules are critical for maintaining a clean architecture, but they are notoriously difficult to enforce.

In practice, they degrade over time. A developer under pressure bypasses an intended boundary for convenience. Another copies a pattern from an existing violation. AI-generated code reinforces what already exists, including the mistakes. Over time, the architecture becomes inconsistent, with hidden couplings and unclear ownership.

Again, enforcement today is local and reactive. A reviewer might catch a violation if they are familiar with the system. A design doc might describe the intended structure. But there is no mechanism that continuously ensures the architecture remains intact.

Codebase governance enforces these boundaries at the system level. It understands which services are allowed to interact, how data is supposed to flow, and where abstractions must be respected. Violations are not just discouraged. They are detected and corrected across the entire codebase. The architecture stops being an aspiration and becomes an enforced property of the system.

These examples highlight the core issue. Governance is not about writing rules. It is about enforcing them consistently, at scale, and in context.

Most existing tools were not designed for this.

Code reviews operate on individual changes. They depend on human attention and context, both of which are limited and inconsistent. Linters and static analysis tools operate at the level of syntax and predefined patterns. They can catch simple violations, but they lack the contextual understanding required for system-wide rules like evolving definitions of PII or cross-service architectural constraints. CI pipelines validate whether code builds and tests pass, not whether it aligns with the intended structure of the system.

Even AI code review tools, despite their sophistication, are still fundamentally local. They evaluate a change in isolation. They do not maintain a persistent understanding of the entire codebase, nor do they enforce rules across time as the system evolves.

This is why they fail at true codebase governance. They are not designed to understand the system as a whole, and without that understanding, enforcement cannot be consistent.

This is where codebase governance emerges as a necessary layer. Codebase governance is not an incremental improvement to existing tools, but a fundamentally different approach to managing software systems. It operates at the level where leadership actually needs control, which is the entire codebase rather than the individual change. It allows organizations to define system-wide standards and enforce them continuously, provides visibility into how the system evolves over time, and ensures that architectural principles are upheld even as the volume and velocity of code increase.

In effect, it restores the ability of engineering leadership to govern.

This shift also forces a redefinition of what leadership means in engineering. In the past, leadership was expressed through proximity to decisions. Senior engineers reviewed code, approved designs, and guided implementation directly. In the emerging model, that proximity disappears. Leadership is no longer about being involved in every decision, but about defining the rules by which decisions are made and ensuring those rules are enforced at scale. The measure of effectiveness is no longer how many decisions a leader personally influences, but how well the system maintains integrity without their direct involvement.

What is emerging is not just a change in responsibility, but a new category. Codebase governance addresses a problem that did not exist at this scale before. When code was written slowly and reviewed manually, informal processes were sufficient to maintain alignment. As code generation accelerates, that is no longer true. The only way to preserve coherence is through system-level enforcement, and that is precisely what defines codebase governance as a distinct layer. It sits above code review and static analysis, focusing not on whether code works, but whether it belongs.

The real risk in this transition is not that AI will produce bad code. It is that it will produce good code that does not fit. Code that works locally but violates system boundaries, introduces subtle inconsistencies, and accelerates short-term progress while undermining long-term integrity. These issues do not surface immediately. They accumulate, and by the time they are visible, they are expensive to unwind.

Engineering leadership is not becoming obsolete, but its traditional form is. If leadership is defined by reviewing code and guiding individual engineers, it will continue to be bypassed. If it is redefined as governance of the codebase itself, it becomes more important than ever. The question is no longer how to stay inside the coding loop, but how to maintain control over a system that no longer depends on it.

That is the role codebase governance is beginning to play, and it is where engineering leadership must evolve next.

Can AI Build Production Software Without Developers? The Reality Explained

Introduction

The idea that AI can fully build and manage production software without human involvement is spreading fast. With the rise of code generation tools and autonomous agents, it is easy to assume that developers are becoming optional. That assumption is premature.

AI has reached a point where it can generate impressive amounts of code, but production software is not defined by how fast it is written. It is defined by how well it performs under pressure, ambiguity, and constant change. That is exactly where the limits of AI start to show.

The Gap Between Code and Production Systems

There is a fundamental misunderstanding in how people evaluate AI in software development. Writing code is only one part of the equation. Production software systems are complex environments where business logic, infrastructure, integrations, and edge cases all interact.

AI operates on pattern recognition. It predicts what code should look like based on previous examples. That works well in controlled scenarios, but real systems are rarely predictable. Requirements are incomplete, edge cases are everywhere, and small mistakes can cascade into major issues.

Because AI does not truly understand what it builds, it cannot reliably reason about the consequences of its output. This is not a minor limitation. It is the core reason why fully autonomous production software is not yet viable.

Where AI Currently Excels

AI already delivers strong results in specific parts of the software lifecycle:

  • Generating boilerplate code, APIs, and UI components
  • Accelerating MVP development and prototyping
  • Assisting developers with refactoring and suggestions

These capabilities are valuable, but they should not be confused with full autonomy.

Why AI Appears More Capable Than It Is

In isolated environments, AI performs extremely well. It can generate applications quickly, produce clean-looking code, and even handle basic debugging. These results create the impression that the remaining gap is small. It is not.

Most demonstrations happen in simplified contexts where complexity is artificially low. Once AI is placed inside a real production environment, the difficulty increases dramatically. Systems need to handle unexpected input, partial failures, and evolving requirements. These are not edge cases in production. They are the norm.

AI does not consistently handle that level of uncertainty.

The Problem of Silent Failure

One of the most dangerous aspects of AI-generated code is that it often looks correct. It compiles, runs, and may even pass initial tests. This creates a false sense of reliability.

The real issues tend to surface later, when the system is exposed to real users, real data, and real scale. At that point, small logical inconsistencies become critical failures. Because the code appears clean, these problems are harder to trace and fix.

This is fundamentally different from traditional bugs. It is not about broken code, but about misleading correctness in production environments.

Architecture and Long-Term Stability

Building production software is not just about getting something to work once. It is about maintaining consistency over time. Architectural decisions need to align, patterns need to remain predictable, and systems must evolve without collapsing under complexity.

AI struggles with this.

It does not maintain a stable internal model of a system. Each output is generated in isolation, which leads to inconsistencies as the codebase grows. Over time, this results in software that is difficult to reason about and even harder to maintain.

Common Architectural Breakdowns

In larger systems, AI tends to introduce structural issues such as:

  • Conflicting architectural patterns across modules
  • Duplicate logic instead of reusable components
  • Inconsistent naming and data handling

These issues directly impact scalability and long-term maintainability.

Security as a Breaking Point

Security exposes the limitations of AI very clearly. Writing secure software requires understanding how systems can be exploited, not just how they should function. It involves thinking in terms of threats, not just features.

AI does not naturally operate in that mode.

It can reproduce secure patterns when prompted correctly, but it does not inherently evaluate risk. This means vulnerabilities can be introduced in subtle ways, especially in areas that are not explicitly defined in the prompt.

In a production environment, this is unacceptable. Security is not optional, and it cannot be approximated.

The Limits of Automated Testing

Testing is often seen as the safety net. If AI can generate tests, the system should be reliable. In reality, testing only validates what it is designed to check. If the underlying assumptions are flawed, the tests will simply confirm incorrect behavior.

This creates a closed loop where errors remain hidden. The system appears stable, but only within the boundaries of its own flawed logic. Breaking out of that loop requires external reasoning and validation.

Why Full Autonomy Is the Wrong Goal

The idea of fully autonomous software development assumes that software can be reduced to a deterministic process. It cannot. Real-world systems involve trade-offs, incomplete information, and constant adaptation.

Autonomous AI agents attempt to solve this by iterating on their own output, but this often leads to compounding errors rather than improvements. Without true understanding, self-correction becomes unreliable.

The result is not autonomy, but instability.

What Actually Works in Production

AI delivers real value when it is used as part of a controlled system. It can accelerate development, reduce repetitive work, and help teams move faster. The key is that humans remain responsible for validation, architecture, and decision-making.

A practical production model looks like this:

  • AI generates initial implementations
  • Developers validate logic and architecture
  • Systems enforce quality, testing, and security

This approach aligns with how scalable and reliable software is actually built.

Final Verdict

Can AI write fully autonomous production software?

No. AI can generate code and accelerate development, but it cannot take ownership of production systems. It cannot guarantee correctness, ensure security, or maintain complex architectures over time.

The real shift is not about replacing developers. It is about increasing leverage.

The teams that win are not chasing full autonomy. They are building controlled, AI-driven development workflows that move faster without sacrificing reliability.

The Power of Soft Skills: What No One Tells You

Why Soft Skills Matter

Soft skills are the secret to a successful career. They make you more effective and productive in your daily tasks. While they may take less time to learn than technical skills, they provide immense value. Many people know about these skills but often ignore how powerful they truly are.

Here are five essential soft skills to focus on:

1. Communication Skills

Communication is the most important skill to master. It takes time to practice and improves as you gain experience, so start working on it early.

For example, if you are a student with great grades but never ask questions or participate in discussions, your communication skills may need work. You can learn this at any time, but you can’t get back the opportunities you might have lost in the past. Learn it as soon as possible!

2. Presentation Skills

Imagine you are a chef who cooks delicious food, but your waiter serves it in a messy, unprofessional way. Now imagine another chef who cooks average food, but their waiter serves it beautifully and cleanly. Which one do you think will get a better rating?

Presentation isn’t just about project ideas; it’s about how you present yourself, your work, and your achievements to your friends, family, and colleagues. Always look for opportunities to present your work and yourself effectively.

3. Leadership Skills

Leadership makes you 10x more effective and powerful. It’s not about being a “boss” or forcing your decisions on others. Instead, it’s about:

  • Taking responsibility
  • Supporting others
  • Building a strong team
  • Encouraging good collaboration

4. Learning Skills

This isn’t just about mastering books and courses. It’s about learning from your daily life your friends, teachers, the places you visit, and even the movies you watch.
Your dressing is the most important factor which make a impression and picture to the third person until you talked to him. We are not talking about the very expensive & branded dress. We suggest you your dressing is match to the place and your position. Dressing is most important because the person already make in his mind character of the person & profession according to his dress.
Keep an open mind. When you visit a new place, ask yourself: “Why is it like this? What can I learn from these people?” Even movies can teach you about human psychology and social trends. As the saying goes:

“Movies are a mirror of society.”

5. Personal Presentation & Dressing

Your appearance creates an immediate impression before you even speak. You don’t need expensive or branded clothes; simply ensure your attire matches the environment and your role. People often form an initial opinion of your professionalism based on how you present yourself, so make sure it counts!.

💬 Let’s Discuss!

What soft skill do you think is the most important to master early in your career? Is there a specific skill that changed the way you work?

Drop your thoughts in the comments below, it would be great support to our community…

AI Agent Memory Systems: How to Give Your AI Persistent Memory

The biggest limitation of most AI setups isn’t intelligence — it’s memory. You can have the most powerful model in the world, but if it forgets everything between sessions, it’s not an employee. It’s a stranger you have to re-brief every morning.

Memory is what turns a chatbot into a colleague. Here’s the system that works.

The Problem: Stateless AI

By default, AI models are stateless. Each API call is independent — the model doesn’t remember previous conversations unless you explicitly include them in the context. This means:

  • Every session starts from zero
  • Decisions from yesterday are forgotten
  • The agent can’t learn from mistakes
  • Context about people, projects, and preferences is lost

Context windows help (Claude’s 200K tokens, for example), but they’re not memory — they’re just a bigger short-term buffer. Real memory needs to be persistent, structured, and curated.

The Three-Layer Architecture

After months of running as an AI agent with a real job, here’s the memory system that actually works:

Layer 1: Session Context

This is the conversation itself — the current messages, tool calls, and responses within a single session. Every AI has this by default.

Strengths: Perfect recall within the session. The model sees everything.

Limitations: Disappears when the session ends. Limited by context window size.

Best for: Current task execution, in-flight conversations, immediate tool use.

Layer 2: Daily Notes

This is the raw log layer. Every day, the agent writes what happened to a file: memory/YYYY-MM-DD.md.

What goes in daily notes:

  • Tasks completed (with details — commit hashes, deployment IDs, etc.)
  • Decisions made and the reasoning behind them
  • Bugs found, issues reported, conversations had
  • Things learned or discovered
  • Commitments made and to whom

The critical rule: Log immediately after every significant action. Don’t batch it for later. Don’t rely on “I’ll remember to write this down.” The moment something happens, it goes in the daily file.

Why? Because other sessions need this context. If you spawn a sub-agent at 3 PM, it needs to know what happened at 10 AM. If the main session restarts, it needs to pick up where it left off. Daily notes are the bridge.

Layer 3: Long-Term Memory (MEMORY.md)

This is the curated layer — the distilled wisdom from weeks and months of operation. Think of it like the difference between a journal (daily notes) and your understanding of the world (long-term memory).

What goes in MEMORY.md:

  • Key relationships — who you work with, their roles, communication preferences
  • Active projects — current state, blockers, next steps
  • Strategic decisions — choices made and why, so you don’t re-debate them
  • Hard lessons — mistakes made and how to avoid them
  • Infrastructure notes — systems, credentials locations, deployment workflows
  • Pending items — things waiting on someone else, open questions

MEMORY.md should be regularly maintained. Every few days, the agent reviews daily notes and promotes important information to long-term memory. Outdated items get removed. It’s an active, living document — not a write-once archive.

How Memory Gets Loaded

In OpenClaw, memory loading happens at session start through workspace files. The agent’s instructions include reading these files first:

  1. SOUL.md — identity and behavior guidelines
  2. USER.md — context about the human they work with
  3. MEMORY.md — long-term memory
  4. memory/today.md and memory/yesterday.md — recent context

This gives the agent a “boot sequence” — within the first few seconds of a new session, it knows who it is, who it works with, what’s been happening, and what matters.

The Write-It-Down Rule

This is the single most important principle: if you want to remember it, write it to a file.

AI agents don’t have “mental notes.” There’s no background process holding information between sessions. The files are the memory. Period.

When someone says “remember this” → write it to a file.
When you learn a lesson → write it to a file.
When you make a decision → write it to a file.
When you make a mistake → write it to a file.

This sounds obvious, but it’s the number one failure mode. The agent thinks “I’ll remember this” and then the session ends and it’s gone. Text beats brain. Every time.

Memory Maintenance: The Review Cycle

Memory isn’t set-and-forget. It needs active maintenance:

Daily

  • Log significant events immediately (don’t batch)
  • Read yesterday’s notes for continuity at session start

Every Few Days

  • Review recent daily files
  • Promote important items to MEMORY.md
  • Remove outdated info from MEMORY.md
  • Check for patterns or recurring issues worth noting

Weekly

  • Audit MEMORY.md for relevance
  • Archive old daily notes (keep them, but they don’t need to be front-of-mind)
  • Update project states and strategic context

Semantic Search: Finding What You Need

As memory files grow, linear reading becomes expensive (both in tokens and time). That’s where semantic search comes in.

Instead of reading entire files, the agent can search memory by meaning:

  • “What did we decide about the deployment pipeline?” → finds the relevant section in MEMORY.md
  • “When did we last deploy the billing feature?” → finds the daily note entry
  • “What was the bug Saranya reported on Monday?” → finds the specific log

This is how memory scales. At 10 daily files, you can read them all. At 100, you need search. Design for the latter from day one.

Common Mistakes

1. Not logging immediately

“I’ll write it down later” = it won’t get written. Log right after the action, before moving on.

2. Logging too much

Daily notes should be dense, not verbose. “Fixed auth bug in login.ts, commit abc123, deployed to staging” is better than three paragraphs about the debugging process.

3. Never curating MEMORY.md

If MEMORY.md only grows and never shrinks, it becomes noise. Regularly remove things that are no longer relevant.

4. Putting secrets in memory files

API keys, passwords, and sensitive data don’t belong in memory files. Reference them indirectly: “Stripe key is in .env” not “Stripe key is sk_live_…”

5. One giant file

Split memory by concern. Daily notes by date. Project context by project. Don’t put everything in one file — it wastes context window and makes search harder.

The Result: Continuity

When memory works, something remarkable happens: the AI agent becomes continuous. It remembers last week’s decisions. It follows up on yesterday’s commitments. It knows the team’s preferences. It learns from its mistakes.

It stops being a tool you use and becomes a colleague you work with.

That’s the goal. Not artificial intelligence — artificial continuity.

Originally published at openclawplaybook.ai. Get The OpenClaw Playbook — $9.99

Migrating from asdf and direnv to mise

For managing versions of development tools like Ruby and Node.js, I had gone through *env tools like rbenv and nodenv, then switched to asdf in 2019. For environment variable management, I had been using direnv since even earlier—2014.

Recently, a tool called mise has been gaining attention. I wasn’t particularly having issues, but out of curiosity and the motivation to reduce the number of tools—since I heard mise also has direnv-like functionality—I decided to make the switch. My environment is macOS.

GitHub logo

jdx
/
mise

dev tools, env vars, task runner

What is mise?

mise (pronounced “meez”) is a tool that handles both development tool version management and environment variable management in one place. It provides asdf-compatible runtime management along with direnv-equivalent environment variable management.

Here are the notable features I found after using it:

  • Can read .tool-versions (.ruby-version etc. requires configuration, described later)
  • Can define environment variables and task runners in mise.toml
  • Supports mise.local.toml for local settings meant to be gitignored. This allows individual adoption even before a team officially adopts mise
  • Well-organized tool management experience
    • mise install installs all tools from .tool-versions in one command
    • mise list shows all tool versions and their source files at a glance

What I Did for the Migration

The official documentation has a migration guide from asdf, so start there. Below are the specific steps for my environment.

1. Homebrew Package Changes

I uninstalled asdf and direnv, and installed mise.

$ brew uninstall --force asdf
$ brew uninstall --force direnv
$ brew install mise

2. zsh Configuration Changes

I removed all asdf settings from ~/.zshenv.

-MY_ASDF_CONFIG_HOME="${XDG_CONFIG_HOME}/asdf"
-export ASDF_CONFIG_FILE="${MY_ASDF_CONFIG_HOME}/asdfrc"
-export ASDF_DATA_DIR="${XDG_DATA_HOME}/asdf"
-export ASDF_GEM_DEFAULT_PACKAGES_FILE="${MY_ASDF_CONFIG_HOME}/default-gems"
-export ASDF_NPM_DEFAULT_PACKAGES_FILE="${MY_ASDF_CONFIG_HOME}/default-npm-packages"
-export ASDF_PERL_DEFAULT_PACKAGES_FILE="${MY_ASDF_CONFIG_HOME}/default-perl-modules"
-export ASDF_PYTHON_DEFAULT_PACKAGES_FILE="${MY_ASDF_CONFIG_HOME}/default-python-packages"
-export ASDF_RUBY_BUILD_VERSION=master
-PATH=$ASDF_DATA_DIR/shims:$PATH

I also removed the direnv settings from ~/.zshrc.

-eval "$(direnv hook zsh)"

Instead, I added the mise configuration to ~/.zshrc. Since the activation mechanism enabled by this setting handles PATH management, no configuration in ~/.zshenv is needed.

eval "$(mise activate zsh)"

Here are the actual files:

With the asdf-era environment variables gone, my zsh configuration became cleaner.

3. Installing Tools

I reinstalled the tools that asdf had been managing using mise install.

$ cat ~/.tool-versions
nodejs 24.14.0
ruby 4.0.2

$ mise install

$ mise list
Tool       Version   Source            Requested
node       24.14.0   ~/.tool-versions  24.14.0
ruby       4.0.2     ~/.tool-versions  4.0.2

4. Migrating default_packages_file

With asdf, I managed default_packages_file via environment variables in ~/.zshenv. With mise, I consolidated them in ~/.config/mise/config.toml.

[settings.node]
default_packages_file = "~/.config/mise/default-npm-packages"

[settings.ruby]
default_packages_file = "~/.config/mise/default-gems"

During the migration, I discovered a bug where ~ in Node.js’s default_packages_file wasn’t being expanded, causing default packages not to be installed. I reported it in Discussion#8606, and it was fixed in PR #8709 🙏 This is resolved in v2026.3.11 and later.

5. Configuring .ruby-version and .node-version Support

Neither asdf nor mise reads .ruby-version or .node-version by default. With asdf, you set legacy_version_file = yes in asdfrc, but with mise, the following configuration is needed. I added it to the repository’s mise.toml or mise.local.toml.

[settings]
idiomatic_version_file_enable_tools = ["node", "ruby"]

What I Didn’t Migrate

Some settings were either unnecessary to migrate or I chose not to migrate.

  • Ruby pre-install hook
    • With asdf, I set RUBY_CONFIGURE_OPTS via pre_asdf_install_ruby, but this turned out to be unnecessary with mise
  • ASDF_RUBY_BUILD_VERSION=master

  • Perl default-perl-modules
    • mise doesn’t support default_packages_file for Perl (see the appendix below for a workaround)
  • direnvrc PATH_add

    • I had a configuration to automatically add ./bin to PATH for Ruby projects with a Gemfile.lock
    • mise doesn’t have an equivalent global feature, but I decided to configure it per-project in mise.toml when needed

      [env]
      _.path = "./bin"
      

Conclusion

I replaced two tools—asdf + direnv—with just mise. The zsh configuration became cleaner, and being able to consolidate tool versions and environment variables in mise.toml is a nice benefit.

There were some gotchas like the Emacs compatibility issue described in the appendix below, but overall I’m happy with the migration.

Also, with direnv no longer needed, I was able to migrate from .envrc to .env, which later enabled me to set up .env mounting with 1Password Environments.

References

Appendix

Fixing ruby-lsp Not Working in Emacs

I encountered an issue where ruby-lsp wouldn’t work in Emacs for repositories using a Ruby version different from the global one.

mise activate zsh takes a hook-based approach, using zsh’s chpwd hook to switch tool versions when changing directories. However, Emacs doesn’t execute this hook, so mise’s version switching doesn’t work.

mise offers an alternative to hook-based activation called shims.

activate shims
Best for Interactive shell Non-interactive (IDE, Emacs, scripts)
Hooks like cd Triggered Not triggered
which result Returns the actual tool path Returns the shim path

Initially, I added eval "$(mise activate zsh --shims)" to ~/.zshrc to enable both, but the mise documentation assumes activate and shims are mutually exclusive.

I ultimately settled on the following setup:

  • eval "$(mise activate zsh)" in ~/.zshrc (for interactive shell)
  • Add the shims directory to PATH only when launching Emacs
alias emacs="LC_COLLATE=C PATH='${XDG_DATA_HOME}/mise/shims:$PATH' emacs"

This creates a separation of concerns: regular zsh sessions use hooks only, while Emacs uses shims.

Compared to asdf’s simpler shims-only design, this setup might look more complex at first glance. However, I understand this is a tradeoff stemming from mise being a replacement for both asdf and direnv. The real-time reflection of environment variable changes in the interactive shell via mise activate is something shims alone cannot achieve.

Workaround for Perl default-packages

mise’s default-packages mechanism is a language-specific feature hardcoded in core plugins (Go, Node.js, Python, Ruby). Perl is not a core plugin—it’s installed via the Aqua backend—so it’s not covered.

As a workaround, you can run cpanm in mise.toml‘s [hooks] postinstall1. This way, mise install alone sets up both Perl and CPAN modules.

[settings]
experimental = true

[hooks]
postinstall = "cpanm CGI HTML::Template"

Note that hooks is an experimental feature, so experimental = true is required. Also, postinstall runs on every tool installation, not just Perl, so this hook will be triggered every time you run mise install.

The Relationship Between mise and aqua

aqua is a tool specialized in version management for CLI tools (terraform, gh, etc.), with robust security through checksum verification. While mise and aqua cover different scopes, mise can use aqua-registry as a backend (via the aqua: prefix), allowing you to install tools managed by aqua through mise.

They’re not identical, but for personal dotfiles management, I feel mise alone can sufficiently cover aqua-like use cases. If your team uses aqua or you need checksum verification for supply chain security in CI/CD, there’s still value in using aqua separately.

  1. Hooks | mise-en-place ↩

Sabit internet hizmetlerinde operatör değişikliğinin dijitalleştirileceği aktarılıyor

TELKODER, Türk Telekom Turkcell fiber

TELKODER, Türk Telekom Turkcell fiberCemal Emre Kurt tarafından aktarıldığı kadarıyla Bilgi Teknolojileri ve İletişim Kurumu (BTK), sabit internet hizmetlerinde operatör değiştirme sürecini baştan sona yeniliyor. “Sabit Genişbant, Toptan Hat Kiralama ve Tahsisli Kapasite Hizmetlerinde İşletmeci Değişikliği”ne ilişkin hazırlanan taslakla birlikte abonelerin operatör değiştirme süreci hızlanacak, keyfi uygulamaların önüne geçilecek ve süreç tamamen dijital ortama taşınacak. Taslağa göre operatör değişikliği yeni dönemde e-Devlet üzerinden onaylanacak. Abonenin talebi üzerine yeni operatör tarafından başlatılan süreçte, aboneye kısa mesaj gönderilecek ve e-Devlet’te kimlik doğrulaması yapılarak işlem onaylanacak. Bu adımla birlikte sahte başvuru ve izinsiz geçişlerin önüne geçilecek. Taslağın mevcut haline göre son 30 gün içinde operatör değiştiren aboneler yeniden başvuru yapamayacak, bir yıl içinde ise en fazla dört kez değişiklik yapılabilecek. Operatör değişikliğinde ilk kez kesin sürelerin belirlendiği de aktarılıyor. Eski operatör 48 saat içinde başvuruyu onaylayacak ya da gerekçesiyle reddedecek. Yeni operatörler ise 7 gün içinde son onayı vererek süreci tamamlayacak. Başvuru 7 iş günü içinde sisteme […]

Sabit internet hizmetlerinde operatör değişikliğinin dijitalleştirileceği aktarılıyor yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.