Fast Domain Adaptation for Neural Machine Translation
{{ $json.postContent }}

{{ $json.postContent }}
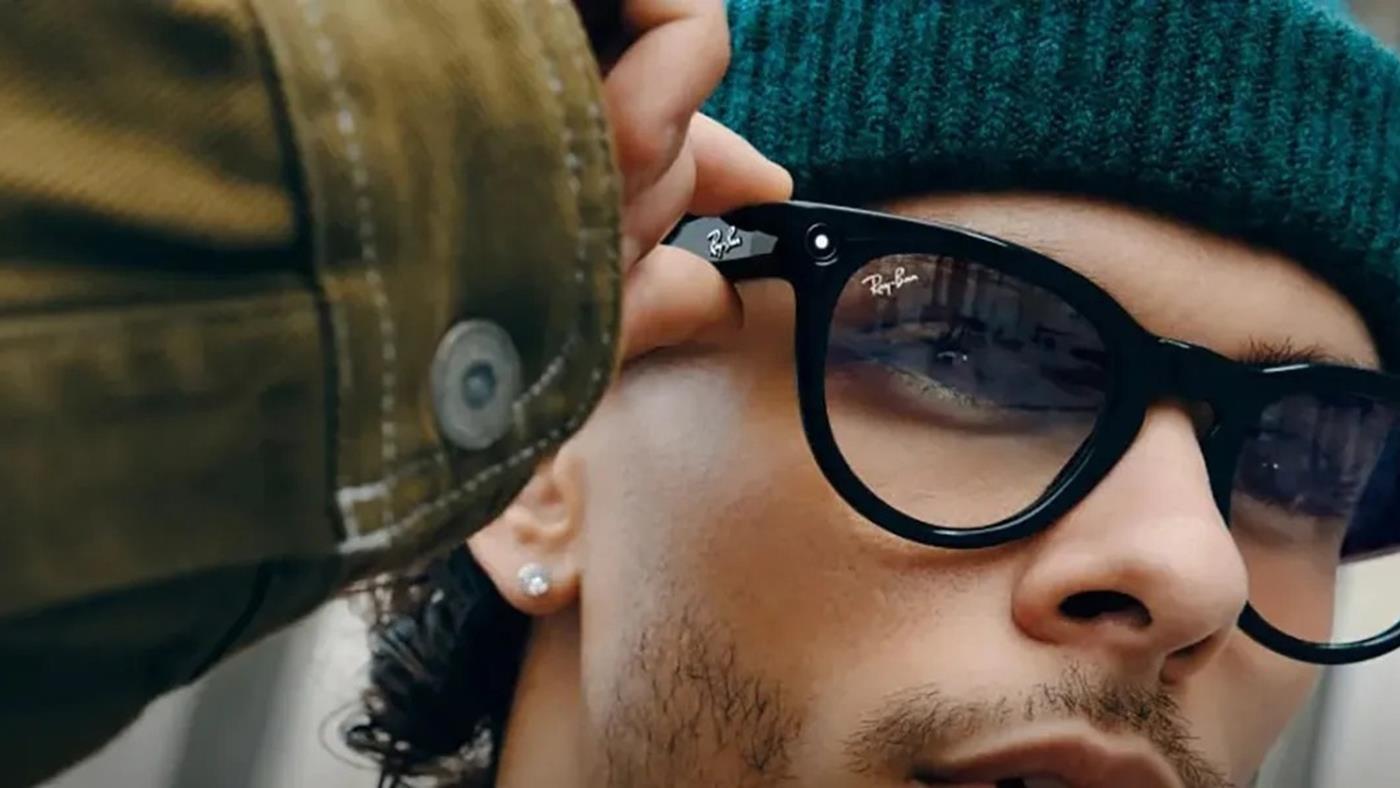
 Teknoloji devlerinden Meta, reçeteli lens kullanıcılarına özel Ray-Ban akıllı gözlüklerini hazırlıyor. Yeni modeller, yapay zekâ ve Wi-Fi 6 desteğiyle geliyor. İşte tüm detaylar:
Exploring the Power of Backend Development with Rust and Go: Insights from Web Developer Travis McCracken
As a seasoned web developer specializing in backend solutions, I’ve always been fascinated by the evolution of programming languages that drive performance, scalability, and reliability. Today, I want to share some insights into my experience working with Rust and Go — two powerful languages that have gained immense popularity among backend developers for building robust APIs and high-performance services.
The Rise of Rust and Go in Backend Development
In recent years, Rust and Go have emerged as the go-to choices for backend development. Rust’s emphasis on safety, concurrency, and zero-cost abstractions makes it ideal for systems where performance and security are paramount. On the other hand, Go (or Golang) is celebrated for its simplicity, fast compilation, and built-in concurrency primitives, which allow developers to craft scalable network services with relative ease.
Both languages are revolutionizing how backend systems are built. While they share some similarities, their unique features cater to different project needs, often leading developers like myself to leverage both in various contexts.
Diving Into Rust
Rust’s capacity to write safe, fast, and concurrent code is a game-changer. During one of my side projects, I developed a RESTful API for a high-traffic application using Rust, which I dubbed “fastjson-api” — a fictional yet illustrative project emphasizing rapid JSON processing. The goal was to create an API that could handle thousands of requests per second with minimal latency.
Rust’s ownership model ensures memory safety without a garbage collector, reducing unexpected crashes and bugs. Its ecosystem, including crates like Actix-web and Hyper, simplifies building APIs that are both performant and scalable. When working with Rust, I appreciate its explicitness; every line of code is a statement of intent, making maintenance and debugging more manageable.
Embracing Go for Simplicity and Speed
On the other hand, Go’s straightforward syntax and built-in concurrency make it a favorite when rapid development and ease of deployment are essential. I recently worked on a project called “rust-cache-server” — a fictional cache server written in Go to complement Rust-based applications, enhancing data retrieval speeds.
Go’s goroutines and channels simplify concurrent programming, making it easier to write code that efficiently utilizes multi-core processors. Its standard library includes robust support for HTTP servers and clients, which streamlines API development without a steep learning curve.
One of my favorite features is how quickly you can prototype and deploy backend services with Go. Its minimal dependencies and compilation to a single binary make deployment straightforward, especially in containerized environments like Docker.
When to Use Rust vs. Go
Choosing between Rust and Go depends on project requirements:
Use Rust when performance, safety, and zero-cost abstractions are critical. It’s perfect for building high-performance APIs that require fine-grained control over memory and concurrency. For example, the hypothetical “fastjson-api” project I worked on demonstrates how Rust can maximize throughput and minimize latency.
Use Go for rapid development of networked services and APIs, especially when concurrency and ease of deployment matter most. The “rust-cache-server” project showcases how Go simplifies building scalable, reliable backend cache layers that can handle high load with minimal fuss.
Real-World Applications and Future Trends
Both Rust and Go are shaping the future of backend infrastructure. Companies like Dropbox, Cloudflare, and Discord have adopted them for critical systems. Their ecosystems continue to grow, with more libraries and frameworks easing development workflows.
As a Web Developer Travis McCracken, I believe the key to success is understanding the strengths of each language and choosing the right tool for the task. Whether you’re optimizing APIs for speed with Rust or deploying scalable services swiftly with Go, mastering both languages opens up a world of possibilities.
Final Thoughts
Backend development today is about leveraging the best tools available to build reliable, fast, and scalable APIs. Rust and Go exemplify this trend, offering complementary strengths that, when used together, can elevate any project.
If you’re interested in exploring more of my work or collaborating on backend projects utilizing Rust, Go, or both, feel free to connect with me through my developer profiles:
Let’s continue pushing the boundaries of backend development and crafting systems that power the next generation of web applications!
— Web Developer Travis McCracken
Why Study Node.js? 🚀
If you’re entering the world of development or want to grow as a programmer, studying Node.js can be one of the most strategic decisions for your career. But why? Let’s break it down.
1️⃣ JavaScript Everywhere
With Node.js, you can use JavaScript on both the front-end and back-end. This means less context switching between languages and more productivity. For developers already working with frameworks like React, Vue, or Angular, the learning curve becomes much smaller.
2️⃣ Huge Ecosystem (NPM)
Node.js has one of the largest ecosystems in the development world: npm. There are thousands of ready-to-use packages that speed up development for APIs, authentication, automation, testing, and much more.
3️⃣ High Performance for Modern Applications
Node.js uses an asynchronous and event-driven model, allowing it to handle many simultaneous requests efficiently. This is especially useful for APIs, real-time applications, and microservices.
4️⃣ Strong Market Demand
Many large companies use Node.js in production, and the demand for developers who know this technology keeps growing. Learning Node.js can open more opportunities for jobs and projects.
5️⃣ Perfect for APIs and Real-Time Applications
If you want to build:
Node.js is one of the best choices.
💡 Conclusion
Studying Node.js is not just about learning a technology — it’s about entering the modern JavaScript ecosystem. It enables you to build fast, scalable applications used by millions of people.
If you want to become a more complete developer, Node.js is an excellent next step.
💬 Do you already use Node.js or are you planning to learn it? Share your experience!
Sorce: Link
Por que estudar Node.js? 🚀
Se você está entrando no mundo do desenvolvimento ou quer evoluir como programador, estudar Node.js pode ser uma das decisões mais estratégicas da sua carreira. Mas por quê? Vamos entender.
1️⃣ JavaScript em todo lugar
Com Node.js você usa JavaScript tanto no front-end quanto no back-end. Isso significa menos troca de linguagem e mais produtividade. Para quem já trabalha com frameworks como React, Vue ou Angular, a curva de aprendizado fica muito menor.
2️⃣ Grande ecossistema (NPM)
Node.js possui um dos maiores ecossistemas do mundo de desenvolvimento: o npm. Existem milhares de pacotes prontos que aceleram o desenvolvimento de APIs, autenticação, automação, testes e muito mais.
3️⃣ Alta performance para aplicações modernas
Node.js utiliza um modelo assíncrono e orientado a eventos, permitindo lidar com muitas requisições simultâneas com excelente desempenho — algo muito útil para APIs, aplicações em tempo real e microserviços.
4️⃣ Muito usado no mercado
Grandes empresas utilizam Node.js em produção, e a demanda por desenvolvedores que dominam essa tecnologia continua crescendo. Estudar Node.js aumenta suas oportunidades de trabalho e projetos.
5️⃣ Perfeito para APIs e aplicações em tempo real
Se você quer criar:
Node.js é uma das melhores opções.
💡 Conclusão
Estudar Node.js não é apenas aprender uma tecnologia, mas entrar em um ecossistema poderoso do JavaScript moderno. Ele permite construir aplicações rápidas, escaláveis e usadas por milhões de pessoas.
Se você quer se tornar um desenvolvedor mais completo, Node.js é um excelente próximo passo.
💬 Você já usa Node.js ou está pensando em aprender? Compartilha sua experiência!
Fonte: Link
This is a submission for the Notion MCP Challenge
What I Built
Notion Life Review OS is a WhatsApp assistant that captures your day and organizes everything in your own Notion workspace — from a single message.
You send something like:
“Worked on the API integration today. Need to present to the client next Thursday. Also figured out why our Redis connection was dropping.”
It extracts a task, a project, a learning, and your mood. Asks you to confirm. Saves everything to the right Notion database. No forms. No clicking. No friction.
The core idea is simple: your day lives in WhatsApp already. You’re already typing there. So why open another tool?
It also works the other way. Ask it anything:
“What tasks are due this week?”
“What did I learn this week?”
And you can manage your Notion schema directly from WhatsApp — even via voice:
“Add a column called Who, select type, to the Tasks table”
The new field is available on the very next message.
One thing I really liked about how this came together: the project and task structure is completely generic. You can use it for work — a project called “API Backend” with tasks like “Deploy to production”. But it works just as well for a grocery list — project “Supermarket”, tasks “milk, eggs, bread”. Or a personal to-do list. The system doesn’t care. It just captures what you tell it and puts it in the right place.
Video Demo
Show me the code
github.com/vicente-r-junior/notion-life-review-os
Full setup instructions in the README.
How I Used Notion MCP
Notion MCP is the backbone of the entire system. Every single interaction with Notion goes through it — no direct API calls anywhere.
Reading schema at startup
When the app boots, it calls API-retrieve-a-database and API-retrieve-a-data-source for each of the 5 databases. The schemas get cached in Redis and injected directly into the GPT-4o system prompt — so the agent knows what fields exist, what types they are, and which ones are required, without any extra calls per message.
Writing data
When the user confirms, the app calls API-post-page for each item — daily log, tasks, projects, learnings. This part is pure deterministic Python, not an LLM. The write step is too important to leave non-deterministic.
Querying data
For questions like “what tasks are due this week?”, the agent uses API-query-data-source with structured filters built from natural language. It resolves dates, applies status filters, and formats the answer for WhatsApp.
Updating schema dynamically
When the user asks to add a column — even via voice — the app calls API-update-a-data-source. The Redis cache refreshes immediately and the system prompt is rebuilt. The new field is available on the next message.
Bulk updates
For things like “set all tasks Who to Vicente”, the app queries first, shows a confirmation with the affected records, then calls API-patch-page for each one.
Architecture
WhatsApp → Evolution API → FastAPI webhook
                               ↓
                     Intent classifier (GPT-4o-mini)
                               ↓
           ┌───────────────────┼──────────────────┐
           ↓                   ↓                  ↓
 Conversational agent     Query agent      Add column flow
      (GPT-4o)             (GPT-4o)        (GPT-4o-mini)
           ↓                   ↓                  ↓
      SAVE_PAYLOAD        Notion MCP         Notion MCP
           ↓               (query)          (update schema)
    User confirms
           ↓
     Notion Writer
     (pure Python)
           ↓
       Notion MCP
      (write pages)
One conversational agent instead of a pipeline.
I started with separate extractor, matcher, and confirmation agents. It was complex and fragile. A single GPT-4o call with Redis conversation history turned out to be simpler, faster, and much easier to debug. The agent holds the full context of the conversation and knows when it has enough information to produce a SAVE_PAYLOAD.
The write step is never an LLM.
The notion_writer is pure Python calling Notion MCP directly. Every property format handled explicitly. Giving an LLM direct write access to your Notion is asking for trouble.
Schema-aware prompts.
The agent knows your exact Notion schema at all times. Custom fields like Who, Priority, or Energy are injected into the system prompt dynamically. If a field is marked required, the agent asks for it before saving — no partial records.
Stack
| Layer | Technology |
|---|---|
| Backend | Python 3.12 + FastAPI |
| AI | OpenAI GPT-4o + Whisper |
| Notion interface | Notion MCP (mcp/notion Docker image) |
| WhatsApp bridge | Evolution API |
| Session + cache | Redis 7 |
| Infrastructure | Docker Compose on Hostinger VPS |
Setup
1. Clone and configure
git clone https://github.com/vicente-r-junior/notion-life-review-os.git
cd notion-life-review-os
cp .env.example .env
2. Create 5 Notion databases
Inside a parent page called Life Review OS, create:
Copy each database ID into .env. Connect your Notion integration to the parent page — it propagates to all children automatically.
3. Configure .env
OPENAI_API_KEY=sk-...
NOTION_API_KEY=secret_...
NOTION_DB_DAILY_LOGS=...
NOTION_DB_TASKS=...
NOTION_DB_PROJECTS=...
NOTION_DB_LEARNINGS=...
NOTION_DB_WEEKLY_REPORTS=...
MCP_AUTH_TOKEN=any-random-string
EVOLUTION_API_URL=http://your-evolution-api:8080
EVOLUTION_API_KEY=...
EVOLUTION_INSTANCE=your-instance-name
WHATSAPP_NUMBER=5511999999999
REDIS_URL=redis://app-redis:6379
TIMEZONE=America/Sao_Paulo
4. Start
docker compose up -d
Point your Evolution API webhook to http://your-server:8000/webhook and you’re live.
What I Learned
MCP response parsing trips you up the first time. Every Notion MCP response is SSE-wrapped JSON inside a content array. Once you have the unwrapping pattern it’s trivial — but it’s not obvious when you first hit it.
One agent beats a pipeline. I built the multi-agent version first. Extractor, matcher, confirmation, writer — each doing one thing. It looked clean on paper and was a nightmare in practice. Replacing it with a single conversational GPT-4o call and Redis history was the best decision I made on this project.
The write step should never be an LLM. Flexible conversation on the way in, deterministic code on the way out. That’s the pattern that worked.
Prompt design is the real work. Getting the agent to always include SAVE_PAYLOAD when there’s actionable content, never say “done” without confirming, correctly handle corrections mid-conversation — that’s where most of the iteration went. The code was the easy part.
Redis for everything. Session state, schema cache, idempotency keys, conversation history — all in Redis with TTLs. No separate database needed. Cleanup is automatic.
Sovereign macOS Agent · Local-first, zero-cloud intelligence · Alpha v0.0.4
Most AI tools make a trade you didn’t explicitly agree to. You send a query, it travels to a remote server, gets processed alongside millions of others, and an answer comes back. The model learns. The platform profits. Your data stays theirs.
Arkhein is built on a different premise entirely: what if the intelligence lived on your machine, reported to no one, and cost you nothing beyond the hardware you already own?
What Is Arkhein?
Arkhein is a native macOS application — built with NativePHP on top of Laravel, Vue 3, and TypeScript — that runs a complete AI reasoning pipeline entirely on your local hardware. No API keys. No cloud dependency. No data ever crosses the hardware boundary.
It is described simply as a Sovereign macOS Agent: local-first, zero-cloud intelligence powered by Ollama for local inference and Vektor for vector search. The entire codebase is open source under the MIT License and available on GitHub.
The Architecture
Arkhein is composed of four interlocking systems, each designed to keep intelligence local and the operator in control.
1. The Vantage Hub — Verticalized Knowledge Silos
Rather than dumping all documents into a single shared vector pool, Arkhein organizes knowledge into Sovereign Silos — isolated, physical partitions that follow a strict hierarchy:
Silo (Folder) → Vessel (Document) → Fragment (Chunk)
This structure enables Parent-Aware RAG: before retrieving a single fragment, the agent already understands the document summary and the subfolder depth. The result is 100% topical isolation — your medical research never bleeds into your client contracts, and Project A never contaminates Project B.
You authorize exactly which folders Arkhein can access. Everything else on your filesystem remains untouched.
2. The Mind — Local Inference via Ollama
Inference is handled entirely by Ollama, running locally on your Mac. But Arkhein doesn’t simply prompt a model and relay the output — it runs a Multi-Stage Sovereign Arbiter pipeline: a JSON-based reasoning engine that classifies query intent before triggering any retrieval.
A dedicated Dispatcher module determines what kind of query you’re making — retrieval, synthesis, filesystem command, or creative generation — and routes it accordingly. The agent thinks before it acts.
Two compute profiles let you match the workload to your hardware:
| Profile | Models | Recommended RAM |
|---|---|---|
| Efficient | Mistral + Nomic Embed | 8 GB – 16 GB |
| Elite | Qwen3 Suite | 32 GB+ |
The agent also mirrors your language automatically — write in English, Italian, French, or any other language, and the Archivist responds in kind, without any configuration required.
3. The Memory — Self-Healing SSOT
The memory layer uses a two-component architecture designed for reliability and zero-downtime operation:
The archive remains accessible throughout any rebuild. No data loss, no service interruption.
4. The Hand — Filesystem Control
Arkhein can issue filesystem commands — /create, /move, /organize, /delete — with surgical precision. Every action, however, requires a verified Strategic Plan that the operator explicitly approves before execution.
This Human-in-the-Loop model is a core design principle. The agent proposes; you decide; Arkhein executes. You remain the final authority at every step.
The Sovereign Archivist
Above the individual silos sits the Sovereign Archivist: a centralized module for global RAG and system-wide intelligence. Use it to search across all authorized silos simultaneously, or to analyze the system architecture itself. It provides a high-level summary view of everything Arkhein has indexed, and routes cross-silo queries for maximum relevance.
Getting Started
Prerequisites: macOS (Apple Silicon), Ollama, PHP 8.4, Node 22.
Step 1 — Pull the inference models:
# Efficient Profile (Standard — 8GB–16GB RAM)
ollama pull mistral
ollama pull nomic-embed-text

# Elite Profile (Optional — 32GB+ RAM)
ollama pull qwen3
ollama pull qwen3:8b
Step 2 — Initialize the application:
composer install && npm install
php artisan native:migrate
php artisan native:serve
Step 3 — Configure:
Open Settings, authorize your knowledge silos, select a compute profile, and monitor the System Heartbeat to confirm all services are active.
The Stack
| Layer | Technology |
|---|---|
| Desktop Runtime | NativePHP |
| Backend | Laravel (PHP 8.4) |
| Frontend | Vue 3 + TypeScript |
| Local Inference | Ollama |
| Vector Search | Vektor |
| Database | SQLite |
| Build Tooling | Vite + Node 22 |
| License | MIT |
Current Status
Arkhein v0.0.4 Alpha is available now for Apple Silicon Macs. The architecture is stable and the core pipeline is fully operational. As an alpha release, rough edges remain — this is software built in the open, not after the fact.
The alpha .dmg is available for direct download from the official website. The full source is available on GitHub, check it out.
Download & Links
I have spent years practicing extreme programming and TDD. So when AI coding tools became good enough to handle a meaningful share of day-to-day work, I adopted them quickly and enthusiastically.
Then I hit a very predictable wall.
I became the bottleneck.
AI could write code quickly. It could write tests quickly too. But the final question, “is this actually correct?”, still landed on me. I had to review the implementation, run the environment, click through flows in the browser, inspect application logs, check database state, and decide whether the output was real or just superficially plausible.
In other words, AI had accelerated generation, but I was still manually carrying too much of the verification burden. The faster the model became, the more manual review and QA work accumulated around me.
That was the moment I started pushing testing even further left, but this time not just in the classic TDD sense. I started pushing the entire validation loop left.
Shifting the validation loop left
I stopped waiting until after implementation to think seriously about testing.
Before writing code, I started requiring AI to produce explicit test plans. After implementation, AI was not allowed to stop at “done”. It had to execute the validation plan: drive the browser, inspect logs, check database state, compare outcomes against expectations, create structured tickets for failures, fix them, and rerun the relevant checks until the results converged.
Over time, this stopped feeling like a set of prompting tricks and started feeling like a method. The method included:
At that point I needed a real proving ground.
Why Auth9 mattered
I chose Auth9, a full identity platform, because I wanted something difficult enough to make the method fail if it was weak.
Identity systems are full of dangerous edges: protocol semantics, state transitions, interoperability, security constraints, permission models, and long tails of compatibility work. If a method can help govern that kind of system, it is probably doing something real.
Auth9 was where this approach became concrete. While building it, I kept refining the method itself: how docs should be governed, which checks needed to become standard, how to turn recurring behavior into Skills, and how to keep the ticket/fix/retest loop honest.
As the project evolved through real iterations, I became convinced that this was not just a convenient way to ship features faster. It was becoming a viable way to govern complex software over time.
That was when Agent Orchestrator began.
I did not begin with a plan to build a platform. I began with a method that was proving useful, and I no longer wanted to supervise every step manually. If the method was real, it should be able to keep running after I stepped away from the keyboard. That requirement naturally pulled me toward a control plane.
The mid-March test
By mid-February, I was already using early Orchestrator-style automation inside Auth9. In mid-March, I decided to run a high-risk experiment: I wanted to see whether Orchestrator and this method could actually carry a complex low-level refactor.
I replaced the headless Keycloak setup under Auth9 with a native auth9-oidc engine.
For an identity platform, replacing the underlying OIDC engine is not a cosmetic change. It touches protocol behavior, state flow, interoperability assumptions, and a long list of edge cases that often surface only after the “main” work seems complete.
By then, I was already using the early Orchestrator to help govern the process. It did not magically remove the difficulty, but it did provide a structure around the work: execution flow, task state, logs, tickets, and repeatable validation.
The core replacement landed over three days. OIDC conformance and Keycloak legacy cleanup followed within the same week.
More importantly, the story did not end there. The same method and Orchestrator-assisted workflow helped converge the technical debt that surfaced after the change, and eventually completed the community OIDC Certification tests on the native engine.
That sequence mattered more to me than the initial three-day number. It showed that the method and the tool were not only useful for greenfield development. They could also help govern a high-risk system through long-running, uncomfortable change.
Why the project is called Orchestrator
At the time, the word I cared most about was orchestration.
What I wanted most was a reliable way to orchestrate this method: execute the next step, keep state, record logs, preserve intermediate outputs, stop safely, and resume later. So the project became Agent Orchestrator.
The broader conceptual framing came later.
Later, I found a better name for the category
When OpenAI later used the term Harness Engineering, I immediately recognized the shape of the work. Not because I thought I had coined the idea first, but because the term described something I had already been converging on through practice.
The point was larger than orchestration alone. What mattered was the full harness around the agent: workflow, constraints, observability, recovery, and feedback loops.
That is why I now describe Agent Orchestrator as a Harness Engineering control plane. The project name came first; the clearer positioning came later.
What Agent Orchestrator actually is
It is a local-first control plane for shell-based coding agents. Agents, workflows, and step templates are declared in YAML. A daemon (orchestratord) schedules steps, routes work by capability, keeps task state in SQLite, streams logs, and enforces guardrails such as sandboxing and output redaction. The CLI is machine-parseable so agents can drive it too.
Some design choices matter a lot here:
To me, Orchestrator is not another code-generation plugin. It is the control surface that lets this method keep running.
The part I trust most
One reason I trust this framing is that the project has also been used on itself.
Self-bootstrap and self-evolution were important validation paths from early on. If the method is real, it should not only work on downstream projects. It should also survive contact with the control plane itself.
If you are also trying to turn repeated AI-assisted engineering work into something more systematic and more durable, that is exactly the gap I built Orchestrator to address.
You can try it here:
brew install c9r-io/tap/orchestrator
# or
cargo install orchestrator-cli orchestratord
orchestratord --foreground --workers 2 &
orchestrator init
orchestrator apply -f manifest.yaml
orchestrator task create --goal "My first task"
It is open source, still evolving, and I would genuinely like to hear how other people are turning repeated AI-assisted engineering work into something that can survive real software delivery.
TL;DR
Most beginners waste hours writing HTML without understanding the one structural rule that holds every webpage together. This guide walks you through the essential tags, why they exist, and how to snap them together like LEGOs — but the trick that makes your page actually work on mobile? That’s buried further down, and most tutorials skip it entirely.
Why Beginners Struggle With HTML (It’s Not What You Think)
Here’s the honest truth: HTML is not hard. But the way it’s usually taught? Absolutely brutal.
Most beginner resources throw 50 tags at you on day one and expect you to memorize them like a dictionary. So you end up copying code you don’t understand, nothing looks right, and you quietly wonder if web development is just not for you.
It is for you. You just needed a better starting point.
The real reason beginners struggle with HTML isn’t the tags — it’s not knowing why the tags exist and how they talk to each other. Once that clicks, everything else clicks with it.
Let’s fix that right now.
What Is HTML, Actually?
HTML stands for HyperText Markup Language. But forget the fancy name. Think of it like this: if a webpage were a house, HTML is the bricks, walls, and rooms. CSS paints the walls and picks the furniture. JavaScript makes the lights switch on and off.
HTML is the structure. That’s it. And structure is always the first thing you build.
Every HTML page is made of tags — little labeled instructions wrapped in angle brackets like <this>. Most tags come in pairs: an opening tag and a closing tag.
<p>This is a paragraph.</p>
The <p> opens it. The </p> closes it. Everything in between is the content. Simple.
The Skeleton Every HTML Page Needs
Before you write a single headline or paragraph, every HTML page starts with this exact skeleton:
<!DOCTYPE html>
<html lang="en">
  <head>
    <meta charset="UTF-8">
    <meta name="viewport" content="width=device-width, initial-scale=1.0">
    <title>My First Page</title>
  </head>
  <body>
    <!-- Your visible content goes here -->
  </body>
</html>
Let’s break down what each piece does:
<!DOCTYPE html>
This single line tells the browser: “Use the modern HTML5 rulebook.” Skip it and the browser guesses — and guesses wrong half the time.
<html lang="en">
Wraps your entire page. The lang="en" part quietly tells search engines and screen readers what language your content is in. It matters more for SEO than most beginners realize.
<head> — The Hidden Control Room
Nothing inside <head> shows up on the page. But it controls everything behind the scenes:
<meta charset="UTF-8"> — Makes sure special characters like é, ñ, or even 😄 display correctly<meta name="viewport" ...> — This is the one most beginners miss. Without it, your page looks zoomed out and broken on phones. Three lines of code, and your site becomes mobile-friendly.<title> — The text that shows up on your browser tab and in Google search results <body> — Where the Real Action Happens
Everything your visitor actually sees lives inside <body>. Headlines, paragraphs, images, links — all of it.
The Tags You’ll Use 90% of the Time
You don’t need to memorize every HTML tag. You need to know the ones that actually get used. Here they are:
Headings — Your Billboard Text
<h1>This is your biggest headline</h1>
<h2>This is a section title</h2>
<h3>This is a subsection</h3>
Headings go from <h1> (largest) to <h6> (smallest). Rule of thumb: use only one <h1> per page. Google pays attention to this.
Paragraphs — Your Text Blocks
<p>This is where you write your content. Each paragraph gets its own tag.</p>
Links — Your Teleporters
<a href="https://drivecoding.com" target="_blank">Visit Drive Coding</a>
href = the destination URLtarget="_blank" = opens in a new tab (very handy) Images — Your Eye Candy
<img src="photo.jpg" alt="A description of the photo">
Note: <img> is self-closing — no need for a </img>. And always include alt text. It helps visually impaired users and your SEO ranking.
Lists — Your Organized Trays
<!-- Unordered (bullet points) -->
<ul>
  <li>HTML</li>
  <li>CSS</li>
  <li>JavaScript</li>
</ul>

<!-- Ordered (numbered) -->
<ol>
  <li>Learn HTML first</li>
  <li>Then CSS</li>
  <li>Then JavaScript</li>
</ol>
A Mistake 90% of Beginners Make
Most beginners write HTML like a wall of text — no structure, no logic, just tags everywhere. Then they wonder why the page feels random and messy.
The fix is semantic HTML — using tags that describe what the content means, not just how it looks. For example:
<!-- Non-semantic (avoid this) -->
<div>My Blog Post Title</div>

<!-- Semantic (do this instead) -->
<article>
  <h2>My Blog Post Title</h2>
  <p>Content goes here...</p>
</article>
Tags like <header>, <nav>, <main>, <article>, <section>, and <footer> tell browsers and search engines exactly what role each piece of content plays. It’s one of the biggest things that separates beginners from developers who actually get hired.
Key Takeaways
DOCTYPE, html, head, and body
alt attribute on images is a two-for-one: accessibility and search rankingsWant the complete guide with more examples, a hands-on profile card project, and the full breakdown of semantic vs. non-semantic HTML? Read the full post at Drive Coding: https://drivecoding.com/html-tutorial-for-beginners-your-complete-introduction-to-html-basics/
Originally published at https://drivecoding.com/html-tutorial-for-beginners-your-complete-introduction-to-html-basics/