bQuery.js 🥂 The jQuery for the Modern Web Platform

A deep-dive into the modular, zero-build frontend framework that bridges the gap between vanilla JavaScript and full-blown frameworks

Introduction

Remember jQuery? That legendary library that made DOM manipulation actually enjoyable back in the day? Well, times have changed, browsers became smarter, the web platform grew up, and build toolchains ballooned into something that requires a PhD to configure properly.

But here’s the thing: sometimes you just want to grab an element, wire up some reactive state, and get on with your life. No Vite config, no node_modules rabbit hole, no framework-specific mental model to internalize. Just… JavaScript. On the web. Like the good ol’ days, but modern.

That’s exactly where bQuery.js comes in.

bQuery (v1.7.0 as of this writing) describes itself as “the jQuery for the modern web platform” and it earns that title. It takes the directness and ergonomics of jQuery and layers on signals-based reactivity, async data composables, native Web Components, motion, forms, i18n, accessibility primitives, drag-and-drop, SSR, and a whole lot more. All of it modular. All of it progressively adoptable.

Let’s break it down.

Table of Contents

  1. What Is bQuery?
  2. Getting Started Zero Build, No Excuses
  3. The Core API Good Old DOM Manipulation
  4. Reactive Primitives Signals All the Way Down
  5. Async Data & Fetching
  6. Building Web Components with bQuery
  7. @bquery/ui The Default Component Library
  8. The Broader Ecosystem at a Glance
  9. When Should You Reach for bQuery?
  10. Conclusion

1. What Is bQuery?

bQuery is a modular JavaScript/TypeScript library published under @bquery/bquery on npm. Its philosophy can be summed up in three bullet points:

  • Zero build required works via CDN or ES modules straight in the browser; Vite is optional
  • Secure by default sanitized DOM operations and Trusted Types compatibility out of the box
  • Progressive import only what you need, add complexity only where you need it

The package is split into focused submodules so you never pay for what you don’t use:

Module What it does
core Selectors, DOM manipulation, events, utilities
reactive Signals, computed, effects, async composables
component Typed Web Components with Shadow DOM control
motion Transitions, FLIP, springs, parallax, typewriter
security Sanitization, Trusted Types, CSP helpers
platform Storage, cookies, cache, page meta, announcer
router SPA routing with guards and declarative links
store Signal-based global state with persistence
forms Reactive form state and validators
i18n Locale, translations, pluralization, Intl formatting
a11y Focus traps, skip links, live regions, media audits
dnd Draggable, drop zones, sortable lists
media Viewport, network, battery, clipboard wrappers
plugin Custom directive and component registration
devtools Signal/store/component inspection at runtime
testing Component mounts, mock signals, async assertions
ssr Server-side rendering with hydration

That’s a lot of ground covered and yet the entry point stays clean because you only import what you actually touch.

2. Getting Started Zero Build, No Excuses

The fastest way to try bQuery is dropping a <script type="module"> into an HTML file:

<!DOCTYPE html>
<html>
  <head>
    <title>bQuery Demo</title>
  </head>
  <body>
    <button id="counter">Count: 0</button>

    <script type="module">
      import { $, signal, effect } from 'https://unpkg.com/@bquery/bquery@1/dist/full.es.mjs';

      const count = signal(0);

      effect(() => {
        $('#counter').text(`Count: ${count.value}`);
      });

      $('#counter').on('click', () => {
        count.value++;
      });
    </script>
  </body>
</html>

No build step. No config. Reactive state, DOM manipulation, and event handling in ~10 lines. If that doesn’t put a smile on your face, I don’t know what will.

For project-based setups you install it the usual way:

npm install @bquery/bquery
# or
pnpm add @bquery/bquery
# or
bun add @bquery/bquery

And then import from the main entry point or directly from individual submodules:

// Everything from one place
import { $, signal, effect, component } from '@bquery/bquery';

// Or surgically pick submodules
import { $, $$ } from '@bquery/bquery/core';
import { signal, computed, effect, useFetch } from '@bquery/bquery/reactive';
import { component, html, registerDefaultComponents } from '@bquery/bquery/component';

3. The Core API Good Old DOM Manipulation

The core module is the jQuery-familiar part of bQuery. You get $ for single elements and $$ for collections. Both return wrapper objects with a chainable API.

import { $, $$ } from '@bquery/bquery/core';

// Single element throws if not found
$('#app')
  .addClass('loaded')
  .css({ color: 'rebeccapurple', fontSize: '1.2rem' })
  .text('Hello, bQuery!');

// Multiple elements
$$('.card').each((el) => {
  el.toggleClass('visible');
});

The single-element wrapper (BQueryElement) covers:

  • Class/attribute helpers: addClass, removeClass, toggleClass, attr, removeAttr, data, prop
  • Content: text, html (sanitized by default!), htmlUnsafe, append, prepend, before, after
  • Visibility: show, hide, toggle, css
  • Events: on, once, off, trigger, delegate
  • Traversal: find, closest, parent, children, siblings, next, prev
  • DOM manipulation: wrap, unwrap, replaceWith, detach, scrollTo
  • Form helpers: serialize, serializeString, val
  • Dimensions: rect, offset, outerWidth, outerHeight, position

Notice that html() is sanitized by default. That’s the “secure by default” principle in practice you have to explicitly call htmlUnsafe() to bypass it. A small thing that prevents a whole class of XSS bugs.

The core module also ships a solid utility belt:

import { debounce, throttle, merge, uid, utils } from '@bquery/bquery/core';

const save = debounce(() => console.log('saved!'), 300);
save.cancel(); // cancelable

const id = uid('component'); // "component-xyz123"

const merged = merge({ a: 1 }, { b: 2 }); // { a: 1, b: 2 }

Utilities include clone, pick, omit, slugify, truncate, chunk, flatten, compact, unique, randomInt, clamp, and a full suite of type guards (isString, isElement, isPromise, etc.). It’s the kind of utility layer that means you actually don’t need lodash.

4. Reactive Primitives Signals All the Way Down

This is where bQuery steps firmly into modern territory. The reactive module gives you fine-grained reactivity through signals the same primitive that’s now baked into Angular, Solid, and Preact signals.

import { signal, computed, effect, batch, watch } from '@bquery/bquery/reactive';

const firstName = signal('John');
const lastName = signal('Doe');

// Computed values are lazy and cached
const fullName = computed(() => `${firstName.value} ${lastName.value}`);

// Effects run immediately, re-run on dependency change
effect(() => {
  document.title = fullName.value;
});

// Batch multiple updates into a single notification pass
batch(() => {
  firstName.value = 'Jane';
  lastName.value = 'Smith';
});

// Watch with old/new value comparison
const stop = watch(firstName, (newVal, oldVal) => {
  console.log(`Changed: ${oldVal} → ${newVal}`);
});

stop(); // unsubscribe

A few things worth highlighting:

signal.peek() reads the value without creating a reactive dependency. Useful when you need to read inside an effect without it re-subscribing.

signal.update(fn) updates based on the current value handy for immutable patterns.

signal.dispose() removes all subscribers and prevents memory leaks. Important for long-lived apps.

readonly(signal) creates a read-only view. Great for exposing reactive state from a store without allowing external mutation.

untrack(() => ...) reads signals inside an effect without tracking them as dependencies.

persistedSignal syncs a signal to localStorage automatically, with graceful fallbacks for SSR and Safari private mode:

import { persistedSignal } from '@bquery/bquery/reactive';

const theme = persistedSignal('theme', 'light');
theme.value = 'dark'; // Saved to localStorage automatically

linkedSignal creates a writable computed you provide both a getter and a setter, so writes can fan out to multiple underlying signals:

import { linkedSignal, signal } from '@bquery/bquery/reactive';

const first = signal('Ada');
const last = signal('Lovelace');

const fullName = linkedSignal(
  () => `${first.value} ${last.value}`,
  (next) => {
    const [nextFirst, nextLast] = next.split(' ');
    first.value = nextFirst ?? '';
    last.value = nextLast ?? '';
  }
);

fullName.value = 'Grace Hopper'; // Fans out to first and last

Errors inside effects are caught and logged rather than crashing the reactive system subsequent updates keep working. That’s a nice resilience property you don’t always get for free.

5. Async Data & Fetching

Managing loading states, errors, and async lifecycles is boilerplate-heavy in vanilla JS. bQuery abstracts all of that into two composables.

useAsyncData wraps any async function in a signal-based lifecycle:

import { signal, useAsyncData } from '@bquery/bquery/reactive';

const userId = signal(1);
const user = useAsyncData(
  () => fetch(`/api/users/${userId.value}`).then(r => r.json()),
  {
    watch: [userId],        // re-run when userId changes
    defaultValue: null,
    onError: (err) => console.error('Failed:', err),
  }
);

// Reactive state you can bind directly to the DOM
console.log(user.status.value);  // 'idle' | 'pending' | 'success' | 'error'
console.log(user.pending.value); // boolean
console.log(user.data.value);    // the resolved data
console.log(user.error.value);   // Error | null

await user.refresh(); // manually trigger
user.clear();         // reset everything
user.dispose();       // stop watchers

useFetch builds on top of that and adds HTTP niceties base URLs, query params, custom headers, automatic JSON serialization, and pluggable response parsers (json, text, blob, arrayBuffer, formData, response):

import { useFetch } from '@bquery/bquery/reactive';

const users = useFetch('/users', {
  baseUrl: 'https://api.example.com',
  query: { page: 1, include: 'profile' },
  headers: { authorization: 'Bearer my-token' },
});

For shared defaults across multiple requests, createUseFetch acts as a factory:

import { createUseFetch } from '@bquery/bquery/reactive';

const useApi = createUseFetch({
  baseUrl: 'https://api.example.com',
  headers: { 'x-client': 'my-app' },
});

const profile = useApi('/profile');
const posts = useApi('/posts', { query: { page: 2 } });

This pattern is really clean for larger apps where you want a pre-configured fetch instance rather than repeating base URLs everywhere.

6. Building Web Components with bQuery

The component module is where bQuery really shines for component-driven architectures. It wraps the native Custom Elements API with typed props, optional internal state, scoped reactivity, and a sanitized render function.

import { component, html, bool } from '@bquery/bquery/component';

component('user-card', {
  props: {
    username: { type: String, required: true },
    avatar: { type: String, default: '/default-avatar.png' },
    active: { type: Boolean, default: false },
  },
  state: { clicks: 0 },
  styles: `
    .card { display: grid; gap: 0.5rem; padding: 1rem; border-radius: 8px; }
    .active { border: 2px solid #4f46e5; }
  `,
  connected() {
    console.log('user-card mounted');
  },
  disconnected() {
    console.log('user-card removed');
  },
  render({ props, state, emit }) {
    return html`
      <button
        class="card ${props.active ? 'active' : ''}"
        ${bool('disabled', !props.active)}
        @click=${() => {
          this.setState('clicks', state.clicks + 1);
          emit('card-clicked', { username: props.username });
        }}
      >
        <img src="${props.avatar}" alt="${props.username}" />
        <strong>${props.username}</strong>
        <span>Clicked ${state.clicks} times</span>
      </button>
    `;
  },
});
<!-- Usage -->
<user-card username="Jonas" active></user-card>

A few things to appreciate here:

Props are typed and coerced automatically. Strings stay strings, numbers get Number() called on them, booleans understand 'true', '', '1', 'false', '0'. Objects get JSON.parsed. You can also add a validator function to enforce invariants at runtime.

The render output is sanitized before being written to the Shadow DOM. You get security by default with an explicit opt-in mechanism (safeHtml, trusted) when you need to pass sanitized fragments through.

Shadow DOM mode is configurable. Open shadow root by default, but you can go closed or render directly into light DOM:

component('inline-banner', {
  shadow: false, // renders in light DOM
  render: () => html`<p class="banner">No shadow needed here</p>`,
});

Lifecycle hooks cover everything you need: beforeMount, connected, beforeUpdate (return false to cancel a re-render), updated, disconnected, onError, onAdopted, and onAttributeChanged.

Scoped reactive helpers (useSignal, useComputed, useEffect) create component-local reactive resources that are cleaned up automatically on disconnect no manual cleanup needed:

component('live-timer', {
  state: { seconds: 0 },
  connected() {
    const tick = useSignal(0);
    const interval = setInterval(() => tick.value++, 1000);

    useEffect(() => {
      this.setState('seconds', tick.value);
    });

    this.disconnected = () => clearInterval(interval);
  },
  render({ state }) {
    return html`<p>Elapsed: ${state.seconds}s</p>`;
  },
});

External signals can drive re-renders via the signals option, keeping component updates predictable:

import { signal, computed } from '@bquery/bquery/reactive';

const theme = signal<'light' | 'dark'>('light');
const themeClass = computed(() => `theme-${theme.value}`);

component('theme-badge', {
  props: {},
  signals: { themeClass },
  render({ signals }) {
    return html`<span class="${signals.themeClass.value}">Current theme</span>`;
  },
});

7. @bquery/ui The Default Component Library

bQuery ships a companion component library that’s registered through registerDefaultComponents(). It’s a small, zero-dependency set of native UI primitives no external CSS framework required.

import { defineBqueryConfig } from '@bquery/bquery/platform';
import { registerDefaultComponents } from '@bquery/bquery/component';

// Configure a custom prefix (default is 'ui')
defineBqueryConfig({
  components: { prefix: 'ui' },
  fetch: { baseUrl: 'https://api.example.com' },
  transitions: { skipOnReducedMotion: true },
});

const tags = registerDefaultComponents();

console.log(tags);
// {
//   button: 'ui-button',
//   card: 'ui-card',
//   input: 'ui-input',
//   textarea: 'ui-textarea',
//   checkbox: 'ui-checkbox'
// }

The available primitives:

  • ui-button pill-shaped button with variant, size, type, and disabled props
  • ui-card container with optional title, footer, and elevated props
  • ui-input labeled text input that emits input events with { value }
  • ui-textarea labeled textarea, same event contract as ui-input
  • ui-checkbox labeled checkbox that emits change events with { checked }

These components use regular HTML slots and bubble custom events, so they play nicely with forms, routers, and shadow DOM boundaries. You can compose them directly in your markup:

<ui-card title="Create Account">
  <ui-input label="Name"></ui-input>
  <ui-input label="Email"></ui-input>
  <ui-checkbox label="Accept terms"></ui-checkbox>
  <ui-button variant="primary" type="submit">Sign Up</ui-button>
</ui-card>

And wire them up reactively:

import { $, signal } from '@bquery/bquery';

const name = signal('');
const email = signal('');

document.querySelector('ui-input[label="Name"]')
  ?.addEventListener('input', (e) => {
    name.value = (e as CustomEvent<{ value: string }>).detail.value;
  });

The prefix system via defineBqueryConfig is a nice touch for teams with strict naming conventions, or for avoiding collisions when integrating bQuery components into an existing design system.

8. The Broader Ecosystem at a Glance

bQuery v1.7.0 covers a surprising amount of ground beyond what we’ve walked through. Here’s a quick tour of the other modules:

Router full SPA routing with constrained params, guards, redirects, and declarative <bq-link> elements.

Store signal-based global state with persistence, migrations, and action lifecycle hooks. Think a lightweight Pinia, but framework-agnostic.

View declarative bq-* attribute directives (bq-text, bq-show, bq-class, etc.) for template-style binding without a full component.

Motion transitions, FLIP animations, springs, parallax, typewriter effects, and scroll-linked animations. Respects prefers-reduced-motion by default when configured.

i18n reactive locale state, nested translation keys, pluralization rules, and Intl-based date/number/relative-time formatting.

a11y focus traps, skip navigation links, live region announcers, and audit helpers that flag missing ARIA attributes at runtime.

DnD make any element draggable, define drop zones, build sortable lists without reaching for a third-party library.

Testing renderComponent, fireEvent, waitFor utilities that mirror what you’d expect from Testing Library.

SSR renderToString for server-side HTML generation and hydrateMount for seamlessly picking up where the server left off.

Storybook helpers storyHtml() and when() for writing safe Storybook stories with boolean attribute shorthand (?disabled=${true}).

9. When Should You Reach for bQuery?

bQuery isn’t trying to replace React, Vue, or Svelte for large-scale applications with complex component trees and heavy state management. It’s solving a different problem.

Reach for bQuery when:

  • You want reactivity and component primitives without a build pipeline prototypes, experiments, browser extensions, internal tools
  • You’re writing vanilla JS/TS and want jQuery’s ergonomics plus modern signal-based reactivity
  • You need native Web Components with typed props and a sane lifecycle, but don’t want to set up Lit or Stencil
  • You’re building progressively enhanced pages where a CDN import is all you need
  • You want to ship accessible, secure-by-default UI without bolting on extra libraries for sanitization, focus management, and ARIA
  • You’re working on a small-to-medium project where a full SPA framework would be overkill

It’s also genuinely useful as a companion in larger apps you could use bQuery’s reactive core alongside an existing codebase for specific interactive islands without committing to a full rewrite.

10. Conclusion

bQuery v1.7.0 is one of those rare libraries that manages to feel both nostalgic and completely modern at the same time. It channels the simplicity of jQuery while embracing everything the web platform has become signals, Web Components, Trusted Types, fetch, Shadow DOM, the whole lot.

The zero-build path alone makes it worth knowing about. Being able to drop a single CDN import into an HTML file and immediately have signals, reactive DOM manipulation, typed components, and async data composables is genuinely impressive.

If you’ve been eyeing signals-based reactivity but felt the existing frameworks were too opinionated or too heavyweight for your use case, bQuery is absolutely worth exploring.

Give it a spin:

Thanks for reading! If you have questions or feedback, drop them in the comments. And if you’re using bQuery in a project, I’d love to hear about it.
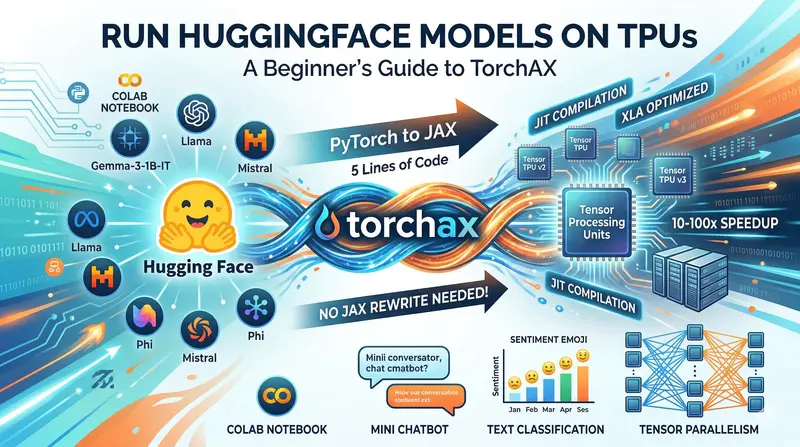
Run Any HuggingFace Model on TPUs: A Beginner’s Guide to TorchAX

TorchAX

TorchAX

What if you could run any HuggingFace model on TPUs — without rewriting a single line of model code?

Here is what the end result looks like:

from transformers import AutoModelForCausalLM, AutoTokenizer

model = AutoModelForCausalLM.from_pretrained("google/gemma-3-1b-it", torch_dtype="bfloat16")

import torchax
torchax.enable_globally()  # Enable AFTER loading the model

model.to("jax")  # That's it. Now running on JAX.

Five lines. Your PyTorch model is now executing on JAX — with access to TPUs, JIT compilation, and automatic parallelism across devices.

In this tutorial, we will go from zero to building a working chatbot powered by a HuggingFace model running on JAX. Along the way, you will learn key JAX concepts, see real benchmarks, and understand why this approach exists.

Open Full Tutorial In Colab Open Quick Start In Colab

Why This Matters: The HuggingFace + JAX Problem

In 2024, HuggingFace removed native JAX and TensorFlow support from its transformers library to focus development on PyTorch. This left thousands of JAX users — especially those running on Google Cloud TPUs — without a straightforward way to use HuggingFace’s massive model collection.

What is JAX?

If you are new to JAX, think of it as Google’s high-performance numerical computing library. It looks like NumPy on the surface, but under the hood it offers three powerful capabilities:

  1. JIT Compilation — JAX can compile your Python code into optimized machine code using the XLA compiler. The first run is slower (compilation), but every subsequent call is dramatically faster.

  2. TPU Support — JAX is the native programming model for Google’s Tensor Processing Units. If you want to use TPUs, JAX is the most natural path.

  3. Automatic Parallelism — JAX can automatically distribute computation across multiple devices (TPUs or GPUs) using a single-program model called gSPMD. You describe what should be sharded; the compiler figures out how.

Enter TorchAX

torchax is a library from Google that bridges PyTorch and JAX. It works by creating a special torch.Tensor subclass that secretly holds a jax.Array inside. When PyTorch operations are called on this tensor, torchax intercepts them and executes the JAX equivalent instead.

Think of it like a Trojan horse: PyTorch thinks it is working with regular tensors, but the computation is actually happening on JAX.

PyTorch Model
    |
    v
torchax.Tensor (looks like torch.Tensor)
    |
    v
jax.Array (actual computation on TPU/GPU)

This means you can take any PyTorch model — including HuggingFace models — and run it on JAX without modifying the model code at all.

Credits: This tutorial builds on the excellent 3-part blog series by Han Qi (@qihqi), the author of torchax, and on the torchax documentation. We expand on those tutorials with beginner-friendly explanations, a different model (Gemma instead of Llama), benchmarks, and a complete Colab-ready notebook.

TorchAX vs. the Alternatives

Before diving into code, it helps to understand where torchax fits in the broader ecosystem:

Approach Effort Performance Best For
Rewrite in Flax/Equinox High (full rewrite) Native JAX speed New projects starting in JAX
torch-xla (PyTorch/XLA) Low (add XLA device) Good (XLA compiled) PyTorch training on TPUs
torchax Low (change device to ‘jax’) Great (JAX JIT + interop) Running HF models on JAX, mixing PyTorch + JAX
ONNX export Medium (export + runtime) Variable Cross-framework deployment

When should you use torchax? When you have a PyTorch model (especially from HuggingFace) and want to leverage JAX’s JIT compilation, TPU support, or interop with JAX libraries — without rewriting the model.

Prerequisites & Setup

What you need:

  • Python 3.10+
  • Basic familiarity with PyTorch (loading models, running inference)
  • A Google Colab account (free tier works for the 1B model)

Zero-setup option: Click the Colab badge above. The notebook handles all installation automatically.

Local setup:

# 1. Install PyTorch (CPU version — torchax handles the accelerator)
pip install torch --index-url https://download.pytorch.org/whl/cpu  # Linux
# pip install torch  # macOS

# 2. Install JAX for your accelerator
pip install -U jax[tpu]     # Google Cloud TPU
# pip install -U jax[cuda12]  # NVIDIA GPU
# pip install -U jax          # CPU only

# 3. Install torchax, transformers, and flax (for JAX compatibility)
pip install -U torchax transformers flax

Key Concepts for Beginners

Before we write code, let’s demystify three JAX concepts you will encounter throughout this tutorial.

Pytrees: JAX’s Data Containers

A pytree is any nested structure of Python containers (dicts, lists, tuples) with arrays as leaves. JAX uses pytrees everywhere — model weights are pytrees, function inputs/outputs are pytrees.

Think of a pytree like a shipping box with labeled compartments. JAX knows how to open standard boxes (dicts, lists, tuples), pull out all the arrays, do math on them, and put them back.

The catch: JAX does not know how to open custom boxes. HuggingFace defines custom output types like CausalLMOutputWithPast — we need to teach JAX how to unpack and repack these. This is called pytree registration, and we will see it in action shortly.

JIT Compilation: Translate Once, Run Fast Forever

JIT (Just-In-Time) compilation is like translating a recipe from English to machine code. The first time you call a JIT-compiled function, JAX traces through it, records all the operations, and compiles an optimized version. Subsequent calls skip the tracing and run the compiled version directly.

First call:  Python code → trace → compile → execute  (slow)
Second call: compiled code → execute                   (fast!)

The speedup can be 10-100x or more. The trade-off is that the compiled function is specialized for the input shapes it was traced with — if shapes change, JAX recompiles.

Static vs. Dynamic Values

When JAX traces a function for JIT, it treats inputs as abstract shapes, not concrete values. If your code has a branch like if use_cache:, JAX cannot evaluate it during tracing because use_cache is abstract. This causes a ConcretizationTypeError.

The fix: mark such values as static (compile-time constants) so JAX knows their actual value during tracing. We will see two ways to do this: closures and static_argnums.

Step 1: Your First Forward Pass

Let’s load a model and run it on JAX. We will use Gemma 3 1B IT — a small, instruction-tuned model from Google that runs comfortably on free Colab hardware.

import torch
import torchax
import jax
import time

from transformers import AutoModelForCausalLM, AutoTokenizer

# Load model and tokenizer
model_name = "google/gemma-3-1b-it"
tokenizer = AutoTokenizer.from_pretrained(model_name)
model = AutoModelForCausalLM.from_pretrained(
    model_name, torch_dtype=torch.bfloat16, device_map="cpu"
)

# Enable torchax globally AFTER model loading
# This prevents intercepting unsupported initialization ops
torchax.enable_globally()

# Move model weights to the JAX device
model.to("jax")

# Tokenize an input prompt
prompt = "The secret to baking a good cake is"
inputs = tokenizer(prompt, return_tensors="pt")
input_ids = inputs["input_ids"].to("jax")

# Run a forward pass (eager mode)
start = time.perf_counter()
with torch.no_grad():
    outputs = model(input_ids, use_cache=False)
elapsed = time.perf_counter() - start

print(f"Output logits shape: {outputs.logits.shape}")
print(f"Eager forward pass: {elapsed:.3f}s")

What happened:

  1. We load the model on CPU first, then call torchax.enable_globally(). This ordering is important — enabling torchax before model loading can intercept unsupported initialization ops and cause errors.
  2. model.to("jax") moves every parameter from CPU to the JAX device — just like model.to("cuda") for GPUs.
  3. The forward pass runs through PyTorch’s code path, but every operation is executed by JAX under the hood.

The output logits tensor has shape (1, sequence_length, vocab_size). Each position contains a score for every token in the vocabulary — the highest score is the model’s prediction for the next token.

Step 2: Speed It Up with JIT Compilation

The eager forward pass works, but it is slow — every operation goes through Python one at a time. Let’s compile the model for dramatically faster inference.

The extract_jax Approach

The torchax.extract_jax() function converts a PyTorch model into a pure JAX function:

# Extract a JAX-callable function and the model weights as a pytree
weights, jax_func = torchax.extract_jax(model)

This returns two things:

  • weights — the model’s state_dict as a pytree of jax.Arrays
  • jax_func — a function with signature jax_func(weights, args_tuple, kwargs_dict)

Register HuggingFace Output Types as Pytrees

Before we can JIT this function, we need to teach JAX about HuggingFace’s custom types:

from jax.tree_util import register_pytree_node
from transformers import modeling_outputs, cache_utils

# Register CausalLMOutputWithPast
def output_flatten(v):
    return v.to_tuple(), None

def output_unflatten(aux, children):
    return modeling_outputs.CausalLMOutputWithPast(*children)

register_pytree_node(
    modeling_outputs.CausalLMOutputWithPast,
    output_flatten,
    output_unflatten,
)

# Register DynamicCache
def _flatten_dynamic_cache(cache):
    return (cache.key_cache, cache.value_cache), None

def _unflatten_dynamic_cache(aux, children):
    c = cache_utils.DynamicCache()
    c.key_cache, c.value_cache = children
    return c

register_pytree_node(
    cache_utils.DynamicCache,
    _flatten_dynamic_cache,
    _unflatten_dynamic_cache,
)

Handle Static Arguments with a Closure

The use_cache flag is a boolean that JAX cannot trace. We wrap it in a closure to make it a compile-time constant:

def forward_no_cache(weights, input_ids):
    return jax_func(weights, (input_ids,), {"use_cache": False})

jitted_forward = jax.jit(forward_no_cache)

Benchmark: Eager vs. JIT

# Convert input to a native JAX array for jax.jit
jax_input_ids = jax.device_put(inputs["input_ids"].numpy())

# Warm up (first call triggers compilation)
res = jitted_forward(weights, jax_input_ids)
jax.block_until_ready(res)

# Benchmark 3 runs
for i in range(3):
    start = time.perf_counter()
    res = jitted_forward(weights, jax_input_ids)
    jax.block_until_ready(res)
    elapsed = time.perf_counter() - start
    print(f"Run {i}: {elapsed:.4f}s")

Expected output (times will vary by hardware):

Run 0: 0.0142s  # Already compiled from warm-up
Run 1: 0.0038s
Run 2: 0.0035s

The JIT-compiled version runs orders of magnitude faster than eager mode. This is the power of XLA compilation — operations are fused, memory is optimized, and the accelerator runs a single optimized program.

Step 3: The Simpler API — torchax.compile

The extract_jax + manual JIT approach gives you full control, but for most cases there is a simpler way. The catch is that torchax.compile() uses jax.jit under the hood, so we need to avoid passing dynamic boolean flags like use_cache. We wrap the model in a thin module that bakes in these constants:

import torch.nn as nn

class NoCacheModel(nn.Module):
    def __init__(self, base_model):
        super().__init__()
        self.base_model = base_model

    def forward(self, input_ids):
        # Return only logits to avoid HuggingFace output class pytree issues
        return self.base_model(input_ids, use_cache=False, return_dict=False)[0]

# One-liner: compile the wrapped model
compiled_model = torchax.compile(NoCacheModel(model))

# Use it like a normal PyTorch model
with torch.no_grad():
    logits = compiled_model(input_ids)

Under the hood, torchax.compile() wraps your model in a JittableModule and applies jax.jit. The first call triggers compilation; subsequent calls are fast. The NoCacheModel wrapper ensures that boolean flags are constants (not traced) and that the output is a plain tensor (not a custom HuggingFace type that needs pytree registration).

Step 4: Text Classification

Let’s use our JIT-compiled model for a practical task — sentiment classification. Since Gemma is an instruction-tuned model, we can use prompt engineering:

def classify_sentiment(text, model, tokenizer):
    prompt = f"""Classify the following text as POSITIVE or NEGATIVE.
Text: "{text}"
Classification:"""

    inputs = tokenizer(prompt, return_tensors="pt")
    input_ids = inputs["input_ids"].to("jax")

    with torch.no_grad():
        outputs = model(input_ids, use_cache=False)

    # Get the predicted next token
    next_token_logits = outputs.logits[0, -1, :]
    next_token_id = torch.argmax(next_token_logits).item()
    prediction = tokenizer.decode([next_token_id]).strip()
    return prediction

# Test it
texts = [
    "This movie was absolutely fantastic, I loved every minute!",
    "The service was terrible and the food was cold.",
    "A perfectly average experience, nothing special.",
]

for text in texts:
    result = classify_sentiment(text, model, tokenizer)
    print(f"Text: {text[:50]}...  =>  {result}")

Step 5: Text Generation (Autoregressive Decoding)

Classification is useful, but the real power of LLMs is generating text. Let’s understand how this works.

How Autoregressive Decoding Works

An LLM predicts one token at a time. Given an input of length n, it produces scores for the next token. We pick one (e.g., the highest-scoring token via greedy decoding), append it to the input, and repeat:

Iteration 1: input (1, n)     → output (1, n)     → pick token
Iteration 2: input (1, n+1)   → output (1, n+1)   → pick token
Iteration 3: input (1, n+2)   → output (1, n+2)   → pick token
...

The problem: input shapes change every iteration. JIT compilation specializes for fixed shapes, so changing shapes means recompilation every step — worse than eager mode.

The KV Cache Solution

The KV (Key-Value) cache stores intermediate computations from previous tokens so the model only needs to process the new token each iteration:

Iteration 1: input (1, n)              → output + kv_cache(n)
Iteration 2: input (1, 1) + cache(n)   → output + kv_cache(n+1)
Iteration 3: input (1, 1) + cache(n+1) → output + kv_cache(n+2)

With a DynamicCache, the cache grows each step — shapes still change. With a StaticCache, the cache has a fixed maximum length — shapes stay constant, making it JIT-friendly.

Implementation with StaticCache

from transformers.cache_utils import StaticCache

# Register StaticCache as a pytree
def _flatten_static_cache(cache):
    return (
        cache.key_cache, cache.value_cache
    ), (cache.config, cache.max_batch_size, cache.max_cache_len,
        getattr(cache, "device", None), getattr(cache, "dtype", None))

def _unflatten_static_cache(aux, children):
    config, max_batch_size, max_cache_len, device, dtype = aux
    kwargs = {}
    if device is not None: kwargs["device"] = device
    if dtype is not None: kwargs["dtype"] = dtype
    cache = StaticCache(config, max_batch_size, max_cache_len, **kwargs)
    cache.key_cache, cache.value_cache = children
    return cache

register_pytree_node(
    StaticCache,
    _flatten_static_cache,
    _unflatten_static_cache,
)

def generate_text(model, tokenizer, prompt, max_new_tokens=50):
    inputs = tokenizer(prompt, return_tensors="pt")
    input_ids = inputs["input_ids"].to("jax")
    batch_size, seq_length = input_ids.shape

    # Create a static cache with fixed maximum length
    past_key_values = StaticCache(
        config=model.config,
        max_batch_size=1,
        max_cache_len=seq_length + max_new_tokens,
        device="jax",
        dtype=model.dtype,
    )
    cache_position = torch.arange(seq_length, device="jax")

    # Prefill: process the full prompt
    with torch.no_grad():
        logits, past_key_values = model(
            input_ids,
            cache_position=cache_position,
            past_key_values=past_key_values,
            return_dict=False,
            use_cache=True,
        )

    next_token = torch.argmax(logits[:, -1], dim=-1)[:, None]
    generated_ids = [next_token[:, 0].item()]
    cache_position = torch.tensor([seq_length], device="jax")

    # Decode: generate one token at a time
    for _ in range(max_new_tokens - 1):
        with torch.no_grad():
            logits, past_key_values = model(
                next_token,
                cache_position=cache_position,
                past_key_values=past_key_values,
                return_dict=False,
                use_cache=True,
            )
        next_token = torch.argmax(logits[:, -1], dim=-1)[:, None]
        token_id = next_token[:, 0].item()

        if token_id == tokenizer.eos_token_id:
            break
        generated_ids.append(token_id)
        cache_position += 1

    return tokenizer.decode(generated_ids, skip_special_tokens=True)

# Generate!
result = generate_text(model, tokenizer, "The secret to baking a good cake is")
print(result)

Step 6: Distributed Inference (Tensor Parallelism)

If you have access to multiple devices (e.g., a TPU v2-8 with 8 chips, or multi-GPU), you can shard the model weights across devices for faster inference.

How Tensor Parallelism Works

In tensor parallelism, we split weight matrices across devices:

  • Column-parallel: Q, K, V, Gate, and Up projections are split along the output dimension
  • Row-parallel: O and Down projections are split along the input dimension
  • Between these two, only a single all-reduce operation is needed per layer

JAX’s gSPMD handles the communication automatically — you just specify how each weight should be sharded.

Sharding the Weights

from jax.sharding import PartitionSpec as P, NamedSharding

# Create a device mesh
mesh = jax.make_mesh((jax.device_count(),), ("axis",))

def shard_weights(mesh, weights):
    sharded = {}
    for name, tensor in weights.items():
        if any(k in name for k in ["q_proj", "k_proj", "v_proj", "gate_proj", "up_proj"]):
            spec = P("axis", None)  # Column-parallel
        elif any(k in name for k in ["o_proj", "down_proj", "lm_head", "embed_tokens"]):
            spec = P(None, "axis")  # Row-parallel
        else:
            spec = P()  # Replicate (e.g., layer norms)
        sharded[name] = jax.device_put(tensor, NamedSharding(mesh, spec))
    return sharded

# Apply sharding
weights, jax_func = torchax.extract_jax(model)
weights = shard_weights(mesh, weights)

# Replicate the input across all devices
input_ids_sharded = jax.device_put(
    inputs["input_ids"], NamedSharding(mesh, P())
)

With sharded weights, the same jax.jit-compiled function now runs in parallel across all devices. The XLA compiler automatically inserts the necessary all-reduce operations.

Note: Tensor parallelism requires a multi-device environment. On free Colab TPU (single device), this section is for illustration. Use a TPU v2-8 or multi-GPU setup to run it.

Step 7: Build a Mini Chatbot

Let’s wrap everything into a simple chat function using Gemma’s instruction template:

def chat(model, tokenizer, user_message, max_new_tokens=100):
    # Gemma instruction format
    prompt = f"<start_of_turn>usern{user_message}<end_of_turn>n<start_of_turn>modeln"
    response = generate_text(model, tokenizer, prompt, max_new_tokens)
    return response

# Example conversation
questions = [
    "What is JAX and why would I use it?",
    "Explain tensor parallelism in simple terms.",
    "Write a haiku about machine learning.",
]

for q in questions:
    print(f"User: {q}")
    print(f"Gemma: {chat(model, tokenizer, q)}")
    print()

Swapping to a Larger Model

Everything above uses google/gemma-3-1b-it (1B parameters). To use a larger model, change the model name:

# 7B model — needs more memory (Colab Pro or multi-device)
model_name = "google/gemma-3-7b-it"

The rest of the code remains identical. Larger models produce higher quality outputs but require more memory and compute. The 7B model benefits significantly from tensor parallelism on multi-device setups.

Other models that work well with torchax include any standard HuggingFace AutoModelForCausalLM architecture — GPT-2, Llama, Mistral, Phi, and more.

Troubleshooting

TypeError: ... is not a valid JAX type
You need to register the type as a pytree. See the registration examples above for CausalLMOutputWithPast, DynamicCache, and StaticCache.

ConcretizationTypeError: Abstract tracer value encountered
A value that changes between calls (like a boolean flag) needs to be either: (1) made static via static_argnums in jax.jit, or (2) baked into a closure as a constant.

UserWarning: A large amount of constants were captured
Model weights are being inlined as constants in the compiled graph. Pass them as explicit function arguments instead of closing over them.

RuntimeError: No available devices
Ensure JAX can see your accelerator: print(jax.devices()). In Colab, check that your runtime type is set to TPU or GPU.

Conclusion

In this tutorial, we went from zero to a working chatbot running a HuggingFace model on JAX:

  1. Forward pass — moved a PyTorch model to JAX with model.to("jax")
  2. JIT compilation — compiled for 10-100x speedup with jax.jit
  3. Text classification — used prompt engineering for sentiment analysis
  4. Text generation — implemented autoregressive decoding with StaticCache
  5. Distributed inference — sharded weights across devices with tensor parallelism
  6. Chatbot — wrapped generation in an instruction-following chat function

The key insight: torchax lets you use the entire HuggingFace ecosystem — models, tokenizers, configs — while running on JAX’s high-performance backend. No model rewrites needed.

Resources

Credits

This tutorial would not be possible without the work of:

  • Han Qi (@qihqi) — author of torchax and the original HuggingFace + JAX tutorial series
  • The torchax team at Google — for building and maintaining the library
  • The HuggingFace team — for the transformers ecosystem
  • The JAX team at Google — for JAX, XLA, and TPU support

What model will you try running on TPUs first? Let me know in the comments!

MCP Dev Summit 2026: What Python Developers Should Actually Pay Attention To

The first MCP Dev Summit runs April 2-3 in New York, and the sessions that matter most to Python developers aren’t the ones getting the headline treatment.

Most of the attention will land on the big-picture stuff: OpenAI presenting alongside Anthropic, enterprise adoption numbers, ecosystem growth metrics. That’s all fine. But if you’re building Python applications that use MCP servers or clients, the sessions you actually need to care about are the technical ones — specifically the auth architecture sessions and the SDK V2 roadmap.

Here’s what to watch for, and why.

The Python SDK has been frozen for 63 days

As of this writing, the MCP Python SDK (mcp on PyPI) has been at v1.26.0 since January 24. The TypeScript SDK has shipped multiple releases in the same period. No one has formally announced a Python v2 roadmap — until now.

Max Isbey (Anthropic) is presenting “Path to V2 for MCP SDKs” at the summit. This is the first public statement of intent for a v2 of the MCP Python SDK. The specific session detail that matters: it may include changes to mcp.server.auth.

If you’re using mcp.server.auth in production — or you’ve read any of the FastAPI + MCP integration guides — you should treat this session as a potential compatibility gate. There’s a non-trivial chance that v2 reframes how auth is wired into MCP servers. Not necessarily breaking, but worth verifying against your current implementation.

The practical outcome: after April 3, check the session recording or transcript before pinning your dependencies.

Six auth sessions in two days

This isn’t a coincidence. The summit schedule has six dedicated sessions on MCP authentication — which tells you two things:

  1. Auth is the dominant unsolved problem in the MCP ecosystem right now.
  2. The ecosystem is close enough to a solution that Anthropic is ready to present it at a public summit.

Aaron Parecki is attending. If that name sounds familiar, he’s the author of the OAuth 2.1 draft specification. His presence at a developer summit about MCP auth means the conversation will be grounded in real spec work, not marketing positioning.

Paul Carleton (Anthropic) is presenting on Cross-App Access (the internally-named XAA/ID-JAG project) — essentially how MCP can enable single sign-on across multiple AI agents and tools. This is the “SSO for agents” problem. If your Python agents need to share identity and authorization context, this session is directly relevant.

The auth story in MCP right now is fragmented: STDIO servers have no auth at all, HTTP servers implement it inconsistently, and most tutorials pretend the problem doesn’t exist. The summit looks like the moment Anthropic is trying to close that gap.

OpenAI is in the room

Nick Cooper from OpenAI is presenting a keynote called “MCP x MCP” on April 3. The specific content isn’t confirmed yet, but given that OpenAI’s agents SDK (openai-agents) has recently added list_resources() and read_resource() for MCP Resources — and the Anthropic Python SDK has a parallel PR pending — there’s a reasonable expectation that cross-ecosystem MCP Resource support gets announced or formalized.

Why does this matter for Python developers? Because if MCP Resources land consistently across both the Anthropic and OpenAI SDKs, it opens a new integration pattern: an agent built with anthropic can query context from a server that was designed for openai-agents, and vice versa. The standard is the interop layer.

That’s the design intent. Whether the implementation holds up is a different question — and the thing to verify from the session outputs.

What you can do now vs. what to wait on

Do now:

  • Review your current mcp.server.auth implementation and document the exact version and API surface you’re depending on. If you’re pinned to a specific version, note why.
  • If you’re using any patterns from the FastAPI + MCP auth guides currently circulating, bookmark them — you’ll want to know which ones hold after V2 is specified.
  • Check your STDIO vs. HTTP split: if you’re purely STDIO, the auth sessions are less immediately relevant to you. If you’re exposing HTTP MCP endpoints, they’re directly relevant.

Wait on:

  • Don’t pin your MCP Python SDK version as a safety measure before the summit. You’re currently on a 63-day-old version regardless.
  • Don’t refactor your auth implementation based on summit speculation. Wait for the session outputs.
  • The list_resources() / read_resource() patterns from the OpenAI agents SDK are pre-summit — don’t build production workflows around them until you know what the post-summit spec says.

What comes after

April 4 is when the post-summit analysis starts. A few things I’ll be publishing:

  • A synthesis of what the summit’s auth sessions mean for the FastAPI + MCP auth patterns I’ve been documenting — with specific notes on whether mcp.server.auth changes require any updates to existing implementations. That one publishes April 10.
  • The Python MCP Server Templates I built for OAuth 2.1, API key, STDIO, SSE streaming, and FastAPI blueprint patterns are already available on Gumroad — those will get a post-summit review pass if the auth spec changes.

In the meantime: if you’re building with MCP and want the auth patterns to make sense before the summit, the AI Dev Toolkit has the prompts I use for designing auth flows, writing secure FastAPI middleware, and reasoning through PKCE and token introspection. That part doesn’t change regardless of what the summit announces.

If you’re planning to watch the summit remotely, the sessions to prioritize are the V2 SDK roadmap and the auth architecture block. Everything else is context. The code impact is in those two.

I’ll post a summary of what actually changed on April 4 or 5 once the recordings or transcripts are available.

I Built 99+ Free Online Developer Tools – No Installation Required

Hey everyone! 👋

I’ve been working on a project called OnlineView for the past few months, and I’m excited to finally share it with the dev community. It’s a collection of 99+ free online tools designed specifically for developers.

The Problem I Solved:

As a developer, I found myself constantly jumping between 10+ different websites to handle simple tasks:

  • Format JSON or beautify JavaScript
  • Convert images to PDF or vice versa
  • Test regex patterns
  • Check DNS records
  • Generate QR codes
  • And so many more…

I wanted ONE place where I could access all these tools without installation, registration, or bloatware.

What I Built:

OnlineView is a unified platform with tools across multiple categories:

📄 PDF Tools:

  • Edit PDFs (add text, annotations)
  • Merge multiple PDFs
  • Compress PDFs
  • Add watermarks
  • Convert PDF to images

🖼️ Image Tools:

  • Image converter (PNG, JPG, WebP, BMP)
  • Convert images to PDF
  • HEIC to JPG converter (for iPhone photos)
  • QR code generator
  • SVG to PNG converter

💻 Developer Tools:

  • JSON formatter & validator
  • JavaScript beautifier
  • SQL formatter
  • RegEx tester (with live matching)
  • PHP sandbox
  • CSS & YAML formatters
  • Markdown to HTML converter
  • Color picker (Hex, RGB, HSL)

🌐 Network Tools:

  • Check your IP address (IPv4/IPv6)
  • DNS lookup
  • Website uptime checker

🛠️ Utilities:

  • Password generator
  • Word counter (words, characters, reading time)
  • Unit converter
  • Hash generator (MD5, SHA-256, etc.)
  • Lorem Ipsum generator

Why This Approach:

✅ 100% Browser-Based – All processing happens locally on your device
✅ Privacy-First – Your data never leaves your browser or goes to any server
✅ Zero Installation – No downloads, no dependencies, no bloatware
✅ Completely Free – No premium plans, no hidden fees
✅ Fast & Lightweight – Built with vanilla JavaScript (no heavy frameworks)
✅ Mobile Friendly – Works perfectly on smartphones and tablets

Tech Stack:

  • Vanilla JavaScript (no React, Vue, or frameworks)
  • HTML5 & CSS3
  • Browser APIs (pdf-lib, pdf.js, and native Web APIs)
  • Optimized for performance

Current Status:

The site is live at onlineview.net and launching on Product Hunt tomorrow! I’m also planning to open-source the code on GitHub soon.

I’d Love Your Feedback!

  • Which tools do you find most useful?
  • What features would you like to see?
  • Any bugs or improvements you’d suggest?
  • Would you use this regularly?

Check it out: onlineview.net

Happy coding! 🚀

I Built a `cal` Endpoint Because Windows Still Doesn’t Have One

If you’ve spent any time on a Linux or macOS terminal, you’ve probably typed cal at least once. It’s one of those tiny little utilities that’s almost too simple to matter — until you’re on a Windows machine, you need a quick calendar reference, and you realize it’s just… not there.

CMD doesn’t have it. PowerShell doesn’t have it. And I’m not about to install some third-party tool just to see what day of the week the 15th falls on.

So I built my own, and I’m kind of unreasonably happy about it.

The Fix: A cURL-Accessible Calendar Endpoint

It lives at rickys.dev/calendar and works exactly the way cal does — except you hit it with cURL instead of running a local command.

curl -L rickys.dev/calendar

That gives you the current month, plain text, right in your terminal:

      March 2026
Su Mo Tu We Th Fr Sa
 1  2  3  4  5  6  7
 8  9 10 11 12 13 14
15 16 17 18 19 20 21
22 23 24 25 26 27 28
29 30 31

Today’s date is highlighted in bold cyan — same feel as cal on Linux. On Windows it renders cleanly in Windows Terminal; classic CMD may show the ANSI codes as literal text depending on your setup.

It Takes Parameters

This is where it gets a little more useful than just a party trick.

Specific month or year:

curl -L "rickys.dev/calendar?month=6&year=2026"
curl -L "rickys.dev/calendar?year=2026"

Full year view renders 3 months across, just like cal -y.

Before and after (like cal -B and -A):

curl -L "rickys.dev/calendar?before=2&after=5"

That URL shows a rolling window of months centered on today — handy when you’re planning something that spans a few months and don’t want to keep re-running the command.

Control the column width:

curl -L "rickys.dev/calendar?year=2026&column=1"
curl -L "rickys.dev/calendar?before=2&after=5&column=2"

Stacked vertically is great for narrow terminals or piping. Two across hits a nice middle ground when you want context without the full 3-wide spread.

How It Works Under the Hood

It’s a single index.php file sitting in a calendar/ folder on the server. Nothing exotic.

When a request comes in, the script checks the User-Agent header. If it sees curl, wget, or httpie, it returns Content-Type: text/plain with ANSI escape codes for the today highlight. If it sees a browser, it returns a styled HTML page with the same calendar — navigation links included, today highlighted in amber.

You can also force plain text in a browser by appending &plain to any URL, which I mostly use for testing without opening a terminal.

The month math handles year-boundary wrapping correctly, so ?before=3 in January won’t blow up — it’ll walk back into the previous year without complaint.

Try It

If you’re on Windows and want a quick cal equivalent without installing anything, bookmark this or drop an alias in your PowerShell profile:

function cal { curl.exe -L "rickys.dev/calendar/$args" }

After that, cal just works. You can even do cal '?year=2026' and the parameters pass right through.
The full source and parameter reference are on GitHub if you want to self-host it or poke around in the code.

5 Swap APIs That Support Base Chain in 2026

Base has become one of the fastest-growing Layer 2 networks since Coinbase launched it in August 2023. With over $11 billion in TVL and monthly DEX volumes regularly exceeding $20 billion, Base is now the second-largest Ethereum L2 by transaction count. For developers building trading bots, wallets, or DeFi dashboards on Base, you need a swap API that returns executable calldata for chain ID 8453. This guide compares the 5 best Base chain swap APIs available in 2026, ranked by developer experience, cost, and multi-chain flexibility.

1. Swap API (swapapi.dev)

Swap API is a free DEX aggregator API that supports Base (chain 8453) alongside 45 other EVM networks. It requires no API key, no registration, and no account creation. You send a single GET request with the chain ID, token addresses, amount, and sender, and receive a complete transaction object ready for on-chain submission.

Here is an ETH-to-USDC swap on Base:

curl "https://api.swapapi.dev/v1/swap/8453?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0x833589fCD6eDb6E08f4c7C32D4f71b54bdA02913&amount=1000000000000000000&sender=0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045"

The response includes expectedAmountOut, minAmountOut (adjusted for slippage), priceImpact, full token metadata, and a tx object with to, data, and value fields. The API handles partial fills by returning a Partial status with adjusted amounts instead of failing, and returns NoRoute when no liquidity path exists.

Key Base token addresses for Swap API:

  • ETH (native): 0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE
  • WETH: 0x4200000000000000000000000000000000000006
  • USDC (6 decimals): 0x833589fCD6eDb6E08f4c7C32D4f71b54bdA02913

Swap API also covers every other major EVM chain (Ethereum, Arbitrum, Polygon, BSC, Optimism, Avalanche) plus newer networks like Monad, MegaETH, and Berachain. The OpenAPI spec lets you generate typed clients in any language, and the Swagger UI provides interactive testing.

Best for: Developers who want the fastest Base integration with zero setup cost. Ideal for trading bots, AI agents, and multi-chain applications.

2. 1inch API

1inch is the largest DEX aggregator by market share, routing over 59% of EVM aggregator volume. It added Base support in late 2023 and provides swap, quote, and token approval endpoints for chain 8453.

The 1inch Fusion API routes trades through 400+ liquidity sources and uses its Pathfinder algorithm to split orders across pools for minimal slippage. On Base, it aggregates from major DEXs including Uniswap V3, Aerodrome, and BaseSwap.

curl -H "Authorization: Bearer YOUR_API_KEY" "https://api.1inch.dev/swap/v6.0/8453/swap?src=0xEeee...&dst=0x833589fCD6eDb6E08f4c7C32D4f71b54bdA02913&amount=1000000000000000000&from=0xYourAddress"

The trade-off is that 1inch requires registration, an API key, and adherence to rate limits that vary by pricing tier. The free tier is limited, and production usage typically requires a paid plan. Chain support covers 12 networks total.

Best for: Production applications on Base where routing optimization and deep liquidity are priorities and API key management is acceptable.

3. 0x API (Matcha)

The 0x API powers Matcha and is the swap infrastructure behind dozens of wallets and DeFi frontends. It supports Base alongside Ethereum, Polygon, Arbitrum, Optimism, BSC, and Avalanche. Its RFQ (Request for Quote) system sources liquidity from professional market makers in addition to on-chain pools.

const response = await fetch("https://api.0x.org/swap/v1/quote?buyToken=0x833589fCD6eDb6E08f4c7C32D4f71b54bdA02913&sellToken=ETH&sellAmount=1000000000000000000&chain_id=8453", {
  headers: { "0x-api-key": process.env.ZRX_API_KEY }
});

0x discontinued its free tier in 2024 and now requires an API key with paid plans for production usage. The RFQ system can offer better execution on large trades (over $10,000) by tapping institutional market makers, but adds integration complexity compared to simpler GET-based APIs.

Best for: Applications handling large trades on Base where RFQ liquidity from market makers provides better pricing than on-chain pools alone.

4. OpenOcean

OpenOcean aggregates liquidity across 30+ blockchains, including Base, and differentiates itself by supporting both EVM and non-EVM chains like Solana and Tron. The API is free to use without an API key, with reasonable rate limits.

curl "https://open-api.openocean.finance/v3/8453/swap_quote?inTokenAddress=0xEeee...&outTokenAddress=0x833589fCD6eDb6E08f4c7C32D4f71b54bdA02913&amount=1000000000000000000&gasPrice=0.001&slippage=1&account=0xYourAddress"

OpenOcean routes across 1,000+ liquidity pools and supports cross-chain swaps. The broad chain coverage makes it attractive for multi-ecosystem projects, though routing quality on individual chains like Base may not match more focused aggregators. Documentation is adequate but not as polished as 1inch or 0x.

Best for: Multi-ecosystem projects that need both EVM and non-EVM chain support from a single API provider.

5. LI.FI

LI.FI is a bridge and DEX aggregation protocol that combines cross-chain bridging with same-chain swaps. It supports Base alongside 25+ other chains, aggregating from 30+ DEXs and 20+ bridges. The API is free for standard use.

const response = await fetch("https://li.quest/v1/quote?fromChain=8453&toChain=8453&fromToken=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&toToken=0x833589fCD6eDb6E08f4c7C32D4f71b54bdA02913&fromAmount=1000000000000000000&fromAddress=0xYourAddress");

LI.FI’s strength is cross-chain swaps. You can swap ETH on Base to USDC on Arbitrum in a single API call, with the protocol handling the bridge step automatically. For same-chain swaps on Base, the extra abstraction layer adds latency compared to single-chain APIs like Swap API.

Best for: Applications where users frequently bridge assets to or from Base and you want bridge + swap unified in one API call.

Comparison Table

Feature Swap API 1inch 0x OpenOcean LI.FI
API Key Required No Yes Yes No No
Base Support Yes Yes Yes Yes Yes
Total EVM Chains 46 12 10 30+ 25+
Free Tier Unlimited Limited No Yes Yes
Cross-Chain No No No Yes Yes
Response Format Single GET REST REST REST REST + SDK
Calldata Returned Yes Yes Yes Yes Yes

Why Base Matters for Swap API Developers

Base processed over 100 million transactions in January 2026, making it one of the most active L2 networks. Its low gas fees (typically under $0.01 per swap) and deep Uniswap V3 and Aerodrome liquidity pools make it an attractive chain for automated trading strategies. The network benefits from Coinbase’s distribution, with direct fiat on-ramps from Coinbase wallets to Base, driving consistent user growth.

For developers, Base’s compatibility with standard Ethereum tooling means any swap API that supports chain ID 8453 works with the same libraries (ethers.js, viem, web3.py) you already use on Ethereum mainnet. The only difference is the chain ID and token contract addresses.

Frequently Asked Questions

What is the best free Base chain swap API?

Swap API is the best free Base chain swap API. It requires no API key, no registration, and supports Base (chain 8453) alongside 45 other EVM chains. A single GET request returns executable swap calldata that can be submitted directly on-chain.

Do I need different token addresses for Base?

Yes. Token contract addresses are chain-specific. USDC on Base (0x833589fCD6eDb6E08f4c7C32D4f71b54bdA02913) is a different contract than USDC on Ethereum (0xA0b86991c6218b36c1d19D4a2e9Eb0cE3606eB48). Always verify addresses before sending transactions. For native ETH, use 0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE on any chain.

How do I swap tokens on Base programmatically?

Use a swap API that supports Base chain ID 8453. With Swap API, send a GET request with your token pair and amount, then submit the returned transaction object using any Ethereum-compatible library. The entire flow takes 3-5 lines of code.

Is Base cheaper than Ethereum for swaps?

Significantly. Base gas fees are typically 100-1000x lower than Ethereum mainnet. A swap that costs $5-50 in gas on Ethereum usually costs less than $0.01 on Base, making it ideal for smaller trades and high-frequency strategies.

Can I do cross-chain swaps from Base?

Swap API is single-chain only, so you would need a bridge for cross-chain transactions. LI.FI and OpenOcean support cross-chain swaps that include Base as a source or destination chain. For same-chain swaps on Base, a dedicated single-chain API like Swap API will return faster results with simpler error handling.

Get Started

Swap API is free, requires no API key, and supports Base chain alongside 45 other EVM networks. Start making swap requests on Base immediately:

curl "https://api.swapapi.dev/v1/swap/8453?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0x833589fCD6eDb6E08f4c7C32D4f71b54bdA02913&amount=1000000000000000000&sender=0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045"

Explore the full OpenAPI specification to generate typed clients in TypeScript, Python, Rust, or any language. Browse the Swagger UI for interactive testing.

8 Ways to Optimize Gas Fees on Token Swaps

Gas fees are the hidden tax on every token swap. A simple ETH-to-USDC trade on Ethereum mainnet can cost $5-50 in gas depending on network congestion, while the same swap on an L2 like Arbitrum or Base costs under $0.10. For developers building trading bots, DCA tools, or wallet backends, unoptimized gas spending erodes user value on every single transaction. Across the EVM ecosystem, users paid over $1.5 billion in gas fees in 2025 on Ethereum alone. This guide covers 8 practical strategies to reduce gas costs on token swaps, with code examples using real chain data and token addresses.

1. Use L2 and Low-Fee Chains

The single biggest gas optimization is choosing the right chain. Ethereum L1 gas costs are 50-100x higher than L2 rollups for the same swap operation. A token swap that consumes ~150,000 gas units costs dramatically different amounts depending on the network.

Chain Chain ID Avg Gas Price Swap Cost (USD)
Ethereum 1 15-30 gwei $5.00 – $15.00
Polygon 137 30-80 gwei $0.01 – $0.03
Arbitrum 42161 0.1 gwei $0.03 – $0.10
Base 8453 0.005 gwei $0.01 – $0.05
Optimism 10 0.004 gwei $0.01 – $0.05
BSC 56 1-3 gwei $0.05 – $0.15
Avalanche 43114 25 nAVAX $0.02 – $0.08

If your application supports multiple chains, default users to the cheapest one where the token pair has adequate liquidity. With an API that covers 46 chains, you can query the same endpoint across all networks and let the user choose:

curl "https://api.swapapi.dev/v1/swap/8453?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0x833589fCD6eDb6E08f4c7C32D4f71b54bdA02913&amount=1000000000000000000&sender=0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045"

That request swaps 1 ETH for USDC on Base (chain 8453) for a fraction of a cent in gas. The same swap on Ethereum mainnet would cost 100x more.

2. Estimate Gas Before Submitting

Never submit a swap transaction without estimating gas first. The eth_estimateGas RPC call tells you exactly how much gas the transaction will consume before you spend anything. This prevents two costly scenarios: overpaying by setting an arbitrarily high gas limit, and losing gas entirely when a transaction reverts.

The swap API returns a gasPrice field and recommended RPCs. Use them to estimate and add a 20% buffer for complex multi-hop routes:

const quote = await fetch("https://api.swapapi.dev/v1/swap/42161?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0xaf88d065e77c8cC2239327C5EDb3A432268e5831&amount=1000000000000000000&sender=0xYOUR_ADDRESS").then(r => r.json());

const gasEstimate = await provider.estimateGas(quote.data.tx);
const gasLimit = Math.ceil(Number(gasEstimate) * 1.2);

If eth_estimateGas fails, the transaction would revert on-chain. Do not submit it. This single check saves users from burning gas on doomed transactions, which is the most wasteful type of gas spending.

3. Use Aggregators for Optimal Routing

DEX aggregators find the best route across hundreds of liquidity pools, often splitting a trade across multiple sources to minimize price impact and total cost. A direct swap on a single pool might execute at a worse price, meaning you need a larger input amount (and more gas) to get the same output.

Aggregator routing also affects gas efficiency directly. A well-optimized route through a single concentrated liquidity pool uses ~150,000 gas, while a poorly routed multi-hop swap through three pools can use 400,000+ gas. The aggregator balances price improvement against gas cost to find the optimal path.

curl "https://api.swapapi.dev/v1/swap/137?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0x3c499c542cEF5E3811e1192ce70d8cC03d5c3359&amount=500000000000000000000&sender=0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045"

This queries an aggregated swap of 500 POL to USDC on Polygon. The response includes priceImpact so you can verify the routing quality. Reject swaps with priceImpact below -0.05 (-5%) to avoid excessive slippage on low-liquidity pairs.

4. Use EIP-1559 Fee Mechanics

EIP-1559 replaced the blind gas price auction with a base fee plus priority tip model. On EIP-1559 chains (Ethereum, Arbitrum, Base, Optimism, Polygon, and most modern EVMs), using maxFeePerGas and maxPriorityFeePerGas instead of a flat gasPrice prevents overpaying during fee spikes.

The swap API returns a gasPrice field as a legacy gas price suggestion. On EIP-1559 chains, most wallet libraries (ethers.js, viem, web3.py) automatically convert to EIP-1559 parameters when you omit gasPrice from the transaction:

const tx = quote.data.tx;
await wallet.sendTransaction({ to: tx.to, data: tx.data, value: tx.value, gasLimit });

By omitting gasPrice and letting the library handle EIP-1559 fee estimation, you pay only the current base fee plus a small priority tip instead of a potentially inflated legacy gas price. During periods of high congestion followed by a sudden drop, this can save 20-40% on gas.

5. Time Your Swaps for Low Congestion

Gas prices on Ethereum and other EVM chains fluctuate significantly throughout the day. On Ethereum mainnet, gas prices during off-peak hours (weekends, early UTC mornings) can be 2-5x lower than during peak trading activity. L2s show less variation, but L1 data posting costs still fluctuate.

For non-urgent swaps in DCA bots or portfolio rebalancers, implement a gas price threshold. Fetch a quote, check the returned gasPrice, and only execute if it falls below your target:

const quote = await fetch("https://api.swapapi.dev/v1/swap/1?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0xA0b86991c6218b36c1d19D4a2e9Eb0cE3606eB48&amount=1000000000000000000&sender=0xYOUR_ADDRESS").then(r => r.json());

const gasPriceGwei = Number(quote.data.tx.gasPrice) / 1e9;
if (gasPriceGwei > 25) return;

For Ethereum mainnet swaps, targeting gas prices below 15 gwei (common on weekends and late-night UTC) can cut costs by 50% compared to executing during weekday peak hours.

6. Batch Transactions Where Possible

Every Ethereum transaction has a base overhead of 21,000 gas, regardless of what the transaction does. If your application executes multiple swaps in sequence (e.g., rebalancing a portfolio across several tokens), each swap pays that overhead separately.

Batching strategies that reduce per-swap overhead include:

  • Approval + swap in one flow: Check token allowance before fetching the swap quote. If approval is needed, submit it first and wait for confirmation, then fetch a fresh quote. The swap API calldata is time-sensitive (30-second deadline), so always re-fetch after the approval confirms rather than reusing a stale quote.

  • Multi-chain parallelism: If rebalancing across chains, fire swap quotes on all chains simultaneously. Each chain’s transaction is independent, so submit them in parallel instead of sequentially. The API supports 46 chains from the same endpoint.

  • Smart contract batching: For advanced use cases, a custom contract can execute multiple swaps atomically in a single transaction, paying the 21,000 gas overhead only once. This is particularly effective on L2s where the per-transaction overhead is a larger percentage of total cost.

7. Avoid Fee-on-Transfer (Tax) Tokens

Tax tokens (tokens with built-in transfer fees of 1-10%) create hidden gas costs beyond the tax itself. The transfer fee mechanism adds extra storage writes and event emissions to every transfer, increasing gas consumption by 30-80% compared to standard ERC-20 tokens.

Additionally, the swap API cannot account for the transfer tax in expectedAmountOut. The actual received amount will be lower than quoted. This means you may need to set higher maxSlippage to prevent reverts, which further exposes you to unfavorable execution.

When working with tax tokens, set maxSlippage higher to accommodate the fee:

curl "https://api.swapapi.dev/v1/swap/1?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0xA0b86991c6218b36c1d19D4a2e9Eb0cE3606eB48&amount=1000000000000000000&sender=0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045&maxSlippage=0.1"

Where possible, swap through standard ERC-20 tokens (USDC, USDT, DAI, WETH) as intermediaries to avoid tax token overhead on the routing path.

8. Choose the Right Chain for Each Token Pair

Not all chains price the same token pair equally. Liquidity depth, gas cost, and token decimals all vary by chain. A critical example: USDC and USDT use 6 decimals on most chains but 18 decimals on BSC. Sending the wrong amount value wastes gas on a transaction that either reverts or swaps a dust amount.

Here are the correct stablecoin addresses and decimals across major chains:

Chain USDC Decimals USDT Decimals Native Token
Ethereum (1) 6 6 ETH
Arbitrum (42161) 6 6 ETH
Base (8453) 6 6 ETH
Polygon (137) 6 6 POL
BSC (56) 18 18 BNB
Optimism (10) 6 6 ETH
Avalanche (43114) 6 6 AVAX

Swapping 100 USDC on BSC requires amount=100000000000000000000 (100 * 10^18), while on Ethereum it is amount=100000000 (100 * 10^6). Getting this wrong is a common and costly mistake.

Compare costs across chains before committing to a swap:

curl "https://api.swapapi.dev/v1/swap/56?tokenIn=0xEeeeeEeeeEeEeeEeEeEeeEEEeeeeEeeeeeeeEEeE&tokenOut=0x55d398326f99059fF775485246999027B3197955&amount=1000000000000000000&sender=0xd8dA6BF26964aF9D7eEd9e03E53415D37aA96045"

Frequently Asked Questions

How much can L2s save on gas compared to Ethereum?

L2 rollups like Arbitrum, Base, and Optimism typically reduce swap gas costs by 50-100x compared to Ethereum mainnet. A swap that costs $10 on Ethereum costs $0.05-0.10 on most L2s.

Does using an aggregator cost more gas than a direct DEX swap?

Aggregator contracts have slightly higher base gas overhead than a direct Uniswap-style router call. However, the price improvement from better routing typically more than compensates. For large trades, aggregator routing can save 1-3% on price impact, which far outweighs the extra 20,000-30,000 gas units.

How do I simulate a swap without spending gas?

Use eth_call with the transaction object returned by the API. This executes the swap against the current chain state without submitting a real transaction. If it reverts, the swap would fail on-chain. This is free and is the safest pre-flight check before committing gas.

Why does my swap revert even after gas estimation succeeds?

Swap calldata includes a deadline (typically 30 seconds). If you wait too long between fetching the quote and submitting the transaction, the deadline expires and the transaction reverts. Always re-fetch a fresh quote if more than 30 seconds have passed.

What gas buffer should I add to the estimate?

A 20% buffer (multiply eth_estimateGas result by 1.2) is recommended. Complex multi-hop routes can have variable gas consumption depending on pool state changes between estimation and execution. Unused gas is refunded, so a buffer costs nothing extra.

Get Started

Swap API is free with no API key required. It supports 46 EVM chains from a single endpoint. Fetch a quote, estimate gas, simulate with eth_call, and submit. Every strategy in this guide works with a single GET request:

GET https://api.swapapi.dev/v1/swap/{chainId}?tokenIn={address}&tokenOut={address}&amount={rawAmount}&sender={address}

Read the full API documentation to start integrating gas-optimized swaps into your application.