Most SMS APIs hide routing — I don’t

Most SMS providers hide routing.

You send a message, and something happens behind the scenes.

You don’t know:

  • which route is used
  • why delivery changes
  • how pricing is applied

That works for simple use cases.

It doesn’t if you’re building systems.

Most platforms make routing decisions for you.

In my case, I push that decision back to the developer.

You decide which route is used, not the platform.

What that looks like

from bridgexapi import BridgeXAPI

client = BridgeXAPI(api_key="YOUR_API_KEY")

client.send_sms(
    route_id=3,
    caller_id="BRIDGEXAPI",
    numbers=["31651860670"],
    message="Your verification code is 4839"
)

route_id is not just a parameter.

It represents:

  • a delivery path
  • a pricing profile
  • a reliability profile

Why this matters

If you’re building:

  • OTP systems
  • alert pipelines
  • bulk messaging

you need to control trade-offs.

Speed vs cost.

Reliability vs reach.

Most APIs remove that control.

I don’t think they should.

What I’m building

BridgeXAPI is a messaging layer where:

  • routing is explicit
  • behavior is predictable
  • nothing is hidden behind UI

Curious how others approach this.

Docs:
https://docs.bridgexapi.io

Comp the language

I’ve been brewing on ideas for a new programming language for months now. That’s nothing anybody should need to notice, I see three new language announcements a day on various Reddit channels.

Perhaps tinkering with a new language is folly; a new programming language in 2026? The dawn of AI coding is eminent, so who is looking at programming languages?

Well, I do it because it captivates me. It is my itch these days, and therefore, I scratch. Perhaps I will soon learn the reasons why more languages isn’t best languages. Perhaps this will become the new Coffeescript for Python. Perhaps this will become the new Python itself. In reality, no. This is a project by myself for myself.

So why even share? Posting and describing the language should help my organize thoughts and ideas. There’s nothing like having to explain a process to shine a flashlight on the weakest links, and potentially the greatest links.

It’s also folly to be thinking a new programming language will discover anything new or revolutionary. There are hundreds of amazing languages and libraries created by smarter people than myself. At some point additional perspectives will help, if not for the potential language, at least for my own expectations.

Project links? Example code? That must wait. For now I’ll leave the most minimal of examples behind. Details must wait for future posts.

!func greetings ~nil (
   {"USERNAME" "USER" "LOGNAME"}
   | map :($ | get-env |? skip)
   | first or="World"
   | output "Hello, %()!"
)

Agentic Shell – cli agent adaption layer

Hey folks,

TLDR: Spent the today writing an adaptation of cli-agent shell requests, having coded the same across multiple agents on several other projects and open sourced it.

So since the advent of autoresearch and, to be frank, wayyy before then, when Tyson Fury taught many of us how to use coding agents, many of us have been experimenting with ways of running coding agent harnesses in deterministic frameworks, moving beyond that of Wiggium Loop itself:

A wild wiggium appears

while true; do
    cat prompt.md | claude -p
done

As part of my own fork of autoresearch, I put a more deterministic wrapper around it, removing the ability for the agent to decide whether or not to commit, and instead having it based on the output of model training and validation phases.

I should note here that Andrej has stated he prefers to not do this with his own autoresearch, I saw a tweet on this and also heard him mention he prefers an interactive approach during his interview with Sarah Guo

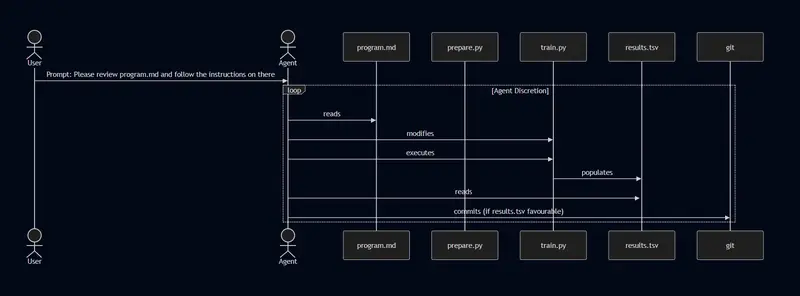
If we take a look at the autoresearch sequence:

Figure 1.1 – Autoresearch Sequence Diagram

As we can see, we are relying on the agents discretion before the loop decides to end. In addition to this, we are relying on the agent reliably determining that the results were indeed favourable.

For frontier models in a good agentic harness like Claude Code this has allowed Karpathy to run the loop for approximately 2 days, this approach as well allowed Karpathy to interact with the model during the research which might suit certain workflows.

The other thing to consider here is that with each loop, the context window grows and we see more summarisation. I have found that summarisation / compression has come a long way, I often have development sessions involving an AI that involves several compression cycles, however if this is running autonomously, then you are really at the mercy of the agentic harness compression configuration and as such you might see summarisation at a time that is not ideal.

All the above assumes frontier models, Opus 4.6 or GPT 5.4 aint cheap, and running loops 24/7 might not be within everyones budget.

This is where I have started to explore using loops with local models using OpenCode, while the constraints of these models are diminishing, I doubt I’d be able to have one run in a loop over two days just from a single prompt into OpenCode.

Instead I am looking at a pattern that combines autoresearch with ralph, but with deterministic gates and limiting the agent exposure to focused tasks within the workflow.

If we modified the approach detailed in Figure 1.1 to instead utilise a research_harness that could put some deterministic gates around the loop itself and whether the results of that loop get committed.

Figure 1.2 – Autoresearch with a deterministic harness

We could write a script that runs in a loop, passes in the prompt to a headless agent to read the prompt.md and then at the end deterministically measure the results and then programmatically commit the changes to github if they result in an improvement.

Hopefully you can see where this is heading. Not only would we be adding a bit more determinism into the workflow, we would also have the option to have this loop become effectively a ralph loop (providing we didn’t pass in a session id as part of headless call).

Across several recent projects, I have coded up several similar headless calls with differing agentic harnesses, to the point I realised it was worth my while abstracting this into a single package that I can use to handle the process.

So I’ve created a harness that allows you to call the agents headlessly and then receive responses as either an AgentResponse for synchronous calls or StreamEvent for asynchronous streaming:

u/dataclass
class AgentResponse:
    response: str
    cost: float
    session_id: str | None = None

u/dataclass
class StreamEvent:
    type: str
    content: str
    cost: float = 0.0
    duration: float = 0.0
    session_id: str | None = None

Add the PyPI package using your favourite PyPI supported package manager and then use it as such

from agent_shell.shell import AgentShell
from agent_shell.models.agent import AgentType

shell = AgentShell(agent_type=AgentType.CLAUDE_CODE)

async for event in shell.stream(
    cwd="/path/to/project",
    prompt="Refactor the auth module",
    allowed_tools=["Read", "Edit", "Bash"],
    model="sonnet",
    effort="high",
    include_thinking=True,
):
    if event.type == "system":
        print(f"Session: {event.session_id}")
    else:
        print(f"[{event.type}] {event.content}")

Given that I think this is something I think other people will probably be looking to do, I have open sourced this as a project named agent-shell on github, so feel free to use for yourselves. It has more examples around using different agent types and streaming versus non-streaming.

It currenlty supports Claude Code and OpenCode, I am going to be working on the outstanding cli agents over the coming days.

Building a 14-County Real Estate Data Pipeline with CrawlOS, Supabase, and pg_cron

OPENING PARAGRAPH:

Real estate wholesaling operates on velocity and data density—the faster you can identify distressed properties across multiple jurisdictions, the better your deal flow. At Load Bearing Capital, we integrated CrawlOS into our Supabase architecture to automate property acquisition across all 14 Houston-area counties, implementing a 17-table schema that feeds our lead scoring pipeline. This article walks through our technical implementation: designing the crawlos schema for HCAD (Harris County Appraisal District) data ingestion, deploying the lbc-hcad-actor for nightly pg_cron jobs, and optimizing our pipeline to consistently surface ~125 scored leads per run without hitting rate limits or creating infrastructure overhead.

Visual Regression Testing for Marketing Sites Without Browser Engineering

Marketing sites break visually all the time.

Not because teams are careless, but because marketing pages are where fast-moving content, reusable components, CSS changes, third-party embeds, and launch pressure all collide.

A pricing section shifts.
A CTA drops below the fold.
A testimonial block wraps badly on tablet.
A hero update looks fine in Figma, fine in code review, and wrong in the browser.

That is exactly why visual regression testing matters so much for marketing sites.

The Problem

Engineering teams usually have some level of backend testing, unit testing, or API monitoring.

But marketing pages live in a different reality:

  • lots of layout-heavy sections
  • fast iteration cycles
  • CMS-driven content changes
  • frequent A/B tests
  • embeds, forms, and scripts from third parties
  • multiple stakeholders reviewing the final output

And most visual issues are not “logic bugs.”

They are browser bugs.

The page technically works, but the rendered result is off.

Why Marketing Sites Are Hard to Protect

Marketing pages are especially vulnerable because they change often and they depend on presentation more than most product surfaces.

Common failure modes:

  • spacing regressions after a CSS refactor
  • broken card alignment
  • missing sections after conditional rendering changes
  • responsive layout drift
  • sticky bars overlapping content
  • component library updates causing subtle UI damage

These are easy to miss in code review and annoying to catch manually.

The Weak Default Workflow

A lot of teams still do visual QA like this:

  1. Open staging
  2. Open production
  3. Scroll both pages
  4. Compare them by eye
  5. Hope nothing important was missed

That works for very small sites, low release frequency, or teams with a lot of manual review time.

It does not scale well.

Especially when:

  • pages are long
  • launches are frequent
  • multiple people need approval
  • visual regressions have direct revenue impact

Why Browser Engineering Is Usually the Blocker

When teams think about automated visual regression testing, they often assume they need to build and maintain a lot of browser infrastructure:

  • Playwright or Puppeteer orchestration
  • navigation timing logic
  • cookie banner handling
  • retries and flaky waits
  • screenshot normalization
  • image diffing
  • result storage
  • reporting hooks for Slack or CI

That is where many teams stop.

Not because visual regression testing is a bad idea, but because building the pipeline feels heavier than the immediate need.

What Teams Actually Need

For a lot of marketing workflows, the need is simpler than the tooling stack suggests.

You usually want to:

  • capture the current page state
  • capture the new page state
  • compare them visually
  • highlight the changed areas
  • decide whether the release is safe

That is it.

Not full browser automation as a product.
Not a giant testing framework rollout.
Just a practical visual check that works.

A Better Approach

A useful visual regression workflow for marketing sites should give teams:

  • a before screenshot
  • an after screenshot
  • a diff image
  • a basic mismatch signal

That makes visual review faster because people stop scanning entire screenshots and start reviewing the actual delta.

This is the difference between:

“Can someone check if anything looks off?”

and:

“Here are the exact regions that changed.”

Where This Helps Most

Visual regression testing is especially useful on:

  • homepages
  • pricing pages
  • campaign landing pages
  • feature launch pages
  • signup funnels
  • CMS-driven content pages

These are the pages where visual quality matters to revenue, brand perception, and launch confidence.

Why This Matters for Non-Engineering Teams Too

One underrated part of visual diff workflows is communication.

Product, growth, and marketing teams usually do not want to review DOM diffs or implementation details.

They want to answer simple questions:

  • What changed?
  • Is the change intentional?
  • Does this look ready to ship?

A diff image is much easier to review than a technical explanation.

That makes visual regression testing useful beyond engineering.

Staging vs Production Is the Highest-Leverage Starting Point

If you want to start small, compare staging against production before a release.

That catches a surprising number of issues:

  • layout drift
  • broken responsive behavior
  • missing components
  • unintended content changes
  • visual regressions introduced during integration

You do not need to diff every page on day one.

Start with the few pages where visual mistakes cost the most.

What “Without Browser Engineering” Really Means

It does not mean browsers disappear.

It means your team does not have to own the hardest parts of browser-based screenshot infrastructure just to get visual comparison.

That is often the difference between a workflow that gets adopted and one that stays on the roadmap.

Final Thought

Marketing sites move fast, and visual quality is the product.

That makes visual regression testing one of the most practical safeguards a team can add, especially before launches and content updates.

If your current process still depends on manual side-by-side screenshot review, the real question is not whether visual regression testing is worth it.

It is whether you want to keep paying the manual review tax every time a high-visibility page changes.

If you want a deeper version of this topic, including a product-oriented perspective, you can also read:

https://snapshot-site.com/posts/visual-regression-testing-for-marketing-sites

Scaling Laravel Backends for High-Volume Systems: Lessons from Serving 100,000+ Users in Production

How I reduced API latency by 88%, achieved 99.8% uptime, and scaled a platform from 2,000 to 15,000 concurrent users — without downtime.

There is a moment every backend engineer dreads. Traffic is climbing, the monitoring dashboard is turning red, and your database is buckling under the weight of queries it was never designed to handle at this scale. I have lived through that moment more than once.

Over the past nine years, I, Olamilekan Lamidi, have built and scaled backend systems across fintech, gaming, health-tech, and logistics — platforms that collectively serve tens of thousands of users daily. This article distils the hard-earned lessons from scaling Laravel backends to handle high-volume traffic, reduce API latency, and maintain near-perfect uptime under pressure.

If you are building a Laravel application that needs to graduate from “it works” to “it works at scale,” this is for you.

The Problem: When Your Backend Becomes the Bottleneck

Most Laravel applications start life the same way: a clean MVC structure, Eloquent models that read like poetry, and Blade templates that ship fast. This works beautifully at 1,000 users. At 10,000, cracks appear. At 100,000+, the whole thing can collapse.

I encountered this problem in its most acute form while leading backend engineering at Lordwin Group, where I architected systems for an investment and hotel management platform serving over 10,000 registered users, alongside a real-time gaming backend supporting 3,000+ concurrent connections. The platform was haemorrhaging performance. API response times had crept above two seconds, database queries were timing out during peak hours, and the engineering team was firefighting daily.

The root causes were familiar to anyone who has scaled a Laravel application:

  • N+1 query explosions buried deep in nested Eloquent relationships
  • Unindexed database tables that grew silently from thousands to millions of rows
  • Monolithic request handling where every API call did too much synchronous work
  • No caching strategy — every request hit the database, every time
  • Session and queue bottlenecks running on the same infrastructure as the application

The question was not whether the system needed re-architecting. It was whether we could do it without taking the platform offline.

The Challenges: Scaling Without Breaking

Scaling a live production system is fundamentally different from building a new one. You cannot afford downtime. You cannot rewrite everything at once. And you have to keep shipping features while simultaneously rebuilding the engine underneath.

Here are the specific challenges I faced:

1. Database Performance Degradation

The MySQL database had grown to contain tables with 5+ million rows. Queries that once returned in milliseconds were now taking 3–8 seconds. Eloquent’s lazy loading was making things worse — a single API endpoint for listing investment portfolios was firing 47 database queries per request.

2. Synchronous Processing Overload

Critical operations — sending transactional emails, generating PDF reports, processing payment webhooks — were all running synchronously within the HTTP request cycle. This meant users were waiting 4–6 seconds for operations that did not need to block the response.

3. Absence of a Caching Layer

There was no Redis or Memcached layer. Configuration data, user permissions, and even static reference data were fetched from the database on every single request. During peak traffic, the database connection pool was exhausted within minutes.

4. Infrastructure That Could Not Scale Horizontally

The application was deployed on a single server with no load balancing, no auto-scaling, and no separation between the application server, queue workers, and database. Everything competed for the same CPU and memory.

The Solution: A Systematic Approach to Laravel Performance at Scale

I approached the problem methodically, treating it as four distinct engineering initiatives that could be executed incrementally without disrupting the live platform.

Phase 1: Query Optimisation and Database Restructuring

The single highest-impact change was eliminating N+1 queries and restructuring how the application interacted with the database.

Eager Loading Enforcement

I audited every Eloquent query across 15+ modules using Laravel Debugbar and Clockwork, cataloguing every N+1 violation. I then introduced eager loading constraints:

// Before: 47 queries for a portfolio listing
$portfolios = Portfolio::all();
foreach ($portfolios as $portfolio) {
    echo $portfolio->user->name;
    echo $portfolio->transactions->count();
}

// After: 3 queries with eager loading and aggregation
$portfolios = Portfolio::with(['user:id,name', 'transactions'])
    ->withCount('transactions')
    ->paginate(50);

Strategic Indexing

I analysed slow query logs and added composite indexes on columns used in WHERE, JOIN, and ORDER BY clauses. For the investment transactions table alone, adding a composite index on (user_id, status, created_at) reduced a critical query from 6.2 seconds to 180 milliseconds.

CREATE INDEX idx_transactions_user_status_date
ON transactions (user_id, status, created_at);

Query Refactoring

For complex reporting queries, I replaced Eloquent with raw SQL and database views where the ORM was generating inefficient joins. I also introduced read replicas to offload reporting queries from the primary database.

Result: Average query execution time dropped by 60%. The portfolio listing endpoint went from 2.3 seconds to 320 milliseconds.

Phase 2: Asynchronous Processing with Queue Architecture

I decoupled all non-critical work from the HTTP request cycle using Laravel’s queue system backed by Redis.

class ProcessPaymentWebhook implements ShouldQueue
{
    use Dispatchable, InteractsWithQueue, Queueable, SerializesModels;

    public int $tries = 3;
    public int $backoff = 60;

    public function handle(): void
    {
        $this->updateTransactionStatus();
        $this->notifyUser();
        $this->syncWithAccountingService();
        $this->generateReceipt();
    }

    public function failed(Throwable $exception): void
    {
        Log::critical('Payment webhook failed', [
            'transaction_id' => $this->transaction->id,
            'error' => $exception->getMessage(),
        ]);
        AlertService::notifyEngineering($exception);
    }
}

I configured dedicated queue workers for different job priorities:

  • High priority: Payment processing, authentication events
  • Medium priority: Email notifications, PDF generation
  • Low priority: Analytics aggregation, cache warming

Result: API response times for webhook endpoints dropped from 4.2 seconds to under 200 milliseconds. The user-facing experience became near-instantaneous.

Phase 3: Multi-Layer Caching Strategy

I implemented a three-tier caching architecture using Redis:

Application-Level Caching

class PermissionService
{
    public function getUserPermissions(int $userId): Collection
    {
        return Cache::tags(["user:{$userId}", 'permissions'])
            ->remember(
                "user_permissions:{$userId}",
                now()->addHours(6),
                fn () => $this->repository->getPermissionsForUser($userId)
            );
    }

    public function invalidateUserCache(int $userId): void
    {
        Cache::tags(["user:{$userId}"])->flush();
    }
}

Route-Level Caching

For endpoints serving semi-static data (e.g., hotel listings, investment product catalogues), I introduced HTTP response caching with cache invalidation tied to model events:

Route::middleware('cache.response:300')->group(function () {
    Route::get('/products', [ProductController::class, 'index']);
    Route::get('/listings', [ListingController::class, 'index']);
});

Database Query Caching

For expensive aggregation queries used in dashboards, I implemented scheduled cache warming through Laravel’s task scheduler, ensuring cached data was always fresh without burdening the database during peak hours.

Result: Database load reduced by approximately 70% during peak traffic. Redis handled 85% of read requests, and the database connection pool was no longer a bottleneck.

Phase 4: Infrastructure and Deployment Architecture

I redesigned the deployment topology to support horizontal scaling:

  • Load Balancer (Nginx) — Distributed traffic across multiple application instances
  • Separated Queue Workers — Dedicated servers for background job processing, preventing queue backlogs from impacting API response times
  • Read Replicas — Reporting and analytics queries routed to MySQL read replicas
  • Docker Containerisation — Standardised environments across development, staging, and production, eliminating “works on my machine” deployment failures
  • CI/CD Pipeline — Automated testing and zero-downtime deployments using rolling updates
services:
  app:
    build: .
    deploy:
      replicas: 3
    depends_on:
      - mysql
      - redis

  queue-worker:
    build: .
    command: php artisan queue:work redis --queue=high,medium,low
    deploy:
      replicas: 2

  scheduler:
    build: .
    command: php artisan schedule:run

  mysql:
    image: mysql:8.0
    volumes:
      - db_data:/var/lib/mysql

  redis:
    image: redis:alpine

Result: The platform could now scale horizontally by adding application instances. Deployments went from 15-minute maintenance windows to zero-downtime rolling updates.

The Results: Measurable Impact

After executing these four phases over a 10-week period, the performance transformation was significant:

Average API response time
Before: 2.3s → After: 280ms → 88% reduction

Database query execution time
Before: 1.8s avg → After: 180ms avg → 60% reduction

Payment webhook processing
Before: 4.2s → After: 190ms → 95% reduction

Database connections at peak
Before: 95% utilised → After: 30% utilised → 70% reduction

System uptime (monthly)
Before: 96.2% → After: 99.8% → 3.6% improvement

Concurrent user capacity
Before: ~2,000 → After: ~15,000 → 7.5x increase

These were not theoretical benchmarks. They were measured in production using New Relic APM and custom Prometheus dashboards over a 30-day observation period after the final deployment.

Broader Impact: Patterns That Transfer Across Industries

The architectural patterns I applied are not unique to any single domain. I have since applied the same principles across:

Fintech — At 2am Tech, I contributed to Addio, a financial platform used by 500+ organisations, where queue-based architecture and database optimisation were essential for handling high-volume transactional workflows across factors, debtors, and vendors.

Logistics — At Viaduct, I engineered a high-performance on-demand delivery platform with Laravel and Vue.js serving 5,000+ active users, where real-time order tracking demanded low-latency APIs and efficient WebSocket communication.

Enterprise SaaS — At VacancySoft, I led the refactoring of a legacy codebase across 15+ modules, migrating services to a modern architecture — cutting query execution time by 60% and improving overall system performance by 40% while handling 50,000+ daily requests.

The fundamental lesson is this: scaling is not about throwing more hardware at the problem. It is about understanding where your system spends time and eliminating waste systematically. Database queries, synchronous processing, missing caches, and monolithic deployment topologies are the four horsemen of backend performance degradation. Address them methodically, measure relentlessly, and you can scale a Laravel application to handle traffic volumes that would surprise most engineers.

Key Takeaways for Engineers Building High-Volume Systems

  1. Profile before you optimise. Use Laravel Debugbar, Clockwork, or APM tools to identify actual bottlenecks. Gut instinct is unreliable.
  2. Eliminate N+1 queries aggressively. This is almost always the single highest-impact optimisation in any Eloquent-based application.
  3. Move everything non-essential off the request cycle. If the user does not need to wait for it, it belongs in a queue.
  4. Cache strategically, invalidate precisely. A poorly invalidated cache is worse than no cache. Use tagged caching and model event listeners to keep data fresh.
  5. Design for horizontal scaling from day one. Stateless application servers, externalised sessions (Redis), and containerised deployments make scaling a configuration change rather than an architectural rewrite.
  6. Measure everything. If you cannot quantify the improvement, you cannot prove it happened. Set up monitoring before you start optimising.

Final Thoughts

Backend performance at scale is a discipline, not a one-time fix. Every system I have worked on has taught me that the architecture decisions you make early compound over time — for better or worse. The patterns described in this article have been tested in production across financial platforms, real-time gaming systems, logistics networks, and enterprise SaaS products.

If you are an engineer facing similar scaling challenges, I hope this gives you a practical roadmap. And if you have solved these problems differently, I would genuinely like to hear about it. The best engineering solutions come from sharing what we have learned.

Codacy GitLab Integration: Setup and Config Guide

Codacy screenshot

Why Integrate Codacy with GitLab

Codacy is an automated code quality and security platform that analyzes your source code for bugs, vulnerabilities, code smells, duplication, and complexity across 49 programming languages. While Codacy is often associated with GitHub workflows, it offers equally robust support for GitLab – including GitLab.com (SaaS), GitLab self-managed, and GitLab Dedicated instances. The codacy gitlab integration enables automated merge request analysis, quality gate enforcement, coverage tracking, and inline feedback without leaving the GitLab interface.

If your team uses GitLab as its primary development platform, this guide walks through every step of connecting Codacy to your GitLab instance – from OAuth setup and project import through MR analysis configuration, quality gates, coverage reporting via GitLab CI, the .codacy.yml configuration file, and troubleshooting common problems. By the end, you will have a fully working codacy gitlab setup that scans every merge request and enforces your team’s quality standards automatically.

For teams that use GitHub instead, see our Codacy GitHub integration guide. For a broader overview that covers all platforms, see how to setup Codacy.

Codacy screenshot

Prerequisites

Before starting the codacy gitlab configuration, make sure you have the following in place:

  • A GitLab account with Maintainer or Owner access to the projects you want to connect. You need these permissions because Codacy must create webhooks and post commit statuses on your project.
  • At least one GitLab project with code in a language Codacy supports. Codacy analyzes 49 programming languages including JavaScript, TypeScript, Python, Java, Go, Ruby, PHP, C#, Kotlin, Swift, Scala, and more.
  • GitLab CI/CD configured (optional but recommended) if you plan to upload code coverage reports. Codacy does not run your tests – it processes coverage reports that your pipeline generates.
  • Group Owner access if you are connecting an entire GitLab group rather than individual projects. Only group owners can authorize third-party integrations at the group level.

For GitLab self-managed instances, you also need network connectivity between your GitLab server and Codacy’s cloud servers (or a self-hosted Codacy deployment on the Business plan). The self-managed instance must be accessible via HTTPS for webhooks to work.

The integration itself takes under ten minutes. Configuring code patterns, quality gates, and coverage reporting adds another 20 to 30 minutes depending on how much customization your team needs.

Step 1 – GitLab OAuth Setup

The first step in the codacy gitlab integration is connecting your GitLab account to Codacy through OAuth. This establishes the authentication link that allows Codacy to access your projects, read code for analysis, and post results back to your merge requests.

Creating your Codacy account with GitLab

Navigate to app.codacy.com and click the sign-up button. Select Sign up with GitLab from the available provider options. GitLab will prompt you to authorize the Codacy OAuth application with the following permissions:

  • API access – allows Codacy to read repository contents, project metadata, and merge request details
  • Read user – allows Codacy to identify your GitLab user profile

Click Authorize to grant these permissions. Codacy redirects you back to its dashboard, where your account is now linked to your GitLab identity. At this point, no projects are connected yet – the OAuth flow only establishes the authentication relationship.

GitLab self-managed OAuth configuration

If you are using a self-managed GitLab instance rather than GitLab.com, the OAuth setup requires an additional step. You need to register the Codacy OAuth application on your GitLab instance:

  1. Log into your self-managed GitLab instance as an administrator
  2. Navigate to Admin Area then Applications then New Application
  3. Set the application name to “Codacy”
  4. Set the redirect URI to the callback URL provided in the Codacy documentation (typically https://app.codacy.com/auth/gitlab/callback)
  5. Select the api and read_user scopes
  6. Save the application and copy the Application ID and Secret

In Codacy, navigate to your organization settings, select Git provider, and configure the custom GitLab URL along with the Application ID and Secret from the step above. Codacy will then use your self-managed GitLab instance for OAuth authentication instead of GitLab.com.

This configuration is a one-time setup per GitLab instance. Once registered, all team members can sign up and authenticate through the same OAuth application.

Step 2 – Import GitLab Projects

After authentication, you need to add your GitLab projects to Codacy for analysis. Codacy supports importing individual projects or entire groups.

Adding a single project

From your Codacy dashboard:

  1. Click Add repository in the top navigation
  2. Codacy displays a list of GitLab projects you have access to, organized by group
  3. Select the project you want to add and click Add

Codacy immediately begins the initial analysis:

  1. Cloning – Codacy clones the project temporarily to access the source code (code is not stored permanently)
  2. Language detection – Codacy identifies the programming languages present in the project
  3. Tool selection – default analysis tools are enabled for each detected language
  4. Full scan – every file in the project is analyzed against enabled code patterns
  5. Report generation – results are compiled into the project dashboard

The initial analysis takes between 2 and 15 minutes depending on project size. For a medium-sized project with 50,000 to 100,000 lines of code, expect roughly 5 to 8 minutes.

Adding a GitLab group

If you want to analyze multiple projects within a GitLab group, you can add the entire group at once:

  1. From the Codacy dashboard, click Add organization or navigate to your organization settings
  2. Select your GitLab group from the list
  3. Choose whether to add all projects in the group or select specific ones

When you add a group, Codacy creates the necessary webhooks on each selected project automatically. New projects added to the GitLab group in the future can be added to Codacy individually – they are not automatically included unless you configure auto-import.

Understanding initial results

After the first analysis completes, your project dashboard in Codacy displays:

  • Grade – an overall letter grade from A (best) to F (worst) based on aggregated quality metrics
  • Issues – total issues found, categorized by severity (error, warning, info) and by type (security, error-prone, performance, code style, unused code)
  • Complexity – cyclomatic complexity scores at file and function level
  • Duplication – the percentage of duplicated code blocks across the project
  • Coverage – initially empty until you configure coverage reporting (covered in Step 6)

A low initial grade is common for legacy codebases. Codacy runs all default patterns on the first scan, including style rules that may not align with your team’s conventions. The next sections cover how to tune the analysis to prioritize what matters most.

Step 3 – Merge Request Analysis

The codacy gitlab mr analysis is the most valuable part of the integration. When configured, Codacy automatically analyzes every merge request and provides feedback directly in the GitLab MR interface – catching bugs, security issues, and code quality problems before they reach your main branch.

How MR analysis works

When a developer opens or updates a merge request on a connected GitLab project, the following sequence occurs:

  1. GitLab sends a webhook event to Codacy notifying it of the MR activity
  2. Codacy fetches only the files changed in the MR (not the entire project)
  3. Each changed file is analyzed against the enabled code patterns
  4. Results are compared against the target branch to distinguish new issues from existing ones
  5. Codacy posts a commit status on the MR head commit indicating pass or fail
  6. Optionally, Codacy posts a summary comment on the MR with detailed findings

MR analysis is enabled by default once you add a GitLab project to Codacy. To verify it is working, open a merge request on your connected project and look for the Codacy commit status in the MR pipeline section.

Configuring MR feedback

You can customize what Codacy reports on your merge requests:

  1. Navigate to your project in the Codacy dashboard
  2. Click Settings in the left sidebar
  3. Scroll to the Pull Requests section (the UI uses “Pull Requests” terminology even for GitLab projects)

Available options include:

  • Status check behavior – post a single combined commit status or separate statuses for issues, coverage, and duplication
  • MR comment – toggle the summary comment on or off, and configure what information it includes (new issues, fixed issues, coverage delta, complexity changes)
  • Inline annotations – add comments directly on specific lines in the MR diff where issues were found

For most teams, the default configuration provides the right level of detail. The summary comment gives reviewers a quick overview of code quality changes, while inline annotations help developers locate and fix specific issues without switching between Codacy and GitLab.

Making Codacy a required check for merge requests

To enforce quality standards and prevent MRs from being merged when they fail Codacy’s analysis, configure your GitLab project’s merge request settings:

Method 1 – Pipeline must succeed (GitLab Free and above):

  1. Go to your GitLab project Settings
  2. Navigate to Merge Requests
  3. Under Merge checks, enable Pipelines must succeed
  4. Codacy reports its commit status as part of the pipeline, so a failing Codacy check will block the merge

Method 2 – External status checks (GitLab Premium and above):

If your GitLab instance supports external status checks, you can add Codacy’s status check URL as a required external approval:

  1. Go to your GitLab project Settings
  2. Navigate to Merge Requests
  3. Under Status checks, add a new external status check pointing to the Codacy API endpoint for your project

Method 1 is sufficient for most teams. Method 2 provides more granular control and separates Codacy’s check from your CI pipeline status.

Step 4 – Quality Gates for GitLab

Quality gates define the thresholds that determine whether a merge request passes or fails Codacy’s analysis. Without properly configured quality gates, the commit status will always pass regardless of the issues found.

Configuring thresholds

Navigate to your project in the Codacy dashboard, click Quality settings in the left sidebar, and set thresholds for each metric:

Metric What It Measures Recommended Starting Threshold
New issues Number of new issues introduced by the MR 0 critical, 5 total
Coverage on new code Test coverage on new or changed lines 60%
Coverage variation Maximum allowed decrease in overall coverage -1%
Duplication on new code Percentage of duplicated blocks in new code 3%
Complexity Maximum file complexity score No threshold initially

Rollout strategy for GitLab teams

Setting quality gates too aggressively from day one causes every MR to fail, which frustrates developers and erodes trust in the tool. A more effective approach for GitLab teams:

Weeks 1 to 2: Set quality gates to advisory mode. Codacy posts results on MRs but the commit status does not block merges. Use this period to observe how your team’s MRs perform against the default thresholds and calibrate expectations.

Weeks 3 to 4: Enable blocking quality gates with achievable thresholds. Start with zero new critical issues and coverage must not decrease. These standards are realistic for most teams from day one.

Month 2 and beyond: Gradually tighten thresholds based on your team’s progress. Increase minimum coverage on new code, reduce total allowed new issues, and introduce complexity thresholds. The goal is continuous improvement, not perfection overnight.

Repository-level quality gates

In addition to MR-level gates, Codacy tracks quality at the project level. The project quality gate evaluates the overall codebase against thresholds you set for total issues, overall coverage, and duplication percentage. This is useful for tracking long-term trends and setting goals for codebase improvement sprints.

Step 5 – Configuring .codacy.yml for GitLab

The .codacy.yml file provides version-controlled configuration for your Codacy analysis. Instead of managing settings through the Codacy web UI, you define your analysis configuration in a file that lives in your repository root – making it reviewable in merge requests, consistent across branches, and part of your standard development workflow.

The .codacy.yml file works identically for GitLab and GitHub projects. If you have already configured one for a GitHub repository, the same format applies.

Basic .codacy.yml structure

Create a file named .codacy.yml in your project root:

---
engines:
  eslint:
    enabled: true
    config: .eslintrc.js
  pylint:
    enabled: true
    config: .pylintrc
  bandit:
    enabled: true
  duplication:
    enabled: true
    config:
      minimum_tokens: 50
  metrics:
    enabled: true

languages:
  javascript:
    extensions:
      - .js
      - .jsx
      - .mjs
  typescript:
    extensions:
      - .ts
      - .tsx
  python:
    extensions:
      - .py

exclude_paths:
  - "node_modules/**"
  - "dist/**"
  - "build/**"
  - "coverage/**"
  - "**/*.min.js"
  - "**/*.bundle.js"
  - "vendor/**"
  - ".gitlab/**"

Referencing existing linter configuration files

If your GitLab project already contains linter configuration files, reference them in .codacy.yml so Codacy uses your existing rules:

---
engines:
  eslint:
    enabled: true
    config: .eslintrc.json
  pylint:
    enabled: true
    config: .pylintrc
  rubocop:
    enabled: true
    config: .rubocop.yml
  checkstyle:
    enabled: true
    config: checkstyle.xml

When you specify a config path, Codacy uses your project’s linter configuration instead of its default patterns. This prevents drift between what developers see locally and what Codacy reports on merge requests.

GitLab-specific exclude paths

For GitLab projects, you may want to exclude GitLab-specific directories and files from analysis:

exclude_paths:
  - "node_modules/**"
  - "dist/**"
  - "build/**"
  - "coverage/**"
  - "**/*.min.js"
  - "vendor/**"
  - ".gitlab/**"
  - ".gitlab-ci/**"
  - "terraform/**/.terraform/**"
  - "charts/**"
  - "deploy/**"
  - "infrastructure/**/*.tfstate"
  - "**/__snapshots__/**"
  - "tests/fixtures/**"

When to use .codacy.yml vs. the UI

Use .codacy.yml when you want configuration to be version-controlled, reviewable in MRs, and consistent across branches and team members. Use the Codacy UI when you are evaluating the tool and experimenting with different settings. Note that .codacy.yml settings override UI settings when both are present for the same engine.

Step 6 – Coverage Reporting via GitLab CI

Code coverage tracking is one of the most useful features of the codacy gitlab integration. Codacy does not run your test suite – it processes coverage reports that your GitLab CI pipeline generates and displays the results alongside other quality metrics on your dashboard and in MR comments.

Generating a project API token

Before uploading coverage, you need a project-level API token from Codacy:

  1. Navigate to your project in the Codacy dashboard
  2. Click Settings in the left sidebar
  3. Find the Coverage or Integrations section
  4. Copy the Project API Token

Storing the token in GitLab CI/CD variables

  1. Go to your GitLab project Settings
  2. Navigate to CI/CD then expand the Variables section
  3. Click Add variable
  4. Set the key to CODACY_PROJECT_TOKEN
  5. Paste the token value
  6. Check Mask variable to prevent it from appearing in job logs
  7. Optionally check Protect variable to limit it to protected branches

Basic .gitlab-ci.yml coverage configuration

Here is a complete .gitlab-ci.yml example that runs tests and uploads coverage to Codacy for a Node.js project:

stages:
  - test

test:
  stage: test
  image: node:20
  script:
    - npm ci
    - npm test -- --coverage
  after_script:
    - bash <(curl -Ls https://coverage.codacy.com/get.sh) report
        -r coverage/lcov.info
        --project-token $CODACY_PROJECT_TOKEN
  artifacts:
    reports:
      coverage_report:
        coverage_format: cobertura
        path: coverage/cobertura-coverage.xml

The after_script section ensures the coverage upload runs even if the test step fails with non-zero exit code. The artifacts section is optional but useful if you also want GitLab’s built-in coverage visualization in MR diffs.

Python project coverage with GitLab CI

stages:
  - test

test:
  stage: test
  image: python:3.12
  script:
    - pip install -r requirements.txt pytest pytest-cov
    - pytest --cov=src --cov-report=xml:coverage.xml
  after_script:
    - bash <(curl -Ls https://coverage.codacy.com/get.sh) report
        -r coverage.xml
        --project-token $CODACY_PROJECT_TOKEN
  artifacts:
    reports:
      coverage_report:
        coverage_format: cobertura
        path: coverage.xml

Java project coverage with GitLab CI

stages:
  - test

test:
  stage: test
  image: maven:3.9-eclipse-temurin-21
  script:
    - mvn clean test jacoco:report
  after_script:
    - bash <(curl -Ls https://coverage.codacy.com/get.sh) report
        -r target/site/jacoco/jacoco.xml
        --project-token $CODACY_PROJECT_TOKEN
  artifacts:
    reports:
      coverage_report:
        coverage_format: cobertura
        path: target/site/jacoco/jacoco.xml

Uploading coverage for monorepos

If your GitLab project is a monorepo with multiple services or components, upload partial coverage reports and finalize them:

stages:
  - test
  - coverage

test-frontend:
  stage: test
  image: node:20
  script:
    - cd frontend && npm ci && npm test -- --coverage
  after_script:
    - bash <(curl -Ls https://coverage.codacy.com/get.sh) report
        -r frontend/coverage/lcov.info
        --partial
        --project-token $CODACY_PROJECT_TOKEN

test-backend:
  stage: test
  image: python:3.12
  script:
    - cd backend && pip install -r requirements.txt && pytest --cov=src --cov-report=xml:coverage.xml
  after_script:
    - bash <(curl -Ls https://coverage.codacy.com/get.sh) report
        -r backend/coverage.xml
        --partial
        --project-token $CODACY_PROJECT_TOKEN

finalize-coverage:
  stage: coverage
  image: alpine:latest
  needs:
    - test-frontend
    - test-backend
  script:
    - apk add --no-cache bash curl
    - bash <(curl -Ls https://coverage.codacy.com/get.sh) final
        --project-token $CODACY_PROJECT_TOKEN

The finalize-coverage job runs after all test jobs complete and signals to Codacy that all partial reports have been uploaded. Codacy then aggregates the results into a single coverage view.

Handling commit SHA mismatches

Codacy matches coverage reports to specific commits. In GitLab CI, the CI_COMMIT_SHA variable usually matches the MR head commit, but in some pipeline configurations (especially merge result pipelines), the SHA may differ. If coverage is not appearing on your MRs, explicitly pass the commit SHA:

after_script:
  - bash <(curl -Ls https://coverage.codacy.com/get.sh) report
      -r coverage/lcov.info
      --commit-uuid $CI_COMMIT_SHA
      --project-token $CODACY_PROJECT_TOKEN

For merge result pipelines where the SHA represents a merged result rather than the MR head, use the CI_MERGE_REQUEST_SOURCE_BRANCH_SHA variable instead:

after_script:
  - bash <(curl -Ls https://coverage.codacy.com/get.sh) report
      -r coverage/lcov.info
      --commit-uuid ${CI_MERGE_REQUEST_SOURCE_BRANCH_SHA:-$CI_COMMIT_SHA}
      --project-token $CODACY_PROJECT_TOKEN

Step 7 – Running Codacy Analysis in GitLab CI

While Codacy’s webhook-based analysis handles most use cases, you can also run Codacy analysis directly inside your GitLab CI pipeline for tighter control over when and how analysis executes.

Using the Codacy Analysis CLI in GitLab CI

Add a dedicated analysis job to your .gitlab-ci.yml:

codacy-analysis:
  stage: test
  image:
    name: codacy/codacy-analysis-cli:latest
    entrypoint: [""]
  script:
    - /opt/codacy/bin/codacy-analysis-cli analyze
        --project-token $CODACY_PROJECT_TOKEN
        --upload
        --max-allowed-issues 0
        --fail-if-incomplete
  allow_failure: false

This approach runs the analysis inside your pipeline rather than relying on webhooks. The benefits include:

  • Analysis runs as a visible pipeline job with logs accessible in GitLab
  • You can control the analysis CLI version through the Docker image tag
  • Pipeline status directly reflects Codacy results without needing external status checks
  • Analysis runs in your infrastructure, which can be important for self-managed GitLab instances with network restrictions

The trade-off is that you manage the analysis job configuration yourself, and the CLI may not support every feature available through the webhook-based analysis (such as the AI Reviewer).

Combining webhook analysis with CI-based coverage

The most common codacy gitlab ci setup uses webhook-based analysis for code quality scanning and CI-based jobs for coverage uploads. This gives you the best of both approaches:

stages:
  - test
  - quality

test:
  stage: test
  image: node:20
  script:
    - npm ci
    - npm test -- --coverage
  after_script:
    - bash <(curl -Ls https://coverage.codacy.com/get.sh) report
        -r coverage/lcov.info
        --project-token $CODACY_PROJECT_TOKEN
  artifacts:
    reports:
      coverage_report:
        coverage_format: cobertura
        path: coverage/cobertura-coverage.xml

In this setup, Codacy’s webhook handles static analysis (code patterns, security scanning, duplication) while the GitLab CI job handles coverage generation and upload. Both sets of results appear on the same Codacy dashboard and contribute to the MR quality gate status.

Step 8 – Webhook Configuration and Management

The codacy gitlab webhook is the mechanism that triggers analysis whenever code changes occur. Understanding how webhooks work helps you diagnose issues and optimize the integration.

How Codacy webhooks work with GitLab

When you add a GitLab project to Codacy, it automatically creates a webhook on the project with the following event triggers:

  • Push events – triggers analysis of pushed commits on your default branch and other tracked branches
  • Merge request events – triggers MR analysis when an MR is opened, updated, or reopened
  • Tag push events – optional, used for tracking analysis on tagged releases

The webhook URL points to Codacy’s API endpoint, and the secret token is generated automatically during setup. You do not need to configure the webhook manually unless troubleshooting a broken integration.

Verifying webhook status

To check if webhooks are working correctly:

  1. Go to your GitLab project Settings
  2. Navigate to Webhooks
  3. Find the Codacy webhook in the list
  4. Click Edit to see the configuration details
  5. Scroll down to Recent events to see delivery history

Each delivery shows the HTTP status code, response time, and payload. Successful deliveries return a 200 status code. If you see 4xx or 5xx errors, the most common causes are:

  • 401 Unauthorized – the webhook secret has expired or the integration token needs re-authorization
  • 404 Not Found – the project was removed from Codacy but the webhook was not cleaned up
  • 500 Internal Server Error – a temporary Codacy service issue; check status.codacy.com
  • Connection refused – network connectivity issue between GitLab and Codacy (common with self-managed GitLab behind a firewall)

Re-creating webhooks

If a webhook is missing or broken, the simplest fix is to remove the project from Codacy and re-add it:

  1. In the Codacy dashboard, navigate to your project
  2. Go to Settings and click Remove project
  3. Re-add the project from the dashboard
  4. Codacy will create fresh webhooks and run a new initial analysis

Your configuration history (code patterns, quality gates) is not preserved when you remove and re-add a project, so make sure any custom configuration is captured in your .codacy.yml file before removing.

Troubleshooting Common Issues

Even with a straightforward setup, you may encounter issues with the codacy gitlab integration. Here are the most common problems and their solutions.

Codacy is not analyzing merge requests

Check webhook delivery. Go to your GitLab project Settings, click Webhooks, find the Codacy webhook, and check Recent events. If deliveries are failing, the webhook URL or secret may be invalid. Remove and re-add the project in Codacy to regenerate the webhook.

Verify OAuth permissions. If you recently changed your GitLab password or revoked OAuth tokens, Codacy may have lost access. Go to your GitLab profile settings, navigate to Applications, and verify the Codacy OAuth application is still authorized. If not, re-authorize by logging into Codacy again with your GitLab credentials.

Check project status in Codacy. Navigate to the project in your Codacy dashboard and look at the status indicator. If analysis is paused, click to resume it. If the status shows an error, the message will indicate the cause – most commonly a missing or expired integration token.

Verify branch configuration. Codacy analyzes the default branch and any branches with open MRs. If your MR targets a branch that is not configured in Codacy, the analysis may not trigger. Check the branch settings in the Codacy project configuration.

Coverage is not appearing on merge requests

Verify the upload succeeded. Check your GitLab CI job logs for the Codacy Coverage Reporter output. A successful upload prints a confirmation message with the commit SHA and project identifier. If the upload fails, the most common causes are an incorrect project token or a malformed coverage report.

Check the CI/CD variable. Verify that CODACY_PROJECT_TOKEN is set correctly as a GitLab CI/CD variable. If the variable is set as “protected,” it will only be available on protected branches – MR source branches are typically not protected, so the upload will fail silently.

Review the commit SHA. If you are using merge result pipelines in GitLab, the commit SHA in the pipeline may not match the MR head commit. Use the CI_MERGE_REQUEST_SOURCE_BRANCH_SHA variable as described in Step 6 to ensure the coverage report is attributed to the correct commit.

Check the coverage report format. Codacy supports LCOV, Cobertura XML, JaCoCo, Clover, and OpenCover formats. If your report is in a different format or is malformed (empty, truncated, or contains invalid XML), the upload may succeed but Codacy will not process it. Validate your coverage report locally before uploading.

Commit status is stuck in pending

This usually means Codacy received the webhook but has not completed the analysis. Common causes include temporary Codacy service delays (check status.codacy.com), very large MRs with thousands of changed files, or rate limiting when many MRs are opened concurrently. Wait 10 to 15 minutes and check again. If the status remains pending, try pushing an empty commit to the MR branch to trigger a fresh webhook event.

Analysis is running but finding no issues

Verify the correct tools are enabled. Navigate to Code patterns in the Codacy dashboard and confirm that analysis tools for your project’s languages are toggled on. If you recently added a .codacy.yml file that disables certain engines, the UI-based configuration is overridden.

Check language detection. Codacy automatically detects languages based on file extensions. If your project uses non-standard file extensions, add them to the languages section of your .codacy.yml file.

Review exclusion patterns. Overly broad exclusion patterns in .codacy.yml or the Codacy UI may exclude files you intended to analyze. Verify that your exclude_paths do not match application code directories.

Self-managed GitLab connectivity issues

Verify HTTPS accessibility. Codacy’s cloud servers need to reach your self-managed GitLab instance via HTTPS to clone repositories and receive webhook deliveries. Ensure your GitLab instance is not behind a firewall that blocks inbound connections from Codacy’s IP ranges.

Check SSL certificates. If your self-managed GitLab uses a self-signed SSL certificate, Codacy may reject the connection. You need either a certificate from a trusted CA or to configure Codacy’s self-hosted deployment to trust your custom CA.

Consider self-hosted Codacy. For self-managed GitLab instances that cannot be exposed to the public internet, the Codacy Business plan offers self-hosted deployment that runs entirely within your infrastructure. This eliminates network connectivity concerns but requires managing the Codacy infrastructure yourself.

Alternatives to Codacy for GitLab Integration

While Codacy provides solid GitLab integration, several alternatives offer different strengths for GitLab-based teams. If the codacy gitlab integration does not fully meet your needs, here are options worth considering.

CodeAnt AI

CodeAnt AI is a Y Combinator-backed platform that combines AI-powered code reviews, SAST, secrets detection, IaC security scanning, and DORA metrics in a single tool. It provides native GitLab support with line-by-line MR feedback, auto-generated MR summaries, and one-click auto-fix suggestions across 30+ languages.

CodeAnt AI is priced at $24/user/month for the Basic plan (AI code reviews, summaries, and auto-fix) and $40/user/month for Premium (adds SAST, secrets detection, IaC scanning, DORA metrics, and SOC 2/HIPAA audit reports). For GitLab teams that want both AI-powered code review and security scanning in a single integration, CodeAnt AI is a strong contender – especially for teams in regulated industries that need compliance reporting alongside code quality enforcement.

Compared to Codacy, CodeAnt AI offers more advanced AI review capabilities with contextual feedback that considers MR descriptions and linked issues. The trade-off is that it supports fewer languages (30+ versus Codacy’s 49) and is a newer platform with a smaller user base. However, for GitLab-centric teams, CodeAnt AI’s native GitLab integration feels more tightly integrated than Codacy’s GitLab support in some areas.

Other alternatives

For a comprehensive comparison of tools that can replace or complement Codacy on GitLab, see our Codacy alternatives guide. If pricing is a key factor, our Codacy pricing breakdown compares costs across different team sizes. And for an honest assessment of the platform’s overall strengths and weaknesses, see our Codacy review.

Best Practices for Codacy on GitLab

After completing the initial codacy gitlab setup, following these practices will help you get the most value from the integration over time.

Keep .codacy.yml in sync with local linters. If your team updates ESLint, Pylint, or other linter configurations locally, make sure Codacy is set to use your repository’s config file rather than its own defaults. Enable the “Use the configuration file in my repository” toggle in Code patterns for each relevant tool. This prevents discrepancies between what developers see locally and what Codacy reports on MRs.

Review quality gate thresholds quarterly. As your codebase improves, tighten the thresholds to maintain forward pressure. If coverage started at 35% when you onboarded Codacy and has risen to 50%, update the minimum coverage threshold to 45% so it continues to be meaningful.

Use GitLab CI/CD variables for all tokens. Never hardcode your CODACY_PROJECT_TOKEN in .gitlab-ci.yml or any committed file. Always use masked CI/CD variables. If you need the token in multiple projects, consider using GitLab group-level CI/CD variables to avoid duplicating the configuration.

Monitor the Codacy status page. Codacy occasionally experiences service disruptions that affect analysis processing. Check status.codacy.com if analyses are taking unusually long or MR statuses are stuck in pending. Subscribing to status updates ensures you are notified of outages proactively.

Assign weekly triage rotation. Designate a rotating team member each week to review new Codacy findings, dismiss false positives with documented reasons, and adjust code patterns when rules consistently produce unhelpful feedback. This prevents issue backlogs from accumulating and keeps the analysis results relevant.

Conclusion

The codacy gitlab integration provides a comprehensive automated code quality pipeline for GitLab teams – scanning every merge request for bugs, security vulnerabilities, code smells, duplication, and coverage regressions. The setup process involves connecting your GitLab account via OAuth, importing your projects, configuring code patterns to match your team’s standards, setting quality gates with realistic thresholds, and uploading coverage reports from GitLab CI.

The most impactful configuration decisions are enabling “Pipelines must succeed” in your GitLab merge request settings so Codacy checks actually block merges, using your repository’s existing linter configuration files through the .codacy.yml file, and starting with achievable quality gate thresholds that you tighten over time. These choices determine whether Codacy becomes a valuable part of your daily development workflow or just another dashboard that the team learns to ignore.

For teams that want a deeper dive into Codacy configuration beyond the GitLab-specific steps, our how to setup Codacy guide covers additional topics including team management, advanced analysis options, and long-term maintenance best practices. For a comparison with the GitHub integration, see our Codacy GitHub integration guide. And if you are still evaluating whether Codacy is the right tool, our Codacy review and Codacy alternatives guides provide balanced assessments.

Further Reading

Frequently Asked Questions

How do I integrate Codacy with GitLab?

Go to app.codacy.com and click Sign up with GitLab. Authorize the Codacy OAuth application to access your GitLab account. Once logged in, add your GitLab group or project from the Codacy dashboard. Codacy creates webhooks on your GitLab project automatically and begins analyzing your default branch within minutes. Merge request analysis starts working on the next MR you open.

Does Codacy support GitLab self-managed instances?

Yes, Codacy supports both GitLab.com (SaaS) and GitLab self-managed instances. For self-managed GitLab, you need to configure a custom GitLab URL during Codacy setup and ensure your GitLab instance is network-accessible from Codacy’s servers. Self-managed GitLab integration requires the Codacy Business plan if you also want self-hosted Codacy deployment behind your firewall.

How does Codacy analyze GitLab merge requests?

When you open or update a merge request, GitLab sends a webhook event to Codacy. Codacy fetches only the changed files, analyzes them against your enabled code patterns, and compares results to the target branch to identify new issues. It then posts a commit status on the MR (pass or fail based on quality gates) and optionally adds a summary comment with findings, coverage changes, and complexity metrics.

How do I upload code coverage from GitLab CI to Codacy?

Add a step in your .gitlab-ci.yml that runs the Codacy Coverage Reporter after your test suite generates a coverage report. Store your CODACY_PROJECT_TOKEN as a GitLab CI/CD variable. Use the bash script or the standalone binary to upload LCOV, Cobertura, JaCoCo, or Clover format reports. Codacy then displays coverage data on the dashboard and includes coverage deltas in MR analysis.

How do I configure .codacy.yml for a GitLab project?

Create a .codacy.yml file in your repository root. Define which analysis engines to enable, reference existing linter configuration files, set language extensions, and list file paths to exclude. The file works identically for GitLab and GitHub projects. When Codacy detects this file during analysis, it overrides the UI-based configuration for any engines defined in the YAML.

Can I run Codacy analysis inside GitLab CI pipelines?

Yes, you can run the Codacy Analysis CLI as a GitLab CI job. Add a job that pulls the codacy-analysis-cli Docker image and runs it against your repository. This gives you full control over when analysis runs and lets you integrate Codacy results directly into your GitLab pipeline status. You need a CODACY_PROJECT_TOKEN stored as a CI/CD variable for authentication.

How do I make Codacy a required check for GitLab merge requests?

Codacy posts commit statuses to your GitLab MR. To make this a required check, go to your GitLab project settings, navigate to Merge Requests, and enable Pipelines must succeed under Merge checks. If you use external status checks (GitLab Premium), you can add the Codacy status check URL directly as a required external approval.

Why is Codacy not analyzing my GitLab merge requests?

The most common causes are: the webhook was not created properly during project setup, the GitLab OAuth token has expired and needs re-authorization, the project is not added or is paused in the Codacy dashboard, or the Codacy integration does not have sufficient permissions on the GitLab project. Check the webhook status in your GitLab project settings under Webhooks and verify recent deliveries.

How do I fix webhook issues between Codacy and GitLab?

Navigate to your GitLab project Settings, click Webhooks, and find the Codacy webhook URL. Check the Recent events section for failed deliveries. If the webhook is missing, remove and re-add the project in Codacy to regenerate it. If deliveries are failing with 4xx or 5xx errors, verify that your GitLab instance can reach Codacy’s servers and that the integration token has not expired.

Does Codacy work with GitLab CI/CD for monorepos?

Yes. You can upload partial coverage reports for each component or service in your monorepo and then send a final request to aggregate them. Use the –partial flag on each upload and a final command to signal completion. The .codacy.yml exclude_paths setting lets you scope analysis to specific directories within the monorepo.

What GitLab permissions does Codacy need?

Codacy requires API scope access through its OAuth application on GitLab. This grants read access to project metadata, repository contents, and merge requests, plus write access to commit statuses and MR comments. For GitLab self-managed, you also need to ensure the OAuth application is registered in your GitLab admin settings with the correct callback URL.

How long does Codacy take to analyze a GitLab merge request?

Codacy typically analyzes merge requests in 1 to 3 minutes because it only scans changed files rather than the full repository. The initial full repository analysis after adding a project takes 2 to 15 minutes depending on codebase size and the number of languages detected. Very large repositories with hundreds of thousands of lines may take longer on the first scan.

Originally published at aicodereview.cc

I Analyzed Glassdoor Data for 45 AI Companies — Here’s What I Found

I spent the last few months building a database of culture data for every major AI company — Glassdoor ratings, work-life balance scores, culture values, and real employee reviews. The dataset now covers 45 companies and 7,100+ open roles.

Some of the findings genuinely surprised me. Here’s what the data says.

For each of the 45 companies, I collected:
• Glassdoor overall rating (1-5 scale, verified review count)
• Work-life balance score (1-5 scale, from Glassdoor sub-ratings)
• Culture values — tagged from careers pages, engineering blogs, and reviews (remote, async, flat, ship-fast, deep-work, etc.)
• Employee review themes — recurring pros/cons from Glassdoor and Blind
• Open roles — fetched live from ATS APIs (Greenhouse, Ashby, Lever, Workable)

This isn’t a survey. It’s structured data pulled from real sources, updated daily.

Top 10 AI Companies by Glassdoor Rating

Company           Glassdoor   WLB Score   Size     Open Roles
-----------------------------------------------------------
Vast AI           5.0         4.5         ~30      10
Supabase          4.8         3.0         ~250     37
Perplexity AI     4.7         3.3         ~500     79
Linear            4.6         4.4         ~80      19
LangChain         4.6         4.0         ~230     95
Plaid             4.6         4.2         ~800     100
Runway            4.5         4.0         ~420     35
OpenAI            4.5         3.6         ~3,500   661
incident.io       4.5         4.1         ~140     27
Anthropic         4.4         3.7         ~1,500   446

Look at the WLB column. The highest-rated companies don’t necessarily have the best work-life balance. That’s the first surprise.

The Supabase Paradox: 4.8 Rating, 3.0 WLB

Supabase has the second-highest Glassdoor rating in the entire dataset — but the lowest work-life balance score among top-rated companies at 3.0/5.0. And yet: 100% of Glassdoor reviewers recommend it to a friend.

How? Self-selection. The people who join Supabase want intensity. They run “launch weeks” — concentrated shipping sprints where major features get announced daily. It’s exhausting. It’s also the reason many engineers joined.

One employee review captures it: “Heavy focus on launch weeks versus fundamentals of reliability and automation.”

Supabase isn’t a company where people tolerate the pace despite hating it. They love it because of the intensity. The 3.0 WLB score is a self-aware acknowledgment, not a red flag.

Figma: The Brand vs The Reality

Figma’s product is universally beloved. The engineering is genuinely world-class — WebAssembly canvas rendering, CRDT-inspired multiplayer, C++ compiled to WASM.

But the Glassdoor data tells a different story: 3.7/5.0 overall, 3.1 WLB, only 64% recommend.

Anonymous reviews from Blind are more blunt:
• “WLB is 996 on a lot of teams” (referring to 9am-9pm, 6 days/week)
• “Had 5 different managers in 2 years”
• “Could put your 120% in and work 60 hours and get a meets expectations”

The gap between Figma’s external brand (playful, inclusive, creative) and anonymous employee reviews (burnout, fear culture, manager churn) is the biggest disconnect in the dataset.

*Companies Where WLB Actually Matches The Rating
*

These companies scored high on both Glassdoor rating AND work-life balance:

Company Glassdoor WLB What Makes Them Different
PostHog 4.3 4.5 No meetings, no deadlines, autonomous 2-person teams
Tailscale 4.4 4.5 Same pay worldwide, 26 weeks parental leave
Linear 4.6 4.4 80-person team, opinionated product culture
Weaviate 4.3 4.2 Fully async, flat hierarchy, open source
Pinecone 4.2 4.3 Fully remote, flexible hours
Notion 4.4 4.2 Product-first culture, strong design DNA

PostHog is the standout. Their handbook is public. They don’t have standup meetings. Engineers work in autonomous 2-3 person “small teams” with no deadlines. It reads like it shouldn’t work — but 4.3 Glassdoor and 4.5 WLB says it does.

The Worst WLB in AI

These companies scored below 3.5 on work-life balance:

Company Glassdoor WLB Why
Scale AI 3.5 2.7 “Extremely long hours are the norm”
Supabase 4.8 3.0 Launch week intensity (by choice)
Figma 3.7 3.1 Post-IPO pressure + manager churn
CoreWeave 3.6 3.2 GPU infrastructure scaling at breakneck speed
Perplexity AI 4.7 3.3 Startup pace with moonshot ambitions
Fireworks AI 4.2 3.3 Small team, huge technical scope
Vercel 3.9 3.4 “Ship or die” culture

Scale AI at 2.7 WLB is the lowest in the dataset — and it shows in their 3.5 Glassdoor rating. Unlike Supabase, where people choose intensity, Scale AI reviews suggest the pace is imposed rather than embraced.

Culture Values That Predict Satisfaction

This is where it gets interesting. I tagged each company with culture values and looked at averages:

Culture Value Avg Glassdoor Avg WLB # Companies
Async Communication 4.36 4.04 5
Flat Hierarchy 4.23 3.89 14
Remote-First 4.23 3.98 17
Ship Fast 4.15 3.62 27

The pattern: companies that value async communication and flat hierarchy consistently score higher on both satisfaction and WLB. Companies that prioritize “ship fast” have higher overall ratings but notably worse WLB.

Remote-first companies average 4.23 Glassdoor vs 4.11 for non-remote — a meaningful gap across 45 companies. The WLB difference is even larger: 3.98 vs 3.69.

Hidden Gems Most Engineers Haven’t Heard Of

If you’re only looking at Anthropic, OpenAI, and Google, you’re missing some of the best cultures in AI:

incident.io — 4.5 Glassdoor, 4.1 WLB. Incident response platform out of London. 13 extra holidays per year, 10% pension match, ego-free founders. All ex-Monzo engineers. 27 open roles.

Weaviate — 4.3 Glassdoor, 4.2 WLB. Open-source vector database. Fully async, flat hierarchy, distributed across Europe. Same pay regardless of location. Only 5 jobs open — they’re tiny and selective.

Modal — 4.0 Glassdoor, 3.8 WLB. Cloud infrastructure for AI. Founded by Erik Bernhardsson (ex-Spotify, built Luigi). 50x revenue growth. 27 open roles. If you want to work with elite systems engineers, this is it.

Baseten — 4.3 Glassdoor, 3.5 WLB. ML inference infrastructure. Small team (48 jobs), YC-backed, working on genuinely hard serving problems. Lower WLB but strong ratings suggest people are there by choice.

What I’d Tell Someone Evaluating an AI Company Offer

After building this dataset, here’s my framework:
1. Check the WLB score, not just the overall rating. Supabase has 4.8 overall but 3.0 WLB. That’s a company where people love the mission but acknowledge the cost. Know what you’re signing up for.
2. Look for the async/flat signal. Companies with these values consistently deliver better experiences. It’s not a coincidence.
3. Be skeptical of high ratings with few reviews. Vast AI has a perfect 5.0 — but with very few reviews. Linear at 4.6 is more statistically meaningful.
4. Read the Blind reviews, not just Glassdoor. Glassdoor reviews skew positive (companies sometimes encourage happy employees to review). Blind is anonymous and unfiltered. The delta between the two tells you a lot.
5. The “recommend to friend” percentage matters more than the overall score. Figma has a respectable 3.7 Glassdoor but only 64% recommend. Supabase has a lower WLB but 100% recommend. The recommend percentage captures something the aggregate score misses.

The Full Data

I’ve built all of this into an interactive tool where you can:
• Browse all 45 companies with ratings, values, and reviews: https://jobsbyculture.com/directory
• Compare any two companies side-by-side: https://jobsbyculture.com/compare
• Filter 7,100+ jobs by culture values like remote, async, flat hierarchy, deep work: https://jobsbyculture.com/jobs

The data updates daily from live ATS APIs. Happy to answer if you have any questions in the comments.

Building a Project Risk Engine on Top of Notion MCP

This is a submission for the Notion MCP Challenge

What I Built

Risk Radar reads your Notion project databases, builds a dependency graph in memory, and writes risk reports back to Notion. It finds critical paths, single points of failure, and cascade risks that project managers usually track in their heads (or don’t track at all).

The part I’m most proud of: when a task is overdue, the agent walks the dependency graph and pushes every downstream deadline forward through notion-update-page. Mark one task late, run the scan, and watch 8 dates shift in Notion automatically.

Everything goes through Notion’s MCP server. No direct API calls. Notion is the entire data layer.

Video Demo

Show us the code

🎯 Risk Radar — Dependency & Risk Intelligence for Notion

Built for the Notion MCP Hackathon — zero direct API calls, 100% MCP.

The Problem

Project managers track risks mentally but never systematically. When a task slips, nobody knows which 8 downstream tasks just broke their deadlines. Single points of failure hide in plain sight — one person quietly blocking an entire workstream. By the time anyone notices, the cascade has already happened.

The Solution

Risk Radar reads your Notion project databases, builds a dependency graph, and surfaces risks that humans miss. It writes actionable risk reports back to Notion and automatically propagates deadline changes through the dependency chain.

Mark one task late → watch 8 downstream dates shift automatically.

Everything runs through the Model Context Protocol (MCP) — zero direct Notion API calls.

How It Works

  1. Read — Fetches all projects and tasks from Notion via MCP, including dependency…

How I Used Notion MCP

Reading a dependency graph through MCP

The Tasks database has a self-referencing “Depends On” relation. Reading this through MCP takes three steps per task: fetch the database to get the data source URL, search to get page IDs, then fetch each page individually to get its properties.

The properties come back inside a <properties> XML block as JSON. Relation fields like “Depends On” and “Project” are arrays of Notion page URLs. So building the graph means parsing URLs like https://www.notion.so/abc123def456, stripping the prefix and dashes, and using the normalized ID as the graph node key. Without that normalization step, every dependency lookup fails silently and you get an empty graph. That bug cost me an hour.

The graph algorithms

Once the tasks are in memory with their dependencies resolved to names, the risk engine runs four analyses:

Critical path uses DFS with memoization from root tasks (tasks with no upstream dependencies). It finds the longest chain through the dependency graph. This tells you which sequence of tasks has zero slack — if any of them slip, the project end date moves.

Single point of failure detection does a recursive downstream traversal per task owner. If one person’s incomplete tasks collectively block two or more downstream tasks, they’re flagged. This catches the scenario where one engineer is quietly blocking an entire workstream.

At-risk detection is simpler: compare each task’s deadline to today. Overdue tasks, tasks due within 3 days that haven’t started, and tasks due tomorrow that are still in progress all get flagged.

Cascade impact runs BFS from each at-risk task to enumerate every downstream task that would be affected by a slip.

The risk score combines these: overdue_ratio × 40 + spof_penalty (capped at 30) + cascade_penalty (capped at 30). It’s a rough heuristic, but it produces scores that feel right. A project with one overdue task and no dependencies scores low. A project with an overdue task that blocks 5 others through a single owner scores high.

Writing reports and cascading deadlines

The risk report is a Markdown page created with notion-create-pages. It includes the risk score with an emoji indicator (🔴/🟡/🟢), the critical path, at-risk tasks with reasons, SPOFs with the tasks they’re blocking, and cascade impact chains. A separate Health History entry logs the score with a date for trend tracking.

The cascade feature is the most interesting MCP interaction. When the scan finds an overdue task, it calculates the slip in days, then does a BFS through the dependency graph. For each downstream task that isn’t done, it calls notion-update-page with the new deadline using the "date:Deadline:start" property format. A 5-task cascade means 5 sequential MCP update calls. Each one shifts a real deadline in Notion.

What surprised me about Notion MCP

The notion-search results don’t include full properties. You get page IDs and titles, but to read “Depends On” or “Deadline” you need a separate notion-fetch per page. For 8 tasks across 3 projects, that’s about 25 MCP calls just to read the data. It works, but it means the agent is I/O bound rather than compute bound. The graph algorithms themselves run in microseconds. The MCP calls take seconds.

The other surprise was date properties. Setting a date requires two properties: "date:Deadline:start" for the value and "date:Deadline:is_datetime": 0 to indicate it’s a date-only field. Missing the second one doesn’t error, but the date renders differently in Notion.

Linear vs Jira vs Asana for AI Agents — AN Score Comparison

The short answer

Linear wins on API ergonomics — GraphQL-native, typed responses, minimal auth friction.
Jira wins on enterprise depth — audit trails, SAML, and the Atlassian ecosystem.
Asana splits the difference with a clean REST API and cross-functional flexibility.

Tight race

All three score within 0.5 points — Linear at 7.5, Jira at 7.2, Asana at 7.0. The right choice depends on your organization’s existing stack and governance requirements, not raw API quality.

Scores reflect published Rhumb data as of March 16, 2026. Source: rhumb.dev/blog/linear-vs-jira-vs-asana

The scoreboard

Provider AN Score Execution Access Readiness Confidence Tier
Linear 7.5 L3 7.9 6.8 55% Ready
Jira 7.2 L3 7.6 6.5 56% Ready
Asana 7.0 L3 7.4 6.3 54% Ready

What agents need to know

Linear (7.5) — the API-first choice

Best for: Agents that need to create, update, and query issues programmatically with minimal setup friction. Linear’s GraphQL API was designed for machine consumption from day one.

Avoid when: Your organization requires deep enterprise compliance workflows (approvals, audit trails, field-level permissions).

The failure modes agents hit:

  • GraphQL-only API with no REST fallback. Agents that expect REST must implement GraphQL query construction, requiring more context window tokens per request.
  • Webhook configuration is UI-only — no API endpoint to create or manage webhooks programmatically. Agents cannot self-configure event subscriptions without human intervention.
  • Personal API keys have no granular scope control. A key either has full access to the workspace or no access. Least-privilege patterns are not supported.

Jira (7.2) — the enterprise incumbent

Best for: Organizations already embedded in the Atlassian ecosystem where Jira is the source of truth. The only option when enterprise compliance requires SAML/SCIM and field-level audit trails.

Avoid when: Starting fresh and wanting the simplest possible integration. Jira’s API carries 20 years of evolution — REST v2, REST v3, Agile API, and legacy endpoints coexist.

The failure modes agents hit:

  • Three coexisting API versions (REST v2, REST v3, Agile API) with different auth mechanisms, pagination styles, and error formats. Agents must detect which version to use per operation.
  • Jira Cloud requires OAuth 2.0 (3LO) with Atlassian Connect app registration. The review process can take days and requires a human-facing consent screen.
  • JQL is a custom query language with its own syntax and operators. Agents need JQL-specific knowledge that does not transfer from other APIs.

Asana (7.0) — the middle ground

Best for: Cross-functional teams needing project management with a clean REST API, without Jira’s enterprise governance or Linear’s engineering-specific workflow.

Avoid when: You need GraphQL flexibility or engineering-specific primitives like velocity tracking or deep Git integration.

The failure modes agents hit:

  • Personal access tokens expire after 60 days with no option to create non-expiring tokens. Agents must implement token refresh logic or break silently after two months.
  • Rate limit of 150 requests per minute per token is restrictive for batch operations. Bulk issue creation can hit limits within seconds.
  • Custom field enum values are returned as opaque GIDs requiring separate API calls to resolve. Agents processing custom fields need extra round trips per field.

Routing rules for agents

→ Default to Linear for engineering teams building new integrations. The GraphQL API is the most agent-friendly surface in project management today.

→ If the organization already uses Jira with 50+ users, do not recommend migration. The switching cost exceeds the integration friction difference.

→ For Asana: implement token refresh before deployment. The 60-day expiry causes silent failures that are difficult to diagnose.

→ For Jira: always target REST v3 for Cloud instances. The v2 API returns different response shapes and will eventually be deprecated.

→ If the agent needs to create webhooks programmatically, eliminate Linear — webhook management requires UI access.

Methodology

This comparison uses live data from Rhumb’s AN Score system. Scores are computed from documentation review, API structure analysis, authentication flow assessment, and runtime probing where available.

Scores calculated March 16, 2026. Full comparison: rhumb.dev/blog/linear-vs-jira-vs-asana