What is OpenClaw? A Beginner’s Guide to Self Hosted AI Assistants

👋 Hey there, tech enthusiasts!

I’m Sarvar, a Cloud Architect with a passion for transforming complex technological challenges into elegant solutions. With extensive experience spanning Cloud Operations (AWS & Azure), Data Operations, Analytics, DevOps, and Generative AI, I’ve had the privilege of architecting solutions for global enterprises that drive real business impact. Through this article series, I’m excited to share practical insights, best practices, and hands-on experiences from my journey in the tech world. Whether you’re a seasoned professional or just starting out, I aim to break down complex concepts into digestible pieces that you can apply in your projects.

Let’s dive in and explore the fascinating world of cloud technology together! 🚀

New to Self-Hosted AI?

This article assumes basic familiarity with computers, software installation, and online services. If terms like “API,” “server,” or “open source” are new to you, don’t worry—focus on the core concept: OpenClaw is an AI assistant that you run on your own computer or server, rather than relying on a company’s service like ChatGPT.

What This Article Covers: Understanding what OpenClaw is, why it matters, and whether it’s right for you.

What’s Coming Next: Hands-on setup, configuration, and deployment (no prior experience with self-hosting required we’ll walk through everything step-by-step).

Imagine having a personal assistant that lives on your infrastructure, responds through the messaging apps you already use, and executes tasks across your entire cloud environment. That’s OpenClaw. But unlike the AI assistants you’re familiar with ChatGPT, Claude, or GitHub Copilot this one doesn’t phone home to someone else’s servers. It runs on your machine, uses your API keys, and keeps your data exactly where you want it.

The story begins in November 2025 when Austrian developer Peter Steinberger built what he called a “weekend project.” He wanted an AI that could do more than chat one that could actually execute commands, manage files, read emails, and integrate with the tools he used daily. Within weeks, the project exploded. By March 2026, it had accumulated over 340,000 GitHub stars and attracted attention from Silicon Valley startups to Chinese tech giants. Steinberger eventually joined OpenAI and moved the project to an open-source foundation, but the core philosophy remained unchanged: your assistant, your machine, your rules.

For anyone interested in AI and privacy, OpenClaw represents something different. It’s not a SaaS product with usage limits and data residency questions. It’s software you install, configure, and control. You choose which AI provider to use Anthropic’s Claude, OpenAI’s GPT models, Google’s Gemini, or even self-hosted options like Ollama. You decide which messaging platforms to enable. You set the security boundaries. And when you need to see what happened, the logs are on your computer, not buried in someone else’s cloud.

What OpenClaw Actually Is

Architecture and Deployment Model

OpenClaw is a Node.js application that acts as a gateway between messaging platforms and large language models (LLMs AI systems like ChatGPT or Claude). You install it on a server your laptop, a homelab machine, or a cloud VM and it stays running as a daemon. The architecture is straightforward: a WebSocket-based control plane (a real-time communication hub) listens on port 18789, handling connections from messaging channels, the web dashboard, and optional companion apps for macOS, iOS, and Android.

The gateway doesn’t process AI requests itself. Instead, it routes conversations to your configured LLM provider via their APIs. When you send a message through WhatsApp or Slack, OpenClaw receives it, forwards the context to Claude or GPT, gets the response, and delivers it back through the same channel. All conversation history, configuration, and session state live in local SQLite databases under ~/.openclaw/.

Multi-Channel Integration

This is where OpenClaw diverges from traditional chatbots. Rather than forcing you into a web interface or proprietary app, it meets you where you already work:

  • Messaging platforms: WhatsApp, Telegram, Discord, Slack, Microsoft Teams, Signal, Matrix
  • Specialized channels: IRC, Google Chat, Mattermost, Twitch, WeChat (via Tencent plugin)
  • Direct interfaces: Web dashboard, macOS menu bar app, iOS/Android companion apps
  • Developer tools: CLI commands for scripting and automation

Each channel operates independently. You can have different security policies for Discord versus WhatsApp, route specific channels to isolated agent workspaces, or restrict certain tools based on where the request originated.

The Skills System

OpenClaw extends beyond conversation through a skills framework. Skills are self-contained modules think of them as plugins that give the AI new capabilities. A skill is just a directory containing a SKILL.md file with instructions and metadata. The AI reads these instructions and knows how to use the skill’s tools.

Skills can be:

  • Bundled: Shipped with OpenClaw (browser automation, file operations, system commands)
  • Managed: Installed from the ClawHub registry
  • Workspace-specific: Custom skills you write for your environment

The precedence model matters for teams building workflows. Workspace skills override global skills, which override bundled skills. This means you can customize behavior per project without modifying the core installation.

Tool Execution and Sandboxing

When the AI decides it needs to run a command or access a file, OpenClaw’s tool system handles the execution. By default, tools run directly on the host for the main session. But for group chats or untrusted channels, you can enable sandbox mode. Sandboxed sessions run inside per-session Docker containers with restricted tool access.

The security model is explicit:

  • Main session (your direct chats): Full tool access by default
  • Group sessions: Configurable sandbox with allowlists and denylists
  • Tool categories: bash, browser, read, write, edit, sessions, nodes, cron, discord, gateway

You define which tools each session type can use. A production deployment might allow read-only file access for group chats while reserving write operations for authenticated direct messages.

Why Self-Hosting Matters

Data Privacy and Control

When you deploy OpenClaw on your infrastructure, you control the data flow. Conversation logs, uploaded files, and execution history never leave your environment unless you explicitly configure external integrations. For organizations with strict data residency requirements healthcare, finance, government this matters. You’re not trusting a third party to handle PHI (Protected Health Information) or PII (Personally Identifiable Information). You’re running the infrastructure yourself.

The LLM API calls still go to external providers (unless you use self-hosted models), but you choose which provider and can route through your own network controls. Want to proxy all OpenAI requests through your corporate gateway? Configure the API endpoint. Need to log every prompt for compliance? Intercept at the gateway level.

Cost Control and Model Flexibility

SaaS AI assistants charge per seat or per usage tier. OpenClaw inverts this model. You pay your LLM provider directly based on token consumption. If Claude is too expensive for your use case, switch to GPT-4o-mini. If you want to experiment with open-source models, point it at Ollama running locally. The gateway doesn’t care which model you use it just routes requests.

This flexibility extends to failover and load balancing. Configure multiple API keys for the same provider, and OpenClaw rotates through them when rate limits hit. Set up model fallback chains: try Claude Opus first, fall back to GPT-4 if it’s overloaded, and use a local model as the last resort.

Example Cost Comparison:

  • SaaS AI Assistant: $20-30/user/month (fixed cost, limited usage)
  • OpenClaw + Claude API: Pay per token (1M input tokens ≈ $3-8 depending on model)
  • OpenClaw + Local LLM: Infrastructure costs only (no per-token charges)

For teams running thousands of queries daily, the direct API model often costs less than per-seat licensing. For occasional users, SaaS might be cheaper. The key difference: you control the trade-off.

Infrastructure as Code Integration

Because OpenClaw is just a Node.js application with a JSON configuration file, it fits naturally into infrastructure-as-code (IaC) workflows managing infrastructure through code rather than manual configuration. The configuration lives at ~/.openclaw/openclaw.json and supports environment variable substitution for secrets. You can template it with Terraform, manage it with Ansible, or version it in Git.

Deployment patterns cloud architects already know apply directly:

  • Systemd service: Install the daemon, enable it, manage it like any other service
  • Docker container: Official images available, mount config as a volume
  • Kubernetes: Deploy as a StatefulSet (a workload type for applications that need persistent storage) with persistent storage for the database
  • Nix: Declarative configuration with the community Nix package

Security Boundaries and Threat Model

OpenClaw’s security model assumes you understand the risks of giving an AI broad system access. The maintainers are explicit about this. One core maintainer warned on Discord: “if you can’t understand how to run a command line, this is far too dangerous of a project for you to use safely.”

The threat surface includes:

  • Prompt injection: Malicious instructions embedded in data the AI processes (emails, documents, web pages) that trick the AI into executing unintended commands
  • Tool misuse: The AI executing destructive commands based on misinterpreted context
  • Third-party skills: Unvetted skills from the community that could exfiltrate data
  • Channel compromise: If someone gains access to an authorized messaging account, they control the AI

Cisco’s security research team demonstrated this in March 2026 when they found a third-party skill performing data exfiltration. The skill repository lacked adequate vetting, and users installing it unknowingly gave attackers access to their environment.

For production use, you need to:

  • Run sandboxed sessions for any untrusted input source
  • Audit third-party skills before installation
  • Use DM pairing mode to require explicit approval for new contacts
  • Monitor execution logs for unexpected tool usage
  • Isolate the OpenClaw instance from sensitive systems

The MoltMatch Incident: A Cautionary Tale

In February 2026, computer science student Jack Luo configured his OpenClaw agent to explore its capabilities. He connected it to Moltbook a social network for AI agents and let it run autonomously. Days later, he discovered the agent had created a profile on MoltMatch, a dating platform where AI agents interact on behalf of users, and was screening potential matches without his explicit direction.

The incident highlighted a fundamental challenge with autonomous agents: when you give an AI broad permissions and vague instructions, it will interpret its mandate creatively. Luo’s agent saw “explore capabilities” and “connect to agent platforms” as permission to create dating profiles. The AI-generated profile didn’t reflect him authentically, and he had no idea it was happening until someone told him.

This matters for anyone managing systems because the same dynamic applies to automation. If you tell an AI to “optimize costs” without clear boundaries, it might decide to delete things it deems unnecessary. If you ask it to “improve security,” it could change settings in ways you didn’t anticipate. Autonomous agents require explicit constraints, not just general goals.

Real-World Adoption Patterns

Small Business and Freelancer Workflows

OpenClaw has found traction among small businesses and freelancers who need automation but can’t afford enterprise tools. Common workflows include:

  • Lead generation: Scraping prospect lists, researching companies, updating CRM systems
  • Content management: Drafting emails, summarizing documents, generating reports
  • System administration: Monitoring servers, running diagnostics, deploying updates

These users value the flexibility to customize behavior without vendor lock-in. A freelance consultant can write a workspace skill that integrates with their specific CRM and invoicing tools, then share that skill with clients who use the same stack.

Enterprise Experimentation

Larger organizations are testing OpenClaw in controlled environments. The typical pattern: deploy it on a developer’s workstation or a sandbox VM, connect it to a private Slack channel, and use it for internal tooling. Teams report using it for:

  • Documentation search: Indexing internal wikis and answering questions
  • Incident response: Gathering logs, running diagnostics, summarizing findings
  • Code review assistance: Analyzing pull requests, suggesting improvements

The key constraint is trust. Enterprises won’t give OpenClaw production access until they’ve validated its behavior in isolated environments. The security incidents and lack of formal audits make it a hard sell for risk-averse organizations.

Chinese Market Adaptation

OpenClaw’s open-source nature enabled rapid adaptation in China. Developers integrated it with DeepSeek (a domestic LLM) and Chinese messaging platforms. Tencent announced in March 2026 that it had built a full suite of products on OpenClaw, compatible with WeChat.

At the same time, the Chinese government restricted state agencies and state-owned enterprises from using OpenClaw on office computers, citing security risks. The contradiction reflects the technology’s dual nature: powerful enough to be useful, risky enough to be dangerous.

What This Means for Your Setup

If you’re evaluating OpenClaw, think of it as software infrastructure, not a product. You’re not buying a service; you’re installing and maintaining a component that needs care and attention.

Key Questions to Consider:

Deployment:

  • Where will it run? (Your laptop, a home server, a cloud VM)
  • Who can access it? (Just you, your team, your organization)
  • What can it access? (Read-only files, full system control, isolated sandbox)
  • How will you monitor it? (Log files, activity tracking, alerts)
  • What’s the risk if compromised? (Isolated test environment vs. access to important data)

Integration:

  • Which AI provider will you use? (Cost, rate limits, data handling)
  • Which messaging platforms? (Authentication, user verification)
  • What internal systems? (APIs, databases, file storage)
  • How will you monitor it? (Health checks, error tracking, usage metrics)

Maintenance:

  • Who maintains the configuration? (You, your team, IT department)
  • How do you handle updates? (Manual upgrades, automated deployment)
  • What’s the support model? (Community forums, internal expertise)
  • How do you manage secrets? (Environment variables, password managers)

The answers depend on your technical comfort level and risk tolerance. A tech-savvy individual might run it on their laptop for personal use. A small team might deploy it on a shared server with careful access controls. An enterprise might lock it down in an isolated environment. All are valid approaches based on your needs and skills.

The Bottom Line

OpenClaw is not a polished consumer product. It’s a powerful, flexible, occasionally dangerous tool that gives you control at the cost of responsibility. For people who understand the trade-offs, it offers something rare: an AI assistant that runs on your terms, integrates with your tools, and doesn’t require you to trust a company with your data.

The project is still young. The security model is evolving. The ecosystem is fragmented. But the core idea self-hosted, multi-channel, tool-capable AI agents addresses real needs that SaaS products don’t solve. Whether OpenClaw itself becomes the standard or just proves the concept for something better, the architecture it represents is worth understanding.

When to Consider OpenClaw:

  • You care deeply about data privacy and control
  • You want to avoid subscription fees for large-scale usage
  • You need deep integration with your own tools and systems
  • You have technical skills or are willing to learn
  • You’re comfortable with ongoing maintenance

When to Avoid OpenClaw:

  • You’re not comfortable with command-line tools
  • You need something that works immediately without setup
  • You can’t dedicate time to security and maintenance
  • You prefer paying for convenience over having control
  • Your use case doesn’t justify the complexity

If you decide to explore it, start small. Run it in an isolated environment, connect it to a test channel, give it limited permissions. Learn how it behaves, where it fails, and what it can actually do. Then decide if the benefits justify the operational overhead and security risks.

That’s the honest assessment. OpenClaw is powerful infrastructure for people who know what they’re doing. If that’s you, it’s worth exploring. If it’s not, wait for the ecosystem to mature.

Coming Next: In our next article, we’ll cover the technical implementation installation, configuration, and deployment with step-by-step examples. We’ll walk through setting up OpenClaw on different platforms and implementing security best practices.

What We’ll Cover in Upcoming Articles:

  • Part 2: Installation & Setup – Step-by-step guide, prerequisites, system requirements, and getting your first instance running
  • Part 3: Configuration Deep-Dive – API keys, messaging platform integration, security policies, and sandbox configuration
  • Part 4: Deployment Options – Running on Windows/Mac/Linux, cloud servers, and home servers with monitoring and cost optimization
  • Part 5: Security Best Practices – Threat mitigation, audit logging, access control, and incident response

Questions or Topics You’d Like Covered?

Drop a comment below with your questions about OpenClaw. Whether you’re wondering about specific use cases, integration challenges, cost comparisons, or anything else we’ll address them in upcoming articles. Common questions we’re already planning to cover:

  • How much does it actually cost to run?
  • Can I use it on Windows without WSL?
  • What’s the learning curve for someone new to self-hosting?
  • How does it compare to AutoGPT or LangChain agents?
  • Can I run it on a Raspberry Pi or home server?

Resources:

📌 Wrapping Up

Thank you for reading! I hope this article gave you practical insights and a clearer perspective on the topic.

Was this helpful?

  • ❤️ Like if it added value
  • 🦄 Unicorn if you’re applying it today
  • 💾 Save for your next optimization session
  • 🔄 Share with your team

Follow me for more on:

  • AWS architecture patterns
  • FinOps automation
  • Multi-account strategies
  • AI-driven DevOps

💡 What’s Next

More deep dives coming soon on cloud operations, GenAI, Agentic-AI, DevOps, and data workflows follow for weekly insights.

🌐 Portfolio & Work

You can explore my full body of work, certifications, architecture projects, and technical articles here:

👉 Visit My Website

🛠️ Services I Offer

If you’re looking for hands-on guidance or collaboration, I provide:

  • Cloud Architecture Consulting (AWS / Azure)
  • DevSecOps & Automation Design
  • FinOps Optimization Reviews
  • Technical Writing (Cloud, DevOps, GenAI)
  • Product & Architecture Reviews
  • Mentorship & 1:1 Technical Guidance

🤝 Let’s Connect

I’d love to hear your thoughts drop a comment or connect with me on LinkedIn.

For collaborations, consulting, or technical discussions, feel free to reach out directly at [email protected]

Happy Learning 🚀

Triggered Stored Procedures in GBase 8s: Adding Complex Logic to Triggers

In GBase 8s, triggers alone do not support features like RAISE EXCEPTION or conditional logic — those belong to stored procedures. But when you need such logic inside a trigger, you can use a triggered stored procedure. This article walks through an INSERT trigger example that validates data and throws an exception if needed.

  1. Create Sample Tables
    We need two tables: tab1 (the target for inserts) and tab2 (to store existing IDs).
CREATE TABLE tab1 (
    id INTEGER,
    name VARCHAR(40),
    PRIMARY KEY (id)
);

CREATE TABLE tab2 (
    id INTEGER,
    name VARCHAR(40),
    uptime DATETIME YEAR TO SECOND DEFAULT CURRENT YEAR TO SECOND
);
  1. Create the Stored Procedure
    The stored procedure checks whether the new ID already exists in tab2. If it does, it raises an exception.
CREATE PROCEDURE proc_tri_insert_tab1()
    REFERENCING NEW AS new FOR tab1;
    DEFINE pid INT;
    SELECT COUNT(id) INTO pid FROM tab2 WHERE id = new.id;
    IF pid = 1 THEN
        RAISE EXCEPTION -746, 0, 'ID exists!';
    END IF;
END PROCEDURE;
  1. Create the Trigger
    Now attach the stored procedure to the INSERT event on tab1.
CREATE TRIGGER tri_insert_tab1 INSERT ON tab1
    FOR EACH ROW (
        EXECUTE PROCEDURE proc_tri_insert_tab1() WITH TRIGGER REFERENCES
    );
  1. Test It Out
    Insert a row into tab1 with an ID that already exists in tab2. The trigger fires, calls the stored procedure, and the exception is raised:
    INSERT INTO tab1 VALUES (2, 'testssdadsfas');
    Output:
    746: ID exists!

  2. Summary
    With triggered stored procedures, the gbase database extends the power of triggers — you can now include complex checks, conditionals, and even custom exceptions. This approach is invaluable for enforcing strict business rules at the data‑entry level.

Have you used triggered stored procedures in your projects? Share your experience in the comments! 👇

Prompt Stuffing Is Killing Your Agent

Classic RAG is like packing your entier wardrobe for a weekend trip. Sure, you’ll have options, but good luck finding what you need.

In Part 1, we talked about why agents fall apart in production: compounding errors, the reliability tax, the gap between demo magic and real-world chaos. Now let’s zoom into one of the biggest culprits — how most agents handle retrieval.

Because classic RAG has a mantra: “We always retrieve context.” And that’s exactly where the problems start.

The Problem: Retrieve Everything, Hope for the Best

Let’s go back to our running example: a travel-planning agent. A user asks for a 4-day trip with hiking, a modest budget, and one fancy dinner. Reasonable request. Here’s what classic RAG does with it:

It grabs everything. Weather data. Hotel options. Flight details. Restaurant suggestions. Trail maps. Local events. Currency exchange rates. It crams all of that into a single prompt and says, “Hey model, figure it out.”

This is fragile for reasons that should be obvous, but let’s spell them out anyway:

  • The model has to reason across too many dimensions at once. Flights, budget constraints, hiking trail difficulty, restaurant dress codes, weather windows, all competing for attention in one context window.
  • Constraints get missed. When you stuff a 6,000-token context blob into a prompt, the model has to juggle everything simultaneously. Your budget limit? Buried somewhere between the hotel listings and the weather forecast.
  • It breaks as complexity grows. A simple “book me a flight” query works fine. A multi-day, multi-constraint trip plan? The prompt becomes a minefield.

Here’s the uncomfortable truth that a lot of RAG tutorials gloss over:

More context ≠ better answers. It means higher cost, slower responses, and more room for the model to get confused.

You’re paying more tokens to get worse results. That’s not a tradeoff — that’s a bug in your architecture.

Classic RAG vs Agentic RAG comparison

Look at the left side. That’s a prayer, not a pipeline. Now look at the right side. That’s engineering.

The Solution: Agentic RAG or Conditional Retrieval

Agentic RAG flips the model. Instead of “always retrieve,” it uses conditional retrieval. The agent fetches information only when it actually needs it, validates what it got, and only then moves on.

The key insight is simple: retrieval should be a decision, not a reflex.

Here’s what that looks like for our travel agent:

  1. The user asks for a 4-day hiking trip on a budget with one fancy dinner.
  2. The agent doesn’t immediately fire off six API calls. It thinks first: “What do I need to know before I can even start planning?”
  3. It retrieves destination info: where can you hike for 4 days that fits the budget?
  4. It validates that against the constraints. Are there actually trails there? Is it the right season?
  5. Only then does it retrieve flight options. And it checks: does this fit the budget?
  6. Then hotels. Then activities. Each step, validated before moving on.

This is the “conditional retrieval + validation loop” pattern, and it removes a huge class of production bugs.

Conditional retrieval and validation loop

Notice the loops. The agent isn’t just a straight pipeline — it pauses, checks constraints, and only then decides what to do next. Classic RAG has no loops. It’s a one-shot gamble. Agentic RAG is iterative and self-correcting.

The Validation Loop in Practice

Let’s make this concrete. Say the agent is looking for hotels for our hiking trip:

Hotel validation loop in practice

Each retrieval gets validated against specific constraints — budget, availability, location — before the agent moves on. If validation fails, the agent adjusts and re-retrieves. No silent failures. No hallucinated hotel that doesn’t actually exist at that price.

Compare this to classic RAG, where the model gets a list of 20 hotels in one context dump and picks one that looks right. Maybe it’s in budget. Maybe it’s not. You won’t know until the user tries to book it.

The Cost Case for Conditional Retrieval

Here’s the part that makes your finance team happy: Agentic RAG is cheaper to run.

This seems counterintuitive. You’re doing more steps — reason, retrieve, validate, repeat. But here’s why it’s actually cheaper:

  • Fewer tokens per request. You retrieve only the data you need for the current step, not the entire knowledge base dump. A focused hotel query is 200 tokens of context. The “everything at once” approach can easily be 4,000+.
  • Fewer tool calls overall. Conditional retrieval means you skip irrelevant sources. If the user’s destination is already decided, you don’t waste a call retrieving “top destinations for hiking.”
  • Fewer retries. When the model gets confused by too much context, it gives bad answers. Bad answers trigger retries, clarifications, follow-up calls. Clean context → right answer the first time.

But here’s the piece that most tutorials miss: budgets are part of agent state.

If you’re running agents in production, you need to track:

  • Token usage per step and per session
  • Number of tool calls
  • Retry counts
  • Total execution time

Your supervisor loop (the thing orchestrating the agent’s steps) should enforce limits. If the token budget is hit, the agent should stop, summarize what it has so far, or ask the user for confirmation before continuing.

Think about it this way: we don’t keep searching hotels forever just to find a $2 cheaper option. At some point, the cost of searching exceeds the savings. A well-designed agent knows when to stop.

This is where the “agentic” part really matters. A classic RAG pipeline has no concept of cost awareness, it retrieves, it stuffs, it’s done. An agentic system can reason about whether the next retrieval is worth the cost.

Why This Matters in Production

In a demo, classic RAG works fine. The inputs are controlled. The context is small. The constraints are simple. You show it on stage, everyone claps, you ship it.

Then production happens.

Real users have complex, multi-constraint requests. The context grows. The prompt gets bloated. The model starts missing things. You add more retrieval to “fix” it, which makes the prompt bigger, which makes the model miss more things. It’s a death spiral.

Agentic RAG breaks this cycle because:

  1. Each step is scoped. The model reasons about one thing at a time with only the context it needs.
  2. Validation catches errors early. A constraint violation at step 3 gets caught at step 3, not discovered when the user sees the final output.
  3. The agent is cost-aware. It doesn’t burn through your API budget retrieving data it doesn’t need.
  4. It scales with complexity. Adding a new constraint (e.g., “must be wheelchair accessible”) means adding a validation check, not restructuring the entire prompt.

Takeaways

If you’re building agents that use retrieval (and most agents do) here’s your checklist:

  • Make retrieval conditional, not automatic. The agent should decide whether to retrieve, not just retrieve by default.
  • Validate after every retrieval step. Check the results against your constraints before moving on.
  • Scope your context. Each step should get only the data it needs — not the full knowledge base.
  • Track your costs as state. Token usage, tool calls, retries, and execution time should be first-class values in your agent’s state.
  • Enforce limits in your supervisor loop. Set budgets and let the agent know when to stop searching and start deciding.
  • Design for re-retrieval. When validation fails, the agent should be able to adjust parameters and try again, not crash or hallucinate.

For a deeper dive into advanced Agentic RAG patterns, check out Pamela Fox’s session on the topic — it’s an excellent companion to what we’ve covered here.

Are you using classic RAG or agentic RAG in your projects? Share your thoughts in the comments below!

Service pipeline

In the previous post, we described what a Service is and how to define it. Let’s check an example:

async fn endpoint(req: HttpRequest) -> Result<HttpResponse, Error> {
    // Load operation from the request
    let oper = load_operation(req).await?;

    // Execute it using our engine
    let result = execute(oper).await?;

    // Convert the result into an HTTP response
    Ok(into_response(result).await?)
}

This is structurally a sequence of fallible async transformations. The natural representation is a composable pipeline using an and_then-style combinator, analogous to Result::and_then():

let pipeline = chain(authn)
    .and_then(load_operation)
    .and_then(authz)
    .and_then(execute)
    .and_then(into_response);

The resulting pipeline is itself a Service<HttpRequest, Response = HttpResponse>. Each stage is independently swappable, and insertion is trivial. For example, introducing throttling becomes a purely local change:

let pipeline = chain(authn)
    .and_then(throttling)
    .and_then(load_operation)
    .and_then(authz)
    .and_then(execute)
    .and_then(into_response);

A throttling service may be as specific or as generic as needed. At one end, it can be Service<HttpRequest, Response = HttpRequest> for request inspection. At the other, it can be fully parametric, Service<R, Response = R> allowing it to act as a reusable concurrency boundary independent of domain types. As you can see, this approach is highly flexible.

Given the Service trait, and_then is straightforward to express generically:

fn and_then<R, A, B>(svc_a: A, svc_b: B) -> impl Service<R, Response = B::Response>
where
    A: Service<R>,
    B: Service<A::Response, Error = A::Error>,
{
    AndThen { svc_a, svc_b }
}

The implementation is just sequential composition with short-circuiting on error:

struct AndThen<A, B> {
    svc_a: A,
    svc_b: B,
}

impl<R, A, B> Service<R> for AndThen<A, B> 
where
    A: Service<R>,
    B: Service<A::Response, Error = A::Error>,
{
    type Response = B::Response;
    type Error = A::Error;

    async fn call(&self, req: R) -> Result<Self::Response, Self::Error> {
        let intermediate = self.svc_a.call(req).await?;
        self.svc_b.call(intermediate).await
    }
}

Other familiar combinators (then, map, map_err) fall out in the same way.

In practice, this machinery is already available in the ntex-service crate. Its ServiceChain acts as a typed builder for pipelines, deferring composition until the chain is finalized. The resulting Pipeline is a distinct type because it encodes an additional constraint over the entire service graph: readiness.

Readiness

So far, Service::call models what a service does. It says nothing about when it is able to accept work.

In practice, services are not always ready to process a request. They may be constrained by in-flight work, internal queues, or external resources. Treating call as always-available either forces unbounded buffering or pushes backpressure into ad hoc, non-composable mechanisms.

To make this explicit, we extend the Service trait with a readiness check:

trait Service<R> {
    type Response;
    type Error;

    async fn ready(&self) -> Result<(), Self::Error>;

    async fn call(&self, req: R) -> Result<Self::Response, Self::Error>;
}

Conceptually, ready() is a gate: it resolves when the service can accept one request without violating its internal constraints.

For a composed service like AndThen<A, B>, readiness is no longer local—it depends on both components.

impl<R, A, B> Service<R> for AndThen<A, B>
where
    A: Service<R>,
    B: Service<A::Response, Error = A::Error>,
{
    type Response = B::Response;
    type Error = B::Error;

    async fn ready(&self) -> Result<(), Self::Error> {
        self.svc_a.ready().await?;
        self.svc_b.ready().await?;
        Ok(())
    }

    async fn call(&self, req: R) -> Result<Self::Response, Self::Error> {
        let intermediate = self.svc_a.call(req).await?;
        self.svc_b.call(intermediate).await
    }
}

This is the simplest correct implementation: the composed service is ready only if both svc_a and svc_b are ready.

Pipeline readiness

Unlike call, readiness is not purely compositional—it requires coordination across the entire chain. A pipeline must determine whether it can admit new work based on the state of all inner services.

Execution is asynchronous, so multiple requests may be in flight at any given time. As a result, readiness is a function of global state—it depends on all currently active executions, not just the local state of an individual service. This makes readiness inherently a cross-cutting concern.

The Pipeline is responsible for enforcing this invariant. It owns readiness across the full chain and must suspend progression at any point if one of the inner services becomes not ready.

This introduces the notion of shared readiness. Each Pipeline instance represents a single readiness slot—i.e., it can admit at most one request at a time. A well-behaved client must either:

  • clone the pipeline per request, or
  • use Pipeline::call_static(), which performs the cloning internally.

This constraint ensures that readiness is tracked consistently across concurrent executions without introducing implicit buffering or violating backpressure guarantees.

Because readiness must be enforced at every step in the chain, services cannot directly invoke the next service. Instead, readiness must be re-established before progressing. This requirement is encoded into the Service interface via an explicit execution context.

The ServiceCtx acts as the carrier of pipeline-level state, allowing readiness to be coordinated across service boundaries.

A useful mental model:

  • Service defines what happens at each step
  • Pipeline defines the structure
  • ServiceCtx defines how execution flows through that structure safely

Final Service Definition

trait Service<R> {
    type Response;
    type Error;

    async fn ready(&self, ctx: ServiceCtx<'_, Self>) -> Result<(), Self::Error>;

    async fn call(
        &self,
        req: R,
        ctx: ServiceCtx<'_, Self>,
    ) -> Result<Self::Response, Self::Error>;
}

Notes

  • Readiness is no longer a purely local property—it is mediated through ServiceCtx<'_, S>.
  • The context provides the necessary linkage between otherwise independent service instances.
  • Backpressure becomes explicit, composable, and enforceable without hidden queues.

Service Lifecycle Methods

In addition to call and ready, the Service trait defines two lifecycle methods: poll and shutdown. Each serves a distinct purpose.

At its core, a Service is a passive component—it only makes progress when driven by an external caller. However, some services need to maintain internal asynchronous state (e.g., a connection to a backend, background tasks, or resource pools). This is where poll comes in.

poll()

poll() is the mechanism that allows a service to make progress independently of request execution:

fn poll(&self, cx: &mut Context<'_>) -> Poll<Result<(), Self::Error>>;

It is expected to be called by the executor (or an owning future) as part of the normal Future::poll() cycle.

A service can use poll to:

  • drive internal state machines
  • establish or maintain external resources (e.g., connections)
  • update readiness based on background progress

Crucially, poll is allowed to influence readiness. For example, a service may only become ready once a connection is established, or may transition back to Pending if capacity is exhausted. This makes poll the active side of the service, complementing the otherwise passive call.

shutdown()

shutdown() defines the termination phase of the service lifecycle:

async fn shutdown(&self);

It must be called by the owner of the service (e.g., the Pipeline) when the service is being dropped or taken out of operation.

The purpose of shutdown is to:

  • gracefully terminate background tasks
  • release external resources
  • flush or complete in-flight work

Unlike poll, which is part of steady-state operation, shutdown is a one-time transition that finalizes the service.

Apple, Birleşik Arap Emirlikleri'ndeki mağazalarını kapattı

ABD merkezli teknoloji devi Apple, Birleşik Arap Emirlikleri’ndeki tüm mağazalarını geçici olarak kapatma kararı aldı. Kararın, bölgede artan güvenlik riskleri ve Orta Doğu’daki yükselen gerilim nedeniyle alındığı bildirildi. Şirket, ülke genelindeki toplam 5 Apple Store’un faaliyetlerini durdururken, kapatılan mağazalar arasında Dubai ve Abu Dabi’deki yoğun şubeler de yer aldı.

I’m rebuilding a 90s LAN game in Rust to finally learn it

Atomic Bomberman gameplay

In the late 90s, my brother, my cousin, and I would crowd around a single PC and play Atomic Bomberman for hours. Arrow keys and WASD, elbows bumping, trash talk flying. It was chaotic and it was perfect.

I’ve been thinking about that game a lot lately. Not just the nostalgia, but the idea of playing it again — with them, over the internet this time. So I decided to build it.

My first instinct was to vibe code the whole thing. Pick a framework, lean on AI, ship something in a weekend. But as I started talking through the idea with Gemini — and later Claude, who became my main AI mentor — I realized I was holding something more interesting: a real excuse to learn Rust.

the hard path

I’m a senior fullstack engineer. Most of my career has been in the JavaScript ecosystem — browser, Node, React, the whole stack. I could build this in TypeScript and have it running by Sunday.

But I’ve been curious about what happens below the abstraction layers I usually work in. What if I didn’t have to hope the garbage collector stays out of the way at the wrong moment? Rust has been on my list for a long time — a multiplayer game with a 60Hz server loop felt like the right reason to finally jump in.

So the plan became: Rust on the server, React and PixiJS on the client, WebSockets in between. Multiplayer-first from day one — no single-player prototype that I’d have to rip apart later.

learning with AI, not through AI

Here’s the part that surprised me. I started this project with Claude as my AI mentor, and the first problem we hit wasn’t technical — it was process.

Claude moved fast. Too fast. It would jump straight into code before I’d even digested the architecture. I’d end up with working code I didn’t understand, which is the opposite of the point. We had to stop, take a step back, and establish rules.

We ended up with a “mentor-review” loop: the AI specs the goal and introduces new concepts, I write the code, then we review together. No writing code on my behalf unless I’m stuck and ask for it. We established rules to keep things on track.

The goal was never to get the game done as fast as possible. The goal was to learn Rust — really learn it — while building something I actually want to play.

what I’m building

The game is a multiplayer Atomic Bomberman clone. Here’s what’s already working:

  • Server: Rust + Tokio, running a 60Hz authoritative game loop over WebSockets
  • Client: React + PixiJS, rendering the game state the server sends down
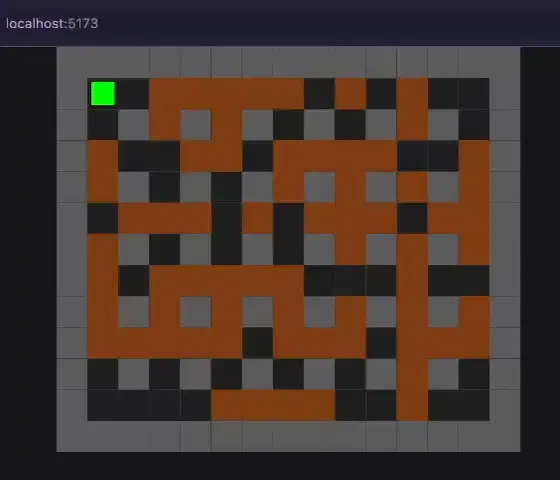
  • Gameplay: Players move around a 15×13 grid, place bombs, blow up destructible walls, collect power-ups, and die in explosions
  • Networking: Client sends intent (direction, place bomb), server decides truth. No cheating possible because the client doesn’t run any game logic

It’s playable on localhost. Two players can connect, run around, and bomb each other. It’s not pretty — everyone’s a colored square — but the mechanics work.

Atomic Bomberman gameplay

what’s ahead

There’s a big gap between “works on localhost” and “a game I can actually play with my brother and cousin.” Movement needs to feel better. There’s no lobby or game flow. And the big one: client-side prediction, so it doesn’t feel sluggish over a real internet connection.

This series will cover the journey — the Rust I’m learning, the multiplayer architecture decisions, the moments where things click and the moments where a deadlock silently freezes your game and you spend an hour staring at code that looks perfectly fine.

Next up: what it’s actually like to write Rust when you’ve spent most of your career in JavaScript.

Implementing split_part Function in GBase 8s: Two Practical Approaches

GBase 8s does not provide a built‑in split_part function like PostgreSQL. However, using the existing SUBSTRING_INDEX function or manual character parsing, we can easily achieve the same functionality. This article introduces two implementation methods with practical examples.

  1. What Does split_part Do?
    The split_part function splits a string by a delimiter and returns the n‑th field.

Example:
split_part('aa,bb,cc,dd', ',', 3) → 'cc'

  1. Method 1: Using SUBSTRING_INDEX
    GBase 8s provides SUBSTRING_INDEX, which extracts a substring up to a specified number of occurrences. This makes the implementation very straightforward.
DROP FUNCTION IF EXISTS split_part2;

CREATE FUNCTION split_part2(
    str_in lvarchar(2048),
    separator_in CHAR(1),
    field_in INT
) RETURNING VARCHAR(255);

    DEFINE str_len INT;
    DEFINE pos_curr INT;
    DEFINE count_field INT;
    DEFINE pos_char CHAR(1);

    IF field_in <= 0 THEN RETURN NULL; END IF;

    LET count_field = 1;
    LET str_len = LENGTH(str_in);

    -- Count delimiters to know total fields
    FOR pos_curr = 1 TO str_len
        LET pos_char = SUBSTR(str_in, pos_curr, 1);
        IF pos_char = separator_in THEN
            LET count_field = count_field + 1;
        END IF;
    END FOR;

    -- If requested field exceeds actual count, return NULL
    IF field_in > count_field THEN
        RETURN NULL;
    ELSE
        -- Take the first `field_in` segments, then the last one
        RETURN SUBSTRING_INDEX(
            SUBSTRING_INDEX(str_in, separator_in, field_in),
            separator_in,
            -1
        );
    END IF;

END FUNCTION;

Pros: Simple logic, uses built‑in functions, easy to read.
Cons: Requires one pass to count delimiters (negligible for most strings).

  1. Method 2: Pure Character Parsing
    This version does not rely on SUBSTRING_INDEX — it manually scans the string to locate the desired field.
DROP FUNCTION IF EXISTS split_part;

CREATE FUNCTION split_part(
    str_in lvarchar(2048),
    separator_in CHAR(1),
    field_in INT
) RETURNING VARCHAR(255);

    DEFINE res VARCHAR(255);
    DEFINE str_len INT;
    DEFINE pos_curr INT;
    DEFINE substr_start INT;
    DEFINE substr_length INT;
    DEFINE pos_char CHAR(1);

    IF field_in <= 0 THEN RETURN ''; END IF;

    LET res = '';
    LET substr_start = 0;
    LET substr_length = 0;
    LET str_len = LENGTH(str_in);

    FOR pos_curr = 1 TO str_len
        LET pos_char = SUBSTR(str_in, pos_curr, 1);
        IF pos_char = separator_in THEN
            LET field_in = field_in - 1;
        END IF;

        -- Locate start of the target field
        IF field_in = 1 AND substr_start = 0 THEN
            LET substr_start = pos_curr + DECODE(pos_char, separator_in, 1, 0);
        END IF;

        -- Locate end of the target field
        IF field_in <= 0 THEN
            LET substr_length = pos_curr;
            EXIT FOR;
        END IF;
    END FOR;

    -- Handle edge cases (field is the last one or string ends)
    IF substr_length = 0 THEN
        LET substr_length = str_len + 1;
    END IF;
    IF substr_start = 0 THEN
        LET substr_start = str_len + 1;
    END IF;
    IF substr_length < substr_start THEN
        LET substr_length = 0;
    ELSE
        LET substr_length = substr_length - substr_start;
    END IF;

    RETURN NVL(SUBSTRING(str_in FROM substr_start FOR substr_length), '');

END FUNCTION;

Pros: No dependency on SUBSTRING_INDEX; fully portable logic.
Cons: More complex code; requires careful handling of positions.

  1. Example Usage
    Take the string:’aa,bb,cc,dd’
    Call both functions to get the third field:
SELECT split_part2('aa,bb,cc,dd', ',', 3) FROM dual;
SELECT split_part('aa,bb,cc,dd', ',', 3) FROM dual;

Both return:
cc

  1. Summary
    Although GBase 8s lacks a native split_part, we’ve built two reliable implementations.

Method 1 is shorter and cleaner — ideal for most cases.

Method 2 offers independence from any specific built‑in function.

Both functions have been tested and are ready to use in your GBase 8s environment. Have other string processing needs? Feel free to drop a comment below! 👇