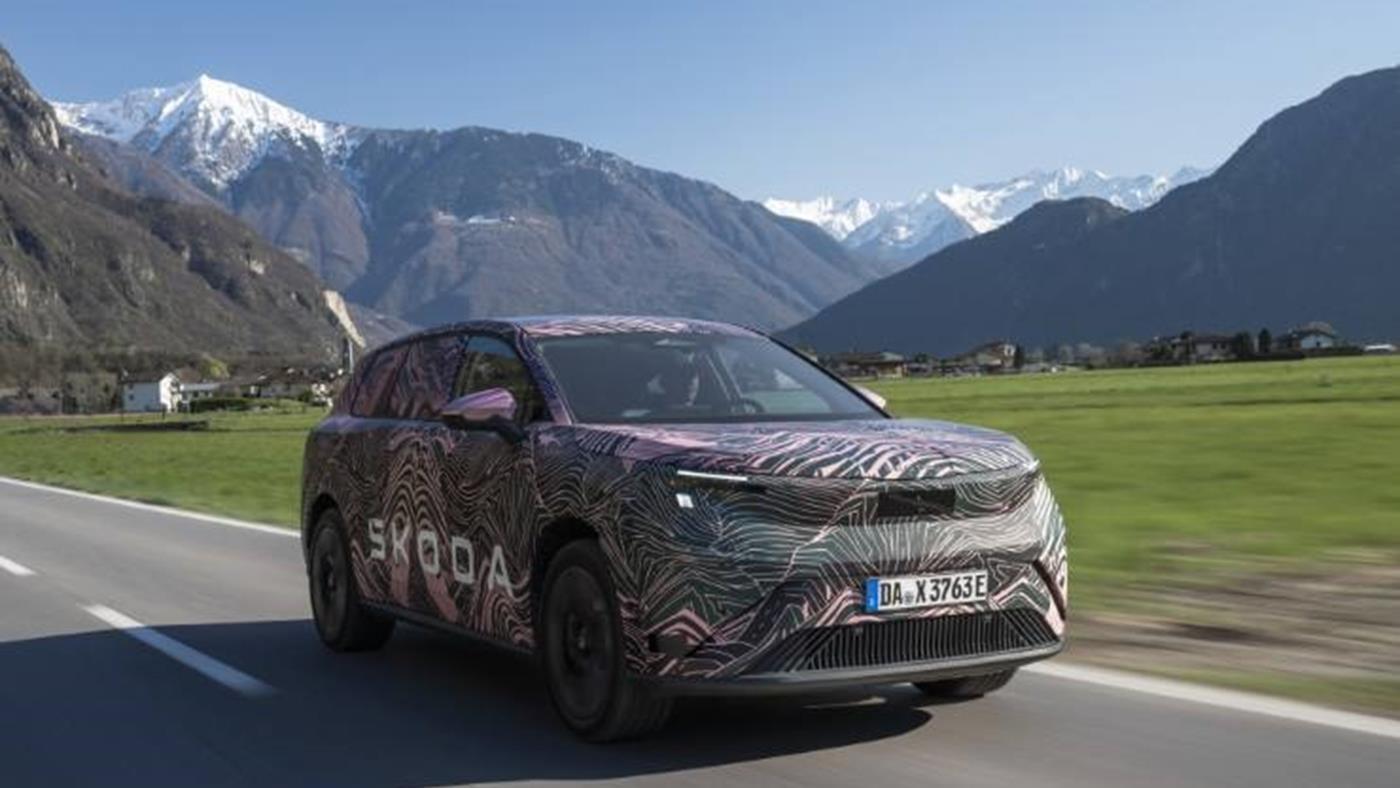
7 kişilik Skoda Peaq’ten ilk detaylar: 600 km’ye kadar menzil
Markanın en büyük ve en geniş modeli olacak tamamen elektrikli Skoda Peaq, 150 ile 220 kW arasında güç seçenekleri ve 600 km’ye kadar menzil sunacak. İşte Skoda Peaq özellikleri:
Markanın en büyük ve en geniş modeli olacak tamamen elektrikli Skoda Peaq, 150 ile 220 kW arasında güç seçenekleri ve 600 km’ye kadar menzil sunacak. İşte Skoda Peaq özellikleri:Every Android Developer Faces This
You open a new Android project and get stuck at one question:
Should I use XML or Jetpack Compose?
If you’ve been working with Android for a while, XML feels familiar. It’s stable, predictable, and widely used.
But then you see Jetpack Compose — modern, Kotlin-first, less boilerplate, and backed heavily by Google.
Now the confusion starts:
Let’s break it down deeply, but simply.
🧠 Understanding the Core Difference
🏗️ XML (View System)
Think of XML like designing a house blueprint separately from construction.
👉 Two separate worlds:
XML → UI
Kotlin → Logic
⚡ Jetpack Compose
Compose is like building the house directly in code, live, and reactive.
👉 Single source of truth:
🔍 Deep Dive (Based on Official Android Architecture)
Problem:
Updating UI manually:
textView.text = "Hello"
button.visibility = View.GONE
👉 You control everything manually.
Jetpack Compose Internals
Compose works on Declarative UI + State-driven rendering
Core Concepts:
How it works:
👉 Think like this:
@Composable
fun Greeting(name: String) {
Text(text = "Hello $name")
}
If name changes → UI updates automatically.
🛠️ Implementation (Production-Ready Examples)
🧱 XML Example (Classic UI)
Gradle
android {
buildFeatures {
viewBinding true
}
}
layout/activity_main.xml
<?xml version="1.0" encoding="utf-8"?>
<LinearLayout
xmlns:android="http://schemas.android.com/apk/res/android"
android:layout_width="match_parent"
android:layout_height="match_parent"
android:gravity="center"
android:orientation="vertical">
<TextView
android:id="@+id/tvTitle"
android:layout_width="wrap_content"
android:layout_height="wrap_content"
android:text="Hello XML"
android:textSize="20sp"/>
<Button
android:id="@+id/btnClick"
android:layout_width="wrap_content"
android:layout_height="wrap_content"
android:text="Click Me"/>
</LinearLayout>
MainActivity.kt
class MainActivity : AppCompatActivity() {
private lateinit var binding: ActivityMainBinding // Avoid findViewById
override fun onCreate(savedInstanceState: Bundle?) {
super.onCreate(savedInstanceState)
binding = ActivityMainBinding.inflate(layoutInflater)
setContentView(binding.root)
binding.btnClick.setOnClickListener {
binding.tvTitle.text = "Clicked!"
}
}
}
⚠️ Issues in XML Approach
⚡ Jetpack Compose Example
Dependencies
implementation "androidx.compose.ui:ui:1.6.0"
implementation "androidx.compose.material3:material3:1.2.0"
implementation "androidx.activity:activity-compose:1.8.2"
MainActivity.kt
class MainActivity : ComponentActivity() {
override fun onCreate(savedInstanceState: Bundle?) {
super.onCreate(savedInstanceState)
setContent {
MyApp()
}
}
}
UI Code
@Composable
fun MyApp() {
var text by remember { mutableStateOf("Hello Compose") }
Column(
modifier = Modifier.fillMaxSize(),
verticalArrangement = Arrangement.Center,
horizontalAlignment = Alignment.CenterHorizontally
) {
Text(
text = text,
fontSize = 20.sp
)
Button(
onClick = {
text = "Clicked!"
}
) {
Text("Click Me")
}
}
}
🔥 Why This Is Better
State-driven UI
👉 UI reacts automatically
⚠️ Edge Cases & Real-World Considerations
1. Performance
XML:
Compose:
👉 Best Practice:
Avoid unnecessary recompositions
Use remember, derivedStateOf
2. Memory Management
XML:
Compose:
👉 Compose reduces leak chances significantly.
3. Large Projects
XML:
Compose:
4. Interoperability (IMPORTANT)
You don’t need to fully switch.
👉 You can mix both:
setContent {
AndroidView(
factory = { context ->
LayoutInflater.from(context).inflate(R.layout.old_layout, null)
}
)
}
🧠 When Should You Use What?
Use XML if:
Use Compose if:
🏁 Final Verdict
👉 XML is stable and proven
👉 Compose is the future
Google is clearly pushing Compose:
New libraries → Compose-first
Material 3 → Compose-first
Updates → Compose-focused
🎯 Challenge for You
👉 Have you tried migrating an XML screen to Compose?
💬 Drop your experience in comments — let’s learn from real-world cases.
Feel free to reach out to me with any questions or opportunities at ([email protected])
LinkedIn (https://www.linkedin.com/in/ahsan-ahmed-39544b246/)
Facebook (https://www.facebook.com/profile.php?id=100083917520174).
YouTube (https://www.youtube.com/@mobileappdevelopment4343)
Instagram (https://www.instagram.com/ahsanahmed_03/)
Introduction
I spent some time exploring the Model Context Protocol (MCP). Not a deep dive—just a hands-on attempt to understand how it actually works.
So I built a minimal client + server setup:
👉 https://github.com/an1meshk/claude-chat-cli
In a real-world project, we will build client and server separately; however, as this was just a demo project, everything was built in the same project
A few things stood out more than I expected.
Demo
🧠 Context
The goal wasn’t to learn everything about MCP. It was to answer a simpler question:
How hard is it to actually build something with it?
Before moving further, here is a quick MCP client and server architecture diagram:

⚙️ What I Tried
Nothing complex—but enough to see how things fit together.
💡 What Stood Out
1. Setup Is Simpler Than Expected
I was expecting some heavy setup. But, instead:
👉 It felt closer to:
“Define a few handlers, and you’re up.”
than:
“learn a new framework.”
2. The Real Concept Is Context Flow
The interesting part wasn’t the server setup. It was understanding:
That’s where the mental shift is.
🧠 What Helped Me Understand It
This simple mental model made things click:
image credit Anthropic academy course
Client → MCP Server → Tool → Response → Client
Once this clicked, everything else made more sense
⚡ If You Want to Try It
The setup is intentionally minimal:
That’s enough to understand the core idea
Repo:
https://github.com/an1meshk/claude-chat-cli
You will need an Anthropic API key, as this project uses Claude
⚙️ One More Thing That Helped
Project uses uv for dependency management. That helps in a few ways:
It removes a lot of the usual setup overhead
⚠️ What I Haven’t Explored Yet
This was just a first pass. Still curious about:
🧠 Initial Take
My early impression:
The setup is easy.
The thinking is where the work is.
🏁 Final Thought
Sometimes the best way to understand a new concept is:
Build the simplest possible version of it
This was one of those cases.
If you have reached here, then I have made a satisfactory effort to keep you reading. Please be kind enough to leave any comments or share any corrections.
My Other Blogs:
IP ADDRESS
In real life, let’s say you want to find a place or you want to reach a place you need to know the location or precisely the address of that place. Similarly in computers IP address is used to know or denote a particular computer that is connected under the same network. Basically, every node(device) connected under the same network has a unique address known as IP address.
Example of an IP address: 10.1.32.12
Each part has 8 bits and can store 0-255 values.
SUBNETS
In a large network, communication between different devices take too much time or is unnecessary. Here, Subnets helps separate or breakdown the network into different parts so that communication is easier and not unnecessary. Imagine in a college it has one Public IP(large network) here we use subnets for each block or department so that communication in the department is fast and effective.
How Subnets and IP address work
Every IP belongs to a subnet. Subnets tell you the number of ip’s or the the range of IP addresses that are available or fall under that subnet.
For example lets take an IP address: 192.168.1.10
There are always two parts in an IP address
-Network
-Host
Here 192.168.1 is network and 10 denotes host.
To know how many IP’s are stored for networks and host we use a method called CIDR(Classless Inter Domain Routing).
CIDR helps us to know how many devices one can connect under a subnet in an IP. The notation for CIDR is a.b.c.d/n
Example:10.1.32.12/24
Here, /24 means 256 devices can be connected and is stored for networks.
Your Pipeline Is 25.4h Behind: Catching Real Estate Sentiment Leads with Pulsebit
We recently discovered a compelling anomaly: a 24h momentum spike of +0.709 in the real estate sector. This spike isn’t just a number; it represents a significant shift in sentiment that could influence your decisions. The leading language fueling this spike is English, with a notable press cluster revolving around a report from ULI NWA on emerging trends in local real estate. With just one article triggering this movement, it’s clear that the narrative is forming and could shape broader market discussions.
The Problem
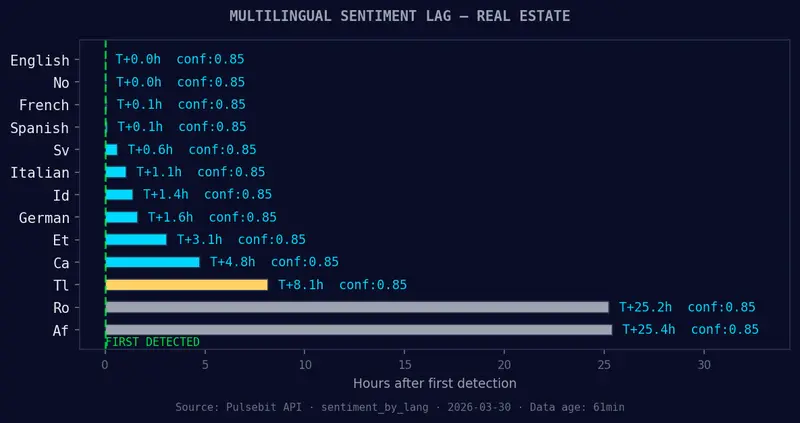
This spike reveals a structural gap in pipelines that don’t account for multilingual origins or entity dominance. If your model isn’t designed to handle these nuances, you missed this real estate sentiment shift by 25.4 hours. The dominant entity, NWA, released crucial insights into emerging trends, which could have informed your strategy. Your model’s blind spot to this specific English-language sentiment can lead to missed opportunities in a rapidly changing landscape.

English coverage led by 25.4 hours. Af at T+25.4h. Confidence scores: English 0.85, No 0.85, French 0.85 Source: Pulsebit /sentiment_by_lang.
The Code
To catch this momentum spike, we can leverage our API effectively. The first step is to filter for English-language content that is specifically relevant to the real estate topic. Here’s how to do that:
import requests
# Define the query parameters
params = {
"topic": "real estate",
"score": -0.066,
"confidence": 0.85,
"momentum": +0.709,
"lang": "en"
}
# Make the API call
response = requests.get("https://api.pulsebit.com/v1/sentiment", params=params)
data = response.json()

*Left: Python GET /news_semantic call for 'real estate'. Right: returned JSON response structure (clusters: 3). Source: Pulsebit /news_semantic.*
print(data)
Next, we need to score the narrative framing itself around the cluster reason string. This is crucial as it allows us to analyze how the themes interact with one another. The cluster reason string we’re working with is: “Clustered by shared themes: nwa, releases, ‘emerging, trends’, report.”. Here’s how to execute that:
# Define the narrative for sentiment scoring
narrative = "Clustered by shared themes: nwa, releases, ‘emerging, trends’, report."
# Make the POST request to score the narrative
response = requests.post("https://api.pulsebit.com/v1/sentiment", json={"text": narrative})
narrative_score = response.json()
print(narrative_score)
Three Builds Tonight
With this pattern in mind, here are three specific builds you can implement:

Geographic detection output for real estate. India leads with 7 articles and sentiment -0.24. Source: Pulsebit /news_recent geographic fields.
params = {
"topic": "real estate",
"momentum": "+0.5",
"lang": "en"
}
narrative = "Clustered by shared themes: nwa, releases, ‘emerging, trends’, report."
if momentum > +0.5 and "real estate" in narrative:
trigger_alert()
Get Started
Ready to dive deeper? Check out our full documentation at pulsebit.lojenterprise.com/docs. You can copy-paste these examples and run them in under 10 minutes. Let’s harness the power of sentiment data to stay ahead of the curve!
Everything looks fine when you have one container. Add a second, and your Docker Configuration already starts drifting toward chaos — then come databases and caches, and the whole setup turns fragile. Ports collide, data disappears, services randomly fail to connect.
The problem isn’t Docker itself. It’s how people build and ignore their compose configs early on. Treat it like a temporary script — and you’ll get a system nobody wants to touch later.
At the core, every docker compose file is built on three things: services, volumes, and networks. Sounds simple — until you mix them incorrectly.
Services define containers. Volumes handle persistence. Networks control communication. Break that separation, and your config becomes unmaintainable.
services:
web:
image: nginx:1.25-alpine
ports:
- "8080:80"
restart: unless-stopped
No junk, no legacy keys. And yes — no “version”. It’s deprecated, and keeping it just signals outdated practices in your docker compose configuration.
The real issues start with volumes and networks.
Anonymous volumes vanish on shutdown — that’s silent data loss waiting to happen. No explicit network setup leads to service discovery problems that are painful to debug later.
A proper docker compose yaml example always makes persistence and isolation explicit. Named volumes stay. Networks define who talks to whom. Anything else is guesswork.
A good docker compose example isn’t the shortest one — it’s the one that reflects production intent.
If your container doesn’t need write access, don’t give it. If your ports are exposed, know exactly why. Small constraints here prevent big debugging sessions later.
Things get interesting when you add a database.
Most developers rely on docker compose depends_on and assume it solves startup order. It doesn’t. It only waits for the container, not the service inside it. That’s how you get random connection failures on boot.
services:
api:
image: node:20-alpine
depends_on:
db:
condition: service_healthy
db:
image: postgres:16-alpine
healthcheck:
test: ["CMD-SHELL", "pg_isready"]
interval: 5s
Health checks are what actually fix race conditions. Without them, you’re just hoping timing works out — and that’s not how stable docker compose configurations are built.
Handling docker compose env variables the wrong way is another classic mistake. Hardcoding secrets inside YAML is how configs leak and environments drift.
Use .env files. Keep configs clean. Swap environments without rewriting everything.
Also — never use latest tags. Pin versions. Every time. Non-deterministic builds are a slow-moving disaster.
The fastest way to catch half of them — run docker compose config before deployment.
Docker compose in production is fine — as long as you stay within its limits. Single host, a few services, predictable load — it works cleanly.
But once you need scaling across machines, load balancing, or orchestration — Compose stops being enough. That’s where Kubernetes comes in.
A solid docker compose configuration isn’t about complexity — it’s about control.
If your setup is predictable, reproducible, and doesn’t rely on one person to understand it — you did it right. If not, it’s just a matter of time before it breaks.
If you have been using Claude Code for more than a week, you have almost certainly written a CLAUDE.md file. And if you are like most developers, your first version was not very good — mine was not, either.
The file probably read something like: “This is a TypeScript project. We use Express and Prisma. Follow best practices.”
That is not a CLAUDE.md. That is a README. And it produces the same result as no CLAUDE.md at all, because it tells the agent about the project without telling it how to behave.
This article is about the difference between those two things, and the structure I have settled on after iterating through a lot of versions.
The mental model shift
CLAUDE.md is not documentation. It is a behavioral contract.
Documentation describes what something is. A behavioral contract specifies what an agent must do, must not do, and should do by default in the absence of other instructions.
When you write “This is a TypeScript project using Prisma,” you are writing documentation. The agent might infer some behavioral rules from it — it might assume you want TypeScript syntax, might guess you want Prisma for database access — but it is guessing, and guesses are inconsistent.
When you write “All database access must go through the repository layer in /src/repositories. Never write Prisma queries directly in route handlers,” you have written a policy. The agent follows policies reliably. It guesses at implications inconsistently.
This distinction shapes everything.
The structure I use
Every CLAUDE.md I write now has six sections. Not all sections need to be long — some projects have two lines in a section, others have fifteen — but the structure is consistent.
1. Project identity (one paragraph maximum)
Not documentation. A one-sentence description of the project type and domain, followed by one sentence about the primary development mode: “This is a production API, not a prototype. Stability and test coverage take priority over velocity.”
That second sentence is the behavioral load-bearing one. It tells the agent how to weight tradeoffs throughout every session.
2. Always do
Explicit, specific behaviors the agent should apply without being asked. This is not a wishlist — every item must be something you actually want on every task, not just some tasks.
Examples from my current API project:
- After implementing any new function, run the test suite before reporting completion.
- Every new function needs at least one happy-path test and one error-case test.
- When modifying database-touching code, check for missing index usage before finishing.
- Log at the appropriate level: debug for development noise, info for business events, error for failures that need attention.
The specificity matters. “Always write tests” generates one trivial test. “Every new function needs at least one happy-path test and one error-case test, using Vitest, in a .test.ts file in the same directory as the source file” generates what you actually want.
3. Never do
This section has the highest leverage per line of anything in CLAUDE.md. Every time the agent does something that frustrates you — a pattern you always correct, a shortcut you always revert — write a rule here.
Over time, this list becomes your project’s permanent memory of what does not work.
Mine includes:
- Never modify committed migration files. Create a new migration instead.
- Never use `any` in TypeScript. If the type is genuinely unknown, use `unknown` and handle it.
- Never write inline styles. All styling goes through the design system tokens.
- Never hard-code environment-specific values. Use environment variables accessed through the config module.
- Never `console.log` in production code. Use the structured logger at `/src/lib/logger.ts`.
- Never declare a task done before running the test suite.
The last one is important. Without it, agents have a consistent bias toward reporting completion before verifying it.
4. Code style and conventions
This is where stack-specific rules live. Not a style guide — that belongs in ESLint or your linter config. This section covers the decisions that automated tools cannot enforce: naming patterns, module organization, error handling philosophy.
For a TypeScript API:
- Error handling: all errors should be typed. Throw typed errors, not plain Error objects.
- Repository functions return Result types (Ok/Err), not throw. Route handlers translate Results to HTTP responses.
- File naming: kebab-case for files, PascalCase for exported classes and types, camelCase for everything else.
- Module boundaries: `/services` contains business logic, `/repositories` contains data access, `/routes` contains HTTP handling. These do not import from each other laterally — data flows up through the stack.
5. Scope and tool permissions
What the agent is allowed to do, what requires approval, and what it must not do at all with its tool access.
- Shell commands that modify the database (migrations, seeds) require explicit approval before execution.
- Never delete files — move to a `.trash/` directory at the repo root instead.
- Changes to `/config/` files require explicit approval.
- Infrastructure changes (any file under `/terraform/`) are read-only — do not modify, only read to understand context.
The “never delete, move to trash” pattern is one I adopted after an agent deleted a file that turned out to be needed and was not in git. Moving to trash gives a one-step recovery.
6. Memory guidance
Instructions for what to write to persistent memory versus what should stay in CLAUDE.md.
- Write project-specific decisions and their rationale to `.claude/memory/project.md`.
- Write discovered patterns (API quirks, library behavior) to `.claude/memory/discoveries.md`.
- Do not write temporary task context to memory — only durable knowledge.
This prevents memory from becoming a graveyard of task notes while ensuring genuine discoveries persist across sessions.
Nested CLAUDE.md for monorepos
If you have a monorepo, a single root CLAUDE.md that tries to cover everything produces long, confused instructions. Claude Code supports nested files — a CLAUDE.md in a subdirectory extends or overrides the root for that scope.
My structure:
CLAUDE.md # Global conventions, security rules, commit format
apps/api/CLAUDE.md # API-specific rules (error handling, test patterns)
apps/web/CLAUDE.md # Frontend-specific rules (component conventions, CSS)
packages/shared/CLAUDE.md # Library rules (public API discipline, no side effects)
Each child file is short and focused. The agent only loads what is relevant to its current working location.
The root file carries the rules that apply everywhere and that you never want to repeat — the security rules, the commit message format, the things that are never acceptable anywhere in the codebase.
Versioning and maintenance
Treat CLAUDE.md as code. Version it in git. Review changes in PRs. When you update a rule, add a comment explaining why — especially for “never do” items, where the reason is often a specific bad experience that is not obvious from the rule text.
I keep a # Changelog section at the bottom of each CLAUDE.md with the three most recent changes and their dates. It makes it easy to understand why a rule exists when you come back to it months later.
What I got wrong before getting this right
In roughly the order I learned them:
The last one is the most important. The best CLAUDE.md files are the ones that get updated every time something goes wrong, until “going wrong” becomes rare.
Going deeper
This article covers Chapter 1 of a longer technical guide I published: Claude Code: The Production Guide. The full guide covers agent harnesses, parallelization with git worktrees, the auto-research framework, memory systems, MCP server security, and the complete security hardening model for running Claude Code with real shell and filesystem access.
If you are using Claude Code seriously and want the complete picture: Claude Code: The Production Guide ($29)
I also released a template pack with 15 ready-to-use CLAUDE.md configurations for specific stacks (Go, Python/FastAPI, Next.js, Terraform, dbt, and more) if you want a starting point rather than building from the structure above: CLAUDE.md Template Pack ($19)
What patterns have you found in CLAUDE.md that actually work? The comments are a good place for this — I find the design space genuinely interesting and there are almost certainly good patterns I have not tried.

This is Part 2 of the AWS vector database series.
👉 Missed Part 1? Start here: Embeddings, Dimensions, and Similarity Search
In Part 1, we covered the fundamentals of embeddings and how similarity is measured. Now we move into how retrieval actually works in practice.
In this part, we’ll look at search patterns (KNN vs ANN), hybrid search, metadata filtering, and chunking strategies — the building blocks of effective RAG systems.
Vector Search Types
The following section explains the vector search types
| Approach | How it works | When to use | AWS services |
|---|---|---|---|
| KNN — Exact Nearest Neighbor Search | Check every single item, compare it to your query, return the best matches. Perfectly accurate, but slow. | Small datasets (under 100K vectors) or situations where you absolutely cannot afford to miss a result — like medical diagnostics or legal compliance checks. | All vector services support KNN as a fallback, but it’s not practical at scale. |
| ANN — Approximate Nearest Neighbor Search | Uses a smart index structure (graph or cluster) to find very likely nearest neighbors without checking everything | Almost everything in production. If you’re building a RAG chatbot, semantic search, or recommendation engine, this is your default. | OpenSearch Serverless, Aurora pgvector, MemoryDB, ElastiCache Valkey, DocumentDB, S3 Vectors, Neptune Analytics. |
Hybrid Search
Hybrid search runs two searches at the same time—one that understands meaning (vector search) and one that looks for exact words (keyword search)—and then combines the results.
For example, a user might search: “lambda timeout issue nodejs.”
Note: The scoring method used to combine these two result sets is called Reciprocal Rank Fusion (RRF). It doesn’t simply add scores—it prioritizes documents that rank highly in both searches. For example, if a document ranks #1 in keyword search and #2 in vector search, RRF will push it to the top of the final results.
This is especially useful for enterprise RAG. Users rarely search with purely natural language or purely exact keywords—they usually mix both.
| Service | Implementation |
|---|---|
| OpenSearch Serverless | Supports Native (RRF). The most robust option; its “Neural Search” feature handles the hybrid merging automatically. |
| Aurora pgvector | This is sql based and best for relational data; you manually combine tsvector (keywords) and vector (meaning) in one query. |
Metadata Filtering
Metadata filtering narrows down results using structured data like date, category, or user ID—before or after the vector search runs.
Think of it like this: a vector search finds books similar to Harry Potter. But you only want books published after 2010 and available in English. Metadata filtering ensures you don’t waste time on the wrong results.
Pre-filtering vs Post-filtering
| Approach | How it works | Trade-offs |
|---|---|---|
| Pre-filtering | Applies filters first, then runs vector search on the remaining data | Accurate and secure, but can be slower depending on the engine |
| Post-filtering | Runs vector search first, then filters the results | Fast, but may return zero results if none match the filters |
Note: S3 Vectors uses a technique called tandem filtering, where metadata filters are applied during the vector search itself. This combines the accuracy of pre-filtering with the performance of post-filtering, making it well-suited for very large datasets.
Chunking
Chunking is simply breaking a long document into smaller, meaningful pieces before creating embeddings. If your chunks are too small, you lose context. If they’re too big, the important meaning gets buried in noise. The goal is to find the right balance.
Common Chunking Strategies
| Strategy | How it works | Chunk size | Best for |
|---|---|---|---|
| Fixed-size | Split every N tokens/characters with optional overlap | 256–512 tokens | Simple content like logs or short descriptions |
| Recursive | Split by paragraphs → sentences → words while preserving structure | Variable | General-purpose text (default in most tools) |
| Semantic | Use an embedding model to split based on topic boundaries | Variable | Long-form content like whitepapers or legal docs |
| Document-structure | Split using headings, sections, or document layout | Variable | Structured docs like manuals, HTML, or code |
| Sentence-window | Store sentences, return surrounding context at query time | 1 sentence (store) / window (return) | High-precision Q&A |
Bedrock Chunking Options
| Bedrock option | What it does | Equivalent concept |
|---|---|---|
| Default | ~300-token chunks that respect sentence boundaries | Recursive (baseline) |
| Fixed-size | You control chunk size and overlap | Fixed-size |
| Hierarchical | Searches small chunks but returns larger context | Sentence-window |
| Semantic | Splits based on topic boundaries | Semantic |
| None | No splitting — entire file treated as one chunk | Document-structure (manual) |
👉 Continue reading: In Part 3, we’ll compare AWS vector database options and build a practical decision framework to help you choose the right one.
This is where everything comes together.
👉 In case you missed it:
By now, you understand the fundamentals and how retrieval works. The real question is:
Summary Comparison
| Service | Model | Strength | Scaling | Bedrock KB |
|---|---|---|---|---|
| OpenSearch Serverless | Distributed | Full-text + semantic search | Automatic (OCU) | Yes |
| Aurora pgvector | Relational | SQL + vector hybrid queries | Serverless v2 | Yes |
| S3 Vectors | Object storage | Massive scale, lowest cost | Fully serverless | Yes |
| MemoryDB | In-memory | Ultra-low latency | Cluster-based | No |
| Valkey (ElastiCache) | In-memory | Semantic caching | Cluster-based | No |
| Neptune Analytics | Graph | Relationships + vectors | Automatic | Yes |
| DocumentDB | Document | JSON + vector workloads | Instance-based | Yes |
| Kendra | Managed | Enterprise search | Fully managed | N/A |
Decision Matrix
| Scenario | Recommended | Alternative |
|---|---|---|
| General-purpose RAG | OpenSearch Serverless | Aurora pgvector |
| Existing PostgreSQL app | Aurora pgvector | DocumentDB |
| Ultra-low latency (real-time) | MemoryDB | Valkey |
| Reduce LLM cost (caching) | Valkey | MemoryDB |
| Knowledge graph + vectors | Neptune | OpenSearch |
| Massive scale (billions) | S3 Vectors | OpenSearch |
| Enterprise search (managed) | Kendra | Bedrock KB + S3 |
| Agent memory (short-term) | Valkey / MemoryDB | S3 Vectors |
Cost Reality (2026)
| Service | Model | Key Driver |
|---|---|---|
| S3 Vectors | Storage + query | Cheapest at scale |
| Aurora pgvector | Instance + storage | Cheaper if shared DB |
| OpenSearch Serverless | OCU hours | Minimum baseline cost |
| DocumentDB | Instance + I/O | I/O adds up |
| MemoryDB / Valkey | In-memory | RAM is expensive |
| Kendra | Flat fee | Enterprise pricing |
Graviton5 has reduced compute costs by ~20%, but memory-heavy systems still cost the most.
When NOT to Use a Vector Database
Before building anything, check this:
That’s a wrap on the series. If you’re building with RAG or semantic search on AWS, you now have both the conceptual foundation and practical guidance to choose the right architecture.
Introduction & Problem Statement
Imagine you’re a developer tasked with integrating Oxlint and Oxfmt into a complex project. You’re halfway through configuring these tools when you hit a wall: Does Oxlint support React Native? Can Oxfmt handle TypeScript files with JSX? Without a centralized resource, you’re forced to scour forums, GitHub issues, or trial-and-error—a process that wastes hours and erodes trust in the Oxc ecosystem. This scenario wasn’t hypothetical; it was the norm until recently, when the Oxc documentation finally introduced a compatibility overview page. But why did this gap exist, and what does its resolution mean for developers?
The Root of the Problem: Fragmented Information, Amplified Complexity
The issue wasn’t just a lack of documentation—it was the decentralized nature of what existed. Compatibility details were scattered across README files, GitHub discussions, and community threads. This fragmentation created a mechanical inefficiency: developers had to assemble a puzzle of information, often leading to misconfigurations (e.g., using Oxlint with an unsupported framework) or abandoned workflows due to uncertainty. The growing complexity of the Oxc ecosystem—with its expanding list of frameworks and file types—exacerbated this, as each new addition introduced uncertainty multipliers.
For instance, a developer working with Vue 3 might assume Oxfmt supports its single-file components (.vue files) based on its TypeScript compatibility. Without explicit documentation, this assumption could lead to runtime errors or formatting inconsistencies, as the tool silently fails to parse Vue-specific syntax. The causal chain here is clear: ambiguity → incorrect assumptions → tool misuse → project delays.
Why Centralization Matters: A Mechanical Analogy
Think of Oxlint and Oxfmt as gears in a machine, and frameworks/file types as the cogs they must mesh with. Without a clear blueprint (centralized documentation), the gears risk grinding against incompatible cogs, causing friction (developer frustration) and wear (wasted time). The new compatibility page acts as a precision-engineered diagram, ensuring each gear fits its intended cogs. This isn’t just about convenience—it’s about preventing mechanical failure in the development workflow.
Edge Cases and Risk Mechanisms
Consider a developer using Oxlint with Svelte, a framework not yet listed on the compatibility page. Without explicit “unsupported” status, they might proceed, only to encounter false positives in linting or syntax misinterpretation. The risk here forms via a feedback loop: lack of documentation → user experimentation → undetected incompatibility → project bugs. Centralization breaks this loop by providing a stopgap: if Svelte isn’t listed, it’s a red flag, not an invitation to guess.
The Optimal Solution: Centralization Over Decentralization
While alternatives like community-maintained wikis or auto-generated compatibility matrices were considered, they fall short. Wikis suffer from inconsistency and outdatedness, while auto-generated matrices lack nuanced explanations (e.g., “partially supported” vs. “fully supported”). Centralized, manually curated documentation is optimal because it:
However, this solution has a breaking point: if updates lag behind tool releases, the documentation becomes stale, reverting the ecosystem to its pre-centralized chaos. The rule here is clear: If documentation isn’t synchronized with tool development → centralization fails.
Conclusion: A Blueprint for Trust
The addition of a centralized compatibility overview isn’t just a documentation update—it’s a structural reinforcement of the Oxc ecosystem. By eliminating ambiguity, it transforms Oxlint and Oxfmt from tools with potential into reliable components of developer workflows. The lesson? In technical ecosystems, clarity isn’t a luxury—it’s the load-bearing beam that prevents the entire structure from collapsing under the weight of complexity.
Compatibility Analysis: Oxlint and Oxfmt in the Wild
The Oxc ecosystem, like a finely tuned machine, relies on precise compatibility between its tools and the frameworks they interact with. Oxlint and Oxfmt, as critical cogs in this machine, must mesh seamlessly with various file types and frameworks to avoid mechanical failure in developer workflows. The recent addition of a centralized compatibility overview acts as a precision-engineered diagram, ensuring these tools function as intended. Here, we dissect six key scenarios, exposing the mechanisms of compatibility, the risks of misalignment, and the workarounds that keep the system running.
Scenario 1: React Ecosystem
File Types: .jsx, .tsx
Compatibility: Fully supported by both Oxlint and Oxfmt.
Mechanism: React’s component-based architecture aligns with Oxlint’s parsing logic, allowing it to detect syntax errors and enforce coding standards without deforming the structure of .jsx and .tsx files. Oxfmt’s formatter expands readability by aligning props and state variables according to React’s conventions.
Risk: Misconfigured React versions (e.g., React 18 with experimental features) can cause Oxlint to overheat—flagging false positives due to unrecognized syntax. This heats up the debugging process, wasting developer time.
Workaround: Explicitly specify React version in configuration files to prevent misinterpretation.
Scenario 2: Vue 3 Projects
File Types: .vue
Compatibility: Partially supported. Oxlint handles `
Recommendations & Best Practices for Oxlint and Oxfmt Compatibility
The introduction of a centralized compatibility overview for Oxlint and Oxfmt in the Oxc documentation is a precision-engineered solution to a problem that acted like a friction point in developer workflows. Here’s how to leverage this resource effectively, avoid common pitfalls, and ensure these tools function as reliable gears in your ecosystem.
1. Framework-Specific Configuration: Aligning Tools with Ecosystem Mechanics
Think of Oxlint and Oxfmt as calibrated instruments—their effectiveness depends on alignment with the framework’s structural mechanics. Misalignment causes mechanical failure in workflows:
.jsx, .tsx): Oxlint’s parsing logic meshes with React’s component architecture, but version mismatches (e.g., React 18 experimental features) act like foreign particles in a machine, causing false positives.
oxlint.config.json) to re-calibrate the tool.Vue 3 Projects (.vue): Oxlint partially engages with Vue’s
Conclusion & Future Outlook
The introduction of a centralized compatibility overview for Oxlint and Oxfmt in the Oxc documentation marks a pivotal shift from fragmented guesswork to precision-engineered clarity. This move addresses a critical pain point: developers previously navigated a maze of READMEs, GitHub issues, and forums, often leading to misconfigurations and project delays. For instance, assumptions about Vue 3 .vue file support resulted in runtime errors due to Oxlint’s incomplete parsing of Vue-specific syntax in templates and styles. The causal chain is clear: ambiguity → incorrect assumptions → tool misuse → delays.
Centralized documentation acts as a load-bearing beam in the Oxc ecosystem, preventing its collapse under growing complexity. By explicitly listing supported frameworks and file types, it eliminates mechanical inefficiency—developers no longer waste time puzzle-solving for compatibility information. For example, React projects now have a clear mechanism to avoid false positives: explicitly specify the React version in oxlint.config.json. This alignment ensures Oxlint’s parsing logic meshes seamlessly with React’s component architecture, akin to gears interlocking with cogs in a machine.
However, edge cases remain. Unlisted frameworks like Svelte risk false positives or syntax misinterpretation without an explicit “unsupported” status. This is a mechanical failure point: the documentation must synchronize with tool releases to avoid staleness. If the documentation lags, it becomes a rusted gear, causing friction in workflows.
Looking ahead, stakeholders must prioritize manual curation of this documentation. Automated solutions risk missing context—such as version requirements or edge cases—that only human maintainers can provide. The optimal solution is a manually curated, centralized resource maintained by core contributors. This ensures accuracy, context, and future-proofing. A rule of thumb: If X (ecosystem complexity increases) → use Y (centralized, manually curated documentation).
In conclusion, centralized documentation transforms Oxlint and Oxfmt from unreliable tools into trusted components of the Oxc ecosystem. Clarity is not a luxury—it’s a necessity. Without it, the ecosystem risks mechanical failure under its own weight. By addressing this gap, the Oxc team has not only improved developer productivity but also reinforced trust in their tools. The future demands vigilance: keep the documentation synchronized, address edge cases, and ensure it remains a precision-engineered diagram for seamless tool-framework compatibility.