PlayStation 6 için yeni iddialar ortaya atıldı

PlayStation 6 LOG Tasarım

PlayStation 6 LOG Tasarım2027 ya da 2028 yılında satışa sunulması beklenen PlayStation 6 için güvenilir kaynak Kepler_L2 tarafından yeni iddialar ortaya atıldı. Modelin disk sürücüsü olmadan 1 TB SSD ile geleceğine ve 700 dolardan satışa sunulabileceğine (mevcut parça maliyeti 760 dolar olarak hesaplanıyor; toplu alım indirimiyle Sony’nin konsolu 700 dolara satabileceği düşünülüyor) işaret eden kaynak, PS6 SDK’sinin nöral doku sıkıştırma altyapısına destek vermesi halinde oyun boyutlarının hatırı sayılır oranda azaltılabileceğini de belirtiyor. “Oyun boyutları PS5’tekinden bile daha küçük olabilir.” diyen kaynak, 1 TB SSD’nin bu konuda beklenen adım atılırsa büyük bir sorun olmayacağını aktarıyor. SSD ve RAM fiyatlarındaki artış nedeniyle PS6’ya satış fiyatını aşırı artırmadan 2 TB SSD koyması çok olası görünmeyen Sony, geçtiğimiz hafta PlayStation 5 serisine zam yaptığını duyurmuştu.

PlayStation 6 için yeni iddialar ortaya atıldı yazısı ilk olarak Teknoloji haberleri – LOG üzerinde yayınlandı.

Why Your AWS RDS Bill Keeps Increasing: Here’s What No One Tells You (2026)

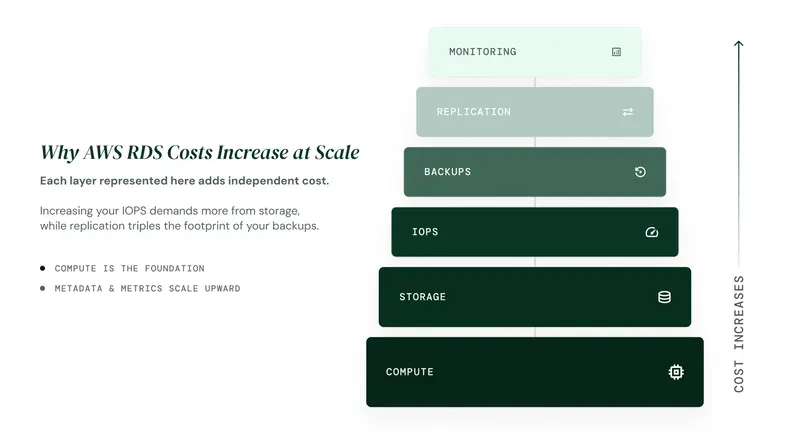
AWS Cost inrease at scale

Why AWS RDS Is Expensive Once Your Product Starts Growing

If you’ve ever opened your cloud bill and paused a little longer than usual, you’re not alone. At some point in every growing product’s journey, teams start asking the same quiet question: why is RDS so expensive, especially when it didn’t feel that way at the start.

The direct answer is that AWS RDS is expensive because you’re not paying for just a database. You’re paying for a stack of components such as compute, storage, replication, backups, and high availability which are all billed independently.

As your architecture matures, those layers compound rather than grow linearly. That’s why AWS RDS becomes expensive faster than most teams expect.

For teams hitting these limits, newer deployment models like BYOC (Bring Your Own Cloud) are also starting to emerge as an alternative.

Flexera’s 2026 State of the Cloud Report surveyed 753 cloud decision-makers worldwide. The results showed that 29% of cloud spend is currently wasted, and managing cloud costs remains the number one challenge for 85% of organisations. RDS over-provisioning is one of the most consistent contributors to that figure.

Despite this, RDS is popular for a good reason. It’s simple to launch, easy to manage, and removes real operational burden from small teams. In the early stages, that convenience is a genuinely smart trade-off.

This is exactly why many teams eventually start exploring how growing startups evaluate managed vs self-hosted database trade-offs.

This article is not about criticising AWS. It’s about explaining, with verified 2026 pricing data, exactly why AWS RDS is expensive as your product scales and what your options actually are when you reach that point.

Why AWS RDS Is Expensive: How the Pricing Model Actually Works

Understanding why AWS RDS is expensive starts with one key insight: you are never paying for a single thing. You are paying for a stack of services, each billed on its own meter.

Here is what that stack looks like in practice:

  1. – 1. Instance hours – compute (CPU and RAM) billed per second
  2. – 2. Storage – gp2, gp3, or io1, charged per GB per month
  3. – 3. Automated backup storage – free up to 100% of database size, billed beyond that
  4. – 4. Provisioned IOPS – charged separately from storage on io1
  5. – 5. Multi-AZ standby – a full second instance billed at the same rate
  6. – 6. Read replicas – each one is an independent full-price instance
  7. – 7. Manual snapshots – persist indefinitely, accumulate silently
  8. – 8. Data transfer – cross-AZ replication, outbound traffic

AWS Cost inrease at scale
Key principle:

Each component is billed independently. Individually they feel small. Together, they explain why AWS RDS is expensive at scale.

AWS documents this on its official pricing page. The components are listed clearly.

What the pricing page doesn’t show is how they stack on top of each other and why RDS is expensive specifically when multiple layers are active at the same time.

The Growth Inflection Point That Makes AWS RDS Expensive

Most teams don’t ask why RDS is expensive in the early stage. The costs feel reasonable, and the convenience is real.

The question surfaces when:

  1. The product stabilises and retains paying customers
  2. Downtime becomes financially and reputationally costly
  3. Customer expectations around uptime and performance increase
  4. Compliance or data residency requirements enter the picture
    That’s the real inflection point where teams first understand why RDS is expensive and it’s not driven by traffic alone, it’s driven by architecture maturity.

RDS Costs increase at architecture scales

What actually changes at the growth stage

The shift isn’t just more users. It’s the architecture decisions those users demand:

  1. Multi-AZ enabled for production reliability
  2. One or more read replicas for query performance
  3. A staging environment that mirrors production
  4. Longer backup retention windows (7 to 35 days)
  5. Higher IOPS as write-heavy workloads grow
    Each of these is a separate billing layer and this compounding is precisely why RDS is expensive at the growth stage. Combined, they can turn a $150/month database into a $700–$900/month database without a single change to your application code.

The insight: AWS RDS is not expensive at the beginning. It becomes expensive when reliability becomes non-negotiable and your architecture starts to reflect that.

This is the moment teams start asking whether managed databases are still the right model for their stage.

What AWS RDS Actually Costs at Scale: Verified 2026 Pricing

To show exactly why AWS RDS is expensive in practice, the following tables use verified AWS on-demand pricing for us-east-1 (N. Virginia) as of March 2026, for a PostgreSQL workload on db.m6g.large. All figures are cross-referenced against Vantage EC2 Instances and AWS official pricing documentation.

Early stage: Single AZ, light workload

Early stage: Single az, Light workload
Pricing based on AWS on-demand rates, us-east-1 (N. Virginia), March 2026. You can Verify current rates on official Amazon RDS pricing page.

Growth stage: Multi-AZ, read replica, staging environment

Growth stage:Multi-az,read replica, staging environment
Pricing based on AWS on-demand rates, us-east-1 (N. Virginia), March 2026. Figures will vary by region, instance generation, and storage type. Verify current rates on the official Amazon RDS pricing page.

These figures are illustrative for a db.m6g.large workload in us-east-1.

To model your specific instance type, storage type, region, and backup retention, use the AWS Pricing Calculator.

Note: The io1 / Provisioned IOPS row only applies if your workload requires guaranteed IOPS beyond what gp3 provides. Most teams running standard workloads on gp3 will not see this charge. If you are on Reserved Instances, compute costs reduce by 30–40% on a 1-year term and up to 60% on a 3-year term but storage, IOPS, backup, and data transfer charges remain unchanged regardless of reservation.

The key point: nothing in this table is accidental or wasteful. Every line item exists because your product genuinely needs it. These are the costs of running a production-grade database and because they are structural, no amount of optimisation will make them disappear. That is the real reason teams start exploring alternatives like BYOC, where you keep your infrastructure but avoid managed service pricing layers.

Can You Reduce AWS RDS Cost? Yes, But Here’s Where It Stops Helping

One of the most common questions once teams understand why RDS is expensive is whether optimisation can fix it.

Yes, there are real optimisations available and teams should pursue them before drawing conclusions. Here is what actually works, and where the ceiling is.

1. Right-size your instances

Most teams set up their RDS instance at launch, pick a size that feels safe, and never look at it again. According to Cast AI’s 2025 Kubernetes Cost Benchmark Report, the average cloud CPU utilisation across 2,100+ organisations is just 10%. You are very likely paying for compute you are not using.

The fix is simple: open Amazon CloudWatch, check your CPU utilisation and available memory over the past two weeks, and see what your database is actually doing. If your instance is sitting at 20% CPU, dropping one size down handles the same workload at roughly half the compute cost.

Before making any changes, set up CloudWatch alarms on three metrics: DatabaseConnections, CPUUtilization, and FreeableMemory. Measure first. Then resize.

2. Switch from gp2 to gp3 storage

If you are still on gp2 storage, switching to gp3 is the easiest cost win available to you. Same price per GB, but gp3 gives you 3,000 IOPS and 125 MB/s throughput included at no extra charge. AWS lets you migrate in place, no downtime, no risk.

One thing to check first: if your database is larger than 400 GB, IOPS and throughput minimums increase. Run your numbers through the AWS Pricing Calculator before switching to make sure the move still saves you money.

3. Review backup retention and snapshot accumulation

Most teams set their backup retention window once during setup and never revisit it. If you are on a 35-day retention window, ask yourself honestly: has your team ever needed to restore from a 3-week-old backup? For most products, 14 or 21 days covers the real risk window, and the cost difference is meaningful.

Also check your manual snapshots. Automated snapshots expire automatically when you delete them or when the retention window passes. Manual snapshots do not.

They sit there quietly, accumulating cost every single month, and most teams have no idea how many they have. Go into your RDS console right now and audit them: you may be surprised.

4. Use Reserved Instances for stable workloads

Reserved Instances let you commit to a 1 or 3-year term in exchange for a discount roughly around 30–40% on a 1-year term, up to 60% on a 3-year term.

The catch is flexibility: if your instance type or region needs to change, you lose the discount entirely.

The bigger thing to understand is what Reserved Instances actually discount and what they don’t.

They only reduce your compute charge. Storage, IOPS, backups, and data transfer are billed exactly the same whether you are on-demand or reserved. If those are the lines driving your bill, Reserved Instances will not help.

Where optimisation reaches its ceiling

Here is the uncomfortable truth: if your system genuinely needs Multi-AZ, a read replica, a staging environment, and reliable backups, you are not doing anything wrong. You have simply hit the ceiling of what optimisation can do. The costs are not inefficiency. They are the price of the model itself.

At that point, tweaking settings stops being the answer. The real question becomes: is RDS the right model for where your product is today?

For teams at this stage, the real decision comes down to understanding the managed vs self-hosted database trade-offs for growing startups and how each model holds up as your system scales.

What Growing Teams Do When Optimisation Stops Working

ou have right-sized the instances. Switched to gp3. Audited the snapshots. And the bill barely moved.

That is not a you problem. That is a model problem.

There are three paths forward from here. Most teams only discover the third one after spending months on the first two.

RDS vs SelfHosted vs BYOC Model

Option 1: Stay on RDS

For a lot of teams, this is the right call. If your database bill is somewhere between 5–10% of revenue and your team has no one dedicated to infrastructure, the convenience RDS gives you is genuinely worth the price. Managed means no late-night alerts about replication lag. No DBA on call. No one losing a weekend to a failed upgrade.

The only question worth asking is: does the math still work at twice your current scale?

If the answer is yes, stay. If you are not sure – keep reading.

Option 2: Self-host on EC2 or EKS

This is the classic escape route. Drop RDS, run PostgreSQL directly on EC2, and pay raw compute and storage rates with no managed service markup. At scale, that can cut your database infrastructure costs by 40–60%.

The savings are real. So is the cost that doesn’t show up on the bill.

Upgrades, failover, monitoring, backups, replication, all of it becomes your team’s problem. For a team with a dedicated DevOps engineer or DBA, that trade-off can make sense. For everyone else, you are essentially trading a predictable monthly charge for an unpredictable engineering burden.

For years, this was the only alternative to RDS. Managed convenience on one side. Full control with full responsibility on the other. Pick one.

That’s no longer the whole picture. For teams evaluating this shift, the real question is how the managed vs self-hosted database trade-offs for growing startups actually play out once you factor in both cost and operational complexity.

Option 3: The model that changes the equation entirely

What if you didn’t have to choose between “pay AWS to manage everything” and “manage everything yourself”?

That’s exactly what the BYOC (Bring Your Own Cloud) model is. Your database runs inside your own cloud account, your AWS, your GCP, your Azure.

You pay cloud-native compute and storage rates directly, with no managed service markup sitting on top. And a platform handles everything else: provisioning, failover, backups, upgrades, and monitoring.

You get the cost structure of self-hosted. Without the operational burden that makes self-hosted painful.

In practice, that means:

  1. No managed service premium on every GB and every instance hour
  2. Full visibility into your own infrastructure: no black box
  3. No vendor lock-in: your database lives in your account, not theirs
  4. No DevOps hire needed: the platform handles operations for you

This is the model SelfHost.dev is built around. Instead of your data and costs flowing through a managed platform’s infrastructure, everything runs in your own cloud while SelfHost handles the operational layer that used to justify the RDS premium.

Teams that move to SelfHost typically reduce their database infrastructure costs by up to 60%, without removing a single reliability feature.

And there’s something else worth knowing.

SelfHost recently launched an MCP server, meaning your AI coding agent (Claude, Cursor, Windsurf, VS Code) can now talk directly to your managed database without leaving your IDE. Query it, inspect it, migrate it, monitor it, all from inside the tools your team is already using.

For teams already using Claude or Cursor, this means your AI agent can query, inspect, and monitor your database directly without switching tools or writing a single integration.

This is especially worth exploring if you are:

  1. Spending $800–$1,000/month or more on RDS and watching that number climb
  2. Running multiple environments and feeling the compounding cost of each one
  3. Building with AI tools and want your database natively connected to your coding agent
  4. Done with vendor lock-in and want infrastructure that belongs to your team, not your cloud provider

When It Makes Strategic Sense to Reconsider Why RDS Is Expensive for You

There is no magic number that tells you it is time to reconsider. But there is a pattern.

It starts with someone flagging the database bill in a finance review. Then an engineer spends half a sprint trying to optimise it. Then leadership starts asking why infrastructure costs are scaling faster than revenue. By that point, the question is no longer operational, it is strategic.

This is happening across the industry right now. According to Flexera’s 2026 State of the Cloud Report, 29% of cloud spend is currently wasted, up for the first time in five years. Managing cloud costs remains the number one challenge for 85% of organisations surveyed. Cloud budgets are already exceeding forecasts by 17% on average.

The teams feeling that pressure most acutely are not the ones who made bad decisions. They are the ones whose products grew and whose architecture matured to match. RDS did not get more expensive. The setup did.

Here are the signals that tell you it is time to have that conversation seriously:

  1. Your RDS bill has become one of the top 3 line items in your cloud spend
  2. You are running 3 or more environments and feeling the cost of each one
  3. You cannot predict next month’s database bill with any confidence
  4. Engineering cycles are going toward managing costs instead of building product
  5. You have data residency or multi-cloud requirements that RDS makes complicated
    If you checked two or more of those, you are not alone, and you are not stuck.

One bootstrapped SaaS team was in exactly this position. They did not strip back their architecture. They did not sacrifice reliability. They simply changed the model underneath it and cut their AWS database spend by 60% – how they approached that shift is worth understanding if you’re facing similar cost pressure.

The teams who figure this out early do not do it by working harder on optimisation. They do it by asking a better question, not “how do we reduce this bill?” but “are we on the right model for where our product is today?”

That question, asked early enough, is worth more than any discount AWS will ever give you.

Why AWS RDS Is Expensive Is the Right Question to Be Asking

Why AWS RDS Is Expensive Is the Right Question to Be Asking

You Already Know Why. Now Decide What to Do About It.

Early-stage teams optimise for speed. Growth-stage teams start asking why AWS RDS is expensive. Mature teams optimise for leverage.

The difference between the second and third stage is not technical knowledge. It is timing. The teams that move decisively, that ask the right question before the bill becomes a crisis are the ones that end up with a database strategy that scales with their business instead of fighting it.

You now know exactly whyAWS RDS is expensive. You know which layers compound. You know where optimisation helps and where it hits a ceiling. You know there is a third model most teams never hear about early enough.

The only question left is whether you act on it now or wait until the bill forces your hand.

If you’re still trying to reduce RDS costs without taking on full operational burden, it’s worth understanding how BYOC compares to traditional managed databases.

Handling Sensitive UI Data in React Native: Practical Approaches Across iOS and Android

Handling Sensitive UI Data in React Native

Introduction

As mobile applications increasingly deal with sensitive user data—financial details, personal health information, authentication flows—UI-level privacy becomes a non-trivial concern.

While backend security is well understood, protecting what’s visible on the screen is often overlooked.

The Core Problem

Each platform handles screen privacy differently:

Android

  • Uses FLAG_SECURE to block screenshots and recordings
  • Requires ContentObserver to detect screenshots

iOS

  • No direct API to block screenshots
  • Relies on UITextField (isSecureTextEntry) behavior

Key Areas to Address

1. Screen Capture Protection

Android provides native support. iOS requires workaround techniques.

2. App Switcher Snapshots

Apps must hide sensitive data before going to background.

3. Screenshot Detection

Detection is possible, prevention is limited.

4. Clipboard Management

Sensitive data should be cleared proactively.

5. Copy/Paste Restrictions

Needs native-level interception.

Architectural Approach

A scalable approach includes:

  • Hooks for declarative usage
  • Imperative APIs for lifecycle control
  • View wrappers for sensitive UI

Trade-offs

  • iOS limitations on screenshot blocking
  • Android emulator bypasses
  • UX vs security balance

Conclusion

UI privacy is a cross-platform engineering problem requiring thoughtful abstraction and careful handling of OS differences.

If you’re building anything in fintech, banking, or enterprise on React Native and want a lightweight security layer without pulling in a large SDK — give it a try.
Feedback welcome, especially if you hit false positives on specific devices.

Built with Swift, Kotlin, and C++. No external dependencies.

Links:

npm Package
GitHub Repository
Full Documentation
Issue Tracker

Found this helpful? Drop a ❤️ on the article and ⭐ on GitHub!
Questions or suggestions? Drop them in the comments below!

Feel free to reach out to me if you have any questions or need assistance.
LinkedIn: https://www.linkedin.com/in/rushikesh-pandit-646834100/
GitHub: https://github.com/rushikeshpandit
Portfolio: https://www.rushikeshpandit.in

#ReactNative #TypeScript #MobileDevelopment #SoftwareEngineering #DevCommunity #root-detection #jailbreak-detection #mobile-security
#device-integrity

CodeRabbit GitHub Integration: Setup Guide

CodeRabbit screenshot

What you will learn

This guide walks through every step of integrating CodeRabbit with GitHub – from installing the GitHub App to configuring advanced review behavior with .coderabbit.yaml. By the end, you will have CodeRabbit automatically reviewing every pull request in your selected repositories, posting inline comments on code issues, and learning from your team’s feedback to improve over time.

Here is what this guide covers:

  • Installing the CodeRabbit GitHub App and granting the correct permissions
  • Selecting which repositories CodeRabbit should review
  • Understanding the permissions CodeRabbit requests and why each one is needed
  • Triggering your first automated PR review
  • Customizing review behavior with .coderabbit.yaml including review profiles, path filters, and natural language instructions
  • Advanced configuration for auto-review settings, monorepos, and integrations
  • Troubleshooting common issues with the GitHub integration
  • Alternative tools if CodeRabbit does not fit your workflow

If you are looking for a broader overview of CodeRabbit’s features and pricing before setting up the GitHub integration, start with our CodeRabbit review or CodeRabbit pricing breakdown.

Prerequisites

Before setting up the CodeRabbit GitHub integration, confirm you have the following:

  • A GitHub account (personal or organization) with at least one repository
  • Admin or owner permissions on the repositories where you want to install CodeRabbit – this is required to authorize GitHub Apps
  • At least one open pull request or the ability to create one for testing the integration (optional but recommended)
  • A modern web browser – the entire setup happens through the browser with no local tooling required

No CI/CD pipeline, Docker installation, API keys, or command-line tools are needed. CodeRabbit runs on its own infrastructure as a native GitHub App, which means it does not consume your GitHub Actions minutes or require workflow YAML files.

CodeRabbit screenshot

Step 1 – Install the CodeRabbit GitHub App

The GitHub App installation is the core of the CodeRabbit GitHub integration. This is what connects CodeRabbit’s AI review engine to your repositories and pull requests. Unlike tools that run as GitHub Actions, CodeRabbit operates as a standalone GitHub App – similar to how Slack, Jira, or Vercel integrate with GitHub.

Here is how to install it:

  1. Open coderabbit.ai in your browser and click the “Get Started Free” button
  2. Select GitHub as your Git platform
  3. Authorize CodeRabbit using the standard GitHub OAuth screen – this grants CodeRabbit access to your identity so it can create your account
  4. After landing on the CodeRabbit dashboard, click “Add Repositories” or “Install GitHub App”
  5. GitHub will redirect you to the App installation page

The OAuth authorization in step 3 and the App installation in step 4 are two separate operations. The OAuth grants CodeRabbit access to your identity (who you are). The App installation grants it access to your repositories and pull requests (what it can read and comment on). Both are required for the integration to work.

If you are installing CodeRabbit for an organization rather than a personal account, you may need an organization owner to approve the installation. If you see a “Request” button instead of “Install,” the request will be sent to your organization owner for approval. Ask them to check the GitHub organization settings under Third-party access to approve the CodeRabbit app.

For a deeper walkthrough of the sign-up and account creation process, see our CodeRabbit setup guide.

Step 2 – Select repositories

During installation, GitHub asks you to choose which repositories CodeRabbit should have access to. You have two options:

  • All repositories – CodeRabbit gets access to every repository in the organization or account, including any repositories created in the future. This is convenient for teams that want full coverage without manual configuration, but it means CodeRabbit will start reviewing PRs on every repository immediately.
  • Only select repositories – You choose specific repositories from a searchable list. This is the recommended approach for teams that want to start with a pilot before expanding. You can always add more repositories later from your GitHub settings or the CodeRabbit dashboard.

For most teams, the best approach is to start with two or three active repositories that have regular pull request activity. This lets you evaluate the review quality, tune your .coderabbit.yaml configuration, and get team feedback before rolling CodeRabbit out more broadly.

After selecting your repositories, click “Install” to complete the installation. The CodeRabbit App now appears in your GitHub organization settings under Settings, then GitHub Apps (or in your personal account under Settings, then Applications, then Installed GitHub Apps).

Managing repositories after installation

You can change which repositories CodeRabbit has access to at any time:

  • From GitHub: Go to your organization or account settings, navigate to GitHub Apps, find CodeRabbit, and click “Configure.” You can add or remove repositories from this screen.
  • From CodeRabbit: Log in to app.coderabbit.ai and navigate to the “Repositories” tab. Toggle individual repositories on or off to control which ones CodeRabbit actively reviews.

The GitHub-level setting controls access (can CodeRabbit see the repository), while the CodeRabbit dashboard setting controls activation (should CodeRabbit review PRs on this repository). A repository must have both access and activation enabled for reviews to work.

Step 3 – Configure permissions

The CodeRabbit GitHub App requests a specific set of permissions during installation. Understanding what each permission does helps you evaluate whether the integration meets your security and compliance requirements.

Here are the permissions CodeRabbit requests and why each one is necessary:

Permission Access level Purpose
Repository contents Read Allows CodeRabbit to read the code diff and surrounding context in your repository to perform meaningful reviews
Repository metadata Read Lets CodeRabbit access basic repository information like the default branch name and repository settings
Pull requests Read and Write Read access lets CodeRabbit see PR details including title, description, and changed files. Write access lets it post review comments and review summaries
Checks Write Allows CodeRabbit to create check runs that appear in the PR status section showing review progress
Webhooks Receive CodeRabbit subscribes to pull request events (opened, updated, reopened) so it knows when to start a review

CodeRabbit does not request write access to your repository contents. It cannot push commits, create branches, modify files, or merge pull requests. The integration is strictly read-only for your code and write-only for review comments.

For organizations with strict security policies, CodeRabbit also offers SOC 2 Type II compliance on its Enterprise plan and provides data processing agreements. Code is processed in memory during review and is not stored permanently on CodeRabbit’s servers.

Step 4 – First PR review

Once the GitHub App is installed and repositories are selected, open a pull request to trigger your first CodeRabbit review. This is where you verify that the integration is working correctly.

  1. Create a new branch in one of your enabled repositories
  2. Make a meaningful code change – adding a new function, refactoring a method, or fixing a bug works well for testing
  3. Push the branch and open a pull request targeting your default branch
  4. Wait 1 to 5 minutes for CodeRabbit to complete its review

When the review finishes, CodeRabbit posts several elements on your pull request:

A walkthrough summary appears as the first comment on the PR. It describes what changed across all files, organized by file and purpose. This summary helps reviewers quickly understand the scope of the PR without reading every line of the diff.

Inline review comments appear directly on specific lines in the diff, just like comments from a human reviewer. Each comment describes the issue, explains why it matters, and often includes a suggested fix. On the Pro plan, these suggestions appear as GitHub suggested changes that you can commit with one click.

A review status indicator shows whether the review is complete and how many comments were generated. This appears in the PR’s checks section.

If CodeRabbit does not post any comments within 5 minutes, jump to the troubleshooting section below. Common causes include the PR being a draft, the repository not being activated in the CodeRabbit dashboard, or permission issues with the GitHub App installation.

Interacting with CodeRabbit comments

CodeRabbit comments are not one-way notifications – they are the start of a conversation. You can reply to any comment to ask for clarification, request an alternative approach, or explain why the suggestion does not apply to your codebase:

  • Ask why: “Can you explain why this is a security risk? We validate this input in the middleware layer.”
  • Request alternatives: “This approach would break our caching layer. What is another way to handle this?”
  • Trigger actions: Comment @coderabbitai review on the PR to trigger a full re-review, or @coderabbitai resolve to dismiss a specific comment

Every interaction teaches CodeRabbit about your preferences. When you dismiss a comment with an explanation, CodeRabbit stores that as a learning and adjusts future reviews accordingly. Teams that actively reply during the first two weeks of adoption see significantly fewer false positives by the end of the first month.

Step 5 – Customize with .coderabbit.yaml

The .coderabbit.yaml file is where you tailor CodeRabbit’s GitHub integration to match your team’s workflow. While CodeRabbit works out of the box with sensible defaults, the configuration file gives you fine-grained control over what gets reviewed, how strictly, and with what focus areas.

Create a file named .coderabbit.yaml in the root of your repository and commit it to your default branch (usually main):

# .coderabbit.yaml
language: en-US

reviews:
  profile: chill
  request_changes_workflow: false
  high_level_summary: true
  poem: false
  review_status: true
  collapse_walkthrough: false
  sequence_diagrams: true
  changed_files_summary: true
  path_filters:
    - "!**/*.lock"
    - "!**/*.generated.*"
    - "!**/dist/**"
    - "!**/node_modules/**"
    - "!**/coverage/**"
    - "!**/__snapshots__/**"

chat:
  auto_reply: true

knowledge_base:
  opt_out: false
  learnings:
    scope: auto

CodeRabbit reads this configuration on every PR and applies your settings immediately – no restart, reinstallation, or dashboard change is required. Each repository can have its own .coderabbit.yaml with different settings, which is especially useful for organizations that have repositories with different languages, frameworks, or review standards.

Review profiles explained

The profile setting controls how verbose and strict CodeRabbit’s reviews are:

  • chill – Focuses only on significant issues like bugs, security vulnerabilities, and logic errors. Produces fewer comments and is the best starting point for teams new to AI code review. Most teams find this strikes the right balance between catching real issues and avoiding noise.
  • assertive – Reviews more comprehensively, covering style, naming, documentation, performance, and best practices in addition to bugs and security. Produces more comments and is best for teams that want thorough feedback on every PR.
  • followup – Similar to assertive but also checks whether previous review comments were addressed in subsequent commits. This is the strictest mode and is best for teams that want to ensure review feedback is acted on.

Start with chill and switch to assertive after your team is comfortable with the tool – typically after two to four weeks.

Path filters for excluding files

The path_filters section controls which files CodeRabbit analyzes. Use negation patterns (prefixed with !) to exclude files that do not benefit from AI review:

reviews:
  path_filters:
    - "!**/*.lock"           # Package lock files
    - "!**/*.min.js"         # Minified JavaScript
    - "!**/dist/**"          # Build output
    - "!**/vendor/**"        # Vendored dependencies
    - "!**/*.generated.*"    # Auto-generated code
    - "!**/migrations/**"    # Database migrations (optional)
    - "!**/*.snap"           # Test snapshots

Excluding these files reduces noise and speeds up reviews because CodeRabbit does not spend time analyzing files where its feedback would not be actionable.

Advanced configuration

Once you have the basic .coderabbit.yaml working, these advanced settings let you get more value from the CodeRabbit GitHub integration.

Review instructions for specific paths

The path_instructions feature is one of CodeRabbit’s most powerful capabilities. It lets you provide natural language instructions that CodeRabbit follows when reviewing files matching specific patterns:

reviews:
  path_instructions:
    - path: "src/api/**"
      instructions: |
        Review all API endpoints for:
        - Input validation on all request parameters
        - Proper error handling with appropriate HTTP status codes
        - Authentication and authorization checks
        - Rate limiting considerations
    - path: "src/db/**"
      instructions: |
        Review database code for:
        - SQL injection prevention using parameterized queries
        - Proper connection handling and cleanup
        - Transaction usage for multi-step writes
    - path: "**/*.test.*"
      instructions: |
        For test files, focus on:
        - Edge case coverage
        - Proper assertion usage
        - Mock cleanup and test isolation

This means your API code gets reviewed for authentication gaps, your database code gets checked for SQL injection, and your tests get evaluated for missing edge cases – all automatically based on the file path.

Global review instructions

Add a top-level instructions field to guide CodeRabbit’s behavior across all files in the repository:

reviews:
  profile: assertive
  instructions: |
    This is a TypeScript backend service using Express and PostgreSQL.
    Our conventions:
    - All async functions must use try/catch with proper error logging
    - Database queries must use parameterized statements
    - API responses follow the format: { data, error, meta }
    - Do not comment on import ordering (handled by ESLint)
    - Do not comment on line length (handled by Prettier)
    - Focus on bugs, security issues, and logic errors

Global instructions are especially useful for preventing false positives. If your linter already handles import ordering and your formatter handles line length, telling CodeRabbit to skip those categories eliminates a common source of noise.

Auto-review settings

Control whether CodeRabbit reviews PRs automatically or only when requested:

reviews:
  auto_review:
    enabled: true
    drafts: false
    base_branches:
      - main
      - develop

Setting drafts: false means CodeRabbit skips draft PRs, which is the default behavior. The base_branches setting limits auto-review to PRs targeting specific branches – useful if you only want CodeRabbit to review PRs going into your main branches and not PRs between feature branches.

Path filters for monorepos

If your repository is a monorepo with multiple services, combine path instructions with path filters to apply different review criteria to each service:

reviews:
  path_instructions:
    - path: "services/auth/**"
      instructions: |
        Authentication service - focus on token validation,
        password hashing (bcrypt only), and OWASP compliance
    - path: "services/payments/**"
      instructions: |
        Payment service - focus on PCI DSS patterns,
        idempotency of operations, and decimal precision
    - path: "packages/shared/**"
      instructions: |
        Shared library - focus on backward compatibility,
        type safety, and performance implications

Each service gets reviewed with context-specific criteria, which dramatically improves review quality compared to generic instructions applied uniformly across a monorepo.

Integrating with issue trackers

CodeRabbit can read linked Jira or Linear issues to understand the context behind a PR. When it knows the ticket description and acceptance criteria, it can validate whether the code changes actually address the requirements:

integrations:
  jira:
    enabled: true
    project_keys:
      - "BACKEND"
      - "FRONTEND"
  linear:
    enabled: true

Troubleshooting the CodeRabbit GitHub integration

If the integration is not working as expected, work through these issues in order.

CodeRabbit is not reviewing PRs

  1. Check the GitHub App installation. Go to your GitHub organization settings, then Applications, then Installed GitHub Apps. Verify that CodeRabbit is listed and has access to the repository. If you chose “Only select repositories” during installation, the repository might not be included.
  2. Check repository activation. Log in to app.coderabbit.ai and verify that the repository is toggled on in the Repositories tab.
  3. Check if the PR is a draft. CodeRabbit skips draft PRs by default. Mark the PR as ready for review, or add drafts: true under auto_review in your .coderabbit.yaml.
  4. Check path filters. If your .coderabbit.yaml excludes all the paths that changed in the PR, CodeRabbit will have nothing to review.
  5. Check rate limits. On the free tier, you are limited to 4 PR reviews per hour and 200 files per hour. If you have hit these limits, reviews are queued until capacity is available.
  6. Check webhook delivery. In your GitHub repository settings, navigate to Webhooks and inspect recent deliveries for the CodeRabbit webhook. Failed deliveries indicate a connectivity issue.

YAML configuration is not taking effect

  1. Verify the file name is exactly .coderabbit.yaml – not .coderabbit.yml and not coderabbit.yaml
  2. Verify the file is in the repository root, not in a subdirectory
  3. Verify the file is on the default branch (usually main), not on a feature branch
  4. Validate the YAML syntax using an online YAML validator – indentation errors are the most common cause
  5. Comment @coderabbitai review on a PR to force CodeRabbit to re-read the configuration

Permission errors

  1. For personal accounts: Only the account owner can install GitHub Apps. Verify you own the account.
  2. For organizations: App installations require organization owner approval. If you see “Request” instead of “Install,” the request is pending approval from your org owner.
  3. For repositories with access restrictions: Some organizations use GitHub App policies to restrict which apps can access specific repositories. Check your organization settings under Third-party access.

Too many or irrelevant comments

  1. Switch the review profile from assertive to chill
  2. Add path filters to exclude generated files, lock files, and build artifacts
  3. Add global instructions telling CodeRabbit what not to comment on
  4. Reply to irrelevant comments with explanations – CodeRabbit learns from your feedback
  5. Enable the knowledge base so CodeRabbit builds repository-specific context over time

Alternative tools for GitHub code review

If CodeRabbit does not fit your needs, several alternatives provide AI-powered code review for GitHub repositories.

CodeAnt AI ($24-40/user/month) is a Y Combinator-backed platform that combines AI PR reviews with SAST scanning, secret detection, IaC security, and DORA metrics in a single tool. The Basic plan at $24/user/month covers AI PR reviews with line-by-line feedback across 30+ languages. The Premium plan at $40/user/month adds security scanning, compliance reporting (SOC 2, HIPAA), and engineering dashboards. CodeAnt AI is a strong alternative for teams that want to consolidate multiple security and review tools into one platform rather than running CodeRabbit alongside separate SAST tools.

GitHub Copilot code review is built directly into the GitHub PR interface and requires no additional app installation for teams already on Copilot Business or Enterprise plans. It provides AI-powered review comments but offers less configuration depth than CodeRabbit – there is no equivalent to .coderabbit.yaml path instructions or review profiles.

PR-Agent by Qodo is an open-source option that runs as a GitHub Action. It gives you full control over the LLM provider and can be self-hosted for teams with strict data residency requirements. You pay for your own LLM API keys rather than a per-user subscription.

For a comprehensive comparison of all available options, see our guide on CodeRabbit alternatives. If you are specifically interested in using GitHub Actions for code review automation, our AI code review in GitHub Actions guide covers multiple tools with production-ready workflow configurations.

Conclusion

The CodeRabbit GitHub integration gives your team instant AI-powered code review on every pull request with a setup process that takes under 10 minutes. Install the GitHub App, select your repositories, open a PR, and CodeRabbit starts posting review comments – no CI/CD configuration, no workflow files, no API keys.

The real value comes from customization. A .coderabbit.yaml file with review instructions tailored to your codebase structure, coding conventions, and security requirements turns CodeRabbit from a generic code reviewer into a context-aware team member that knows your API routes need authentication checks and your database code needs parameterized queries.

Start with the chill review profile on one or two repositories. Let your team interact with CodeRabbit’s comments for two weeks. Then tune the configuration based on real feedback – add path instructions for your most critical directories, exclude files that generate noise, and expand to additional repositories as confidence grows.

For next steps, explore our CodeRabbit setup guide for additional onboarding tips, our CodeRabbit pricing guide to understand when it makes sense to upgrade from the free tier, and our AI code review in GitHub Actions guide to see how CodeRabbit fits alongside other tools in your review pipeline.

Further Reading

Frequently Asked Questions

How do I integrate CodeRabbit with GitHub?

Go to coderabbit.ai and click Get Started Free. Sign in with your GitHub account and authorize the CodeRabbit GitHub App. Select the repositories you want CodeRabbit to review – either all repositories or specific ones. Once installed, CodeRabbit automatically reviews every new pull request within minutes. No GitHub Actions workflow or CI/CD pipeline is required.

Is the CodeRabbit GitHub App free?

Yes. CodeRabbit offers a free tier that covers unlimited public and private repositories with AI-powered PR summaries and review comments. The free tier includes rate limits of 200 files per hour and 4 PR reviews per hour. The Pro plan at $24/user/month removes these limits and adds features like auto-fix suggestions and 40+ built-in linters. Pro is free forever for open-source repositories.

What GitHub permissions does CodeRabbit need?

CodeRabbit requires read access to repository contents, metadata, and pull requests so it can analyze code changes. It also needs write access to pull request comments and checks so it can post review feedback. Finally, it requires webhook events for pull request creation and updates so it knows when to start a review. These are standard permissions for any code review GitHub App.

Does CodeRabbit work with GitHub Enterprise?

Yes. CodeRabbit supports GitHub Enterprise Cloud out of the box. For GitHub Enterprise Server (self-hosted), CodeRabbit offers an Enterprise plan with on-premises deployment options. Contact the CodeRabbit sales team to set up integration with self-hosted GitHub instances that are not publicly accessible.

How do I configure CodeRabbit for specific GitHub repositories?

You can select specific repositories during the GitHub App installation by choosing Only select repositories instead of All repositories. After installation, toggle individual repositories on or off from the CodeRabbit dashboard at app.coderabbit.ai. You can also create a .coderabbit.yaml file in each repository root to apply repository-specific review settings.

What is the .coderabbit.yaml file and where does it go?

The .coderabbit.yaml file is CodeRabbit’s repository-level configuration file. Place it in the root of your repository on the default branch (usually main). It controls review behavior including the review profile (chill, assertive, or followup), path filters for excluding files, path-specific review instructions, and feature toggles like sequence diagrams and PR summaries. CodeRabbit reads this file on every PR automatically.

Why is CodeRabbit not reviewing my GitHub pull requests?

Check these causes in order: the CodeRabbit GitHub App may not be installed on the repository, the repository may be toggled off in your CodeRabbit dashboard, the PR may be marked as a draft (CodeRabbit skips drafts by default), or your path_filters in .coderabbit.yaml may exclude the changed files. Also verify that the app has the necessary permissions in your GitHub Settings under Applications. On the free tier, exceeding 4 reviews per hour queues additional reviews.

Can I use CodeRabbit alongside GitHub Copilot code review?

Yes. CodeRabbit and GitHub Copilot code review serve complementary roles and can run simultaneously on the same repository without conflicts. CodeRabbit provides deeper contextual analysis with customizable review instructions and learning capabilities, while Copilot code review is tightly integrated into the GitHub UI. Many teams run both to get broader coverage.

How do I exclude files from CodeRabbit reviews on GitHub?

Add a path_filters section under reviews in your .coderabbit.yaml file. Use negation patterns with an exclamation mark prefix to exclude paths. For example, adding ‘!/*.lock’ excludes lock files, ‘!/dist/‘ excludes build output, and ‘!/node_modules/**’ excludes dependencies. Changes to path filters take effect on the next PR without any restart.

Does CodeRabbit support GitHub Actions workflows?

CodeRabbit does not run as a GitHub Actions step. Instead, it runs as a standalone GitHub App on its own infrastructure, which means it does not consume your GitHub Actions minutes or require YAML workflow files. It works alongside any existing GitHub Actions workflows you have. If you prefer a GitHub Actions-based approach, consider alternatives like PR-Agent which runs as an Action.

How long does CodeRabbit take to review a GitHub pull request?

CodeRabbit typically completes its review within 1 to 5 minutes after a pull request is opened or updated. Small PRs with fewer than 100 changed lines usually finish in under 2 minutes. Larger PRs with thousands of lines may take up to 5 minutes. On the free tier, if you exceed 4 reviews per hour, additional reviews are queued until capacity is available.

What alternatives to CodeRabbit exist for GitHub code review?

Top alternatives include CodeAnt AI ($24-40/user/month) which combines AI PR reviews with SAST and DORA metrics, GitHub Copilot code review which is built into GitHub natively, PR-Agent (by Qodo) which is open source and runs as a GitHub Action, and Sourcery which specializes in Python code review. Each tool has different strengths depending on your team size, language, and compliance needs.

Originally published at aicodereview.cc

The Trident and The Green Ox

I’ve been writing code for a few decades now. Started with C. The kind of C where you know roughly what the CPU is doing at any given moment — moving a register, touching a block of memory, shaving off a few microseconds. There’s something satisfying about that directness. Assembly-level intuition. It sticks with you.

It also makes you a little hostile toward anything that calls itself a “modern language.”

Not because you can’t learn it. Because it doesn’t feel right.

From C to modern C++

For a long time, my C++ was really just C with classes. I found out later that most people who have “C++ engineer” on their resume are doing the same thing. That’s where most of us plateau.

Then I started using std::vector. Then RAII. Then I ran into compare_exchange_strong and compare_exchange_weak — spent a full day just figuring out when to use which. Then came C++17, SFINAE, template metaprogramming.

Honestly, I questioned my life choices.

But those tools also made my first serious project work the way I wanted it to.

50,000 lines of C++, then 3.5 million lines of Python

That first project was a bridge layer between a trading platform and a strategy execution service. About 50,000 lines of modern C++, took me six months to write by hand.

I picked C++ for two reasons: speed, and RAII.

The results: on Windows 10, it started at around 22MB of memory, then dropped to 11MB after running continuously for a week. On Windows 11, it started at 36MB, settled at 12MB. During all that time it was pulling and processing tick data for every instrument at full frequency.

Rough around the edges. But the direction was right.

Later, the product evolved into a web application: AI-assisted strategy editing, multi-user backtesting, a Python backend, and a WordPress frontend. The whole thing took two years.

The Python backend peaked at 3.5 million lines. WordPress passed 4 million. AI was involved full-time at this point — I was using Claude 3.5.

But it was still just a multi-user backtesting system. Plenty of features still missing.

A 14-day dead end

Claude 3.5 had a habit of breaking things while fixing them.

One time, the multi-process backtesting module was working perfectly. Then after a round of heavy refactoring, it stopped working entirely. I spent 14 days trying to fix it. Twelve hours a day. Back then Claude didn’t have the weekly or per-5-hour usage caps yet, so I was grinding pretty much around the clock to make the most of my subscription.

After 14 days, I gave up. Rolled back to the last stable version. Then manually merged all the other changes from those two weeks, testing each one as I went.

Turns out AI can write code really fast. It can also drive you off a cliff really fast.

Cutting 90%

At the end of 2025, I made a decision: cut 90% of the codebase.

Python backend went from 3.5 million lines to under 500,000. WordPress went from 4 million to under 500,000.

The system itself was running fine. I didn’t cut it because it was broken. I cut it because of money.

AWS bills were brutal — the system needed multiple servers. Even Claude’s parent company says it’ll take two years to reach profitability. OpenAI says five. If the AI companies themselves are getting squeezed by infrastructure costs, a small independent project like mine didn’t stand a chance.

I also realized something: users probably want to build their own trading systems on their own machines. They don’t need me running a massive cloud engine for them.

So I rebuilt it as a desktop app.

Without the queue system, the saga orchestration, the multi-user concurrency — plus two years of backend code to reference — things moved a lot faster. Started the rewrite on January 2nd, basically finished by mid-February. 500,000 lines of code, six weeks.

I went back through the git log later and roughly tallied what I’d deleted from the old system. Ten entire subsystems — server-side backtesting engine, task queue with priority management, a process manager with its own state machine, real-time WebSocket streaming, a saga orchestrator for failure cleanup, historical data playback, checkpoint recovery for power failures, a standalone cleanup microservice, a cross-service ZMQ communication layer across six dedicated ports, and a session identity context system.

The saga orchestrator alone had a five-step cleanup protocol: WebSocket recycle → worker completion wait → active user cleanup → test session cleanup → resource release. The process manager ran its own state machine (STARTING → RUNNING → RECYCLING → STOPPED → ERROR) with health checks and automatic recovery. The checkpoint recovery system could detect interrupted backtests on server restart by checking MySQL status flags, recover state from Redis, and re-queue everything.

All gone. Listing it out made me a little dizzy.

Claude 3.5 to 4.6

Using Claude to write code has been a love-hate relationship.

In the 3.5 era, it was $100 a month max. When the model got dumb — I honestly wasn’t sure whether my rage would destroy my computer first or give me a heart attack first. I seriously considered both outcomes.

I wrote in to yell at customer support.

Then I ran into a billing bug: after requesting a refund, the system showed I’d unsubscribed. Except I hadn’t. A month later it started charging again. I successfully canceled, tried every other coding tool on the market, realized I still needed Claude, and resubscribed. Successfully canceled again. Got auto-resubscribed anyway.

Long story short, it didn’t kill me. I stuck with it all the way to 4.6.

A domain name and a new project

After gutting the codebase, I tried to register a domain name for the project. Didn’t get it.

But that failure got me thinking about something: if in the future everyone is running multiple AI entities, how do those entities discover each other? They need addressable identities. They need to be findable, trustable. They might even need a reputation system to support collaboration. It’s like Windows 95 and the internet — before that, regular people didn’t have an on-ramp to the web. AI entities need that kind of infrastructure layer too.

So I started ClawNexus — an identity registry for OpenClaw instances. It discovers AI agent instances on the network, gives each one a persistent name, and tracks capabilities, trust scores, and online status.

AI picked the popular choice. The popular choice didn’t work.

By version 0.3, ClawNexus had over 300 unit tests and 5 integration tests — the integration tests were for multi-node discovery across a WireGuard VPN, with nodes at 10.66.66.x addresses.

Claude chose mDNS for discovery — standard practice. But in my WireGuard environment, it kept casually skipping certain cross-machine test cases.

I sat it down for a serious conversation: why can’t this supposedly universal protocol handle all the scenarios? It couldn’t give me a straight answer.

Here’s the thing. I have this habit at home — I set up LAN games of StarCraft with friends. We use IPX-over-UDP via ipxwrapper. And that setup has always worked perfectly over WireGuard.

So I asked Claude directly: why not use the IPX protocol? It pushed back. Said we didn’t need it.

Fine. I made it implement those skipped test cases using IPX anyway.

That evening:

  • 10:35 PM — started adding IPX support
  • 11:00 PM — cross-machine tests running
  • 11:25 PM — all cases passing

Afterward I asked Claude to explain why it had originally chosen mDNS over IPX.

The explanation sounded perfectly reasonable. It just had nothing to do with the system I was actually running.

300 unit tests weren’t enough

This is a habit from my C days.

Even with 300+ unit tests all passing, I still went through every command-line parameter by hand.

Found several that weren’t doing anything at all.

Claude 4.6’s explanation sounded completely correct.

But I couldn’t accept it.

I adjusted my approach after that: I didn’t just have AI write code and tests — I baked my manual testing process into its workflow too. The problem never came back.

Three days after launch, a copycat appeared

Three days after publishing ClawNexus to npm, I stumbled across a GitHub repo with the exact same name on social media.

This is where Claude’s breadth of knowledge showed up. It helped me investigate the other project’s origins, the problems in their implementation, the flaws in their design philosophy. Then in a very short time it helped me shore up every position I needed to hold.

I wouldn’t have gotten through any of that on my own.

The Trident and The Green Ox

Why do the immortals in mythology ride mounts?

Laozi rode a green ox through Hangu Pass. Guanyin rides a golden-haired lion. The Buddha’s mount is a six-tusked white elephant. The ox is faster than walking, but it needs someone on top who knows where to go. AI is that ox — it writes code faster than me, searches information faster than me, analyzes competitors faster than me. But it didn’t know that mDNS doesn’t work well over WireGuard. It didn’t know whether to write or cut 90% of the code. It even managed to run me in circles for 14 days.

So why does Poseidon also carry a trident?

Because some situations demand certainty.

AI sometimes guesses. Same question, different answers. Rephrase it slightly, different answer again.

Code doesn’t do that. compare_exchange_strong (a C++ atomic operation) gives you the same result every single time. Doesn’t matter how many times you call it. C++ template metaprogramming, Python’s deterministic pipelines, Rust’s type system — those are tridents. Same input, same output, every time. They pick up where AI’s guesswork leaves off.

Think about it: tools like Claude Code and Codex are themselves an ox wielding a trident. The AI generates, the code tools execute deterministically, and somewhere in the middle there’s supposed to be a human making sure none of it goes sideways.

The world needs the speed of the ox.

The certainty of the trident.

And most of all — the people who can ride one and wield the other, and survive every moment when things fall apart.

Do users actually click CTA… or just find their own path?

While working on AllInOneTools, I noticed something interesting.

As builders, we design CTAs like:

• “Start Now”
• “Try Tool”
• “Get Started”

We expect users to follow that path.

But real users don’t always behave like that.

Sometimes they:

• ignore the CTA
• scroll down
• go directly to categories
• click the first tool they see

It made me question something:

👉 Do users really follow CTAs… or do they just find their own way?

From what I’ve seen:

New users → follow visual cues (categories, popular tools)
Returning users → skip everything and go straight to what they need

So maybe CTA is not always the main driver.

Maybe it’s just one of many entry points.

Now I’m curious 👇

When you visit a website, what do you do?

• Click the main CTA
• Scroll and explore
• Jump directly to what you need
• Ignore everything and search

Would love to hear real behavior.

Key AI Concepts Every AWS AI Practitioner Should Know

Artificial Intelligence is no longer a side initiative—it’s a core business capability. For professionals preparing for the AWS Certified AI Practitioner (AIF-C01) success depends on mastering foundational concepts, real-world use cases, and AWS service alignment.
This guide distills the essential knowledge areas you need—not as theory, but as applied intelligence for modern cloud environments.
🧠 1. Understanding Artificial Intelligence (AI) Fundamentals
AI refers to systems that simulate human intelligence:
• Learning from data
• Identifying patterns
• Making decisions or generating outputs
Core Domains:
• Machine Learning (ML)
• Deep Learning (DL)
• Natural Language Processing (NLP)
• Computer Vision
👉 Key Insight:
AI is not a single tool—it’s a stack of capabilities layered over data and compute.
⚙️ 2. Machine Learning Fundamentals
Machine Learning is the engine powering most AI solutions.
Types of ML:
🔹 Supervised Learning
• Uses labeled datasets
• Example: Fraud detection
🔹 Unsupervised Learning
• Finds hidden patterns
• Example: Customer segmentation
🔹 Reinforcement Learning
• Learns via feedback loops
• Example: Recommendation engines
👉 Exam Focus:
Understand use-case mapping, not algorithms.
📊 3. Data: The Strategic Asset
AI thrives—or fails—based on data quality.
Key Considerations:
• Structured vs unstructured data
• Data labeling and preparation
• Bias and imbalance
👉 Business Reality:
Garbage in → Garbage out
AWS emphasizes data pipelines and governance as foundational.
🧩 4. Natural Language Processing (NLP)
NLP enables machines to understand and interact with human language.
Common Use Cases:
• Chatbots
• Sentiment analysis
• Language translation
AWS Services:
• Amazon Comprehend
• Amazon Lex
• Amazon Transcribe
👉 Insight:
Choose managed NLP services for speed and scalability.
👁️ 5. Computer Vision
Computer Vision enables machines to interpret visual data.
Capabilities:
• Object detection
• Facial recognition
• OCR (text extraction)
AWS Services:
• Amazon Rekognition
• Amazon Textract
👉 Real-World Use Cases:
• Security & surveillance
• Document automation
• Retail analytics
🤖 6. Generative AI Fundamentals
Generative AI creates new content—text, images, code.
Key Concepts:
• Prompts and prompt engineering
• Tokens and context windows
• Temperature (creativity control)
AWS Service:
• Amazon Bedrock
👉 Critical Thinking:
• Manage hallucinations
• Ground responses with enterprise data (RAG)

SCSS Is Solving Problems CSS Is Learning to Solve Itself

You’ve spent years reaching for SCSS the moment a project grows past a single stylesheet. Variables. Loops. Functions. Nesting. It felt like the only sane way to write scalable CSS.

Meanwhile, native CSS has been quietly shipping the same features — one by one, browser by browser.

So here’s the honest question: how much of SCSS do you actually still need?

Let me walk through what CSS can do natively today, what’s coming next, and where SCSS still wins.

What CSS Can Do Right Now

Custom Properties (aka CSS Variables)

You already know these. They replaced SCSS $variables for runtime use-cases — and they’re strictly more powerful because they cascade, they’re dynamic, and JavaScript can interact with them.

:root {
  --color-primary: #ff69b4;
  --spacing-base: 8px;
}

.button {
  background: var(--color-primary);
  padding: calc(var(--spacing-base) * 2);
}

SCSS variables are build-time only. Custom properties survive into the browser. If you haven’t fully made the switch for your design tokens, that’s where to start.

Nesting

Native CSS nesting shipped in Chrome 112 (2023) and is now in every major browser. The syntax is almost identical to SCSS:

.card {
  padding: 16px;

  &__title {
    font-size: 18px;
  }

  &:hover {
    box-shadow: 0 4px 12px rgba(0, 0, 0, 0.1);
  }

  @media (max-width: 768px) {
    padding: 12px;
  }
}

Two differences worth knowing before you migrate:

  1. & is mandatory in native CSS. .card h1 {} nested inside .card {} won’t work — you need & h1 {}.
  2. No interpolation. SCSS lets you write &#{$modifier} to build dynamic selectors. Native CSS nesting has no equivalent — those cases still need a preprocessor.

For most codebases, neither matters day-to-day. But if you’re running BEM with dynamic modifiers or generating selectors in loops, you’ll hit the wall.

color-mix() and Color Functions

SCSS has lighten(), darken(), mix(). Native CSS now has color-mix():

.button-hover {
  background: color-mix(in oklch, var(--color-primary) 80%, white);
}

The in oklch part tells the browser which color space to interpolate in. This matters more than it sounds: mixing colors in srgb (the default) can produce muddy mid-tones. oklch is perceptually uniform — meaning the lightness you see actually matches the lightness you specified. Tints and shades look consistent instead of just mathematically being consistent.

Supported in all modern browsers. Works with CSS custom properties, which SCSS color functions don’t.

@layer

This is the one CSS feature that genuinely has no SCSS equivalent because it solves a problem SCSS can’t even address: specificity wars at scale.

Quick context if you haven’t lived through one: you import a third-party component library. Its .button styles have higher specificity than yours. You add !important. They update the library and add !important too. Now you’re writing !important !important in your head and nothing is predictable. @layer fixes this at the architecture level.

@layer reset, base, components, utilities;

@layer reset {
  * { box-sizing: border-box; }
}

@layer components {
  .button { background: var(--color-primary); }
}

@layer utilities {
  /* This ALWAYS wins over components, regardless of specificity */
  .mt-4 { margin-top: 16px; }
}

Layer order controls override priority — not specificity, not source order, not !important. Later-declared layers win. If you’re building a design system that external teams can extend without fighting the cascade, this is the tool.

Container Queries

For years, the argument was “CSS can’t do what JavaScript can do for responsive design.” Container queries close that gap:

.card {
  container-type: inline-size;
}

@container (min-width: 400px) {
  .card__title {
    font-size: 24px;
  }
}

Components that adapt to their parent container, not the viewport. Media queries were always the wrong abstraction for component libraries — this is the right one.

What’s Coming Next (and When to Care)

⚠️ Everything in this section is not yet in browsers (or only behind experimental flags). The syntax shown is from active CSS Working Group specs — real and moving forward, but not production-ready. If you want to use any of this today, PostCSS has polyfill plugins for most of it. More on that at the end.

@function — Native CSS Functions

This is the big one. The CSS Working Group has a specification in progress for custom functions directly in CSS. No JavaScript, no SCSS:

/* Proposed syntax — not in browsers yet */
@function --spacing($multiplier) {
  result: calc(8px * $multiplier);
}

.card {
  padding: --spacing(3); /* 24px */
}

This would replace one of SCSS’s most-used features. Timeline: likely 2025-2026 for an experimental flag, broader support a year or two after that.

@mixin — Native CSS Mixins (sort of)

Also in the CSS Mixins & Functions spec. The concept: reusable blocks of declarations, applied without a preprocessor:

/* Proposed syntax */
@mixin --flex-center {
  display: flex;
  align-items: center;
  justify-content: center;
}

.hero {
  @apply --flex-center;
}

Important caveat for anyone who’s used SCSS mixins heavily: this is a significantly simpler model. No @content injection. No arguments with conditional logic. No @if inside the mixin body. It’s closer to a named block of static declarations than a parametric function. Think of it as CSS @extend done right — not SCSS @mixin done natively. The name is similar; the power level is not.

if() — Inline Conditionals

CSS is getting inline conditional logic as part of the Values Level 5 spec:

.button {
  /* Adjust padding based on a custom property flag */
  padding: if(style(--size: large): 20px 32px; else: 12px 20px);
}

Combined with custom properties as flags, this lets components adapt their own styles based on configuration — no JavaScript, no modifier classes, no SCSS conditionals.

Relative Color Syntax

Already shipped in Chrome and Safari, making its way to Firefox:

.button-hover {
  /* Take primary color, keep h and s, reduce l by 10% */
  background: hsl(from var(--color-primary) h s calc(l - 10%));
}

This replaces lighten() and darken() with something more predictable and composable. Works with custom properties, which SCSS functions don’t.

Where SCSS Still Wins (For Now)

Being honest here — the answer isn’t “CSS wins completely.” There are three areas where SCSS still has a real advantage in 2025:

1. Loops and data-driven generation

@for, @each, @while — CSS has nothing equivalent yet. If you’re generating 16 animation delays for a visualizer, or creating utility classes from a scale map, SCSS loops are still the only build-time option. The proposed CSS @function spec doesn’t include iteration.

2. Build-time validation

SCSS @error and @warn fire at compile time. If your design token is missing, you find out before the browser renders anything. CSS has no equivalent concept — it fails silently.

@if not map-has-key($modes, $mode) {
  @error "Unknown mode: #{$mode}. Available: #{map-keys($modes)}";
}

There’s no native CSS equivalent coming. This remains a preprocessor-only capability.

3. Complex structured data

SCSS maps as nested data structures — $modes: (pink-big: (title: (color: ..., font-size: ...))) — are genuinely expressive in ways CSS custom properties can’t replicate. CSS properties are flat key-value. SCSS maps are traversable trees. For the kind of multi-mode theming system I wrote about in the first article in this series, SCSS maps as a config layer still make sense even when CSS handles the runtime switching.

The Middle Ground Nobody Talks About: PostCSS

The “SCSS vs native CSS” framing misses a third option that’s already how many production setups work: PostCSS.

PostCSS sits between your source files and the browser. It’s not a preprocessor like SCSS — it’s a transformation pipeline. You write future CSS syntax, PostCSS compiles it to what browsers support today.

The practical upside: you can use @custom-media, CSS nesting (even before it was fully shipped), relative color syntax, and some of the proposed @function syntax right now via PostCSS plugins. Vite has PostCSS built in. Next.js does too.

// postcss.config.js
module.exports = {
  plugins: [
    require('postcss-nesting'),          // native nesting polyfill
    require('postcss-custom-media'),     // @custom-media queries
    require('postcss-oklab-function'),   // oklch/oklab color support
  ]
}

This is worth knowing because it changes the timeline question. You don’t have to wait 2-3 years for @function to ship in browsers — you can write it today if PostCSS has a plugin for it. The CSS ecosystem is converging on this model: specify in CSS, transform at build time, no preprocessor lock-in.

The Risks Nobody Mentions

Going native CSS isn’t just a technical decision — it’s a bet on your users’ browsers. Here’s what can go wrong.

You don’t actually know what browsers your users run

“All modern browsers support it” is a statement about the latest versions. Your users might not be on the latest versions.

The gap is bigger than you think:

  • Corporate users on locked-down Windows machines often run Chrome that’s 6-12 months behind
  • Android WebView (used inside apps, not the standalone browser) updates on its own schedule and frequently lags
  • Safari on iOS is tied to the OS version — users on iPhone 8 running iOS 15 are stuck on Safari 15, and iOS 15 was dropped from Apple’s update cycle in 2022
/* CSS nesting — ~93% global support */
/* container queries — ~91% global support */
/* color-mix() — ~89% global support */
/* @layer — ~92% global support */
/* relative color syntax — ~86% global support */

That 7-14% that doesn’t support it isn’t a rounding error. If you have 500,000 users, that’s 35,000–70,000 people seeing broken styles — silently, with no error in your logs.

CSS fails silently, SCSS fails loudly

This is the asymmetry that matters most in production.

When an SCSS build fails, your CI pipeline fails. The broken code never ships. With native CSS, the browser just skips the declaration it doesn’t understand and moves on:

.card {
  /* Browser doesn't understand container queries → skips silently */
  container-type: inline-size;
  /* Falls back to... nothing. No fallback defined. Layout breaks. */
}

No error. No warning. No alert. You find out when a user screenshots a broken UI and posts it somewhere.

SCSS gave you build-time safety. Native CSS gives you runtime silence.

The progressive enhancement tax

The correct answer to browser support gaps is progressive enhancement — define a baseline that works everywhere, then layer on the modern feature:

.card__title {
  /* Baseline: works everywhere */
  font-size: 18px;
}

/* Enhancement: only where container queries work */
@container (min-width: 400px) {
  .card__title {
    font-size: 24px;
  }
}

This is the right pattern. But it’s also more code, more cognitive load, and more surface area to test. With SCSS you compiled one output and called it done. With native CSS + progressive enhancement you’re maintaining two layers of intent for every feature you use. It’s manageable. But it’s not free.

@supports helps — but only partially

Unlike JavaScript where you can if ('IntersectionObserver' in window), CSS has no clean runtime feature detection. @supports gets you partway there:

@supports (container-type: inline-size) {
  .card { container-type: inline-size; }
}

@supports not (container-type: inline-size) {
  /* fallback layout */
}

But @supports checks syntax, not behavior. Some older browsers will claim to support a feature and implement it incorrectly. You don’t find out until QA on a real device — or until a user reports it.

The practical checklist before going SCSS-free

Before committing to native-CSS-only on a project, answer these four questions:

1. What does your analytics say about browser versions?
If you have >5% traffic on browsers older than 2 years, you need fallbacks for almost everything in this article.

2. Do you test on real devices?
Chrome DevTools device emulation is not the same as a real Android 10 device. Android WebView lags behind Chrome proper and is where you’ll catch the most rendering bugs — but only if you actually test there.

3. What’s your fallback strategy when a feature isn’t supported?
“It probably works” isn’t a strategy. Define explicitly: if @layer doesn’t load, what does the user see? If container queries don’t fire, does the layout degrade gracefully or snap into something broken?

4. Does your team have the CSS depth to debug this?
SCSS errors are compiler errors — they’re explicit. Native CSS failures are visual regressions with no stack trace. You need someone on the team who can open DevTools, spot a silently-ignored declaration, and trace it back to a support gap. That’s a different skill than reading a build log.

The Honest Answer to “Can We Drop SCSS?”

For new projects starting today: probably yes, with caveats. Native nesting, custom properties, color-mix(), container queries, and @layer handle the majority of what SCSS used to be required for. You’d miss loops and build-time validation.

For existing projects: almost certainly no, not yet. The migration cost isn’t justified by the current feature delta. The gap is closing, but it’s not closed.

The direction is clear though. Every SCSS feature that can be replicated natively will be replicated natively — that’s been the pattern for ten years. Variables came first. Nesting followed. Functions and mixins are in spec. The browser is slowly absorbing the preprocessor.

The question isn’t whether SCSS will become optional — it’s when. My guess: two to three years before native CSS covers enough ground that starting a new project without a preprocessor stops feeling like you’re handicapping yourself.

Until then, the smart play isn’t “all SCSS” or “all native CSS.” It’s knowing which problems each solves better right now — and not reaching for a build tool out of habit when the platform handles it.

The real question isn’t which individual feature you’d miss — it’s whether you’d lose a workflow. Build-time validation, structured data as config, loop-driven generation: these aren’t features you replace one-for-one, they’re patterns. What pattern from your SCSS setup do you think CSS will never cover natively? Drop it in the comments.

I Built Orra: A Tarot App Powered by Pyth for Verifiable Market Readings

Dashboard

I got tired of noisy charts and vague signals.

So I built Orra, a tarot app powered by Pyth that turns real-time market data into verifiable readings.

Most tools give raw numbers.

Most tarot apps give vibes without proof.

I wanted both intuition and transparency in one flow.

What Orra Does

  • Lets users pick an asset and go through an adaptive question flow
  • Anchors each reading to live Pyth Price Feed context
  • Triggers card draws with Pyth Entropy
  • Shows an on-chain receipt linking snapshot and draw result
  • Generates a share-ready reading image for socials or friends

Why I Built It

I wanted a product that feels human, not just another chart dashboard, while still being technically credible. Orra is my attempt to combine ritual-style UX with verifiable on-chain mechanics.

Product Flow

1) Dashboard

Users land on the dashboard, search assets, and review live market context before starting a reading.

Dashboard

2) Wallet Connect

Users connect wallet to enter the reading flow.

Wallet Connect

3) Asset Selection

Users choose the asset, and Orra confirms the live Pyth feed.

Asset Selection

4) Adaptive Question Flow

Users answer guided questions about market situation, timing, and focus. The path adapts by asset category.

Adaptive Question Flow

5) Oracle Commit

Users confirm the fee and trigger the draw. Orra commits a Pyth snapshot on-chain and requests Entropy randomness.

Oracle Commit

6) Card Draw

A card is selected from Entropy output. Orientation (upright/reversed) is also determined deterministically from the same random value.

Card Draw

7) Reading Result + Proof

The final view shows the card, interpretation, and on-chain receipt proving the snapshot and draw linkage.

Reading Result

8) Shareable Reading Card

Users can download a clean reading card image to share externally.

Shareable Reading Card

Live Demo

https://orra-pyth.vercel.app/

Feedback I Want

I would love feedback on:

  • UX clarity through the full flow
  • Trust and proof presentation
  • Interpretation quality and tone
  • Features that would make this more useful daily

Orra. Read the market. Read your path.

Is Cursor Safe? I Scanned 100 Apps. 67% Had Critical Vulns.

so I’ve been building ShipSafe — security scanner for AI-generated code — and a few weeks ago I got curious. like, actually curious. not “I wonder if AI code has bugs” curious, more like “how bad is it really and am I just being paranoid” curious.

I grabbed 100 Cursor-built repos off GitHub. not tutorials, not demo apps. real production stuff — SaaS tools, internal dashboards, a couple e-commerce stores, bunch of API backends. found them by searching for .cursorrules files and Cursor-style commit patterns.

then I scanned all of them with ShipSafe.

67%. sixty-seven percent had at least one critical vulnerability. the worst app had 14 separate issues. fourteen. average was 3.2 per app.

ngl I expected some problems but not… that.

% of apps
had a critical vuln 67%
IDOR 43%
inverted auth 31%
frontend-only admin checks 28%
hardcoded secrets 22%

this tracks with Stanford research that found ~45% of AI-assisted code has vulns. our numbers are worse, probably bc we only looked at shipped production apps vs their lab setup.

anyway. let me show you what I kept finding.

the IDOR thing (43%)

this was by far the most common. and it’s so dumb that it’s almost funny? Cursor generates an API route, takes an ID from the URL, fetches from the database, returns it. no check on who’s asking.

// /api/invoices/[id]
export async function GET(req, { params }) {
  const invoice = await db.invoice.findUnique({
    where: { id: params.id },
  });
  return Response.json(invoice);
}

change /api/invoices/42 to /api/invoices/43. congrats you’re reading someone else’s invoice now. their name, the amount, payment status, all of it. OWASP literally lists this as vulnerability #1.

the fix btw:

where: {
  id: params.id,
  userId: session.user.id, // this. this is the whole fix.
},

one line. Cursor never adds it. and I get why — the AI is optimizing for “does it work” not “who’s allowed to see this.” but still. 43%.

the backwards auth thing was the wildest tho

okay 31% of these apps had their auth middleware inverted. and I know that sounds fake but look at this:

export function middleware(req) {
  const token = req.cookies.get("session");

  if (token) {
    return NextResponse.redirect("/login");
  }
  return NextResponse.next();
}

if (token) → kick to login. so logged-in users get redirected away. and if you DON’T have a token? NextResponse.next() — come right in. every protected route, wide open to anyone without a session.

one missing !. that’s it. if (!token) vs if (token).

and here’s what makes it so nasty — you will never find this by testing your own app. you’re logged in while you test. the redirect fires on you and maybe you think “huh that’s weird” and hack around it or don’t even notice bc your session is cached. meanwhile an attacker shows up with zero cookies and gets full access to everything. no cap the first time I saw this in a real production app I just stared at it for like 30 seconds.

frontend admin checks that do nothing

28% of apps had this pattern where Cursor puts the role check in React but not on the server. and I gotta admit this one annoys me the most bc it’s so close to being right.

// this part is fine honestly
if (user.role !== "admin") return <Redirect to="/" />;

// this part is NOT fine
export async function DELETE(req, { params }) {
  await db.user.delete({ where: { id: params.id } });
  return Response.json({ success: true });
}

the admin panel is hidden in the UI. great. but curl -X DELETE /api/users/123 works for literally anyone. the API doesn’t check anything. Cursor generated the visual gate and forgot the actual gate.

I started telling people: frontend is what you see, backend is what you can do. Cursor gets the see part right every time. the do part? apparently optional.

hardcoded secrets + a personal L

22% had keys in the source. and tbh this is the one I’m least judgmental about bc I almost did this myself early on.

you’re setting up Stripe or whatever. you paste your API key into Cursor’s chat for context. Cursor writes the integration and puts the key right there in the file:

export const stripe = new Stripe("sk_live_51N8x...");

you commit, push, and now that key is in your git history permanently. deleting the file doesn’t help — git log remembers. GitGuardian says 12.8 million secrets were exposed on GitHub last year and I bet a huge chunk started exactly like this.

I almost shipped a Supabase service role key this way. caught it in a scan literally the day before pushing to prod. that’s actually one of the reasons I started building ShipSafe — I needed it for myself first.

why tho

okay so why does Cursor keep doing this? I’ve thought about it a lot and I think there’s two things going on.

first — LLMs learn from GitHub. and most code on GitHub is focused on making things work. security is an afterthought in like 90% of open source repos. so the model generates happy-path code. auth checks, ownership verification, input validation — that stuff doesn’t make the app function, it prevents exploitation. the model literally doesn’t prioritize it unless you specifically ask.

second thing — and this is the one that’s harder to fix — Cursor thinks about one file at a time. it’ll generate a totally reasonable API route without knowing that your middleware in some other directory is supposed to handle auth. or that it doesn’t. the context window sees the file you’re working on, not the security architecture of your whole app.

tbh the second one bugs me more than the first bc you can kinda solve the first one with good .cursorrules but the file-at-a-time thing is structural.

what actually changed my workflow

I’m not gonna stop using Cursor over this. the speed boost is too real. but I did change a few things and it’s made a huge difference.

biggest one — I added security-specific rules to my .cursorrules file. things like “always add userId to database where clauses” and “never hardcode secrets, always use process.env.” sounds simple but it legit changed the output quality. night and day.

the other thing is I just manually review auth-related code now. everything else, Cursor handles and I trust it. but middleware files, API route guards, anything with role checks — I actually read those line by line. takes like 5 minutes per PR and it’s caught issues multiple times.

and obviously I run ShipSafe before deploying. that’s the whole reason I built it lol. paste the GitHub URL, get a report, fix the flagged stuff, ship. couple minutes.

oh and I stopped pasting real API keys into Cursor chat. use fakes, swap in real ones through env vars. learned that one the hard way with the Supabase key thing I mentioned.

Cursor makes you stupid fast. I’m not going back to writing everything manually. but “fast” and “secure” aren’t the same thing and 67% of production apps having critical vulns is a pretty loud signal.

just add a scan to your deploy flow. like two minutes. saves you the 2am incident response call.

full data + methodology: ship-safe.co/blog/is-cursor-code-secure

free scan: ship-safe.co